# LorcanDempsey.net
> Deep dives into the organization, culture and technology of libraries and their milieux.
Public Ghost content for AI and LLM tooling. This file includes a bounded export of public pages first, then recent public posts.
Append `.md` to any post or page URL to get the content in Markdown (for example, `/example-post.md`).
## Pages
### long bio
URL: https://www.lorcandempsey.net/cv/
Last updated: 2025-07-26T15:33:15.000Z
I enjoy working with groups of libraries to develop shared services, products and directions. I help guide national and international cooperative and R&D programs. I have been lucky to have worked with smart, dedicated people, in impactful organizations, in Ireland, the EU, the UK and the US.
## Employment summary
**8/2023 - 6/25**
**The University of Washington, Seattle** *Professor of Practice and Distinguished Practitioner in Residence.* As a faculty member I developed and taught courses in library collaboration/partnership and management, and participated in the activities of the Information School .
**8/2022 -**
*International librarian, writer, adviser*
**7/2001 - 7/2022**
**OCLC, Dublin Ohio, US** *VP, Membership and Research, and Chief Strategist*. I managed the Membership and Research Division of OCLC, a high performing group of 55 professionals from various professional backgrounds. I also jointly coordinated the strategic planning process.
**7/2000 - 6/2001**
**Jisc, King’s College London, UK**. *Director, Distributed National Electronic Resource*. Oversaw the central, national UK Higher/Further Education investment in information services and resources.
**11/1994 -6/2000**
**University of Bath, UK**, *Director, UK Office for Library and Information Networking (UKOLN)*. Grew a high impact policy and R&D unit, with multiple funding streams.
**1987 – 1994**
**University of Bath**
*Research Officer, UKOLN*
1982 – 1987
**Dublin City Public Lib, Ireland**, *Library assistant*. (inc career break for library school)
## Honors
- The Walford Award of the Knowledge and Information Management Group of CILIP (UK) (November 2023). For an outstanding contribution to knowledge and information management services.
- IFLA Medal (July 2022). For distinguished contribution to international librarianship and to IFLA.
- Award of the Library Association of Ireland (July 2022). For outstanding contribution to libraries and librarianship.
- Honorary Doctor of the University, The Open University, UK (June 2014). For advancing digital libraries globally.
- ALA ALCTS Presidential Citation (2014). For work on shared print and Collective Collections report (OCLC Research).
- NFAIS Miles Conrad Award (2010). For influence on the library and information industry.
- ALA ALCTS Presidential Citation (2004). For work on OCLC *Environmental Scan* (with co-authors).
[Lorcan Dempsey - WikipediaWikimedia Foundation, Inc.Contributors to Wikimedia projects](https://en.wikipedia.org/wiki/Lorcan%5FDempsey?ref=lorcandempsey.net)
## Principal attributes
The summary of my career below shows these attributes:
- **Learning.** I have lived and worked in three countries, which share a language but are divided by cultural, social and behavioural norms (Ireland, UK, US). I have worked in different organizational and political cultures, with different drivers and patterns of decision-making (local government, education, non profit run along business lines). I have worked with academic and public libraries. This experience has taught me that I always need to question my assumptions, that I have something to learn from everybody.
- **Impact.** I have worked successfully at executive level for OCLC and Jisc, organizations with broad reach. I have been privileged to direct two of the most impactful R&D units in the library community, UKOLN and OCLC Research. I have helped shape national programs, major R&D programs, and far-reaching product/service portfolios.
- **Networking.** I have worked in complex multi-stakeholder environments, working with boards, advisory committees, membership structures. I have a strong network of partners and colleagues around the world. I am focused on positive outcomes.
- **Build.** I have built successful teams, successful operational services, and successful partnerships thoughout my career. I am always focused on the outcome.
- **Influence.** I have always combined my work responsibilities with my writing and speaking, through which I have contributed to library thinking about emphasis and direction. My proudest professional moment was when this contribution was acknowledged in the award of an honorary doctorate by the Open University in the UK.
## Management roles
[OCLC: Worldwide, member-driven library organizationOCLC is a nonprofit global library organization that provides shared technology services, original research, and community programs so that libraries can better fuel learning, research, and innovation.OCLC](https://www.oclc.org/en/home.html?ref=lorcandempsey.net)
****OCLC**
OCLC provides library and research services to over 18,000 libraries and related institutions worldwide. It has a staff of 1,300, spread throughout North America, Europe and Australia.
****Position**: Vice President, Membership and Research, & Chief Strategist.
Reporting to the CEO and President, participated fully in enterprise-level budget, planning, and strategic decisions as a permanent member of the OCLC Executive Management Team.
Direct the Membership and Research Division, with a staff of \~55, in addition to broader enterprise responsibilities. Specifics include:
- Manage the OCLC membership function, including Global and Regional Councils, Community Center, and related governance and outreach functions. In 2015/17 worked with Councils to achieve a major streamlining and realignment of Council responsibilities.
- Manage OCLC Research, one of the world’s largest multidisciplinary groups devoted to R&D in libraries and archives, a high performing team comprising advanced developers, librarians, data scientists and other specialists.
- We help scale learning and innovation through publication of reports, development of prototypes and support for communities of practice. I contribute actively to our research agenda, helping shape community discussions around collective collections, evolving scholarly record, libraries and Wikipedia, linked data, processing of distinctive collections, and other areas.
- Support OCLC products and services through advanced data science techniques, data modelling, prototyping and processing of OCLC linked data resources.
- Includes the Research Library Partnership and WebJunction programs. Oversaw the integration of the RLG group into OCLC in 2007/8.
- Oversee a revenue diversification strategy based on OCLC support, service contributions (for the WebJunction learning platform), member dues, and grants (from IMLS, Mellon, Gates, and the Knight Foundation).
- The OCLC Library, Archive and Museum is a part of this division.
[JiscJisc](https://www.jisc.ac.uk/?ref=lorcandempsey.net)
****Jisc, King’s College London**
Jisc is a national UK body responsible for providing networking, information and innovation services to UK higher education. Jisc recruited me to shape the full breadth of Jisc’s investment in information services and development.
****Position:** Director, Distributed National Electronic Resource.
Managed the entire Jisc investment in national information services.
Policy, funding and accountability oversight for national services (including 3 national data centers and several other operational services), the national content licensing program, a set of national advisory services, and a major R&D program (comprising over 40 projects).
Gave shape and direction to Jisc’s information-related activities. Secured political support for ongoing work within the Jisc community committee framework.
Administered the Jisc central information office with a staff of 16\. Responsible for oversight of the national information content and services budget, and the R&D budget competitively distributed as grants.
[University of BathA leading UK university with an international reputation for teaching and research excellenceUniversity of BathUniversity of Bath](https://www.bath.ac.uk/?ref=lorcandempsey.net)
****University of Bath, UKOLN**
UKOLN (UK Office for Library and Information Networking) was an internationally renowned national research and policy centre at the University of Bath, funded by the Higher Education Funding Councils (through Jisc), the (now disappeared) Museums, Libraries, and Archives Council, the British Library, the European Union, and others.
****Position:** Director.
Oversaw growth into national and international center of excellence.
Developed UKOLN into an ‘international centre of excellence for networking and new technology’ (external review by the Higher Education Funding Councils and the British Library). Developed a diversified funding strategy which delivered sustainable, planned growth (core funding from Jisc and others, and grant funding from Jisc, EU Framework Programmes).
Helped shape foundational digital library programs (eLib in UK HE, the European Libraries Programme, and the People’s Network in UK public libraries) through consulting and facilitation services.
Co-founded (with Dan Greenstein) the Resource Discovery Network (RDN, later Intute) and subsequently managed the organizational and service framework for the coming together of independent ‘subject gateways’ into the RDN. Co-founded (with John MacColl) *Ariadne Magazine*.
## Education
- University College Dublin: Master Library & Information Studies
- University College Dublin: Dip. Library & Information Studies
- University College Dublin: B.A. (English Language & Literature)
[University College DublinUCD is one of Europe’s leading research-intensive universities; an environment where undergraduate education, masters and PhD training, research, innovation and community engagement form a dynamic spectrum of activity.](https://www.ucd.ie/?ref=lorcandempsey.net)
Select professional development
- OCLC. Variety of 360-review and evaluations; courses on Equity, Diversity, Inclusion and cultural competence; executive coaching.
- Ohio State University, 2001-8\. Executive development courses (strategy, finance, HR)
- Civil Service College, UK, 1995\. PRINCE - project management
- Univ. Western England, 1992\. Higher National Cert, Computing, Distinction
- Trinity College Dublin, 1987\. Dip. Adv Computer Programming. (First year completed of a 3-year course. Stopped when moved to UK)
## Select committees
### Current
- Advisory Board, ARL/CNI Futurescape Libraries: Mapping Possibilities for Tomorrow's Information Hub
### Some past commitments
- Visiting committee, Cambridge University Library, UK
- Advisory Committee, Wayne State University, School of Library & Information Science, US
- Advisory Committee, Kent State University, School of Library & Information Science, US
- IFLA WLIC 2016 National Organizing Committee (Organizational lead for OCLC participation when the global IFLA meeting came to Columbus)
- NISO Board (National Information Standards Organization, US)
- CISTI Advisory Board (Canada Institute for Scientific and Technical Information and Canadian National Science Library)
- Library of Congress Working Group on the Future of Bibliographic Control
- Ithaka Research Advisory Committee
- Member of editorial boards of *Program*, *Journal of Academic Librarianship*, *Public Access Computer Systems Review*.
- Visiting committee to Los Alamos National Laboratories Research Library (review of library), UK
- Visiting committee to the Natural History Museum, London (review of Information services), UK
## Communication, publications and presentations
The citation for the award of the honorary Doctorate at the Open University (UK) reads:
> Through his extensive writing, inspirational speaking and thought-provoking online presence … Lorcan is responsible for a wide range of influential concepts that have shaped the conversation about the future of libraries in the broader information environment.
[ORCID](https://orcid.org/0000-0002-2925-8764?ref=lorcandempsey.net)
A full annotated description of my writing and some recent presentations are available here:
[WritingI have written widely over the years. Topics have evolved, but follow a general chronological arc from the technical, through the description of evolving digital systems and services, to organizational and institutional issues.LorcanDempsey.netLorcan Dempsey](https://www.lorcandempsey.net/writing/)
[Some recent presentationsHere are some recent presentations. I debated whether to use Slideshare or Figshare to share. Slideshare is interesting and seemed to peak a while ago. I don’t know why it did not last within the Linkedin family and we will see what Scribd will do with it now that they own it. It has the advantage o…LorcanDempsey.netLorcan Dempsey](https://www.lorcandempsey.net/presentations/)
Twice awarded an ALA ALCTS (Assoc. for Library Collections and Technical Services) Presidential citation for publications with colleagues. A book of my blog was published by ALA Publishing in 2014: *The network reshapes the library.*
> Thoughtful, prescient yet also self-deprecating, Lorcan Dempsey's blog has been a must read for many years. This collection brings together some highlights spanning 10 years between 2003 and 2013\. Curated into loosely themed chapters, they provide an accessible summary of some significant trends during that period and better illustrate how good Dempsey has been at identifying and describing key ideas. This for me was a lively reminder of how things are changing and how much there is yet to do. I inhaled it in one sitting. // [Network Reshapes the Library: Lorcan Dempsey on Libraries, Services, and Networks by Lorcan Dempsey | LibraryThing](http://www.librarything.com/work/14938005/reviews/116495798?ref=lorcandempsey.net)
## Grants and programs
### Grant maker and program development
- Managed the R&D program of Jisc in the UK, distributing grant funding to support innovation in library and information services.
- Provided consulting, facilitation and support services to the UK’s Electronic Libraries Programme, and helped shape its direction.
- Co-author of the libraries section of the EU Fourth Framework Programme. Acted as consultant, evaluator and drafter for the libraries programme of the European Commission.
- Member of the working group which created the People’s Network, a UK public library network infrastructure funding initiative.
### Grant recipient
- Have overseen an extensive OCLC Research range of projects funded by IMLS, Gates, and the Andrew W. Mellon and Knight Foundations.
- Co-PI, University futures, library futures. Andrew W. Mellon Foundation (2017-18).
- At UKOLN managed a portfolio of influential grant funded projects in distributed library services, resource discovery, and consensus-making. Funding from Jisc and the European Union Framework programmes.
- Experienced application writer with a high hit rate.
### Why join?
URL: https://www.lorcandempsey.net/membershipp/
Last updated: 2022-11-15T19:57:48.000Z
##
**Sign up** to join. You can then opt in to receive updates. Once you are a member, you need to **Sign in** if you wish to comment. This is to reduce spam.
- [Signup](#/portal/signup)
- [Sign in](#/portal/signin)
The system stores your details in a minimal profile, which you can review/edit if you are signed in.
- [Account](#/portal/account)
- [Sign out](#/portal/signout)
These functions are also accessible through the Member 'Sign up/in' button floating on the screen. And in some sidebar and footer forms (which you do not see if you are signed in).
The Sign in feature becomes more important where paid content features are used. However this is not an issue here as all of this site is openly available.
## Privacy
The site does not use passwords. It uses an email-based approach. So no passwords are stored.
No personal details are stored beyond provided email and name. LorcanDempsey.net will use these only for the purposes described above (updates and comment management) and will not share with anyone.
This site is hosted on Ghost using Ghost software. The software is open source and open to inspection. The organization is a not for profit funded entirely from user fees. The Ghost position on security and privacy is described here:
[Ghost Security & PrivacyGhost is committed to developing secure, reliable products utilising all modern security best practices. Find out more about Ghost security and privacy.Ghost - The Professional Publishing Platform](https://ghost.org/docs/security/?ref=lorcandempsey.net)
### personal coordinates
URL: https://www.lorcandempsey.net/contact/
Last updated: 2025-10-26T21:43:11.000Z
You can reach me in the usual ways:
[ ](mailto:lorcand@lorcandempsey.net) [](https://www.linkedin.com/in/lorcand?ref=lorcandempsey.net) [](https://twitter.com/lorcand?ref=lorcandempsey.net) [](https://www.facebook.com/lorcand)
Click above for email. Or here it is:
lorcand \[at\] lorcandempsey \[dot\] net
Check the About page for a brief bio, pictures and other details:
[LorcanDempsey.netWelcome! This is a place to bring together my work on library services and directions.LorcanDempsey.netLorcan’s posts](https://www.lorcandempsey.net/about/)
### Signup
URL: https://www.lorcandempsey.net/signup/
Last updated: 2024-07-08T03:46:25.000Z
_No content available._
### writing
URL: https://www.lorcandempsey.net/writing/
Last updated: 2025-07-03T05:16:36.000Z
## Overview
While these particular emphases have been enduring interests, each has emerged successively. I moved to the UK to work for what was then *The Centre for Bibliographic Management*, at the University of Bath, which later morphed into the *UK Office for Library and Information Networking* (UKOLN). So my early focus was very much on the emerging apparatus of metadata, networking and related approaches. However, this evolution from the specialist to the more social or organizational is maybe not surprising in a typical career trajectory? It also reflects of course the changing reality of digital and the network during these years, as they have become more pervasive of our behaviors and social organization.
> Through his extensive writing, inspirational speaking and thought-provoking online presence … Lorcan is responsible for a wide range of influential concepts that have shaped the conversation about the future of libraries in the broader information environment. // Citation for the award of Hon. Doctorate from the Open University.
Most of my writing has been professional in focus, motivated by a desire to influence practice and direction. The emphasis is often on environmental analysis, description of particular initiatives, or exploration of near-term trends. It tends to be synthetic and not explicitly theoretical, although I do discuss shaping influences below.
The unifying theme of this chronological arc has been the threefold entanglement of library organizations and services, learning and research behaviors, and the developing digital network. Alongside an abiding commitment to the value and social contribution of the library. Taken as a whole, a modest contribution of this work is to present a view of the historical development of libraries in this crucial network period.
I include a fullish chronological list of publications below. Many are available open access, especially in more recent years. This is followed by some consideration of central themes.
Here I am on the scholarly engines ...
[ ](https://figshare.com/authors/Lorcan%5FDempsey/10018391) [ ](https://scholar.google.com/citations?user=rOEEU4wAAAAJ&hl=en) [ ](https://orcid.org/0000-0002-2925-8764) [ ](https://www.semanticscholar.org/author/Lorcan-Dempsey/145368307) [ ](https://www.worldcat.org/search?q=lorcan+dempsey)
---
## A list of publications
### Papers: \*peer reviewed and professional
**Library Studies, the Informational Disciplines, and the iSchool: Some Remarks Prompted by LIS Forward.** In: LIS Forward (2025) *Responses to the LIS Forward Position Paper: Ensuring a Vibrant Future for LIS in iSchools, The Friday Harbor Papers, Volume 2*. \[[pdf](https://doi.org/10.6069/F6CQ-H317?ref=lorcandempsey.net)\]
**\*Reflections on collective collections**.
Reflections on Collective Collections. *College & Research Libraries*, *81*(6), 2020\. (with Brian Lavoie and Constance Malpas).
[https://doi.org/10.25333/t51w-b252](https://doi.org/10.25333/t51w-b252?ref=lorcandempsey.net)
**What Collaboration Means to Me: Library collaboration is hard; effective collaboration is harder.**
*Collaborative Librarianship*, Vol. 10: Iss. 4, Article 3\. 19 March 2019.
[https://digitalcommons.du.edu/cgi/viewcontent.cgi?article=1409&context=collaborativelibrarianship](https://digitalcommons.du.edu/cgi/viewcontent.cgi?article=1409&context=collaborativelibrarianship&ref=lorcandempsey.net)
**Academic Library Futures in a Diversified University System**.
In: Gleason N. (eds) Higher Education in the Era of the Fourth Industrial Revolution. Palgrave Macmillan, Singapore, 2018\. (with Constance Malpas).
[https://link.springer.com/chapter/10.1007/978-981-13-0194-0\_4](https://link.springer.com/chapter/10.1007/978-981-13-0194-0%5F4?ref=lorcandempsey.net)
**\*Library collections in the life of the user: two directions**.
*Liber Quarterly*, Vol. 26, No. 4, 2016.
[https://www.liberquarterly.eu/articles/10.18352/lq.10170/](https://doi.org/10.18352/lq.10170?ref=lorcandempsey.net)
**A Platform Publication for a Time of Accelerating Change.**
*College & Research Libraries*, 75, November 2014: 760-762\. (with Scott Walter).
[https://crl.acrl.org/index.php/crl/article/view/16387/17833](https://crl.acrl.org/index.php/crl/article/view/16387/17833?ref=lorcandempsey.net)
**\*Collection Directions: The Evolution of Library Collections and Collecting**.
*portal: Libraries and the Academy,* 14, 3 (July 2014), 393–423\. (with Constance Malpas and Brian Lavoie).
*portal*: [https://muse.jhu.edu/article/549200](https://muse.jhu.edu/article/549200?ref=lorcandempsey.net)
PDF: h[ttps://www.oclc.org/content/dam/research/publications/library/2014/oclcresearch-collection-directions-preprint-2014.pdf](https://www.oclc.org/content/dam/research/publications/library/2014/oclcresearch-collection-directions-preprint-2014.pdf?ref=lorcandempsey.net)
**Thirteen ways of looking at libraries, discovery and the catalog: scale, workflow, attention.**
*Educause Review Online*. December 10, 2012\.
[http://www.educause.edu/ero/article/thirteen-ways-looking-libraries-discovery-and-catalog-scale-workflow-attention](http://www.educause.edu/ero/article/thirteen-ways-looking-libraries-discovery-and-catalog-scale-workflow-attention?ref=lorcandempsey.net)
**Libraries and the Informational Future: Some Notes**
in *Information Professionals 2050: Educational Possibilities and Pathways*, Moran. Chapel Hill, NC: University of North Carolina at Chapel Hill, 2012, pp. 113-26\.
[http://sils.unc.edu/news/2012/ip2050-book-video](http://sils.unc.edu/news/2012/ip2050-book-video?ref=lorcandempsey.net)
Also published by UNC on Lulu and appears in a special issue of *Information Services and Use.*
[http://www.oclc.org/resources/research/publications/library/2012/dempsey-informationalfutures.pdf](http://www.oclc.org/resources/research/publications/library/2012/dempsey-informationalfutures.pdf?ref=lorcandempsey.net)
**Beyond 1923: Characteristics of Potentially In-copyright Print Books in Library Collections**.
*D-Lib Magazine*, Vol. 15, No. 11/12, November/December 2009\. (with Brian F. Lavoie)
[http://www.dlib.org/dlib/november09/lavoie/11lavoie.html](http://www.dlib.org/dlib/november09/lavoie/11lavoie.html?ref=lorcandempsey.net)
\* **Always on: libraries in a world of permanent connectivity**.
*First Monday*, vol 14 No. 1, 5 January 2009\.
[http://firstmonday.org/htbin/cgiwrap/bin/ojs/index.php/fm/article/view/2291/2070](http://firstmonday.org/htbin/cgiwrap/bin/ojs/index.php/fm/article/view/2291/2070?ref=lorcandempsey.net)
An earlier version of this paper appeared in Mohamed Ally and Gill Needham (eds). *M-Libraries: libraries on the move to provide virtual access*. London: Facet, 2008.
**\*Reconfiguring the Library Systems Environment**.
p*ortal: Libraries and the Academy*, Vol. 8, No. 2, April 2008.
[http://www.oclc.org/research/publications/archive/2008/dempsey-portal.pdf](http://www.oclc.org/research/publications/archive/2008/dempsey-portal.pdf?ref=lorcandempsey.net)
**The History of Libraries in Modern 'Britain and Ireland'**
\[Review article\] *Ariadne*, Issue 53, October 2007\. Review of Alistair Black and Peter Hoare (eds). 2006\. *The Cambridge History of Libraries in Britain and Ireland*. Cambridge, UK: Cambridge University Press. Volume III, 1850-2000.
[http://www.ariadne.ac.uk/issue/53/maccoll-dempsey-rvw/](http://www.ariadne.ac.uk/issue/53/maccoll-dempsey-rvw/?ref=lorcandempsey.net)
**The Library Catalogue in the New Discovery Environment: Some Thoughts**.
*Ariadne*, Issue 48, July 2006.
[http://www.ariadne.ac.uk/issue/48/dempsey/](http://www.ariadne.ac.uk/issue/48/dempsey/?ref=lorcandempsey.net)
**A Service Framework for Libraries**.
*D-Lib Magazine*, Vol. 12, No. 7/8, July/August 2006\. (with Brian F. Lavoie and Geneva Henry).
[http://www.dlib.org/dlib/july06/lavoie/07lavoie.html](http://www.dlib.org/dlib/july06/lavoie/07lavoie.html?ref=lorcandempsey.net)
**Libraries and the Long Tail: Some Thoughts about Libraries in a Network Age**.
*D-Lib Magazine*, Vol. 12, No. 4, April 2006.
[http://www.dlib.org/dlib/april06/dempsey/04dempsey.html](http://www.dlib.org/dlib/april06/dempsey/04dempsey.html?ref=lorcandempsey.net)
**The (Digital) Library Environment: Ten Years After.**
*Ariadne*, Issue 46, February 2006.
[http://www.ariadne.ac.uk/issue/46/dempsey/](http://www.ariadne.ac.uk/issue/46/dempsey/?ref=lorcandempsey.net)
**Anatomy of aggregate collections: the example of Google Print for Libraries**.
*D-Lib Magazine*, Vol. 11, No. 9, September 2005\. (with Brian F. Lavoie and Lynn Silipigni Connaway).
[http://www.dlib.org/dlib/september05/lavoie/09lavoie.html](http://www.dlib.org/dlib/september05/lavoie/09lavoie.html?ref=lorcandempsey.net)
Reprinted in *Zeitschrift fur Bibliothekswesen und Bibliographie*, Vol. 52, No. 6, 2005\. pp 299-310.
**Thirteen ways of looking at ... digital preservation**.
*D-Lib Magazine*, Vol. 10, No. 7/8, July/August 2004\. (with Brian F. Lavoie)
[http://www.dlib.org/dlib/july04/lavoie/07lavoie.html](http://www.dlib.org/dlib/july04/lavoie/07lavoie.html?ref=lorcandempsey.net)
Also in: Kresh, D. (2007). *The whole digital library handbook*. Chicago: American Library Association.
**The recombinant library: portals and people**
Co-published simultaneously in *Journal of Library Administration*, Vol. 39, No. 4, 2003, pp. 103-136; and in *Improved Access to Information: Portals, Content Selection, and Digital Information*, edited by Sul H. Lee, pp. 103-136\. Binghamton, NY: Haworth (2003).
Pre-print available at:
[http://www.oclc.org/research/staff/dempsey/recombinant\_library/](http://www.oclc.org/research/staff/dempsey/recombinant%5Flibrary/?ref=lorcandempsey.net)
**The Distributed National Electronic Resource (DNER) and the hybrid library**.
*Ariadne*, Issue 26, January 2001\. (with Stephen Pinfield).
[http://www.ariadne.ac.uk/issue/26/dner/](http://www.ariadne.ac.uk/issue/26/dner/?ref=lorcandempsey.net)
**A policy context - eLib and the emergence of the subject gateways**.
*Ariadne*, Issue 25, September 2000\. (with Derek Law).
[http://www.ariadne.ac.uk/issue/25/subject-gateways/](http://www.ariadne.ac.uk/issue/25/subject-gateways/?ref=lorcandempsey.net)
**RSLP collection description**.
*D-Lib Magazine*, September 2000\. (with Andy Powell and Michael Heaney)
[http://www.dlib.org/dlib/september00/powell/09powell.html](http://www.dlib.org/dlib/september00/powell/09powell.html?ref=lorcandempsey.net)
**The subject gateway: experiences and issues based on the emergence of the Resource Discovery Network.**
*Online Information Review*, 24(1), 2000, 8-23\. Preprint available at:
http://www.ukoln.ac.uk/metadata/publications/ior/dempsey.htm
**The scientific, industrial and cultural heritage: a shared approach: a research framework for digital libraries, museums and archives**.
*Ariadne*, 22, 2000\. (Slightly revised version of EC report.)
[http://www.ariadne.ac.uk/issue/22/dempsey/](http://www.ariadne.ac.uk/issue/22/dempsey/?ref=lorcandempsey.net)
**The network and the library: working in a new shared space: infrastructure and institutions**.
*The Electronic Library*. August 1999\. (Guest editorial article for special libraries and networking theme issue.)
[http://homes.ukoln.ac.uk/\~lisld/publications/electlib.html](http://homes.ukoln.ac.uk/~lisld/publications/electlib.html?ref=lorcandempsey.net)
**International information gateway collaboration: report of the first IMesh Framework Workshop**.
*D-Lib Magazine*, Vol. 5, No. 12\. December 1999\. (with Tracy Gardner, Michael Day and Titia van der Werf)
[http://www.dlib.org/dlib/december99/12dempsey.html](http://www.dlib.org/dlib/december99/12dempsey.html?ref=lorcandempsey.net)
**\*The library, the catalogue, the broker.**
*New Review of Information Networking*, Volume 5, 1999\. (Also available in: *Information landscapes and a learning society: networking and the future of libraries 3*. Sally Criddle, Lorcan Dempsey, Richard Heseltine, eds. London: Library Association Publishing, 1999.)
[http://www.ukoln.ac.uk/dlis/models/publications/landscape/](http://www.ukoln.ac.uk/dlis/models/publications/landscape/?ref=lorcandempsey.net)
**\*Library places and digital information spaces: reflections on emerging network services**.
*Alexandria*, 11(1), 1999, 51-58\. (An amended version of: Places and spaces. In: *Towards the digital library: the British Library’s Initiatives for Access programme.* Edited by Leona Carpenter, Simon Shaw and Andrew Prescott. London: British Library, 1998, 234-241.)
[http://homes.ukoln.ac.uk/\~lisld/publications/alex.html](http://homes.ukoln.ac.uk/~lisld/publications/alex.html?ref=lorcandempsey.net)
**\*Community networking: development, potentials and implications for public libraries**.
*Journal of librarianship and information science*. 31(2), 1999, 71-83\. (With Liangzhi Yu and Sarah Ormes)
**\*From files to landscapes: network information management and UKOLN**.
*Journal of Documentation*, 55(1), 1999, 1-5\. (Introductory article to special issue on UKOLN work.)
**\*A utopian place of criticism?: brokering access to network information**.
*Journal of Documentation*, 55(1), 1999, 33-70\. (with Rosemary Russell and Robin Murray)
[http://www.ukoln.ac.uk/dlis/models/publications/utopia/](http://www.ukoln.ac.uk/dlis/models/publications/utopia/?ref=lorcandempsey.net)
**\*A distributed national electronic resource?**
*The Electronic Library*, 16(4), 1998, 231-237\. (with Rosemary Russell)
**\*The emergence of distributed library systems: a European perspective**.
*Journal of the American Society of Information Scientists.* 49(10), 1998, 942-951\. (with Robin Murray and Rosemary Russell)
**\*Managing access to a distributed library resource**.
*Program*, 32(3),1998, 265-281\. (with Robin Murray, Rosemary Russell, and Richard Heseltine).
[http://www.ukoln.ac.uk/dlis/models/models5/report.rtf](http://www.ukoln.ac.uk/dlis/models/models5/report.rtf?ref=lorcandempsey.net)
**\*Metadata: a current review of practice and issues**.
*Journal of Documentation*, 54(2), March 1998, 145-172\. (with Rachel Heery.)
[http://www.ukoln.ac.uk/metadata/publications/jdmetadata/](http://www.ukoln.ac.uk/metadata/publications/jdmetadata/?ref=lorcandempsey.net)
**\*‘Clumps’ - or distributed access to scholarly material**.
*Program*, 31(3), July 1997\. (With Rosemary Russell.)
[http://www.ukoln.ac.uk/dlis/models/models3/program.html](http://www.ukoln.ac.uk/dlis/models/models3/program.html?ref=lorcandempsey.net)
**\*Scientific information supply: building networked information systems.**
*The Electronic Library*, Vol 14, No. 4, August 1996\. (with Maria Heijne)
**Warwick Metadata Workshop: a framework for the deployment of resource description**.
*D-Lib Magazine*, July/August 1996\. (With Stu Weibel)
[http://www.dlib.org/dlib/july96/07weibel.html](http://www.dlib.org/dlib/july96/07weibel.html?ref=lorcandempsey.net)
**ROADS to Desire: some UK and other European metadata and resource discovery projects.**
D*\-Lib Magazine*, July/August 1996.
[http://www.dlib.org/dlib/july96/07dempsey.html](http://www.dlib.org/dlib/july96/07dempsey.html?ref=lorcandempsey.net)
**Meta detectors: metadata and resource discovery.**
*Ariadne*, Issue 3, May 1996.
[http://www.ukoln.ac.uk/ariadne/issue/3/metadata/](http://www.ukoln.ac.uk/ariadne/issue/3/metadata/?ref=lorcandempsey.net)
**\*Towards distributed library systems: Z39.50 in a European context**.
*Program*, 30 (1), January 1996, 1-22\. (With Rosemary Russell and John Kirriemuir)
[https://www.emerald.com/insight/content/doi/10.1108/eb047214/full/html](https://www.emerald.com/insight/content/doi/10.1108/eb047214/full/html?ref=lorcandempsey.net)
(Paywall version. Program was published by Aslib when this article appeared. Aslib undertook to make an open version available. That disappeared when Aslib was acquired.)
**The public library and the information superhighway.**
*Vine*, Issue no. 98, March 1995.
[http://www.ukoln.ac.uk/services/papers/ukoln/dempsey-1995-01/](http://www.ukoln.ac.uk/services/papers/ukoln/dempsey-1995-01/?ref=lorcandempsey.net)
**Beyond the Internet: developing library services.**
*The Law Librarian*, 26(1), 1995.
**The UK, networking and the European libraries programme.**
*Library and Information Briefing*, 57\. London: **LITC, 1995.**
**\*Towards the virtual library: standards of relevance to networked library services**
*Axis*, 1(1), 1994\. (with Bill Tuck and Anne Mumford).
**Art and the Internet**. *Art Libraries Journal*, 19(4), 1994, 10-14\. (With Ann Lennon)
**Networks, standards and end-user information services.**
*Vine*, December 1993.
[http://www.ukoln.ac.uk/\~lisld/publications/nseu.htm](http://www.ukoln.ac.uk/~lisld/publications/nseu.htm?ref=lorcandempsey.net)
**\*Academic networks and academic information services: towards an academic information infrastructure.**
*Journal of Information Networking*. 1 (1), 1993, 1-27.
**Libraries and networking**.
*Library and Information Briefing*, 37/38\. London: LITC, 1992.
**Publishers and libraries: an all-through system for bibliographic data?**
*International Cataloguing and Bibliographic Control*. 20 (3), July/September 1991, 37-41.
[http://www.ukoln.ac.uk/services/papers/ukoln/dempsey-1991-01/ubcim.rtf](http://www.ukoln.ac.uk/services/papers/ukoln/dempsey-1991-01/ubcim.rtf?ref=lorcandempsey.net)
**Users' requirements of bibliographic records: publishers, booksellers, librarians**.
*ASLIB Proceedings*, 42 (2), February 1990, 61-69.
---
### Books/monographs
**Operationalizing the BIG Collective Collection: A Case Study of Consolidation vs Autonomy** *.*
Dublin, OH: OCLC Research, 2019\. (with Constance Malpas and Mark Sandler)
[https://doi.org/10.25333/jbz3-jy57](https://doi.org/10.25333/jbz3-jy57?ref=lorcandempsey.net)
**An Exploration of the Irish Presence in the Published Record.**
An OCLC Research report, 20 February 2018\. (with Brian Lavoie)
[https://www.oclc.org/content/dam/research/publications/2018/oclcresearch-irish-published-record.pdf](https://www.oclc.org/content/dam/research/publications/2018/oclcresearch-irish-published-record.pdf?ref=lorcandempsey.net)
**New roles for the road ahead: essays commissioned for the ACRL's 75th anniversary.**
Chicago: ACRL, 2015\. (with Stephen J. Bell, Barbara Fister, Nancy Allen, and Lizabeth Wilson)
**The Network Reshapes the Library: Lorcan Dempsey on Libraries, Services and Networks.**
Chicago: ALA Publishing, 2014\. Ken Varnum, ed.
[https://www.oclc.org/research/publications/2014/network-reshapes-library-2014-overview.html](https://www.oclc.org/research/publications/2014/network-reshapes-library-2014-overview.html?ref=lorcandempsey.net)
**Understanding the Collective Collection: Towards a System-wide Perspective on Library Print Collections.**
with Brian Lavoie, Constance Malpas, Lynn Silipigni Connaway, Roger C. Schonfeld, JD Shipengrover, and Günter Waibel. Dublin, Ohio: OCLC Research, 2013.
[http://www.oclc.org/research/publications/library/2013/2013-09.pdf](http://www.oclc.org/research/publications/library/2013/2013-09.pdf?ref=lorcandempsey.net)
**The 2003 OCLC Environmental Scan: Pattern Recognition: a Report to the OCLC Membership.**
Dublin, Ohio: OCLC Online Computer Library Center, 2004\. (with Cathy de Rosa and Alane Wilson) (also translated into Spanish)
**Libraries, networks and OSI.**
1992 edition. Westport CT.: Meckler, 1992\. ISBN 0-88736-818-2\. (first edition published by UKOLN, University of Bath, 1991)
**Bibliographic records: use of data elements in the book world**.
Bath: Bath University Library, 1989\. ISBN 0861970853
---
### Papers: contributions to books and proceedings
**Library discovery directions**.
In McLeish, Simon. *Resource discovery for the twenty-first century library: case studies and perspectives on the role of IT in user engagement and empowerment*. London: Facet Publishing, 2020.
Preprint: [https://www.oclc.org/content/dam/research/publications/2020/oclcresearch-library-discovery-directions-preprint.pdf](https://www.oclc.org/content/dam/research/publications/2020/oclcresearch-library-discovery-directions-preprint.pdf?ref=lorcandempsey.net)
**The Emergence of the Collective Collection: Analyzing Aggregate Print Library Holdings.**
In:*Understanding the Collective Collection: Towards a System-wide Perspective on Library Print Collections.*Dempsey, Lorcan, Brian Lavoie, Constance Malpas, Lynn Silipigni Connaway, Roger C. Schonfeld, JD Shipengrover, and Günter Waibel. Dublin, Ohio: OCLC Research, 2013
[http://www.oclc.org/content/dam/research/publications/library/2013/2013-09intro.pdf](http://www.oclc.org/content/dam/research/publications/library/2013/2013-09intro.pdf?ref=lorcandempsey.net).
**Always on: libraries in a world of permanent connectivity**.
In: *International M-Libraries Conference*, Mohamed Ally, and Gill Needham. M-Libraries: Libraries on the Move to Provide Virtual Access. London: Facet, 2008\. (A revised version of this paper appears under the same name in *First Monday*, Vol. 14, No. 1, 5 January 2009)
**Intermediate consumers**
*netConnect*, 15 July 2005\. Also in: Kresh, D. (2007). *The whole digital library handbook*. Chicago: American Library Association.
[http://www.libraryjournal.com/article/CA609689.html](http://www.libraryjournal.com/article/CA609689.html?ref=lorcandempsey.net)
**Thirteen ways of looking at ... digital preservation**.
*D-Lib Magazine*, Vol. 10, No. 7/8, July/August 2004\. (with Brian F. Lavoie) Also in: Kresh, D. (2007). *The whole digital library handbook*. Chicago: American Library Association.
[http://www.dlib.org/dlib/july04/lavoie/07lavoie.html](http://www.dlib.org/dlib/july04/lavoie/07lavoie.html?ref=lorcandempsey.net)
**The recombinant library: portals and people**
Co-published simultaneously in *Journal of Library Administration*, Vol. 39, No. 4, 2003, pp. 103-136; and in *Improved Access to Information: Portals, Content Selection, and Digital Information*, edited by Sul H. Lee, pp. 103-136\. Binghamton, NY: Haworth (2003).
[http://www.oclc.org/research/staff/dempsey/recombinant\_library/](http://www.oclc.org/research/staff/dempsey/recombinant%5Flibrary/?ref=lorcandempsey.net)
**Metadata Switch: thinking about some metadata management and knowledge organization issues in the changing research and learning landscape.**
In: *EScholarship: A LITA Guide*, ed. Debra Shapiro (2005). February 2005
with Eric R. Childress, Carol Jean Godby, Thomas B. Hickey, Andrew Houghton, Diane Vizine-Goetz, and Jeff Young.
[http://www.oclc.org/research/publications/archive/2004/dempsey-mslitaguide.pdf](http://www.oclc.org/research/publications/archive/2004/dempsey-mslitaguide.pdf?ref=lorcandempsey.net)
**The library, the catalogue, the broker.**
In*: Information landscapes and a learning society: networking and the future of libraries 3*. Sally Criddle, Lorcan Dempsey, Richard Heseltine, eds. London: Library Association Publishing, 1999\. (Also available in *New Review of Information Networking*, Volume 5, 1999.)
[http://www.ukoln.ac.uk/dlis/models/publications/landscape/](http://www.ukoln.ac.uk/dlis/models/publications/landscape/?ref=lorcandempsey.net)
**Places and spaces.**
In: *Towards the digital library: the British Library’s Initiatives for Access programme*. Edited by Leona Carpenter, Simon Shaw and Andrew Prescott. London: British Library, 1998, 234-241\. (a slightly amended version of this paper is available as **Library places and digital information spaces: reflections on emerging network services.** *Alexandria*, 11(1), 1999, 51-58.)
[http://homes.ukoln.ac.uk/\~lisld/publications/alex.html](http://homes.ukoln.ac.uk/~lisld/publications/alex.html?ref=lorcandempsey.net)
**In at the shallow end: metadata and cross-domain resource discovery**.
In: *Discovering online resources across the humanities: a practical implementation of the Dublin Core*. Edited by Paul Miller and Daniel Greenstein on behalf of the Arts and Humanities Data Service and the UK Office for Library and Information Networking. Bath: UKOLN, 1997, 63-71\. (with Rosemary Russell and Rachel Heery.)
[http://www.ukoln.ac.uk/metadata/publications/ahds-ukoln/disc\_07.html](http://www.ukoln.ac.uk/metadata/publications/ahds-ukoln/disc%5F07.html?ref=lorcandempsey.net)
**Crossing the great divide: integrating access to the scholarly record**.
In: *Discovering online resources across the humanities: a practical implementation of the Dublin Core*. Edited by Paul Miller and Daniel Greenstein on behalf of the Arts and Humanities Data Service and the UK Office for Library and Information Networking. Bath: UKOLN, 1997, 7-12\. (with Daniel Greenstein.)
[http://www.ukoln.ac.uk/metadata/publications/ahds-ukoln/disc\_02.html](http://www.ukoln.ac.uk/metadata/publications/ahds-ukoln/disc%5F02.html?ref=lorcandempsey.net)
**Metadata and libraries: background and introduction.**
In: *Second international summer school on the digital library*. Jola Prinsen and Elsenoor Meijer (eds). Tilburg: Ticer B.V., 1997\. P. 8.1-8.9.
**Network resource discovery: a European library perspective.**
In: *Libraries, networks and Europe: a European networking study*. Neil Smith, ed. London: British Library, 1994 (Library and Information Research Paper 101), 29-68.
[http://www.lub.lu.se/UB2proj/LIS\_collection/lorcan.html](http://www.lub.lu.se/UB2proj/LIS%5Fcollection/lorcan.html?ref=lorcandempsey.net)
**RADAR reflections: Internet resource access, discovery and retrieval systems and libraries.**
In: *Library networking in Europe.* Proceedings of a conference held in Brussels in October 1994.
**Standards of relevance to networked library services**
In: *Libraries and IT: working papers of the HEFCs' Libraries Review Group IT Sub Committee*. Bath: UKOLN, 1993\. (with Bill Tuck and Anne Mumford).
**Library systems: insulated or integrated?**
In: *Networking and the future of libraries*. Smith, John (ed). Westport, CT: Meckler, 1992.
**Bibliographic access: patterns and developments**.
In: *Bibliographic access in Europe*. Lorcan Dempsey, ed. Aldershot: Gower, 1990\.
**Subject to change: aspects of subject access in the book world**. In: *Beyond the bibliographic record: proceedings of 15th Annual Seminar and Annual General Meeting of the MARC Users' Group*. London: MARC Users' Group, 1990, 23-42.
---
### Edited collections
**Understanding the Collective Collection: Towards a System-wide Perspective on Library Print Collections** *.*
Dublin, Ohio: OCLC Research, 2013\. (several contributions. With Brian Lavoie, Constance Malpas, Lynn Silipigni Connaway, Roger C. Schonfeld, JD Shipengrover, and Günter Waibel.)
[http://www.oclc.org/content/dam/research/publications/library/2013/2013-09intro.pdf](http://www.oclc.org/content/dam/research/publications/library/2013/2013-09intro.pdf?ref=lorcandempsey.net)
**Delivering the electronic library: an Ariadne reader.**
\[Dundee\]: The Ariadne Project, 1999\. (Joint editor with John MacColl and Lyndon Pugh. Joint introduction with John MacColl is at
[http://www.ariadne.ac.uk/issue/22/ariadne-reader/intro.html](http://www.ariadne.ac.uk/issue/22/ariadne-reader/intro.html?ref=lorcandempsey.net))
**Information landscapes and a learning society: networking and the future of libraries 3\.**
London: Library Association Publishing, 1999\. (Joint editor with Sally Criddle and Richard Heseltine. Introduction, contribution.)
**Journal of Documentation**. Vol. 55(1), 1999\. Special issue from UKOLN. (Editor, introduction, contribution)
**The Internet, networking and public libraries.**
London: Library Association Publishing, 1997\. (Joint editor with Sarah Ormes, Introduction)
**Networking and the future of libraries 2: managing the intellectual record.**
London: Library Association Publishing, 1995\. (Joint editor with Derek Law and Ian Mowat, introduction)
**Bibliographic access in Europe: proceedings of the first international conference.**
Aldershot: Gower, 1990\. (Editor, contributor).
**Influencing the system designer: proceedings of the third national conference.**
Oxford: Elsevier, 1988\. (Editor, introduction).
---
### Papers: short communications
**What is the most popular Irish book?**
*Irish Times*, June 29, 2017.
[https://www.irishtimes.com/culture/books/what-is-the-most-popular-irish-book-1.3136544](https://www.irishtimes.com/culture/books/what-is-the-most-popular-irish-book-1.3136544?ref=lorcandempsey.net)
**A Platform Publication for a Time of Accelerating Change.**
*College & Research Libraries*, 75, November 2014: 760-762\. (with Scott Walter)
**Making Data Work Harder**
*LibraryJournal.com*, January 15, 2006\. (with Brian Lavoie and Lynn Silipigni Connaway)
[http://www.libraryjournal.com/article/CA6298444.html](http://www.libraryjournal.com/article/CA6298444.html?ref=lorcandempsey.net)
**Intermediate consumers**
*netConnect,* 15 July 2005.
[http://www.libraryjournal.com/article/CA609689.html](http://www.libraryjournal.com/article/CA609689.html?ref=lorcandempsey.net)
Also in: Kresh, D. (2007). *The whole digital library handbook*. Chicago: American Library Association.
**The three stages of library search**
*Library + Information Update*, November 2004.
[http://www.cilip.org.uk/publications/updatemagazine/archive/archive2004/november/lorcan.htm](http://www.cilip.org.uk/publications/updatemagazine/archive/archive2004/november/lorcan.htm?ref=lorcandempsey.net)
**Pick up a portal**
*Library + Information Update*, October 2004.
[http://www.cilip.org.uk/publications/updatemagazine/archive/archive2004/october/lorcan.htm](http://www.cilip.org.uk/publications/updatemagazine/archive/archive2004/october/lorcan.htm?ref=lorcandempsey.net)
**Introduction**.
In*: Delivering the Electronic Library: the ARIADNE Reader*. \[Dundee\]: The Ariadne Project, 1999.
[http://www.ariadne.ac.uk/issue/22/ariadne-reader/intro.html](http://www.ariadne.ac.uk/issue/22/ariadne-reader/intro.html?ref=lorcandempsey.net)
**Virtual library - false dawn?: An exchange between Frank Webster and Lorcan Dempsey.**
*Ariadne*, Issue 20, 1999\. (A condensed version of this exchange appears in *Library Association* *Record*, 101(5) May 1999, p.284-5.)
[https://www.ariadne.ac.uk/issue/20/public-libraries/](https://www.ariadne.ac.uk/issue/20/public-libraries/?ref=lorcandempsey.net)
**Widening the networks**
*Library Association Record*, 100(10), 1998, 523-525.
**Soul and song: New library: the people’s network.**
*Ariadne*, Issue 12, 1997\. (reprinted in *Delivering the electronic library: an Ariadne reader.*\[Dundee\]: The Ariadne Project, 1999\. John MacColl, Lyndon Pugh, Lorcan Dempsey (eds) p.2-4)
[http://www.ariadne.ac.uk/issue/12/public-libraries/](http://www.ariadne.ac.uk/issue/12/public-libraries/?ref=lorcandempsey.net)
**Electronic Libraries Programme: learning together.**
*Library Association Record*, 99(1), January 1997, p. 5.
**Kicking up the dust in a chaotic storehouse**.
*The Times Higher Education Supplement*, Multimedia section iv, October 11, 1996.
**Net use in public libraries**.
*Library Association Record*, 98(4), p.200\. (with Sarah Ormes).
**The public library and the Internet: a UK perspective.**
*Ariadne*, 2\. (with Sarah Ormes) (an adapted web version of ‘Net use in public libraries’ above)
**Readbites: the scandal of serials holding data**.
*Catalogue & Index*, number 118, Winter 1995\. p. 9.
**Road to resource discovery**.
*Library Association Record*, July 1995, 97(7), p. 374\. (with Debra Hiom and Frank Norman)
**The Nordic WAIS/WWW project**.
*Journal of Information Networking*, 1994, 2(2), 152-154\. (With Traugott Koch)
**Don's diary.**
*The Times Higher Education Supplement*
**Towards distributed library services: the importance of Z39.50.**
*Managing Information*, June 1994.
**American information infrastructure - part 2**.
*Computer Communications*. 14 (4), September 1991.
**American information infrastructure - part 1**.
*Computer Communications*. 14 (2), June 1991,258-259.
**Libraries, networks and OSI**.
*JUGL Newsletter*. Issue Number 3, Spring 1991,15-21.
**Entering new zones: some aspects of bibliographic access in Europe**.
*British Book News*, August 1989, .548-550.
---
### Directory
**Library bibliographic networks in Europe: a LIBER directory.**
2nd edition. The Hague: NBLC, 1992\. ISBN 9062520898
---
### Selected reports
**DLF Service Framework for Digital Libraries: A progress report for the DLF Steering Committee,** 17 May 2005
(With Brian F. Lavoie, on behalf of the DLF Service Framework Working Group.)
[https://old.diglib.org/architectures/serviceframe/dlfserviceframe1.htm](https://old.diglib.org/architectures/serviceframe/dlfserviceframe1.htm?ref=lorcandempsey.net)
**Full disclosure: releasing the value of library and archive collections:**
a report to the Pathfinding Group of the British Library, Library and Information Commission and the Library and Information Co-operation Council by UKOLN and the National Council on Archives on a national strategy for the retrospective conversion of library and archive catalogues
Bath: UKOLN, 1999\. (with Ann Chapman and Nick Kingsley)
(A report commissioned by the BL, LIC, and LINC).
[http://www.ukoln.ac.uk/services/lic/fulldisclosure/report.pdf](http://www.ukoln.ac.uk/services/lic/fulldisclosure/report.pdf?ref=lorcandempsey.net)
**The scientific, industrial and cultural heritage: a shared approach.**
Luxembourg: European Commission, DGXIII, 1999.
[http://www.ariadne.ac.uk/issue/22/dempsey/](http://www.ariadne.ac.uk/issue/22/dempsey/?ref=lorcandempsey.net)
**eLib standards guidelines.**
Version 2, 1998\. (with Brian Kelly, Ian Peacock, Anne Mumford, Alan Robiette, and Chris Rusbridge on behalf of JISC). (Editor and significant contributor)
[http://www.ukoln.ac.uk/services/elib/papers/other/standards/version2/](http://www.ukoln.ac.uk/services/elib/papers/other/standards/version2/?ref=lorcandempsey.net)
**Metadata formats: a review of current practice.**
Report prepared for review as part of EU project DESIRE. November 1996 (with Rachel Heery).
[http://www.ukoln.ac.uk/metadata/publications/jdmetadata/](http://www.ukoln.ac.uk/metadata/publications/jdmetadata/?ref=lorcandempsey.net)
**eLib standards guidelines** *.*
Version 1, Feb. 1996\. (with Anne Mumford, Alan Robiette, and Chris Rusbridge on behalf of FIGIT). (Editor and significant contributor)
[http://www.ukoln.ac.uk/services/elib/papers/other/standards/version2/](http://www.ukoln.ac.uk/services/elib/papers/other/standards/version2/?ref=lorcandempsey.net)
**Library and Information Commission public library Internet survey.**
1995\. (with Sarah Ormes).
[http://www.ukoln.ac.uk/services/papers/ukoln/ormes-1995-01/](http://www.ukoln.ac.uk/services/papers/ukoln/ormes-1995-01/?ref=lorcandempsey.net)
**Subject access to monograph records.**
A draft report presented to the BLR&DD, (with Jane Dacey, Steven Prowse, Stephen Walker), 1993.
**SuperJANET Project on Information Resources** (SPIRS): a study commissioned by the JNT, February 1993\.
(with the SPIRS working group, chaired by Michael Breaks).
**Currency with coverage - a survey report.**
London: MARC Users' Group, 1989\. ISBN 0-905463-08-0.
---
### Book reviews
**The History of Libraries in Modern 'Britain and Ireland**'.
Review of Alistair Black and Peter Hoare (eds). 2006\. *The Cambridge History of Libraries in Britain and Ireland*. Cambridge, UK: Cambridge University Press. Volume III, 1850-2000\. Ariadne, Issue 53, October 2007.
[http://www.ariadne.ac.uk/issue/53/maccoll-dempsey-rvw/](http://www.ariadne.ac.uk/issue/53/maccoll-dempsey-rvw/?ref=lorcandempsey.net)
**Net failings that drive the desire to be digital: a review of International Journal on Digital Libraries** *.*
*The Times Higher Education Supplement*, October 10, 1997\. Multimedia section VII.
**Public libraries of Europe: a review of the web site created by Sheila and Robert Harden.**
*Ariadne*, Issue 7, 1997.
**The Information Motorway: a review of the M25 Consortium web site** *.*
*Ariadne*, Issue 6, 1996.
**\[A review of\] Harries, Steve. Networking and telecommunications for information systems.**
London: Library Association Publishing. In: *Journal of Documentation*, September 1995.
**\[A review of\] Technological developments in library and information work:** proceedings of an Irish joint conference held 22-26 April 1991, in Newcastle, Co. Down. \[\]: The Library Association of Ireland; The Library Association: Northern Ireland Branch, 1992\.
In: *Journal of Documentation*, September 1993
**\[A review of\] OBN final report: from project to library users**. Leiden: Pica, 1993\.
In: *Program*, 27(3), 1993.
**\[A review of\] Impact of local systems on the national networking environment**: proceedings of the Library of Congress Network Advisory Committee Meeting, April 1-3, 1991\. Washington, DC: Library of Congress Network Development and MARC Standards Office, 1991\.
In: *Program*, 27(1), 1992.
**\[A review of\] Hagler, Ronald. The bibliographic record and information technology**. London: Adamantine Press, 1991\.
In*: Program*, 26(3), July 1992.
**\[A review of\] McClure, Charles et al. The National Research and Education Network (NREN): research and policy perspectives**. Norwood, NJ: Ablex Publishing Corporation, 1991\.
In: *Computer Communications*, 15(7), 1992.
## A note on the blog
Of particular note is my blogging activity. From 2004 to 2020 I actively blogged at my OCLC venue, at which point I transferred the content to here. A signal of the impact of this work is that ALA Publishing released a [book of the blog](https://blog.oclc.org/lorcand/book-of-the-blog/?ref=lorcandempsey.net) in 2014\.
Given the longevity and range of the blog, many topics have been briefly discussed there which have not been looked at in longer form writing.
I have been especially pleased at how concepts iterated in the blog have sometimes been taken up in library discourse ("in the flow", "discovery happens elsewhere", "collective collections", the "inside-out collection", the "facilitated collection", "making data work harder," "library logistics," the "[amplified conference](https://www.wikiwand.com/en/Amplified%5Fconference?ref=lorcandempsey.net)," "the network level," and others). I have tagged some posts which had particular resonance or introduced specific terms with '[classic](#/tag/classics).' The book was reviewed widely - I especially valued these comments by my compatriot ..
> His ability to operate instinctively in a networked and connected way is remarkable. He consistently lifts the intellectual level of debate above a simple wonderment with technology or communications. He explores, argues and persuades towards a movement from critical thinking to the next level where synthesis, and in some cases profound analysis, of complex systems leads to discovery and new ways of seeing things. Never afraid to level criticism where it is justified, Dempsey is equally passionate about defending his profession. // Rónán O’Beirne, Library and Information Research, Volume 39 Number 121, 2015.
I have ported the entries from the original blog over to this site .. for the moment I have a navigation label, [\*Orweblog](https://www.lorcandempsey.net/orweblog/), to highlight that.
## Selective writing themes
### Institutional and organizational
I am increasingly interested in the place of the library in its organizational setting - educational or civic - and the evolution of meanings it has for those communities.
In this context, we carried out some work with Ithaka S+R exploring the different emphases of universities, and discussing how the configuration of library services was influenced by their parent institution. The model of excellence for libraries should be plural, based on the nature of the support their institution needs. Drawing on this work, Constance Malpas and I wrote this article about academic library directions. I have been pleased to be told of its use in library planning and to prepare for library interviews!
[Academic Library Futures in a Diversified University SystemDempsey and Malpas consider the future of the academic library in the context of a diversifying higher education system. The academic library is not fixed. It is changing as it adapts to the changing...SpringerLinkAuthors and affiliations](https://link.springer.com/chapter/10.1007/978-981-13-0194-0%5F4?ref=lorcandempsey.net)
I thought I would note two reflective Ariadne pieces. One is an extended review article about the third volume of the *Cambridge History of Libraries in Britain and Ireland*. The first thing to note is the delicacy of creating a suitable title - Britain and Ireland, or Great Britain and Ireland, or the United Kingdom and the Republic of Ireland, or ... This piece has been little noted, but I enjoyed writing it and it touches on a range of historic, social and cultural interests.
[Book Review: The Cambridge History of Libraries in Britain and IrelandLorcan Dempsey reviews Volume III of a landmark collection on the history of libraries in ‘Britain and Ireland’ from 1850 to 2000.LorcanDempsey.netLorcan’s posts](https://www.lorcandempsey.net/book-review-the-cambridge-history-of-libraries-in-britain-and-ireland/)
The second is a narrative review of foundational digital library initiatives in the EU and UK, with some reflections on the US. I place this in the context of a high level historical survey of the development of these initiatives and some assessment of the utility of that type of top-down funded support.
[The (Digital) Library Environment: 10 years afterLorcan Dempsey considers how the digital library environment has changed in the ten years since Ariadne was first published.LorcanDempsey.netLorcan’s posts](https://www.lorcandempsey.net/the-digital-library-environment-10-years-after/)
### Collaboration and consortial activity
Working for Jisc and OCLC, I have always been interested in library collaboration. Where does it make sense to collaborate? This is an area which intriguingly underlines the mutual and evolving construction of policy and strategy, organizational configurations, and technological practice. An example is provided by our work with the BTAA. The BTAA is a research, learning and social powerhouse of mostly public universities centered in the American Midwest. Collectively, it has greater research capacity than the Ivy + group, and individually its universities are crucial engines of social and economic activity in their regions. The BTAA libraries recently declared their intention to manage their collections as a single unit, influenced by the report myself and colleagues Constance Malpas and Mark Sandler prepared.
[Operationalizing the BIG Collective Collection: A Case Study of Consolidation vs AutonomyPrepared in collaboration with the Big Ten Academic Alliance (BTAA) Library Initiatives, this report presents a framework for operationalizing the BTAA collective collection—a collection managed collaboratively across a network of libraries—and is focused specifically on the ”purchased” or print col…OCLCOCLC](https://www.oclc.org/research/publications/2019/oclcresearch-operationalizing-the-BIG-collective-collection.html?ref=lorcandempsey.net)
I offer some thoughts about this collaborative balance between autonomy and consolidation of operations within consortial settings in this piece in the *Journal of Collaborative Librarianship*, where I also reference a series of blog entries on this topic.
[What Collaboration Means to Me: Library collaboration is hard; effective collaboration is harderIn this short piece I argue that library collaboration is very important, so important that it needs to be a more deliberate strategic focus for libraries and the organizations that support them. This is especially so in a network environment, where scale is important in creating efficiencies and im…Digital Commons @ DULorcan Dempsey](https://digitalcommons.du.edu/collaborativelibrarianship/vol10/iss4/3/?ref=lorcandempsey.net)
### Collections
Collections are core to library identity and service, but have changed in interesting ways. Over the past few years I have been talking about three systemic ways in which collections, broadly understood, are evolving in a network environment. They are: the [collective](https://www.oclc.org/research/publications/2019/oclcresearch-operationalizing-the-BIG-collective-collection.html?ref=lorcandempsey.net)[collection](https://www.oclc.org/research/publications/2020/reflections-on-collective-collections.html?ref=lorcandempsey.net), the [facilitated](https://blog.oclc.org/lorcand/the-facilitated-collection-redux-a-note-on-collections-as-a-service-the-university-of-california-and-elsevier/?ref=lorcandempsey.net)[collection](https://www.liberquarterly.eu/articles/10.18352/lq.10170/?ref=lorcandempsey.net), and the [inside-out collection](https://www.liberquarterly.eu/articles/10.18352/lq.10170/?ref=lorcandempsey.net). In different ways, each moves beyond the carefully constructed and locally acquired collection.
I consider briefly how these directions are accelerated by pandemic effects in an extended blog entry. Libraries are also increasingly focused on optimizing collections against evolving requirements (online learning, or open access, for example) and on pluralizing collections, recognizing the ways in which they are entangled in dominant cultures and institutional settings, and trying to understand where to consciously de-center historically dominant perspectives.
[Collection directions accelerated? Pandemic effects.Over the past few years I have been talking about three systemic ways in which collections, broadly understood, are evolving in a network environment. They are: the collective collection, the facilitated collection, and the inside-out collection.LorcanDempsey.netLorcan’s posts](https://www.lorcandempsey.net/collection-directions-accelerated-pandemic-effects/)
Much of this work has been done with colleagues Brian Lavoie and Constance Malpas. Various of these strands are summarised in an article in *LIBER Quarterly*.
[Library collections in the life of the user: two directions | LIBER Quarterly: The Journal of the Association of European Research LibrariesCreative Commons LicenseAuthors Lorcan Dempsey OCLC, Dublin, OH, US](https://liberquarterly.eu/article/view/10870?ref=lorcandempsey.net)
Our work on collective collections was recently summarised in a contribution to *College & Research Libraries*.
[Reflections on Collective Collections | Lavoie | College & Research LibrariesReflections on Collective CollectionsCollege & Research Libraries05\_Lavoie\_etalBrian Lavoie, Lorcan Dempsey, and Constance Malpas\*](https://crl.acrl.org/index.php/crl/article/view/24618/32438?ref=lorcandempsey.net)
### Systems and services
I have tracked library discovery developments over the years. For most library users, discovery happens elsewhere, so I have been especially interested in locating library services within the broader environment of use. I contributed an extended introduction to this edited collection summarising recent trends and issues: [*Resource Discovery for the Twenty-First Century Library* (2020)](http://www.facetpublishing.co.uk/title.php?id=301386&ref=lorcandempsey.net#.XvtJ0ZNKhTY).
[Library Discovery DirectionsIn this foreword to the edited collection Resource Discovery for the Twenty-First Century Library (2020), Lorcan Dempsey traces shifting trends in the library discovery environment contributing to the diversified scope of resource discovery.OCLCOCLC](https://www.oclc.org/research/publications/2020/resource-discovery-twenty-first-century-library.html?ref=lorcandempsey.net)
Digital preservation seems to be emerging again more strongly as an area of attention. This piece with Brian Lavoie considers some general questions. It is quite old now, but many of the questions still seems relevant.
[Thirteen Ways of Looking at...Digital PreservationD-Lib Magazine](http://www.dlib.org/dlib/july04/lavoie/07lavoie.html?ref=lorcandempsey.net)
### The digital library and the network
Early digital library work had three strong emphases. The first was on repositories of content, thinking about actual discrete digital collections. The second was on the protocol frameworks for tying network components together - searching, federating, requesting, and so on. And the third was on the metadata frameworks that provided intelligence about what was available and about how it worked. In the earlier part of my career, I was very involved in the second and third of these.
A major contribution was *Libraries, networks and OSI,* a book length reportwhich documented the early impact of networks on library services in the US, ranging over collaboration, the early Internet, and applications for resource sharing, distributed searching, and so on. It provide an early lesson in marketing. OSI was the ISO protocol suite supported by the European Union and other governments. There was major work done to implement OSI library application protocols, which is described here. However, OSI soon became eclipsed by TCP/IP and the Internet stack. By the time the second edition was published by Meckler in the US, OSI was already on the way out. I should have just called it *Libraries and networks* or somesuch!
[Libraries, networks, and OSI (1992 edition) | Open LibraryLibraries, networks, and OSI by Lorcan Dempsey, 1992, Meckler in association with the UK Office for Library Networking edition, in English - 1992 ed.Open LibraryOpenLibrary.org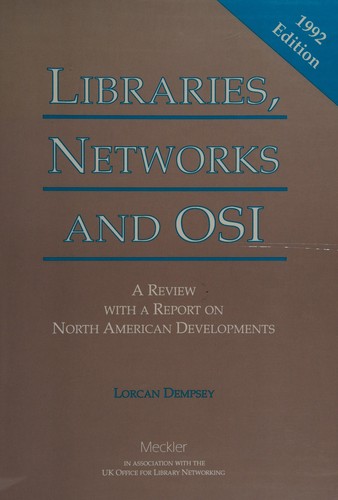](https://openlibrary.org/books/OL1544863M/Libraries%5Fnetworks%5Fand%5FOSI?ref=lorcandempsey.net)
> This is a wonderful book that we should thank Dempsey for writing and the British Library for supporting. (I do find myself thinking, parochially, that it is strange that the first real book on these topics has been written from a European perspective and underwritten by the British Library. The topics covered are terribly important to the library, information science, and networking communities. Why hasn't this type of book been written from a U.S. perspective?) // Clifford A. Lynch, The Public-Access Computer Systems Review 2, no. 1 (1991): 171-176.
The article that I wrote on metadata with the sadly deceased Rachel Heery remains my most cited (published in the more 'scholarly' *Journal of Documentation*). We reviewed the current state of the art of metadata in the library and related sectors, and discussed function and direction. We offered this definition of metadata which I still quite like: "metadata is data associated with objects which relieves their potential users of having to have full advance knowledge of their existence or characteristics. A user might be a program or a person."
[Metadata: a current view of practice and issuesthe University of Bath's research portalMetadata : a current view of practice and issues](https://researchportal.bath.ac.uk/en/publications/metadata-a-current-view-of-practice-and-issues?ref=lorcandempsey.net)
Finally, I note an area of considerable focus where I have come to have mixed feelings. Through the MODELS project (Moving to Distributed Environments for Library Services) we did quite a bit of work which influenced early UK nationally funded digital library work. It gave rise to some interesting vocabulary - 'clumps' for 'physical union catalogs' (as opposed to federated or 'virtual union catalogs') and 'discovery to delivery' (or discover, locate, request, deliver). A major focus was on reference models for library services, abstract characterizations of functional areas. We picked up this emphasis later in some work with the Digital Library Federation in the US. There is a balance between this kind of top down activity and more opportunistic or entrepreneurial work to identify and cater for emerging needs. I would now lean to the latter as a stronger engine of progress. Here is a rather prolix and long discussion of some of this work.
[A utopian place of criticism? Brokering access to network informationthe University of Bath's research portalA utopian place of criticism? Brokering access to network information](https://researchportal.bath.ac.uk/en/publications/a-utopian-place-of-criticism-brokering-access-to-network-informat?ref=lorcandempsey.net)
## Influences
My best career advice is to work with people who are smarter than you are. Over the years, I have benefited enormously from writing with colleagues. And some important collaborators recur in the list of publications.
I mentioned above that the professional nature of most of my writing means that it is not explicitly theoretical. However there are some important shaping influences and interests.
- Historically, Raymond Williams has been the thinker to whom I am most indebted, acknowledging that he may now seem antique to many. I hope some day to write about his [novels](https://www.goodreads.com/review/show/161342182?book%5Fshow%5Faction=true&from%5Freview%5Fpage=1&ref=lorcandempsey.net).
- As somebody Irish who has lived for significant periods in the UK and the US, and given our children's multiple affiliations, I am increasingly interested in questions of diaspora, migration, identity, (de)colonization.
- In recent years, a shaping background influence has been the emergence of sociotechnical thinking and the practice turn: services, organizational patterns and technology come into being through their mutual interaction. I have found the work of Wanda Orlikowski and colleagues especially suggestive. The distinction they make between technology-as-artifact and technology-as-practice is especially relevant to library discussions. It would be interesting to consider some library trajectories through the practice lens.
- My thinking about modernity is influenced by Castells, Giddens, Beck and others, and especially by writers on space and mobility (Massey, Lash/Urry, Creswell, Thrift, Harvey, ...). I return to those modern classics by Benjamin and Benedict Anderson occasionally.
- Libraries are organizations in a richly interconnected organizational ecosystem and I believe have something to learn from organizational behavior and economics. Work stemming from Coase is clearly relevent here, as we think about what libraries internalise as opposed to externalise to vendors or to cooperative arrangements.
[Memory institutions redux: pluralizing memories and a stay against forgettingWe are now used to memory institutions as a way of collectively referring to libraries, archives and museums. We also recognize that memory is not univocal or may be contested.LorcanDempsey.netLorcan Dempsey](https://www.lorcandempsey.net/memory-institutions-redux/)
A note on how memories and collecting are entangled
---
## A note on open access
Not subject to the academic pressure to publish, or to cultivate citations, I have often published in response to invitation, have contributed much as technical reports outside of the journal literature, and have favored open access channels. I have usually tried to ensure that an openly accessible version is available. It is interesting to see which of those copies has persisted.
Importing the list of publications above, I was also reminded how much I had published in *D-Lib Magazine* and *Ariadne Magazine* (which I co-founded), each an important record of early programmatic work in digital libraries, in the US and UK respectively. Of course, neither continues as an active publication, which itself is a comment on early web activity (and the diamond access path to publication).
An occasional theme in my presentations and panel discussion has been the library community's own practice in relation to open access. It makes sense to model the practice one would like to see elsewhere, so I think that we should be especially focused on the structure and availability of our own literature.
**Picture:** My son, Eoghan, created the feature picture.
### about lorcan
URL: https://www.lorcandempsey.net/about/
Last updated: 2025-11-02T22:19:11.000Z
## Brief bio
Lorcan Dempsey is a librarian who has worked for library, non-profit and educational organizations in Ireland, the UK and the US. His influence on library directions in the US, Europe and around the world is widely recognized. He has overseen national library and informational programs in the UK and has managed two internationally recognized library R&D units (UKOLN and OCLC Research). He has worked on pioneering network information systems, has overseen a variety of membership and governance activities, and has been responsible for national and international operational services.
Lorcan was recently **Professor of Practice* and **Distinguished Practitioner in Residence* at the Information School, University of Washington (a two year engagement). He worked for over twenty years at OCLC, a global library services organization and before this he worked for national educational infrastructure and innovation organization, Jisc, in the UK. He began his library career in public libraries in Dublin, Ireland, where he grew up.
He has been awarded an honorary doctorate by the Open University in the UK, the IFLA Medal, the Miles Conrad Award, and other honors in recognition of his contribution to library development around the world. He was very pleased to have his work acknowledged by a special award from the Library Association of Ireland.
## Long Bio
There is a little more formal career stuff elsewhere:
[long bioSince I first began working in Dublin public libraries I have always been motivated by mission and impact.LorcanDempsey.netLorcan Dempsey](https://www.lorcandempsey.net/cv/)
[Lorcan Dempsey - WikipediaWikimedia Foundation, Inc.Contributors to Wikimedia projects](https://en.wikipedia.org/wiki/Lorcan%5FDempsey?ref=lorcandempsey.net)
Summary: more a 🦊 than a 🦔.
## Web coordinates
You can find me on the web in the usual places:
[](https://www.linkedin.com/in/lorcand?ref=lorcandempsey.net) [](https://twitter.com/lorcand?ref=lorcandempsey.net) [](https://www.facebook.com/lorcand) [](https://www.youtube.com/channel/UCyjqIYJBSCr8ZGKZUfyKNcg?ref=lorcandempsey.net)
And here are some scholarly venues:
[ ](https://figshare.com/authors/Lorcan%5FDempsey/10018391) [ ](https://scholar.google.com/citations?user=rOEEU4wAAAAJ&hl=en) [ ](https://orcid.org/0000-0002-2925-8764) [ ](https://www.semanticscholar.org/author/Lorcan-Dempsey/145368307) [ ](https://www.worldcat.org/search?q=lorcan+dempsey)
## Get in touch
I am always interested in hearing from colleagues about potential collaboration. Check out the [contact page](https://www.lorcandempsey.net/contact/) if you would like to get in touch.
[personal coordinatesget in touch!LorcanDempsey.netLorcan](https://www.lorcandempsey.net/contact/)
## Pictures


##
### Authors
URL: https://www.lorcandempsey.net/authors/
Last updated: 2022-11-07T02:19:42.000Z
_No content available._
### speaking
URL: https://www.lorcandempsey.net/presentations/
Last updated: 2026-06-18T01:49:21.000Z
My contact details are here if you would like to discuss a speaking opportunity.
[ContactDrop me a note here if you would like to get in touch. Email works too. You can also reach me in the usual ways: \* \* \* \* Check the About page for a brief bio, pictures and other details: LorcanDempsey.netWelcome!…LorcanDempsey.netLorcan](https://www.lorcandempsey.net/contact/)
I include slides and videos of some presentations below. Slides are often a poor record of a presentation, especially when used as prompts rather than as full records. But they can be useful. Of course, I will sometimes give various evolving versions of a similar presentation.
I also include some videos, although I cannot bear to watch myself in rerun!
## Recent slides on figshare
[ So-called soft skills are hard: CILIP K&IM SIG AGM This is a presentation to the AGM of the Knowledge and Information Management group of CILIP, the UK Library and Information Association. It discusses how so-called soft skills are at the core of information work.  figshare  ](https://doi.org/10.6084/m9.figshare.32720757?ref=lorcandempsey.net)
Knowledge and Information management Group of CILIP AGM, Online, 6 June 2026\.
[ Librarianship, information & education Librarianship, information and education — each of these words is complicated by social and technological reconfigurations. This presentation considers the educational demands of the relational library, the floating contexts of information, and the university as a research and education partner of the library in its institutional and organizational fullness. Delivered in the Bobinski Lecture Series, Dept of Information Science, Graduate School of Education, University at Buffalo, 23 April 2026.  figshare figshare  ](https://figshare.com/articles/presentation/Librarianship%5Finformation%5Feducation/32232000?ref=lorcandempsey.net)
Bobinski Lecture Series, University at Buffalo, 23 April 2026.
[Libraries, librarianship and cross-lamination: notes on education and career preparation for librariesThis presentation was the keynote at the Charleston Conference. It discusses the education and career preparation of libraries. It discusses the current library service environment, the broad contours of current library education, and notes some gaps and challenges. It concludes with three recommended areas for attention by the organizations which represent library and library education interests. Given the rapidly evolving social and political environment it suggests that libraries should find collective ways of influencing and assisting in the preparation of many of those who come to work in libraries.figshare](https://figshare.com/articles/presentation/Libraries%5Flibrarianship%5Fand%5Fcross-lamination%5Fnotes%5Fon%5Feducationa%5Fand%5Fcareer%5Fpreparation%5Ffor%5Flibraries/30670526/2?ref=lorcandempsey.net)
Charleston Library Conference Keynote, 5 November 2025.
[Libraries, AI and directions: 3 directionsOnly two years in and AI is everywhere. This presentation looks at AI and libraries from three perspectives, as a way of framing some of the drivers, developments, and concerns. These are 1\] a cultural technology perspective, 2\] an industry perspective, and 3\] a library policy/practice perspective.figshare](https://figshare.com/articles/presentation/Libraries%5FAI%5Fand%5Fdirections%5F3%5Fdirections/27859323?file=50640561&ref=lorcandempsey.net)
Canadian Association of Research Libraries members' meeting, Ottawa, 19 November 2024.
[Libraries, AI And The Messy MiddleThis presentations discusses a variety of issues around AI and its adoption in libraries.figshare](https://figshare.com/articles/presentation/Libraries%5FAI%5FAnd%5FThe%5FMessy%5FMiddle/25974283?file=46828723&ref=lorcandempsey.net)
Versions of this presentation were given at the Vancouver Island Staff Library Conference, University of Victoria, 3 May 2024, and at the California AI Libraries Summit, California State Library, Sacramento, 26 April 2024\.
[From collections to community: libraries and the relational turnA presentation to Chalmers University Library colleagues. The library is repositioning itself on campus as a partner in supporting research and learning across the whole life cycle. Discusses various ways in which this manifests itself. While collections remain central, they are also changing in imp…figshare](https://doi.org/10.6084/m9.figshare.24428293.v1?ref=lorcandempsey.net)
Chalmers University Library, October 24 2023
[Towards the relational libraryA brief presentation outlining some academic library directions, as they transition from a collections-focused library to a relational one. It was delivered on the occasion of University of Washington celebration of library/iSchool collaboration.figshare](https://doi.org/10.6084/m9.figshare.24295468.v1?ref=lorcandempsey.net)
University of Washington, Allen Collaboration Celebration, October 12 2023
[Collection directions and the relational libraryA presentation at the University of Kentucky Libraries. Outlines transition from ‘collections-based’ library to the relational library. Discusses trends with collections in this context. Talks about collective collections, facilitated collections, and inside out collections. Also discusses how colle…figshare](https://figshare.com/articles/presentation/Collection%5Fdirections%5Fand%5Fthe%5Frelational%5Flibrary/23734362?ref=lorcandempsey.net)
University of Kentucky Libraries, 20 July 2023
[Consortial observations: Orbis Cascade Alliance retreatA presentation to the Orbis Cascade Alliance. Discusses some dynamics of library consortia, some factors involved in developing ‘one collection’, and other shared service areas.figshare](https://figshare.com/articles/presentation/Consortial%5Fobservations%5FOrbis%5FCascade%5FAlliance%5Fretreat/23734353?ref=lorcandempsey.net)
Orbis Cascade Alliance retreat, Ashland, Oregon, 13 July 2023
[The academic library and the relational turnLibraries have transitioned from collections to services. We are now seeing another transition, as the relational turn becomes important. The library is positioned in a dense network of partnerships, services, and interactions, and evolves in coordination with its users. This is especially important…figshare](https://figshare.com/articles/presentation/The%5Facademic%5Flibrary%5Fand%5Fthe%5Frelational%5Fturn/23503857?file=41221680&ref=lorcandempsey.net)
AMICAL 2023, 24–26 May‘23, Al Akhawayn University, Ifrane, Morocco.
[Evolving library discovery: 10 directionsLibrary discovery layers are now mature, constructed from commodity systems and data. However, if one thinks about discovery practice and requirements there are many areas that remain underserved. This presentation discusses 10 gaps in how we think about discovery, and suggest some steps that wou…figshare](https://figshare.com/articles/presentation/Evolving%5Flibrary%5Fdiscovery%5F10%5Fdirections/22213861?ref=lorcandempsey.net)
Seminari de l'Aula Jordi Rubió i Balaguer, University of Barcelona, 28 Feb 2023
[Workflow is the new content: presentation at the digital initiatives symposium, U of San DiegoThe digital environment makes workflow support more important, as activities, content, and communications are tied together on the network in various combinations. Think of the interesting mix of social and functional capacities in an application like Strava, used by athletes to track activity and…figshare](https://figshare.com/articles/presentation/Workflow%5Fis%5Fthe%5Fnew%5Fcontent%5Fpresentation%5Fat%5Fthe%5Fdigital%5Finitiatives%5Fsymposium%5FU%5Fof%5FSan%5FDiego/20288676?ref=lorcandempsey.net)
Digital Initiatives Symposium. University of San Diego, 25 April 2022.
[One score and then: systemwide library contexts. Closing plenary address, CNI San Diego, 29 March 2022.A discussion of 20 years of academic library issues in the US from a personal perspective.figshare](https://figshare.com/articles/presentation/One%5Fscore%5Fand%5Fthen%5Fsystemwide%5Flibrary%5Fcontexts%5FClosing%5Fplenary%5Faddress%5FCNI%5FSan%5FDiego%5F29%5FMarch%5F2022%5F/20288682?ref=lorcandempsey.net)
One score and then: systemwide library contexts. Closing plenary address, CNI San Diego, 29 March 2022.
[Collection DirectionsThis is a presentation presented at Informatie aan Zee in Belgium and in modified form at Bibliostar in Italy. It discusses some Pandemic Effects and how various collections trends are being affected.figshare](https://figshare.com/articles/presentation/CollectionDirectionsOstendeBibliostar%5Fpptx/17001154?ref=lorcandempsey.net)
Presented at both: Informatie aan Zee 2021, Ostende, 14 October 2021 and Bibliostar Stelline Conference, Milan, 29 September, 2021
[College, consortium, collaboration, collective collectionA presentation to the Board of Directors of Boston Library Consortium. Although library collaboration is common and many libraries collaborate through many organizations, it is a relatively unexamined aspect of library work. Many descriptions exist, but little from the point of view of organization …figshare](https://figshare.com/articles/presentation/College%5Fconsortium%5Fcollaboration%5Fcollective%5Fcollection/13669619?ref=lorcandempsey.net)
Boston Library Consortium Board of Directors, 4 December 2020 (with Constance Malpas)
[Pandemic effects and collection directionsBeyond the scramble of the current situation, universities will be looking at long term pandemic effects. This clearly has implications for libraries, as they cleave more closely to university strategies. This presentation looks at some pandemic effects, and considers how it will likely accelerate s…figshare](https://figshare.com/articles/presentation/Pandemic%5Feffects%5Fand%5Fcollection%5Fdirections/13670698?ref=lorcandempsey.net)
Opened the RLUK Digital Shift Forum, 30 October 2020\.
[Collection directions, collaboration, and pandemic effectsThis presentation discusses how libraries are optimizing and pluralizing their collections for an increasingly online post-pandemic environment. Versions were presented at the Mobius Annual Conference (1 June 2020) and the Orbis Cascade Webinar (17 June 2020).figshare](https://figshare.com/articles/presentation/Collection%5Fdirections%5Fcollaboration%5Fand%5Fpandemic%5Feffects/13670713?ref=lorcandempsey.net)
Versions presented to both Mobius Annual Conference, 1 June 2020, and OrbisCascade Alliance, 17 June 2020.
[Rediscovering discovery: three general examplesThis presentation describes three trends in library discovery, tying them to broad pandemic effects. It was presented in a panel at the CNI Spring 2020 meeting.figshare](https://figshare.com/articles/presentation/Rediscovering%5Fdiscovery%5Fthree%5Fgeneral%5Fexamples/13670710?ref=lorcandempsey.net)
CNI Spring Meeting, 21 May 2020\.
[Library consortia: scale, opportunity, challengeThis presentation describes some of the dynamics, challenges and opportunities for consortia. It was presented at the ICOLC meeting in Vancouver (8 April 2019).figshare](https://figshare.com/articles/presentation/Library%5Fconsortia%5Fscale%5Fopportunity%5Fchallenge/13670719?ref=lorcandempsey.net)
ICOLC meeting, Vancouver, 8 April 2020\.
[Operationalizing the collective collection: a case study of consolidation vs autonomyThis a presentation about operationalizing the collective collection. It focuses some of the decisions and frameworks that could underlie deployment of a shared approach. It is based on work done in partnership with the BTAA.figshare](https://figshare.com/articles/presentation/staffbtaa%5Fpptx/13624088?ref=lorcandempsey.net)
BTAA ILL Coordinators meeting, U Minnesota, 25 October 2019\.
[The Irish presence in the published recordUses the pattern of global library holdings as represented in WorldCat to explore the characteristics of the Irish published record. The most popular works and authors. It is an example of distant reading.figshare](https://figshare.com/articles/presentation/The%5FIrish%5Fpresence%5Fin%5Fthe%5Fpublished%5Frecord/13670767?ref=lorcandempsey.net)
CONUL Annual Conference, Athlone, Ireland, 30/31 May 2017.
## Recent videos
Libraries, librarianship, and cross-LAMination: notes on education and career preparation for librarians. Charleston Library Conference Keynote, 5 November 2025.
[GMT20240904-180801\_Recording\_1920x1080.mp4Google Docs](https://drive.google.com/file/d/1FsyGsLL0%5F9aD0AuggPMne57eOo5wH5O5/view?ref=lorcandempsey.net)
Libraries, AI and the messy middle. Presentation at the Center for Advances in Libraries, Museums and Archives, September 4, 2024\. Information School, University of Washington.
AMICAL 2023, 24–26 May‘23, Al Akhawayn University, Ifrane, Morocco. Some reflective issues on screen. Changed mike a few minutes in.
Seminari de l'Aula Jordi Rubió i Balaguer, University of Barcelona, 28 Feb 2023
One score and then: systemwide library contexts. Closing plenary address, CNI San Diego, 29 March 2022.
Presented at both: Informatie aan Zee 2021, Ostende, 14 October 2021 and Bibliostar Stelline Conference, Milan, 29 September, 2021
Opened the RLUK Digital Shift Forum, 30 October 2020
CNI Spring Meeting, 21 May 2020.
**Note on slide presentation:** I debated whether to use Slideshare or figshare to present slides. Slideshare seemed to peak a while ago. I don't know why it did not last within the Linkedin family and we will see what Scribd do with it now that they own it. It has the advantage of a somewhat more easy to use embed feature. However, it is also a little forlorn in appearance and clearly has not received a lot of development effort in recent times. figshare, of course, is a very different type of service in terms of scope and demographic. It also has quite a new feel. I thought I would go with it for a while, although I am not embedding the view. I think clicking through to figshare is a better experience.
**Updated note on slide presentation (9 March 2023):** Slideshare is indeed much improved from a UI and experience point of view. However, YouTube-style, there are ads imposed periodically in the slide show so I have not gone back to it. Figshare does not do a great job with the formatting. Apparently it uses Office Libre to render the presentations, so in a call to support they advise using PDF for presentations. Sort of defeats the purpose? Of course, as one is not a paying customer in either case there will be a compromise.
### About the Blog
URL: https://www.lorcandempsey.net/about-2/
Last updated: 2020-08-07T20:51:24.000Z
This blog was developed as an internal communications vehicle and externalized after a year or so in October 2004\. Naturally, its interests relate closely to those of OCLC Research generally.
How do libraries serve network people? How are library organization, services and technologies co-evolving with the behaviors of their users? It looks at library logistics, collaborative sourcing, the collective collection, and evolving metadata and bibliographic practices. It is also interested in how libraries support changing research and learning needs, and on how the curatorial traditions of archives, libraries and museums come together in the digital environment.
### About Lorcan Dempsey

Lorcan is the Chief Strategist and VP, Membership & Research, OCLC.
He has worked for library and educational organizations in Ireland, the UK and the US. His influence on national policy and library directions is widely recognized.
In 2010 he received the National Federation of Advanced Information Services’ (NFAIS) highest award, The Miles Conrad Award. He is an honorary Doctor of the Open University in the UK and has twice received an ALCTS Presidential Citation for his work with OCLC colleagues. Lorcan began his career in public libraries in his native Dublin, Ireland. Before moving to OCLC, he managed the UK higher education national investment in information services for Jisc. He is a member of the Cambridge University Library Visiting Committee.
On Twitter he is @LorcanD
#### Publications
- [Selected](https://www.oclc.org/research/publications.dempsey-lorcan.html?ref=lorcandempsey.net)
#### Presentations
- [Selected recent presentations](https://www.oclc.org/research/presentations.dempsey-lorcan.html?ref=lorcandempsey.net)
#### WorldCat Identity
- [Lorcan Dempsey](https://worldcat.org/identities/lccn-n90-602202?ref=lorcandempsey.net)
### Lorcan Dempsey
URL: https://www.lorcandempsey.net/homepage/
Last updated: 2026-01-26T04:52:23.000Z
Hi ... I am a librarian, analyst, and adviser. I have worked with groups of libraries to develop shared programs, products and directions. I have been very lucky to work for library, educational, and non-profit organizations in Ireland, the UK, the EU and the US.
I am currently based in Columbus, [Ohio](https://www.lorcandempsey.net/ohio/). I grew up in Dublin, Ireland, and [worked](https://www.lorcandempsey.net/letter-to-an-lis-graduate-student/) for many years in the UK before coming to the US.
I recently [served](https://ischool.uw.edu/news/2025/06/lorcan-dempsey-leaves-mlis-students-ready-tackle-tough-issues?ref=lorcandempsey.net) as the *Professor of Practice* and *Distinguished Practitioner in Residence* at the Information School, University of Washington.
Explore my reflections about the evolution of libraries in their social and cultural contexts in these pages. And you can check out a little more about me [here](https://www.lorcandempsey.net/about/) and in more detail [here](https://www.lorcandempsey.net/cv/). I regularly [write](https://www.lorcandempsey.net/writing/) and [speak](https://www.lorcandempsey.net/presentations/) about libraries and their social contexts.
Please [get in touch](https://www.lorcandempsey.net/contact/) if you would like to discuss shared interests. And sign up to follow along!
### Topics
URL: https://www.lorcandempsey.net/tags/
Last updated: 2022-11-07T01:59:48.000Z
_No content available._
### the deep archive
URL: https://www.lorcandempsey.net/archive/
Last updated: 2025-01-03T21:37:25.000Z
_No content available._
### Membership
URL: https://www.lorcandempsey.net/membership/
Last updated: 2023-01-30T06:51:20.000Z
**Why join?**
A couple of reasons. Members can comment on posts and members can receive updates when significant new content is added. Sign up to join. You can then opt in to receive updates. Once you are a member, you need to sign in if you wish to comment. This is to reduce spam.
The system stores your details in a minimal profile, which you can review/edit if you are signed in.
**Privacy**
The site does not use passwords. It uses an email-based approach. So no passwords are stored.
No personal details are stored beyond provided email and name. LorcanDempsey.net will use these only for the purposes described above (updates and comment management) and will not share with anyone.
This site is hosted on Ghost using Ghost software. The software is open source and open to inspection. The organization is a not for profit funded entirely from user fees. The Ghost position on security and privacy is described here:
[Ghost Security & PrivacyGhost is committed to developing secure, reliable products utilising all modern security best practices. Find out more about Ghost security and privacy.Ghost - The Professional Publishing Platform](https://ghost.org/docs/security/?ref=lorcandempsey.net)
### ⁂ thanks for joining! ⁂
URL: https://www.lorcandempsey.net/welcome/
Last updated: 2024-05-06T13:46:53.000Z
****Welcome!** Do leave a comment on a post or get in touch. I don't post a huge amount so you will not be overwhelmed by email from me.
Now that you are here, here are some overview pages on writing and work.
[ContactYou can reach me in the usual ways: You can also send me a note using this form: Check the About page for a brief bio, pictures and other details: LorcanDempsey.netWelcome! This is a place to bring together my work on library services and di…LorcanDempsey.netLorcan](https://www.lorcandempsey.net/contact/)
[Summary LorcanHi! Brief bio, contact details and pics below, together with links to fuller info. Get in touch!LorcanDempsey.netLorcan](https://www.lorcandempsey.net/about/)
[Reflecting life and career: Advice to an LIS graduate studentWhat do I value about libraries? asked a student. What is essential for a library student to know? Here are several ways in which life experiences have influenced my views.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/letter-to-an-lis-graduate-student/)
A post reflecting on advice to somebody starting their library career, which leans on personal experience more than most.
[Selected publications - Lorcan DempseyI have written widely over the years. Topics have evolved, but follow a general chronological arc from the technical, through the description of evolving digital systems and services, to organizational and institutional issues.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/writing/)
A pretty full list of publications with a commentary on themes of interest.
And as a starter, here are some posts about topics of special interest or with which I am associated.
[Collection directions accelerated? Pandemic effectsOver the past few years I have been talking about three systemic ways in which collections, broadly understood, are evolving in a network environment. They are: the collective collection, the facilitated collection, and the inside-out collection.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/collection-directions-accelerated/)
Discusses collective collections, inside out collections and the facilitated collection with links to other writings.
[The powers of library consortia 1: how consortia scale capacity, learning, innovation and influenceLibraries and related organizations group together in a variety of ways to get their work done. They consort where there are scale advantages: to lobby, for example, to negotiate and license, to reduce costs, or to build shared infrastructure.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/the-powers-of-library-consortia-1-how-consortia-scale-capacity-learning-innovation-and-influence/)
The first in a series of posts on library collaboration. Discusses the balance between autonomy and efficient working and issues of collective action.
[Memory institutions redux: pluralizing memories and a stay against forgettingWe are now used to memory institutions as a way of collectively referring to libraries, archives and museums.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/memory-institutions-redux/)
A discussion of memory and forgetting and the role of memory institutions.
### colophon
URL: https://www.lorcandempsey.net/colophon/
Last updated: 2026-06-07T19:24:01.000Z
This site has been in continuous operation since 2003\. It has moved platforms several times.
## Current platform
This site is currently built on the Ghost platform using the *Tuuli* theme from Biron themes. I mostly inherit typographic and layout design choices from the theme, although I have customized it, uninformed by any very well-developed design knowledge.
However, I have certainly enjoyed swapping fonts in and out and I have become more interested in fonts and font choices – in a very non-initiate way – since moving to Ghost (see my discussion of [Ghost](https://www.lorcandempsey.net/working-with-ghost/) and of [fonts](https://www.lorcandempsey.net/national-libraries-and-fonts/)). Of course, I am not doing anything very elaborate with them, as I am staying within the design canvas of the reasonably simple blog structure.
## Current fonts
I talk about the fonts industry and ecosystem in a longish blog post, [**Font choices, values and ecosystem, with some national library examples*](https://www.lorcandempsey.net/national-libraries-and-fonts/). While I was working at the University of Washington iSchool I qualified for educational discounts on fonts which are offered by some foundries. I would note especially the very generous deals offered by Nan and ABC Dinamo. I also benefited from the site license to Adobe Fonts. I have sometimes licensed fonts on Future Fonts, the interesting platform where works in progress are made available at pre-commercial prices. I am interested that more foundries don't have license prices geared towards the solo non-commercial user. Perhaps it is not a big enough market, and the cost per customer might be too high? Seems like a small miss, though.
I have adapted the theme to more easily cycle through different font combinations, and tend to change them frequently.
## Platform history
This blog began in 2003 on Typepad. It was eventually moved to an internal instance of WordPress at OCLC where I worked, and then to a hosted WordPress at [Libchalk](https://libchalk.com/?ref=lorcandempsey.net). It now has over 1900 entries together with associated material. With the heroic assistance of Brian Pichman of Libchalk, I moved it to Ghost in 2021\. There are occasional glitches in older entries, with some images, and unfortunately we lost the comments.
## Coda
I write about the font ecosystem with some example references to choices made by National Libraries here:
[Font choices, value and ecosystem. National Library examplesTypefaces and fonts are functional. However they also contribute in other ways - to brand, to atmosphere, to feeling. This is a brief introduction to aspects of the typeface ecosystem. I combine this with some commentary about how typefaces are used in national libraries to provide context.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/national-libraries-and-fonts/)
Here is a rather long and ponderous review of Ghost written a while after I moved to it. I should do another, now that I have more experience.
[Working with the Ghost blogging platform: a reviewThis site is built with Ghost and the Krabi template. I use it for blogging and as a professional home on the web. Why Ghost? Here are some initial thoughts. Ask me again in a year’s time .LorcanDempsey.netLorcan](https://www.lorcandempsey.net/working-with-ghost/)
**Updated:** 19 November 2025.
##
## Posts
### The informational disciplines
URL: https://www.lorcandempsey.net/the-informational-disciplines/
Last updated: 2026-03-11T00:58:57.000Z
This is an ****excerpt** from a longer contribution I made to **Responses to the LIS Forward Position Paper: Ensuring a Vibrant Future for LIS in iSchools.* \[[pdf](https://digital.lib.washington.edu/researchworks/bitstreams/5fb927cc-c3a4-4198-bf04-e3601107308f/download?ref=lorcandempsey.net)\] It is a sketch only, and somewhat informal, but I thought I would put it here in case of interest. It occasionally references the position paper, and the longer piece of which it is a part. It is also influenced by the context in which it was prepared which was a discussion of the informational disciplines and the iSchool in R1 institutions.
This section could of course be much expanded in a fuller treatment. It is striking to me how much LIS and Information Science can still reference different intellectual, disciplinary or institutional boundaries depending on context.
If you wish to reference it, I would be grateful if you cite the full original: Dempsey, L. (2025). Library Studies, the Informational Disciplines, and the iSchool: Some Remarks Prompted by LIS Forward. In LIS Forward (2025) **Responses to the LIS Forward Position Paper: Ensuring a Vibrant Future for LIS in iSchools, The Friday Harbor Papers, Volume 2*. \[[pdf](https://doi.org/10.6069/F6CQ-H317?ref=lorcandempsey.net)\]
This informational diffusion has given the iSchool great latitude and it can accommodate a great diversity of disciplinary lenses – from the very technical, to the social sciences and humanities, to design, to marketing and communication, to public policy, to critical theory, and so on. The Deans’ interviews suggest that this is at once a great strength and a potential weakness, as the iSchool does not have exclusive ownership of a foundational discipline, but rather a multidisciplinary focus on a hard to define phenomenon. Furthermore, this phenomenon has become an object of study in many other disciplines also.
In this section I discuss the informational disciplines (sic), LIS and Information Science, and conclude with some comments about Library Studies, LIS and the iSchool.
## Informational disciplines
### Library studies
First, here is a brief note on LS. Buckland (2005) traces the emergence of ‘library science’ to Martin Schrettinger in the early 19th century. The first American library school was opened by Melvil Dewey at Columbia in 1887\. Unsurprisingly, a central focus of each of these figures is organization of the collection.
In general, the ‘library school’ has not been a story of optimism and growth. Some closed. Many changed their name to lose ‘library.’ Some were merged into other schools or departments, with various disciplinary emphases.
There is now some variety of provision across types of university and disciplinary configuration. It is common within iSchools who have a library focus to use the term LIS.
### Information science(s)
What is Information Science or the Information Sciences? It seems to me that one can identify two very provisional emphases here to help scaffold a discussion. The first is in terms of the emergence of Information Science in the mid twentieth century, with a set of shared concerns, intellectual and personal influences, and professional venues. I label this Information Science Classic in this section, and this is what I usually mean when talking about Information Science (IS). The second is more generic, as Information Science or Information Sciences (or Informatics) is used as a designation of convenience for an academic interest in a range of information-related topics, with or without any specific reference to or acknowledgement of Information Science Classic. We see this emphasis in various places, including in some of the iSchools with non-Library Studies backgrounds (see Cornell or Penn State for example). This may sometimes be used to designate an applied technology focus with more of a social or business dimension than you might typically find in Computer Science.
How many on campus outside the iSchool, I wonder, would have any sense of Information Science Classic? How often would Information Science simply be read in the more generic second way? If you read a page of iSchool faculty interests would anything identify information science distinctively? It would be interesting to explore this further.
#### Information science – classic
> As long as the “discipline” is the primary unit of differentiation in the social system of scholarship, it is only strategic for information science to claim its status as one.” // Petras, V. (2024). The identity of information science. *Journal of Documentation*.
> \[Information science\] is a somewhat battered and in some ways disoriented field. // Ian Cornelius (1996). *Meaning and Method in Information Studies.*
> Thus, our second major finding, already conveyed, is that information science lacks a strong central author, or group of authors, whose work orients the work of others across the board. The field consists of several specialties around a weak center.// White, H. D., & McCain, K. W. (1998). Visualizing a discipline: An author co-citation analysis of information science, 1972–1995.
> We may therefore conclude that information science is an unclear label (a floating signifier) and that there is a great need for clarification and for improved terminological hygiene. // Hjørland, B. (2018). Library and Information Science (LIS), Part 1.
> In this final chapter we give an overview of some ideas about the future of the discipline and profession of information science. This has been a source of debate almost since the beginnings of the discipline, and of its sibling, library science. Much of the debate has been negative, with a narrative around disciplines and professions permanently in crisis. And, indeed, if one worries about the structure of academic departments and the names of professional associations one might find cause for concern. If one takes a long view and thinks \[…\] about the power of recorded information and the continuing need for disciplines and professions to deal with it, the concerns come into better focus. // Bawden and Robinson (2022). *Introduction to Information Science.*
> We can see three different, though not incompatible, places for information science in the changing academic firmament. One is a closer alignment with the informatics and data science areas; this is essentially the route taken by the ischools movement. Another is an alignment with media, communications, journalism, publishing and similar subjects. A third is an alignment with cultural studies and the digital humanities. Examples of all three can be seen, and all seem to be viable. It is important, however, not to choose one of these and declare that this is the future of the information sciences. They, and others which will emerge in the future, are simply aspects of the multidiscipline, emhasising different perspectives on the central focus of documents and the human record. // Bawden and Robinson (2022). *Introduction to Information Science.*
We can identify IS Classic as an academic interest with practical applications which emerged in the mid twentieth century as a response to the increasing volumes of scientific, technical and other information. A historical perspective locates this in the interests of special librarianship, of the documentalist movement in Europe (Otlet et al), and of various scientific and technical approaches to the management of growing information resources (Bush, Bradford, Garfield, and so on).
There is an extensive literature seeking to define what is meant by Information Science. Much of this is summarized in Bawden and Robinson (2022), seen as a definitive, if belated, description of the field. Indeed, White and McCain (1998) noted the lack of a definitive textbook when they were writing at the turn of the century. See Furner (2015), Buckland (2012), Bates (2015), and, recently, Petras (2024), for example contributions.
Definitions often emphasize recorded information, or documents in Buckland’s terms, rather than some of the broader social and cultural dimensions discussed above. Robinson and Bawden’s textbook defines it as a ‘field of study, with recorded information and documentation as its concern, focusing on the components of the information chain, studied through the perspective of domain analysis.’ Bates discussed recorded information and the influential analysis of White and McCain talks about ‘literature systems.’ For Petras, Information Science is also about objects (manifested information) but adds an interesting temporal dimension: ‘Information Science is concerned with how information is manifested across space and time.’
What is striking about this literature is how often it comes back to first principles, and also how the ‘field’ seems less a cumulating, coherent discipline than a set of topical emphases (for example, theoretical information retrieval, quantitative views of the literature, and information seeking behaviors). It can seem like a collection of variably related interests in pursuit of a discipline. Indeed, as the Report mentions, White and McCain (1998) identified two main subdisciplines in their early analysis (information retrieval and citation analysis), and notes their relative independence of each other. Marcia Bates (2022) and others would add information seeking behavior as a third emphasis. Of course, looking across LIS one can identify a variety of additional emphases. Some of this work is summarized in Järvelin, K., & Vakkari, P. (2022).
As late as 2022, Bates, a major figure in the field, was proposing a theory of Information Science, and calling for the various emphases to be finally integrated “into a true disciplinary - not interdisciplinary - a true *disciplinary* paradigm for the field?” This was in an article where she notes that in the network era “our little field of information science was simply pushed aside by the behemoths of computer science and business.”
This diffusion is seen in how it is described. I chose ‘interest’ above … Bates describes it as a metadiscipline, or earlier, as a meta-field. In this it is like journalism or education. Each is different from what she calls ‘content disciplines’ in that it explores issues which crosscut those disciplines. In Information Science’s case, the cross-cutting interest is the storage and retrieval of knowledge in recorded form. Bawden and Robinson describe Information Science as a ‘field of study’: it is focused on particular problems, but uses a variety of methods and theories.
Petras resists these definitions, preferring to see IS as having “an independent core and locus in the canonical scholarly universe: a discipline.” But this seems like territorial optimism, as does this author’s quote above. Does one have to claim one’s place as a discipline? It is interesting to see this beside Bawden and Robinson’s acknowledgement above that Information Science is likely to rest within a larger disciplinary home (they might have added Business). Indeed, it is revealing to see the acknowledgement in a (the?) leading textbook that Information Science has had an identity issue from the start.
That said there are strong intellectual traditions and affiliations at play here, around particular topics, academic centers of expertise, researchers/teachers and venues. Familiarity with key figures, central works, and the field's core concepts serves as a shibboleth, marking membership within an ongoing social and intellectual community. The community's activities are supported by dedicated journals, conferences, and professional associations, such as ASIS&T.
> It is perhaps appropriate to think of Information Science Classic in this manifestation as an ongoing community, institutionalized in a small set of journals, events and associations.
It is perhaps appropriate to think of Information Science Classic in this manifestation as an ongoing community, institutionalized in a small set of journals, events and associations. Given the changes within the iSchools which are a strong part of the architecture and identity of this community, one wonders if it will persist with quite the same identity.
#### LIS
> In general, I feel that even authors who write a great deal about the structure of the field sometimes use the combo of “LIS” as a matter of habit, and even in the works of the most prominent thinkers, there is no consistency in usage. // Dali, Keren (2015) How we missed the boat: reading scholarship and the field of LIS. *New Library World.*
> Two major structural shifts are revealed in the data: in 1960, LIS changed from a professional field focused on librarianship to an academic field focused on information and use; and in 1990, LIS began to receive a growing number of citations from outside the field, notably from Computer Science and Management, and saw a dramatic increase in the number of authors contributing to the literature of the field, notably from Computer Science and Management. // Larivière, V., Sugimoto, C. R., & Cronin, B. (2012). A bibliometric chronicling of library and information science’s first hundred years. *Journal of the American Society for Information Science and Technology.*
> This analysis of cognitive structure shows a clear division of LIS into three distinct areas with well-defined objects of study and, to some degree, venues of publication. These three areas can be broadly defined as LS, IS, and scientometrics/bibliometrics. **//** Milojević, S., Sugimoto, C. R., Yan, E., & Ding, Y. (2011). The cognitive structure of Library and Information Science: Analysis of article title words. *Journal of the American Society for Information Science and Technology*.
> Many of these definitions allude to the Janus-faced nature of the field—a field that is at once both professional and academic \[…\] As a result, Miksa (1985, 1992) argues that the field has two distinct paradigms—librarianship, which is focused on libraries as institutions, and information science, which is focused on information and its communication. They are informed by different research traditions: librarianship from social science, and IS from mathematical communication theory. And while some researchers (Ingwersen, 1992; Vakkari) consider library science (LS) to be a subfield within a more general field of IS, others (e.g., Saracevic) still consider them to be two related, but separate fields. // Milojević, S., Sugimoto, C. R., Yan, E., & Ding, Y. (2011). The cognitive structure of Library and Information Science: Analysis of article title words. *Journal of the American Society for Information Science and Technology*.
> For the perspective presented here, libraries are a specialized subject area in the wider field of information science. \[…\] The name library AND information science is redundant for this definition, but links to the historical roots of the fields and is now often used to represent a school’s particular focus on libraries in the disciplinary problem space. // Petras, V. (2024). The identity of information science. *Journal of Documentation*.
> A field of research may institutionalize both cognitively and socially (Whitley, 1984). The former means a shared and coherent understanding of principal research problems and goals, ways of conceptualizing the research objects and methodologies to study them. The latter refers to, e.g. university departments, journals and conferences representing the field of research. It is questionable whether the 50 years have led to cognitive institutionalization in LIS as a whole. There hardly exists a shared understanding of principal research problems and goals. \[…\] Interdisciplinarity is fruitful in developing new knowledge, but isn’t here a risk for LIS being absorbed by the stronger partners – both cognitively and socially? Further study is needed to analyse these questions. // Järvelin, K., & Vakkari, P. (2022). LIS research across 50 years: content analysis of journal articles. *Journal of Documentation*.
The report focus is LIS. The report says it applies LIS in a ‘general sense of “LIS-oriented” — the range of research, academic programs, faculty, and students who contribute to the profession of librarianship, broadly construed.’
However, this is not always how it is used in practice, although as noted by many, including Dali above, LIS is a very elastic term.
Often ‘Library and Information Science,’ it can sometimes be ‘Library and Information Studies.’ Syntax does not help. It can be parsed in a left-branching way ((library and information) science) suggesting ‘library and information’ is a unit. Sometimes it is parsed in a more flat structure as if ((library science) and (information science)) are two parallel concepts brought together. My sense is that it is used in the former way when the discussion is more library related, but I cannot confirm that.
However, in his interesting historical overview of LIS, Hjørland (2018) notes that “In general, however, the tendency today is to use the terms Information Science and Library and Information Science as synonyms.” And, as if to underline the deep confusion around the term, he describes this guidance to prospective authors posted by the editor of a journal.
> 8\. The editor of Information Research recommends the following use of the terms: “An additional point about LIS—this is much over-used and people are rarely writing about research directly related to libraries when they use it: if you are writing about research in libraries, use ‘library research,’ if you are writing about information research, use ‘information research’ or ‘information science research.’ If you really intend both, use ‘research in librarianship and information science.”” (Wilson 2015).
In support of his view above, he also notes that in the *ASIS&T Thesaurus of Information Science, Technology, and Librarianship* (2005) LIS is considered synonymous with Information Science, whereas librarianship is considered a related term.
At the same time, Petras claims that Library Studies is a subset of Information Science, and hence argues that LIS as a term is formally redundant. And in another position again, Dali resists the IS encroachment on L.
So, there is some ambiguity in the term.
There is general agreement that LIS was formed by combining library and information science perspectives. From a library point of view, this made sense in the context of the growing digital environment and because the information management, policy or other topics that emerged were not exclusive to the library space. However, equally, there is a recurrent note, as in the Report, that the two have not always sat beside each other comfortably. In fact, it has been suggested (Petras and elsewhere) that the ‘science’ in Information Science was chosen to differentiate the emerging discipline from the more practice-oriented Library Studies.
Referring to this dual nature, Milojević et al (2011) note the Janus-faced nature of the field. In their analysis of article words across a range of LIS journals they conclude that there is “a clear division of LIS into three distinct areas with well-defined objects of study and, to some degree, venues of publication.” The three areas “can be broadly defined as LS, IS, and scientometrics/bibliometrics.” They go on to more tentatively suggest that information seeking behavior may be establishing itself as another first order category. One striking feature of the analysis is the separated clustering they discovered of IS and LS journals.
In a later study, Järvelin & Vakkari (2022) carry out a content analysis of 30 LIS journals. They question “whether the 50 years have led to cognitive institutionalization in LIS as a whole” noting that there “hardly exists a shared understanding of principal research problems and goals.” They further observe that in some areas LIS researchers partner with other disciplines, and wonder whether there is a risk of LIS being absorbed by stronger partners both cognitively and socially (partners include computer science, communications, management).
Of course, LIS has indeed been organizationally subsumed into other departments/schools for some time (examples include education, business, computing, communications).
Another recurrent feature of discussion and debate is the low level of theory formation within the field. Not unexpectedly, given the nature of its interests there is a high level of borrowing from other fields. A recent survey of theory formation and use in LIS (Roy & Mukhopadhyay, 2023) concludes rather dramatically by claiming that LIS is facing a “theory crisis.” I am not sure about this, but it is certainly a factor contributing to perceptions of the prestige of the field.
Finally, both Järvelin & Vakkari (2022) and Larivière et al (2012) note a decline in the proportion of publications on librarianship specifically, and a growth in informational and other topics. This is not too surprising, but one wonders how much of a factor the relative balance of L and IS faculty in LIS departments/schools was, acknowledging the absence of clear boundaries.
So, LIS is a confusing term for a diffuse field which has not cohered around a sense of itself as a single entity. The term may be used synonymously with Information Science, and it may be used in a library context to acknowledge a wider informational dimension or to sound more ‘rigorous.’ If it is being used in a specific way, it really needs to be qualified to make this clear.
Again, however, LIS may also have a strong social dimension, whatever about its disciplinary coherence. It references shared schools, conferences, journals, and influences. Although, that said, it is interesting to note the strong divide between IS and L in some of the analysis above.
#### Information sciences, informatics, iSchool
> Some iSchools grew out of Library Science Schools, some out of Computer Science Schools, some have merged with Communication Departments, some have merged with Management—but the telling characteristic of each is that they are interdisciplinary and all share the same goal—to enable their graduates to become successful professionals based on their combined expertise in information, technology, and management. // Liddy, E. D. (2014). iSchools & the iSchool at Syracuse University.
As I noted in the introduction, my view of iSchools has been a little idealistic, given their variety, seeing them as multidisciplinary homes for a variety of informational interests. I suggested that a working characterization might be schools with a sociotechnical perspective that consider technology, people and organizations within a multidisciplinary setting.
Of course, actually existing iSchools are quite various, in terms of breadth of faculty expertise, configuration within the university, and so on. And their number has grown, if membership of the *iSchools Organization* is a measure. The designation has come to be applied less exclusively as membership has grown. At the time of writing, there are 130 members of this group.
Some offer undergraduate degrees. There are graduate degrees in information systems, data science, and other in-demand areas. There is a strong focus on general IT issues with a social and business dimension. They teach and research topics arising from the construction, deployment and management of information systems across industry, business, educational, or other, domains. This means that some may have a wider bandwidth connection to industry, in terms of partnership and vocational preparation. There may be local drivers around income, employability and overseas students.
At the same time, many have broad research agendas, and they are hospitable to a range of informational perspectives in the terms above, looking at the ramifications of informational organization of social and cultural phenomena. (The Center for an Informed Public at UW is an example.)
It is interesting to note that the iSchools Organization ‘about’ page does not mention libraries or library studies, again as of this writing, although it does include what may be a stock photo of the (all male) busts from the Long Room of Trinity College Dublin, one of the most photographed libraries in the world, and a common media recourse when a library is required.
> It is interesting to note that the iSchools Organization ‘about’ page does not mention libraries or library studies, again as of this writing, although it does include what may be a stock photo of the (all male) busts from the Long Room of Trinity College Dublin, one of the most photographed libraries in the world, and a common media recourse when a library is required.
Not all of the iSchools have a library or LIS heritage, and various terms may be used in quite general ways hospitable to many dimensions of information education and research. These include Information Science (with or without a connection to what I call Classic Information Science), Information Sciences and Informatics.
### Library studies, information science, LIS and the iSchool
The difference between a multidisciplinary and an interdisciplinary approach is one thread in discussions, with some favoring a multidisciplinary approach (e.g. Bates, 2022). The contrast is between an independent focus which cooperates in a peer-to-peer way versus a more integrated approach in which the characteristics of an individual approach may be subsumed.
A discussion of multidisciplinarity or interdisciplinarity depends on some scale of activity. Library studies has much to gain from a rich mix, in educational and research terms. This is both within the disciplinary mix of the iSchool, and potentially across campus. That depends on Library Studies itself thriving, in education and research terms as part of the mix. As discussed, this presents challenges in the R1 setting, which for scale, prestige and other reasons favors library studies sitting within a broader disciplinary setting. I discussed library studies in the previous section.
Is Information Science (Classic) in a different place? It brings a legacy of interesting work in specialisms which are not exclusive to it (information retrieval, information seeking behavior, domain analysis, …) and a community who may share some traditions and social venues. However, as is evident from the literature, it doesn’t bring a coherent body of work organized around a well-understood discipline. This is especially the case when one notes that the research interests of IS Classic are not exclusively the concern of IS Classic. Indeed, this becomes very apparent within the broader umbrella of the iSchool, which contains researchers and educators exploring similar issues and coming from different disciplinary traditions.
This broader iSchool informational agenda addresses core IS issues in a hybrid disciplinary setting. Information Science Classic still has some organizational momentum, embedded in schools and the social apparatus of a community (journals, ASIS&T, …), but it seems doubtful that it has a strong future as a distinct discipline recognized within the university canon. Bawden and Robinson suggest that it might live in several possible disciplinary homes. However, as with LIS below, one wonders if the continued academic transformation and relocation of the informational disciplines might weaken also the social affiliations of Information Science Classic.
The discussion of LIS in the report is both interesting and ambivalent. It is not clear how you circumscribe LIS. And, although there is an emphasis on LIS faculty, it is not clear either how you circumscribe the LIS faculty population. The report leans to a strong LIS association with librarianship, although, as discussed above, this is not universally true of its usage.
Is it somebody who has a PhD from a current ‘LIS school’? If this is so, and if the trends outlined in the report continue, presumably some of those LIS graduates with a strong IS or technical formation may naturally gravitate to other options in the iSchool. What is an LIS concentration when the IS is increasingly intermingled in the broader disciplinary array of the iSchool?
Is it a particular disciplinary focus? Well, as discussed throughout, there is an informational dimension to many subjects, which means that the IS part of LIS is intellectually less distinctive over time (even if there remains a community distinction, as discussed). The L part of LIS is more distinctive, one might as well just say LS?
Is it a matter of values? The discussion of LIS values reinforces this library emphasis (are those values espoused by the tradition of theoretical IR researchers or by those who are traditionally active in information systems?)
Is it a shared history, tradition and way of thinking? Undoubtedly. And, in this context, many researchers and teachers readily self-identify in an LIS tradition. However, as discussed here, LIS may be used in different ways and this identity may gradually dilute given changes in the iSchools themselves which have been part of the social institutionalization of LIS.
Much of the time whether one uses LS or LIS does not matter much. However, it makes sense to be clear what you are talking about - especially when it matters, as, for example, given the concerns of the report, in a recruitment discussion in an iSchool context.
There is also a variety of ways in which you want to talk about the library which are not about information processing or management.
Suggesting a preference for LS is not to be isolationist. Quite the contrary: LS will benefit from the multidisciplinarity of the iSchool in both research and education terms.
## Cross-LAMination
Several iSchools have expertise in libraries, archives and museums and offer degrees across the range. Archives and libraries may be a more common combination.
I have suggested it would be interesting to consider a horizontal LAM expansion to include archival studies (and potentially museum studies), in future iterations. It is important to recognize their distinct intellectual, social and vocational contexts and traditions. In my recommendations I ask if a LAM Forward initiative would create a stronger story than an LIS Forward one.
## A note on other disciplines
Historically, several other disciplines had an informational interest. These include, for example, Management Information Systems in a business setting, or Communications/Media studies, or Journalism.
While there might be some porosity of borders, each has a clear center of gravity. Interestingly, the first two of these at least might find a home in a current iSchool.
Of course, there are also significant examples of influential researchers in the Information Science Classic tradition who find a home in other disciplines, information retrieval in computer science, notably, but also in the social sciences, communications or elsewhere.
However, as more activities have become informationalized, many other disciplines have a strong, explicitly informational dimension. The sciences (e.g. bioinformatics), geography, the digital humanities, and so on. And the Report notes the range of disciplines with a strong informational flavor.
Ischools may often promote their work by repeating what Castells above calls the common-sense view that information or knowledge is everywhere. This is a double-edged proposition, and goes to iSchool identity. While it may suggest that the study of information can anchor a school, it can also suggest a lack of distinction.
## Coda: overview of and links to full contribution
**Collection:** LIS Forward (2025) *Responses to the LIS Forward Position Paper: Ensuring a Vibrant Future for LIS in iSchools, The Friday Harbor Papers, Volume 2*. \[[pdf](https://doi.org/10.6069/F6CQ-H317?ref=lorcandempsey.net)\]
**Contribution**: Dempsey, L. (2025). Library Studies, the Informational Disciplines, and the iSchool: Some Remarks Prompted by LIS Forward. In LIS Forward (2025) *Responses to the LIS Forward Position Paper: Ensuring a Vibrant Future for LIS in iSchools, The Friday Harbor Papers, Volume 2*. \[[pdf](https://doi.org/10.6069/F6CQ-H317?ref=lorcandempsey.net)\]
**Contents:** Here are the sections from my contribution. Where I have excerpted them on this site, I provide a link.
- 1 Introduction \[and summary\] \[[excerpted here](https://www.lorcandempsey.net/introduction-and-summary-library-studies-the-informational-disciplines-and-the-ischool-some-remarks-prompted-by-lis-forward/)\]
- 2 Information: a brief schematic history \[[excerpted here](https://www.lorcandempsey.net/information-a-brief-schematic-history/)\]
- 3 Libraries and library studies \[[excerpted here](https://www.lorcandempsey.net/libraries-and-library-studies/)\]
- 4 Informational disciplines \[[excerpted here](https://www.lorcandempsey.net/the-informational-disciplines/)\]
- 5 On the dissemination of ideas and innovation \[[excerpted here](https://www.lorcandempsey.net/on-the-dissemination-of-ideas-and-innovation/)\]
- 6 Symbolic capital
- 7 Recommendations and candidate recommendations
- Coda 1: Google Ngram
- Coda 2: Personal position
- References
## References
Bates, M.J. (2015). The information professions: knowledge, memory, heritage. *Information Research*, *20*(1). [https://informationr.net/ir/20-1/paper655.html](https://informationr.net/ir/20-1/paper655.html?ref=lorcandempsey.net)
Bates, M.J. (2022). A proto-paradigm for information science research. *Information Research*, *27*(Special issue). [https://informationr.net/ir/27-SpIssue/CoLIS2022/colis2201.html](https://informationr.net/ir/27-SpIssue/CoLIS2022/colis2201.html?ref=lorcandempsey.net)
Bawden, D., & Robinson, L. (2022). *Introduction to Information Science* (Second). Routledge. [https://www.routledge.com/Introduction-to-Information-Science/Bawden-Robinson/p/book/9781783304950](https://www.routledge.com/Introduction-to-Information-Science/Bawden-Robinson/p/book/9781783304950?ref=lorcandempsey.net)
Buckland, M. (2005). *Information schools: A Monk, Library Science, and the Information Age.* [https://escholarship.org/uc/item/33g728qk](https://escholarship.org/uc/item/33g728qk?ref=lorcandempsey.net)
Buckland, M. (2012). What kind of science can information science be? *Journal of the American Society for Information Science and Technology*, *63*(1), 1–7\. [https://doi.org/10.1002/asi.21656](https://doi.org/10.1002/asi.21656?ref=lorcandempsey.net)
Cornelius, I. (1996). *Meaning and method in information studies*. Ablex Pub.
Dali, K. (2015). How we missed the boat: reading scholarship and the field of LIS. *New Library World*, *116*(9/10), 477–502\. [https://doi.org/10.1108/nlw-01-2015-0007](https://doi.org/10.1108/nlw-01-2015-0007?ref=lorcandempsey.net)
Furner, J. (2015). Information science is neither. *Library Trends*, *63*(3). [https://doi.org/10.1353/lib.2015.0009](https://doi.org/10.1353/lib.2015.0009?ref=lorcandempsey.net)
Hjørland, B. (2018). Library and Information Science (LIS), Part 1\. *Knowledge organization*, *45*(3), 232–254\. [https://doi.org/10.5771/0943-7444-2018-3-232](https://doi.org/10.5771/0943-7444-2018-3-232?ref=lorcandempsey.net)
Järvelin, K., & Vakkari, P. (2022). LIS research across 50 years: content analysis of journal articles. *Journal of Documentation*, *78*(7), 65–88\. [https://doi.org/10.1108/jd-03-2021-0062](https://doi.org/10.1108/jd-03-2021-0062?ref=lorcandempsey.net)
Larivière, V., Sugimoto, C. R., & Cronin, B. (2012). A bibliometric chronicling of library and information science’s first hundred years. *Journal of the American Society for Information Science and Technology*, *63*(5), 997–1016\. [https://doi.org/10.1002/asi.22645](https://doi.org/10.1002/asi.22645?ref=lorcandempsey.net)
Liddy, E. D. (2014). iSchools & the iSchool at Syracuse University. In C. Chen & R. Larsen (Eds.), *Library and Information Sciences, Trends and Research* (pp. 31–37). Springer. [https://doi.org/10.1007/978-3-642-54812-3\_4](https://doi.org/10.1007/978-3-642-54812-3%5F4?ref=lorcandempsey.net)
Milojević, S., Sugimoto, C. R., Yan, E., & Ding, Y. (2011). The cognitive structure of Library and Information Science: Analysis of article title words. *Journal of the American Society for Information Science and Technology*, *62*(10), 1933–1953\. [https://doi.org/10.1002/asi.21602](https://doi.org/10.1002/asi.21602?ref=lorcandempsey.net)
Petras, V. (2024). The identity of information science. *Journal of Documentation*, *80*(3), 579–596\. [https://doi.org/10.1108/jd-04-2023-0074](https://doi.org/10.1108/jd-04-2023-0074?ref=lorcandempsey.net)
Roy, B. K., & Mukhopadhyay, P. (2023). Theoretical Backbone of Library and Information Science: A Quest. *LIBER Quarterly: The Journal of the Association of European Research Libraries*, *33*(1), 1–57\. [https://doi.org/10.53377/lq.13269](https://doi.org/10.53377/lq.13269?ref=lorcandempsey.net)
White, H. D., & McCain, K. W. (1998). Visualizing a discipline: An author co-citation analysis of information science, 1972–1995. *Journal of the American Society for Information Science*, *49*(4), 327–355\. [https://doi.org/10.1002/(sici)1097-4571(19980401)49:4<327::aid-asi4>3.0.co;2-4](https://doi.org/10.1002/%28sici%291097-4571%2819980401%2949:4%3c327::aid-asi4%3e3.0.co;2-4?ref=lorcandempsey.net)
**Feature picture:** I took the picture in the somewhat grim Penitentiary in Mansfield, Ohio.
### Introduction and summary: library studies, the informational disciplines, and the iSchool: some remarks prompted by LIS Forward
URL: https://www.lorcandempsey.net/introduction-and-summary-library-studies-the-informational-disciplines-and-the-ischool-some-remarks-prompted-by-lis-forward/
Last updated: 2025-10-29T03:53:27.000Z
This is an ****excerpt** from a longer contribution I made to **Responses to the LIS Forward Position Paper: Ensuring a Vibrant Future for LIS in iSchools.* \[[pdf](https://digital.lib.washington.edu/researchworks/bitstreams/5fb927cc-c3a4-4198-bf04-e3601107308f/download?ref=lorcandempsey.net)\] It is a sketch only, and somewhat informal, but I thought I would put it here in case of interest. I have not revised it.
This is the introduction and summary, and it extensively references the full response and the Position Paper itself. I link to the position paper, my response, and sections excerpted here below.
As I note also below, it is very much influenced by the context in which it was prepared which was a discussion of the informational disciplines and the iSchool in R1 institutions.
If you wish to reference it, I would be grateful if you cite the full original: Dempsey, L. (2025). Library Studies, the Informational Disciplines, and the iSchool: Some Remarks Prompted by LIS Forward. In LIS Forward (2025) **Responses to the LIS Forward Position Paper: Ensuring a Vibrant Future for LIS in iSchools, The Friday Harbor Papers, Volume 2*. \[[pdf](https://doi.org/10.6069/F6CQ-H317?ref=lorcandempsey.net)\]
## Introductory
iSchools have created a space where many disciplinary backgrounds come together in potentially exciting ways. My focus here is on the position of Library Studies within this mix. I don’t mean to ignore the bigger questions about iSchools and their future, or about Library Studies in other disciplinary configurations; they are just not within my scope. A strong Library Studies component has much to gain from this mixed disciplinary hinterland.
This response reflects its origins as a personal commentary on the **LIS Forward* document, and as such manifests some informality, in both presentation and preparation. It covers several areas that could be treated much more extensively or completely in a different kind of consideration.
Given the original emphases of the report, I focus on libraries and library studies, LIS, and IS, and assume an R1 setting.
I am very aware of my partial and particular perspectives. I make a note of my experience in a coda. It should be clear that my aim most of the time is to be suggestive rather than comprehensive.
I use IS (information science), LIS (library and information science/studies) and LS (library studies) throughout.
The *LIS Forward* report is motivated by “a sense of urgency concerning the future of LIS in information schools.” It is a welcome and interesting contribution.
The Report looks at the current position of LIS (Library and Information Science/Studies)[\[1\]](#%5Fftn1) in the iSchool. It echoes recurrent discussions about the prestige or position of LIS/Library Studies within the academy, the unsettled relationship between various informational disciplines, circular debates about the nature of those informational disciplines, and the challenges to a practice-based discipline in a research environment.
I share the authors’ sense of urgency. However, this sense of urgency is not driven primarily by questions of disciplinary definition or boundary. It is driven by a sense that this is an important moment for libraries and for librarianship.
It is an exciting time, as the library has been transforming from a transactional, collection-centered one to a relational, community-centered one. It is also a challenging time as both library value and library values are being questioned.
It is very much a field in motion, and occasional commotion.
For these reasons it is a time when it is more important than ever to have strong learning, research and advocacy partners which can strengthen the field and provide leadership in these areas:
- Research: enrich the library’s knowledge base about its community and environment.
- Career preparation: understood broadly as provision of skills and outlooks to understand and act in changing social, political, technical and service environments.
- Engagement: connect libraries to frameworks, evidence and arguments which influence practice and inform policy.
Library or Information Studies is one important place this leadership can come from, although as I note below, there are others. The current iteration of the Report focuses on research, although I make comments on all three areas.
Accordingly, the urgency that I see is in the connection between, on one hand, the library of today and tomorrow and, on the other, the university educational capacity that prepares much of the library workforce, and the university research capacity that can potentially advance the field.
Is iSchool education and research helping libraries succeed? I am not sure to what extent it is. I would be interested to see more of an outside-in view of the questions raised in the report in future iterations. What do libraries and related organizations need in terms of iSchool (or other) research, education and innovation partners?
I mostly use the term ‘Library Studies’ (LS) – or librarianship -- in my response.[\[2\]](#%5Fftn2) This is certainly because libraries and librarianship are my primary focus; however, I also want to avoid some of the definitional blurriness around the use of ‘LIS’ that the report acknowledges. I believe that this blurriness can be politically and personally convenient while also being more generally unhelpful.
It is clearly significant that *LIS Forward* was initiated by a group of iSchools within R1 institutions, given the reputational hierarchies and research focus at play in those institutions. Library studies may have low prestige or ‘symbolic capital’ in these environments. This comes across very clearly in the contribution in Chapter 3 of the Early Career Faculty. It is also evident in some comments in the Deans’ interviews.
Indeed, in support of this view, one need not look beyond the disciplinary backgrounds of the Deans of the involved iSchools, and the relative absence among them of a disciplinary or practitioner background in library studies. The low proportion of LS hires in 2022 (as opposed to LIS hires) noted by the report authors also seems telling.
At the same time, the perception of libraries themselves, particularly within university structures of influence and opinion, may be static and out of date. They may not be seen as complex management environments embedded in demanding political situations, or as sites of evolving technology or strategic choices, or as public investments in wellness, education and research.
At a high level, this leads to a two-fold challenge for Library Studies within the iSchool, especially within the R1 environment. First is the lack of academic prestige and hence emphasis; second is a potential lack of belief that libraries can motivate theoretical frameworks or professional preparation that is sufficiently worthy of academic attention.
These and other challenges have led to what I call here a story of progressive subsumption, as library studies is subsumed into various broader informational constructs. Schools of Library Studies diversified into LIS to reflect the changing technology environment, and the variety of informational careers students were following. LIS was subsumed into broader schools of information, as information processing and management became more common. The iSchool range is wide, with emphases as various as, say, vocationally oriented information systems work, or as social and philosophical aspects of an informational society, or as values-driven social justice and equity explorations. In some cases, informatics or related undergraduate degrees were added. The Report makes clear that Library Studies feels squeezed or undervalued, despite reporting continued demand for the MLS. There are also questions about the balance between teaching-oriented faculty and research faculty, as this educational demand continues.
This pattern of subsumption also relates to scale, the LS research and education capacity available in any iSchool or in aggregate across iSchools and other institutions. Is this a community that is stable or in decline? Of course, an advantage of the bigger school unit is the ability to work in concert with others.
There is a third challenge, one of agency and change. Local evolution will be driven by individual university configurations, influences and needs. Any change process is diffuse and slow, and is subject to the collective action problem across schools. It may also be resisted, although the report does not emphasise this, as may happen if some reallocation of resources, influence and vested interests is suggested.
Together, these challenges lead to a major question the Report needs to address. Given the depressingly recurrent nature of the discussions about the position of Librarianship/LIS in R1 institutions, what needs to be done differently now to secure and elevate that position?
This is why I emphasise four factors throughout this response:
1. the benefits of increasing the awareness, scale and impact of research and policy work through a more concertedly collaborative approach,
2. the benefits of reconnecting more strongly with libraries and related organizations, and the organizations that channel their interests, which includes discussion of more flexible and tailored learning and certification reflecting evolving skills and workplace demands,
3. the possible benefits of refocusing this particular discussion of Library Studies around the institutional and service dynamics of LAM and connecting that with a variety of disciplinary hinterlands (public administration, social studies, and so on) and moving away from the familiar and maybe superseded discussions about IS, LIS and so on,
4. the benefits of developing an agenda of Key Areas which connect with current library needs, and which can provide some rationale or motivation for recruitment, research activity, granters, collaborative activity and so on. If iSchool education and research respond more actively to evolving library issues, the people with appropriate skills and interests need to be in place.
Of course, there is a prior question about whether Library Studies has a place in the iSchool at all, but for now I assume it does. In fact, one is aware of opportunity. R1 institutions contain the space, resources and ambition to potentially remake Library Studies in ways that address the challenges of the times. If Library Studies is to benefit from strong collaborations within the range of specialisms an iSchool offers then Library Studies itself must be strongly represented in the structures of the school, be connected with the practitioner community, and have a strong research profile. The report recognizes this, notably in recommendation 3.
It seems unlikely that library studies has the prestige, track record or scale to exist in the R1 environment outside of a bigger grouping such as the iSchool. Given the history of library schools within this environment, a favorable position with an iSchool or other school seems like a win. (And again, Library Studies exists outside of this environment also.)
I comment on iSchools here given that that is the focus of the report, acknowledging that other disciplinary-departmental configurations exist and may offer other advantages. A key issue here is the scale required to have a range of educational offerings and some research capacity.
Finally, as the Report notes, iSchools are quite different from each other and given the fluidity of disciplinary definition, origin stories, and departmental organization, it is clear that practices are highly contingent – on institutional histories and configurations, on Deans’ preferences and outlooks, on hiring decisions, on institutional political and economic drivers, and on existing faculty interests. This comes across quite strongly in some places in the report, and I thought that it would be interesting for the authors to lean a little more into some of these questions at some stage.
For this reason, when I talk about iSchools I tend to have a somewhat idealized version in mind, assuming a broad scope that entails a sociotechnical exploration of technology, people and organizations within a multidisciplinary setting. Thinking about the position and future of the iSchool within the university is outside my scope here, and, indeed, outside my competence. Library Studies certainly have a place within such an environment. Of course, actually existing iSchools variably embody that idealized version.
## Summary note
My response is in seven sections. This introduction is followed by five relatively self-standing pieces which could be considered independently, each looking at a different aspect of Library Studies and the iSchool. For this reason, there may be a little redundancy between them. Finally, there is a section which responds to the Report’s invitation to provide some candidate recommendations.
Five opening remarks:
1. The initiative should have ambition which is proportional to the urgency they describe, and to the benefits of having a strong research and education partner for a challenged and changing library community. This needs some thinking about agency in respect of collaborative activity, and I suggest the group seeks funding to coordinate and seek additional support.
2. Given the recurrent nature of the discussion about the position of Library Studies/LIS within the University, and given the prestige dynamics of an R1 institution, a (the?) major question before the initiative is how to secure and elevate that position. This involves steps to elevate the interest in, the awareness of, and the impact of the research and education questions Library Studies addresses, to sharpen focus on the distinctiveness of LS, and to reconnect with evolving library challenges and interests.
3. The report notes an identity challenge within an identity challenge (LIS within the iSchool). One could extend the identity challenge concertina and add Informatics, Library Studies, Information Science and Information Sciences to the mix. At the same time, as the Deans note, outside perceptions can be confused about labels, be unaware of intellectual traditions, or be confused about the nature of the scholarly enquiry or education involved. After many years of discussion, the LS/LIS/IS discourse does not cumulate to consensus about a unified field, about the main emphases in such a field, or about the terms used to describe it. Seen against the challenge I describe above, this disciplinary discussion seems like a played-out topic, of declining interest; however, it still commands attention and I explore it further below. At the same time, the library is not just a set of information management techniques. Nor is the future of the library more Python or data science, important as those are for some who work in libraries. The library is a service organization that needs to be designed and sustained and a social and cultural institution with a long history and a vital educational and civic role. Library education and research have other potential partners in the disciplinary ecosystem, which is one reason that the potentially broader social and cultural range of the iSchool is of interest. If the focus of the initiative is on libraries, I think that it makes sense to talk about Library Studies (rather than LIS), noting, as the report does, the evolution of and interaction between informational disciplines.
4. I question above whether switching from LIS to LAM as a focus would clarify and sharpen the goals. This would move it away from definitional discussion within the informational fields, although it could still benefit from their focus. Of course, libraries, archives and museums have quite different traditions and emphases, but they do share that they are practitioner-focused, and represent institutional responses to social, cultural and scholarly needs. Establishing a new focus, within the rich multi-disciplinary hinterland of the iSchool, connects to the future rather than to a past struggling to establish its place. A Library/Archive/Museum focus also potentially presents a more understandable and relatable focus to other parties.[\[3\]](#%5Fftn3)
5. A key factor here is economics. I do not have the data or the knowledge to comment on this. However, it is important to understand local economic drivers, market demand and willingness to pay, and so on. This plays into the interesting discussion about certificates, stackable qualifications, and other flexible learning pathways in evolving practitioner-oriented disciplines.
Here is a brief description of what is to follow.
### 1 Information – an elusive and changing concept
I sketch a brief historical schematic, just to provide some context for subsequent discussion of libraries and the informational disciplines. I note the move from the long age of literacy and print, to the proliferation of recorded information and knowledge resources after World War II, to the current ‘informationalized’ environment where information is an integral part of social organization. I note how the library, Information Science, and the iSchool emerged, respectively, in these successive phases. And I also discuss the current broad philosophical, technical, cultural and social interest in informational issues across disciplines. This interest is also turned to the past, which may be reinterpreted in informational terms. In parallel with this rise, information critique becomes more important.
### 2 Libraries – organizational responses to learning and creative needs
My main focus is to reaffirm that libraries are complex and changing social organizations, which are deeply collaborative and networked, and which are often working in challenging political and social contexts. They are shifting from being transactional and collections-centered to being relational and community-centered. This means that they manifest interesting educational and research issues, from the technical, to the management, to the social and political. For example, libraries are relevant if you are interested in the public sphere, the nature and support of public goods, equity of opportunity, childhood learning, building sustainable scholarly infrastructure, the balance between creators and consumers, the nature of memory and forgetting. Information management skills remain important but there is a range of community, management, organization, advocacy and other skills that are also very important. This underlines how the library can generate interesting education and research agendas, and a principal theme here is how to elevate awareness of this and interest in it among peers from other disciplines. I suggest that the initiative convene with central library organizations and funders to develop a motivating list of Key Areas that will be important for libraries, and might provide some signals for recruitment, research, and course development.
### 3 The informational disciplines
I review some of the literature about LIS, Information Science (IS) and the emergence of the iSchool. I note the binary nature of LIS (L + IS) and the subsequent ambiguity in its use as well as occasional tension between the two wings. The relative L or IS emphasis may vary by context of use or person. In its classic form, Information Science may only be fully appreciated by those familiar with its tradition. Others may understand it more generically as a more applied companion to computer science or as a general enquiry. We already see discussion of ‘information sciences’ or ‘information science’ which make no reference to the classical Information Science intellectual legacy or social community. Nevertheless, there are strong intellectual traditions and affiliations at play, and I conclude that it may be appropriate to think of LIS and of Information Science as ongoing social communities, supported by particular educational affiliations, journals, conferences and associations rather than as self-standing disciplines. The iSchools themselves are an important part of the IS and LIS social architecture. However, this may mean that the specificity of the IS or LIS community may be diluted as the iSchool faculty continues to be diversified, as the broader iSchool informational agenda subsumptively addresses the core IS issues in a hybrid disciplinary setting, and as iSchool graduates have a variety of disciplinary outlooks. Library Studies can potentially benefit from being a strong focus within the multidisciplinary mix of the iSchool.
### 4 Ideas – impact on policy and practice
I briefly look at the general transmission of ideas and innovation in the library domain and wonder if the impact of Library Studies here is less than one might expect. The report is relatively silent about this area, but some disciplines (business and economics, for example) do aim to inform policy and influence practice. This seems like an important discussion point. I would be interested to see some follow-up work comparing Library Studies with other disciplines. Education, Health Sciences, Social Work, Industrial Relations and Hospitality Studies come to mind.
### 5 Prestige and power in the university
I talk about prestige and power, which are clearly very much at play in the dynamics of the iSchool and the influences on the Report. I draw on Bourdieu’s discussion of field, capital and power. The historical trajectory of Library Studies in the context of successively emerging informational disciplines (Information Science, LIS and the iSchool) lends itself extremely well to analysis using these categories. To what extent does the historical addition of ‘Information Science’ to library (as in LIS) or the positioning within a broader technology hinterland represent a desire to increase the symbolic capital of the discipline? Has the ‘IS’ subsequently crowded the ‘L’, as the report seems to suggest? How do Library Studies play within the prestige politics of an R1 institution? Library studies undoubtedly benefit from the scale and diversity a broader iSchool brings and the Report also notes the addition of interesting and relevant new domains of study, Indigenous knowledges, for example. However, Library Studies also struggles for attention or prestige and is pressed in some of the ways discussed emphatically by the Early Career Faculty. The Library Studies field typically has a professional focus, does not generate large collaborative grants, and its community engagement and contribution does not result in industry breakthroughs, major policy initiatives, newsworthy prizes, or other markers of distinction valued in this environment. Reception is also gendered, given the historically feminized nature of the profession. There is a comment in the Dean’s section about having to continually make the case for librarianship: I would have been interested to have heard more from the iSchool Deans about the realities of leading iSchools in an R1 institution, and indeed more generally about power, prestige, and politics in this environment. This section was written in dialogue with ChatGPT, which notes “The struggle for symbolic capital in LIS involves both defending the value of library-centric research and aligning with the broader, more interdisciplinary goals of the iSchool movement.”
### 6 Recommendations and candidate recommendations
A concluding section takes up the invitation to offer some candidate recommendations. They mostly focus on how to elevate the status and recognition of Library Studies, in part through stronger collaboration across the iSchools. I also include some suggestions for additional studies that would amplify topics or questions raised in the Report.
There are two Codas. In Coda 1 I include some NGram diagrams of vocabulary used in the report (LIS, Information Science, etc.). The curves are interesting, but I did not incorporate them here given uncertainty about NGram data and interpretation. Coda 2 is a note describing my experience, and acknowledging my partial perspective.
## Some preliminary notes
Finally, here are some additional notes of areas that are important but not pursued here.
- Library studies shares with some other practice-oriented disciplines (health professions, hospitality, social work, and others) a historic association with service and community engagement. These areas have been traditionally feminized and undervalued. How much is this dynamic in play in the relationship between Library Studies and the informational qualifications in part designed to make it appear more technological or scientific? This definitely bears further exploration by the initiative.
- The report notes that libraries can stand in for LAM generally in discussion. I think that ‘LAM’ should only be used when it is applicable to and inclusive of all three strands, not when the discussion is really library or LIS based. While acknowledging that there are variously converging interests, each practice also has a history, professional community(ies), and curatorial traditions that warrant individual discussion. Assimilating LAM to an LIS/LS discussion like this is unhelpful. That said, schools that are lucky to have all three strands benefit greatly.
- I am very conscious that the report does not consider student or potential employer interests. My own knowledge here is largely personal and subjective. Given that many students are looking for the MLS credential as an entry point to a library or related career, this seems like an important gap which future work may address. The relevance of LS research, education and other work to libraries and related organizations is an important element of their claims to research and education status.
- The Report is about iSchools. Of course, as noted above, Library Studies may achieve some scale and collaboration possibilities in other configurations – within cultural studies or communications schools, for example, or business or education. Given the organizational context of libraries, there is a variety of relevant disciplinary hinterlands, and it is increasingly the case that ‘information’ is only one possibility. Given the topic of the report, I do not discuss those, although I do suggest some further exploration.
- I use ‘librarian’ generally to refer to those who work in libraries and have a vocational interest in their evolution. Only occasionally do I explicitly limit it to those who have the MLIS credential.
- I include references. Given the historical nature of the discussion, some of these are to older materials.
## Coda: overview of and links to full contribution
**Collection:** LIS Forward (2025) *Responses to the LIS Forward Position Paper: Ensuring a Vibrant Future for LIS in iSchools, The Friday Harbor Papers, Volume 2*. \[[pdf](https://doi.org/10.6069/F6CQ-H317?ref=lorcandempsey.net)\]
**Contribution**: Dempsey, L. (2025). Library Studies, the Informational Disciplines, and the iSchool: Some Remarks Prompted by LIS Forward. In LIS Forward (2025) *Responses to the LIS Forward Position Paper: Ensuring a Vibrant Future for LIS in iSchools, The Friday Harbor Papers, Volume 2*. \[[pdf](https://doi.org/10.6069/F6CQ-H317?ref=lorcandempsey.net)\]
**Contents:** Here are the sections from my contribution. Where I have excerpted them on this site, I provide a link.
- 1 Introduction \[and summary\] \[[excerpted here](https://www.lorcandempsey.net/introduction-and-summary-library-studies-the-informational-disciplines-and-the-ischool-some-remarks-prompted-by-lis-forward/)\]
- 2 Information: a brief schematic history \[[excerpted here](https://www.lorcandempsey.net/information-a-brief-schematic-history/)\]
- 3 Libraries and library studies \[[excerpted here](https://www.lorcandempsey.net/libraries-and-library-studies/)\]
- 4 Informational disciplines \[[excerpted here](https://www.lorcandempsey.net/the-informational-disciplines/)\]
- 5 On the dissemination of ideas and innovation \[[excerpted here](https://www.lorcandempsey.net/on-the-dissemination-of-ideas-and-innovation/)\]
- 6 Symbolic capital
- 7 Recommendations and candidate recommendations
- Coda 1: Google Ngram
- Coda 2: Personal position
- References
---
\[1\] LIS can be expanded as Library and Information Science, which is how it seems to be used in the report. Less often, perhaps, it is expanded as Library and Information Studies.
\[2\] Of course, not all iSchools include Library Studies in their portfolio.
\[3\] While Archival Studies is present in many ischools, Museum Studies is less so, which can complicate use of the LAM label. I am not suggesting that the designation ‘LAM’ is readily understood, but libraries, museums and archives are. I understand various objections to this, not least the perception that LAMs are about the past.
**Feature picture:** I took the picture on the campus of the University of Washington.
### On the dissemination of ideas and innovation
URL: https://www.lorcandempsey.net/on-the-dissemination-of-ideas-and-innovation/
Last updated: 2025-10-22T16:54:19.000Z
This is an ****excerpt** from a longer contribution I made to **Responses to the LIS Forward Position Paper: Ensuring a Vibrant Future for LIS in iSchools.* \[[pdf](https://digital.lib.washington.edu/researchworks/bitstreams/5fb927cc-c3a4-4198-bf04-e3601107308f/download?ref=lorcandempsey.net)\] It is a sketch only, and somewhat informal, but I thought I would put it here in case of interest. It occasionally references the position paper. It is also influenced by the context in which it was prepared which was a discussion of the informational disciplines and the iSchool in R1 institutions.
It would be interesting to take a fuller discussion in one of two directions, which would fill in more individual or organizational names. The first is empirical, based on survey, citations, and other markers of influence. A second would be to be more opinionated, which would be partial (in more than one sense) but might prompt some reflection about emphasis and omission.
If you wish to reference it, I would be grateful if you cite the full original: Dempsey, L. (2025). Library Studies, the Informational Disciplines, and the iSchool: Some Remarks Prompted by LIS Forward. In LIS Forward (2025) **Responses to the LIS Forward Position Paper: Ensuring a Vibrant Future for LIS in iSchools, The Friday Harbor Papers, Volume 2*. \[[pdf](https://doi.org/10.6069/F6CQ-H317?ref=lorcandempsey.net)\]
## The diffusion of ideas
> As numerous critics beyond Kristof have observed, the professionalization of the academy prioritizes peer-reviewed publications over other forms of writing. Professors allocate the bulk of their efforts to researching, writing, and publishing in their field journals. The first task of any professor—particularly junior professors—is to publish in prestigious peer-reviewed outlets. Even scholars who have some facility with engaging a wider audience have warned that it takes time away from research.49 It is great when academics also express their ideas to a wider audience. Professional incentives dictate, however, that this will always be the hobby and not the job. // Daniel W. Drezner (2017) *The Ideas Industry*.
The university plays an important role in the generation and diffusion of ideas and innovation. The Report does not focus on this area. However, informing practice and influencing policy is an important part of what the university does, especially in a practice-oriented discipline. As noted, in a period of change, libraries benefit from data-based frameworks, evidence, and arguments to support advocacy work, or to think about new service areas. In a related context, being interviewed on NPR when expertise is required or writing an op-ed in a leading newspaper are markers of esteem (see the discussion of symbolic capital in the next section).
> ... in a period of change, libraries benefit from data-based frameworks, evidence, and arguments to support advocacy work, or to think about new service areas.
## Drezner’s typology of sources
Dan Drezner writes about the dissemination of ideas in *The Ideas Industry*. Drezner is interested in how ideas are diffused and taken up in political and policy contexts, and how they lead to action or practical decisions. He discusses the evolving sources of ideas in the policy arena.
- **Academic**. The academy may have been the historically primary source of ideas, although Drezner argues that its influence has waned for various reasons. He notes the scholarly incentives of faculty, which promote peer-reviewed articles in leading journals as the peak achievement, and which in turn leads to disciplinary peers as the primary audience and community they seek. Disciplines will have different dynamics. For example, perhaps because of its normative base, Drezner suggests, economics has more influence than other social sciences.
- **Think tanks**. He charts the rise and changing role of think tanks such as the Rand Corporation or Brookings Institution. Unlike universities, these do have an explicit role in influencing policy, and over time some have become more partisan.
- **Industry and management consulting**. Various firms – McKinsey, Gartner, and others – have developed capacity for published research and thought pieces, often as a form of reputational promotion of their consulting or related services.
- **Individuals**. Drezner highlights, for example, the careers of Fareed Zakaria and Neil Ferguson.
How does this play out in the library field?
The incentives Drezner mentions are strongly at play in R1 schools and may not be aligned with broader community engagement. This is evident in the comments of the Early Career Researchers. Of course, taken collectively iSchools do work which influences both practice and policy, and there are some notable connections (Sheffield and exploration of open access, for example). There are also some high-profile iSchool faculty members who make important and visible contributions to broader debate outside the library context.
While they are not think-tanks as such, one can point to Ithaka S&R and OCLC Research, divisions, respectively, of large not-for-profit service organizations, each of which is quite active in working with groups of libraries to develop applied R&D outputs.[\[1\]](#%5Fftn1) They tend to focus on areas of topical interest, such as collections, collaboration, research infrastructure and scholarly communication. Over the years, they have worked on a variety of topics (including, for example, metadata and protocols, research support, library collaboration, and user behavior in the case of OCLC Research). Ithaka S&R has an academic and cultural focus. OCLC Research works with academic and public libraries (notably through WebJunction, a learning platform for libraries). In each case, there is definitely an interest in providing knowledge, evidence and models that help influence practice or inform policy.
This interest is also evident in the output of professional associations and others which produce outputs on behalf of members. While different from Drezner’s consultancy category, there are some parallels in terms of providing value to members. Here one might point to the Urban Libraries Council or to the Association for Research Libraries and the Coalition for Network Information, or to the divisions of ALA. ARSL is another example.
Advocacy and other groups also produce materials to inform and guide. Helping with evidence and arguments is important here. SPARC and EveryLibrary are examples.
An important element of what associations and membership groups do is to provide venues for networking and to support communities of practice. They aim to scale learning and innovation within their constituencies.
> An important element of what associations and membership groups do is to provide venues for networking and to support communities of practice. They aim to scale learning and innovation within their constituencies.
One can also see that vendors produce occasional reports, as a value-add to customers. Think of Sage or Clarivate for example. In some cases, these may not be seen as more than elevated marketing.
Finally, there is a variety of individual practitioner voices that are quite influential.
I have not given a lot of examples above, because without some analysis, it would be very subjective. However, some exploration of the diffusion of ideas and innovation in this space would be interesting, acknowledging that it is a smaller more tight-knit community than some of the areas Drezner (who is a scholar and commentator of International Relations) discusses.
## Public intellectuals and thought leaders
> Public intellectuals delight in taking issue with various parts of the conventional wisdom. By their very nature, however, they will be reluctant to proffer alternative ideas that appeal to any mass audience. Thought leaders will have no such difficulty promising that their ideas will disrupt or transform the status quo. And the shifts discussed in this chapter only increase the craving for clear, appealing answers. // Daniel W. Drezner (2017) *The Ideas Industry*.
> This is an inherent tension between scholarship and communication, one that breeds resentment for academics trying to engage a wider audience as well as readers who have to wade through complex, cautious prose.Daniel W. Drezner (2017) *The Ideas Industry.*
In Drezner’s terms, thought leaders favor large explanatory ideas, and deliberately aim to influence policy and practice. They value clear communication, may view the world through a single frame, and evangelize their ideas actively. Thomas Friedman is an example in the book. Public intellectuals promote critical thought across different arenas, may not offer easy solutions or answers, and emphasize complexity and questioning. Francis Fukuyama and Noam Chomsky are cited examples here.
Drezner notes that the current climate favors thought leaders because their ideas are easier to consume: their big idea can be delivered in a Ted Talk. Perhaps the library community hit peak thought leadership in the heyday of the personal blog, where several influential librarians achieved large audiences.
## Platform publications
Computing has *Communications of the* *ACM*. Engineering has *IEEE Spectrum*. Business readers turn to the *Harvard Business Review*. The HE technology community has *Educause Review*.
These are what I have called in the past ‘platform’ publications (Dempsey and Walter). They aggregate the attention of an audience within a particular domain, including leadership, practice and research. They provide a platform for their authors, who may be reasonably assured of a broad engaged audience.
The library community does not have such a publication, which could provide a venue for research and practice to co-exist in dialog.
## Ischools and influence on policy and practice
What is the role of the iSchool in influencing policy and informing practice? More specifically, how important is it for Library Studies to visibly do this?
The bilateral research - practice connection is of course much discussed, and I wondered about the gap here above. Is the influence on policy at various levels perhaps less discussed?
This works in a variety of ways, not least through participation in professional venues – membership of associations, presentation where practitioners congregate to learn about direction, partnership with library organizations and libraries.
Again, without supporting evidence, my impression is that there may be a higher level of engagement with policy and practice in Archival Studies than in Library Studies when measured against overall research and education capacity.
I believe that markers of influence are important for elevating the overall profile of Library Studies, and that the initiative should look at this engagement in a further iteration of this work. A comparative perspective would be interesting, thinking firstly of the LAM strands, and then of other practice-oriented disciplines. How do library studies perform in terms of impact on policy/practice compared to other comparable disciplines?
This seems especially important now, given the importance of evidence and arguments in a time of contested value and values.
## Coda: overview of and links to full contribution
**Collection:** LIS Forward (2025) *Responses to the LIS Forward Position Paper: Ensuring a Vibrant Future for LIS in iSchools, The Friday Harbor Papers, Volume 2*. \[[pdf](https://doi.org/10.6069/F6CQ-H317?ref=lorcandempsey.net)\]
**Contribution**: Dempsey, L. (2025). Library Studies, the Informational Disciplines, and the iSchool: Some Remarks Prompted by LIS Forward. In LIS Forward (2025) *Responses to the LIS Forward Position Paper: Ensuring a Vibrant Future for LIS in iSchools, The Friday Harbor Papers, Volume 2*. \[[pdf](https://doi.org/10.6069/F6CQ-H317?ref=lorcandempsey.net)\]
**Contents:** Here are the sections from my contribution. Where I have excerpted them on this site, I provide a link.
- 1 Introduction \[and summary\] \[[excerpted here](https://www.lorcandempsey.net/introduction-and-summary-library-studies-the-informational-disciplines-and-the-ischool-some-remarks-prompted-by-lis-forward/)\]
- 2 Information: a brief schematic history \[[excerpted here](https://www.lorcandempsey.net/information-a-brief-schematic-history/)\]
- 3 Libraries and library studies \[[excerpted here](https://www.lorcandempsey.net/libraries-and-library-studies/)\]
- 4 Informational disciplines \[[excerpted here](https://www.lorcandempsey.net/the-informational-disciplines/)\]
- 5 On the dissemination of ideas and innovation \[[excerpted here](https://www.lorcandempsey.net/on-the-dissemination-of-ideas-and-innovation/)\]
- 6 Symbolic capital
- 7 Recommendations and candidate recommendations
- Coda 1: Google Ngram
- Coda 2: Personal position
- References
---
[\[1\]](#%5Fftnref1) Buschman (2020) talks about ‘white papers’ in the library space, and, focusing attention on the outputs of Ithaka S&R, describes them as ‘empty calories.’
## References
Buschman, J. (2020). Empty calories? A fragment on LIS white papers and the political sociology of LIS elites. *The Journal of Academic Librarianship*, *46*(5), 102215\. [https://doi.org/10.1016/j.acalib.2020.102215](https://doi.org/10.1016/j.acalib.2020.102215?ref=lorcandempsey.net)
Dempsey, L., & Walter, S. (2014). A platform publication for a time of accelerating change. *College and Research Libraries*, *75*(6), 760–762\. [https://doi.org/10.5860/crl.75.6.760](https://doi.org/10.5860/crl.75.6.760?ref=lorcandempsey.net)
Drezner, D. W. (2017). *The Ideas Industry: How Pessimists, Partisans, and Plutocrats are Transforming the Marketplace of Ideas*. Oxford University Press.
**Feature picture:** I took the picture in NYC.
### Libraries and library studies
URL: https://www.lorcandempsey.net/libraries-and-library-studies/
Last updated: 2025-10-22T16:55:04.000Z
This is an excerpt from a longer contribution I made to **Responses to the LIS Forward Position Paper: Ensuring a Vibrant Future for LIS in iSchools.* \[[pdf](https://digital.lib.washington.edu/researchworks/bitstreams/5fb927cc-c3a4-4198-bf04-e3601107308f/download?ref=lorcandempsey.net)\]It is a sketch only, and somewhat informal, but I thought I would put it here in case of interest. It is also influenced by the context in which it was prepared which was a discussion of the informational disciplines and the iSchool in R1 institutions. If you wish to reference it, I would be grateful if you cite the full original: Dempsey, L. (2025). Library Studies, the Informational Disciplines, and the iSchool: Some Remarks Prompted by LIS Forward. In LIS Forward (2025) **Responses to the LIS Forward Position Paper: Ensuring a Vibrant Future for LIS in iSchools, The Friday Harbor Papers, Volume 2*. \[[pdf](https://doi.org/10.6069/F6CQ-H317?ref=lorcandempsey.net)\]
> We often hear it said that libraries (and librarians) select, organize, retrieve, and transmit information or knowledge. That is true. But those are the activities, not the mission, of the library. … the important question is: “To what purpose?” We do not do those things by and for themselves. We do them in order to address an important and continuing need of the society we seek to serve. In short, we do it to support learning. // Robert S. Martin (2003). *Reaching across Library Boundaries. In Emerging Visions for Access in the Twenty-first Century Library.*
> As Robert Bellah observed in *The Good Society* (Knopf, 1991), "Institutions are socially organized ways of paying attention." Hospitals pay attention to illness and health, police pay attention to crime prevention, and the courts pay attention to justice. Similarly, public libraries are society's way of paying attention to learning and equity. In the United States we hold both in high esteem, so we fund public libraries with tax revenues. // Eleanor Jo Rodger (2002). *Value and Vision.*
> \[…\] the similar shift within academic libraries from an existence based on an assumed and stable value that libraries contribute to the institutional mission to a negotiated comprehension of services and resources where social and intellectual capital provide apt and useful frameworks for conceiving of the exchanges that occur between libraries, librarians, users, communities, institutions and other stakeholders. // Tim SchlakinSchlak, T., Corrall, S., & Bracke, P. (2023). *The social future of academic libraries: new perspectives on communities, networks, and engagement.*
## Introduction
The iSchools have the collective resource to situate the library of today in current technology, policy and organizational questions. And potentially to connect to research and education agendas across disciplines.
The report makes clear an immediate challenge - to emphasise and elevate the library research and education agenda within the university. Addressing this seems like a priority. This involves playing (in Bourdieu’s terms) the research university ‘game’, especially looking at what is valued in an R1 institution.[\[1\]](#%5Fftn1) At the same time, today’s libraries will benefit from better frameworks, evidence and arguments to guide them. There is a need for stronger connection to workplace issues and skills, and potentially greater focus on credentialing for ongoing development. Is there a tension between these two goals? Is there a way of aligning academic and practice incentives?
> However, from an educational perspective it is important to see them in their full breadth as institutionalized community and cultural actors. From a research perspective, libraries are sites of major social, organizational and cultural questions.
There are many scholars in iSchools who are making interesting connections with the library as organization, social actor and institution. Within a more technical iSchool context, there may be sometimes a tendency to see libraries as a collection of information management practices. However, from an educational perspective it is important to see them in their full breadth as **institutionalized** **community and cultural actors**. From a research perspective, libraries are sites of major **social, organizational and cultural questions**.
## Libraries
Here are some of the ways in which libraries intersect with broader agendas.
- They are **social, learning and research infrastructure** connected in multiple ways to the communities they serve. They prompt questions about support and investment in social infrastructure, equity, the status of public goods, health and wellness, the construction and maintenance of research and learning infrastructure.
- They are **social creations** where one can explore long standing manifestations of the public sphere, of social capital, of network theory, of memory and forgetting.
- They support **learning** in both directed and emergent ways – early reading, social skills, study spaces, instruction, life-wide learning. This interacts with community agendas around reading, childhood development, equity, pedagogy, student retention, and wellness.
- They have curated **the scholarly and cultural record**, and so offer the opportunity to explore cultural patterns, including legacies of oppression or oversight.
- They are embedded in **evolving scholarly ecosystems** and help influence their direction. They are centrally involved in service and policy questions around open access, scholarly communication, and research infrastructure.
- They have created innovative organizational responses to the **network dynamics** of recent decades, developing network platforms and logistics systems before they were common more broadly. They have built multi-faceted consortia to help distribute collections, infrastructure and expertise. They were early movers to the cloud. They are deeply embedded in collaborative, vendor and other networks, raising strategic, investment and organizational development questions about platforms, network organization, and related topics. This poses interesting organizational development, management, negotiation and partnering strategies and skills.
- They are exploring what **organizational, skills development, and staffing patterns** will support their future as they continue to provide access to the means of creative production. They need a broad array of skills and attributes, some of which will be drawn from outside the MLIS pool.
- Libraries deploy and advise about technologies in a variety of settings – enterprise systems, discovery, content delivery, research workflow, and so on. They are great environments in which to explore the **sociotechnical** evolution of technologies in practice.
Here are some broad ways in which the library may be reconfiguring services, expertise, and positioning.
1. **Scope.** Libraries are co-creating their futures with deeply engaged communities. There is a transition from a library which was transactional and collections-based to one which is relational and community-based. Public libraries have a social role and align services with education and social services, with a range of non-profits and charities. They serve the community’s needs for equity, for educational attainment, for food security, for immigrant services. Academic libraries more deeply engage with campus partners across the research and learning spectrum. They are important partners in research effectiveness, scholarly communication, student retention, and life-wide learning. These trends all create the need for a variety of teachable skills.
2. **Institution.** The library is an institution, embedded in particular social relations, values and investments. As such, it has a history and evolving social and cultural meanings. Rodgers argues that public libraries are society’s way of paying attention to equity and learning. What happens when elements of a society do not value learning and equity? Or where this is not understood by the voter? We see this now in the challenges to the public library. What is the equivalent of ‘learning and equity’ for academic or other libraries? It is important for all libraries to explain their value and story in ways that the host understands, and libraries have been very focused on value, values and vision. For much of its existence these have been stable and accepted. However, the abundance of information resources on the web and the rise of economic liberalism has meant that this can no longer be taken for granted.
3. **Story.** The library story is being retold to be relational, community-focused and generative, but this story is not widely socialized or always understood by those that support or fund libraries. The value of the library cannot be taken as ‘assumed or stable.’ As Bob Martin suggests, an information-based story is not strong, especially as information activities and investigation are diffused through multiple services on the web, personal activities, and disciplinary homes. The library story is being renegotiated.
4. **Empathy and equity.** Recent experiences have underlined the need for the library to purposefully recognize the importance of equity and empathy. Libraries have recognized a need to move past mere statements of diversity and inclusion, to recognize harm or omission and to begin to repair damaging and exclusive practices. The pandemic has also underlined economic inequities, the digital divide, the importance of available social infrastructure, especially for those that critically rely on library spaces and extended services. We know that libraries support mental wellness, social cohesion, digital equity, and personal and community development. Libraries have been asked to step up to additional social roles and to reshape services. This in turn has highlighted staff stress and unpreparedness, and the need for self-care and boundaries.
This makes it an extraordinarily interesting time to prepare people to work in libraries or to investigate them. The library position and role are being re-negotiated and co-created within diverse user communities. This generates educational needs and a wide variety of research questions which would benefit from a multi-disciplinary approach.
> At the same time, today’s libraries will benefit from better frameworks, evidence and arguments to guide them.
## Libarianship and the iSchool
> With new challenges comes a demand for education and for training new skills. This necessity is the topic of this article. We seek the answer to the question of how research librarians can educate themselves to meet the challenges of the unknown ‘new research library’? \[…\] No uniform standardized educational program can take into consideration all the possible paths that the modern research library may choose and therefore all the skills needed by a modern research librarian – and information specialist. // Wien, C. N., & Dorch, B. F. (2018). *Applying Bourdieu’s field theory to analyze the changing status of the research librarian.*
> It’s very important for people who want to work in a library to learn communication skills, advocacy skills, because people with an MLIS are going to rise to leadership roles. It’s not going to necessarily be the entry point anymore for working in a library—there are other entry points. When you’re seeking that MLIS, it should be a management degree. It should be helping people to prepare for leading in some way. // Sari Feldman (2019). Sari Feldman Gets Ready to Transform (Again).
> Of those 11 skills ranked as core, only four could be considered specific to the field of LIS: knowledge of professional ethics, evaluating and selecting information sources, search skills, and the reference interview. The remaining seven are not only more generic but could also be categorized as “soft skills” or personal attributes: interpersonal communication, writing, teamwork, customer service skills, cultural competence, interacting with diverse communities, and reflective practice grounded in diversity and inclusion. // Laura Saunders (2018). Core and more: examining foundational and specialized content in library and information science.
### Learning and teaching
It was always a challenge encompassing the range of desired skills in the MLIS, given the variety of practice-oriented roles a librarian performs throughout their careers and the variety of working environments (youth services, special, academic, public, etc.). The knowledge and skills needed to run libraries effectively continue to evolve, to the extent that it is now common to recruit for other expertise (languages, social work, instructional design, disciplinary knowledge, marketing and communications, research expertise). The library of today requires the skills needed to manage complex changing organizations, engage and nurture diverse communities, negotiate and advocate.
> The library of today requires the skills needed to manage complex changing organizations, engage and nurture diverse communities, negotiate and advocate.
In this context, Sari Feldman’s perspective that the MLS should be a management degree is interesting when placed alongside the demand for increasingly diverse technical skills (data science, data curation, application development, content licensing, collection development, instructional design, and so on) and a broad range of other vocational and general skills (communications, project management, and so on).
The skills and competencies required by the library (and related organizations) have been the subject of ongoing research (e.g. Saunders). And different career stages may prompt very different responses, depending on role, administrative responsibilities, and so on.
Of course, programs may offer different pathways, there may be specialisms (legal, health, …), and there is a variety of joint options possible in some settings (with an MBA for example, or history, or some other discipline).
Is the library education market large enough for eMBA or eMPA style MLSs for those in library management career paths? What about additional certificate-style credentials? These may be in technical areas (data science or AI, for example), in public administration or public policy, in intellectual freedom, in negotiation, in social work, in industrial relations, in copyright, and so on.
The University of Southern Denmark took an interesting approach. In the article above the authors argue that the prestige of the research librarian[\[2\]](#%5Fftn2) has declined and that it is not actually clear what skills they will need to do their jobs given the evolving nature of the research library. They introduced a masters program which allowed students to combine some LIS courses with courses from elsewhere in the University and beyond which they feel prepares them best.[\[3\]](#%5Fftn3)
Has Library Studies kept up with the changing library landscape? Is it well-positioned to educate the library workforce or to guide its development? In its current iteration the report does not look at career preparation needs or the research and policy interests of the library community they serve. Anecdotally, one is aware of concerns that there is a gap here. Closing this gap is clearly a priority, although one has to understand it first. This is naturally a focus of individual schools and their positioning and emphases.
More collectively, it would be useful to do some research about career preparation needs and research and policy interests in the context of an exploration of Key Areas for education and research. A part of the ambition I spoke about in the introduction should surely involve some recalibration of the library education and research agenda, to ground and connect.
That said, again, the ability to refocus within the existing model in R1 institutions is limited in various important ways.
The Report does not discuss curriculum, and the candidate range could be broad given the discussion above. Here are some high-level library emphases, which do not necessarily map onto potential courses, but which suggest some directions. It is of course just indicative and incomplete.
#### Nurturing and engaging community
As the library engages with a variety of community partners, a set of collaboration, communication and other skills is required. This might include supporting student success and retention and research workflows in academic settings. In a public library setting, the library is welcoming the community to its space with a growing variety of creative activities and events. It is partnering with social and educational services, with local charities or cultural institutions, with schools and colleges. It is reaching previously overlooked or marginalized populations, it is developing special programs for particular language groups, it is providing services for immigrants. Skills around, for example, community engagement, instruction, event management, public health, and exhibitions are more important.
#### Values
The Report emphasizes LIS values. The importance of equity and empathy has been underlined in recent years. Both within the structures of the library itself, and in relation to the role of the library within its community. Libraries are refocusing organizational cultures and values, the importance of reparative action in relation to collections, practices and attitudes, and are more actively working to understand and practice inclusion, plurality and diversity. They are working to embrace more justly the experiences, memories and knowledges of all the communities they serve.
#### Social and so-called soft skills
So-called soft skills, and the contributions of the (often female) library workers who demonstrate them, have often been undervalued or gone unobserved. However, the value and visibility of this work is increasingly recognized as critical (see for example Decker, Dempsey). This is especially so as the library is more relational and collaborative. These are learnable skills which include advocacy, negotiation or conflict resolution, for example, or empathy, communications and teamwork. So-called soft skills are actually very hard, especially in the stressful contexts that have become common in some public library settings.
> So-called soft skills, and the contributions of the (often female) library workers who demonstrate them, have often been undervalued or gone unobserved.
#### Administrative and organizational
The skills required to manage complex connected organizations are various. It is common now to have a Management of People and Organizations course (or some such) which may end up being overloaded.
- Management of complex organizations, relationships and tasks.
- Greater project-based work.
- Negotiation – for content, services and collaborative work.
- Strategic planning and budgeting.
- People recruitment, retention and development.
- Creating diverse and inclusive environments for users and for staff.
- Working in consortial and collaborative environments.
- Organizational development.
- Industrial relations.
- Fund raising.
- Grant work.
#### Positioning, communication and advocacy
Traditionally, libraries may have distrusted ‘marketing’, however developing the library story has become more important given changing roles and current pressures around value and values.
- Communications and marketing – ensuring that the library story and position is well understood within its community, and elsewhere.
- Advocacy – representation of library interest to voters, host institutions, funders, user groups, and others.
#### Information policy and intellectual freedom
Balancing the rights of creators and consumers, pricing of licensed materials, open access discussions, information ethics, digital equity, attitudes to harvesting for AI or search – there is heightened attention to a range of information policy issues where libraries have to make decisions, advocate, and implement. Librarians also need to understand the legal framework of intellectual freedom, to be equipped with strategies and arguments in a contested political environment, and to have access to updated information.
#### Specialist skills
A growing number of staff will be drawn from outside the MLIS ranks. We already see this in roles like communication and marketing, technology, development, social work, subject specialties. Certificates or other approaches offered in partnership with others on campus may become more useful. Public Administration or instructional design come to mind, for example.
#### Information management
Of course, this is a historic core. The iSchool location is valuable in terms of the expanding information management skills of interest. Career preparation certainly benefits from options in data science, programming, research data management, instructional technology, metadata management, and so on.
## LIS Forward
As noted throughout, the position of Library Studies within the university, its relationship to other informational disciplines, and its practice orientation have been much discussed. LIS Forward places this discussion in the current iSchool dynamic, a multidisciplinary school in an R1 institution.
As noted, it is in some ways a story of progressive subsumption. Schools of Library Studies diversified into LIS to reflect the changing technology environment, and the variety of informational careers students were following. LIS was subsumed into broader schools of information, as information processing and management became more common. The possible range is very wide, from quite vocationally oriented information systems, to social and philosophical aspects of an informational society, to values-driven social justice and equity emphases. In some cases, informatics or related undergraduate degrees were added. The Report makes clear that Library Studies feels squeezed or undervalued, despite reporting continued demand for the MLS. There are also questions about balance between teaching-oriented faculty and research faculty, as this educational demand continues, as well as increased use of guest faculty.
Given that this is a recurrent discussion, given the gap to practice, given the putative advantages of the multidisciplinary environment, and given the ‘urgency’ expressed in the report, one might expect that a strong response is required. To move the needle, after all, the needle must be moved.
I suggest some candidate areas for attention in the recommendations below. As noted in the introduction, I emphasize these four factors in relation to education and research for libraries throughout:
1. the benefits of increasing the awareness, scale and impact of research and policy work through a more concertedly collaborative approach,
2. the benefits of reconnecting more strongly with libraries and related organizations, and the organizations that channel their interests, which includes discussion of more flexible and tailored learning and certification reflecting evolving skills and workplace demands,
3. the possible benefits of refocusing this particular discussion of Library Studies around the institutional and service dynamics of LAM and connecting that with a variety of disciplinary hinterlands (public administration, social studies, and so on) and moving away from the familiar and maybe superseded discussions about IS, LIS and so on,
4. the benefits of developing an agenda of Key Areas which connect with current library needs, and which can provide some rationale or motivation for recruitment, research activity, granters, collaborative activity and so on. If iSchool education and research respond more actively to evolving library issues, the people with appropriate skills and interests need to be in place.
This was written before the current administration came into office in the US. I have not updated it in that context.
## Coda: overview of and links to full contribution
**Collection:** LIS Forward (2025) *Responses to the LIS Forward Position Paper: Ensuring a Vibrant Future for LIS in iSchools, The Friday Harbor Papers, Volume 2*. \[[pdf](https://doi.org/10.6069/F6CQ-H317?ref=lorcandempsey.net)\]
**Contribution**: Dempsey, L. (2025). Library Studies, the Informational Disciplines, and the iSchool: Some Remarks Prompted by LIS Forward. In LIS Forward (2025) *Responses to the LIS Forward Position Paper: Ensuring a Vibrant Future for LIS in iSchools, The Friday Harbor Papers, Volume 2*. \[[pdf](https://doi.org/10.6069/F6CQ-H317?ref=lorcandempsey.net)\]
**Contents:** Here are the sections from my contribution. Where I have excerpted them on this site, I provide a link.
- 1 Introduction \[and summary\] \[[excerpted here](https://www.lorcandempsey.net/introduction-and-summary-library-studies-the-informational-disciplines-and-the-ischool-some-remarks-prompted-by-lis-forward/)\]
- 2 Information: a brief schematic history \[[excerpted here](https://www.lorcandempsey.net/information-a-brief-schematic-history/)\]
- 3 Libraries and library studies \[[excerpted here](https://www.lorcandempsey.net/libraries-and-library-studies/)\]
- 4 Informational disciplines \[[excerpted here](https://www.lorcandempsey.net/the-informational-disciplines/)\]
- 5 On the dissemination of ideas and innovation \[[excerpted here](https://www.lorcandempsey.net/on-the-dissemination-of-ideas-and-innovation/)\]
- 6 Symbolic capital
- 7 Recommendations and candidate recommendations
- Coda 1: Google Ngram
- Coda 2: Personal position
- References
## References
Buckland, M. (2012). What kind of science can information science be? *Journal of the American Society for Information Science and Technology*, *63*(1), 1–7\. [https://doi.org/10.1002/asi.21656](https://doi.org/10.1002/asi.21656?ref=lorcandempsey.net)
Cronin, B. (1995). Shibboleth and Substance in North American Library and Information Science Education. *Libri*, *45*(1), 45–63\. [https://doi.org/10.1515/libr.1995.45.1.45](https://doi.org/10.1515/libr.1995.45.1.45?ref=lorcandempsey.net)
Decker, E. N. (2020). The X-factor in academic libraries: the demand for soft skills in library employees. *College & Undergraduate Libraries*, *27*(1), 17–31\. [https://doi.org/10.1080/10691316.2020.1781725](https://doi.org/10.1080/10691316.2020.1781725?ref=lorcandempsey.net)
Dempsey, L. (2024, March 7). So-called soft skills are hard. *Lorcan Dempsey Dot Net*.
Feldman, S. (2019, May 15). *Sari Feldman Gets Ready to Transform (Again)* \[Interview\]. [https://www.libraryjournal.com/story/sari-feldman-gets-ready-to-transform-again](https://www.libraryjournal.com/story/sari-feldman-gets-ready-to-transform-again?ref=lorcandempsey.net)
Martin, R. S. (2003). Reaching across Library Boundaries. In *Emerging Visions for Access in the Twenty-first Century Library*. CLIR. [https://www.clir.org/pubs/reports/pub119/martin/](https://www.clir.org/pubs/reports/pub119/martin/?ref=lorcandempsey.net)
Rodger, E. J. (2002). Value and Vision. *American Libraries*, *33*(10). [https://www.webjunction.org/documents/webjunction/Value\_and\_Vision.html](https://www.webjunction.org/documents/webjunction/Value%5Fand%5FVision.html?ref=lorcandempsey.net)
Saunders, L. (2019). Core and More: Examining Foundational and Specialized Content in Library and Information Science. *Journal of Education for Library and Information Science*, *60*(1), 3–34\. [https://doi.org/10.3138/jelis.60.1.2018-0034](https://doi.org/10.3138/jelis.60.1.2018-0034?ref=lorcandempsey.net)
Schlak, T., Corrall, S., & Bracke, P. (2023). *The social future of academic libraries : new perspectives on communities, networks, and engagement*. Facet Publishing.
Wien, C. N., & Dorch, B. F. (2018). Applying Bourdieu’s field theory to analyze the changing status of the research librarian |. *LIBER Quarterly: The Journal of the Association of European Research Libraries*, *28*(1). [https://liberquarterly.eu/article/view/10719/11586](https://liberquarterly.eu/article/view/10719/11586?ref=lorcandempsey.net)
---
[\[1\]](#%5Fftnref1) Blaise Cronin (1995) is caustic about librarianship’s inability to play the university game (he does not express the thought in these words), tying this directly to closure of library schools. He argues for the ‘decoupling’ of the L and the IS in LIS, and, in his discussion of a candidate future, foreshadows something of the multi-disciplinary way in which the iSchool actually developed.
[\[2\]](#%5Fftnref2) The authors use ‘research librarian’ in a specialist sense which seems somewhat similar to library faculty in the US.
[\[3\]](#%5Fftnref3) This particular program is no longer offered but in a personal communication one of the authors informs me that it is possible to assemble a similar program at a more general level within the university.
**Feature picture:** I took the picture on a trip to Calgary.
### Clifford A Lynch, RIP
URL: https://www.lorcandempsey.net/clifford-a-lynch-rip/
Last updated: 2025-09-07T02:57:54.000Z
Cliff has left a major legacy and a large gap. Read the touching tributes from [ARL](https://www.arl.org/news/memorial-clifford-lynch/?ref=lorcandempsey.net) and [CNI](https://www.cni.org/news/in-memoriam-clifford-lynch?ref=lorcandempsey.net).
I first met Cliff in 1990\. I was on a study trip to the US and Canada, commissioned by the British Library to prepare a report on emerging network trends in libraries, with a special emphasis on the US. It was an early activity associated with UKOLN at the University of Bath, which the BL partly funded (the UK Office for Library and Information Networking, which has since ceased to exist).
The Division of Library Automation at the University of California, under Cliff's leadership, had been a pioneer in networking and shared systems. Melvyl was an important early example of a shared, network system with some scale, and Cliff was an authority on the emerging Z39.50 protocol which was a central part of what I was looking at.
It was my first trip to the US. I was a little nervous, compounded by the fact that my wardrobe was unsuited to the climate and the relaxed Californian working environment. However, I was immediately put at ease by Cliff's gentle, curious welcoming manner. He was very generous with his and his colleagues' time, and created a schedule with care and attention.
I observed with interest the collegial working environment he fostered in the office. This was my first introduction to Cliff in person - to his thoughtful conversation and gracious social presence. It was a revelation for me and provided a glimpse into what was to make his contribution to libraries and the research community so special over many years. He combined deep computational knowledge with a complex appreciation of the evolving scholarly and cultural record in a network environment. This was integral to how he saw libraries - as critical and inseperable elements of the infrastructure and practice of research and scholarship.
Later, when the report was published, Cliff reviewed it at length. Characteristically, the review [appeared](https://uh-ir.tdl.org/items/9add4b76-4a5f-4ba8-982a-5468dd0cc828/full?ref=lorcandempsey.net) in what we might now call a Diamond access publication, The [*Public-Access Computer Systems Review*](https://uh-ir.tdl.org/communities/11c822e5-d7d4-4f99-a613-fe1f4eb03dc1?ref=lorcandempsey.net), an important early electronic journal. I think the positive review may have influenced the release of a [second edition](https://search.worldcat.org/en/title/185576057?ref=lorcandempsey.net) of the report by Meckler for a US audience.
He correctly identified some of the traits of my subsequent writing career:
> Sometimes, the coverage is a bit encyclopedic, which makes for slightly tedious reading, but such detail is necessary in a comprehensive report.
From my current perch in the US, I was interested to be reminded of this passage from his kind concluding comments.
> This is a wonderful book that we should thank Dempsey for writing and the British Library for supporting. (I do find myself thinking, parochially, that it is strange that the first real book on these topics has been written from a European perspective and underwritten by the British Library. The topics covered are terribly important to the library, information science, and networking communities. Why hasn't this type of book been written from a U.S. perspective?)
This visit began a long relationship.
Cliff later came to the UK to present in the series of conferences we organized at the University of Bath. I remember a discussion in Bath between Cliff and the affable and inspirational Paul Evan Peters, who was at the time the inaugural leader of the Coalition for Networked Information. They agreed that they would readily pay for a service that managed the transfer of their luggage between destinations, with which they could then occasionally rendezvous. That said, packing was simplified for Cliff as he became identified with a standard outfit of jeans and blue oxford shirt.
From this vantage point, it is difficult to capture the excitement of those early Internet years. There was a magical and formative period, between that early promise and the later Amazoogle enclosure. And the inclusive and generous vision of Paul, Cliff and the early CNI was an important part of that, aiming initially to provide a venue for conversation between libraries, publishers and technologists. While the library element may have come to dominate, it always fostered connections.
It was in Bath also, that we met Cecilia for the first time, which began a long exchange about Irish tea and whiskey and yarn. Cliff's work depended on Cecilia's support in so many ways.
Professional and personal interactions continued as CNI developed a strong working relationship with UKOLN and with Jisc, the national information and networking infrastructure organization, with which I later worked for a while. We organized a series of [joint US/UK conferences](https://www.cni.org/events/events-co-sponsored-by-cni/jisc-cni-conference?ref=lorcandempsey.net), which provided an ongoing collaborative venue, and an important input into the [extensive project and development](https://www.lorcandempsey.net/the-digital-library-environment-10-years-after/) work of Jisc in subsequent years.
Cliff was also a contributor to the second Dublin Core meeting which UKOLN jointly organized in Warwick in the UK. I remember reading a transcript of some remarks by Cliff on this event which rendered 'Warwick' as 'Woolworths.' And indeed, 'divided by a common language' was the title I adopted for a presentation I was invited to give to the [fourth Jisc/CNI event](https://www.ukoln.ac.uk/events/jisc-cni-2002/programme.html?ref=lorcandempsey.net) about differences between the UK and the US library environments. Again, I remember speaking to Cliff about my remarks, considering on the one hand the incredible volume and variety of institutions in the decentralized US higher education environment, and on the other, the important shared services infrastructure being put in place by Jisc in the UK. We joked about how far away hills seem greener, so that while some of the US delegates envied the shared attention possible through Jisc in the UK, many of the UK delegates envied the scale and capacity of the larger US organizations.
When I was first offered a job in the US I immediately reached out to Cliff for advice. Later, when I occasionally entered into discussions about other jobs, I sometimes sought his guidance. On one memorable (for me) occasion, he strongly advised that I withdraw my interest in a library Dean role: he argued that the library in question did not have great institutional support. He was always candid and direct in this way, even as his delivery remained gentle and considered. I remember I sent him a piece I had written early in the pandemic about likely trends. He gently nudged me away from publishing it, as something that would date badly.
For many people, Cliff was CNI. Although of course he always acknowledged the strong contributions of Joan and of the other members of the team that made it work. When I think about CNI and Cliff's CNI career three things stand out for me.
First, Cliff and his colleagues made CNI an extraordinarily successful venue for scaling learning and innovation across the library community and beyond. As much as through any formal presentations, this was through the congregation and personal networks it facilitated. Like all successful networks, it offered a venue where people could pool their uncertainty, gain confidence in new approaches, connect with like minds, identify potential hires or new job opportunities, and serendipitously connect with people and ideas. This is how norms, ideas, and innovation diffuse. It promotes sharing, mentoring, and career growth. This was valuable in immeasurable ways.
Second, there was Cliff's intellectual contribution. I would occasionally remark that CNI was a brain support mechanism for Cliff, and I was only half-joking. I believe that many members were more than happy to make an investment in CNI in order to provide a community space for Cliff to reflect on directions and to share his thoughts. Colleagues valued his luminously synthetic introductions to the meetings, the publications that immediately patterned your response to particular topics, his remarkably fluent presentations delivered with a few notes, and his generous counsel. His reading was wide, across the very technical, as well as the social and cultural. Much will be said about all of this by others. I will just note here that no matter how often one saw him do it, one was always awestruck by his range, insight and shaping powers.
Finally, Cliff was a bridge from the research library community to other communities and organizations. His effectiveness here depended not only on the knowledge and insight he brought into any conversation, but also on the universal recognition that he was motivated by a desire to lift up all interested parties in support of research and scholarship.
Perhaps the library community doesn't have the scale to generate a deep historical perspective. It would be especially interesting to document the web of influence and development in the period in which Cliff was active, which saw research, learning and cultural expression shape and be re-shaped by the evolving material base of the network and the digital.
Cliff has a special place as somebody whose work and writing with the University of California influenced emerging library services, and who transitioned into a role where he selflessly and persistently worked to help a community be a better version of itself.
Work interests meant that I did not go to CNI regularly for several years. I was very pleased when Cliff asked me to deliver the keynote at CNI after my departure from OCLC was announced. It did not turn out to be my best outing; I was trying too much to live up to the occasion and I ended up saying too little because I actually said too much.
Cliff was kind and I was touched by the enthusiasm with which he described how keynote speakers were added to the CNI meeting invitation list. In this way, he suggested in his reserved way, he hoped I would attend future meetings. I will miss the opportunity of being able to relax into such quiet interactions based on long shared history and conversations.
Cecilia's loss is immense. It may be a small comfort to know that Cliff's influence is strong and active in all the lives that he touched.
**Note:** Feature picture and caption by John Kirriemuir in a 1997 [interview](https://www.ariadne.ac.uk/issue/10/clifford/?ref=lorcandempsey.net) with Cliff for *Ariadne*. Cliff talks about his role at the University of California and his transition to CNI, as well as about various network information topics.
### Information: a brief schematic history
URL: https://www.lorcandempsey.net/information-a-brief-schematic-history/
Last updated: 2025-10-22T16:57:55.000Z
This is an excerpt from a longer contribution I made to **Responses to the LIS Forward Position Paper: Ensuring a Vibrant Future for LIS in iSchools.* \[[pdf](https://digital.lib.washington.edu/researchworks/bitstreams/5fb927cc-c3a4-4198-bf04-e3601107308f/download?ref=lorcandempsey.net)\] It is a sketch only, and somewhat informal, but I thought I would put it here in case of interest. It is also influenced by the context in which it was prepared which was a discussion of the informational disciplines and the iSchool in R1 institutions. If you wish to reference it, I would be grateful if you cite the full original: Dempsey, L. (2025). Library Studies, the Informational Disciplines, and the iSchool: Some Remarks Prompted by LIS Forward. In LIS Forward (2025) **Responses to the LIS Forward Position Paper: Ensuring a Vibrant Future for LIS in iSchools, The Friday Harbor Papers, Volume 2*. \[[pdf](https://digital.lib.washington.edu/researchworks/bitstreams/5fb927cc-c3a4-4198-bf04-e3601107308f/download?ref=lorcandempsey.net)\]
## Introduction
> The word information has been used so much that it has come to dominate discourse (Day, 2001). \[…\] Vagueness and inconsistency are advantageous for slogans and using “chameleon words” that assume differing colors in different contexts allows flexibility for readers to perceive what they wish. // Buckland, M. (2012). What kind of science can information science be? *Journal of the American Society for Information Science and Technology.*
> I should like to draw an analytical distinction between the notions of “information society” and “informational society,” with similar implications for information/informational economy. The term “information society” emphasizes the role of information in society. But I argue that information, in its broadest sense, e.g. as communication of knowledge, has been critical in all societies \[…\]. In contrast, the term “informational” indicates the attribute of a specific form of social organization in which information generation, processing, and transmission become the fundamental sources of productivity and power because of new technological conditions emerging in this historical period. My terminology tries to establish a parallel with the distinction between industry and industrial. An industrial society (a usual notion in the sociological tradition) is not just a society where there is industry, but a society where the social and technological forms of industrial organization permeate all spheres of activity, starting with the dominant activities, located in the economic system and in military technology, and reaching the objects and habits of everyday life. My use of the terms “informational society” and “informational economy” attempts a more precise characterization of current transformations beyond the common-sense observation that information and knowledge are important to our societies. *// Castells, M. (2009). The Rise of the Network Society, With a New Preface : the Information Age: Economy, Society, and Culture Volume I (2nd ed)*
I look very briefly at our senses of information itself as it is the context for the discussion about informational disciplines to follow. It is certainly a ‘chameleon’ word. It has become so widely used as to become drained of specificity unless explicitly qualified in particular circumstances.
Raymond Williams’ *Keywords* does not include an entry for ‘Information,’ which is telling. This influential work gave rise to multiple subsequent collections which aim to update it or adapt it to particular domains. I quote from the entries on ‘information’ in three of these here:
> Information as keyword — digital or otherwise — did not exist before the twentieth century. \[…\] Then, unexpectedly, in the 1920s this formerly unmarked and unremarkable concept became a focal point of widespread scientific and mathematical investigation. // ‘Information’ by Bernard Geoghegan in Peters, B. (Ed.). (2016). *Digital Keywords.*
> Toward the end of the C20 “information” became a popular prefix to a range of concepts that claimed to identify essential features of an emerging new sort of society. The **information explosion**, **information age**, **information economy**, **information revolution**, and especially **information society** became commonplace descriptions (Castells, 1996-8; Webster, 2002). These covered, and tried to conceive, disparate phenomena, perhaps unwarrantedly. The concepts appeared superficially to capture similar phenomena, yet on closer inspection centered often on quite different things. For example, their concern ranged over a general increase in symbols and signs that accelerated from the 1960s (the information explosion); the development of information and communications technologies, especially the Internet (the **information superhighway**, reputedly coined by US vice-president Al Gore), the increased prominence of information in employment (**information scientists**, **information labor**, **information professions**); the growing significance of tradable information (information economy); and concerns for new forms of inequality (the **information divide**, the **information rich/poor**). // ‘Information’ by Frank Webster *in* Bennett (2005) *New Keywords: a Revised Vocabulary of Culture and Society.*
> As burgeoning use of information in preference to related terms encroaches on the word’s surrounding lexical field, questions arise as to how everything from the human genome to celebrity gossip can so readily be referred to as information. // ‘Information’ in MacCabe, C., & Yanacek, H. (2018). *Keywords for today : a 21st century vocabulary : the keywords project.*
Geoghegan notes the relatively recent general use of the word, and is primarily interested in the information-theoretic work of Shannon and others in the mid-20th century which was important for the development of telegraphy and in subsequent years of computing, cryptography, genetics, network theory and other areas (although was ultimately not very influential in Library Studies or related fields, as Hjørland (2018) points out). The other two excerpts emphasise growing use of the word throughout the latter half of the 20th Century. Webster (a sociologist who has specialized in information-related topics and has written about public libraries) notes the way in which it became attached to various generally descriptive labels, notably of course in the ‘Information society’ and for our purposes ‘Information science.’
The quotes above underline the strong emergence of information-related issues as a topic of investigation, and as an explanatory framework in different contexts. Given this widespread use, any account of information is also going to be provisional and contextual.
As background here, I sketch a very schematic overview of information history which departs from the W. Boyd Rayward (2014) account which influenced it.
> However, as Castells notes, this “common-sense observation that information and knowledge are important to our societies,” is not in itself very revealing.
This may seem a little hubristic, but I am prompted to insert it here by the common assertion in iSchool materials – accompanied by such phrases as the ‘knowledge economy’ or the ‘information age’ – that the importance of information in our world elevates the work of the iSchool.
However, as Castells notes, this “common-sense observation that information and knowledge are important to our societies,” is not in itself very revealing.
Information has also gone beyond the bounds of any one subject. The chemist or the cultural geographer or the sociologist has an informational perspective. In this context, it seems to me, the promise of the iSchool is not that it has specialist or unique expertise, but that it can bring together a historical perspective and a multidisciplinary focus.
For reasons that should be clear, I do not attempt to define information here. See Bates (2010) for an exhaustive review of definitions, which, more than anything, suggests why a singular view is unlikely.
For convenience, I reference Michael Buckland’s (2017) pragmatic and functional account.
- *Information as thing*. Informational artifacts – books, passports, menus. Broadly synonymous with Buckland’s inclusive view of ‘document.’
- *Information as process*. Becoming informed.
- *Information as knowledge*. Intangible. Fixed in ‘things.’ Imparted in the informing process.
In their reflective overview of information definitions in IS, Dinneen and Bauner (2017) note that “Buckland was aware that the overall account was likely to disappoint the pickiest of theorists.” While a more conceptual characterization—such as Bateson’s "a difference that makes a difference" or Bates’ "the pattern of organization of matter and energy"—might offer additional nuance or insight, it is less well-suited to my purposes. Dinneen and Bauner (2017) favor the recently influential work of Floridi, which also, incidentally, is highlighted in the important information science textbook, Bawden and Robinson (2022).
I reference it mostly because its somewhat technocratic emphasis is convenient. Much of the emphasis of library studies or information science is indeed on the recorded information that can provide a part of the material base for some of the more abstract or general uses above. And also partly because Buckland is such an interesting and historically influential figure in this discussion (librarian, leading Information Science theorist and practitioner, central player in the iSchool movement at Berkeley (Buckland, 2024)).
I take the pivotal mid- to late mid-twentieth Century as a starting point. As noted above, information was foregrounded in a variety of ways at this time, and terms such as ‘information science’ and ‘information society’ emerged. I refer to this as *the short age of documents*, a reference to the discourse around the challenge of managing recorded information.
Then, we have the long period before this, in which recorded information was manifest in print or manuscript forms. I refer to this as *the long age of literacy and print*.
And third, we have the short period after this, which we are now living through. While we can characterize this as a digital or network age, the more interesting point here is that an informational perspective becomes more common, extending to social and political contexts. Modern institutional constructs -- markets or bureaucracies for example -- can be seen in informational terms. I refer to this as *the informational age* (influenced by Castells’ characterization of the current period).
Furthermore, it is now common to reinterpret the past through an informational lens. Perhaps the most interesting recent example of this is Youvel Noah Harari's ambitious *The Nexus*, which was published recently to mixed reception. He tends to see any ‘intersubjective reality’ as informational. He takes a long historical view, discussing developments as stages in the emergence of information networks. For example, he discusses the difference between democratic and totalitarian regimes as a difference between self-correcting and closed information networks. He talks about civilizations as combinations of a managerial and operational bureaucracy and a legitimating or imposed mythology, each again very much an informational apparatus. He reinterprets the past in terms of an informational present; here he is, for example, talking about the impact of printing: “print allowed the rapid spread not only of scientific facts but also of religious fantasies, fake news, and conspiracy theories.”
In this period also there is a strong emphasis on information critique, and with the advent of AI, perhaps, as I will suggest, we are seeing the apotheosis of the document.
## The long age of literacy and print
The emergence of the document marked an important early transition.
Writing allowed thought to be externalized, fixing information in a medium that could persist across space and time. In an oral culture, knowledge had to be remembered. Mnemonic techniques and repetition aided memory. It was retained through song, story and ritual.
As Walter Ong and others have argued, the external documentary accumulation of knowledge co-evolved with a profound shift in the structure of thought, knowledge and communication, evident in the development of more abstract and systematic forms of thinking, the emergence of formal learning and scholarship, the development of laws, the codification of expertise, and so on. This intensified after the invention of movable type.
> Libraries are a strongly institutionalized response to the print distribution model, where information or cultural resources were expensive or available in limited ways.
From then until the Second World War, say, information exchange was dominated by the production and exchange of print. Infrastructures and institutions emerged which helped create, manage and preserve documents, including libraries, archives, scholarly societies and publishing, publishers, commercial distribution mechanisms, and so on.
Libraries are a strongly institutionalized response to the print distribution model, where information or cultural resources were expensive or available in limited ways. Efficient access required the physical proximity of collections to their potential readers, and libraries built local collections to make them conveniently available within their communities. In this way, collection size and transaction volumes became a signifier of quality. Those interested in technical, scholarly, cultural or other documents built their workflow around the library.
So, while at a material or mechanical level, we see the progressive intensification and amplification of the production and exchange of documents, a greater variety of ways of processing information, and the massive accumulation of recorded knowledge, the more interesting story involves the mutual interaction between this and social and cultural life.
The progressive connectedness and complexity of social contexts entails progressively more communication across time and space, and a corresponding expansion of the external shared documentary accumulation of expertise and knowledge. Libraries are a part of the apparatus for retaining and sharing that documentary record.
## The short age of documents
In the mid-20th Century, the production, circulation, and institutionalization of information expanded significantly, shaped by the ongoing interplay between social structures, technological developments, and organizational demands. The Second World War itself accelerated this, intensifying the need for systematic coordination across scientific, governmental, and industrial domains. There was growth in the scientific and technical literature, while governments and institutions expanded their administrative records, accompanying new forms of bureaucratic surveillance and tracking. Businesses became increasingly reliant on structured data, for decision-making, to optimize workflows, to comply with regulatory frameworks, and so on.
In this way, the volume and variety of documents (again, broadly understood) continued to grow, as did the processes by which they were shared. It is in this period, as noted above, that Information Science emerged, as a response to the challenges of managing this abundance of information in various ways.
Through the sixties and later, there was a focus on the structural changes brought about by “knowledge-intensive production and a post-industrial array of goods and services.” (Lash) This work was informed by the empirical work of Porat and Machlup and others and was given influential synthetic expression as the ‘information society’ or the ‘post-industrial society’ in the work of Daniel Bell. Peter Drucker also popularized the concepts of ‘knowledge work’ and ‘knowledge worker’ during this period.
In successive decades, digital information systems emerged – chemical information, health and legal systems, early knowledge management, and so on.
In this period also there was some modest social institutionalization of Information Science and related areas. The *American Documentation Institute* (ADI) was founded in 1937, becoming the *American Society for Information Science* (ASIS) in 1968\. It acquired a final ‘t’ for technology in 2000, and finally became the *Association for Information Science and Technology* in 2013\. The *Institute of Information Scientists* was formed in the UK in 1968, and merged with the *Library Association* in 2002 to form *CILIP*. IFIP (*International Federation for Information Processing*) was founded in 1960.
## The evolving informational age
> Then it looks at how the logic of information flows reterritorialize into new formations of the brand, the platform, the standard, intellectual property and the network. \[…\] The primary qualities of information are flow, disembeddedness, spatial compression, temporal compression, real-time relations. It is not exclusively, but mainly, in this sense that we live in an information age. // Lash, Scott (2002). *Critique of information.*
In his highly influential three volume *The Information Age*, Castells talks of a network society and an informational society. I will use this to frame an introduction to the current period, dating from the late 20th Century.
Contributory factors in this period are the accelerated evolution of communications and computational capacity which has provided the material base for a range of other developments. These include the restructuring and intensification of capitalism brought about by deregulation, privatization, global extension and geopolitical changes; the network flows of money, data and people which have changed how we think about the boundaries of organizations, nations and personal relations; and the ongoing transformation of the media, personal communications, and the means of shaping public opinion.
This environment rests on complex network systems, aggregations of data, and applications which communicate via protocols and APIs. This material base has co-evolved with social organization. For Castells (as for Lash and Harari), a key feature is the organizing power of networks, throughout all aspects of what we do.
For example, network effects have led to several dominant platforms that articulate much of our social, cultural and business activities (the Amazoogle phenomenon). Retail, music and entertainment were transformed. The flow of materials is monitored by tracking systems, and is articulated in complex just-in-time supply chains; mobile communications and mapping services have changed our sense of mobility and delivery; distribution chains, the disposition of goods around retail floors, investment decisions, variable real-time pricing, and many other taken for granted aspects of what we do are driven by the collection, exchange and analysis of data.
From a functional point of view, varieties of 'Informationalisation' are visible at all levels in everyday life: doors open automatically, material money is disappearing; advanced instrumentation for observation and analysis is common in the sciences. Increasingly, our activities yield up data which influences what products are offered to us, the news we see, and so on.
Something as apparently simple as the selfie has interacted with behaviors to affect mental wellness, the travel industry and communication.
It is this sense of qualitative change that prompts Manuel Castells to pose the distinction between the ‘information society’ and the ‘informational society.’ We are now seeing an intensification of some of the informational trends he observes as AI becomes more common.
Castells discusses how the network has facilitated broad coordination of interests, in social movements, popular uprisings, or organized crime, for example. It extends to a global scale, where a network of megacities channels power and innovation. He suggests that there is at once a global integration facilitated by the network, but, at the same time, a growing fragmentation between those connected to the network circuits of power and prosperity and those not connected.
More recently, we also see a counter force to global integration. Rather than frictionless global information flow, we are seeing regimes forming around power blocs, with different policy, control and regulatory regimes. Think of the US, EU, Russia and China. There has also been some argument that unequal participation in the ‘knowledge economy’ is a factor in emerging political polarization.
Given this general importance, there has also been an interesting and unsurprising informational development in modern theory. This has come into our field most clearly perhaps in Jurgen Habermas’ concept of the public sphere, but think also, for example, of Anthony Giddens’ concept of ‘reflexive modernity’ or Ulich Beck’s ‘risk society.'
For Giddens' ‘reflexive modernity’ entails the “... the reflexive ordering and reordering of social relations in the light of continual inputs of knowledge affecting the actions of individuals and groups” so that “production of systematic knowledge about social life becomes integral to system reproduction.” Modern life rests on the dynamic reassessment of available information and expertise (in construction, engineering, medicine, technology, …), which builds on the accumulated record of science and technology.
I have chosen to reference the social sciences here, as informationalization and social and cultural change are intricately linked. It is also notable how little reference there is to classical information science in this discussion.
## The generative turn: the apotheosis of the document
> Instead, these AI systems are what we might call cultural technologies, like writing, print, libraries, internet search engines or even language itself. They are new techniques for passing on information from one group of people to another. Asking whether GPT-3 or LaMDA is intelligent or knows about the world is like asking whether the University of California’s library is intelligent or whether a Google search “knows” the answer to your questions. But cultural technologies can be extremely powerful—for good or ill. // Alison Gopnik, 2022.
The current form of generative AI emerged as late as 2023\. I find Alison Gopnik’s characterization of it as a cultural technology helpful. She places it in a historical context as the latest technique for passing information from one group of people to another, again considering information very broadly. I was interested to see her place libraries in this frame as well.
Effectively, large language models are statistical models derived from vast accumulations of documentary representations of knowledge. In the context of the narrative presented here, the volume and variety of documents is now so great that they are treated as a proxy for knowledge. Proponents of intelligent AI argue that the models, working with both the broad accumulated representation of knowledge in the training collections, and with massive compute, can find a way to not only summarize and generalize from the content of those documents, but also to replicate the minds that created them.
I tend to Gopnik’s skepticism on this question (see Yiu, E., Kosoy, E., & Gopnik, A. (2024) for an extended argument).
Nevertheless, the processing powers of the models make them very effective for some purposes, and the agentic and applications infrastructure being built on top of them promise to make them more so. We do not know yet whether and where developments will plateau, or how adoption varies by tolerance for hallucinations,[\[1\]](#%5Fftn1) or where the impact will be most felt.
However, given the key role of documents (information) in managing complex organizations and interactions, some see the reach of AI as extensive. In this way, the informational, reflexive, networked nature of social life is potentially further intensified.
This extensive informationalization is why Harari, for example, is concerned about the potential reach and impact of AI, as the systemic processability of the connective informational tissue of organizations and systems, he argues, renders them vulnerable to manipulation.
> This extensive informationalization is why Harari, for example, is concerned about the potential reach and impact of AI, as the systemic processability of the connective informational tissue of organizations and systems, he argues, renders them vulnerable to manipulation.
Of course, the ramifications of AI for libraries and for iSchools are accordingly significant. It intensifies some of the trends we have observed, and -- as with other activities at scale -- has both constructive and problematic elements (to use a phrase of Barrett and Orlikowski’s).
If we think of the informational disciplines having a special interest in recorded information, some immediate issues arise.
- **Cultural synthesizers**. Synthesized content and context add a new dimension and challenge.
- **Iterative and chained interaction**. We will interact differently with information objects or bodies of knowledge. Think of how larger publishers or aggregators will provide access to the scholarly literature, for example.
- **Social confidence and trust**. Our sense of authenticity, identity, authorship will all be redefined, creating issues of trust and verification.
- **Policy, law and practice** will all evolve unevenly in concert.
## Information critique
Our simplest actions or interactions now entail complex informational networks and platforms. Think of what is involved in just texting, sending an email or writing in cloud-based Office 365, whatever about group document preparation, remote experiments, or mapping activity.
Day to day behaviors yield up data which is aggregated at scale and used in various ways to monitor, sell or advertise. Large companies have built vast consolidated infrastructure - we are used to thinking of information as immaterial, however, AI has also emphasized how the cloud has boots of concrete. These companies also wield great cultural and economic power - Spotify does our listening for us, Amazon holds sway over merchants on its site.
These social and cultural ramifications mean that undesirable effects are visible and urgent. Addressing these has become an ongoing research, education and advocacy role for the informational disciplines, among others. There is also greater historical sensitivity, an alertness to the ways in which experiences, memories and knowledges may have been suppressed, distorted or invisible (see Benedict Anderson’s classic discussion of museums, maps and other resources in the emergence of nationalism, for example).
Here is a non-exhaustive list of information issues.
- **Inequity**. Given the centrality of the network and digital resources, differential access creates inequities.
- **Surveillance**. There is an increase in direct surveillance and also increased collection of data which drives other aspects of our environment. We are generating data shadows which are operationalized in various ways to influence or inform.
- **Market concentration**. The winner takes all dynamic of network services has resulted in the dominance of several platforms who wield great economic power and influence.
- **Dominant or partial perspectives**. Perspectives which are historically dominant, or politically motivated, or which reflect imbalances of power and influence may be over-represented in any resource. The plurality of experiences, memories and knowledges is under-represented in the record.
- **Dis- and misinformation/’degraded democratic publics’**. Our reliance on flows of information has led to concerted attempts to distort, mislead or defraud. Henry Farrell has argued that there is a more fundamental problem, which is “not that social media *misinforms individuals* about what is true or untrue but that it creates *publics with malformed collective understandings*.” (Farrell)
- **Geopolitical fragmentation**. Rather than a global information flow, as noted above, we are seeing regimes forming around power blocs, with different policy, control and regulatory regimes. Think of the US, EU, Russia and China.
## Information today – systems of information
I kept this section in for completeness although its references to 'later' *etc* are to the origin document \[[pdf](https://drive.google.com/file/d/1ULPoVrz8OwAXQAlKrUDWizqzoORDmGNC/view?ref=lorcandempsey.net)\].
Information, then, is at once fugitive and everywhere, chameleon-like.
I noted above how libraries, Information Science, and the iSchool emerged in different phases of the information evolution. And in some ways, they reflect elements of when they emerged.
The library is different from the other two, in that I talk about the library itself as an organization, rather than as a body of knowledge or techniques. Libraries emerged in the first phase described above. Historically, the collection was the core of library identity, as an organized response to accessible distribution in a print world, and to the preservation of knowledge. The library continues as an organized response by cities, universities and others to learning, research and equity of access to the means of creative production. In this way the scope has moved beyond the collection in various ways, as discussed further below. As an organization, the library benefits from education and research in information management topics, but also across a range of other topics (public policy, for example).
Information science emerged, in the second phase, in the mid-20th Century. In this narrative, its origin story splits from the library as information production grows, requiring new methods of organization and access, and it anticipates elements of today’s information environment. As discussed further below, common to definitions of Information Science is a concern with documents (or recorded information, literatures, and similar).
Although, it doesn’t make sense to lean on it too heavily, one might say that Information Science largely retains an information view of the world, concerned with access to and management of information as a thing (in Buckland’s terms).
In the third phase, information is not only seen as something to be managed or discovered, but as an organizing element of social structure and interaction. It has become an object of study across many disciplines and in social and cultural analysis.
The iSchool has emerged in this third phase and it typically embraces a broad set of informational interests. In some ways it subsumes Information Science interests in a very broad view of information in the modern world.
A large part of typical iSchool portfolio is information systems oriented, at undergraduate and graduate levels, meeting needs for workers with technology, business and social skills. It may be a more applied alternative to computer science. It may also encompass expertise in other informational fields (policy, philosophical/social/cultural, data science, HCI, digital humanities, and so on). The broad disciplinary spread also potentially encompasses social and philosophical perspectives as well as very often a strong information critique emphasis.
Borrowing a suggestive phrase from an article by Black and Schiller (2014), one could say that the iSchool is often interested in both information systems and systems of information, ‘systems that create information through social means.’
Of course, the iSchool is not a discipline – it is an evolving academic structure, although, as I have noted, it may be associated with a broad view of Information Science (understood generically not in the classical sense) or Information Sciences. Informatics, a term which emerged in the 1960s (often associated with another term, as in health or social informatics) may also feature.
The focus and disciplinary spread varies across schools.
## Coda: overview of and links to full contribution
**Collection:** LIS Forward (2025) *Responses to the LIS Forward Position Paper: Ensuring a Vibrant Future for LIS in iSchools, The Friday Harbor Papers, Volume 2*. \[[pdf](https://doi.org/10.6069/F6CQ-H317?ref=lorcandempsey.net)\]
**Contribution**: Dempsey, L. (2025). Library Studies, the Informational Disciplines, and the iSchool: Some Remarks Prompted by LIS Forward. In LIS Forward (2025) *Responses to the LIS Forward Position Paper: Ensuring a Vibrant Future for LIS in iSchools, The Friday Harbor Papers, Volume 2*. \[[pdf](https://doi.org/10.6069/F6CQ-H317?ref=lorcandempsey.net)\]
**Contents:** Here are the sections from my contribution. Where I have excerpted them on this site, I provide a link.
- 1 Introduction \[and summary\] \[[excerpted here](https://www.lorcandempsey.net/introduction-and-summary-library-studies-the-informational-disciplines-and-the-ischool-some-remarks-prompted-by-lis-forward/)\]
- 2 Information: a brief schematic history \[[excerpted here](https://www.lorcandempsey.net/information-a-brief-schematic-history/)\]
- 3 Libraries and library studies \[[excerpted here](https://www.lorcandempsey.net/libraries-and-library-studies/)\]
- 4 Informational disciplines \[[excerpted here](https://www.lorcandempsey.net/the-informational-disciplines/)\]
- 5 On the dissemination of ideas and innovation \[[excerpted here](https://www.lorcandempsey.net/on-the-dissemination-of-ideas-and-innovation/)\]
- 6 Symbolic capital
- 7 Recommendations and candidate recommendations
- Coda 1: Google Ngram
- Coda 2: Personal position
- References
## References
Anderson, B. (2016). *Imagined communities: reflections on the origin and spread of nationalism (revised edition)*. Verso.
Barrett, M., & Orlikowski, W. (2021). Scale matters: doing practice-based studies of contemporary digital phenomena. *MIS Quarterly*, *45*(1). [https://doi.org/10.25300/misq/2021/15434.1.3](https://doi.org/10.25300/misq/2021/15434.1.3?ref=lorcandempsey.net)
Bates, M. J. (2010). Information. In M. J. Bates & M. N. Mack (Eds.), *Encyclopedia of Library and Information Sciences, 3rd Ed.* (Vol. 3). CRC Press. https://pages.gseis.ucla.edu/faculty/bates/articles/information.html
Bawden, D., & Robinson, L. (2022). *Introduction to Information Science* (Second). Routledge. [https://www.routledge.com/Introduction-to-Information-Science/Bawden-Robinson/p/book/9781783304950](https://www.routledge.com/Introduction-to-Information-Science/Bawden-Robinson/p/book/9781783304950?ref=lorcandempsey.net)
Beck, U., & Ritter, M. (1992). *Risk society : towards a new modernity*. Sage Publications.
Bell, D. (1976). *The coming of post-industrial society : a venture in social forecasting*. Basic Books.
Bennett, T., Grossberg, L., & Morris, M. (Eds.). (2005). *New Keywords: A Revised Vocabulary of Culture and Society*. Wiley-Blackwell.
Black, A., & Schiller, D. (2014). Systems of information: The long view. *Library Trends*, *63*(3), 628–662\. [https://hdl.handle.net/2142/89724](https://hdl.handle.net/2142/89724?ref=lorcandempsey.net)
Buckland, M. (2012). What kind of science can information science be? *Journal of the American Society for Information Science and Technology*, *63*(1), 1–7\. [https://doi.org/10.1002/asi.21656](https://doi.org/10.1002/asi.21656?ref=lorcandempsey.net)
Buckland, M. (2017). *Information and society*. The MIT Press.
Buckland, M. (2024). *The Berkeley School of Information: A Memoir*. https://escholarship.org/uc/item/79v080z7
Castells, M. (2009). *The Rise of the Network Society, With a New Preface : the Information Age: Economy, Society, and Culture Volume I* (2nd ed). Hoboken, N.J.: John Wiley & Sons, Ltd.
Dinneen, J. D., & Bauner, C. (2017). Information-not-thing: further problems with and alternatives to the belief that information is physical. *CAIS/ACSI \`17: Proceedings of the Annual Conference of the Canadian Association for Information Science / l’Association Canadienne Des Sciences de l’Information*. [https://philarchive.org/archive/DINIFP](https://philarchive.org/archive/DINIFP?ref=lorcandempsey.net)
Farrell, H. (2025). We’re getting the social media crisis wrong. *Programmable Mutter*. [https://www.programmablemutter.com/p/were-getting-the-social-media-crisis](https://www.programmablemutter.com/p/were-getting-the-social-media-crisis?ref=lorcandempsey.net)
Floridi, L. (2011). *The Philosophy of Information*. Oxford University Press.
Giddens, A. (1990). *The Consequences of Modernity*. Polity Press.
Gopnik, A. (2022, July 22). *What AI still doesn’t know what to do*. Alison Gopnik The Wall Street Journal Columns. [http://alisongopnik.com/Alison\_Gopnik\_WSJcolumns.htm#22Jul22](http://alisongopnik.com/Alison%5FGopnik%5FWSJcolumns.htm?ref=lorcandempsey.net#22Jul22)
Harari, Y. N. (2024). *Nexus : a brief history of information networks from the Stone Age to AI*. Random House, an imprint and division of Penguin Random House LLC.
Hjørland, B. (2018). Library and Information Science (LIS), Part 1\. *Knowledge organization*, *45*(3), 232–254\. [https://doi.org/10.5771/0943-7444-2018-3-232](https://doi.org/10.5771/0943-7444-2018-3-232?ref=lorcandempsey.net)
Lash, S. (2002). *Critique of Information*. SAGE Publications Ltd. [https://doi.org/10.4135/9781446217283](https://doi.org/10.4135/9781446217283?ref=lorcandempsey.net)
MacCabe, C., & Yanacek, H. (2018). *Keywords for today : a 21st century vocabulary : the keywords project*. Oxford University Press.
Ong, W. J. (1982). *Orality and literacy: the technologizing of the word*. Routledge.
Peters, B. (Ed.). (2016). *Digital Keywords*. Princeton University Press. [https://press.princeton.edu/books/paperback/9780691167343/digital-keywords](https://press.princeton.edu/books/paperback/9780691167343/digital-keywords?ref=lorcandempsey.net)
Rayward, W. Boyd. (2014). Information Revolutions, the Information Society, and the Future of the History of Information Science. *Library Trends*, *62*(3), 681–713\. https://doi.org/10.1353/lib.2014.0001
Webster, F. (2014). *Theories of the Information Society* (4th ed.). Taylor and Francis Group. [https://doi.org/10.4324/9781315867854](https://doi.org/10.4324/9781315867854?ref=lorcandempsey.net)
Williams, R. (2014). *Keywords* (New Edition). Oxford University Press.
Yiu, E., Kosoy, E., & Gopnik, A. (2024). Transmission Versus Truth, Imitation Versus Innovation: What Children Can Do That Large Language and Language-and-Vision Models Cannot (Yet). *Perspectives on Psychological Science*, *19*(5), 874–883\. [https://doi.org/10.1177/17456916231201401](https://doi.org/10.1177/17456916231201401?ref=lorcandempsey.net)
---
[\[1\]](#%5Fftnref1) It is pity that ‘hallucination’ has become the term used here, as it gives a misleading sense of how the LLMs work.
**Feature picture**: I took the picture outside the Cambridge University Library. I think they are very successful as ornaments and instruments (they keep cars from parking).
### Document chat: an early AI use case
URL: https://www.lorcandempsey.net/document-chat-an-early-ai-use-case/
Last updated: 2025-04-24T17:14:39.000Z
## Introduction: boundaries between reading, interaction and workflow are blurring
It is useful to think about AI as a new cultural technology, a phrase development psychologist Alison Gopnik has been using.
> Instead, these AI systems are what we might call cultural technologies, like writing, print, libraries, internet search engines or even language itself. They are new techniques for passing on information from one group of people to another. Asking whether GPT-3 or LaMDA is intelligent or knows about the world is like asking whether the University of California’s library is intelligent or whether a Google search “knows” the answer to your questions. But cultural technologies can be extremely powerful—for good or ill. // [Alison Gopnik](http://alisongopnik.com/Alison%5FGopnik%5FWSJcolumns.htm?ref=lorcandempsey.net#22Jul22)
Thinking in this way broadens the context of the library discussion about AI. A new cultural technology will ramify through the ways in which we create, curate, interact with, and communicate knowledge artifacts. This has implications for social trust and confidence, for the boundaries between content, interaction and workflow, and for what we value and transmit in the scholarly and cultural record.
****Note:** This is a fast-moving area and service characteristics will evolve. This post describes services as of 1 December 2024\.
This general use also makes it very important for libraries to advocate for transparency and good practices in the training collections for the Large Language Models (LLMs) used in these services. They need to be informed consumers, and reflect on how to use their collective influence. It is important to understand how such models are constructed, and the potential for bias and partiality given the dominant and sometimes harmful perspectives represented in the historical record they are trained on. It is also important to gain [practical experience](https://www.lorcandempsey.net/the-rhinoceros-in-the-room-redux/) of how such services behave, how they are not like search engines, for example.
We can already see incremental changes in how we interact with informational resources. A set of services is becoming more common in daily tools.
For example, the *search/summarise/sources* pattern is becoming familiar from search services which deploy Retrieval-Augmented Generation models. See Microsoft CoPilot, Perplexity, or the new search feature in ChatGPT, for example, as well as the growing range of more specialist scholarly or research resources (see Scholarcy or Undermind, for example). Library and scholarly service providers are also carefully moving in this direction (see for example Clarivate or Digital Science).
There is an overlapping set of services that allows you to manage a collection of documents or other resources, and to interact with them in various ways. Such 'research assistant' or collection management services offer a suite of services. NotebookLM from Google, for example, has been much in the news recently, in particular for its ability to re-present submitted materials in the form of a very life-like podcast. Beyond this media-friendly feature, it supports other ways of interacting with a group of resources, summarization for example, or question-asking.
One common feature of these services is the ability to 'ask a PDF a question.' There are also multiple general purpose '[document chat tools](https://usefulai.com/tools/ai-document-chat?ref=lorcandempsey.net)' where this may be the primary focus.
Increasingly, I find that it is quite useful to be able to ask a document questions in this way - especially where it sits within existing workflows, in the browser, in my reference manager, when a PDF opens in Acrobat, and so on. It is useful to summarize, to look for stuff, to remind myself of a passage, to work with long documents. This is not necessarily a substitute for reading, when I do indeed need or want to read something. However, it is a way of navigating, prospecting, or locating, and can accelerate discovery.
Given I found myself doing this more, I thought I would have a closer look and quickly ask several services the same question to see whether there was much variation in response or whether one or the other was more helpful from my point of view.
The services I look at are Microsoft Copilot, Readcube Papers from Digital Science, Adobe Acrobat, Google's NotebookLM, ChatGPT, and Scholarcy.
So my focus here is very specific. This is a quick exploration driven by curiosity. It is not a carefully controlled experiment or research investigation. This is especially the case given the variety of ways in which the services differ, the probabilistic way in which the LLMs work, and the different environments in which the services are embedded. While my central theme is looking at question-asking across several services, I will certainly discuss these broader questions, but in an anecdotal way.
In particular, it should be noted that the same question will potentially produce different responses when re-run against an LLM. I was very aware of this when looking at the outputs from the various services, and for this reason I reran the question against the services after an interval of a day. For the purposes of comparison I include this second round of outputs below, although I do not analyze them closely.
This post is structured as follows.
- [Asking documents questions: reflections on a simple example](https://www.lorcandempsey.net/p/35c021ce-7a64-4dd0-944e-9beed82c44b2/#asking-documents-questions-reflections-on-a-simple-example) I introduce a question and note some context.
- [Looking at the outputs](https://www.lorcandempsey.net/p/35c021ce-7a64-4dd0-944e-9beed82c44b2/#some-observations-on-the-outputs) I look at the responses to my question, and explore some characteristics of particular services.
- [Reflecting on the experience](https://www.lorcandempsey.net/p/35c021ce-7a64-4dd0-944e-9beed82c44b2/#observations-on-the-experience) I look at some wider context, in particular UI/workflow and how the nature of the services mean that responses can vary.
- [Listing the service outputs](https://www.lorcandempsey.net/p/35c021ce-7a64-4dd0-944e-9beed82c44b2/#listing-the-service-outputs) I provide the full text of the responses, to ground the discussion. I also provide some the second round of outputs, generated when the question was later re-run.
****A summary note.** I looked at a variety of 'document chat' services to see how their results compared. ****\*** Overall outputs were good, with no significant hallucination, and no outlier or odd responses. ****\*** There was variation between responses, and some variation when the same prompt was re-run on the same service. However, there was also quite a bit of overlap and in general responses were reasonable. ****\*** The UI experience was similar across the services, however they were differently situated in the context of the suite of services of which they were a part and their relationship to user workflow and context. ****\*** For pragmatic reasons, I chose a work-related document I had co-authored as I was familiar with the content and could judge the outputs. A different document might have surfaced more issues around bias or partiality. ****\*** It would be interesting to explore with a longer document, more complex prompting, and so on. ****\*** I liked the user experience of NotebookLM and the nuanced responses of Scholarcy, but overall they all performed well enough to re-use.
## Asking documents questions: reflections on a simple example
### Selecting a document
The choice of document matters. I had begun by looking at a political [review](https://doi.org/10.1017/s0080440123000130?ref=lorcandempsey.net) in an area of interest, but was not confident in my judgement of outputs.
However, for pragmatic reasons, I decided to look at a professional document that I co-authored. I was confident in my ability to assess outputs and much of what I look at in this way is work-related.
> Dempsey, L., Malpas, C., & Sandler, M. (2019).[ *Operationalizing the BIG Collective Collection*](https://doi.org/10.25333/jbz3-jy57?ref=lorcandempsey.net)*: A Case Study of Consolidation vs Autonomy*. OCLC Research.
This report includes an extended treatment of the issues involved in creating a consolidated approach to the aggregate [Big Ten](https://btaa.org/library/big-collection/the-big-collection-introduction?ref=lorcandempsey.net) print collection. This is an aspiration of the libraries of the Big Ten Academic Alliance, a consortium of research universities which collectively represent a major portion of the North American aggregate library collections. The report includes detailed discussion of general collaborative frameworks, the current collaborative library landscape, and some of the technical factors at play. So, while it is specific to the BTAA, it is also a general and extensive discussion of library collaboration issues.
I asked a simple question:
> According to this document, what are the top four reasons library collaboration is difficult.
Here are some preparatory notes, before looking in a little more detail at the outputs.
- **Prompt**. The prompt is relatively open-ended. Additional prompting might have improved outputs in various ways, or I could have provided some instructions about length, tone, or some other attribute. However, I did not want to get into an exploration of the characteristics of prompting. It is also true that I could have explored whether particular approaches worked better with the specific characteristics of individual services, but again that was not my purpose here.
- **Large language model**. I think it is important for librarians as advisers to know what LLM is in use in a particular service and to know what policies govern the re-use of submitted materials. I was interested that this information was not more generally front and center, but required some excavation on the website or enquiry to the support line.
- **Sources** Some of the services provide links back into the document, to highlight relevant passages.
- **Bias**. Another document may have exposed more ways in which the service was influenced by omissions or by dominant, partial or harmful perspectives in the training collections. Again, that opens up interesting avenues of exploration, but more than I am doing here.
- **Re-running the question.** Understanding that the same question may produce different responses from an LLM, I re-ran my prompt at a later date. There turned out to be quite a bit of variation. I include the second round outputs for comparison below, but mostly limit my analysis to the first-round outputs.
- **Fee vs free**. I used the for-fee version of services, through either a work or a personal subscription. I did not explore what variation existed, if at all, between these and the free versions.
****Note:** I used the AI Assistant in the Adobe Acrobat Chrome extension. Initially I thought this was through a work subscription but it seems I had access to a guest service. The output noted here is from the guest account. After I discovered this, I took out a subscription to AI Assistant, so the second round output below is generated by the subscription service. I do not know if there is any difference between the two.
## Looking at the outputs
#### The first round answers: four top-level reasons collaboration is difficult
A quick inspection of the first round of outputs shows considerable alignment in terms of the 'four reasons' presented, and in how they are described. Here is a list of reasons with a note of how many services mentioned each.
- **Autonomy vs consolidation** \[5\]
- **Coordination costs** \[4.5\]
- **Interoperability** \[3.5\]
- **Diverse priorities** \[3\]
- **Local vs systemwide optimization** \[2\]
- **Efficiency vs control** \[2\]
- **Ideal vs pragmatic** \[1\]
- **Policy variations** \[1\]
- **Diffusion of effort** \[1\]
- **Decentralised US environment** \[1\]
The 'half' scores are because 'coordination costs and interoperability' was listed as a reason by NotebookLM. Interoperability certainly does create major coordination issues (I have elsewhere called these '[stitching costs](https://www.lorcandempsey.net/stitching-costs/)'), but, given the spread here, I thought it helpful to count separately in this way.
This is a good list which certainly reflects the arguments of the report. Given that 'autonomy vs consolidation' is embedded in the title, it is not surprising to see it top the list. The other topics are discussed throughout: none is an outlier or odd.
I just count the top-level enumerated reasons given here, per the prompt. For example, I do not count an additional systemwide efficiency which is mentioned under one of the others or think about the collective action problem, mentioned a couple of times, in this top-level set. Other reasons certainly come through in the returned narrative.
Are there any major gaps or surprising omissions? One comes to mind, and maybe it is not highlighted in the responses because it is not something that has been commonly discussed in the scholarly record or on the web. The members of BTAA consort in a variety of other organizations to get their work done, or to provide learning and development opportunities, or to lobby and advocate. An important category here is the state or regional network which may do resource sharing, negotiation, and other overlapping services. We call these 'adjacent networks' in the report. They include, for example, OhioLINK for The Ohio State University, or PALCI for Penn State. The member libraries have to manage participation across BTAA and important adjacent networks. They also raise technical interoperability issues, if, for example, resource sharing requests were to be shared. While the challenges this poses surface in general ways (coordination, priorities, ...), I would have expected it to be called out more specifically.
### Looking at the first round outputs more generally
Given the somewhat open-ended prompt, I thought that all the services provided reasonable responses and was interested to see the consistency.
In general, as one would expect, there is not a lot of elaboration or nuance. While the autonomy of the libraries is mentioned, for example, only one of the responses notes that the BTAA libraries are generally large and well-resourced which is an important part of the autonomy/consolidation dynamic. I was interested to see that a couple of the responses recognized the broad way in which interoperability was used, to include organizational and social issues, while it was also seen as a more circumscribed technical issue.
There were no standout examples of hallucination. In general the responses were well-grounded in the document and were accurate and plausible in the context of the library collaboration environment described there. I wondered whether this note from Readcube Papers documentation would hold true of the approach used by the others also.
> We have designed our AI Assistant to focus on answering specific questions contained within the opened research paper, rather than relying on broad knowledge trained within large language models. This can help mitigate the probability of hallucinations (nonsensical or inaccurate AI outputs), but there is always the possibility the AI may misinterpret a question or fail to extract the correct context. Accuracy may also vary depending on the topic. // [Papers](https://support.papersapp.com/support/solutions/articles/30000050358-papers-ai-chat-with-pdf?ref=lorcandempsey.net)
How do the individual responses compare to the aggregated list of reasons? I assigned points to the reasons based on their position in the ranking, and then scored each service based on their coverage. By this simple reckoning Copilot and Acrobat, followed by Scholarcy, had most points. However, for all the reasons mentioned above, I would not lean very heavily on this. There was not a very wide spread of scores, they all did reasonably well.
Did I have a favorite in this set of responses? Entirely subjectively, I would probably chose Scholarcy. It is succinct, but also more nuanced. The four reasons are well chosen against the general ranking. But also the responses are more in the style of the report (I wondered if they were direct quotes). Somebody else who was familiar with the report might prefer the response of one of the other services.
## Reflecting on the experience
### Model used and training
All the services except NotebookLM from Google are using some version of GPT from OpenAI. A couple note that they access these through the Microsoft Azure OpenAI service. Scholarcy is using both Google and OpenAI models. In general it takes some excavation to find this out, and not all services publicly state the underlying model. Perhaps this suggests that the underlying LLM is seen as a commodity and so long as it works well not an important differentiator?
It also takes some work to find out if the services use the submitted documents for training purposes. Again, I was curious about this. I would have thought that some reasonable proportion of users would want to know, but perhaps not. Interestingly, Google's NotebookLM does emphasise its policy of not using submitted documents in training on its home page.
As I note below, I do think that it is important for libraries to be able to reference underlying models and service policies as they advise their users.
### UI/UX: workflow, interaction, content
The actual chat interface (ChUI? - Chewy?) is pretty similar across the services: a question box and a text response. The service may provide a summary and contents by default and sometimes provides candidate further questions.
However, the services are embedded in different contexts which makes the experience rather different. For example, NotebookLM provides the ability to save responses, to work with groups of documents, and so on. Scholarcy also places this functionality in the context of a larger set of services which aim to help you 'summarize, analyze and organize your research.' In this sense, Scholarcy and NotebookLM are 'destinations' which provide a rich set of services. Microsoft Copilot, on the other hand, is available in the browser to provide responses '[in the flow](https://www.lorcandempsey.net/in-the-flow/)' of your general activity. Readcube Papers is perhaps in between, providing a discrete service in the context of reference/document management.
In this way, workflow and context is an important factor in the choice of service and its experience.
### Variation in results: not a database or search engine
LLMs generate responses based on probability distributions, statistical patterns learned from their training collections. In this way, they are unlike databases or search engines whose retrieval model is more deterministic, based on explicitly indexed data.
This means that the same prompt may generate different outputs at different times. Some other factors may also be involved.
- A service may have a 'Temperature' setting which controls the randomness of outputs. A lower temperature makes the model more deterministic leading to more consistent answers. A higher temperature makes the model more 'creative' leading to greater variability. (Some readers may remember the precise/balanced/creative toggle on Microsoft Copilot, where creative was the highest temperature.)
- The service may 'remember' context from previous conversations which influences and alters subsequent responses. This might only be in a single session or may be longer term. For example, see more about 'memory' and ChatGPT [here](https://help.openai.com/en/articles/8590148-memory-faq?ref=lorcandempsey.net), including the ability to switch off the memory function.
- Although it was not a factor in this example, very small changes in the prompt can change outputs.
This variability is a feature of how the services work, and is reasonable in situations like this where there is not a single answer to the question. This is one reason why it is important to get a feel for how different LLMs respond through hands on experience.
## Listing the first round service outputs
Here are the outputs, with a little additional context about each service.
---
### Microsoft Copilot
I now regularly use Microsoft Copilot for searching. I switch between Edge and Chrome, and whenever I am in Edge it tends to be my default internet search. Although, for my purposes here, of course, I just asked it to look at a single document which I loaded.
It appears to use ChatGPT 4, not the most recent version. According to these somewhat complicated [notes](https://learn.microsoft.com/en-us/copilot/microsoft-365/microsoft-365-copilot-privacy?ref=lorcandempsey.net) on privacy, it does not seem that submitted documents are used for training models.
This is a good list. It leads with the issue highlighted in the report title. It uses the phrase 'collective action' but in a general sense, not picking up on the more specialized way it is used in the report in the context of the '[collective action problem](https://en.wikipedia.org/wiki/Collective%5Faction%5Fproblem?ref=lorcandempsey.net).'
---
According to the document “Operationalizing the BIG Collective Collection: A Case Study of Consolidation vs Autonomy,” the top four reasons library collaboration is difficult are:
1. **Autonomy vs. Consolidation**:
- Libraries often prefer to maintain local control over their collections and operations, which can conflict with the need for centralized decision-making and resource allocation required for effective collaboration. This tension between autonomy and the benefits of consolidation creates challenges in aligning strategies and policies across institutions.
2. **Coordination Costs**:
- Managing interactions across multiple libraries and networks involves significant coordination costs. These include the time and effort required to harmonize policies, integrate systems, and manage workflows. The complexity of coordinating different institutional priorities and practices can hinder the efficiency and effectiveness of collaborative efforts.
3. **Diverse Institutional Priorities**:
- BTAA member libraries have varying institutional missions, resource levels, and strategic priorities. This diversity makes it challenging to develop and implement a unified approach to collection management and resource sharing. Differences in institutional goals and resource availability can lead to uneven participation and commitment to collaborative initiatives.
4. **Interoperability and Integration**:
- The technical challenge of integrating different library systems and applications is a significant barrier to collaboration. Libraries use a variety of systems for cataloging, discovery, and resource sharing, which may not easily interoperate. Developing middleware or broker services to facilitate seamless integration requires substantial investment and ongoing maintenance.
These factors collectively contribute to the difficulty of achieving effective library collaboration, as they require balancing local needs with the benefits of collective action, managing complex coordination efforts, aligning diverse institutional priorities, and overcoming technical integration challenges.
---
### Readcube Papers
Coming into my current role, I needed the help of a reference manager. I found the shallow learning curve and utility of Papers convincing and now use it regularly. Overall, I am impressed with it. They recently rolled out an AI update which added some features including the ability to ask a PDF questions.
This is useful because you often have the PDF right there in the workflow - you do not have to load it separately. It feels like an early iteration, currently without a lot of bells or whistles.
I could not immediately see which LLM was being used (see the [documentation](https://support.papersapp.com/support/solutions/folders/30000058261?ref=lorcandempsey.net)). I queried support and received this prompt response (11/22/24): "Papers is currently using ChatGPT-4o, powered by OpenAI. This may be subject to change in the future of the app."
---
The document highlights several reasons why library collaboration is difficult:
1. **Local Priorities vs. Systemwide Optimization**: There is a collective action problem where local priorities and pressures often take precedence over systemwide optimization, making it challenging to coordinate efforts across libraries.
2. **Tradeoffs Between Consolidation and Autonomy**: Consortial working involves tradeoffs between consolidation and autonomy. Libraries, like those in the BTAA, often lean towards autonomy, which can complicate collaborative efforts.
3. **Diverse Membership and Needs**: State consortia have diverse membership and needs, and some may lack the requisite scale to tackle the big challenges faced by research libraries.
4. **Diffusion of Effort**: Libraries are often drawn into various collaborations to accomplish their work, leading to a diffusion of effort and making it harder to focus on a unified strategy.
---
### Adobe Acrobat
Now, when I launch a PDF document in Chrome it opens in the Acrobat Chrome extension. Acrobat has an AI Assistant feature. Again, this means that the document chat functionality is right there in the normal workflow.
While 'diverse membership and needs' is indeed discussed across the BTAA, and while the statement below is certainly true about state consortia, the statement does not quite get at the topic discussed in the report, which is noted as a gap above.
Adobe provides more [background information](https://blog.adobe.com/en/publish/2024/05/08/adobe-acrobat-ai-assistant-enterprise-our-commitment-data-governance-security?ref=lorcandempsey.net) about its practice and policy than others. It notes that it is 'agnostic' about LLM, using the best for the task at hand. The AI Assistant currently uses the Microsoft Azure OpenAI Service, although it does not say which GPT version is used. It uses content filtering services to guard against harmful outputs and does not use customer data in training.
---
According to the document, the top four reasons library collaboration is difficult are:
1. **Coordination Costs**: Managing coordination across multiple systems, libraries, collections, policies, and strategies can be complex and costly.
2. **Autonomy vs. Consolidation**: Libraries often prefer to maintain local control, which can conflict with the need for central coordination to achieve systemwide efficiency.
3. **Diverse Membership and Needs**: State consortia have diverse membership and needs, which can make it challenging to align around a common vision or strategy.
4. **Interoperability Challenges**: Ensuring interoperability between different systems and services is not just a technical issue but also involves aligning policies and practices, which can be difficult to achieve.
These challenges highlight the trade-offs and complexities involved in achieving effective library collaboration.
---
### NotebookLM
This service has been much in the news recently, in particular for its ability to re-present submitted materials in the form of a very life-like podcast. Beyond this media-friendly feature, it is actually quite useful. I especially like the ability to load a collection of documents and to query them together. However, again, here I am just looking at one document.
I can see myself using this service more. In particular, it provides a way of using the LLM search/summarise/source approach across a collection of documents at the same time.
At the time of writing, NotebookLM is using Gemini 1.5 pro, the most functional publicly available model. It also [notes](https://support.google.com/notebooklm/answer/14278184?hl=en&ref=lorcandempsey.net) that it is not training on user-submitted documents; in fact this is also quite prominently declared on the home page.
---
Here are four reasons library collaboration is difficult, according to the source document:
- **Tradeoffs between Efficiency and Control**: Libraries may perceive local control as important, but system efficiency can be improved if individual libraries cede some local control to central coordination. For example, the source notes that an "Amazon-like" user experience requires removing "delay, uncertainty, and discretion from the discovery to delivery supply chain." \[1\]
- **Ideal vs. Pragmatic**: Libraries often have to pursue collaborative projects incrementally, negotiating agreements and retrofitting existing solutions rather than building new systems. The source describes how some library directors did not see a need to invest more in resource sharing, as the existing resource sharing arrangement was already "good enough." \[2\]
- **Coordination Costs and Interoperability**: Coordinating systems, libraries, collections, policies, and strategies across institutions comes with significant costs, and these costs can be difficult to manage. For example, a new library joining a network may need to adjust its policies or interwork its management system with other coordinating applications. \[3, 4\] The source explains that libraries must manage the coordination costs associated with participating in multiple networks, including sitting on boards and committees and adapting workflows. \[5\]
- **Decentralized Library Model in the US**: The US has a decentralized library model with little national coordination. This means that consortia often have to coordinate activities at a smaller, less efficient scale. \[6\] The source notes that this decentralization can sometimes hinder collaborative projects, as individual libraries may not see the need to work together when they can secure resources and services independently. \[7\]
---
### ChatGPT
Of course the model which drives ChatGPT underlies various other services. Here I am using their recently released ChatGPT 4o, their most capable public model to date.
ChatGPT may use files uploaded by individuals for training purposes, although there is an option to opt out. See the [documentation](https://help.openai.com/en/articles/8555545-file-uploads-faq?ref=lorcandempsey.net) here. It would be helpful to date such documents.
---
The document outlines four main challenges to effective library collaboration:
1. **Balancing Consolidation and Autonomy**: Libraries in consortia like BTAA value autonomy due to historical resource independence and local institutional priorities. Coordination often requires a tradeoff between centralized control (to maximize efficiency and impact) and maintaining local autonomy.
2. **Coordination Costs**: Effective collaboration requires significant investment in coordinating systems, policies, and staff across institutions. This includes managing overlapping memberships in other networks and consortia, which can diffuse focus and resources.
3. **Institutional vs. Systemwide Optimization**: Libraries tend to prioritize local optimization over broader systemwide efficiency. This results in collections and services being optimized at the institutional level, rather than achieving maximum collective benefit across the consortium.
4. **Inconsistent Policies and Processes**: Variability in policies, systems, and decision-making processes among member libraries complicates the creation of a seamless, unified experience. This can slow collaboration and reduce its effectiveness.
These factors highlight the complexity and effort required to foster strong, effective collaboration among libraries.
---
### Scholarcy
This is one of the growing number of specialist services emerging in the research/scholarly space. It has an interesting model in which it summarizes articles in a consistent way using a flashcard-style format. You can ask your own questions and it provides a selection of other services.
I could not immediately see details about the LLM in use, so I asked support. The prompt response (11/22/24): 'We use a mixture of in-house NLP algorithms and some third party LLMs including Google Gemini, and GPT-4o.' They also confirmed what is on their website, that user-submitted documents are not used for model training and are deleted once transformed into flashcards.
---
**Top Four Reasons Library Collaboration Is Difficult**
This document does not list the top four reasons library collaboration is difficult. However, it does discuss challenges related to library collaboration in the context of the [Big Ten Academic Alliance](https://en.wikipedia.org/wiki/Big%5FTen%5FAcademic%5FAlliance?ref=lorcandempsey.net) ([BTAA](https://en.wikipedia.org/wiki/Big%5FTen%5FAcademic%5FAlliance?ref=lorcandempsey.net)). These challenges include:
1\. The [BTAA](https://en.wikipedia.org/wiki/Big%5FTen%5FAcademic%5FAlliance?ref=lorcandempsey.net) libraries’ inclination toward autonomy, stemming from historical well-resourcing, established independent operations, and participation in other collaborative ventures (e.g., OhioLINK, CARLI, PALCI). This can make the [BTAA](https://en.wikipedia.org/wiki/Big%5FTen%5FAcademic%5FAlliance?ref=lorcandempsey.net) a less natural venue for collaboration, diminishing incentives for participation.
2\. The high coordination costs involved in managing systems, libraries, collections, policies, and strategies across the [BTAA](https://en.wikipedia.org/wiki/Big%5FTen%5FAcademic%5FAlliance?ref=lorcandempsey.net). This complexity increases significantly when considering interactions between multiple networks and systems.
3\. The trade-offs between efficiency and control. While central coordination improves overall system efficiency, local control is often prioritized for political or service reasons. This conflict is particularly relevant for the [BTAA](https://en.wikipedia.org/wiki/Big%5FTen%5FAcademic%5FAlliance?ref=lorcandempsey.net) which favors institutional optimization over system-wide optimization.
4\. The challenges of interoperability, which is presented not as a purely technical issue, but as a complex area affected by a variety of factors, including the degree of autonomy maintained by individual institutions, the difficulty of providing a unified experience over multiple, relatively autonomous services, and the importance of consistent policies.
---
## A concluding note
Finally, I note again that this is a simple snapshot of a small number of services. I could have looked at many more. And of course, this is only one feature of the broader range of capacities available.
Services and models are evolving quickly, as is the level of integration with existing practices and workflows.
I was interested how it was not possible to immediately see what models or approaches underlay some of the services. I do think that this is an area where libraries can be active as consumers, advocating with services that they publish details of the models used, and also their policy in relation what use is made of submitted documents.
That said, the volume and variety of these services is a signal of the challenge in this environment. Keeping track of services, let alone advising about their use, or, in some cases, licensing them, is difficult.
However, if AI does indeed become a broad-based cultural technology, as Gopnik suggests, our informational behavior will continue to evolve.
## Coda: a second round of questions
I repeated the exercise a day or two later. I anticipated some changes based on experience. However, I was interested in just how much change there was. I offer this just for comparison.
I have not explored what service characteristics are at play here. For example, as noted, Copilot used to explicitly offer 'temperature' settings which were progressively less deterministic: precise, balanced, creative. They no longer offer these, but apparently can adjust based on interactions.
In the context of the discussion of the first round outputs, I was interested to see the 'collective action problem' appear as a top-level issue in the Papers output, as I had noted its absence above. I was also interested to see that Acrobat linked coordination costs and interoperability this time, as NotebookLM had in the first round. The Scholarcy reponse does this time note strong resourcing levels and other collaborative venues as dampeners within a BTAA setting, which again I note as an important issue above.
In summary, these again are good lists, with no significant hallucinations. While they vary, and while they vary from the first round, they represent valid responses.
#### Microsoft Copilot
The document "Operationalizing the BIG Collective Collection" outlines several challenges to library collaboration. Here are the top four reasons:
1. ****Autonomy vs. Consolidation**:
2. - Libraries within consortia like the BTAA (Big Ten Academic Alliance) often value their autonomy and have historically operated independently. This independence can make it difficult to consolidate resources and strategies, which is necessary for effective collaboration.
3. ****Coordination Costs**:
4. - Managing coordination between multiple libraries involves significant costs, including time and resources. These costs arise from the need to align policies, systems, and workflows across different institutions, which can be complex and resource-intensive.
5. ****Diverse Institutional Priorities**:
6. - The member libraries of a consortium often have varying priorities and missions. For example, some may focus more on research while others prioritize undergraduate education. These differing priorities can lead to challenges in aligning goals and strategies for collaboration.
7. ****Policy and Strategy Alignment**:
8. - Effective collaboration requires a high degree of alignment in policies and strategies, which can be difficult to achieve. Libraries may have different policies regarding resource sharing, collection development, and other key areas, making it challenging to create a unified approach.
#### Readcube Papers
The document does not explicitly list the top four reasons why library collaboration is difficult. However, it does mention several challenges and considerations that can make collaboration complex:
1. ****Tradeoffs between Consolidation and Autonomy**: Libraries often face tradeoffs between working collectively and maintaining their autonomy, which can complicate collaboration efforts.
2. ****Diverse Membership and Needs**: State consortia have diverse membership and needs, which can make it challenging to address the big challenges faced by research libraries.
3. ****Decentralized Political Environment**: In a decentralized political environment, national provision is rare, making it difficult for libraries to collaborate on a large scale.
4. ****Collective Action Problem**: Local priorities and pressures often take precedence over systemwide optimization, presenting a classic collective action problem.
These factors highlight the complexity and difficulty of achieving effective library collaboration.
#### Adobe Acrobat
According to the document, the top four reasons library collaboration is difficult are:
1. ****Tradeoffs between consolidation and autonomy**: Libraries often have to balance between consolidating resources for efficiency and maintaining autonomy to meet local needs. This can create tension and make collaboration challenging.
2. ****Coordination costs and interoperability**: Coordinating systems, policies, and strategies across multiple libraries and networks can be complex and costly. Interoperability is not just a technical issue but also involves aligning different policy regimes and operational practices.
3. ****Variability in institutional priorities**: Different libraries have varying priorities based on their institutional missions, which can lead to differing levels of commitment and participation in collaborative efforts.
4. ****Need for explicit commitments and shared processes**: Effective collaboration requires clear commitments, shared strategies, and common processes for decision-making and resource allocation. Without these, it is difficult to achieve cohesive and efficient collaboration.
#### NotebookLM
Here are four reasons, according to the sources, why library collaboration is difficult:
- ****Coordination costs are often underestimated.** For libraries to collaborate effectively, they must agree on common policies, integrate their systems, and share responsibility for collections. This requires a significant investment of time and resources, especially in the context of an already complex library ecosystem with pre-existing relationships. \[1-6\]
- ****Libraries may not have strong incentives to collaborate.** Many research libraries, including BTAA members, have significant resources and capacity to operate independently. Therefore, the benefits of collaboration may not always outweigh the perceived costs of surrendering local control. Libraries also have other avenues for collaboration, such as state or regional networks, and may prioritize those relationships over broader collaborations. \[7-11\]
- ****Differences in institutional priorities and policies can make it difficult to agree on a shared approach.** Each library has its own unique mission, user base, and collection strengths. This can lead to a diversity of needs and priorities, making it challenging to achieve consensus on a collaborative strategy for managing, building, and sharing collections. For example, different institutions may have different levels of commitment to preserving print collections or investing in shared infrastructure. \[8, 12, 13\]
- ****Collaboration often involves trade-offs between efficiency and local control.** Centralized coordination can improve the overall efficiency of a library network, but it may also require individual libraries to relinquish some control over their collections, policies, and workflows. This can be a difficult decision for libraries that are accustomed to operating autonomously, and it may require careful negotiation and compromise among stakeholders. \[11\]
#### ChatGPT
The document identifies four primary challenges that make library collaboration difficult:
1. ****Autonomy vs. Consolidation**: Libraries are used to operating autonomously and may prioritize local decision-making and strategies over consortial goals. This makes it challenging to align efforts across multiple institutions(operationalizing-the-BI…).
2. ****Coordination Costs**: Managing collaborations requires significant investment in time, staff, and resources for coordination, which can strain individual institutions and reduce efficiency(operationalizing-the-BI…).
3. ****Diverse Affiliations and Priorities**: Libraries often belong to multiple consortia and networks, each with its own goals and requirements, leading to competing commitments and diluted focus(operationalizing-the-BI…).
4. ****Inconsistent Policies and Systems**: Variations in policies, workflows, and technology across libraries hinder interoperability and make unified efforts more complex and less effective(operationalizing-the-BI…).
#### Scholarcy
According to the document, the top four reasons library collaboration is difficult are:
1\. ****Autonomy vs. Consolidation**: The [BTAA](https://en.wikipedia.org/wiki/Big%5FTen%5FAcademic%5FAlliance?ref=lorcandempsey.net "Big Ten Academic Alliance") libraries lean toward autonomy due to their historical well-resourcing and other collaboration venues. This autonomy can weaken incentives for collaboration within the [BTAA](https://en.wikipedia.org/wiki/Big%5FTen%5FAcademic%5FAlliance?ref=lorcandempsey.net "Big Ten Academic Alliance"), as libraries are used to acting independently and may not see [BTAA](https://en.wikipedia.org/wiki/Big%5FTen%5FAcademic%5FAlliance?ref=lorcandempsey.net "Big Ten Academic Alliance") as the first venue for collaboration.
2\. ****Coordination Costs**: Managing coordination costs of partnering with multiple groups is challenging. Libraries are embedded in multiple networks, which can compete for attention, staff time, and resources, making it difficult to align efforts.
3\. ****Diverse Membership and Needs**: State consortia have diverse membership and needs, which may not have the requisite scale to tackle the big challenges research libraries face. This diversity can make it harder to align around a vision of shared library services or infrastructure.
4\. ****Lack of Systemwide Optimization**: [BTAA](https://en.wikipedia.org/wiki/Big%5FTen%5FAcademic%5FAlliance?ref=lorcandempsey.net "Big Ten Academic Alliance") collaboration around collections is generally secondary to institutional planning, with local control often taking precedence over systemwide optimization. This results in collections being optimized locally rather than at the [BTAA](https://en.wikipedia.org/wiki/Big%5FTen%5FAcademic%5FAlliance?ref=lorcandempsey.net "Big Ten Academic Alliance") level, which can hinder more effective collaboration.
**Picture:** The feature picture is from an illustration in the report, created by Constance Malpas.
**Acknowledgements:** Thanks to my colleague Ben Lee for helpful comments on an earlier draft.
**Update:** Introduction slightly updated to note library influence and specific focus 12/4/24\.
**Note:** See this link for posts on AI, including some deeper dives into models, library contexts, and other topics.
[AI - LorcanDempsey.netPosts about evolving AI story and its implications for libraries.LorcanDempsey.netLorcan Dempsey](https://www.lorcandempsey.net/tag/ai/)
For those interested in the report itself, there is a summary outline in this post:
[Operationalizing a collective collectionWhile collective collections have been much discussed, less attention has been paid to how to operationalize them in consortial settings. This post introduces work done with the BTAA to explore this challenge.LorcanDempsey.netLorcan Dempsey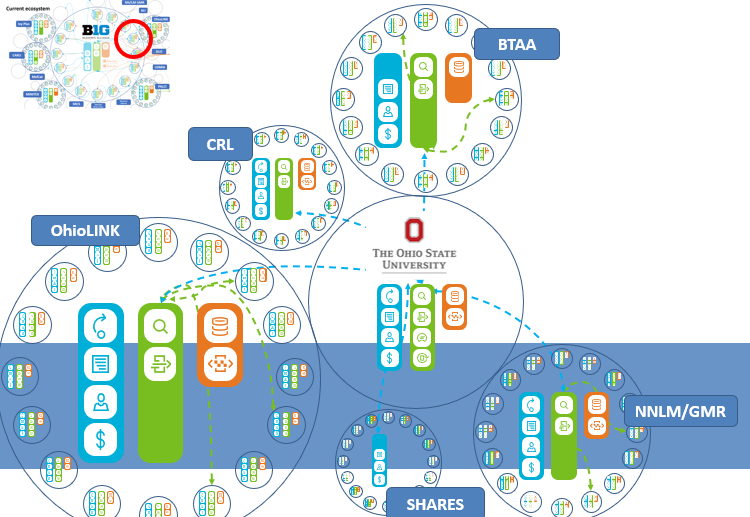](https://www.lorcandempsey.net/operationalizing-a-collective-collection/)
### Teaching: one year in
URL: https://www.lorcandempsey.net/teaching-one-year-in/
Last updated: 2025-09-07T02:58:46.000Z
I am one year into my two-year term as a Distinguished Practitioner in Residence at the Information School at the University of Washington. I have been fascinated to see academic life from the inside, as it were, even though I am a visitor rather than fully domiciled. A bonus has been how much we have enjoyed Seattle, the city, and its amazing watery, mountainy and islandy hinterland.
I have been teaching two courses, one that I created myself from scratch, and one almost oven-ready that I adapted. The new course was on library collaboration and partnerships, a topic that has always seemed to me to be underexamined. I am also about to begin a small research project looking at some of the characteristics of collaboration. I am lucky that the Orbis Cascade Alliance is on my doorstep here in that regard. The other was on management, a course that is mandatory for all MLIS students, and which is viewed with some ambivalence by some.
At this mid-way point, I thought I would reflect a little on my newfound teaching experience, understanding that what I say is not necessarily unique or surprising.
## Teaching and baking
Teaching for the first time presents a steep learning curve. Starting out by developing a new course was in hindsight somewhat optimistic. Once the baking analogy occurred to me, I could not forget it:
> Teaching for the first time while developing a new course is like being in the kitchen on your own, with no recipe, baking a loaf of bread for the very first time. Except that you have an audience who observe your every move, and you cannot throw it away if it doesn't work out.
But I was not quite on my own. Several people helped, and I am especially grateful to my colleague and Associate Teaching Professor, [Chance Hunt](https://ischool.uw.edu/people/faculty/profile/cahunt?ref=lorcandempsey.net), who generously and empathetically stepped in to calm my churning and to help clear a path, and to [Sue Morgan](https://ischool.uw.edu/people/staff/profile/smorgan2?ref=lorcandempsey.net), Teaching and Learning Specialist in Learning Technologies at the iSchool, who patiently helped me climb the Canvas learning curve. They each saved me from some foolishness; what remained was mostly my own.
> A major takeaway was that I needed to talk less!
This is a short piece, so here are some brief takeaways:
- I succumbed early on to the common newbie hubris of imagining that I was there to communicate my knowledge and experience. However, what I was really there for was to facilitate learning. My first course outing needed more interaction and engagement with issues, and rather less of my powerpoint, thoughtful and tasteful though it was. A major takeaway was that I needed to talk less!
- Understanding that good teaching is both learnable and a craft, I had spent some time in preparation reading around the topic. However, without the goalposts of experience, I was overwhelmed by the pedagogical firehose. To reduce confusing superabundance, I returned to [*The new college classroom*](https://www.cathydavidson.com/books/?ref=lorcandempsey.net) by Cathy Davidson as a pragmatic guide, its main recommendation being that I had met Cathy at the interesting [Amical](https://www.amicalnet.org/blog/amical-2023-recordings?ref=lorcandempsey.net) Conference shortly beforehand.
- That said, one can only do so much in one course, and one of the things I most enjoyed was digging into collaboration and thinking about how to sketch out the collaborative space. I also really liked how it made me reconnect with different types of libraries. I enjoyed, for example, exploring public libraries as social infrastructure and the importance of social capital based on Klinenberg's *Palaces of the People*. I was struck again by the differential attention in the literature to different kinds of libraries, noticing how community college libraries, for example, did not receive as much attention as other academic libraries.
- I was curious to see how my assigned readings were received. I do not wholly trust my judgements here, as they are impressionistic, supported by limited end-of-course-feedback. In general, the more abstract or theoretical pieces were less popular than ones which communicated experiences, issues or problems. Not too surprising, perhaps, but I did also wonder about the overall balance between theory and practice. I noted how, especially in the collaboration course, practitioner perspectives in the literature greatly outweighed LIS academic ones.
- I am very grateful to the guest speakers who gave generously of their time, expertise and opinions. They brought energy into the class. I am thinking of invites now for this year. A couple of things really struck me in terms of learning. The first was to communicate that libraries are social organizations, with all that that means in terms of relationships, decision-making, persuasion and influence. I emphasized this throughout. The second is that collaboration and partnership is central in many ways to what libraries do from an operational point of view, but is also so important for creating the networks and communities of practice that do so much to foster learning and innovation. Guest speakers did much to communicate the experiential reality of these two points, alongside the description of libraries, services and initiatives.

I visited Seward Park Library, which features in Klinenberg's Palaces for the People, when in NYC over the Summer
## Students
The main reason I took this position was that I knew it would be good to be challenged and engaged by different perspectives. I was interested in what animated and interested those beginning a career in libraries, archives or related organization. This aspect of the work has been very rewarding, and I have learned so much. I am also encouraged by the energy and sense of purpose I encountered among so many students, and I know they will make an impact. Here are some thoughts ...
- In both of my classes the majority of student career interests broke down approximately evenly between academic and public libraries. I was also interested in the strong archival interest, partly overlapping with the academic interest (in archives and/or special collections) and partly motivated by community archives, or specialist archives of various types. It did strike me in discussions that archives work often appealed where it made direct connections with particular communities of interest, distinctive materials, or reparative recognition and remembrance.
- There was a strong focus among students on social justice and on the agency of libraries and librarians in their communities. This is a clear emphasis of the UW iSchool and course options reflect this, as does the general ethos. This was refreshing to see, acknowledging also that political and advocacy skills will be very important in the library environment students are entering.
- In the management class (I taught in parallel and in close coordination with Chance) we asked students at the beginning of the year how many were interested in being managers. I was struck that the interest was not stronger, although a repeat question at the end of the course did suggest that some opinions had shifted. Some students went into the class thinking of management solely in terms of staff supervision. Following [Linda Hill](https://www.youtube.com/watch?v=lM4SDJwzD5s&ref=lorcandempsey.net), I tried to consistently emphasize that management involves managing oneself and one's network of relationships, in addition to one's team. And of course, organizational management, including strategy, marketing, organizational culture, and so on, is also central and may be new to some. I observed how several students overcame a prior antipathy to the idea of marketing and 'brand' to realize that a broad approach to positioning the library favorably within its community was actually very important.
- Teaching presents the classic [curse of knowledge](https://www.lorcandempsey.net/libraries-and-the-curse-of-knowledge/) situation. In summary it is very difficult to **unknow** something that you already know, and it can be difficult to imagine what it is like not to know it. This creates a potential communication gap. To close this gap we have to step outside our own usual standpoint. For example, I was initially guided by my own interests which are often organizational and strategic, but soon recognised the strong class interest in operational issues. Talking about collaboration between libraries also relies somewhat on knowledge of the object of collaboration (for example a shared ILS or shared content negotiation and licensing) and this opens out into other issues, open access or concerns around ebook licensing, for example. Similarly, in a management class, one can expect that students may have a variety of organizational and supervisory experiences, but, naturally enough, less acquaintance with some of the ways in which libraries are organized or funded. In the management class, for example, I tried to emphasize that the library is not (usually) a stand-alone entity - typically it is accountable to a city, university, or some other parent organization. Even where it reports to a board, the local government agency may appoint some board members. I learned that I need to work hard to try to traverse the gap, thinking about what is covered, using more analogies or examples, for example, and ensuring that participants are comfortable in discussion and questions. Guest speakers are very important here, bringing varied and rich experiences into the class.
- I tend to resist generational (and other) classifications, but I was struck by how direct and candid student feedback could be. I was grateful for the often thoughtful and constructive suggestions for improvement. This is certainly true of the management course. It is especially true of the collaboration one, given it was my first outing and it was new material. I am currently looking at some refocusing based on class observations. I might even lose some slides!
## Systems and services
I have [written](https://www.lorcandempsey.net/writing/) much about library systems and services. My perspective tends to be informed by my own usage, by conversations with librarians, and also by the fact that I have worked for organizations that have built systems and services that libraries rely on, both in production and in R&D mode. I was fascinated to be in a somewhat different position here, as a faculty member and teacher needing to use library resources in the construction of courses and in my other work.
I have had a more tangential relationship to instructional technology, but was looking forward to exploring Canvas and some other tools. Given the firehose note above, I did stick to the core and to a small number of tools.
Here are some slightly random observations about my experience.
- It was a great pleasure to have the resources of a large library available again. Browsing in the stacks may not be quite the adventure it once was, but being able to prospect large reservoirs of print and electronic resources is a joy. While a significant proportion of articles may now be available open access, having access to a large, licensed collection makes a big difference. What was more novel for me was being able to access a large number of ebooks at the chapter level, both for my own use and to add to course readings. The 'access gap' between those able to use a well-resourced library and those who do not have such access is still very wide.
- As library consortia were a central emphasis in the collaboration course, I was very interested to see the benefits of borrowing through the shared Orbis Cascade Alliance system in action: I appreciated receiving items from other Alliance members. The University has just joined BTAA, so the library will be participating in BTAA library initiatives in due course. Although I may be finished my term by then, I will be interested to see how this works out alongside the Orbis Cascade alliance, especially given my [work](https://www.oclc.org/research/publications/2019/oclcresearch-operationalizing-the-BIG-collective-collection.html?ref=lorcandempsey.net) with BTAA in a previous life.
> The 'access gap' between those able to use a well-resourced library and those who do not have such access is still very wide.
- I enjoyed the opportunity to interact with library colleagues. I also admired how library liaison [Alyssa Deutschler ](https://guides.lib.uw.edu/prf.php?account%5Fid=40619&ref=lorcandempsey.net)solicitously worked with iSchool colleagues, readily provided expert advice, participated in events and instruction, and generally modeled the value of the relational library.
- I have written much about the friction in the library 'discovery to delivery' (D2D) chain over the years. It is a challenge, bringing a heterogenous set of resources into a (more or less) unified environment of use, and creating required connections across discovery, authorization, and fulfilment options. A lot of plumbing is involved, and unfortunately some of this still shows. When things work well, it is very impressive (and the deployment of LibKey helps here), however the experience is occasionally not very well-seamed, let alone seamless. Given the state of the art of the involved technologies, the small number of available products to get this work done, and the general reliance on the same set of vendors, this experience is much the same in most libraries. It is not something specific to the University of Washington or to the Orbis Cascade Alliance. While I appreciate the complexities, and have experienced the heavy lift on the system/data provider side also, it is disappointing that things are not better by now.
- This may be one of the places where AI might be helpful in terms of better connecting that D2D workflow, and I look forward to trying out the Primo Research Assistant in my current environment. In general I have been interested to observe the careful way in which AI is being introduced into discovery and other products offered to libraries.
- This experience of the library D2D apparatus matters for a variety of reasons. One in particular is on my mind, as I have been thinking about perceptions of libraries in the academy in the context of [*LIS Forward*](https://lisforward.ischool.uw.edu/?ref=lorcandempsey.net) (an initiative of iSchools looking at the future of Library and Information Science education and research within iSchools and the academy). While the D2D setup is actually quite impressive when you know a little about the moving parts (proxy, knowledge base, LibKey, etc), it does not necessarily seem that way to the non-initiate. It does not showcase the library as a technological leader or innovator; quite the reverse in fact, as the library discovery experience feels like it is from an earlier period. Faculty or students cannot be expected to know about the technologies or products that are available to the library to build this experience.
- I was actually pleasantly surprised by Canvas. I thought it did a good job of supporting some complex workflows in an integrated way. While it may constrain the more adventurous, I appreciated the integrated approach and the continuity across courses. Of course, it can behave inconsistently (sometimes save is automatic, sometimes not). I appreciated that it got the job done and that once you were sufficiently high up the learning curve, you could put your energies elsewhere. As I noted above, I was grateful here to receive a lot of help from the Learning Technologies unit.
- I really like Papers from ReadCube, a Digital Science company. I have used Mendeley and Zotero in the past, but my incentives were not strong enough to climb very far along the learning curve. In my current role, the incentives are stronger, but I have actually also found Papers more straightforward to use. It also works very nicely with the library systems infrastructure mentioned above, and, when all the connections work well, it is like magic to move from publisher page to well formatted citation and stored PDF smoothly. One frustration was the treatment of books. It does not automagically pick up a citation from Amazon or WorldCat, for example, which seems like a miss all around. There was recently an AI upgrade which added some capabilities, including asking questions of a PDF. (This is a small example of how we will interact in more ways with documents in the future.)
- I found the annotation tool Hypothesis very useful, and while not universally loved by students, it did add a dimension to reading and discussion, especially if used in moderately sized groups. Again, it is nice the way it manages a workflow smoothly.
> However, without the goalposts of experience, I was overwhelmed by the pedagogical firehose. ... I found developing my first course quite stressful as I did not know what I did not know.
- I found developing my first course quite stressful as I did not know what I did not know. I made the mistake of trying to build the initial outline in Canvas. This made it difficult to see the course as a whole, and difficult to work on trying to change staging of topics, speakers and exercises. Probably the best advice I received during the year was when Chance suggested I shifted this planning to a whiteboard. In fact I ended up using stickies stuck to the whiteboard at work, and duplicated on the bedroom wall in our small rental. It was simple ... and liberating.

Sophisticated and streamlined course design process.
## Education and career preparation
My experience so far has caused me to reflect quite a bit on library education.
The MLS has always been a challenge, given the variety of skills and specialties at play in libraries. This has become even more so as libraries continue to evolve from being transactional and collections-centered to being relational and community-centered. This means that they manifest interesting educational and research issues, from the technical, to the management, to the social and political.
In one program, how do you balance coverage of broad technical skills and appreciation, nurturing community – whether it is in busy urban settings or around student success and retention –, the management of complex social and political organizations, and the (inappropriately named) [soft skills](https://www.lorcandempsey.net/soft-skills-are-hard/) which are so central to so many aspects of work (teamwork, advocacy, empathy, self care, ...)?
It also prompts reflection on the relationship between research and practice, and on how the library community generates ideas and innovation. There are plenty of topics to return to.
It is a critical time for libraries, and so a critical time for library education and research. I am looking forward to year two!
**Acknowledgements:** Thanks to Alyssa Deutschler, Chance Hunt, Sue Morgan, Denise Pan, and Lauren Pressley for their helpful review of an earlier draft. I am especially grateful to Gabrielle Garcia (UW MLIS '24) for a thoughtful reading and helpful suggestions. While their feedback improved the final piece, all opinions are my own and they do not necessarily agree with all I say!
**Pictures:** I took all the pictures, and also made a lot of soda bread during the pandemic.
**Other entries mentioned:**
[So-called soft skills are hardSo-called soft skills are important across a range of library activities. Existing trends will further amplify this importance. Describing these skills as soft may be misleading, or even damaging. They should be recognized as learnable and teachable, and should be explicitly supported and rewarded.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/soft-skills-are-hard/)
[Libraries and the curse of knowledgeIt is important to know what you know, so that you can avoid the curse of knowledge and communicate effectively.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/libraries-and-the-curse-of-knowledge/)
[Operationalizing a collective collectionWhile collective collections have been much discussed, less attention has been paid to how to operationalize them in consortial settings. This post introduces work done with the BTAA to explore this challenge.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/operationalizing-a-collective-collection/)
### Libraries, AI and the messy middle
URL: https://www.lorcandempsey.net/presentation-libraries-ai-and-the-messy-middle/
Last updated: 2024-12-04T21:16:59.000Z
I am trying something new. I have recently been presenting about AI and libraries. I have annotated and augmented the presentation so that it is a little more self-standing than my usual more elliptical powerpoints.
By the *messy middle*, I mean that libraries are having to grapple with real questions about AI deployment, procurement and use. They may participate in discussions about bold futures or about grave risks. But they also have to provide advice to creators and consumers, create policies and guidelines, and evaluate the AI-enabled offerings of their vendors. Today.
Here is the presentation:
[Libraries, AI And The Messy MiddleThis presentations discusses a variety of issues around AI and its adoption in libraries.figshare](https://figshare.com/articles/presentation/Libraries%5FAI%5FAnd%5FThe%5FMessy%5FMiddle/25974283?file=46828723&ref=lorcandempsey.net)
And here are some additional links. For ease of presentation, I have loaded **PDF** and **PPTX** files.
I gave shorter versions of this presentation as keynotes at two interesting and rewarding meetings recently. I benefited greatly from the rich discussion and other presentations at each event, and am grateful to the organizers for the invitation.
- ***California AI Libraries Summit***, California State Library, Sacramento. 26 April 2024.
- ***Vancouver Island Library Staff Conference 2024***, University of Victoria, Victoria. 3 May 2024


McPherson Library, University of Victoria, and the California State Library, Sacramento
## Coda
For some additional perspectives see the following blog posts and short articles.
I am pleased to have an article on Libraries, AI and training collections in this special issue of Against the Grain.
[Predicting the Unpredictable | American Libraries MagazineAI is everywhere. Library decision makers must understand and weigh both constructive and problematic elements of this technology.American Libraries MagazineLorcan Dempsey](https://americanlibrariesmagazine.org/blogs/the-scoop/predicting-the-unpredictable/?ref=lorcandempsey.net)
Inaugural column in this series. Introduces some issues around AI and argues for greater coordination among bodies representing library interests.
[AI - LorcanDempsey.netPosts about evolving AI story and its implications for libraries.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/tag/ai/)
Blog posts on AI.
[Generative AI and libraries: seven contextsLibraries are engaging with AI in their educational, service and policy work. This post discusses seven contexts in which that work is taking place.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/generative-ai-and-libraries-7-contexts/)
A recent discussion of libraries and AI.
**Pictures:** All pictures taken by me.
### Smile: let's see your teeth
URL: https://www.lorcandempsey.net/the-whole-tooth/
Last updated: 2024-04-25T15:10:26.000Z
*Smile* is a very engaging novel. It is the most popular of Raina Telgemeier's works, if measured by Amazon sales. I bought it last year, prompted by the enormously successful [exhibition](https://cartoons.osu.edu/events/facing-feelings-the-art-of-raina-telgemeier/?ref=lorcandempsey.net) about her work at the Billy Ireland Cartoon Library and Museum at The Ohio State University.
The graphic novel version came out just too late to be a big part of our own children's reading, so I was not familiar with it before.
It is based on the author's own experience of damaging two front teeth in sixth grade, and the emotional, practical and social consequences that followed.
I liked the wit and the clever illustration. I liked how it spoke to the ramifications of such an event through so much of life at an important time in growing up. I have been interested to [read a little](https://en.wikipedia.org/wiki/Smile%5F%28comic%5Fbook%29?ref=lorcandempsey.net) about its web-comic origins as well as the general impact.
However, most of all, it resonated strongly with my own experiences, and caused me to reflect on those.
I broke a front tooth when I was about 10\. We were streaming out of school on the last day of term when the boy in front of me suddenly turned; my upper teeth crashed into his forehead.
I remember the prolonged treatment to try and save the tooth as it became infected. I traveled many times on the bus with my mother to the dental clinic in the city centre, near the looming large and grey Christ Church Cathedral. The clinic was a cold, institutional building.
However, I ended up losing three of my front teeth as the infection spread. I was fitted with a dental plate, which over the years would break from time to time. It also fit progressively less well as I got older, and sometimes in class, I would realise I was moving the teeth in and out with the suction of my tongue on the plate.
I had to take the false teeth out for sports, and it was before people wore mouth guards. In retrospect, I was lucky not to have one of the teeth on either side of the gap knocked out on the rugby field. Swimming was definitely safer. I was not, I confess, a natural athlete, but having to play without front teeth further dampened my desire to participate. In general people were kind, although I was occasionally called Dracula.
Years later, I had what seemed like an overly prominent bridge fitted when I worked for a year in a rubber factory in Germany. When the dentists saw the denture, they were amused and disbelieving that I still wore something so old and by now ill-fitting. Years later again, I had a new less prominent bridge fitted when living and working in the UK. And then when I came to the US, I needed something of an overhaul as the teeth holding the bridge were replaced by implants and I got another bridge.
Yes, with this and other things I have spent a lot of time in the dentist, and a lot of money. Rather more, maybe, than the character in *Smile*.
I believe the experience shaped me in various ways. It certainly made me self-conscious about smiling, which played into more general social interactions, conspiring with a natural shyness to make me sometimes seem aloof. And I do not like posing for photographs, as smiling on demand does not come naturally.
I was drawn to the way in which psychological and emotional consequences were explored in *Smile.* I admired the wit with how the story was told and illustrated. However, my normal critical responses were largely suspended as I was transported back into my own at once similar and very different experience.
**Picture:** Part of the cover of my copy of *Smile*.
### So-called soft skills are hard
URL: https://www.lorcandempsey.net/soft-skills-are-hard/
Last updated: 2024-09-03T15:21:10.000Z
We can recognize the importance of 'soft skills' while acknowledging that 'soft' has multiple associations that may be misleadingly at variance with the importance of those skills.
In this post, I look at some contexts which are making such skills both more visible and more important before making some general concluding observations. It is clear that such skills are core needs for the library which is increasingly networked, relational and community focused.
> We can recognize the increasing importance of 'soft skills' while acknowledging that 'soft' has multiple associations that may be misleadingly at variance with the importance of those skills.
Soft skills, and the contributions of the (often female) library workers who demonstrate them, have often been undervalued or gone unobserved. However, the value and visibility of this work is increasingly recognised, and indeed acknowledged as central.
For example, this recognition is a major focus of the important [collection](https://www.cambridge.org/core/books/social-future-of-academic-libraries/4ECBBA26E7B474067C877CEE055D1DD1?ref=lorcandempsey.net#fndtn-information) *The Social Future of Academic Libraries*: *new perspectives on communities, networks and engagement.* It raises up the sometimes invisible relational work of library workers, and places it very much at the center of library operations and value.
What are soft skills? Examples are emotional and social intelligence, persuasion, team-working, empathy, communication, negotiation, networking, maintaining boundaries and self-care, conflict resolution, cultural awareness, advocacy, relationship-building. I have deliberately presented these as a random list to emphasize that there is no neat definition or bounded category here.
Seth Godin contrasts them with 'vocational' skills and suggests calling them 'real' skills:
> Vocational skills can be taught: You’re not born knowing engineering or copywriting or even graphic design, therefore they must be something we can teach. But we let ourselves off the hook when it comes to decision-making, eager participation, dancing with fear, speaking with authority, [working in teams](https://ideas.ted.com/the-3-things-that-great-teams-have-in-common/?ref=lorcandempsey.net), seeing the truth, speaking the truth, inspiring others, doing more than we’re asked, caring and being willing to change things. We underinvest in this training, fearful that these things are innate and can’t be taught. Perhaps they’re talents. And so we downplay them, calling them soft skills, making it easy for us to move on to something seemingly more urgent. // [Seth Godin](https://ideas.ted.com/soft-skills-and-real-skills/?ref=lorcandempsey.net)
The phrase 'soft skills' is quite problematic in several ways, including its gendered reception. I discuss some issues below. It is tempting to pre-empt that discussion and refer to such skills as CORE skills, where CORE stands for COmmunication, Relational and Empathetic, or some-such \[although see my note about CORE below\]. But although it sends out the right message – that what we have come to call 'soft' skills are in fact 'core' skills – it is probably too confusing.
Similarly, although I think that they might be better, I don't use 'strategic' or 'relational' or 'social' in place of 'soft.' Even though it is clear that 'soft' is hopelessly inadequate when it comes to describing some of the social/relational/strategic skills required in today's library.
## Four contexts
There is a variety of contexts where the importance of soft skills is increasingly highlighted. I describe four here.
### ① The relational library
A frame is always useful. I find it helpful to think of an evolution from a library which is configured around the collection, to one which is configured around the civic, learning or research needs of the people it serves. The ***relational library*** is a helpful label in this context.
One could also point to David Lankes' succinct [provocation](https://davidlankes.org/the-lankes-corollaries/?ref=lorcandempsey.net): 'Bad libraries build collections, good libraries build services, great libraries build communities.'
In an academic setting, the library is interested in more directly supporting research and learning workflows, building connections with departments, instructional practice and research groups. It is also developing richer partnerships with other campus agents, which might include, for example, the center for teaching and learning, the office of sponsored research, and student success initiatives. The library, like other campus units, will be in ongoing interaction with core university functional units such as facilities or communications. What Rebecca Bryant calls [social interoperability](https://hangingtogether.org/category/research-support/social-interoperability/?ref=lorcandempsey.net) is key.
In a public library setting, the library is welcoming the community to its space with a growing variety of creative activities and events. It is partnering with social and educational services, with local charities or cultural institutions, with schools and colleges. It is reaching previously overlooked or marginalised populations, it is developing special programs for particular language groups, it is providing services for immigrants. The awareness of the role of the public library as critical social infrastructure has been elevated by the publication of Eric Klinenberg's *Palaces for the People*.
> The library provides access to the means of creative production.
This deeper community engagement requires what we have called soft skills - communication, relational skills, cultural competence. Working with partners also involves these skills, along with persuasion, trust-building and negotiation. And given that library communities may vary quite a bit, there is a premium on flexibility and adaptability.
The use of 'soft' seems especially misleading in the context of the current realities of public library work. Bringing the community into the library means bringing the whole community into the library. And so, library workers have often to engage with community issues, including mental health, homelessness, food insecurity, and a range of social circumstances for which they may be not very well prepared.
### ② Challenges to value and values
In an important article about library value, Eleanor Jo Rodger characterises the public library in this way.
> Similarly, public libraries are society's way of paying attention to learning and equity. In the United States we hold both in high esteem, so we fund public libraries with tax revenues. // [WebJunction](https://www.webjunction.org/documents/webjunction/Value%5Fand%5FVision.html?ref=lorcandempsey.net)
This was written over twenty years ago. We are in a different political environment now. What happens when learning and equity are not held in high esteem, or their value is questioned? Or when the longstanding values or policies around collections are challenged?
At the same time value questions may be asked of all types of libraries given competing financial demands, mistaken impressions about the digital environment, and so on.
There are very big issues here, but in the context of this post, I want to note again the importance of advocacy, persuasion, storytelling, communication, and relationship building. In any discussion, it is important to understand the position of others, especially if one wants to persuade them of a particular course of action.
Such 'soft' skills don't seem very soft in this context, as the librarian interacts with the mayor, the library board, the provost or the faculty committee.
Again, the recent environment in public libraries underlines this as library workers have to be prepared to talk about collection development, events or other policies in the face of organized and persistent challenges.
### ③ Collaboration and partnership
Collaboration is central to library operations. Libraries also scale learning, innovation and advocacy through collaborative work. And as discussed above, libraries partner with others, whether these are other units within the parent municipality or college, or are outside.
It would actually be interesting to see some research into how much time library workers spend on collaboration and partnership. My sense is that this considerable, and that it is also growing. At the same time, libraries are looking more critically at collaboration, assessing the level of investment it requires.
At the University of Washington, I have been developing a course on library collaboration and partnerships. It has seemed to me that this is a somewhat overlooked area in library education, but also in strategy and planning, given how central it is to library operations and thinking.
In working through the course, I have been struck by how much this kind of library work also depends on what we call soft skills.
Collaboration involves communication, relationship-building, negotiation, teamwork. It involves building the trust that allows candid conversations about priorities to happen. But it is much more. Within these collaborative settings, librarians mentor colleagues from other institutions, develop confidence in committee work and presentation, and advocate for their library's interests. The social and political environments that collaborative working involves depend on 'soft' skills to work well and in turn they allow people to develop those soft skills.
[The powers of library consortia 1: how consortia scale capacity, learning, innovation and influenceLibraries and related organizations group together in a variety of ways to get their work done. They consort where there are scale advantages: to lobby, for example, to negotiate and license, to reduce costs, or to build shared infrastructure.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/the-powers-of-library-consortia-1-how-consortia-scale-capacity-learning-innovation-and-influence/)
A discussion of dynamics of collaborative working
### ④ Equity and empathy
Library workers have been stretched and stressed in very challenging ways in recent years through the pandemic, social unrest, and the real impacts of the culture wars. The murder of George Floyd made libraries and library workers recognise the need to more purposefully identify and repair harm. Librarians have had to step up to additional roles and to handle difficult situations in the workplace. Organizational and hierarchical issues have been emphasised, as, for example, in the uneven need to be physically present during the pandemic. Some may now be concerned about the uncertain impact of AI on their work, and the potential dilution of social trust and confidence as synthesized communication or creation spreads. This is especially so in this year of elections. The cumulative emotional attrition has been draining, and empathy can be difficult.
This may be leading to a change in sensibilities and expectations around libraries and the roles of library workers:
> This may be unevenly manifested, but underlines the need for the library to recognize the importance of equity and empathy, in terms of both value created and values embraced. We know that libraries are social organizations supporting mental wellness, social cohesion, and personal and community development. Current experience has foregrounded these roles.
It has also foregrounded the importance of empathy and understanding in the workplace, as managers and as colleagues. Empathy, transparency and communication are central.
Writing about soft skills, Emy Nelson Decker \[2020\] notes a claim that "many professions that rely heavily upon empathy or listening to the needs of others (i.e. soft skills) are also notorious for burn out or "compassion fatigue."
The work of Kaetrena Davis Kendrick on [empathy and self-preservation](https://kaetrenadaviskendrick.wordpress.com/?ref=lorcandempsey.net) is very relevant here. See for example this WebJunction webinar with a recording and related resources.
[Low Morale in Libraries: Impacts and CountermeasuresLearn about important research on low morale and leave with actionable ideas for promoting a healthy work environment for all staff and cultivating empathetic leadership in libraries.WebJunction](https://www.webjunction.org/events/webjunction/low-morale-in-libraries.html?ref=lorcandempsey.net)
Webinar organized by WebJunction which includes a useful collection of additional related resources
I was taken with this comment from her co-presenter, Sunnie Scarpa: 'Hire and train empathetic staff with healthy boundaries.'
[Reflecting life and career: advice to an LIS graduate studentWhat do I value about libraries? asked a student. What is essential for a library student to know? Here are several ways in which life experiences have influenced my views.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/letter-to-an-lis-graduate-student/#grow-into-your-voicefocus-on-equity-and-empathy)
The paragraphs above draw on a fuller discussion of equity and empathy in this post, from where the quote above also comes
###
## Discussion - the new core
There has been some research about soft skills in the library field, notably by Laura Saunders. She has explored the knowledge, skills and attributes (KSAs) reported as necessary to library work. She identified eleven KSAs deemed core, and of those seven (and possibly eight depending on categorization) were general and could be considered 'soft skills.'
She makes this interesting note about importance:
> This emphasis on interpersonal and communication skills seems to align with the idea of the information professions as user-centered and customer-service oriented. Partridge, Menzies et al. asserted from their findings that “personality traits, not just qualifications, were critical to be a successful librarian or contemporary information worker” (2010, p. 271), and Saunders (2015) found that some focus-group participants said they would prioritize soft skills over hard skills or content knowledge when hiring. // *Saunders, 2019*
This article dates from 2019 based on survey work carried out in 2017\. Given the contexts described above, I imagine that soft skills would be found to be even more urgently important today.
So soft skills are critical to library work in multiple ways and to positioning the library effectively in the community it serves. However 'Soft' is potentially misleading or unhelpful in several ways. In fact the use of the word may actually be damaging in particular settings, or it may suggest something that is directly counter to the actual situation.
- It can suggest that such skills cannot be learned or taught. However, they can be, and how they should be tackled is an intriguing question for library education. In fact, mentoring is an important skill, as is a disposition to learning.
- It can suggest that such skills are less important than so-called 'hard' skills. Or are somehow easier to develop. However, as noted above, and as can be easily seen elsewhere, soft skills are very important in the workplace. And they need to be learned and practiced.
- It may mean that those who have good soft skills are less valued than those with putatively harder skills, that their opinions are less valued, or that they are pushed to the sidelines of decision-making.
- The language may reflect or support prejudices about gender, given the association that may be made between hard and soft, respectively, and masculine and feminine. Emy Nelson Decker notes: "This is particularly worrisome in a historically feminized field as is the case with library science."
- It can suggest that so-called soft and hard skills are mutually exclusive, and that one can only optimise for one. However, consider how we want to be treated in medical settings. Soft skills are important to [technology](https://www.lorcandempsey.net/technology-is-not-on-the-outside/) workers, say, as much as to others.
- A recent *Journal of Engineering Education* editorial [argued](https://doi.org/10.1002/jee.20442?ref=lorcandempsey.net) that it may reduce emphasis on equity and inclusion. 'Ultimately, using the term "soft skills" pushes individuals that advocate for and excel at human-focused competencies to the margins of engineering. While these skills have typically involved communication and interpersonal skills, they also involve commitments to equity and inclusion."
Dissatisfaction with the term is common. I was interested to read these two comments in the context of library collaboration.
> The abilities required for collaboration tend to be poorly covered in professional competency statements, scattered around under multiple headings and also inaccurately labelled in the library literature as “soft skills”, indicating fundamental gaps in understanding that need to be addressed as a matter of urgency. // Sheila Corrall, [*Foreword*](https://alastore.ala.org/netwsch?ref=lorcandempsey.net)
> Most people think of collaboration as a soft skill and dismiss it with a shrug. Here’s the thing: You don’t collaborate to make people feel okay, because it’s expected of you, or to earn brownie points. You collaborate because on large-scale projects, you have no choice. // Valerie Horton, [*American Libraries Magazine*](https://americanlibrariesmagazine.org/2021/11/01/the-necessity-of-collaboration/?ref=lorcandempsey.net)
However, a quick search shows that this dissatisfaction spreads to the general business press and elsewhere.
> While technical skills are vital, "soft skills" are the glue that holds people, teams, and business units together. These skills encompass a wide range of abilities, including communication, problem-solving, critical thinking, emotional intelligence, and teamwork. They are the foundation upon which leaders and their teams develop trust, cooperation, and high performance. // It's about time we abandoned the term 'soft skills', [*Forbes*](https://www.forbes.com/sites/danpontefract/2023/03/27/its-about-time-we-abandoned-the-term-soft-skills/?sh=2ef8b8281ff7&ref=lorcandempsey.net)
The author argues for the adoption of 'professional skills' (which itself might be challenged by some). The [piece](https://americanlibrariesmagazine.org/blogs/the-scoop/predicting-the-unpredictable/?ref=lorcandempsey.net) by Seth Godin I reference above is worth reading in full in this context.
That said, changing the name is unlikely to happen quickly or universally. I think we would benefit from an alternative term which is generally understood. However, the bigger immediate issue is value, recognition and preparation.
For the library community, soft skills are core, and critical to the success of the relational, community focused library. They are essential and valuable skills for all library workers. And what we might have called soft skills are now needed in some very difficult front-line situations where the values of the library are challenged or where library workers are engaging with social issues and stressed populations.
This importance should be recognised ... and not only performatively. But recognised in reality, with focused systematic attention when it comes to review, professional development, promotion, recruitment, human resourcing plans, strategies, job boundaries, and so on.
And it should be recognized that soft skills are not only essential, but they are very hard.
CORE. After suggesting CORE skills above (to refer to Communication, Relational and Empathy), I read Emy Nelson Decker's interesting article on soft skills in academic library settings \[Decker 2020\]. She references the use of CORE to designate Competence in Organizational and Relational Effectiveness.
## Some references
Berdanier, C. G. P. (2022). A hard stop to the term “soft skills.” *Journal of Engineering Education*, *111*(1), 14–18\. [https://doi.org/10.1002/jee.20442](https://doi.org/10.1002/jee.20442?ref=lorcandempsey.net)
Corrall, S. (2024). Foreword: The Network is the Message. In S. Pavey, *The Networked Librarian: The School Librarian’s Role in Fostering Connections, Collaboration and Co-creation Across the Community*. Facet.
Decker, E. N. (2020). The X-factor in academic libraries: the demand for soft skills in library employees. *College & Undergraduate Libraries*, *27*(1), 17–31\. [https://doi.org/10.1080/10691316.2020.1781725](https://doi.org/10.1080/10691316.2020.1781725?ref=lorcandempsey.net)
Horton, V. (2021). The Necessity of Collaboration. *American Libraries Magazine*. [https://americanlibrariesmagazine.org/2021/11/01/the-necessity-of-collaboration/](https://americanlibrariesmagazine.org/2021/11/01/the-necessity-of-collaboration/?ref=lorcandempsey.net)
Kendrick, K. D., & Scarpa, S. (2023, June 29). *Low Morale in Libraries: Impacts and Countermeasures* \[Webinar recording and materials\]. [https://www.webjunction.org/events/webjunction/low-morale-in-libraries.html](https://www.webjunction.org/events/webjunction/low-morale-in-libraries.html?ref=lorcandempsey.net)
Rodger, E. J. (2002). Value and Vision. *American Libraries*, *33*(10). [https://www.webjunction.org/documents/webjunction/Value\_and\_Vision.html](https://www.webjunction.org/documents/webjunction/Value%5Fand%5FVision.html?ref=lorcandempsey.net)
Saunders, L. (2019). Core and More: Examining Foundational and Specialized Content in Library and Information Science. *Journal of Education for Library and Information Science*, *60*(1), 3–34\. [https://doi.org/10.3138/jelis.60.1.2018-0034](https://doi.org/10.3138/jelis.60.1.2018-0034?ref=lorcandempsey.net)
Saunders, L., & Bajjaly, S. (2022). The Importance of Soft Skills to LIS Education. *Journal of Education for Library and Information Science*, *63*(2), 187–215\. [https://doi.org/10.3138/jelis-2020-0053](https://doi.org/10.3138/jelis-2020-0053?ref=lorcandempsey.net)
**Photograph:** I took the picture at the University of Washington, where I am currently [based](https://ischool.uw.edu/news/2023/10/library-luminary-eager-share-practical-expertise?ref=lorcandempsey.net) in the Information School.
**Acknowledgements:** I am grateful to Sari Feldman, Alicia Salaz, and Sharon Streams who generously commented on a draft.
### AI, OpenAI and the evolving AI environment
URL: https://www.lorcandempsey.net/ai-x-and-the-rest/
Last updated: 2024-08-27T21:16:05.000Z
For a while the OpenAI 'ouster' was the top [story](https://www.nytimes.com/2023/12/09/technology/openai-altman-inside-crisis.html?ref=lorcandempsey.net) on the *New York Times* home page, and they devoted considerable ongoing coverage to it. Given the impact of ChatGPT and the commercial, social and policy pervasiveness of AI it was big news. And even if things have settled down again, it has changed perceptions of the organization and kept concerns about AI in the news. Here are some thoughts about what has happened, with some notes about library connections and impacts. I include a short coda on environmental analysis in the library community.
I discussed some library contexts in a [fuller post](https://www.lorcandempsey.net/generative-ai-a-note-about-content/) recently so do not repeat too much of that here. See the links at the end for my series of longer AI posts.
## The future is the future
[Writing](https://www.lorcandempsey.net/generative-ai-and-libraries-7-contexts/) about libraries and AI recently, I noted that the situation was unpredictable. How true that turned out to be! I was thinking about how social practices and their material base in technology interact unpredictably (think of the selfie, then *Instagram*, then the impact on travel or the baleful influence on mental wellness, for example). However, two things jumped out at me over the last few weeks.
First is the impact of personalities and politics on organizational direction and values. Quite often this may be hidden from us, or go undocumented in the public record. And while we do not know exactly what happened, clearly personal dynamics were at play here. This was at various levels. In the Board interactions. In the relationship between the Board and senior staff. In the staff responses at OpenAI. In the personal and business network of Sam Altman. And so on.
We have seen another extraordinary recent example of personality at play in the events surrounding the acquisition and development of Twitter, and the destruction of value that has followed. This may be unusual and exceptionally visible, but it does show how things can go in unanticipated directions.
Second is some of the technical direction. I have observed how OpenAI was reportedly surprised at the success of *ChatGPT*. It was interesting to see this confirmed in the extensive background reporting around the events. Internally, the launch of *ChatGPT* was referred to as a **low-key research preview** and was not expected to attract very much notice. Of course, things turned out very differently, and the *ChatGPT* launch is now seen as a significant inflection point, on a par with the introduction of the graphical web browser or the iPhone, which has led to major investment, experimentation and impact.
> After things settled down, OpenAI employees used DALL-E, the company’s A.I. image generator, to make a laptop sticker labeled “Low key research preview.” It showed a computer about to be consumed by flames. // [NYT](https://www.nytimes.com/2023/12/05/technology/ai-chatgpt-google-meta.html?ref=oembed)
## What is the narrative?
The dominant narrative to emerge in the commentary was about the balance of existential risk and extreme reward.
> The ouster on Friday of Mr. Altman, 38, drew attention to a longtime rift in the A.I. community between people who believe A.I. is the biggest business opportunity in a generation and others who worry that moving too fast could be dangerous. And the vote to remove him showed how a philosophical movement devoted to the fear of A.I. had become an unavoidable part of tech culture. // [New York Times](https://www.nytimes.com/2023/11/18/technology/open-ai-sam-altman-what-happened.html?ref=lorcandempsey.net)
This binary contrast between commercial opportunity, often coupled with a techno-optimism about impact, and the strong societal risk posed by unstable or out of control systems seems to deflect attention from critical engagement with current deployment. This narrative is supported in some ways by the continued stated goal of OpenAI to achieve AGI (Artificial General Intelligence) in a responsible way, as a focus on AGI moves the conversation to an undefined future state and away from current business and service choices.
This general media framing of the current state of AI tended to bypass the factors accompanying the broad rollout of these technologies, sometimes preferring [speculation](https://www.theverge.com/2023/11/22/23973354/a-recent-openai-breakthrough-on-the-path-to-agi-has-caused-a-stir?ref=lorcandempsey.net) about a mysterious Q\* initiative. Meanwhile, the rapid spread of AI continues across sectors, across startups and established businesses, and across the scholarly and cultural domains. Informed choices and use, responsible deployment, policy and ethical frameworks: these are all now central questions in many contexts. The drama narrative pushed aside concerns around some of these current issues and possible remediations (to do with composition of training data, for example, or documentation, hidden labor, mitigation of bias, and so on). It also blurs the real differences among actually existing services in terms of training data, business models, reuse of data, and so on.
This is important ground for libraries to occupy - to advocate, advise and to make informed decisions about AI that is actually existing and increasingly in operation (AI-AE-IO). Libraries, and the organizations that represent them, are well placed to understand and represent public, scholarly and cultural interests. AI is not an abstract entity: it is delivered in particular products and services, which incorporate decisions about how they are designed, built and operate. What data is used or collected? What behaviors can you expect? And so on. This was more fully discussed in my [post](https://www.lorcandempsey.net/generative-ai-and-libraries-7-contexts/) on library contexts.
## Board and governance
The complicated nested [governance model](https://openai.com/our-structure?ref=lorcandempsey.net) of OpenAI has been much referenced, where a not-for-profit dedicated to safe deployment has a for-profit subsidiary, with a 'capped profit' model. The Board's fiduciary responsibilities to society are laid out in the documentation.
> We initially believed a 501(c)(3) would be the most effective vehicle to direct the development of safe and broadly beneficial AGI while remaining unencumbered by profit incentives. We committed to publishing our research and data in cases where we felt it was safe to do so and would benefit the public.
They set up a for-profit subsidiary capable of raising capital to fund development at the required level. Limits were placed on what individuals or investors could take out of the company.
> The for-profit’s equity structure would have caps that limit the maximum financial returns to investors and employees to incentivize them to research, develop, and deploy AGI in a way that balances commerciality with safety and sustainability, rather than focusing on pure profit-maximization.
Some felt the incentives are so misaligned here that it was inherently unstable. And it seems that at this stage that the for-profit incentives are driving the organization, within an overall stated commitment to responsible development. However, what is surprising is that the Board took action at such a late stage given the pace of developments. And also that all parties allowed things to arrive at this apparent breakdown. This is especially the case given what appear to be major philosophical differences between the Board and Altman.
The intervention seemed too late in the game when so much was at stake, to Microsoft, for sure, given the scale of their investment, but also to the whole ecosystem that has come to depend on OpenAI. OpenAI had become too important to too many stakeholders – in terms of both investment and use – for those involved not to find a vehicle in which to continue. So, admittedly with hindsight, the outcome is not too surprising, even if it ran through a hectic unpredictable course. It will be interesting to see what changes in governance now evolve as the very different new board settles in.
From a library point of view, I think this highlights the importance of governance, and underlines board responsibilities as fiduciaries. This is especially important in a community which relies so much on non-profit and collaborative organizations for advancing its aims. It is tempting to think of boards as advisory committees, or as career accelerators. However, board members have an important responsibility for thinking about the vitality of organizations, and by extension of the library community. And also for thinking about which organizations are useful and how existing organizations can work together. This may involve difficult decisions.
> Board members act as trustees of the organization’s assets and must exercise due diligence and oversight to ensure that the organization is well-managed and that its financial situation remains sound. // [Board Source](https://boardsource.org/resources/fiduciary-responsibilities/?ref=lorcandempsey.net)
## Concentration of power and reward
Microsoft, and accomplished media communicator Satya Nadella, moved quickly and, with other investors, were clearly major players in the flurry of discussions after the ouster. While Microsoft did not have a board seat, it had strong influence through the scale of its investment, which was partly [structured](https://www.semafor.com/article/11/18/2023/openai-has-received-just-a-fraction-of-microsofts-10-billion-investment?ref=lorcandempsey.net) as infrastructure support and rights to OpenAI intellectual property. In [interviews](https://nymag.com/intelligencer/2023/11/on-with-kara-swisher-satya-nadella-on-hiring-sam-altman.html?ref=lorcandempsey.net), Nadella emphasized the close operational integration between the companies and their shared technical leadership. In this way, it appears Microsoft was well placed to pick up or to continue with developments itself, even if OpenAI were to go in another direction.
The strength of the reaction to the news was a signal of how important OpenAI had become in financial terms, but also in service terms. Many organizations have built services on top of its APIs or used it in other ways. And while systems might be engineered to swap in a difference language model service at the backend, there is effort involved, and GPT-4 currently leads in terms of usage, functionality and ongoing development.
The outcome seems to have confirmed OpenAI as the clear leader in commercial AI development. Even if it has exposed some issues and raised questions about organization, leadership and direction. The organization has had to slow down its subscription business given issues handling volume of demand. Its close relationship with Microsoft is also now in clear view.
Google has recently released its [Gemini](https://www.theverge.com/2023/12/6/23990466/google-gemini-llm-ai-model?ref=lorcandempsey.net) model in various versions, and has swung the company behind a push to integrate AI, to provide AI services, and not to let the advantage go elsewhere. It has seen how its core search business is potentially vulnerable.
OpenAI/Microsoft and Google are the dominant players, and have made massive investments to position themselves as AI leaders. We seem to be witnessing the same network dynamic we have seen since the web first began. At that time there was great creativity and innovation diffused throughout many organizations on the network. However, the power of network effects created a small number of dominant players in near monopoly positions. Think of Google, Amazon, Facebook. Things may change (look at Twitter again) but we see this dynamic again and again.
It is clear that Microsoft and Google are determined not to be displaced by new entrants, and they want to take a large share of what is seen as an inevitable AI bounty. Microsoft's position is deeply connected to OpenAI, and protecting and building on that lead is part of the recent dynamic. (See the HuggingFace [ratings](https://huggingface.co/spaces/lmsys/chatbot-arena-leaderboard?ref=lorcandempsey.net) of Chatbots.)
Amazon, Nvidia and a variety of others are also important. For example Anthropic (set up by a group which left OpenAI earlier, concerned about safety issues), Cohere, and others are now important players in providing AI-based infrastructure and services. There is strong interest in new French entrant, [Mistral](https://arstechnica.com/information-technology/2023/12/new-french-ai-model-makes-waves-by-matching-gpt-3-5-on-benchmarks/?ref=lorcandempsey.net), which recently released an open source model capable of running on personal machines. There are many, many others. A service like perplexity.ai shows the potential threat to Google's search business, and one wonders whether it will be bought by one of the bigger players.
Now, as I noted, things are also very unpredictable. And there certainly are robust open source and other alternatives. Will they remain niche? Or become central players also? Are there other players who will step in? And I haven't said anything about China. For the moment, however, it would seem that Microsoft/OpenAI and Google are set to be the major players in a crowded field for a while yet.
It is important that libraries understand some of these market dynamics, but also look beyond the dominant players where it makes sense given the rich ecosystem that is emerging. For example, there are some important [initiatives](https://www.lorcandempsey.net/generative-ai-a-note-about-content/) in cultural or scholarly domains for specialist purposes, a range of focused applications, a developing set of open source models, and so on.
## Research-forward?
The boundary between the academy and AI companies has been very porous, and some major players move between the two. The OpenAI Chief Scientist, Ilya Sutskever, who was on the Board which dismissed Altman had worked with Geoffrey Hinton at Toronto.
I was struck by this piece underlining a division between product and research, or between an **industrial** perspective and an **academic** one. This is related to the reward vs risk dynamic, but emphasizes another dimension.
> One thinks AGI is better achieved by deploying products iteratively, raising money, and building more powerful computers — what we could call the industrial/business approach. The industrial approach group includes Altman and Brockman, who have championed the idea of iterative deployment in public the most. The other group, comprised of those who executed the coup against them, including Chief Scientist Ilya Sutskever, thinks AGI is better achieved by conducting deeper R&D on things like interpretability and alignment and devoting fewer resources to making consumer-oriented AI products — what we could call the academic approach. // [*The Algorithmic Bridge*](One thinks AGI is better achieved by deploying products iteratively, raising money, and building more powerful computers — what we could call the industrial/business approach. The industrial approach group includes Altman and Brockman, who have championed the idea of iterative deployment in public the most. The other group, comprised of those who executed the coup against them, including Chief Scientist Ilya Sutskever, thinks AGI is better achieved by conducting deeper R&D on things like interpretability and alignment and devoting fewer resources to making consumer-oriented AI products — what we could call the academic approach.)
Clearly, I do not know how strong this dynamic was, but it seems at least somewhat plausible.
What this whole episode does seem to signal is the emergence of the industrial approach as a dominant shaper. The commercial interests seem to be driving OpenAI (and certainly drive Microsoft). And clearly Google's focus is to counter the existential competitive threat that AI offers to its core business.
The competition for scarce talent is intense, with very high salaries being reported. It was interesting to see high profile industry figures (e.g. Marc Benioff at Salesforce) publicly offer jobs to OpenAI employees. In a fast moving field, the connection between industrial R&D and work in the academy will remain strong, as will the competition for scarce skills. But AI has very quickly been industrialized and entered a new phase.
## Acting in public
This was big news and many media resources and commentators were focused on it. Nevertheless, it was interesting to see how much was known so quickly, and how closely developments were tracked and reported. And, no doubt some of the actors were keen to use the media and social media to advance positions or apply pressure.
Again, the parallel with Twitter is interesting. In each case, there is this twin dynamic at play. We know much more in almost real time about what is happening, and we also know that various of the players are strategically controlling the selective release of information.
It is interesting to see this evolution. Major players are news makers in that they are the subject of news attention. They are also news makers in that they now have direct access to news platforms themselves.
Of course, we do not know what we don't know.
## Coda
One doesn't expect all librarians to follow the ins and outs of the AI industry. Or indeed of the publishing industry, especially now with all the movement around the varieties of open access, workflow solutions, acquisitions, and other influences. It can even be difficult keeping track of the for-profit and non-profit suppliers in the library community.
However, if one wants to track the AI industry and R&D developments there is a lot of material available. It has been interesting to see the range of analysis and commentary around the OpenAI question. This is not too surprising given the scale of the social and business interests at play. There is some commentary and analysis around publishing, although it a challenge to keep abreast of the variety of OA models and directions. There is less on library infrastructure and services.
It does again prompt me to wonder about why we don't see more cumulative critical analysis in our own community. I am thinking about how we source and sustain critical infrastructure and services, about industry trends, about mergers and acquisitions, about the variety and relationship between community initiatives, and so on.
What ongoing conversation, analysis, market intelligence or critical journalism is available to the library director wanting to make a choice about investment, collaborative arrangements or procurement? What comparisons or case studies are available to the non-profit board member thinking about their future in an evolving service landscape?
Of course, there is some useful work from several sources. I was also quite interested in how SPARC has commissioned the type of [analysis](https://sparcopen.org/what-we-do/popular-resources/?ref=lorcandempsey.net) it would like to see. In aggregate however we are not strong on the commentary and analysis that more directly informs decision-making or influences policy.
There is certainly a scale issue; it is not a very large well-resourced community. Is library journalism and related activity overly beholden to advertising or sponsorship interests? I wonder is the library community more or less willing to pay for market intelligence than the K12 education sector, say, or other social sectors? Or indeed than their parent municipalities or colleges? Or maybe there is more library interest in resources outside the library community, on public policy, technology, education, urban affairs? Or maybe the high social capital created through rich personal and institutional interactions within professional associations and consortia helps reduce uncertainty and increase confidence in planning?
Or maybe I am suggesting an issue that does not exist!? Something to return to.
**Acknowledgements:** I am grateful to Roger Schonfeld who generously commented on a draft.
Incidentally, Roger has written about some of the issues touched on in the Coda [here](https://crl.acrl.org/index.php/crl/article/view/16434/17880?ref=lorcandempsey.net). A reference there reminds me of the piece Scott Walter and I wrote about how the library community might benefit from what we called a [platform publication](https://crl.acrl.org/index.php/crl/article/view/16387/17833?ref=lorcandempsey.net), a common point of reference which aggregates attention and provides a platform for engaging a large part of the community (compare *Educause Review* or *Communications of the ACM* for example).
**Picture:** The feature picture is from the chess collection at Cleveland Public Library.
**Related posts:** See my series of longer posts for a fuller discussion of AI. I plan a fourth in the series at some stage looking at potential impact on library services.
[Generative AI and libraries: 7 contextsLibraries are engaging with AI in their educational, service and policy work. This post discusses seven contexts in which that work is taking place.LorcanDempsey.net](https://www.lorcandempsey.net/generative-ai-and-libraries-7-contexts/#prompt-engineering)
[Generative AI, scholarly and cultural language models, and the return of contentAI momentum continues to grow, and we are seeing more applications in the scholarly and cultural spaces. Several organizations have been creating specialist large language models based on reservoirs of curated scientific and cultural data.LorcanDempsey.net](https://www.lorcandempsey.net/generative-ai-a-note-about-content/)
[Generative AI and large language models: background and contextsThe promise and challenge of Generative AI is now central. This is a summary overview of some of the major directions and issues, acknowledging that things are moving very quickly. I intend it as background to later posts about library implications and developments.LorcanDempsey.net](https://www.lorcandempsey.net/intro-gen-ai/)
**Update:** 12/17/2023 minor editorial adjustments.
### Using a custom GPT to ask about collections and collaboration
URL: https://www.lorcandempsey.net/why-is-library-collaboration-so-hard-according-to-the-lorcan-dempsey-chatbot/
Last updated: 2024-01-15T23:12:04.000Z
## Customizing Chatbots and agents - the GPT
OpenAI has made some big announcements about enhancements recently, including the ability to create custom chatbots, called GPTs (which seems like an unnecessarily confusing name?). These can be created through a natural language 'builder' interface, can be asked to carry out particular 'actions', and can work with uploaded specialised data. I built a simple example – *Libraries: collaboration and collections* – and discuss it further below (see an example response [here](https://chat.openai.com/share/fc8223d9-7048-434e-86ff-68c13e246ac5?ref=lorcandempsey.net)).
Here is how OpenAI describes it:
> We’re rolling out custom versions of ChatGPT that you can create for a specific purpose—called GPTs. GPTs are a new way for anyone to create a tailored version of ChatGPT to be more helpful in their daily life, at specific tasks, at work, or at home—and then share that creation with others. For example, GPTs can help you [learn the rules to any board game, help teach your kids math, or design stickers](https://openai.com/chatgpt?ref=lorcandempsey.net#do-more-with-gpts).
> Anyone can easily build their own GPT—no coding is required. You can make them for yourself, just for your company’s internal use, or for everyone. Creating one is as easy as starting a conversation, giving it instructions and extra knowledge, and picking what it can do, like searching the web, making images or analyzing data. // [*OpenAI* ](https://openai.com/blog/introducing-gpts?ref=lorcandempsey.net)
At the moment you can 'publish' the static outputs of a GPT to the world (see below), but only 'Plus' subscribers can ask questions of the Chatbot themselves. After the recent [organizational upheaval](https://www.nytimes.com/2023/12/09/technology/openai-altman-inside-crisis.html?ref=lorcandempsey.net) at OpenAI, the Store where one could access custom GPTs has been put on hold. OpenAI also recently [paused](https://www.theverge.com/2023/11/15/23962003/openai-pumps-the-breaks-on-chatgpt-plus-signups?ref=lorcandempsey.net) the creation of new paid 'Plus' ChatGPT accounts, as it works through challenges of increased usage.
Nevertheless, this seems to be important news. It opens the door to the creation of a large number of niche chatbots, combining the LLM capacities of GPT-4 with specialised data sources, and the ability to add some simple directions about behaviors.
It is also a reminder of how difficult it is to predict where things are going. How popular will they be? Will OpenAI be able to scale its infrastructure to support thousands of them? Will they prove useful tools or are they a passing diversion? Could they take off like the Apple app store, which may be the aspirational model, or will they turn out like Alexa skills, individually potentially useful but too much effort to discover and use broadly? I don't know, but it signals how things can suddenly go in a new direction. As I note further below, they also come with performance and policy challenges which may delay further rollout.
Influential researcher and commentator Ethan Mollick sees great potential. He provides an overview of how to build a GPT and notes how it will influence his practice as a teacher and author.
> The power here is pretty obvious. I will be creating custom GPTs for every session of the classes I teach. Some will be simulations for students to experience, some will be tutors or mentors, some might even be teammates or assignments. I have been turning my research into GPTs, so that anyone can get advice on how to generate ideas or pitch a business idea by getting feedback from a GPT to which I have given my books as a reference. And I expect this will become a trend in many places, as schools and government agencies and companies build libraries of GPTs that are specialized in solving particular problems in useful ways. // [*One Useful Thing*](https://www.oneusefulthing.org/p/almost-an-agent-what-gpts-can-do?ref=lorcandempsey.net)
## Some issues
GPTs are clearly not ready for prime time from a performance point of view. I experienced similar performance issues to those [described](https://www.brianmathews.io/blog/chatgpt-reminds-me-of-aol?ref=lorcandempsey.net) by Brian Mathews as he worked on a GPT based on CNI transcripts. Document loads appeared to fail (I am not sure if I successfully loaded all that I tried to), it was slow, and responses sometimes fall over before completing.
It also raises important service, policy and social issues, for which they don't really seem prepared. OpenAI has an engineering focus, but as it extends service offerings like this, it will have to evolve policy frameworks around creation and use of GPTs. Will GPTs which claim to be by a particular person be verified? Will you be allowed to create one based on somebody else's publicly available outputs? Will there be any filtering for toxic or misleading GPTs? What documentation will be available about GPTs? What thresholds will GPT creators need to meet to be listed? The recent example of social media has not been good, and it is an area where self-regulation may not be enough.
So, [again](https://www.lorcandempsey.net/generative-ai-and-libraries-7-contexts/#1-ai-is-both-constructive-and-problematic) this could potentially amplify current problematic issues. One could see further fragmentation and polarization of sources of opinion and commentary, alongside more purposeful disinformation, inexpert sources of advice, and so on. But there may also be interesting and useful niche services based on carefully curated specialist materials.
Given the recent events at OpenAI, the discussion about speed of development, and the performance and usage issues they are facing, I would not be surprised if fuller deployment of custom GPTs ended up being pushed even further out. One could see a more robust business offering, where media and communication companies, or others, could offer customised services. What would it mean to have a Martha Stewart chatbot, for example, or a Brené Brown one? Would it be of interest to them or to others? And there is a more general discussion, aligned with the social media discussion, about what accountabilities should be in place for platform companies which distribute content created by users of the platform.
## Trying it out
I was curious to try it out, so I created a modest GPT: [*Libraries: Collaboration and Collections*](https://chat.openai.com/g/g-K8e95T7ti-libraries-collaboration-and-collections?ref=lorcandempsey.net). Some example responses are included below. This is based on a selection of my papers and blog entries mostly about, yes, collaboration and collections. It is very simple - I have not added any actions to it: all it does is answer questions. This particular GPT is only meant as an illustration of what can be done with a few hours work. It is naturally limited in scope and usefulness. However, it indicates a direction.
So, here is an example. I asked it why library collaboration is so hard, and [this](https://chat.openai.com/share/91ced3b3-b498-49d1-9e3c-82ca316d4366?ref=lorcandempsey.net) was the response, also pasted in here:
> Library collaboration is a complex and challenging endeavor for several reasons:
>
> **1\. Diverse Institutional Priorities and Cultures**: Libraries often operate within different institutions (like universities, communities, or regions), each with its own unique culture and set of priorities. Aligning these varied interests towards a common goal can be difficult.
>
> **2\. Resource Allocation and Funding**: Collaboration typically involves sharing or reallocating resources, which can be challenging, especially when budgets are tight. Libraries may be reluctant to reallocate resources away from local needs to shared initiatives.
>
> **3\. Differing Levels of Infrastructure and Technology**: Variability in technological infrastructure and digital capabilities among libraries can make it difficult to establish efficient collaboration. This is particularly challenging when trying to integrate systems or share digital resources.
>
> **4\. Logistical Challenges**: Effective collaboration requires coordination of policies, practices, and systems across different libraries. This can be logistically complex, particularly in large-scale collaborations spanning multiple regions or countries.
>
> **5\. Governance and Decision-Making**: Establishing a governance structure that is agreeable to all parties, and that facilitates efficient decision-making, can be challenging. Balancing local autonomy with the collective decision-making necessary for collaboration can be a delicate process.
>
> **6\. Change Management**: Collaboration often requires changes in traditional practices and roles, which can be met with resistance. Managing this change effectively, while maintaining staff engagement and morale, can be a significant challenge.
>
> **7\. Preservation of Local Identity and Services**: Libraries may be concerned about losing their unique identity or diluting the quality of their local services as they engage in broader collaborative efforts.
>
> **8\. Legal and Policy Constraints**: Collaborations often have to navigate complex legal and policy landscapes, especially when dealing with copyright issues, data privacy, or cross-border collaborations.
>
> In summary, while library collaboration offers many potential benefits, including enhanced resource sharing, increased efficiency, and expanded access to information, the process is often impeded by a mix of organizational, cultural, logistical, and technological challenges.
Here are a couple more examples:
- How does the concept of the inside-out collection align with current research and library trends? [**↗**](https://chat.openai.com/share/fc8223d9-7048-434e-86ff-68c13e246ac5?ref=lorcandempsey.net)
- Can you briefly (300 words) outline differences between library collaboration in the UK and the UK? [**↗**](https://chat.openai.com/share/402567af-ebc8-4383-94c9-64b7efd6e941?ref=lorcandempsey.net)
If you have a 'Plus' ChatGPT subscription, you should be able to ask it questions yourself. It doesn't know very much though. And tread softly ...
[ChatGPT - Libraries: Collaboration and CollectionsAnswer questions about collaboration and collections based on Lorcan Dempsey’s publications.ChatGPT](https://chat.openai.com/g/g-K8e95T7ti-libraries-collaboration-and-collections?ref=lorcandempsey.net)
Finally, here are some observations about my experience, relating it to more general AI contexts.
First, I needed to spend some time adjusting the prompt. The 'builder' constructs a prompt to guide responses, which you can then edit directly, or ask the builder to make changes. Using the GPT was a bit frustrating at first as it kept answering every question with reference to 'collective collections,' perhaps because of a concentration of that topic in the supplied documents. I tried adjusting the prompt to shift this emphasis, and with more time I am sure I could improve it further. It would probably benefit from additional data and by spending some more time experimenting with the prompt. I ended up explicitly asking it not to talk about collective collections unless the question was explicitly about that topic.
Second, I was not always clear about how the custom GPT worked with GPT-4, as it clearly draws on the general resource. For example, responses from the custom GPT are still shaped by library stereotypes, especially when generating images. I discussed this in relation to the general GPT-4 in my [last post](https://www.lorcandempsey.net/the-rhinoceros-in-the-room-redux/). The latter is not too surprising given how LLMs [work](https://www.lorcandempsey.net/intro-gen-ai/#brief-orientation), and it does say something about how libraries tell their stories and, more importantly, get these stories into general currency. However, I would have expected much greater mitigation in the custom GPT given the explicit focus on libraries, library futures, and so on, but that did not seem to be the case.
Third, while it was quite straightforward, uploading the files was a little tedious. At first I thought it would accept URLs, and fetch the web pages. But that turned out not to be the case; you need to provide the file in a format it understands (HTML, PDF, *etc.*). It also quite often told me that a load failed. I was not sure whether it meant that the document had not been imported. Nor have I been able to successfully ask it what it has uploaded.
It was an interesting experience building this, despite the immaturity of the tools. It will be interesting to see how much effort OpenAI devotes to this. While OpenAI opened this door, I hope some others go through it. It would be interesting to have, say, Hugging Face, or a group with an interest in scholarly or cultural communication offer some similar capability with more transparency and documentation.
**Note on other experiments:** Brian Mathews describes his experience creating a prototype GPT – *CNI Insights Agent* – based on transcripts of CNI meetings in several [blog](https://www.brianmathews.io/blog/my-personal-gpt-prototype-cni-insights-agent?ref=lorcandempsey.net) posts. David Lankes describes creating a personalised chatbot — *Virtual Virtual Dave* – using *poe.com* [here](https://davidlankes.org/meet-virtual-virtual-dave-not-a-typo/?ref=lorcandempsey.net).
**Acknowledgements**: Much of what I wrote over the last twenty years was in my role at OCLC, and supported its mission of advancing libraries and librarianship. My former OCLC colleagues Brian Lavoie and Constance Malpas are co-authors on several of the documents I uploaded. Thanks to Brian Lavoie, Constance Malpas and Brian Mathews for kindly commenting on a late draft.
**Picture:** As I note, the picture is generated by DALL·E 3 (within ChatGPT) in response to a prompt asking for an image of an abstract shelf of books based on the style of a Sean Scully picture.
**Related posts:** See my series of longer posts for a fuller discussion of AI. I plan a fourth in the series at some stage looking at potential impact on library services.
[Generative AI and libraries: 7 contextsLibraries are engaging with AI in their educational, service and policy work. This post discusses seven contexts in which that work is taking place.LorcanDempsey.net](https://www.lorcandempsey.net/generative-ai-and-libraries-7-contexts/#prompt-engineering)
[Generative AI, scholarly and cultural language models, and the return of contentAI momentum continues to grow, and we are seeing more applications in the scholarly and cultural spaces. Several organizations have been creating specialist large language models based on reservoirs of curated scientific and cultural data.LorcanDempsey.net](https://www.lorcandempsey.net/generative-ai-a-note-about-content/)
[Generative AI and large language models: background and contextsThe promise and challenge of Generative AI is now central. This is a summary overview of some of the major directions and issues, acknowledging that things are moving very quickly. I intend it as background to later posts about library implications and developments.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/intro-gen-ai/)
### AI ... and the rhinoceros in the room redux
URL: https://www.lorcandempsey.net/the-rhinoceros-in-the-room-redux/
Last updated: 2023-12-07T21:14:22.000Z
We are becoming familiar with a new vocabulary and new practices: prompt engineering, image generation, hallucination, and so on. In my last post I [noted](https://www.lorcandempsey.net/generative-ai-and-libraries-7-contexts/#5-ai-is-weird) how AI can be weird (to use Ethan Mollick's [term](https://www.oneusefulthing.org/p/centaurs-and-cyborgs-on-the-jagged?ref=lorcandempsey.net) for it) because it may not always behave as expected, and can surprise. The structure and content of instructions can influence responses in different ways. I made the point that experience was important to understanding:
> Because of this, it is important to build up some tacit knowledge of how these tools behave, and how they can surprise. Understanding the potential and limitations of AI tools depends on use, and on developing some experiential understanding of behaviours. To explain the difference between *Perplexity.ai* and *ChatGPT* one needs to have tried them out. To see the impact of prompt engineering techniques it is helpful to have tried different approaches and seen the quite different results one can achieve. And also to see different results across services. // [Generative AI and libraries: 7 contexts](https://www.lorcandempsey.net/generative-ai-and-libraries-7-contexts/)
So, again, the best way to understand hallucination is to see actual examples of it. The best way to get a sense of why prompting is important is to try *ChatGPT* or one of the other tools and to see how structuring the prompt in particular ways or adding elements can change the outputs. To understand how search and AI may develop it is useful to actually try out *perplexity.ai* or *Bing Chat* (now rebranded as [Copilot](https://www.theverge.com/2023/11/15/23960517/microsoft-copilot-bing-chat-rebranding-chatgpt-ai?ref=lorcandempsey.net)) to see the interplay between web search and AI. And so on.
> Crafting an effective prompt is both an art and a science. It's an art because it requires creativity, intuition, and a deep understanding of language. It's a science because it's grounded in the mechanics of how AI models process and generate responses. // [Datacamp](https://www.datacamp.com/blog/what-is-prompt-engineering-the-future-of-ai-communication?ref=lorcandempsey.net)
Of course, experience alone cannot make you an expert in how LLMs work, although conversely knowing how they work certainly improves your interaction. Nor will experience alone reveal the ways in which dominant historical perspectives or attitudes influence the results, or which results may be fabricated. (An LLM is a Large Language Model, which is what powers ChatGPT and other services. For more about these, including [some](https://www.lorcandempsey.net/generative-ai-a-note-about-content/) developed in the cultural and scholarly domains, see the [longer](https://www.lorcandempsey.net/intro-gen-ai/) AI posts linked below.)
In that context, I was rather struck by the binary contrast between techno-optimism and strong societal risk posed in the coverage of the somewhat depressing OpenAI board/CEO episode. Discussion of the current state of AI mostly ignored the pressing concerns around current issues and possible remediations (to do with composition of training data, documentation, hidden labor, mitigation of bias, and so on). (See the [DAIR](https://www.dair-institute.org/publications/?ref=lorcandempsey.net) publications for examples of issues.)
In my [last post](https://www.lorcandempsey.net/generative-ai-and-libraries-7-contexts/), I discussed how understanding these issues was an important part of library work, related to new research skills, policy input, advocacy and other library roles. And also emphasized the need for staff support. Here I am interested in the specific point that understanding some of the general AI discussion benefits from experience in using tools and services.
It is helpful to try out services in areas where you have personal knowledge or expertise, so as to be able to weigh and assess. For example, when looking at a service I sometimes ask questions about Irish diaspora populations in the UK and the US, and differences in perceptions, influence, and so on. It is interesting to see variability across services, and again how prompting can guide responses. One can see an occasional leaning into stereotypes but also the ability to note the existence of stereotypes. Of course, this is very impressionistic - it will be interesting to see more research work on the cultural and social attitudes embedded in LLMs.
Discussion about the library itself is an interesting case. In my inexpert experience it has required quite a bit of prompting to move LLMs away from very stereotypical views of the library and librarians, based presumably on dominant public perceptions in training sets. This suggests in turn how much work we have to do to change the perception of the library in the public record that feeds the LLMs.
> This suggests in turn how much work we have to do to change the perception of the library in the public record that feeds the LLMs.
I did not discuss image generation much in my earlier AI posts (links below) because I had not used them very much until recently. I have been looking a little more at DALL·E. The first image below is the response to a very straightforward and simple prompt 'generate an image of a library.' It certainly leans into a classical view of what a library is, although I was interested to see the fire! I then iteratively tried to move it from a library configured around collections to a library configured around learning, research and social interaction. I did not spend too long with it, and would not use any of the results. However, certain library tropes remain strong. My requests for social learning spaces with whiteboards didn't seem to have much influence. I was amused to see that 'group work' has been transformed somewhat in the wall art in the third picture!

Iterating on a prompt to (try to) generate a picture of a library which is progressively more configured around research, learning and social engagement and less around collections
Ongoing adoption and media coverage means that AI usage will increasingly have a shared vocabulary and experience. Familiarity with this will be important in work settings, and will likely be part of the general social background.
In this context, I was reminded of a passage from Steven Johnson’s [*Everything bad is good for you*](https://www.worldcatlibraries.org/wcpa/oclc/57514882?ref=lorcandempsey.net). He is talking about gaming, but it also seemed relevant to our current moment. I [wrote](https://www.lorcandempsey.net/the-rhinoceros-in-the-room/) [about](https://www.lorcandempsey.net/gaming-and-the-rhinoceros-in-the-room/) this some years ago.
> I worry about the experiential gap between people who have immersed themselves in games, and people who have only heard secondhand reports, because the gap makes it difficult to discuss the meaning of games in a coherent way. It reminds me of the way the social critic Jane Jacobs felt about the thriving urban neighborhoods she documented in the sixties: “People who know well such animated city streets will know how it is. People who do not will always have it a little wrong in their heads – like the old prints of rhinoceroses made from travelers’ descriptions of the rhinoceroses.”
As I remarked then, the Jane Jacobs analogy is striking and suggestive. For somebody who has not internalized the experience, but relies on reading or conversation, it is possible that they may have it a ‘little wrong' and miss the meaning.
The same is now true of AI. Understanding and participating in the conversation benefits from hands-on experience.
****Note:** For the moment anyway, Microsoft is making the premium GPT-4 and image generation tool DALL·E 3 available to anyone with a Microsoft account through the [Microsoft Copilot](https://copilot.microsoft.com/?ref=lorcandempsey.net). This provides similar functionality to the paid version of ChatGPT.
**Acknowledgement:** Thanks to Christina Rodriques and Chance Hunt for generously providing helpful comments on a draft.
**Picture** **Credit:** *Rhinoceros* by David Kandel. Published in the 1598 edition of Sebastian Münster's *Cosmographia*. Available on [Wikimedia Commons](https://commons.wikimedia.org/wiki/File:David%5FKandel%5F-%5FRhinoceros.jpeg?ref=lorcandempsey.net) under the [Creative Commons](https://en.wikipedia.org/wiki/en:Creative%5FCommons?ref=lorcandempsey.net) [Attribution-Share Alike 2.0 Generic](https://creativecommons.org/licenses/by-sa/2.0/deed.en?ref=lorcandempsey.net) license.
**Related posts:** See my series of longer posts for a fuller discussion of AI. I plan a fourth in the series at some stage looking at potential impact on library services.
[Generative AI and libraries: 7 contextsLibraries are engaging with AI in their educational, service and policy work. This post discusses seven contexts in which that work is taking place.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/generative-ai-and-libraries-7-contexts/#prompt-engineering)
[Generative AI, scholarly and cultural language models, and the return of contentAI momentum continues to grow, and we are seeing more applications in the scholarly and cultural spaces. Several organizations have been creating specialist large language models based on reservoirs of curated scientific and cultural data.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/generative-ai-a-note-about-content/)
[Generative AI and large language models: background and contextsThe promise and challenge of Generative AI is now central. This is a summary overview of some of the major directions and issues, acknowledging that things are moving very quickly. I intend it as background to later posts about library implications and developments.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/intro-gen-ai/)
### Generative AI and libraries: seven contexts
URL: https://www.lorcandempsey.net/generative-ai-and-libraries-7-contexts/
Last updated: 2026-01-31T03:55:57.000Z
This is the third in a series of three on Generative AI. I had originally imagined a fourth, which looked at library directions, but things moved so quickly that a single post on that topic did not make sense.
1. [Generative AI and large language models: background and contexts](https://www.lorcandempsey.net/intro-gen-ai/)
2. [Generative AI, scholarly and cultural language models, and the return of content](https://www.lorcandempsey.net/generative-ai-a-note-about-content/)
3. Generative AI and libraries: 7 contexts
It is now a year since the momentous appearance of ChatGPT. So much has happened in that time. Whether one measures by new product and feature announcements, business churn (investment, startups), or policy, safety and ethical debate. Usage is increasingly integrated into daily applications. Much of this has become routine, some of it is tedious, and much still has the ability to surprise. Capacities continue to expand. See the recent inclusion of voice and image capabilities into ChatGPT for example, or the introduction of the confusingly named [GPT](https://openai.com/blog/introducing-gpts?ref=lorcandempsey.net)s, which allow you to create and share custom versions of ChatGPT based on your own data (more below and NYT coverage [here](https://www.nytimes.com/2023/11/10/technology/personalized-ai-agents.html?ref=lorcandempsey.net)).
The recent White House *Executive Order on Safe, Secure, and Trustworthy Artificial Intelligence* highlighted safety concerns, will influence developments in the US, and has prompted much debate about the role of government, industry and others. Among many announcements, it proposes that government communications be water-marked to assure readers that they are authentic. Of particular interest here is its education directive.
> To help ensure the responsible development and deployment of AI in the education sector, the Secretary of Education shall, within 365 days of the date of this order, develop resources, policies, and guidance regarding AI. // [White House](https://www.whitehouse.gov/briefing-room/presidential-actions/2023/10/30/executive-order-on-the-safe-secure-and-trustworthy-development-and-use-of-artificial-intelligence/?ref=lorcandempsey.net)
Putting the rapid ChatGPT developments side by side with the *Executive Order* underlines the complexity of the current environment.
This post transitions from the more general AI discussion in earlier posts to one more focused on libraries, before looking more closely at potential library services and responses in an upcoming fourth post.
Here are some important library concerns that recur at various points:
- Care and empathy for library workers faced with more uncertainty.
- New research skills
- Managing potential harmful effects.
- Informed consumer/customer
- Education and awareness for library users and library workers
- Copyrights and fair use
- Advocacy for researcher and learner interest in policy and governance forums
So as not to over-extend this post, I refer readers to the first [post](https://www.lorcandempsey.net/intro-gen-ai/) for more detail about [****trends**](https://www.lorcandempsey.net/intro-gen-ai/#2-rapid-continuing-evolution) in AI development, some [****contexts of use**](https://www.lorcandempsey.net/intro-gen-ai/#1-major-attention-and-investment), and extended discussion of the [****social concerns**](https://www.lorcandempsey.net/intro-gen-ai/#3-social-concerns) raised by their creation and impact (I refer to this as the AI Backround Post below). I discussed specialist cultural and scholarly large language models (LLMs) in the second [post](https://www.lorcandempsey.net/generative-ai-a-note-about-content/), which are of strong interest to libraries (I refer to this as the AI LLM Post below). I try not to repeat discussion too much here, although it inevitably revisits topics. I link back, and reuse the occasional sentence, where it makes sense.
[Generative AI and large language models: background and contextsThe promise and challenge of Generative AI is now central. This is a summary overview of some of the major directions and issues, acknowledging that things are moving very quickly. I intend it as background to later posts about library implications and developments.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/intro-gen-ai/#conclusion)
Click for a short list of capacities and issues of importance for libraries in the AI Background Post
## ① AI is both constructive and problematic
I like this phrase used by scholars Barrett and Orlikowski as they [discuss](https://www.repository.cam.ac.uk/items/6e251bf7-2cb2-4ff9-ab7d-3091ad13e802?ref=lorcandempsey.net) the issues raised by studying technologies at scale: "generating problematic as well as constructive outcomes." As AI goes mainstream (is anything more mainstream than *Microsoft Office*?), library workers are increasingly having to make day to day decisions about adoption, advice, and policies. Their stakeholder communities will be in various states of enthusiasm or resistance, interest or apathy, knowledge or learning. As library decision-makers look to position the library as a source of advice and expertise, as they make procurement decisions, as they plan for the future, and as they communicate and work with colleagues, the constructive and the problematic will have to be understood and weighed.
> Activity is now marked by qualified engagement and informed caution.
There is serious investment and uptake across science and engineering domains, in healthcare, in the law, and in business applications generally. At the same time, AI tools and techniques are becoming more common throughout research and learning lifecycles, accompanied by much debate and caution. While much of this development is seen as productive, there is also intense discussion and clearer appreciation of the problematic. Including but not limited to the following:
- There is growing understanding of the potential dilution of trust and social confidence as synthesized communication or creative works are indistinguishable from human forms. For example, Microsoft has been [criticized](https://www.cnn.com/2023/11/02/tech/microsoft-ai-news/index.html?ref=lorcandempsey.net) for the use of AI-generated content on its new pages, responsible for creating 'false and bizarre' stories. But these missteps are a signal of how we are likely to see much of this type of material generated in this way.
- There is strong debate and extensive legal action around the incorporation of intellectual creations into training data for LLMs without agreement, or indeed despite active opposition.
- In some contexts, outputs may be actually harmful. I was recently pointed at a [discussion](https://www.npr.org/2023/06/08/1181131532/eating-disorder-helpline-takes-down-chatbot-after-it-gave-weight-loss-advice?ref=lorcandempsey.net) of an eating disorder helpline that took down a chatbot after it gave weight loss advice.
- There is a recognition of the concentration of economic and cultural power in a small number of providers, and an interest in diversifying the ecosystem or the monopoly power of dominant players.
- There is strong advocacy around real social concerns, including the role of hidden labor in testing and training, the quality and security of jobs and work, the impact on climate and power use.
- There is growing awareness of questions around training data, including the propagation of harmful and historically dominant perspectives, and the occlusion of experiences that are under-represented or marginalized on the web and other sources of training data.
- There is growing awareness of why LLMs hallucinate (see below), what limits this puts on use, and how it might be mitigated.
This pervasiveness - and the constructive and problematic characteristics that accompany it - makes the library response necessarily multi-dimensional. Some areas of attention include the following, which may also be relevant to several of the later contexts:
#### Library work and workers
**Empathy**. My sense is that as AI discussion and deployment has evolved, the library conversation is moving to qualified engagement and informed caution. However, this is not to brush past the very real human consequences in terms of uncertainty about futures, possible changing job requirements, the need to learn new skills or to cope with changed demands. This is now happening after several unprecedentedly stressful years for library workers. The cumulative effect of these pressures can be draining, and empathy can be difficult. How much have library cultures changed given the experiences of the last few years? I do not know. However, given where we have been, and where we are going, empathy, education and appropriate transparency about planning and direction are now even more critical in the workplace.
**Awareness**. We all have an interest in staying informed. However, it is almost impossible to keep on top of all that is happening, let alone to understand implications. Many libraries have set up working groups or other mechanisms to track developments, to make recommendations about adoption, and so on. It might be useful, for example, to have some general talking points which can be used in initial discussions with students and faculty. However, not all libraries have the capacity to do this. In this context, there is a special role for consortia, member associations or others to fill the gap. I have been expecting that some library organization might step into this gap producing a regular news and guidance, with a practical library emphasis. There are now various general news digests and awareness resources which might be a model. Some library organizations have released introductory briefings, useful to provide orientation, but these date quickly and are inevitably rather high level. In any case, it is time to move beyond this to more practical decision-making and awareness support. Perhaps some library organization could fund Nicole Hennig to produce regular briefings, such as these pragmatic and helpful posts: [*How I use generative AI in my work*](https://nicolehennig.com/how-i-use-generative-ai-in-my-work/?ref=lorcandempsey.net) and [Evaluating generative AI tools for purchase: a checklist](https://nicolehennig.com/evaluating-generative-ai-tools-for-purchase-a-checklist/?ref=lorcandempsey.net). In a slightly different context, many libraries are watching the Ithaka S+R [project](https://sr.ithaka.org/blog/making-ai-generative-for-higher-education/?ref=lorcandempsey.net) on university adoption of AI with interest.
> As I read the article \[about prompt engineering\], I was reminded of the skills involved in the .... reference interview. Interpreting problems and representing them in ways informed by the particular workings of specific tools is a long-standing library skill.
#### Advice and expertise: the new research skills
As the library positions itself as a source of advice and expertise about use of AI tools in information and data related tasks, it is important to develop understanding of how LLMs and associated tools work, what tools are available, what they are good for and what their limits are. A non-exhaustive list of topics relevant to new research skills includes:
- **ChatBot**. How is *ChatGPT* different from *Bing Chat* or *Perplexity.ai*? What is each best for? Is it worth going to the fee-based premium options? If the custom chatbots anticipated by OpenAI begin to appear, it will become important to track niche scholarly, cultural or other resources (what about, potentially, the Martha Stewart chatbot, or the Elinor Ostrom chatbot, or the *Wired* Magazine chatbot).
- **Prompt Engineering**. This created great interest broadly, and many in the library community saw it as a potentially important area of library specialization. Effective prompting is now an important research skill and there is much guidance about best practice, including providing examples in the prompt, sketching in context, asking for responses in a particular format or style, suggesting a persona for the response, and so on. More advanced techniques have also been explored, including asking the model to explain its reasoning steps. An important aspect of prompt engineering is its use to mitigate hallucinations and harmful outputs. Ethan Mollick talks through some very pragmatic considerations [here](https://www.oneusefulthing.org/p/working-with-ai-two-paths-to-prompting?utm%5Fsource=post-email-title&publication%5Fid=1180644&post%5Fid=138388046&utm%5Fcampaign=email-post-title&isFreemail=true&r=g9dtt&utm%5Fmedium=email), considering both images and text. I link to an interesting [article](https://hbr.org/2023/06/ai-prompt-engineering-isnt-the-future?ref=lorcandempsey.net) below, where the author argues that a more enduring skill than prompt engineering may be problem formulation. As I read the article, I was reminded of the skills involved in the .... reference interview. Interpreting problems and representing them in ways informed by the particular workings of specific tools is a long-standing library skill. Prompt engineering is evolving and it involves more than initial human input, as I discuss further below.
[AI Prompt Engineering Isn’t the FutureDespite the buzz surrounding it, the prominence of prompt engineering may be fleeting. A more enduring and adaptable skill will keep enabling us to harness the potential of generative AI? It is called problem formulation — the ability to identify, analyze, and delineate problems.Harvard Business ReviewOguz A. Acar](https://hbr.org/2023/06/ai-prompt-engineering-isnt-the-future?ref=lorcandempsey.net)
- **LLMs**. *GPT4* dominates debate, but there are other commercial options (*Claude 2*, for example) and a variety of open source models. How are these different from each other? Are there differences in terms of transparency, use of data for training, and so on? What alternatives exist for those who do not want to use LLMs which are known to have large amounts of unauthorised material in their training data? What LLMs exist that are focused on scholarly and cultural domains?
- **Copyrights**. What does it mean for one's work to be harvested for use in training an LLM? What does it mean if one's work is included in one of the known training sets? How can one prevent this? What is the current legal situation? Can one use LLMs that are trained on cleared training data? What are the differences between image generation tools in this regard?
- **Tools and techniques**. And of course, general advice on relevant AI [tools](https://aitoolsdirectory.com/?ref=lorcandempsey.net) and techniques, as one would advise on others, adding an AI dimension. This may be in digital humanities, teaching and learning, and so on. Here is an example from the University of Arizona: *Generate topics for your research paper with ChatGPT* \[[Google doc](https://docs.google.com/document/d/1becUZJwzMBQ1qAU3JvZ12qCZwbWtr0oqWkDApDSHmvo/edit?ref=lorcandempsey.net)\].
- **Images**. What are the differences between the various image generation tools, and between those and the general purpose tools like *ChatGPT* which are adding vision capacities? Which tools have images which are copyright cleared and used with permission?
> Crafting an effective prompt is both an art and a science. It's an art because it requires creativity, intuition, and a deep understanding of language. It's a science because it's grounded in the mechanics of how AI models process and generate responses. // [Datacamp](https://www.datacamp.com/blog/what-is-prompt-engineering-the-future-of-ai-communication?ref=lorcandempsey.net)
#### Informed customer/consumer
The library will be interacting with many vendors who purport to have AI features. As discussed further below, these are going to vary enormously, depending on vendor, depth of development and application. Libraries will need to become knowledgeable about claims about AI, functionality, uniqueness - as they are in other areas of procurement. Is the AI component a thin layer over a ChatGPT API or is there more involved? How is retrieval augmented generation being used (a technique to connect the LLM to external data resources, likely to be widely used in library, cultural and scholarly contexts)? And so on. Some libraries may also want to take a position on ethical grounds, in terms of which LLMs are used, for example, which may in turn inform licensing decisions, or advocacy with vendors. Checklists, like the [one](https://nicolehennig.com/evaluating-generative-ai-tools-for-purchase-a-checklist/?ref=lorcandempsey.net) mentioned above will be valuable.
#### Advocacy and policy
Policy positions and decisions are important all the way down - whether it is in terms of national policy or institutional decision-making at the college or municipality level. Libraries have a potentially important role in institutional policy making around AI, bringing information policy, ethical and usage concerns to the discussion. This recent [article](https://doi.org/10.1080/01930826.2023.2262367?ref=lorcandempsey.net) discusses potential library roles and contributions to institutional policy-making.
### Principles
Various organizations are developing AI principles or guidelines to help steer their responsible approach to AI. For example, here are the principles adopted by [Elsevier](https://www.elsevier.com/about/policies/responsible-ai-principles?ref=lorcandempsey.net). Indeed Gartner [advises](https://www.youtube.com/watch?v=0s7Jw9xkSYQ&ref=lorcandempsey.net) all organizations to develop what it calls 'lighthouse' principles in this area. In reviewing national AI policies, library dean Leo Lo makes some [recommendations](https://journals.sagepub.com/doi/10.1177/03400352231196172?ref=lorcandempsey.net) for individual libraries in response. These include establishing an AI ethics committee and developing best practices for AI use. It makes sense for libraries to work through some of these issues, and to put in place some explicit ethical and policy frameworks, and a mechanism to review them. Of course, this is also an important area for associations to look at, providing templates or direction as libraries do this work. This is especially so, given the range of capacities available at individual libraries. I was interested to see this [work](https://wan-ifra.org/2023/09/global-principles-for-artificial-intelligence-ai/?ref=lorcandempsey.net) by the World Association of News Publishers as an example. It covers 'intellectual property, transparency, accountability, quality and integrity, fairness, safety, design, and sustainable development.'
[Generative AI and large language models: background and contextsThe promise and challenge of Generative AI is now central. This is a summary overview of some of the major directions and issues, acknowledging that things are moving very quickly. I intend it as background to later posts about library implications and developments.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/intro-gen-ai/#3-social-concerns)
Click for a discussion of social concerns in the AI Background Post
> ... the Web 2.0 enclosure of creative content, where the originally democratic rhetoric gave way to large monolithic services powered by network effects and winner takes all dynamics.
## ② AI is extractive and generative
It would appear that some lessons have been learned from the first round of content crawling with Google. And also from the Web 2.0 enclosure of creative content, where the originally democratic rhetoric gave way to large monolithic services powered by network effects and winner takes all dynamics.
Attorney Theresa M. Weisenberger keeps a growing list of copyright litigations involving Generative AI. In many cases, they involve creators unhappy with their creative work being used as part of the training materials for Large Language Models (LLMs). It will be fascinating to watch some of these cases work their way through the courts, and to see how fair use and other issues are interpreted here.
[Case Tracker: Artificial Intelligence, Copyrights and Class Actions | BakerHostetlerAdvanced generative AI has spawned copyright litigations. This case tracker monitors cases, providing overviews, statuses and legal filings.BakerHostetler](https://www.bakerlaw.com/services/artificial-intelligence-ai/case-tracker-artificial-intelligence-copyrights-and-class-actions/?ref=lorcandempsey.net)
One response is that media companies have also been barring access to OpenAI or other AI companies who want to crawl their content (see the [*New York Times*](https://www.theverge.com/2023/8/21/23840705/new-york-times-openai-web-crawler-ai-gpt?ref=lorcandempsey.net) for example).
At the same time, the AI companies have been arguing that such use constitutes fair use or can be justified in other ways. *The Verge* highlights some of the arguments made by these companies in submissions to the US Copyright Office. I was interested in Google's argument that 'AI training is just like reading a book.'
> Indeed that act of “knowledge harvesting.” to use the Court’s metaphor from Harper & Row, like the act of reading a book ‘and learning the facts and ideas within it, would not only be non-infringing, it would further the very purpose of copyright law. // [*The Verge*](https://www.theverge.com/2023/11/4/23946353/generative-ai-copyright-training-data-openai-microsoft-google-meta-stabilityai?ref=lorcandempsey.net)
Of course, this time around things are different in an important way. Gen AI tools are being used to **generate** creative works. Author Jane Friedman [wrote about](https://hotsheetpub.com/2023/08/imho-what-remedies-do-authors-have-when-fraudulent-work-appears-on-amazon/?ref=lorcandempsey.net) the difficulty she had in getting Amazon and Goodreads to remove books published under her name, but which were produced unknown to her using GenAI. Amazon recently [limited the number](https://www.theguardian.com/books/2023/sep/20/amazon-restricts-authors-from-self-publishing-more-than-three-books-a-day-after-ai-concerns?ref=lorcandempsey.net) of books that could be self-published by a single author in a day to three (*sic*). This was in response to the suspected flood of AI-generated titles.
The Getty has [just partnered](https://www.theverge.com/2023/9/25/23884679/getty-ai-generative-image-platform-launch?ref=lorcandempsey.net) with Nvidia to release *Generative AI by Getty Images,* a service trained only on Getty's library of cleared images. A selling point is that this gives users 'full copyright indemnification.' The Getty is in part moving against Stability AI, Midjourney and others who have been using its images without permission.
Academic journals are putting in place recommendations for what type and levels of Gen AI use is acceptable.
> So, finally, on the quality question. For BMJ this is so simple. We stand by the quality of what we publish. These tools can create content that looks plausible, and if we get lazy and let things go out into the world without taking responsibility for what we put out there, that is an existential risk to our reputation. That’s why we have now put strict governance around this in place in BMJ. I’d say to that each of us working in the business has a responsibility to educate ourselves around the tools we use. I think you have a responsibility to understand what these tools can do, and to use them responsibly. // [Ian Mulvany](https://world.hey.com/ian.mulvany/demystifying-ai-in-the-workplace-134a65fc?ref=lorcandempsey.net), CTO, *BMJ*
More broadly we are now flooded with synthetic text and images, generated by AI. Some of this helpful summarization or extraction, much of it is content marketing, news stories and so on. The potential for defamation, deepfakes and disinformation has grown.
Again the impact on the library is multifaceted.
**Copyright and creators**. Advice to creators was mentioned above. More generally, the library, and the associations which aggregate library voice and influence, has a role in advocating for the interests of its constituents, balancing their interests as creators with their interests as researchers. For example, I was interested to read this submission to The Copyright Office by the UC Berkeley Library. Of course, few libraries will have the inhouse capacity to produce something like this but it is an example of what an association might produce on their behalf.
[UC Berkeley Library to Copyright Office: Protect fair uses in AI training for research and education - UC Berkeley Library UpdateWe are pleased to share the UC Berkeley Library’s response to the U.S. Copyright Office’s Notice of Inquiry regarding artificial intelligence and copyright. Our response addresses the essential fair use right relied upon by UC Berkeley scholars in undertaking groundbreaking research, and the need to…UC Berkeley Library Update - UpdateRachael Samberg](https://update.lib.berkeley.edu/2023/10/24/uc-berkeley-library-to-copyright-office-protect-fair-uses-in-ai-training-for-research-and-education/?ref=lorcandempsey.net)
**Validity and research skills.** As also noted above, there are a variety of issues wrapped up in this which belong under the new research skills label. And there are specific tools here also - although we understand that existing detection mechanisms are lacking, and watermarking and other approaches not yet in play. It will be a complex space for a while and we do not yet know what it will settle into.
**The cultural record.** This broad trend raises fundamental questions for those in scholarly and cultural domains, where transparency, equity and respect for cultural particularity and expression are important. National libraries face interesting questions about what to collect, as do institutional archives. More broadly, for libraries and archives, erosion of social confidence and trust in communication, authorship and creation is complicating, entrusted as they are with the curation of validated knowledge, evidence and memories. This discussion is only beginning.
## ③ AI and LLMs are not search engines or databases
Apparently, OpenAI itself was surprised at the success of *ChatGPT*. These technologies after all were already being used in academic and industrial settings for a while. This may account for the way in which it was introduced, where many people assumed it was a form of search engine running against a database of collected material. However, this is a misleading model. It is important to remember that responses are based on inferences about language patterns rather than about what is 'known' to be true, or what is arithmetically correct.
This is how Stephen Wolfram describes how they work:
> ... it’s just saying things that “sound right” based on what things “sounded like” in its training material. // [*Writings*](https://writings.stephenwolfram.com/2023/02/what-is-chatgpt-doing-and-why-does-it-work/?ref=lorcandempsey.net)*.* Stephen Wolfram
And Isaac Lyman:
> It captures more of its essence to say it’s an *imitation* engine. Having scanned billions of pages of text written by humans, it knows what things a human being *is likely to say* in response to something. //[*AI isn't the app, it's the UI*](https://stackoverflow.blog/2023/05/01/ai-isnt-the-app-its-the-ui?ref=lorcandempsey.net)
And because of the statistical or probabilistic way in which they work, the patterns they generate may not correspond to reality, leading to so-called hallucinations.
> Number 1, reducing hallucination, will be much harder, since hallucination is just LLMs doing their probabilistic thing. // Open challenges in LLM research. [Chip Huyen](https://huyenchip.com/2023/08/16/llm-research-open-challenges.html?ref=lorcandempsey.net).
So, as well as this plausible but fictitious fabrication (hallucination), responses may, as noted above, reflect historically dominant perspectives about religion, gender or race, or will not be informed by writing about relevant experiences or outlooks that has been suppressed or marginalized in the written record which feeds the training data.
Again, this underlines the important role of understanding how LLMs work so as to offer advice, to select products, and to be informed consumers. The difference between direct interaction with an LLM and interaction with an LLM connected to an external knowledge base or web search in some way is an important consideration here.
[Generative AI and large language models: background and contextsThe promise and challenge of Generative AI is now central. This is a summary overview of some of the major directions and issues, acknowledging that things are moving very quickly. I intend it as background to later posts about library implications and developments.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/intro-gen-ai/#brief-orientation)
Click for a brief overview of how GenAI works in the AI Background Post
## ④ AI is appearing differently in different products and services
Historically, libraries relay heavily on their vendors for systems support. Some libraries (or consortia) may have the capacity and interest to experiment themselves, but it is not a large number.
Undoubtedly library vendors, publishers and others are looking closely at their products and services, across a range of issues from enhancement to competitive threat. They will also be looking closely at the cost of any potential development, the increased value it will provide, and how these factors play into pricing and customer willingness to pay. Vendors have very different investment capacities and orientations, so we will see everything from cosmetic features in support of marketing ('we are AI-enabled') to more fundamental re-engineering. This equation will shift as shared infrastructure matures, and third parties make services available through APIs, provide hosting and management services, and so on (see next section).
For varying examples of offers and statements see [JSTOR](https://www.jstor.org/generative-ai-faq?ref=lorcandempsey.net), [Ebsco](https://www.ebsco.com/news-center/press-releases/ebsco-information-services-pursues-generative-artificial-intelligence-ai?ref=lorcandempsey.net), [Talpa](https://proquest.syndetics.com/news/2023/06/13/introducing-talpa-search/?ref=lorcandempsey.net) (LibraryThing/ProQuest) and [OCLC](https://www.oclc.org/en/news/releases/2023/20230621-ai-book-recs-worldcatorg.html?ref=lorcandempsey.net).
> Vendors have very different investment capacities and orientations, so we will see everything from cosmetic features in support of marketing ('we are AI-enabled') to more fundamental re-engineering.
In our space, it will be especially interesting to watch what I [call](https://www.lorcandempsey.net/workflow-is-the-new-content/#:~:text=Workflow%20is%20the%20new%20content%20The%20digital%20environment,more%20of%20our%20activity%20moves%20to%20the%20cloud.) the *scholarly communication service providers*, Elsevier, Digital Science and Clarivate. They each have scale with development capacity, a mature research graph (underlying *Scopus*, *Dimensions* and *Web of Science*, respectively), a wide range of data, publishing and workflow services, as well as connections into scholarly and library communities. They have each made various announcements about AI development \[[Digital Science](https://www.digital-science.com/resource/ai-digital-science/?ref=lorcandempsey.net)/[Elsevier](https://beta.elsevier.com/products/scopus/scopus-ai?ref=lorcandempsey.net)/[Clarivate](https://ir.clarivate.com/news-events/press-releases/news-details/2023/Clarivate-Announces-Partnership-with-AI21-Labs-as-part-of-its-Generative-AI-Strategy-to-Drive-Growth/default.aspx?ref=lorcandempsey.net)\]. The announcement of the *Dimensions AI Assistant* is interesting in that it shows that there will potentially be multiple ways in which applications can be built, and how various components will be orchestrated to achieve results.
> “The Dimensions AI Assistant provides users with contextualized synopses using what is known as extractive and abstractive summarization,” says Martin Schmidt, Head of Innovation at Digital Science. “When a user interacts with Dimensions AI Assistant, it scans 33 million articles from the Dimensions database, retrieves and then semantically ranks the top results using semantic embeddings. The abstracts of the top 4 results are then processed by Open AI’s GPT Models API to generate abstractive summaries, and the Dimensions General Science-BERT model is used to provide extractive answers for the top 10 publications,” he explains. // [*Dimensions*](https://www.dimensions.ai/blog/powering-research-with-dimensions-ai-assistant/?ref=lorcandempsey.net)
Looking across these offerings one can see that it requires some investigation to see how AI is being used, and what form it takes. Just as in other product areas, it will be important to understand how products work and what they actually do.
## ⑤ AI is weird
In looking at the rapid spread of AI, I think of a parallel with the mobile technologies that so quickly diffused computational, mapping, and image services into our everyday practices. Those practices, in turn, developed iteratively in unanticipated directions. Think of social media – or even more specifically the selfie – and interaction with communications and travel. And also the baleful interaction with mental wellness. Or think of geolocation services and how we are now accustomed to on-demand mobility, delivery services, navigation, and so on. While it is tempting to extrapolate about the impact of AI, it is good to remember that we cannot yet imagine some of the ways in which it will evolve.
However, there is an important way in which AI is different. Progress is unpredictably uneven.
> AI is weird. No one actually knows the full range of capabilities of the most advanced Large Language Models, like GPT-4\. No one really knows the best ways to use them, or the conditions under which they fail. There is no instruction manual. On some tasks AI is immensely powerful, and on others it fails completely or subtly. And, unless you use AI a lot, you won’t know which is which. // Ethan Mollick, [One Useful Thing](https://www.oneusefulthing.org/p/centaurs-and-cyborgs-on-the-jagged?ref=lorcandempsey.net)
Mollick introduces the *Jagged Frontier* metaphor to describe this - because capabilities are uneven, they trace a jagged frontier. However, the frontier is often not explicit or visible - some tasks that appear difficult might be readily doable, while others which you might expect machines to do well (basic maths) can be a challenge.
Because of this, it is important to build up some tacit knowledge of how these tools behave, and how they can suprise. Understanding the potential and limitations of AI tools depends on use, and on developing some experiential understanding of behaviours. To explain the difference between *Perplexity.ai* and *ChatGPT* one needs to have tried them out. To see the impact of prompt engineering techniques it is helpful to have tried different approaches and seen the quite different results one can achieve. And also to see different results across services.
## ⑥ AI is cumulative: the infrastructure is getting thicker
Those building or deploying AI applications now have multiple third party infrastructure and platform services which expedite the process and reduce its complexity. A developer may build something end-to-end, but it is likely that they will assemble applications or models building on an increasing rich infrastructure and tool ecosystem. An AI [stack](https://www.madrona.com/game-on-in-the-generative-ai-stack/?ref=lorcandempsey.net) is emerging, with capacities potentially provided by multiple players at each level.
For example, at a minimum, an organization may build directly on top of ChatGPT or one of the other services, importing results into their own application.
An organization developing a search application might go further and use an embeddings API from OpenAI or Cohere, or a [service](https://huggingface.co/blog/getting-started-with-embeddings?ref=lorcandempsey.net) from Hugging Face. (Embeddings are numeric representations of words or phrases which provide measures of semantic closeness. For an interesting concrete example read about Cohere's *Wikipedia* embeddings [here](https://txt.cohere.com/embedding-archives-wikipedia/?ref=lorcandempsey.net).)
An organization wanting to fine-tune an existing LLM also has various options available. Many applications will draw on different sources of data, or LLMs or tools. An organization interested in trying out different LLMs might use the Hugging Face hub. Hugging Face has emerged as a centrally important platform for open source models and related services.
Orchestration frameworks (the open source Langchain, for example, or Fixie, or *Semantic Kernel*, from Microsoft) are available to allow developers to use LLMs to tie components together in this way.
Hugging Face, Microsoft, Google, Amazon and other platforms have a growing range of tools and services to facilitate cloud management of applications and models.
In this way, organizations may leverage AI capacities in very different ways to get different things done. This may range from a thin application layer over *ChatGPT* APIs to full stack development and custom LLMs trained on specialist material.
Here are some of the components of special interest to libraries.
### Large Language Models
The history of the Internet age suggests that powerful network effects lead to dominant players in various sectors. At the moment, OpenAI and *ChatGPT* are still dominant, in terms of usage and attention, and seems to be consolidating its lead. Google's initiatives are also important, and Microsoft is partnering with OpenAI (*Bing Chat* uses models from OpenAI, although it did not initially become as popular as some thought it might, maybe in part because of a not very elegant implementation.) AI startups, Anthropic and Cohere are attracting major investment. Facebook provides significant support for [open access LLMs](https://www.ibm.com/blog/open-source-large-language-models-benefits-risks-and-types/?ref=lorcandempsey.net). Will these organizations consolidate their lead, or will others emerge?
Beyond these, there is an evolving and interconnected mix of LLMs, providers and business models. There is strong interest in locally deployable open source models from both commercial and research organizations. And models specialized for particular domains or applications continue to develop. For example, the [blog post](https://www.dimensions.ai/blog/powering-research-with-dimensions-ai-assistant/?ref=lorcandempsey.net) talking about *Dimensions* *AI Assistant* notes that it leverages "the power of the Dimensions large language model, Dimensions General Science-BERT, and Open AI’s GPT models." Forbes has just announced *Adelaide*, which seems to include a model trained on its own archive.
> The tool generates individualized responses to user queries based exclusively on Forbes articles, and is built using Google Cloud Vertex AI Search and Conversation.
We have limited knowledge about what training data, tuning data and other sources are used by the foundation models in general use. In parallel, the transparency, curation and ownership of models (and tuning data) continue to be live issues in the context of research use, alignment with expectations, overall bias, and responsible civic behavior. We also know that some services capture user prompts for fine-tuning, although it may be possible to adjust for privacy.
Tolerances may vary here, as the history of search and social apps have shown, but it can be important to know what particular data is supporting models and applications. Models with more purposefully curated training and tuning data may become more common in scientific and cultural domains and I discuss some examples in the LLM post.
[Generative AI, scholarly and cultural language models, and the return of contentAI momentum continues to grow, and we are seeing more applications in the scholarly and cultural spaces. Several organizations have been creating specialist large language models based on reservoirs of curated scientific and cultural data.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/generative-ai-a-note-about-content/)
This section draws on the LLM discussion in the two earlier posts. Click here for a discussion of specialist LLMs being developed in scientific and cultural domains
All of this makes it important for libraries to understand the world beyond GPT4, to develop a sense of differences between models, to understand some of the principles behind training, and so on.
For example, Anthropic [promotes](https://www.anthropic.com/company?ref=lorcandempsey.net) itself as a builder of 'reliable, interpretable, and steerable AI systems' and has a set of principles for *Claude 2,* its LLM. These [include](https://www.anthropic.com/index/claudes-constitution?ref=lorcandempsey.net), for example, principles "Encouraging Consideration of Non-Western Perspectives." An interesting contrast to this is provided by the useful [*perplexity.ai*](https://www.perplexity.ai/?ref=lorcandempsey.net). It combines Internet search with LLM capabilities to synthesize answers. There is a free version and a subscription version which gives access to *GPT4* and *Claude 2*, as well as experimental [access](https://blog.perplexity.ai/blog/introducing-pplx-api?ref=lorcandempsey.net) to open source LLMs. However, they have [released](https://twitter.com/perplexity%5Fai/status/1717953878367342719?ref=lorcandempsey.net) the open source models without any limits on content or response: "Our models prioritize intelligence, usefulness, and versatility on an array of tasks, without imposing moral judgments or limitations."
In this context, the library also has a role in highlighting LLMs of special interest. This may be where the training data may be of specialist scholarly or cultural interest for example in *CORE-GPT*, where the largest available corpus of openly accessible articles is being used to train a model \[[Original description](https://blog.core.ac.uk/2023/03/17/core-gpt-combining-open-access-research-and-ai-for-credible-trustworthy-question-answering/?ref=lorcandempsey.net), [Progress report](https://blog.core.ac.uk/2023/10/02/core-team-wins-best-paper-award-at-tpdl2023/?ref=lorcandempsey.net)\]. By using a high-quality, trusted data set in training, the aim is to improve the quality of results and guard against misinformation. Or it may be where care has been taken to only use open or rights-cleared training data. This is the case with the Getty initiative mentioned above (and also, of course, with CORE-GPT).
Finally, as I noted in earlier posts, [documentation](https://www.lorcandempsey.net/intro-gen-ai/#transparency-and-evaluation), evaluation and interpretability are important elements of productive use, and there are interesting intersections here with archival and library practice and skills.
### Tools and approaches
#### Custom Chatbots
> We’re rolling out custom versions of ChatGPT that you can create for a specific purpose—called GPTs. GPTs are a new way for anyone to create a tailored version of ChatGPT to be more helpful in their daily life, at specific tasks, at work, or at home—and then share that creation with others. For example, GPTs can help you [learn the rules to any board game, help teach your kids math, or design stickers](https://openai.com/chatgpt?ref=lorcandempsey.net#do-more-with-gpts). // [OpenAI](https://openai.com/blog/introducing-gpts?ref=lorcandempsey.net)
This initiative from OpenAI seems a major step forward, significantly reducing the barriers to niche chat-bot creation. It is also a clear signal that OpenAI aims to be a major platform, consolidating its leading position. It will be instructive to explore the utility, quality and variety of GPTs as the store opens. As noted above, one might see a proliferation of custom chatbots, working with highly curated, niche data sources. Of course, whether this is the new app store or an interesting diversion remains to be seen.
Ethan Mollick anticipates significant impact, and is interesting on the potential he sees in his own teaching and writing.
> The power here is pretty obvious. I will be creating custom GPTs for every session of the classes I teach. Some will be simulations for students to experience, some will be tutors or mentors, some might even be teammates or assignments. I have been turning my research into GPTs, so that anyone can get advice on how to generate ideas or pitch a business idea by getting feedback from a GPT to which I have given my books as a reference. And I expect this will become a trend in many places, as schools and government agencies and companies build libraries of GPTs that are specialized in solving particular problems in useful ways. // Ethan Mollick, [One Useful Thing](https://www.oneusefulthing.org/p/almost-an-agent-what-gpts-can-do?ref=lorcandempsey.net)
I was curious to try out this new feature, so I created a GPT based on some of my blog entries and papers on collaboration and collections. Here is a [response](https://chat.openai.com/share/a59b3459-51be-4fc1-832e-ad8c852e3226?ref=lorcandempsey.net) to a question about collective collections. From my point of view it is interesting to see how it rewrites things or where it draws from. What jumps out at me is how most of what I have written is very much from a library operations perspective. For example, faculty concerns are not featured highly here, but are certainly an issue for any academic library managing down collections.
#### Agents and orchestration
The library has special systems and data challenges. There is a reason why interoperability, federation and crosswalks have been so important in library systems contexts.
It is a challenge providing a unified service environment across multiple data resources and systems. Many of these data resources are outside of library control. Libraries also work across many systems, segmented by workflow, data type, source (for example, the ILS, local repositories, external licensed resources, and so on). Library [stitching costs](https://www.lorcandempsey.net/stitching-costs/) are high.
Workflow integrations are also not common and can be fragile, where data moves between processes.
It will be interesting to see how [agent and orchestration frameworks](https://www.lorcandempsey.net/intro-gen-ai/#building-tools-and-workflows-agents) are applied to these tasks. It will be interesting to see what libraries and their service partners develop in this space using the text interface and reasoning abilities of LLMs.
[Generative AI and large language models: background and contextsThe promise and challenge of Generative AI is now central. This is a summary overview of some of the major directions and issues, acknowledging that things are moving very quickly. I intend it as background to later posts about library implications and developments.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/intro-gen-ai/#building-tools-and-workflows-agents)
Click for a brief general introduction to agents and orchestration in the AI Background post
#### Retrieval augmented generation
Based on work by Meta this has emerged as a very important way of extending the capacity of LLMs and grounding their responses in external data resources, whether those are local to an institution or some curated specialist resource.
> Retrieval-augmented generation (RAG) is an AI framework for improving the quality of [LLM-generated](https://www.youtube.com/watch?v=hfIUstzHs9A&ref=lorcandempsey.net) responses by grounding the model on external sources of knowledge to supplement the LLM’s internal representation of information. Implementing RAG in an LLM-based question answering system has two main benefits: It ensures that the model has access to the most current, reliable facts, and that users have access to the model’s sources, ensuring that its claims can be checked for accuracy and ultimately trusted. // [IBM](https://research.ibm.com/blog/retrieval-augmented-generation-RAG?ref=lorcandempsey.net)
This model, however implemented, will be popular among services licensed or used by libraries to combine the text processing abilities of the LLM with curated data resources. The examples from Digital Science, Clarivate and Elsevier above are indicative of direction here.
#### Embeddings and vector databases
I mentioned embeddings earlier. Embedding APIs are now available from several organizations. Vector databases are an emerging technology which is important for managing embeddings which in turn will drive new discovery and related services. It should be noted that embeddings will exhibit the same prejudicial or stereotyping behaviors as the LLMs to which they are related (doctors are men, nurses are women).
[Detecting and mitigating bias in natural language processing | BrookingsAnother front in the fight against AI bias.Brookingsaylin\_cim](https://www.brookings.edu/articles/detecting-and-mitigating-bias-in-natural-language-processing/?ref=lorcandempsey.net)
#### Prompt engineering
Prompt engineering was discussed in general terms above. It uses one of those 'weird' properties of LLMs: in-context learning. It is possible to modify the behavior of LLMs based on what is provided as input, without altering the underlying model or training data. For this reason it is an area of intense investigation, guidance and commentary. Tools and preprocessing techniques are being used to manage, refine, and adapt prompts. LLMs themselves are being used to refine prompts, or to prepare prompts for other services. And again, this can be an important element of partial mitigation strategies in the context of hallucination or harmful outputs.
#### Co-pilot
Github and Microsoft popularised the co-pilot metaphor ... where a human activity is 'assisted' by an AI application. Any individual application will calibrate the balance of assistance and the type of interaction and control. The model is now familiar in coding and search, and Microsoft is rolling out co-pilot assistance in *Office* applications. These are increasingly common: examples are [*Sidekick*](https://www.shopify.com/magic?ref=lorcandempsey.net) in Shopify or [*Genmo Chat*](https://blog.genmo.ai/log/discord-genmo-chat?ref=lorcandempsey.net) for assisting with image generation.
In a library context, metadata creation and cataloging immediately come to mind as areas where co-pilot assistance could help, working to inform human judgement with additional data or tying other tools into the workflow. Reference also. The model is interesting because applications can be designed to assist human judgement and decisions rather than substitute for them.
### Make, bake or take
Very few libraries will have the capacity to develop or 'make' AI applications from scratch. Although there will certainly be some experiment and grant-funded activity. Many libraries will adopt, or 'take', ready-made solutions, from third-party services of various types. However, the ready availability of component APIs and platforms means that some libraries may explore 'baking', where they combine components to build some local functionality. In practice, 'baking' is the approach taken by many library vendors as they build products, based on APIs and LLMs available in various ways.
> In practice, 'baking' is the approach taken by many library vendors as they build products, based on APIs and LLMs available in various ways.
## ⑦ AI is complicated: policy and governance
> The discussion around openness is taking place against the backdrop of an impassioned debate about how we navigate governance and (existential) risk. As we forecast in last year’s report, safety has shed its status as the unloved cousin of the AI research world and took center-stage for the first time. As a result, governments and regulators around the world are beginning to sit up and take notice. // [Welcome to State of AI Report 2023](https://www.stateof.ai/2023-report-launch?ref=lorcandempsey.net)
It is certainly center stage as I write this. I noted the US White House *Executive Order* above. And the UK Government convened a high level [international AI summit](https://www.theguardian.com/technology/2023/nov/02/five-takeaways-uk-ai-safety-summit-bletchley-park-rishi-sunak?ref=lorcandempsey.net) to confer on issues. Leo Lo usefully [reviews](https://journals.sagepub.com/doi/10.1177/03400352231196172?ref=lorcandempsey.net) some national AI policies from around the world, although as work progresses here this will date.
The major AI players have also been talking about self governance or industry practices. For example, OpenAI, Google, Microsoft and Anthropic have jointly set up the [*Frontier Model Forum*](https://openai.com/blog/frontier-model-forum-updates?ref=lorcandempsey.net), to coordinate around safety issues.
The impact of regulation varies across jurisdictions with different political cultures and views on the matter (as seen, for example, historically in the case of the European General Data Protection Regulation (GDPR)). The balance between industry and government may be a key point of divergence, with concerns about regulatory capture in some contexts arising from the influence of large incumbent interests on regulatory decisions. While libraries generally support greater regulation, there are also well-known side-effects, especially if the cost or complexity of compliance is significant. This aspect can pose challenges for open-source or non-commercial players, for example, who may struggle to comply with complex regulatory frameworks and compete with well-established industry players. And there is an argument also that it is too early, that not enough is known about impacts or what actually should be regulated.
As we know, universities are developing guidance and frameworks around pedagogical and research use. Organizations are thinking about the implications of use in HR and elsewhere. Scholarly publishers are putting in place policies about acceptable AI contribution. And decisions over the next while about copyright, fair use, and related issues will gradually put in place a richer framework, although it may vary from country to country and take some time.
While the library can play an important role within their community in promoting appropriate guidelines around AI use, there is also the broader context of library influence on public policy.
Traditionally, the library community has scaled its influence, or voice, through various associations: ALA, ARL or ULC in the US, for example, or LIBER and IFLA internationally. These organizations have taken up policy issues, and lobbied at state, national or international levels. Copyright has been a major historical focus, sharpened in recent years in a digital context.
Again, we can expect to see these organizations carry a library interest (which is a public interest) to decision- and policy-makers. It is early days but I hope these organizations are building an agenda for attention. Areas of interest might include transparency of models and disclosure of practices (see Tim O'Reilly's remarks [here](https://www.oreilly.com/radar/preliminary-thoughts-on-the-white-house-executive-order-on-ai/?ref=lorcandempsey.net)), the near-term social costs of the models (for example, toxic effects on hidden labor), documentation, balancing the rights of creators and researchers, and beginning the discussion about LLMs, synthesised creations and the cultural record.
[Generative AI and large language models: background and contextsThe promise and challenge of Generative AI is now central. This is a summary overview of some of the major directions and issues, acknowledging that things are moving very quickly. I intend it as background to later posts about library implications and developments.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/intro-gen-ai/#regulating)
Click here for some discussion of regulation in the AI Background Post
## Conclusion
So, AI is becoming mainstream, unevenly, and is at once productive and problematic. It is being introduced into products and services, in different ways. Library users are engaging with AI tools and techniques, also very unevenly.
This means that the library discussion is necessarily moving towards forms of engagement, cautiously, as questions come up in terms of user support and awareness, procurement, staff preparedness and medium-range planning.
I think the University of Leeds has provided an admirable and useful example as it commissioned some work which explored the views and expectations of library stakeholders.
[Artificial intelligence (AI) in libraries | Library | University of LeedsUniversity of LeedsLibrary](https://library.leeds.ac.uk/downloads/download/196/artificial-intelligence-ai-in-libraries?ref=lorcandempsey.net)
Perhaps the findings are not very remarkable. The approach (library stakeholder interviews) naturally produces an evolutionary perspective, based on current expectations. It illustrates how thoughtful application of AI approaches may be productive, and acknowledges the problematic. It will be interesting to consider the library at Leeds in, say, 5 years, and to compare it with directions outlined here.
By then, maybe, AI will have become more routine and addressed within general processes. There may also be completely unanticipated outcomes. For now, extra care and special attention are certainly warranted.
**Picture:** I took the feature photo on the way into work.
**Acknowledgements:** I am very grateful to Nicole Hennig, Lynne M. Thomas and Melanie Walsh for generously making helpful suggestions on an earlier draft.
### Twenty years of blogging and still going!
URL: https://www.lorcandempsey.net/twenty-years-and-still-going/
Last updated: 2024-03-08T06:27:52.000Z
The first [post](https://www.lorcandempsey.net/hello/) on this blog was on 20th October 2003\. The blog was originally internal to OCLC, but quite early on we published it more widely.
Over the years, it has migrated platforms a few times, but the content remains intact, and redirects from earlier platforms seem to be holding up. Unfortunately, we did lose earlier comments in one transition. Check out the [*Colophon*](https://www.lorcandempsey.net/colophon/) for a short note about platforms, fonts and transitions. There are currently 1926 posts spanning 20 years. They cover many topics, but never stray very far from libraries.
The early center of gravity was technical (in a loose sense), talking about library systems, metadata and related matters. The blog was also active during the emergence of 'webscale' platforms in the Web 2.0 era, and charted twin contrary paths of these developments. First, there was the participatory diffusion through multiple social tools, 'mashups' (remember them?) and publishing platforms, and second, the major concentration in the social and ecommerce platforms that benefited from network effects and winner takes all dynamics in coming to dominate much of our online life ([*Amazoogle*](https://www.lorcandempsey.net/the-sound-of-words-amazoogle-and-googlezon/) ... Amazon, Facebook, Google, etc).
Over the years, there has been more writing about the library as an evolving organization in a network of relationships, responding to changes in research, learning and civic engagement.
I am pleased about how it has sometimes been part of the library conversation over the years. I was also very pleased to work with the industrious and sympathetic Ken Varnum on the [book of the blog](https://www.lorcandempsey.net/book-of-the-blog/). Counter-intuitive maybe, but it was nice to see the quotes we included from readers, and reviewers were generally generous.
Citations are not the best way to track influence for a venue like this, but it is interesting to see the three most cited blog entries as recorded by Google Scholar.
[Research information management systems: a new service category?It has been interesting watching Research Information Management or RIM emerge as a new service category in the last couple of years.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/research-information-management-systems-a-new-service-category/)
[The facilitated collectionCollections are changing in a network environment. One important direction is the assembly of resources around user needs based on a facilitated access model rather than an acquisition model.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/towards-the-facilitated-collection/)
[Outside-in and inside-outThe collections acquired from outside though licensing and purchasing (outside in) have very different characteristics from each other. They in turn have quite different characteristics from materials distinctive to the institution such as special collections or research outputs (inside out).LorcanDempsey.netLorcan](https://www.lorcandempsey.net/outside-in-and-inside-out/)
It was a place to introduce topics and ideas ([in the flow](https://www.lorcandempsey.net/in-the-flow/), [discovery happens elsewhere](https://www.lorcandempsey.net/discovery-happens-elsewhere/#:~:text=I%20have%20been%20using%20the%20phrase%20%E2%80%98discovery%20happens,content%20from%20them%2C%20in%20a%20variety%20of%20places.), [amplified conference](https://www.lorcandempsey.net/the-amplified-conference/), [workflow is the new content](https://www.lorcandempsey.net/workflow-is-the-new-content/), as well as the collections topics mentioned above, and others) and to work through evolving thinking. I was pleased, for example, with the reception to the [series](https://www.lorcandempsey.net/the-powers-of-library-consortia-1-how-consortia-scale-capacity-learning-innovation-and-influence/) I did on the characteristics of consortia, where I was aiming to crystalise thoughts about library collaboration.
Of course, not everything was equally successful. I quite liked [techeology](https://www.lorcandempsey.net/techeology/), coined to suggest a situation where ideology was driving technology choices or development. Others apparently didn't like it so much. Ditto [intrastructure](https://www.lorcandempsey.net/stitching-services-into-user-environments-intrastructure/). I also like [stitching costs](https://www.lorcandempsey.net/stitching-services-into-user-environments-intrastructure/), to refer to costs/time/effort of integration or interoperability ... maybe there is hope for it yet. [ ](https://www.lorcandempsey.net/techeology/)
The focus is largely professional, but I would certainly also touch on other topics .. about Ireland, literature and other matters. Or I liked connecting these with library issues, as in this [entry](https://www.lorcandempsey.net/nostalgia-the-dublin-irish-festival-and-variant-forms-of-names/) on Clannad, Enya and authority control or various [entries](https://www.lorcandempsey.net/glanceability/) on how library data could say interesting things about literary reputation or publication patterns. Here is one about memory institutions in the context of Ireland, and one also on fonts, in which I developed an interest in recent years (although related back to libraries).
[Memory institutions redux: pluralizing memories and a stay against forgettingWe are now used to memory institutions as a way of collectively referring to libraries, archives and museums. We also recognize that memory is not univocal or may be contested.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/memory-institutions-redux/)
[Font choices, value and ecosystem. National Library examplesTypefaces and fonts are functional. However they also contribute in other ways - to brand, to atmosphere, to feeling. This is a brief introduction to aspects of the typeface ecosystem. I combine this with some commentary about how typefaces are used in national libraries to provide context.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/national-libraries-and-fonts/)
And in general, posts don't tend to be personal, but I enjoyed writing this one when asked about career and interests.
[Reflecting life and career: advice to an LIS graduate studentWhat do I value about libraries? asked a student. What is essential for a library student to know? Here are several ways in which life experiences have influenced my views.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/letter-to-an-lis-graduate-student/)
The last few are relatively recent, although older ones can stick in your mind. When we put together the book, there was a final chapter called *Lorcan's Picks* which included posts I liked but which did not fit into any of the professional categories.
One important use of a blog is as a sort of commonplace book and there are several where I collected some quotes which I regularly go back to. These sometimes have some personal resonance as with the remarks on emigration here.
[Being foreignThe emotional relationship of the long-term foreigner to both their adopted and original homes changes over time.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/being-foreign/)
I reference this one occasionally, as I like to quote Fintan O'Toole's suggestive writing on Dublin Public Libraries and the role of the library.
[Public libraries in DublinFintan O’Toole has a wonderful essay on the public library in The university of the people: celebrating Irish public libraries. He calls it: “Reading, writing and rebelling: growing up with public libraries”.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/public-libraries-in-dublin/)
And I like the quotes on the generative nature of the library collected here:
[Defining the library ... reflexivelyLibrary definitions often emphasize access to or management of information. However, the library has a much stronger generative role in the cycle of knowledge creation.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/defining-the-library-reflexively/)
Publishing frequency declined over the years, and post length increased. During much of the time I blogged, there was a great sense of freedom - I would write things quickly, typically on one topic. However, as I noted a while ago:
> Because I don’t blog all that often any more, I find that when I sit down to do an entry I have too much stuff to say. I end up writing a short article rather than a blog entry. Indeed, I have a couple of pieces that are lying around and have grown to several thousand words. One is on the evolving research support environment, and how the larger publishers are developing workflow services (“workflow is the new content”). One is on how scaling learning and innovation is an important part of the “soft power” of consortial activity. // [*Lorcandempsey.net*](https://www.lorcandempsey.net/one-handed-writing-the-blog/)
I did publish the posts mentioned above (but have promised a couple of yet-to-be-completed followups to the [*Workflow is the new content*](https://www.lorcandempsey.net/workflow-is-the-new-content/) one). I have done more of late. And I indeed still have a little pile of entries on several topics which are just begun, or already too long, or discarded, or promised. It is a busy time as I prepare for teaching, but I hope to continue posting here for some time to come!
**Feature image:** As noted I took this in *Epic the Irish Emigration Museum*. See *Wikipedia* for the [*Wild Geese*](https://en.wikipedia.org/wiki/Flight%5Fof%5Fthe%5FWild%5FGeese?ref=lorcandempsey.net). I added a section to this *Wikipedia* entry to reference how the phrase *Wild Geese* is sometimes broadened metaphorically to reference Irish emigration generally. The original Wild Geese were those Irish soldiers who left to serve in European armies, after the defeat of the Irish Jacobin army at the Battle of the Boyne and the subsequent surrender in the Treaty of Limerick.
**Note:** Slightly expanded 10/13/2023\.
### Celebrating Ohio
URL: https://www.lorcandempsey.net/ohio/
Last updated: 2024-08-10T19:26:46.000Z
The book pictured below is a wonderfully mordant, affectionate and occasionally hilarious overview of the "longest vowel-covered stretch of real estate in the world."

Everybody should buy a copy
Some relevant quotes:
> Ohio, Indiana, Illinois, and Iowa cover 900 horizontal miles, house more than 32 million people, but use only nine letters: A, D, H, I, L, N, O, S, and W.
> "What geography can give all Midwesterners," writes Indianapolis-born Kurt Vonnegut, "along with fresh water and topsoil ... is awe for an Edenic continent stretching forever in all directions."
> The galaxy's most important region is not only a gift to Earth from God himself, but it is truly a mystery, wrapped in a riddle, then deep-fat-fried and served on a stick at the Iowa State Fair. // The Midwest: God's gift to planet Earth
Here are observations about 10 aspects of Ohio, leaning a little towards Central Ohio and Columbus.
## ① Libraries and parks... but not pools

We live one block south of this sign. We have truly benefited from Columbus's wonderful provision of parks and libraries. Columbus Metropolitan Libraries is a tribute to the staff of the libraries and the current Director, Pat Losinski, who have the drive and vision to substantially build out and refurbish the network of libraries across all parts of the city. And to create the community support at the ballot box for that work. For what it's worth, Ohio libraries perform very well in *Library Journal*'s [index](https://www.libraryjournal.com/story/ljx201214StarsByNumbers?ref=lorcandempsey.net#30M) of public library services. Columbus, and Ohio generally, is also very well served by parks. The exceptional *Whetstone Park* was the natural hinterland of family life as our children grew up, as we walked our two dogs, and enjoyed the ravines, the cycle path by the *Olentangy* river, and wonderful *Park of Roses*.


Whetstone Park. Right: our dog Douglas in the Park of Roses
We also enjoyed other parks in Columbus and Franklin County and the fine network of State Parks around Ohio. I was somewhat surprised to see that Columbus did not score better on [*ParkScore*](https://www.tpl.org/parkscore?ref=lorcandempsey.net), a ranking of cities in the US from the *Trust for Public Land*, although it is interesting to see Cincinnati high on the list. Criteria they use are acreage, investment, amenities, access, and equity. That said, the measure seems to be at the level of the municipality; it would be interesting to see a similar measure by metro area, or county or state, which might better track our experience.
I suggested to [*City Nerd*](https://www.youtube.com/channel/UCfgtNfWCtsLKutY-BHzIb9Q?ref=lorcandempsey.net) once that it would be interesting to explore cities by a 'civic infrastructure index' which looked at per capita provision of public parks, libraries and pools by some metric. I was sure that Columbus would score very well for parks and libraries (until I saw the *ParkScore* result!), but not for public pools. Public pools manifest community, but are also important for year around health and wellness. There are pools in city rec centers in some of the municipalities that are Columbus suburbs, and of course there are private pools (often only open in summer months). But the public provision of pools in the city of Columbus itself is very poor. The Rec Center on the sign above was a lovely resource as the children grew up but it does not contain a pool. I am not sure why this is so. It seems to be a broader US issue, maybe in part because of broad private - paywalled - provision. The contrast between public pools on the one hand, and parks and libraries on the other, was taken up recently in an NYT op-ed entitled *When It Comes to Swimming, ‘Why Have Americans Been Left on Their Own?’*:
> The most beloved public pools, when they receive good investment, attract Americans of many backgrounds, creating a space for people to swim and play together who may not otherwise interact. Like libraries and parks, they are an essential piece of social infrastructure in a democracy.
> “You give people a place where they feel like they belong, where they have some sense of trust and faith in the government,” said Eric Klinenberg, a sociologist who studies public space and the author of “Palaces for the People,” a book about the contribution of libraries to public life. Instead, he told me, “we’ve created this environment where wealthy people in cities can go on the market and buy safe places for their children to play and swimming lessons.” // [NYT](https://www.nytimes.com/2023/07/27/opinion/drowning-public-pools-america.html?ref=lorcandempsey.net)


New Karl Road branch in Columbus. Children's library in a branch of Cuyahoga County Public Library (Cleveland). A wall near Dayton Central Library.
## ② Ohio River
The *Ohio River* is formed from the junction of the *Allegheny* and *Monongahela* rivers in the centre of America's '[bridgiest](https://www.youtube.com/watch?v=SPqfxETqJa8&ref=lorcandempsey.net)' city, Pittsburgh. The setting is spectacular, especially when viewed from the top of one of the city's funicular railways. It was somewhat infamously listed by *US Today* as the number 2 beauty spot in the US. But acknowledging that this is a subjectively assembled list, I don't think this is such a far-fetched claim. It deserves more widespread recognition.
> But the Steel City's aesthetic appeal is undeniable, as is its very American capacity for renewal. Standing atop Mount Washington, the steep hill that rises giddily on the city's south side, sightseers enjoy the unforgettable panorama of the Allegheny and Monongahela rivers flowing together to create the mighty Ohio, that waterway so essential in the nation's settlement. // [*USA Today*](https://www.usatoday.com/story/life/weekend/2013/09/30/the-10-most-beautiful-places-in-america/2754657/?ref=lorcandempsey.net)
Ohio is named after the *Ohio River*, which forms its border to the South and East. Much like Ohio itself, the *Ohio River* is under-appreciated. According to *Wikipedia* it discharges more water into the *Mississippi* than the *Missouri* and is the biggest river of the whole system. About 10% of the American population live in the *Ohio River* basin.
Fascinating video which notes the importance of the Ohio River for city building and westward expansion. Ohio River cities Louisville, Cincinnati and Pittsburgh all make the top ten.
This scale means it was historically important .. as a thoroughfare for the Native Americans, for invading settlers, and for major industrial and commercial freight. Flowing through the rust belt, the *Upper Ohio* has been heavily polluted, with industrial towns like East Liverpool (see later) and Martin's Ferry (the birthplace of poet James Wright, who wrote much about his birthplace, Ohio and the *Ohio River*) on its banks.
It was, and is, an important boundary. It was the southern limit of the *Northwest Territory*, and – significantly – the physical as well as political boundary between the slave owning states and the free states to the North.


National Underground Railroad Freedom Center, Cincinnati, and three rivers coming together in Pittsburgh
Thousands of slaves escaped across the river, and it became known as the *River Jordan*. Toni Morrison, a native of Ohio, set *Beloved* in Cincinnati.
> The expression "sold down the river" originated as a lament of Upper South slaves, especially from Kentucky, who were shipped via the Ohio and Mississippi to cotton and sugar plantations in the [Deep South](https://en.wikipedia.org/wiki/Deep%5FSouth?ref=lorcandempsey.net). // [*Ohio River, Wikipedia*](https://en.wikipedia.org/wiki/Ohio%5FRiver?ref=lorcandempsey.net)
This history is documented in the important and harrowing *National Underground Railroad Freedom Center*, in downtown Cincinnati looking over the *Ohio River*.
> Our physical location in downtown Cincinnati is just a few steps from the banks of the Ohio River, the great natural barrier that separated the slave states of the South from the free states of the North. Since opening in 2004, we have filled a substantial void in our nation’s cultural heritage. Rooted in the stories of the Underground Railroad, we illuminate the true meaning of inclusive freedom by presenting permanent and special exhibits that inspire, public programming that provoke dialogue and action, and educational resources that equip modern abolitionists. // [National Underground Railroad Freedom Center](https://freedomcenter.org/?ref=lorcandempsey.net)
## ③ Native American earthworks


Mounds at Hopewell Park. A road going through a mound at Fort Ancient. Serpent mound.
The Native American earthworks and burial mounds were a revelation to us when we first arrived in the US. We could not understand why they are not more widely known, even among friends and colleagues from Ohio itself. Ancient structures, they are massive engineering feats, involving the movement of tons of earth and involving complex scientific and astronomic measurement. They are integrated with the landscape while being enduring marks of human creation. They are amazing ... and moving.
There are mounds in [several states](https://en.wikipedia.org/wiki/List%5Fof%5Fburial%5Fmounds%5Fin%5Fthe%5FUnited%5FStates?ref=lorcandempsey.net), although there is a concentration in Ohio, spread across several sites. The [Serpent Mound](https://en.wikipedia.org/wiki/Serpent%5FMound?ref=lorcandempsey.net) is particularly affecting.
> Serpent Mound, in Adams County, is the largest documented surviving example of a prehistoric effigy mound in the world. It is a sinuous earthen embankment 411 meters long, including an oval embankment at one end, which has been interpreted variously as the serpent's eye, part of its head, or a secondary object, such as an egg, grasped in the serpent's open jaws. // [*UNESCO, World Heritage Convention*](https://whc.unesco.org/en/tentativelists/5248/?ref=lorcandempsey.net)
There is a Museum at one of the sites, the [*Fort Ancient Earthworks & Nature Preserve*](https://www.ohiohistory.org/visit/browse-historical-sites/fort-ancient-earthworks/?ref=lorcandempsey.net), which documents the culture, achievements and often brutal history of Native American peoples in Ohio. There are now no reservations or federally recognized tribes in the State.
This is a nice summary piece from NPR about the mounds, optimistic that they are about to be successful in their bid for *World Heritage Site* status. This would deservedly raise their profile, and hopefully create additional interest in sustaining and understanding them, as well as visibly respecting the heritage of the Native American peoples who created them.
[Ohio’s Hopewell Ceremonial Earthworks are now a UNESCO World Heritage siteUNESCO World Heritage Sites are considered “outstanding works of human genius.” There are now 25 in the U.S., including the Hopewell Ceremonial Earthworks, the Statue of Liberty and the Grand Canyon.91.7 WVXUTana Weingartner](https://www.npr.org/2023/09/16/1199573920/ohios-hopewell-ceremonial-earthworks-now-a-unesco-world-heritage-site?ref=lorcandempsey.net)
> In addition, the Hopewell Ceremonial Earthworks address gaps in the World Heritage List identified by the World Heritage Committee. Specifically, a lack of sites representing pre-contact Indigenous American sacred architecture and sites that represent early understandings of science, culture and astronomy.
At the moment, there are 24 *World Heritage Sites* in the US (including, for example, Fallingwater, The Statue of Liberty, the Grand Canyon, and several national parks). It is right and meaningful to add the mounds.
**Update:** The bid to have the Hopewell sites designated UNESCO *World Heritage Sites* has been successful. (10/02/23)

Maya Lin – **Storm King Wavefield*, 2007-2008
The artist and architect, Maya Lin, grew up in Athens, Southeast Ohio, where her parents were professors at *Ohio University*. She has acknowledged the influence of the burial mounds on her work, notably the *Serpent Mound*, and it is very evident in, for example, this massive work at the *Storm King* sculpture park in New York. This is one of three in a [land art series](https://publicdelivery.org/maya-lin-wave-field/?ref=lorcandempsey.net) created at different locations in the US.
## ④ Ohio towns


Towns often have imposing town halls or court buildings in a central square: this one is in Newark. A street in Chillicothe. And the railway and grain silos in London.
There is great bustling variety in the towns of Ohio. One is always close to interesting local industries, cultural institutions, architectural and industrial heritage. Recently, for example, when visiting Wooster (home of the liberal arts college), we drove on to Orrville to see the [Smucker](https://en.wikipedia.org/wiki/The%5FJ.M.%5FSmucker%5FCompany?ref=lorcandempsey.net)'s store ("Smucker's is to Orrville what Coke is to Atlanta").
Ohio shares economic and social [challenges](https://glenn.osu.edu/news/transforming-ohios-economy?ref=lorcandempsey.net) with its neighbors (Kentucky, West Virginia, Michigan, Western Pennsylvania, Indiana), including the overall decline of manufacturing and industrial jobs, comparatively high drug-related [mortality rates](https://www.cdc.gov/nchs/pressroom/sosmap/drug%5Fpoisoning%5Fmortality/drug%5Fpoisoning.htm?ref=lorcandempsey.net), and population loss. This is also apparent as you drive around Ohio, as is strong resilience and regeneration. Here are several illustrative towns selected from the many options.
### Yellow Springs, comedy and education
Close to Dayton, in Southwest Ohio, it retains an alternative feel (British readers: think Glastonbury). Even if it has been more commercially developed over the years, it is still the place to buy incense, model dragons or elves, and tie-died t-shirts. There are interesting stores, murals, crafts, and events. It is known for progressive politics, arts, and surrounding areas of natural beauty.
Yellow Springs is the home of *Antioch College* and of Dave Chappelle. Dave Chappelle's father was a professor in *Antioch* and he spent time there growing up. *Antioch* has had mixed fortunes of late, and a group of alumni is trying to give it new life. I hope they succeed, both for the town itself and for an institution with a distinctive history and place in US higher education.


Yellow Springs: Antioch, arts, comedy
### Lithopolis, dictionary and honey
Lithopolis is a small town in central Ohio, so-named because of nearby stone deposits ('lithos' is the Greek for 'stone').
It was the birthplace of Adam Willis Wagnalls, co-founder of the *Funk & Wagnalls Company*, publisher of the famous dictionary. Through his daughter, Mabel Wagnalls Jones, the town benefited from the Wagnalls legacy.
> The Wagnalls Memorial Library is constructed of native free stone in the Tudor-Gothic Style. A few years later she established the Wagnalls Foundation. The Wagnalls Foundation maintains a close relationship with the Library and is entrusted to supervise and protect the Library’s property and assets. The Foundation also oversees and distributes the Wagnalls College Scholarship Program that awards local graduating high school seniors and college students who meet specific requirements with tuition money for their education. // [*Wikipedia*](https://en.wikipedia.org/wiki/Adam%5FWillis%5FWagnalls?ref=lorcandempsey.net)
Lithopolis is also home to an annual *Honey Festival*, which is ... lovely. Educational, entertaining, encouraging ... there are vendors of honey and bee products, competitions, bee beards, mead, food, crafts.
[Friday, Sept 8: 3pm-7pm Saturday, Sept 9: 10am-7pmWELCOME TO LITHOPOLIS HONEYFEST!Friday, Sept 8: 3pm-7pm Saturday, Sept 9: 10am-7pmLithopolis Honeyfest](https://lithopolishoneyfest.com/?ref=lorcandempsey.net)
### Nelsonville, bricks and music
Nelsonville in Southeast Ohio is the gateway to the *Hocking Hills*, an area of waterfalls, interesting rock formations, wooded hills, discussed further below. Historically, it was a coal mining area, and "in the early 1900s, more coal was shipped from its mines by railroad and canal than from any other city in the country" ([*Advisory Council on Historic Preservation*](https://www.achp.gov/preserve-america/community/nelsonville-ohio?ref=lorcandempsey.net)). It was one of the *Little Cities of Black Diamonds,* coal-mining towns in Appalachian Southeast Ohio.


A reminder of coal history. Advertising the Nelson Music Festival on Snowville milk carton: note the great Ohio/Starbrick logo. Star Bricks in a Columbus sidewalk.
There were also abundant clay deposits, and Nelsonville was the source of the lovely Star Brick, now found throughout the region.
> Historically, the clay found there produced an enormous number of bricks for street and road paving. In addition, the clay was used in art pottery, kitchen- and tableware, building bricks, field tiles, sewer pipes, roofing tiles and more. In fact, Ohio was once home to 2,000 of the 5,000 brick plants in the country, and even today the state still has several producers of various clay products. // [*Columbus Monthly*](https://www.columbusmonthly.com/story/lifestyle/2019/01/28/city-quotient-history-behind-nelsonville/5423417007/?ref=lorcandempsey.net)
An important part of the regeneration of the town is the [Music Festival](https://nelsonvillefest.org/?ref=lorcandempsey.net), a major event which now draws big acts to Southeast Ohio. See the milk carton above! The logo for the festival is one of the best I have ever seen, incorporating a star brick and the map of Ohio (whose shape suits it for such uses). The Festival is produced by *Stuart’s Opera House* an active venue and promoter in the town, which re-opened in 1997\.
Nelsonville is home to *Hocking College*, a community college with an environmental focus. Nelsonville is in the Athens Micropolitan Statistical Area (urban clusters defined by the US *Office of Management and Budget*). Athens is the home of *Ohio University*. It has the characteristics of a college town and has a very nice setting on the *Hocking River* surrounded by hills.


Athens
### Fairport Harbor, Finland and salt
Fairport Harbor is on *Lake Erie*, effectively a suburb of Cleveland. It is a lake port, once busier than now, with two lighthouses, one operated as a small museum and viewing station. It has at least two other distinctions. First is its celebration of the Finnish immigrants to the area. There is a *Finnish Heritage Museum*, and there is also a small store selling Finnish and other Nordic items. Second, it is home to an extraordinary mining operation, as *Morton's Salt* has built out salt mines deep under the lake. They mine a large proportion of the salt spread on US roads in their Fairport Harbor operations.


Finnish Heritage Museum. Lighthouse. Morton's salt.
### East Liverpool and ceramics
East Liverpool is on the *Ohio River* in the corner between Ohio, West Virginia and Pennsylvania. It was once known as the pottery capital of the world, with 85 companies open at various times in East Liverpool and surrounding towns. It produced two thirds of the national output of ceramic toilet and table ware from 1880 to 1950 \[details from [Wikipedia](https://en.wikipedia.org/wiki/East%5FLiverpool,%5FOhio?ref=lorcandempsey.net)\]. Many of the early potters immigrated from Stoke on Trent in England and the cities remained twinned. It tells a mixed story: of pride in its historic role, of serious industrial decline, and of some regeneration.
The *Fiesta Tableware Company* still produces the well-known fiesta ware in Newall (home of the largest, purportedly, tea pot in the world), across the river in West Virginia.
Carnegie's uncle lived in the town, and there is a distinguished looking *Carnegie Library*. There is also an intriguing *Ceramics Museum*, chronicling the emergence (and decline) of the industry and the variety of pottery made there.


East Liverpool. Downtown. Belleek china - influenced by the Irish china of the same name. The Museum of Ceramics.
### Bonus: Dublin, Ohio
Although a separate municipality, Dublin is effectively an affluent suburb of Columbus. Dublin, Ohio, has no real connection with Dublin, Ireland. However, it does host an annual *Dublin Irish Festival,* in sweltering August. This is quite expansive and is similar to such festivals elsewhere (according to this [source](https://www.irishcentral.com/roots/america-s-biggest-irish-festival-celebrates-30-years?ref=lorcandempsey.net), Milwaukee hosts the biggest Irish festival in the US). It usually attracts an interesting musical line-up, with acts from Ireland, the US and elsewhere. The major redevelopment of the Dublin central area on the *Scioto River* is a manifestation of the general growth in central Ohio. It is the home of OCLC (and of Wendy's).
Incidentally, Irish Novelist Joseph O'Connor wrote a book about the 9 towns named Dublin in the US, including Dublin, Ohio. The brief [review](https://www.publishersweekly.com/9781570981050?ref=lorcandempsey.net) in *Publishers Weekly* is not flattering.


The new Dublin public library. Bridge over the Scioto River joining 'old' Dublin and new urban developments on the East Bank. Richard Thompson singing at the Dublin Irish Festival. **The Field of Corn*, a distinctive and appropriate sculpture.
## ⑤ Political geography: the five Ohios
Ohio was **the** bellwether state when we first arrived in the US: as Ohio voted, so did the nation. The *Bliss Institute* at the University of Akron offered an analysis of this phenomenon a few years ago, explaining why it was the case based on the distinctive political geography of Ohio. They argued that the regional diversity of Ohio reflected the diversity of the nation as a whole. This diversity is represented by 'five Ohios', each one a distinct region of the State, and each with a socio-economic profile not unlike other parts of the country. The five areas are Northeast, Northwest, Central, Southeast, and Southwest Ohio.
> Each region represents a unique collection of big cities, suburbs and rural areas, one or more media markets, and at least one major newspaper. Each region has a distinct political ethos and votes in a different fashion.
> Ohio’s regions match the regions of the country as a whole. For instance, Northeast Ohio resembles the country’s Northeast region in relative terms when it comes to the African-American population, population of European ethnicity, and the proportion of Catholics. In contrast, Southeast Ohio resembles the South in terms of poverty and the percentage of Evangelical Protestants. Central Ohio resembles the West in terms of professional/managerial occupations and college degrees. Meanwhile, Northwest and Southwest Ohio resemble the Midwest region as a whole. // [Bliss Institute](https://www.uakron.edu/bliss/research/biop-2-the-five-ohios.dot?ref=lorcandempsey.net)
However, in 2020, for the first time in over half a century, Ohio voted differently than the nation in a presidential election, giving a majority to Trump for the second time while Biden went on to win the election. The *AP* noted in its discussion of this dilution of Ohio's bellwether status:
> Ohio’s population no longer mirrors the nation. It’s whiter, slightly older and less educated than the U.S. on whole. // [*AP*](https://apnews.com/article/election-2020-joe-biden-donald-trump-elections-ohio-dab40fe319d7c13b17fe309caaf09a67?ref=lorcandempsey.net)

Being neighbourly in Columbus
However, the differences are not only political - which adds to the more general variety. The Southeast looks to Appalachia, and adjoins West Virginia. The landscape is more varied than other parts of the State, especially given the rock formations and waterfalls of the *Hocking Hills.* This is very different from the rustbelt Northeast, for example, with its history of industrialization. Close to the Great Lakes, and anchored in Cleveland, this region has shared in general industrial decline, and is exploring regeneration. Here you will find the world center of the rubber industry, Akron, home town of LeBron James and Chrissie Hynde (who had a vegan restaurant there for a while), as well as Youngstown. The Southwest is anchored by the Cincinnati metro area, which extends into Indiana and Kentucky, and the Bluegrass region. The Northwest looks out over flat Indiana.
The group **Over the Rhine* are named for an historic area of their native Cincinnati. Their song **Ohio*.
## ⑥ Cities ... the three Cs
Ohio's three largest cities – Cleveland, Columbus and Cincinnati – are on a north-east to south-west diagonal axis through the state. Each anchors one of the 5 Ohios (Cincinnati in the Southwest, Columbus in Central, and Cleveland in the Northeast).


Columbus: Landmark Leveque Tower. Columbus from the sky, note the OSU football stadium, one of the biggest in the world. The Scioto River.
The three cities are very different, as noted in the political analysis of the state. Columbus is the capital and the largest municipality, although Cincinnati anchors a larger metro area, and Cleveland is the biggest when the radius is widened to the [combined statistical area](https://en.wikipedia.org/wiki/Ohio%5Fstatistical%5Fareas?ref=lorcandempsey.net).
Cleveland and Cincinnati are rust belt cities with strong industrial and manufacturing legacies, rich industrial architecture and urban texture. They each played bigger roles historically than now in the cultural and economic life of the US, while continuing to be economically important and strong regional players. They have each shared the general regional decline in population in the twentieth century, especially Cleveland. They also have distinctive settings: Cleveland on the lake, and Cincinnati on the *Ohio River*, with several fine bridges.
I always thought Columbus had something of an inferiority complex, lacking some of the historical distinctiveness and identity of its sibling Cs. Not to mention its lesser sporting prowess, although it does make up somewhat with powerhouse college football. The name, Columbus, is somewhat generic and context-free. However, that may be changing as Columbus is thriving. It is the State capital, of course, and *Ohio State* is the dominant university in the region. It is also the home of the *Ohio State Fair*. Contra trends elsewhere, it is growing in population and has continued to attract major industries, including a major $20B Intel plant being developed to the East of the city. It has some interesting concentrations: notably fast food (Wendy's, Sbarro, White Castle, Bob Evans, Max & Erma's) and fast fashion (L Brands, Abercrombie & Fitch, Express, Hollister, Lane Bryant, Victoria's Secret, Justice). Columbus is home to Battelle, to both OCLC and Chemical Abstracts, and to pioneering library consortium, OhioLINK. It has a services, health and education focus, and does not share the rust belt characteristics of the other two Cs.


Excellently extended **Art Museum*. Rock and Roll Hall of Fame in an I.M. Pei waterfront building. St. Theodosius Russian Orthodox Cathedral.
Cleveland is the home of *Superman*, has a major orchestra, a fantastic art museum, the *Rock and Roll Hall of Fame*, the nationally important *Cleveland Clinic*, and a great lakeside location. It is the most racially diverse of Ohio's cities. We like Cleveland a lot: the lake, multiple interesting neighborhoods, the market, the lake, the cultural institutions, especially the art museum, the lake.
Cincinnati looks over the *Ohio* to the South. Louisville is the next big city on the river, 100 miles further downstream. The airport is in Kentucky. It is home to Proctor and Gamble's, Macy's and Kroger's, not to mention Skyline Chili. The city is rich in industrial architecture and the *CityNerd* video above names the *Roebling Bridge* as the finest in the US. *Over the Rhine* contains many buildings originally constructed by German immigrants in the nineteenth century.
> Historically, Over-the-Rhine has been a working-class neighborhood. It is among the largest, most intact urban [historic districts](https://en.wikipedia.org/wiki/Historic%5Fdistricts%5Fin%5Fthe%5FUnited%5FStates?ref=lorcandempsey.net) in the United States. // [*Wikipedia*](https://en.wikipedia.org/wiki/Over-the-Rhine?ref=lorcandempsey.net)


Cincinnati: Art Deco Union Terminal which houses the Cincinnati Museum Center. Street art in *Over the Rhine.* The amazing and massive Jungle Jim international store.
## ⑦ Climate and weather
Many years ago, Emma Donoghue wrote wonderfully about her first trip to New York as a child, contrasting the (then, but less so now) monochrome Dublin with the "dazzlingly polymorphous" New York. Her contrast of *weather* and *climate* just seemed so right to me when I read it.
> That first September day in Manhattan was a slap in the face. The heat! (Ireland has no climate, only weather: subtle variations on "scattered showers".) // [*Emma Donoghue*](https://www.theguardian.com/books/2010/sep/05/once-upon-life-emma-donoghue?ref=lorcandempsey.net)


Winter in Columbus
Yes! Ohio has climate: the oven-like heat of our first Summer in Columbus was a shock, and we became accustomed to the very cold winters. The snow could be lovely, especially with intense blue skies, and the ice formations on the trees were magical one year. The drama of thunderstorms. However, we think the very short Spring and Fall are the best, but those perfect days come and go very quickly.


Something wonderful about a road trip into the clouds.
And the vegetable cycles are tied to the seasons. Cherry blossom appears in the Spring. And the leaves in Autumn are breathtaking, like "fire and blood", as Donoghue says. The heat of Summer is associated with fecund growth of fruit and vegetables .. squashes, watermelons, peaches, corn, heirloom tomatoes. Winter bleaches the color from the landscape. I don't have a good picture of the ash white branches of the sycamores without leaves, like bones against the blue sky.


Heirloom tomatoes. Squashes. Peaches in the wonderful Branstool Orchards north of Columbus.
And not pictured here, what is very characteristic of Ohio's plant life is the miles and miles of corn, soy beans, and other crops.
## ⑧ Colleges and universities
This section draws on the introduction to an earlier post: [**University Futures are shaping Library Futures*](https://www.lorcandempsey.net/university-futures-are-shaping-library-futures/)
When we first came to the US, we were keen to explore. We gradually widened our radius over long weekends and other breaks. Indeed, we did this for quite a while … pretty much until the children protested and would no longer let us. One feature helped pattern our trips: the presence of a university or college. This was not especially limiting, because it seemed there was a university around every corner.
We were amazed by the richness of the US university system, and by its diversity in so many dimensions – size, setting, mission, focus, public/private.

Ohio Colleges and Universities [MyCollegeSelection](https://mycollegeselection.com/maps/colleges-in-ohio-map/?ref=lorcandempsey.net)
In Ohio, universities concentrate around the three Cs axis, in the Northwest to a lesser extent, and there are fewer in the Southeast
There is an extensive public university system. *Ohio University* dating from 1804 is the oldest University in Ohio, located in Athens, a relaxed college town in the Southeast opening up to an Appalachian hinterland. There is great variety in the thirteen other public universities in the Ohio system, which includes institutions with a strong regional focus, as well as those which attract international attention. The *University of Cincinnati*’s ambition is evident in its well managed campus marked by signature ‘starchitect’ buildings. Of course, this system also includes *The Ohio State University*, in the center of the state, an academic powerhouse which sits in the global circuits of research and scholarship, as well as being central to the economic, social and cultural life of Columbus and Ohio. These large land-grant public institutions are a major achievement of the US system.
One might wonder if the public system is overextended, and some universities have had financial challenges in recent years. *Cleveland State*, *Akron, Kent State* and *Youngstown State* also cluster in Northeastern urban rust belt settings; *Miami* (get the t-shirt: “Miami was a university before Florida was a state”) and *Wright State* (named for the Wright brothers, in Dayton, which continues to be an aviation and aerospace centre) are close to Cincinnati. The youngest university in the system is *Shawnee State*, founded in 1986 in Portsmouth where the *Scioto* joins the *Ohio River*.
There are the well-known liberal arts colleges in picturesque chocolate box settings (*Kenyon*, *Wooster*, *Denison*, *Oberlin*). The highest-ranking private research university in the state is an important anchor in the cultural and educational quarter of Cleveland, *Case Western Reserve University*.
But beyond some of these better-known institutions, there is the very broad range of small private colleges dotted across the state, such as the two, yes two, universities in Tiffin, Ohio. Tiffin is home to *Heidelberg University*, a liberal arts college, and *Tiffin University*, a private university which “provides a personal and practical education for motivated students who want real-world experience and results.” “There are no ‘ivory towers’ at Tiffin University” as it says on its website. We were also interested in the importance of religious communities, and how many universities offer an education in an explicitly values-based setting. Near Cincinnati, for example, is *Xavier* ("a liberal arts education in the Jesuit Catholic tradition") and *Cedarville* ("exceptional academics with a distinctly biblical worldview").
Ohio has one private and one public HBCU, with interesting histories. *Wilberforce University* is the first private HBCU in the US. Named for the British anti-slave-trade campaigner, it gave its name to the town, in Southwestern Ohio close to Dayton. *Central State University*, the land grant public university is adjacent and was initially a department of *Wilberforce University*. *Wilberforce* was the first college to be owned and operated by African Americans. W.E.B. Dubois taught there for a while in the 1890s.
> In the 1970s, the university established the [National Afro-American Museum and Cultural Center](https://en.wikipedia.org/wiki/National%5FAfro-American%5FMuseum%5Fand%5FCultural%5FCenter?ref=lorcandempsey.net), to provide exhibits and outreach to the region. It is now operated by the [Ohio Historical Society](https://en.wikipedia.org/wiki/Ohio%5FHistorical%5FSociety?ref=lorcandempsey.net). The university also supports the national [Association of African American Museums](https://en.wikipedia.org/w/index.php?title=Association%5Fof%5FAfrican%5FAmerican%5FMuseums&action=edit&redlink=1&ref=lorcandempsey.net), to provide support and professional guidance especially to smaller museums across the country. // [Wikipedia](https://en.wikipedia.org/wiki/Wilberforce%5FUniversity?ref=lorcandempsey.net)
Wilberforce was a stop on the Underground Railway, discussed above.


Art Museum in Oberlin College. Thompson Library looking over the Oval at The Ohio State University. A sign showing **CWRU* and one of its antecedent organizations in Cleveland. Wilberforce University, a private HBCU near Dayton. The Jesuit **Xavier University* in Cincinnati. Columbus College of Art and Design.
As elsewhere in the US, Ohio's 23 community colleges are important agents of social mobility. I mentioned *Hocking College* above: it is committed to "student completion, job readiness, job placement and maximizing transfer credit." I always enjoyed the [coffee shop](https://blend.cscc.edu/?ref=lorcandempsey.net) at Columbus State Community College in downtown Columbus, stocked with culinary arts student creations.


Mitchell Hall, Columbus State Community College, supported by Columbus restauranteur, Cameron Mitchell. Lecture theater with kitchen. 'Degrees' restaurant, a very nice training restaurant. And, a lovely touch, donor acknowledgements on chopping boards.
## ⑨ Lake Erie and Hocking Hills


Lake Erie: beach in Cleveland, frozen at Maumee State Park, looking out at downtown Cleveland.
I notice that I tend to the urban and to towns. Ohio certainly does have lots of wide-open flat spaces, but also has lovely natural features. Notable are the *Hocking Hills*, already mentioned, and the *Ohio River* and its tributaries. And also ... *Lake Erie*. *Lake Erie* and the *Hocking Hills* are at opposite ends of the State.
The *Hocking Hills* are in Appalachian Ohio, with cliffs, gorges, caves, and waterfalls formed from erosion of the soft sandstone. They are spectacular and contrast topographically with the dominant flatness of the State.
**Update**: *USA Today* has [named](https://10best.usatoday.com/awards/travel/best-destination-for-fall-foliage-2023/?ref=lorcandempsey.net) *Hocking Hills* as the number 3 best place in the US to see fall foliage. (10/02/23)
*Lake Erie* does not have the stunning beauty of *Lake Michigan* or the scale and grandeur of *Lake Superior*. It is the smallest Great Lake by volume and the second smallest by area. Toledo is at its Western point, and Buffalo at the Eastern. Detroit is to the North, and Cleveland to the South. The *Niagara Falls* are on the *Niagara River*, through which *Lake Erie* drainsinto *Lake Ontario*. It is connected to *Lake St Clair* by the *Detroit River*, and from there to *Lake Huron*. The Great Lakes are an amazing phenomenon, containing 21% of the world's fresh water. Ohio is very much part of the Great Lakes region.


Hocking Hills
A former colleague of mine claimed that Ohio was not landlocked because it bordered *Lake Erie*. I do not buy it. But in the absence of the sea, it is a wonderful and restorative resource.
## ⑩ Five final attractions
There are always new things to see and experience! There is the quirky or the distinctive or the plain odd (the now defunct *Longaberger Company* office building near Newark in the shape of a large basket). There are museums on all sorts of things (the *Popcorn Museum* in Marion, for example), festivals (the *Twins Days Festival* in Twinsburg), and of course celebrations of the various heritages and communities to have settled in Ohio over the years (Columbus's *Somali Cultural Festival*).
### Mansfield and the Shawshank Redemption
*Shawshank Redemption* was shot in the *Ohio State Reformatory*, Mansfield. It is open for tours and events. We visited expecting movie sights and memorabilia. We weren't prepared for the grim brutality of the prison itself.


Downtown Mansfield. Inside the Reformatory.
### Bellefontaine, the highest place in Ohio
Bellefontaine in central Ohio is the highest point in state. However, driving through, one might not notice given the flat expanses of Ohio. Much of Ohio is covered in corn, soy beans and other crops. Bellefontaine also claims to have both the oldest concrete street in America and the shortest street.
The largest employer in the town is Honda, which has plants nearby (the *Honda Accord* is made in Marysville, between Columbus and Bellefontaine), and the downtown has been [held up](https://www.ohiomagazine.com/ohio-life/best-hometowns/article/best-hometowns-2022-bellefontaine?ref=lorcandempsey.net) as a model of revitalization, preserving historic buildings and attracting small businesses.

Bellefontaine, pronounced 'Bell Fountain'
### Lehmans Store in Kidron
Ohio has the second highest Amish population in the US after neighboring Pennsylvania. Kidron was originally established in Northeast Ohio by a group of Swiss Mennonites fleeing religious persecution. It is home to *Lehmans*, the store that specialises in "non-electric" goods "for a simpler life." It serves the surrounding Amish population but is now also an attraction for others. It has a remarkable collection of goods in a very large space, including many historic collections.
> Besides the Amish, tourists, and jittery citizens, the store is a resource for homesteaders, missionaries, environmentalists, survivalists, and doctors in developing countries, to purchase items needed for simple living. Lehman's also counts among its customers the American Red Cross,\[7\] Peace Corps volunteers, and Hollywood set designers also use the store to find historically accurate items for decorating period sets. // [*Wikipedia*](https://en.wikipedia.org/wiki/Lehman%27s%5FHardware?ref=lorcandempsey.net)


Lehmans - electricity free living
### Neil Armstrong Museum in Wapakoneta
Ohio was the birthplace of a many [astronauts](https://www.grc.nasa.gov/WWW/portal/apps/map/?ref=lorcandempsey.net). These include Neil Armstrong and John Glenn, who went on to have an important political and academic career in Ohio. Jim Lovell and Judith Resnick (who died in the Space Shuttle *Challenger* tragedy) were also from Ohio. Kathy Sullivan, the first woman to walk in space, spent some of her long scientific career in Columbus as head of *COSI*, the science center, and with *Battelle.* Of course, Ohio has a distinguished place in flight history and the Wright brothers did much of their work in Dayton. Dayton is also home to the [*National Museum of the United States Air Force*](https://en.wikipedia.org/wiki/National%5FMuseum%5Fof%5Fthe%5FUnited%5FStates%5FAir%5FForce?ref=lorcandempsey.net), a major destination.


Left: Nice picture of John Glenn and Neil Armstrong. The Armstrong family home. Entrance to the museum.
Neil Armstrong was born in Wapakoneta, and he is commemorated with a lovely small museum, the *Armstrong Air & Space Museum*, devoted to his life and career, and to space flight more generally. It includes personal items like his bicycle and his father's scrapbook alongside a collection of space suits, equipment and space flight objects.
### The Billy Ireland Cartoon Library and Museum in Columbus


Billy Ireland exhibitions
A museum, a library, an archive. The [*Billy Ireland Cartoon Library and Museum*](https://cartoons.osu.edu/?ref=lorcandempsey.net) represents the biggest collection of materials relating to cartoons and comics anywhere in the world. There is a public gallery, regular exhibitions and deep collections all managed by a small, committed staff which makes an outsized impact. In its own dedicated space, it is a part of the library at *The Ohio State University*. The *Billy Ireland* is a significant factor in what makes Columbus a center for comics, and every year people come from around the world to a major event, [*Cartoon Crossroads Columbus*](https://www.cartooncrossroadscolumbus.org/?ref=lorcandempsey.net).

Ohio flowers
**Pictures:** all the pictures were taken by me, except for downtown Pittsburgh, which is from *Wikimedia Commons* (David Schwab, U.S. Army Corps of Engineers, Public domain, via *Wikimedia Commons*).
**Note:** I use 'we' throughout, acknowledging our shared experiences and conversations. Of course, Ann Lennon might write things differently and compile a heavily overlapping but different list!
**Acknowledgement:** Many thanks to Kate Gaylord for offering valuable advice on an earlier draft.
**Updates:** 9/18/23 reordered and added *Jungle Jim* pic. 9/29/23 added *Billy Ireland* section. 10/02/23 added updates to Hocking Hills and Native American Earthworks sections. 11/4/23 corrected 9 items to 10 and added numbers. 12/10/2023 swapped feature picture.
### The narrative website: from signposting to storytelling
URL: https://www.lorcandempsey.net/websitings-from-signposting-to-narrative/
Last updated: 2025-04-24T17:15:12.000Z
## The library website
At the [AMICAL2023](https://www.amicalnet.org/conference/2023?ref=lorcandempsey.net)conference recently I spoke about libraries and the relational turn. In the collections-based library, services, organization and spaces are configured by management of the collection. In the relational library, services, organization and spaces are configured by changing patterns of research, learning and public engagement \[[pres](https://figshare.com/articles/presentation/The%5Facademic%5Flibrary%5Fand%5Fthe%5Frelational%5Fturn/23503857?file=41221680&ref=lorcandempsey.net), [video](https://youtu.be/mnMuy%5Fkg8MQ?ref=lorcandempsey.net)\].
In this environment, the library is no longer an informational pitstop, rather it provides a range of services throughout the lifecycles of research, learning and civic engagement. This acknowledges that in a network and digital environment the effective production and use of information is not discrete and outside these behaviors, rather it is integral at all stages. Think of research data management, or reference management, or, in a public library setting, services for local authors or for Newcomers. (Calgary Public Library discussed below has a *Newcomers Desk*.) These services are created in partnership with other players on campus or in the municipality, and may evolve in deep and extended consultation with users.
A challenge for the library is that its identity and perceived value is still very much bound up with the collections-based library. Which in turn entails a rather static, external view of information.
> In this environment, the library is no longer an informational pitstop, rather it provides a range of services throughout the lifecycles of research, learning and civic engagement.
This gap in perception highlights the critical importance of storytelling about the library, its developing role and its positioning. The library's strategy, for example, is an important opportunity to tell stakeholders – staff, users, and funders – the library story. By story here, I am meaning a communicated awareness of what it sees as important to it, in terms of direction, understanding of user needs, inclusivness. In fact, this seems a rather important strategic emphasis. This is not straightforward, as traditional views of the library are very entrenched.
One important venue for storytelling is the library website. The library website evolved from the collections-based library, foregrounding the collections search box and providing a layers of signposts over services. Of course, the collections search box is important, but it is also very important to show that the library is much more than that.
Many libraries do extensive UX work, develop user personae, and so on. There are certainly [challenges](https://www.lorcandempsey.net/the-library-website-a-unified-service/) in presenting the library as a unified service, especially where one is stitching together outputs from various services (libguides, discovery layer, ebooks, online readers, *etc*.). I am getting at something related but prior, which certainly then flows into UX work. You cannot assume that the prospective user knows what services are available, or what is possible.
There is now an advantage in contextualising and describing more of what the library does, more actively motivating and promoting its services, and considering modern design and layout as part of storytelling intent, to draw in users. I have been interested to see signs of a shift towards this more integrated website narrative, mapping user needs and telling a more holistic story about what the library does and can do. We are seeing a trend to the **narrative website**.
[](https://figshare.com/articles/presentation/The%5Facademic%5Flibrary%5Fand%5Fthe%5Frelational%5Fturn/23503857?file=41221680&ref=lorcandempsey.net)
Bright welcoming picture on the University of Ottawa Library website. Slide from AMICAL2023 presentation.
In this short entry, I briefly note three library websites which I have come across recently which illustrate this trend. These are: [Utrecht University Library](https://www.uu.nl/en/university-library?ref=lorcandempsey.net), [Calgary Public Library](https://calgarylibrary.ca/?ref=lorcandempsey.net), and the [University of Ottawa Library](https://www.uottawa.ca/library/?ref=lorcandempsey.net).
I am not saying that these are the best or necessarily exemplary, rather that they are indicative in various ways. Two of the libraries are Canadian, and one is Dutch. I don't believe their location is significant in the context of this post. All that links them is that they are good examples I have come across recently.
## Web-sightings: storytelling and the narrative website
### Utrecht University Library
Utrecht is admittedly untypical in that it has decided to move away from a discovery layer, so there is not a search box in prime real estate space. Instead, it uses a combination of third party services linked back to local collections, which is described [here](https://www.uu.nl/en/university-library/searching-for-literature?ref=lorcandempsey.net). Also of note is that the library is a visible link on the University [home page](https://www.uu.nl/?ref=lorcandempsey.net), one of just 5 on the prime navigation bar.
The website leads with a news item against the background of a full width image. There is some navigation, including highlighted direct links to search engines (interpreted broadly) and to open access, which as part of open science generally is a major focus of the library. Then there is further news and events, illustrated by photographs. A sense of energy and engagement comes through, especially given the dynamic nature of this content.
What most struck me though was the way in which they described their service offer, using a three-fold distinction: for researchers, for students (learning) and for lecturers (teaching). Rather than a list of services, linked to separate pages, they have a page each for [researchers](https://www.uu.nl/en/university-library/advice-support-to/researchers?ref=lorcandempsey.net), [students](https://www.uu.nl/en/university-library/advice-support-to/students?ref=lorcandempsey.net) and [teachers](https://www.uu.nl/en/university-library/advice-support-to/lecturers?ref=lorcandempsey.net). Each page then contains nicely illustrated panels describing available service areas. These are linked directly from the home page and also from an 'Advice and support to ...' [page](https://www.uu.nl/en/university-library/advice-support-to?ref=lorcandempsey.net).
What is nice here is that each is accompanied by a sentence or two indicating the type of support provided. It is couched in terms of *jobs to be done* throughout the lifecycle, not as a particular service name, or in terms of access to informaton.
Research advice and support
The areas for support are also presented with a short contextual paragraph. Again, they are organised around *jobs to be done*. So it brings together advice and support on publishing "in one spot." It offers a '[visibility check](https://www.uu.nl/en/university-library/advice-support-to/researchers/visibility/research-visibility-check?ref=lorcandempsey.net)' which steps through ways in which you can draw attention to your work on the web. I like how the emphasis is on both **advice** and **support**, so help is available whether or not there is an immediately applicable service. In this way, the library is emphasising its general expertise and contribution, rather than a particular set of named services which may be more or less well understood.
Learning and teaching advice and support
Learning and teaching are presented similarly. The areas are color-coded - the graphic panels in each is in a different color - green for research, blue for teaching.
Each panel leads to a more detailed page which discusses the topic and may provide further resources. There is some contextualization. So, for example, a panel for special collections appears in each area, but the brief description is specialised each time to the group it is aimed at.
### Calgary Public Library
[Calgary Central Library: combining intimacy and civic statementThe Calgary central library was on first impression the finest public building I have been in for years.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/calgary-public-library-a-civic-presence/)
I wrote admiringly about a visit to the Calgary Central Library a few years ago. I recently looked at the [website](https://calgarylibrary.ca/?ref=lorcandempsey.net).
Where public libraries are part of local government (as in the UK or Ireland, for example) they usually need to fit in with the website of their parent, which can be somewhat dull. However, in different organizational contexts, public libraries have control over their own websites. And given their general public audience are often brighter and more directly engaging than academic sites. More relational.
There is much to appreciate on the Calgary website. The immediate impression is contemporary, informative and engaging. The focus of the home page is the Summer program. Then it has a hamburger on the left which expands into four equally emphasised sections: ***Your library*** which provides overview information about the library, its locations and volunteer opportunities (I like that 'your'); ***Connect*** which introduces ways to connect with expertise and facilities; ***Events & programs*** which introduces opportunities for social engagement; and then ***Read, learn & explore*** which introduces the collections, the digital offerings and the central library. There are icons on the top left for search, locations and profile. The [search page](https://calgarylibrary.ca/?ref=lorcandempsey.net) offers a search of either the website or the catalog. It may be a small thing, but I thought that overall these options reflect people's experience of current websites, and it was good to find the catalog under a general search icon.
The rest of the home page continues to be very bright and engaging. Events and tailored reading recommendations follow, again with short contextualising descriptions.
There is a variety of ways in which users can participate in the library, including being on the Board. It is interesting to see how the Board opportunity is presented at the same level as other activities and services. It emphasises partnership with, and accountability to, the community.
Opportunities to participate in a variety of ways
I liked the icons for media types and loved the graphic representations of the individual branch libraries on the [people page](https://calgarylibrary.ca/about-the-library/library-leadership/?ref=lorcandempsey.net), nice to look at but also glanceably informative. There are actually also photographs of the branches on the [locations page](https://calgarylibrary.ca/your-library/locations/?ref=lorcandempsey.net).
Icons throughout ... not just lists of services
Sketches of branch libraries, used throughout
In the context of my theme, the pages that struck me most were those about [joining](https://calgarylibrary.ca/your-library/join/?ref=lorcandempsey.net) and [services](https://calgarylibrary.ca/your-library/free-services/?ref=lorcandempsey.net). This is where the library says who it is for and what it does. The message is of an organization which recognises the plural communities that actually make up its community. And note again pictures, color and a contextualising sentence.
The services page describes a range of services, including support for mental wellness. I like the way it describes the books: yes these are important but we do so much more. This is presented positively. And not in the defensive, negative way that one sometimes hears "we are about more than books."
This page is also actively making the case for joining the library, not just describing services. This is characteristic of the website as a whole - it feels active, it wants to engage and to provide opportunities for participation.
Lovely presentation of services throughout the system
Browse installations by artists from or with a connection to Treaty 7
> This is characteristic of the website as a whole - it feels active, it wants to engage and to provide opportunities for participation.
### The University of Ottawa Library
I came across this when looking for library strategies, of which the [University of Ottawa Library](https://www.uottawa.ca/library/?ref=lorcandempsey.net) has a nice example. I was immediately struck by the full-screen warm and bright picture (see above), showcasing the teaching and social nature of the library. The website itself has extensive use of white space, a generous font-size and well-chosen complementary fonts, which gives it an open expansive feel. Again, it feels current. It inherits these choices from the University, and one slight drawback is that it is sometimes easy to confuse the general university navigation in the header and footer with the library's.
The picture is followed by high level navigation, and by the Omni search box. Omni is the [consortial search system](https://ocul.on.ca/omni/?ref=lorcandempsey.net) to which Ottawa belongs.
The navigation labels are not too surprising but I liked their centrality and also some of the choices made in how services are aligned under them.
***Collections*** covers both what I call **outside in** (materials acquired by the library and made available internally - books and journals) and **inside out** (materials owned or generated by the university and shared with the outside world - special collections, digitised collections, research outputs). I appreciated how these were lined up together, and how the repository material was lined up alongside journals and articles. See the panel on the left here:
Again, note the picture and contextualising description
They also go into a little detail about the types of things you can find in the library (see the panel on the right above). I like that they do not take it for granted that potential users will know what is in the collections and they spell some things out.
***Research help*** also seems purposefully organised, and not just a list. **Research** is a somewhat elastic word on library websites. In the collections-based library, it tended to be used to refer to aspects of literature-based research, and this sense still occurs. Now, as support is provided throughout the research lifecycle it tends to be used more broadly to describe a range of services, as it is here. The set of services includes the use of resource guides, and also support for writing and citing (I think that 'research skills' is a positive and strong term), but also include research data management services, data services and scholarly communication services. Each item opens out on a page with more resources, with a focus on education, awareness, service and further contact as relevent. Services are contextualised in terms of research and learning behaviors.
There is contextual information everywhere .. see for example the introduction to scholarly communication advice and services
***Services*** is a list of areas with some focus, not exclusively, on learning and teaching. Again, pages open out to advice, education, services. Here for example is the hero section from the **course reserves** page ..
This shows several things:
- The University header navigation is on very page. It includes links to student portal, course management system, and employee portal, and to general pages for employees and students.
- It also includes the high level library navigation below the picture, and a link to chat.
- There is occasional use of this trend-conscious flat style of illustration throughout the website (see the [Corporate Memphis](https://en.wikipedia.org/wiki/Corporate%5FMemphis?ref=lorcandempsey.net) trend). The title (course reserves) appears in a panel, with some context. The content of the page follows below.
Library strategy - An outward view
I mentioned the library strategy, which is highlighted in the ***About*** section. It is very much a storytelling document, which aims to show that the library understands and is responding to the research and learning work of the university. This is from the introduction by the University Librarian, to the careful keying to University objectives, to the overall structured presentation. The focus thoughout is outward facing, on participation in the work of the university and on partnership in advancing programs and services. Of course, this has to be balanced with an emphasis on the library and its contribution.
> Each of the libraries is careful to describe itself in terms of what the community it serves values, not in terms of internal capacities or structure.
The language is carefully chosen. Services are *specialised* and they are provided throughout the *research process*. Services are *responsive* and *complement* learning needs that are *evolving*. Space is for *learning* and *collaboration*. The collections objective is not just focused on the locally acquired collection. It notes how collaboration maximises availability, and connects activities with sustainability goals and with the 'distinctive Franco-Ontarian, Franco-Canadian and bilingual character of uOttawa.'
The library mission is pretty direct and clear in what it thinks is important. It highlights the connections to university strategy and how it improves research and learning at the University. And it leads by connecting first to **expertise**, and then to services, collections and technology.
> In alignment with the ambitious vision and core aspirations of Transformation 2030, the uOttawa Library advances cutting edge research and supports transformative learning by connecting the uOttawa community to expertise, services, collections and technology in a welcoming and supportive environment. // [Mission](https://www.uottawa.ca/library/strategic-plan?ref=lorcandempsey.net)
Again, the overall impression is of a library which wants to understand how it can help its researchers and learners succeed, in whatever ways it can. Nothing leaps out, but text and presentation is symptomatic of a relational attitude.
> In its own way, each library shows a commitment to telling a well-grounded story, in which the library is an active partner in enhancing learning, research and civic engagement, and overall community wellbeing.
## Some general observations
Here are some general observations looking at the three websites together.
- In each of these cases it seems to me that the library purposefully starts with a more **holistic** view of the library and its position. Each also recognises that it cannot assume that users already understand all they ways in which they can participate in library services. In the relational library, [full library discovery](https://www.lorcandempsey.net/full-library-discovery/) becomes a starting assumption as one wants to describe and promote all the ways in which the user can participate. The library does not want to assume that a potential participant is already familiar with the variety of ways in which they can benefit from expertise and services.
- Each of the libraries is careful to describe itself in terms of what the community it serves values, not in terms of internal capacities or structure.
- The narrative briefly describes the job the service or potential services can do for the **user**, rather than just naming or listing them. The '[curse of knowledge](https://www.lorcandempsey.net/libraries-and-the-curse-of-knowledge/)', where too many assumptions are made about what the user knows, is avoided in this way.
- Advice and education are emphasised as much as actual services. The library expertise may be manifest in different ways.
- I mentioned that the library strategy was an important vehicle for storytelling above. The current library **strategy** is very visible in each of these cases, and again is presented very much in storytelling terms. It is purposefully a public communications document, as well as an internal guide. These libraries want their users to understand their story, what is important to them, where they are investing their energies \[Utrecht [pdf](https://www.uu.nl/sites/default/files/UB-Policy-Plan-2022-2025-PDF-4MB.pdf?ref=lorcandempsey.net); Calgary [pdf](https://calgarylibrary.ca/assets/Uploads/Calgary-Public-Library-2023-2026-Strategic-Plan.pdf?ref=lorcandempsey.net); [Ottawa](https://www.uottawa.ca/library/strategic-plan?ref=lorcandempsey.net)\]. More generally they share information about the library and its organization.
- They recognise the importance of a **human face**. Generally and also in leadership positions. Calgary has a full people page with photographs (all with the Central Library in the background, and also includes links to branch managers. I like the welcoming [picture](https://www.uottawa.ca/library/strategic-plan?ref=lorcandempsey.net) of the library director on the Ottawa strategic plan, and they have a leadership page (without photographs) and routes into [librarians and specialists](https://www.uottawa.ca/library/research-guides-librarians?ref=lorcandempsey.net) who can help with particular needs. Utrecht [describes](https://www.uu.nl/en/university-library/about-the-library/organisation?ref=lorcandempsey.net) the organization of the library and provides contact points (with photographs).
- Website **design** is fresh with good use of spacing, color, typography. There is generous use of pictures, whether it is screen-width photographs, contemporary-style illustrations, and graphics associated with descriptions. The University websites inherit design from their parent institutions, but in each case it works well. These websites, in particular Calgary and Ottawa, are much more like the general informational websites people are accustomed to. I found myself saying and thinking 'it feels designed' quite a bit when looking at these sites, and I realised that much of what we see appears less so, or seems routine.
- **News** and **events** are important in different ways and tend to be highlighted. Events offer participation opportunities, are often the result of partnership, and signal commitment to shared experiences. A river of news shows activity, and also offers up more text for discovery.
- One area which I think will be increasingly important, but which is not highlighted in these libraries, is the **digital exhibition**. These contextualise and highlight particular strengths or unique materials. They place collections in a narrative which connects them with community and broader interests. They tell a story about the value of collections in terms of research, learning and community sensemaking.
In its own way, each library shows a commitment to telling a well-grounded story, in which the library is an active partner in enhancing learning, research and civic engagement, and overall community wellbeing. They are good examples of the narrative website.
I [wrote](https://www.lorcandempsey.net/national-libraries-and-fonts/) about the importance of fonts recently. Utrecht uses the ubiquitous **Open Sans*. Calgary uses **Museo Sans*, a high-quality commercial font; for me, this contributed to the overall sense of care I experienced. Ottawa uses two very well matched fonts, which again contributed for me to the sense that this was a designed experience. They are both free fonts. It uses the popular and a little quirky **Work Sans* as the main font (nice in large sizes), complemented by the elegant serif font **Spectral*, designed for comfortable screen reading. **Spectral* provides an effective counterpoint to the sans, and I thought the serif was used very well where a more conversational or explanatory tone was wanted.
I [wrote](https://www.lorcandempsey.net/national-libraries-and-fonts/#the-national-library-of-sweden-interesting-in-multiple-ways) about the National Library of Sweden in the fonts post, noting how the strong font choice helps create coherence across the website and enhances its storytelling.
## Coda: a note on two related trends
I think that effective storytelling in the context of the relational library will be increasingly important. There are two related and overlapping emphases, and I think all three together point to evolving re-evaluation of library website positioning.
1. [Generative AI applications ](https://www.lorcandempsey.net/intro-gen-ai/)comprehend, summarise and generate text, which, in concert with search technologies, will cause a step change in discovery services. When your content management system comes with an **AI-enabled conversational interface**, how do you best characterise what you do and offer for good results? Contextualising services in relation to user needs and more fully documenting what they do will be helpful from a discovery point of view. What we might call the documentary website becomes important. (To get a sense of what this may look like, the [perplexity.ai](https://www.perplexity.ai/?ref=lorcandempsey.net) plugin/service is very useful: it allows you to scope a query to your own website.)
2. The pandemic focused attention on the online experience. It underlined the importance of having a more **holistic online experience**, where the full range of services is available and described. I have spoken about this as an important pandemic effect, as in, for example, the RLUK presentation linked below. I used the recently redesigned University of Michigan Library [website](https://www.lib.umich.edu/?ref=lorcandempsey.net) as a good example. This nicely shares many of the narrative characteristics I mention above. And as I discuss in the presentation, it provides a very full overview of the capacities of the library, again in a way that is focused on research and learning needs.
[Pandemic effects and collection directionsBeyond the scramble of the current situation, universities will be looking at long term pandemic effects. This clearly has implications for libraries, as they cleave more closely to university strategies. This presentation looks at some pandemic effects, and considers how it will likely accelerate s…figshare](https://figshare.com/articles/presentation/Pandemic%5Feffects%5Fand%5Fcollection%5Fdirections/13670698?ref=lorcandempsey.net)
**Picture:** I took the feature picture on a trip to Calgary.
**Acknowledgement:** I am grateful to Ken Varnum for helpful comments on an earlier draft.
### Generative AI, scholarly and cultural language models, and the return of content
URL: https://www.lorcandempsey.net/generative-ai-a-note-about-content/
Last updated: 2024-10-16T03:10:05.000Z
## Introduction
I provided a general overview of large language models and generative AI in a [recent](https://www.lorcandempsey.net/intro-gen-ai/) post. As AI momentum continues to grow, there are now more announcements in areas which are closer to our domain.
Here I want to look a little bit more at some examples of scholarly or cultural **large language models** (LLMs). It is not at all a comprehensive review, rather a sampling of indicative initiatives. The focus is on LLMs themselves and the importance of curated data to these initiatives, rather than on the parallel proliferation of AI-based applications which use the LLMs.
There is now a diverse and expanding universe of [LLM](https://www.lorcandempsey.net/intro-gen-ai/)s. There are foundation models from large established players (e.g. Google and Microsoft, individually and in its support for OpenAI) and from several startups (e.g. Anthropic), some of which are developing into platforms for others. There are platforms which make these and other models available in managed environments (e.g. Amazon, Microsoft, Fixie). There is a flourishing ecosystem around open source LLMs which are growing in capabilities, some targeted at more affordable computational environments (many of these are aggregated on Hugging Face, an important AI provider of infrastructure and services).
And then there is a variety of domain specific initatives developing models, or training more general models, for specialised communities or applications (e.g. medicine, finance, biosciences).
The composition, transparency, [documentation](https://www.lorcandempsey.net/intro-gen-ai/#transparency-and-evaluation) and representativeness of these models are important issues given known [concerns](https://www.lorcandempsey.net/intro-gen-ai/#3-social-concerns). There are issues around [IP](https://www.lorcandempsey.net/intro-gen-ai/#authenticity-creation-and-intellectual-property) and reuse, [concentration](https://www.lorcandempsey.net/intro-gen-ai/#concentration-effects-the-rich-get-richer) of economic and cultural power, [exploitation](https://www.lorcandempsey.net/intro-gen-ai/#hidden-labor-and-exploitation) of hidden labor, as well as around environmental [impact](https://www.lorcandempsey.net/intro-gen-ai/#environmental-impact-of-large-scale-computing), impact on [employment](https://www.lorcandempsey.net/intro-gen-ai/#the-impact-on-employment), and social confidence and trust. Given the potential impact [regulation](https://www.lorcandempsey.net/intro-gen-ai/#regulating) is being considered by many regimes.
These issues are of special concern in scholarly and cultural domains, where transparency, equity and respect for cultural particularity and expression are important. For research purposes, results need to be reproducible. In this context, it is interesting to see the emergence of several models specialised to these domains, and some attention to the more careful curation of training and tuning data. We can expect to see more activity here, across scholarly and cultural interests.
Even in research and cultural contexts, the use of AI and LLMs will range widely. For a sense of developments in big science and high performance computing see this [report](https://www.anl.gov/sites/www/files/2023-06/AI4SESReport-2023-v5.pdf?ref=lorcandempsey.net) based on a series of workshops organized by the (US) national laboratories. At a different scale, see for example this discussion of the potential use of AI in computational social sciences \[[pdf](https://arxiv.org/pdf/2305.03514.pdf?ref=lorcandempsey.net)\]. And, for a telling example of issues with current foundational LLMs see this paper about ways in which book literature in training data disproportionately leans in particular directions: *Speak, Memory: An Archaeology of Books Known to ChatGPT/GPT-4* \[[pdf](https://arxiv.org/pdf/2305.00118.pdf?ref=lorcandempsey.net)\].
So as not to over-extend this post, I refer readers to my recent AI overview [post](https://www.lorcandempsey.net/intro-gen-ai/) for more detail about [trends](https://www.lorcandempsey.net/intro-gen-ai/#2-rapid-continuing-evolution) in AI development, some [contexts](https://www.lorcandempsey.net/intro-gen-ai/#1-major-attention-and-investment) of use, and the social [concerns](https://www.lorcandempsey.net/intro-gen-ai/#3-social-concerns) raised by their creation and impact. I occasionally link in this post to relevant sections there, and I also include some final summarising comments from that post below.
[Generative AI and large language models: background and contextsThe promise and challenge of Generative AI is now central. This is a summary overview of some of the major directions and issues, acknowledging that things are moving very quickly. I intend it as background to later posts about library implications and developments.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/intro-gen-ai/)
Recent AI overview post: large language models, generative AI and surrounding developments
As a lead-in, two recent announcements caught my eye.
LibraryThing and ProQuest have introduced an experimental recommender service, [*Talpa*](https://www.talpa.ai/?ref=lorcandempsey.net), assocated with the *Syndetics Unbound* product. It is designed to answer those questions where some characteristics of an item are known, but maybe not the actual title or other details. I thought it was interesting for three reasons. First, it shows what is possible for a small group like LibraryThing to achieve based on leveraging emerging AI platforms, in this case *ChatGPT* and *Claude AI* from Anthropic. Second, it is an example of how apps will be built by articulating elements from various services. The LLMs are queried for books. But the LLM text comprehension and manipulation services are also used to process the incoming queries. Bibliographic data from ProQuest and LibraryThing is used to validate the existence and details of materials. And third, those existing sources of domain-specific and highly curated data are used to improve quality and mitigate the effects of hallucination.
The second is an announcement from Clarivate about a partnership with leading AI company AI21Labs. There are not many details in the release, but it emphasises the deep reservoir of curated content that Clarivate manages, the provision of conversational interfaces, and the tools for language 'comprehension and generation' that AI21 brings to the table.
> Embedding generative AI to enable market-leading academic conversational discovery // [Clarivate](https://www.prnewswire.com/news-releases/clarivate-announces-partnership-with-ai21-labs-as-part-of-its-generative-ai-strategy-to-drive-growth-301857301.html?ref=lorcandempsey.net)
Given its scale, I had wondered whether Clarivate might develop its own language model (see discussion of the scholarly communication service providers below), in the way that Bloomberg, say, has [done](https://www.bloomberg.com/company/press/bloomberggpt-50-billion-parameter-llm-tuned-finance/?ref=lorcandempsey.net). Partnering in this way seems sensible and it is likely that we will see other agreements between service providers and AI platform providers. The press release focuses on the scholarly and library interests of Clarivate, mentioning recommendations and conversational search in discovery.
> It will provide students, faculty and researchers with rapid access to detailed and contextual information and answers along with more personalized services to offer benefits such as relevant recommendations. Conversational search across discovery solutions will allow students to intuitively interact with discovery services, aggregated databases and collections to receive more relevant, diversified results and services based on trusted content. // [Clarivate](https://www.prnewswire.com/news-releases/clarivate-announces-partnership-with-ai21-labs-as-part-of-its-generative-ai-strategy-to-drive-growth-301857301.html?ref=lorcandempsey.net)
So we potentially see three levels here: using LLM APIs to build services, partnering with an LLM provider where there is some scale, or developing an LLM oneself. Here I am looking at some examples of the third level.
## Quick AI recap
For orientation and context I provide the summarising final remarks from the earlier AI overview [post](https://www.lorcandempsey.net/intro-gen-ai/) here, very slightly amended. Skip to the next section if this is not of interest.
Four technology capacities seem central (especially as I think about future library applications):
1. **Language models.** There will be an interconnected mix of [models](https://www.lorcandempsey.net/intro-gen-ai/#a-diversity-of-models), providers and business models. Large foundation models from the big providers will live alongside locally deployable open source models from commercial and research organizations alongside models specialized for particular domains or applications. The transparency, curation and ownership of models (and tuning data) are now live issues in the context of research use, alignment with expectations, overall bias, and responsible civic behavior.
2. **Conversational interfaces.** We will get used to conversational interfaces (or maybe 'ChUI' - the Chat User Interface). This may result in a partial shift from 'looking for things' to 'asking questions about what one wants to know' in some cases. In turn this means that organizations may begin to document what they do more fully on their websites, given the ways in which services will combine discovery and the textual abilities of LLMs to process, summarise and generate text, or pass it to other servcies. For an interesting example, see how the perplexity.ai app/extension can work over a local website (see the screenshots below).
3. **Agents and workflows.** The text interfacing capacities of LLMs will be used more widely to create workflows, interaction with tools and knowledge bases, and so on. LLMs will support [orchestration frameworks](https://www.lorcandempsey.net/intro-gen-ai/#building-tools-and-workflows-agents) for tools, data and agents to build workflows and applications that get jobs done.
4. **Embeddings and Vector databases.** Vector databases are important for managing embeddings which will drive new discovery and related services. Embedding APIs are available from several organizations. (Embeddings are representations of text elements which supports semantic applications like classification, retrieval, translation, and so on. One can compute 'similiarity' between embeddings. They underly many of the services we are now seeing emerge.)
Using the Perplexity.ai plugin. First window shows a general Internet search. The second limits it to the osu.edu domain, where it offers a response partly based on local finding aids.
Several areas stand out where there is a strong intersection between social policy, education and advocacy:
1. **Social confidence and trust: alignment.** Major work needs to be done on [alignment](https://www.lorcandempsey.net/intro-gen-ai/#refinement-or-specialization-fine-tuning-moderation-and-alignment) at all levels, to mitigate hallucination, to guard against harmful behaviors, to reduce bias, and also on difficult issues of understanding and directing LLM behaviors. However, there will be ongoing concern that powerful capacities are available to criminal or political bad actors, and that social trust and confidence may be eroded by the inability to distinguish between human and synthesized communications.
2. **Transparency.** We don't know what training data, tuning data and other sources are used by the foundation models in general use. This makes them unsuitable for some types of research use; it also raises more general questions about behaviors and response. We also know that some services capture user prompts for tuning. Tolerances may vary here, as the history of search and social apps have shown, but it can be important to know what one is using. Models with more purposefully curated training and tuning data may become more common. [Documentation](https://www.lorcandempsey.net/intro-gen-ai/#transparency-and-evaluation), evaluation and interpretability are important elements of productive use, and there are interesting intersections here with archival and library practice and skills.
3. **Regulation.** Self regulation and appropriate government activities are both important. The example of social media is not a good one, either from the point of view of vendor positioning or the ability to regulate. But such is the public debate that [regulation](https://www.lorcandempsey.net/intro-gen-ai/#regulating) seems inevitable. Hopefully, it will take account of lessons learned from the Web 2.0 era, but also proceed carefully as issues become understood.
4. **Hidden labour and exploitation.** We should be aware of the [hidden labour](https://www.lorcandempsey.net/intro-gen-ai/#hidden-labor-and-exploitation) and exploitation involved in building services, and do what we can as users and as buyers to raise awareness, and to make choices.
## The return of content: the value of expertise and verified data
Emad Mostaque, CEO of Stability AI, compares the 'junk food diet' of the large language models with a more 'organic, free-range AI':
> As the saying goes, you are what you eat, so we should feed these models better things.
> No more web crawls, no more gigantic datasets with all sorts in \[...\], instead lets do good quality datasets.
He argues that there should be more emphasis on good quality inputs which reduces the need for [alignment](https://www.lorcandempsey.net/intro-gen-ai/#refinement-or-specialization-fine-tuning-moderation-and-alignment) of outputs where models are fine tuned after training.
> Let's all get together to build good quality, open, permissive datasets so folk don't need to clog the arteries of these GPUs with junk, which often causes dreaded loss spikes. // [On hallucinations, junk food & alignment](https://emad.posthaven.com/on-hallucinations-junk-food-and-alignment?ref=lorcandempsey.net)
In the AI overview [post](https://www.lorcandempsey.net/intro-gen-ai/), I noted the interesting argument by Alex Zhavoronkov in *Forbes* that content generators/owners are the unexpected winners as LLMs become more widely used. The value of dense, verified information resources increases as they provide training and validation resources for LLMs in contrast to the vast uncurated heterogeneous training data. Not unsurprisingly, he points to *Forbes* as a deep reservoir of business knowledge. He also highlights the potential of scientific publishers, *Nature* and others, whose content is currently mostly paywalled and isolated from training sets. He highlights not only their unique content, but also the domain expertise they can potentially marshall through their staffs and contributors.
[The Unexpected Winners Of The ChatGPT Generative AI RevolutionGenerative AI is taking the world by the storm with billions invested in infrastructure, data, and people. The ability to generate human-level responses to complex queries is expected to transform publishing. But publishers may be the biggest winners of the generative AI revolution.ForbesAlex Zhavoronkov, PhD](https://www.forbes.com/sites/alexzhavoronkov/2023/02/23/the-unexpected-winners-of-the-chatgpt-generative-ai-revolution/?ref=lorcandempsey.net)
The balance between specialized curated data and more general internet data is something that will be decided in particular contexts, especially as there is more experience and R&D across the range of training and tuning options.
With that as background, here are some notes about several initiatives. The first is a speculative look at the scholarly communication service vendors. This is followed by descriptions of several LLM initiatives in the scholarly and cultural space.
### ① Speculative: the scholarly communication service vendors
It is interesting to consider for a moment the potential role of Elsevier, Digital Science/Holtzbrinck and Clarivate. In the absence of a general industry category I call these three organizations **scholarly communication service vendors**. They have a very interesting place in the current scholarly ecosystem given the range of their data and workflow resources.
Elsevier and the Holtzbrinck Publishing Group, are major publishers who have evolved a range of scholarly workflow, productivity, analytics and other services alongside their publishing activity. Clarivate has a broad portfolio, across several domains.
Each of these groups offers some selection of publishing, research workflow, research evaluation and analytics and other services. The internal evolution of each has been quite different, in terms of service development, acquisition, and so on, as is how the constituent parts are configured and presented to meet market needs. Importantly, as I have noted before, each is also building a research graph or representation of research activity which supports, and is supported by, other services.
> Each presents a graph-based view of the core of scientific knowledge as represented in the literature, through Scopus, Web of Science and Dimensions, respectively. Increasingly they want to document research entities (researchers, outputs, organizations, etc), they want to analyze research knowledge as represented by those entities, and they want to visualize research patterns and relationships. And then to provide a variety of decision support, discovery and evaluative services on top of those structures. // [Workflow is the new content](https://www.lorcandempsey.net/workflow-is-the-new-content/)
Elsevier and Digital Science/Holtzbrinck have assembled a range of services which involve data, workflows and expertise at multiple points of the research lifecycle.However purposeful this was in retrospect, it certainly now seems strategically advantageous against the background of current developments. Notably, what comes across – to varying degrees and in different ways – is a perspective which sees data and workflow services as connected parts which in turn need to be connected into the broader fabric of research and learning.
Elsevier, for example, has moved strongly both upstream and downstream: upstream into research evaluation and analytics in recent years, or what it calls '[research intelligence](https://www.elsevier.com/research-intelligence?ref=lorcandempsey.net)', and downstream into individual researcher workflows. This portfolio now includes scientific publications, a research graph (*Scopus* and other resources), research data management/research information management/institutional repository services, a set of research analytics and impact measurement services, researcher productivity services, preprints services, and so on.
> ... what comes across \[...\] is a perspective which sees data and workflow services as connected parts which in turn need to be connected into the broader fabric of research and learning.
Holtzbrinck Publishing Group also brings together a major scientific publishing engine, Springer Nature, with a portfolio of high profile workflow, productivity and analytics applications across the research life cycle (for example, *Altmetric*, *Readcube*, *Symplectic Elements*, *Figshare*, *Labguru*, and so on). While they appear to be managed at arms length, it will be interesting to see whether and how Digital Science and Springer Nature work together given the scale of the current challenge and opportunity.
Clarivate has a different profile again. It has significant content resources across several domains. In the scientific and research arena, it also has a curated research graph (*Web of Science*) and associated resources, and the recent acquisition of ProQuest adds other content and workflow resources. As noted above, Clarivate has declared a partnership with AI21 and it will be interesting to see how they leverage that in services.
I have emphasised the composition of these three groups because they have
1. the scale and expertise to do work in this space,
2. major reservoirs of scientific literature, representing a significant part of the scientific record,
3. prior investment in structured data and a research graph, manifest in flagship products
4. the ability to leverage networks of expertise, and
5. a range of workflow services gathering current information and analytics.
What could they do?
We will likely see the general further incorporation of capacities which assist at various stages of the workflow. The scholarly AI taxonomy expanded on [here](https://upstream.force11.org/an-initial-scholarly-ai-taxonomy/?ref=lorcandempsey.net) provides a reasonable framework for thinking about this: one can imagine services around discovery, entity extraction, summarization, trend analysis, and so on.
But beyond this it is interesting to think about what more they could do from a systemwide perspective, and what level of investment they bring to the opportunity.
- Strategic partnership with LLM provider. We have yet to see what Clarivate and AI21 do together. LexisNexis, Elsevier's sibling company, uses several LLMs and its own data in its *[Lexis+ AI](https://www.lexisnexis.com/en-us/products/lexis-plus-ai.page?ref=lorcandempsey.net)* service. Digital Science uses AI in several services, and it recently [announced](https://www.digital-science.com/news/digital-science-expands-executive-team-for-ai-future/?ref=lorcandempsey.net) a management reorganization "to reflect its current steep growth trajectory and further develop its market-leading capabilities in Artificial Intelligence (AI) and related technologies." It promises further product announcements to follow this year. Is there scope for a significant reciprocal partnership between Elsevier or Digital Science and one of the other emerging AI players (Cohere or Anthropic, for example)?
- Develop a specialist LLM to support scholarly work? Use specialist data sets to tune existing language models? The black box nature of the popular LLMs may disincline some to use them for research and scholarly work; these organizations could address that by building models based on their known research graphs and other data.
- License or offer content and their research graphs to LLM developers. Make details public.
- Build new ways of analysing the scholarly literature, doing ranking and measurement, providing discovery services. The semantic capacities offered by the embedding model make it interesting to think what they could do here.
- We are likely to see conversational or chat interfaces to many services (ChUI), as the focus shifts from looking for things to answering questions.
- We are moving quickly into the **third front** of open access, where the discussion is not about individual articles, journals, publishers or deals, but about AI-powered exploration of the research space (to include literature, data, people, organizations, ...). (Taking *Green* and *Gold* as first two fronts. One might add *Diamond*, and say the fourth front, but diamond doesn't have the same scale?) This is worthy of much more discussion, but these organizations are now well placed to offer a new level of access. But to whom and on what terms?
Open access is already a complex topic. There are multiple paths with no single or agreed destination. From a library policy point of view, I think this last point is very important. If (or when) interaction with the literature shifts in this way, then thinking about what open access means also needs to evolve.
> If (or when) our interaction with the literature shifts in this way, then thinking about what open access means also needs to evolve.
[Policies & downloads#Content,title#Relx – link to home page](https://www.relx.com/corporate-responsibility/engaging-others/policies-and-downloads?ref=lorcandempsey.net)
RELX, Elsevier's parent publishes papers on their AI position and principles
### ② Culture and language plus public infrastructure: the National Library of Sweden
The National Library of Sweden has been developing Swedish language models based on its collections. It is also cooperating with Nordic national libraries in the Nordic languages, and more broadly with other germanic languages. The National Library is also working within the public high performance computing environment of the European Union \[[video](https://www.youtube.com/watch?v=8cFYK7kT-ig&ref=lorcandempsey.net)\].
[Sweden’s National Library Turns Page to AI | NVIDIA BlogThe library is training state-of-the-art AI models on a half-millennium of Swedish text to support humanities research in history, linguistics, media studies and more.NVIDIA BlogIsha Salian](https://blogs.nvidia.com/blog/2023/01/23/sweden-library-ai-open-source/?ref=lorcandempsey.net)
AI initiatives are part of a larger project to digitize and make available in readily processable ways the collections of the library. Applications [include](https://www.itpro.com/technology/artificial-intelligence/how-the-national-library-of-sweden-harnessed-ai-to-unlock-centuries-of-language-data?ref=lorcandempsey.net) transcription of handwritten documents into digital text, spelling correction, tagging by topic, author and time period. They hope also to generate descriptions of video.
> An important aspect of the work here is the Swedish language and cultural context.
The National Library of Sweden is an admirable pioneer here. It does prompt the question about what long term public cultural or research provision there will be in this space and what level makes sense.
> “They can ask questions like ‘what the sentiments in headlines in newspapers during the conflict in Ukraine are’,” says Börjeson. “It was sad, then positive last fall, then negative again. You can have that kind of quantitative questions without actually accessing data.” // [ITPro](https://www.itpro.com/technology/artificial-intelligence/how-the-national-library-of-sweden-harnessed-ai-to-unlock-centuries-of-language-data?ref=lorcandempsey.net)
Other players here might be other national libraries, museums and cultural institutions.
There are also some non-profits in the library space who have the scale to do some work here, manage important reservoirs of data, and may be able to attract philanthropic support. Think of the combined bibliographic assets of Ithaka, HathiTrust and OCLC for example. The Internet Archive also has some scale in terms of infrastructure, data and resource.
[KBLab (National Library of Sweden / KBLab)NLP, language models, acoustic models, NER](https://huggingface.co/KBLab?ref=lorcandempsey.net)
National Library of Sweden on Hugging Face
An important aspect of the work here is the Swedish language and cultural context. Although there have been some attempts to broaden scope, existing LLMs will tend to be based on the characteristics of the Internet training data used, which, when compared to the whole of human knowledge, will lean to the English language as well as to more well off countries. This is an important issue given how LLMs are being used in knowledge and question answering applications. The National Library is making models based on the Swedish language available, as well as on its culture, history, current attitudes, and so on. This is important in the global context. Again, it raises the question of whether national libraries in cultural and language communities not strongly represented might have a role to play with other partners.
### ③ CORE: working with the largest publicly available reservoir of open access articles
[*CORE*](https://core.ac.uk/?ref=lorcandempsey.net) is an open access aggregation service provided by the Open University in the UK. It recently announced that it would be building an AI-based application with what they claim is the world's largest available reservoir of open access articles, sourced from repositories and journals.
> The CORE-GPT application is a step change in academic question answering. Our key development is that the provided answer is not just drawn from the model itself, as is done with ChatGPT and others, but is based on, and backed by, CORE’s vast corpus of 34 million open access scientific articles.
They note some of the issues with large language models, and suggest that these would be mitigated by working with their corpus of articles.
> CORE-GPT offers a solution to this problem. By ensuring that answers given are derived exclusively from scientific documents, this largely eliminates the risk of generating incorrect or misleading information. Further, by providing direct links to the scientific articles on which the answer is based, this greatly increases the trustworthiness of the given results. // [CORE](https://blog.core.ac.uk/2023/03/17/core-gpt-combining-open-access-research-and-ai-for-credible-trustworthy-question-answering/?ref=lorcandempsey.net)
There are not a lot of details available, so it will be interesting to see what they are implementing. One imagines that they will still have to manage hallucinations, even if scholarly ones.
There are various scenarios which could be implemented in cases like this. They could build their own LLM. They could use Cohere or OpenAI, say, to provide embeddings to support querying, clustering, visualization, and so on. They could use the language processing and conversational capabilities of ChatGPT or another service in association with searches over their content. I anticipate that we will see a lot of experiment as content providers explore how they can leverage AI services in different ways. *CORE* is not a large organization: it might make sense to partner with other organizations with an interest in this area.
In a parallel development, they are exploring a [membership model](https://blog.core.ac.uk/2022/11/07/1419/?ref=lorcandempsey.net) as their current Jisc funding comes to an end. This raises the question of how initiatives like this sustain themselves, in the absence of direct public support.
A very interesting and detailed overview of technical, data and related Core characteristics and challenges was recently published in *Nature Scientific Data* \[[pdf](https://www.nature.com/articles/s41597-023-02208-w.pdf?ref=lorcandempsey.net)\].
### ④ OLMo, a model for scientific research
*Semantic Scholar* is built by a team within the *Allen Institute for AI (AI2)*. It has been building a scholarly discovery service for some time, already using AI to help identify entities and create relationships in the scientific literature. AI2 has now announced a scientific LLM, *AI2 OlMo* (open language model).
> As a transparent, collaborative, nonprofit institution, we are well-positioned to build a language model that is truly open and uniquely valuable to the AI research community. Our OLMo endeavor will include more than just building an open language model — we’re purposely building a platform that will allow the research community to take each component we create and either use it themselves or seek to improve it. Everything we create for OLMo will be openly available, documented, and reproducible, with very limited exceptions and under suitable licensing. The artifacts released as part of the OLMo project will include training data, code, model weights, intermediate checkpoints, and ablations. A release strategy for the model and its artifacts is in development as part of the project. We also plan to build a demo and release interaction data from consenting users. // [AI2](https://blog.allenai.org/announcing-ai2-olmo-an-open-language-model-made-by-scientists-for-scientists-ab761e4e9b76?ref=lorcandempsey.net)
This is significant given the track record of *Semantic Scholar* and AI2, the commitment to open, and the scale and expertise AI2 brings to the task. It has the potential to be the basis for a variety of scientific or research models.
Additionally, AI2 is partnering with [MosaicML](https://www.mosaicml.com/?ref=lorcandempsey.net), a company which has developed and released several open large language models.
> As well, AI2 will openly share and discuss the ethical and educational considerations around the creation of this model to help guide the understanding and responsible development of language modeling technology. // [MosaicML](https://www.mosaicml.com/blog/introducing-ai2-olmo?ref=lorcandempsey.net)
What other non-profit entities could do similar work? Especially if foundation money were to be support the activity. It is interesting to wonder about Google given some of its assets. Are *Google Books* and *Google Scholar* mobilised within Google's LLM work already? Is there scope for an LLM which leverages that scholarly and bibliographic investment? Of course, Google would probably not approach it with the openness of AI2\.
### ⑤ A note on Intel/Argonne
Intel and Argonne National Laboratory have announced plans for models to support the major scientific activity at the US national laboratories and elsewhere. There is very little detail in the announcement, but it will leverage *Aurora*, the high performance computing capacity at Argonne, being built with Intel.
> These generative AI models for science will be trained on general text, code, scientific texts and structured scientific data from biology, chemistry, materials science, physics, medicine and other sources.
> The resulting models (with as many as 1 trillion parameters) will be used in a variety of scientific applications, from the design of molecules and materials to the synthesis of knowledge across millions of sources to suggest new and interesting experiments in systems biology, polymer chemistry and energy materials, climate science and cosmology. The model will also be used to accelerate the identification of biological processes related to cancer and other diseases and suggest targets for drug design.
> Argonne is spearheading an international collaboration to advance the project, including Intel; HPE; Department of Energy laboratories; U.S. and international universities; nonprofits; and international partners, such as RIKEN. // [Intel](https://www.intel.com/content/www/us/en/newsroom/news/intel-delivers-ai-accelerated-hpc-performance.html?ref=lorcandempsey.net#gs.1nz4x6)
There is relevent background in the *Advanced research directions on AI for science, energy and security* report mentioned above \[[pdf](https://www.anl.gov/sites/www/files/2023-06/AI4SESReport-2023-v5.pdf?ref=lorcandempsey.net)\]. It is interesting given the federal support, the involvement of Intel (who faces strong competition now from Nividia in the AI space), and the ambition. We will have to wait to see more details about general availability, openness, and so on.
Many countries have public science infrastructure support. It will be interesting to see what LLM support might emerge in those contexts.
### ⑥ Language models redux
Finally, based on this, some things to note in the general [context](https://www.lorcandempsey.net/intro-gen-ai/#a-diversity-of-models) of large language models:
- Curation is in line with strong advocacy for greater transparency around both training and fine-tuning data. This is important for reproducibility in research, for reducing [bias](https://www.lorcandempsey.net/intro-gen-ai/#wrong-or-harmful-results) or harm, for making specialist or underrepresented perspectives available. At the same time, developers want to preserve the general textual abilities of such models, developed through training on large amounts of data.
- Some of the data of scholarly interest is behind paywalls, and has not been available as part of training data for current models. Publishers and other content providers have decisions to make about whether to license data to the large model providers, to create models themselves, or to create new partner opportunities. *The Washington Post* [analysed](https://www.washingtonpost.com/technology/interactive/2023/ai-chatbot-learning/?ref=lorcandempsey.net) Google's C4 data set which has been used to train several models. Interestingly, it includes some data from Springer, Elsevier and Wiley although we do not know which data or under what terms.
- Certainly, the importance of curated data sets in training LLMs has introduced a new factor for content providers, and one is reminded of discussions between Google and news providers in the early days of web crawling. One interesting category of service is the community forum style service such as *Reddit* or *Stack Overflow*, whose value is created by open participation on a strong network platform. They have [said](https://www.wired.com/story/stack-overflow-will-charge-ai-giants-for-training-data/?ref=lorcandempsey.net) they will charge to be ingested for training purposes. There has been some suggestion in relation to scholarly data that LLMs may enhance an 'open' advantage, however it is really too early to say in a rapidly evolving data environment.
- Open scientific, cultural and other material have been part of training data. For example, *The Washington Post* analysis shows *Internet Archive*, *arXiv* and *Plos* data in C4\. However, it is mixed with other data.
- There are various ways in which one might specialise an LLM. BloombergGPT uses a mix of its deep historical reservoir of proprietary financial data and general materials in its training and [reports](https://www.bloomberg.com/company/press/bloomberggpt-50-billion-parameter-llm-tuned-finance/?ref=lorcandempsey.net) good results. One can fine-tune an existing model to a particular domain. Google 'aligned' its Med Palm 2 model with specialist medical data. Or one could create a specialist model like the National Library of Sweden's.
- The LLM space is dominated by commercial players, with some collaborative, non-profit and educational contributions. There is little direct public provision or support at the moment (a model which is more common outside the US), although certainly public sources of funding have underpinned R&D and other activities. Understanding issues around sustainability, where can we see LLMs from the cultural, scholarly and non-profit sectors emerge?
> Finding aids are especially interesting in this context. Maybe they will come into their own as new computational users take advantage of the context and connections they provide.
## Conclusion
As the AI ecosystem continues to diversify, libraries have much to think about. I will return to thoughts about libraries and library services, but here are three thoughts specifically about libraries and LLMs in conclusion.
1. **Advocacy and policy.** The way in which we create and use knowledge resources is changing. I mentioned the potential third front of open access above as interaction with the scholarly literature is progressively AI-enabled. It will be important for libraries and library representative and advocacy organizations to track and respond to the computational context of literature use.
2. **Informed consumers.** Libraries will be buying products which are AI-enabled in various ways. They should use that economic weight to argue for good practices, in particular around the [social concerns](https://www.lorcandempsey.net/intro-gen-ai/#3-social-concerns) that they raise and around appropriate [transparency](https://www.lorcandempsey.net/intro-gen-ai/#transparency-and-evaluation) and documentation of models and data.
3. **The documentation and discovery deficit.** Organizations are now used to search engines as consumers of their web content, and there has been a big focus on SEO and related topics. As we see the combination of search technology, LLM text processing and generation capacities, and conversational interfaces, we will potentially see another shift in how organizations make content available. We will likely see more attention to fuller documentation on the web. I recently discussed the documentation and discovery deficit in library operations. This may become more of an issue in this context (see the perpexity.ai example above). It might be advantageous for libraries to do more work in contextualising their services, in contextualising resources with learning contexts (through resource guides, reading lists, ...), in contexualising special collections with exhibitions, in documenting hidden collections or materials from under-represented communities, and so on. Finding aids are especially interesting in this context. Maybe they will come into their own as new computational users take advantage of the context and connections they provide.
***Note:** I discuss the discovery deficit in a [recent](https://www.youtube.com/watch?v=uQ7ckgVfGRQ&ref=lorcandempsey.net) [presentation](https://figshare.com/articles/presentation/Evolving%5Flibrary%5Fdiscovery%5F10%5Fdirections/22213861?ref=lorcandempsey.net). It is a sign of how quickly things have changed that I got the original invitation to speak before the launch of ChatGPT. Interestingly, the discovery deficits I focused on are also areas where AI-based approaches may develop. I discuss this briefly in the presentation, and the environment continues to evolve rapidly.
**Feature picture:** The feature picture is a piece by A.K.Burns, which I took at an [exhibition](https://wexarts.org/exhibitions/ak-burns-space-we-are?ref=lorcandempsey.net) of her work at the Wexner Center for the Arts, The Ohio State University. The photograph on the AI overview [post](https://www.lorcandempsey.net/intro-gen-ai/) is of the same piece, but taken from the other side (with a different color wall in the background).
**Acknowledgement:** I am grateful to Karim Boughida and Ian Mulvany for commenting on an earlier draft.
### Font choices, values and ecosystem, with some national library examples
URL: https://www.lorcandempsey.net/national-libraries-and-fonts/
Last updated: 2025-06-01T20:13:47.000Z
A note on vocabulary: A ****type foundry** is an organization that designs or distributes fonts. They may employ ****type designers** or contract with them to distribute their fonts. They may sell fonts themselves, and will typically also place them with one or more distribution platforms (e.g. Adobe, Monotype, Fontspring). A ****typeface** is a particular design, which may be manifest in multiple ****fonts** (of different weights, or styles, etc). However, typeface and font are now often used interchangably. ****Font pairing** involves selecting complementary fonts in a design; it is common for example to mix [****serif**](https://fonts.google.com/knowledge/glossary/serif?ref=lorcandempsey.net) and [****sans**](https://fonts.google.com/knowledge/glossary/sans%5Fserif?ref=lorcandempsey.net) across headings, text, UI features, and so on. ****Styling** is where CSS properties are used to determine how text will appear in terms of size, weight, style, spacing, and so on. There is a useful typography [glossary](https://fonts.google.com/knowledge/glossary?ref=lorcandempsey.net) at Google Fonts, which will explain font classifications like [****neo-grotesque**](https://fonts.google.com/knowledge/glossary/grotesque%5Fneo%5Fgrotesque?ref=lorcandempsey.net), [****humanist**](https://fonts.google.com/knowledge/glossary/humanist%5Fold%5Fstyle?ref=lorcandempsey.net), [****monospaced**](https://fonts.google.com/knowledge/glossary/monospaced?ref=lorcandempsey.net)****,** [****geometric**](https://fonts.google.com/knowledge/glossary/geometric?ref=lorcandempsey.net) and [****slab**](https://fonts.google.com/knowledge/glossary/slab%5Fserif%5Fegyptian%5Fclarendon?ref=lorcandempsey.net). As well as technical terms like [****variable font**](https://fonts.google.com/knowledge/glossary/variable%5Ffonts?ref=lorcandempsey.net).
## Prelude
> Used consistently, this typographic vocabulary serves as the foundation for a successful identity system, communicating as much about the institution as the words used to describe it. // University Style Guide, Visual Elements. [The University of Illinois Chicago](https://marketing.uic.edu/marketing-toolbox/university-style-guide/visual-elements/?ref=lorcandempsey.net#:~:text=Theinhardt%20is%20the%20signature%20font%20of%20UIC%2C%20evoking,it%20with%20a%20more%20individuated%20and%20distinctive%20font.)
This is a short introduction to some topics around the design and deployment of fonts. I would like to prompt libraries to think a little more about an area that not only involves design choices, but also business and values choices. So I combine it with an exploration of fonts in use in libraries.
I hope to look at academic, public and some other libraries and library organizations in future posts. Given the role of fonts in relation to identity, I thought it would be interesting to look first at some **national libraries**.
> A wonderful font will not save poor design work, and routine fonts can look well as part of an overall good design.
I am interested how library attitudes seem to contrast with, for example, university or corporate views. Many organizations invest considerably in branding, guidelines, and occasionally bespoke or custom fonts. Consider the fine custom font on the Clarivate [website](https://clarivate.com/?ref=lorcandempsey.net), for example. Or look at the way in which informed font choices at the Mellon Foundation or Ithaka websites support their storytelling. The University of Illinois, Chicago quote above is indicative of quite a common university sentiment even if it might seem over-stated.
There are many elaborate brand guidelines, in which typefaces play a role. Here is how New York University [considers](https://www.nyu.edu/employees/resources-and-services/media-and-communications/nyu-brand-guidelines/designing-in-our-style/visual-tone-spectrum.html?ref=lorcandempsey.net) font contribution to its identity, looking at how different sizes and weights of its primary font *Gotham* (a sans serif, made famous by use in Barack Obama's election campaign) and serif *Mercury* can be used singly and together to express mood.
**Gotham* and **Mercury* combine in different weights to create different 'moods'
While it is easy to dismiss this as 'mere' marketing or undue corporate influence, identity is a subtle and influenceable attribute. Fonts play a very small part in this, but looking more closely at them can be intriguing and rewarding.
As I discuss below, it is important to remember that font selection and use is **only one part** of the overall typographic effect.
> I was certainly surprised at the extent to which national libraries have adopted Roboto and the other top Google fonts. If you had to pick any organization that constitutionally was not aligned with a global monoculture then that organization might be a national library?
As always, my competencies limit me in major ways. I confine myself to Latin languages and scripts, I have an untutored design eye, and an amateur knowledge of fonts. I became more interested when I moved platforms for this website and learning more became a personal project during the pandemic. I use the apps **WhatFont* and **Fonts Ninja* to help with font identification, supplemented by inspecting the CSS when it seems necessary. I understand that this may mean that I occasionally might mistake a font. Do send me a [note](https://www.lorcandempsey.net/contact/) if something should be amended.
## National: a national font?
> The British have Gill Sans, the French, Garamond, the Italians, Bodoni, the Swiss, Helvetica. Is there a relationship between a typeface and place? Can a typeface have a regional accent? // There is no such thing as a New Zealand typeface, [Kris Sowersby](https://klim.co.nz/blog/there-no-such-thing-new-zealand-typeface/?ref=lorcandempsey.net)
This text accompanies an exhibition about typeface, place and New Zealand.
Sowersby is currently one of the world's leading type designers. He [writes](https://klim.co.nz/blog/?ref=lorcandempsey.net) reflectively about his work and about type generally. He runs the [Klim Type Foundry](https://klim.co.nz/?ref=lorcandempsey.net) in New Zealand which has created several iconic modern fonts. You will have seen his fonts, if nowhere else, then certainly on *ChatGPT*. OpenAI uses Klim fonts [*Söhne*](https://klim.co.nz/blog/soehne-design-information/?ref=lorcandempsey.net) ("*Söhne* is the memory of *Akzidenz-Grotesk* framed through the reality of *Helvetica*") and *Signifier,* a serif font.
The background for the remarks above is a font – called *National* – that Sowersby developed for New Zealand. The text above continues, and provides this context:
> With a lack of digital typefaces to choose from, and motivated to create a typeface that local designers could use to communicate with rather than reaching for foreign ones, typeface designer Kris Sowersby began investigating a typeface that would be from New Zealand. It was first released in 2007 and was named National.
> Now National is everywhere, especially here at home. \[...\] When we want to say “New Zealand”, we seem to reach for National.
The *National* typeface is used by the Museum of New Zealand Te Papa Tongarewa. However, I note it is not used by the National Library, which actually uses the very common *Proxima Nova* (the most widely used commercial font in the world [according](https://www.marksimonson.com/fonts/view/proxima-nova?ref=lorcandempsey.net) to its designer, Mark Simonson).
While *National* was successful and adopted in the way discussed above I wondered what was distinctively New Zealandish about it. Perhaps ironically, I was interested to see that it is the font currently used on the UK Parliament [website](https://www.parliament.uk/?ref=lorcandempsey.net).
Sowersby revisited these issues when writing about *National 2*, his later reworking of *National*.
> With the re-drawing of National as National 2, I aspire to shed my original confused, pseudo-patriotic impulse and embrace and refine the aesthetic of the typeface itself. Because we live in a networked world where cultures are embraced and shared, designers use typefaces for their visual subtleties, aesthetic and inherent quality, not purely because of their geographic origin. // [National 2 design information](https://klim.co.nz/blog/national-2-design-information/?ref=lorcandempsey.net)
> There is a paradox about fonts: for something so visible, they are surprisingly invisible.
National libraries play an interesting role. They are service organizations, like other libraries, and want to provide effective interactive services. For this reason, they need a functional font which works well. They should also be interested in 'aesthetic and inherent quality.' However, they are also important national cultural institutions which may have a story and a point of view to be communicated. In that context, the font is one communicative device: it potentially communicates an atmosphere or accent, as discussed in the next section. Fonts are functional, but they also contribute to [feeling](https://pimpmytype.com/font-follows-feeling/?ref=lorcandempsey.net) and help tell stories. And sometimes, maybe for national institutions, they might have some local geographic resonance?
## Atmosphere
There is a paradox about fonts: for something so visible, they are surprisingly invisible. Yet, any website or print designer working in the Latin script today has thousands of fonts to choose from. And they convey a message, albeit mostly subtly. As Kris Sowersby says elsewhere:
> Having just said fonts are invisible, I do think typefaces have an atmosphere. You know, like Arial has a very perfunctory, staid atmosphere. It’s boring but it works. // Art Laureate interview, [Kris Sowersby](https://klim.co.nz/blog/arts-laureate-interview/?ref=lorcandempsey.net)
I like the use of 'atmosphere' above to describe the distinctive contribution of a font. He also uses 'accent.' One also comes across the use of vibe, personality, mood, tone or flavor to suggest this. Typographer and lawyer, Matthew Butterick, [refers](https://practicaltypography.com/drowning-the-crystal-goblet.html?ref=lorcandempsey.net) to the 'seasoning' a particular font choice can provide.
This may be very subtle, and, by design, unobtrusive. Here are three examples, showing how fonts can unobtrusively yet effectively help a website work well and also how they can make a more explicit statement.
The **first** is the *Five Books* [website](https://fivebooks.com/?ref=lorcandempsey.net), which makes, I think, very good font selections to unobtrusively contribute to a professional and welcoming site. It pairs the classic *Avenir* for headings with *Alegreya* for body text. *Avenir* is a geometric sans serif designed by Adrian Frutiger (of whom more below). It is softer than the well known geometric font *Futura* (which its name echoes) and is highly legible and balanced. It feels remarkably 'achieved.' *Alegreya* [combines](https://typographica.org/typeface-reviews/alegreya-ht/?ref=lorcandempsey.net) "exuberant and contemporary shapes and treatment with the DNA of classic book types." *Alegreya* also has a lovely italic.
There is a nice tension between the geometric *Avenir* and the calligraphic flow of *Alegreya* which gives the site some energy while being very legible and functional.
**Note:** *Avenir* needs to be licensed from Monotype, who have acquired the rights to many classic fonts; *Alegreya* is from Huerta Tipográfica, an Argentinian foundry, which has several high quality fonts freely available on Google Fonts.
The **second** is *The Verge* [website](https://www.theverge.com/?ref=lorcandempsey.net)*,* which recently went through a typography-led redesign. In terms of overall design, I imagine some may find the very distinctive logo and color choices a little distracting, although I like them. Some readers may also pause over the mix of sans and mono in the sidenotes. While it wants to make a statement, it also wants to provide a functional effective reading experience. I think the fonts support both of these goals very well.
The site uses *PolySans*, a neo-grotesque sans (*Helvetica*\-style) for headings. This functions in low sizes for UI features and becomes more expressive in large sizes with subtle inktraps (notches). Inktraps have been a trend in recent years, and can appear gimmicky. I did not find them so here, and thought they enhanced the well balanced headings. There is a real italic (some sans serifs will just slant for italic) and a *PolySans* monospace font for accent text. Monospace fonts provide very nice accents: they can seem both tech forward (used in coding) and a bit retro (typewriter). I would not have italicised the captions here, but that is a small point. Together and across its variations, *PolySans* signals attention to design, a tech orientation, and a modern sensibility. They also use *Manuka* occasionally for headings, a strong compressed font for display in larger sizes.
*PolySans* is paired with *FK Roman Standard* for body text: "a neutral serif typeface, inspired by a newspaper typography giant *Times New Roman*." This is described by the [foundry](https://fonts.floriankarsten.com/fk-roman-standard?ref=lorcandempsey.net) as 'utilitarian' and a 'workhorse.' It works very well for medium length reading, which *The Verge* encourages. I think *The Verge* combines function and feeling very well here.
**Note:** I like that *The Verge* is supporting the work of two relatively small independent designer foundries. *PolySans* is from Gradiant, based in Bergen. *FK Roman Standard* is from Florian Karsten Typefaces, based in Brno, Czech Republic. The third font, [*Manuka*](https://klim.co.nz/blog/manuka-design-information/?ref=lorcandempsey.net), is again from Klim Type Foundry.
And **finally**, a [custom font](https://www.nan.xyz/custom/cohere/?ref=lorcandempsey.net) on the [website](https://cohere.com/?ref=lorcandempsey.net) of another AI company, [Cohere](https://cohere.com/?ref=lorcandempsey.net), provides an example of a more explicit statement. The goal was to "create a visual identity that could bring language AI \[...\] out of the realm of bleeding edge, experimental tech, and into today’s business needs." I think the body text, influenced by a techy monospace vibe, is lovely. The headings have a futuristic 'dot' feature, which can be varied or turned on and off. It is designed by [Nan](https://www.nan.xyz/custom/cohere/?ref=lorcandempsey.net) and I think it contributes effectively to storytelling about the company and its identity. Would the website and the 'dotted' typeface feel a little overwrought if you have to interact with it regularly? I don't know. I do know that it created a very positive first impression with me. I admired the desire to use the typeface in this way, and I wanted to know more about the company.
**Five Books*, **The Verge* and **Cohere*: font choices
*Five Books* and *The Verge* also showcase an important typographic consideration: **pairing fonts**. There is a lot of attention given to finding fonts which complement each other, and there is quite a bit of 'pairing anxiety' about finding good matches. I think the pairing works very well in each of these cases. Cohere shows a different approach, where a single typeface family is used, albeit in this case one with quite a bit of expressive variation (including the 'holes' in the headline version).
> What matters to us is this: What story does a typeface tell? What kind of personality does it have? // [Grilli Type](https://www.grillitype.com/about?ref=lorcandempsey.net)
## Design matters
> But in reality, picking fonts is only a small fraction of the battle. The vast majority of typography in **day-to-day UI design** is *styling fonts you’ve already chosen*. // The Step-by-Step Guide for Pairing Fonts, [Eric D. Kennedy](https://www.learnui.design/blog/guide-pairing-fonts.html?ref=lorcandempsey.net)
Font choice is only a part of overall typography and design. And in fact, the same font can look very different in different settings, and may be styled in different ways. A wonderful font will not save poor design work, and routine fonts can look well as part of an overall good design.
For example, look at these three sites using the same font, the remarkably popular *Montserrat*. I stumbled onto the [De Gruyter](https://www.degruyter.com/?ref=lorcandempsey.net) website a while ago, and immediately liked how the home page was quietly and effectively laid out. It uses *Montserrat* for headings and text, in small sizes. Another very popular Google font, the serif *Merriweather,* contrasts nicelyfor a warmer welcome message). This combination is used to good effect throughout, with *Merriweather* providing text, and *Montserrat* used in various ways for headings and text. They vary weight, size and capitalization throughout. I like the way that book titles always stand out. More boldly, the Western Washington University [website](https://www.wwu.edu/?ref=lorcandempsey.net) uses *Montserrat* in all caps and a heavy weight to communicate its message.
The Deutsche Nationalbibliothek [website](https://www.dnb.de/DE/Home/home%5Fnode.html?ref=lorcandempsey.net) uses *Montserrat* very effectively also, as part of its overall design. It is the font used on the home page and for headings. There is nice use of all caps, tracking (the space between letters is stretched a little in headings), and hierarchy throughout. As noted later, it is also nicely paired with a serif font for body text. The DNB name on the home page is striking in a subtle way, for example, in all caps and slightly stretched, although it sits a little redundantly beside the strong logotype. I thought it was interesting how they make grid lines visible as part of the user interface, and I really like the use of color throughout. The use of *Montserrat* here is an integral part of what for me was a very good experience - at once warm and confident.
Styling **Montserrat* differently
There are two points I want to make here. First, while De Gruyter, the DNB and WWU are all using *Montserrat* for headings and other elements, they are quite different. Overall design make a big difference, underlining the significance of the Eric Kennedy quote at the beginning of this section. The cumulative effect of a site that focuses attention, makes good use of white space, has good visual hierarchy, is laid out on a grid, and so on, is what one responds to. Font choice is a contributor to, but probably not in most cases a determinant of, response.
The second is more complex. Would the designer font *Gotham* work more effectively than the free Google Font *Montserrat* here? I mentioned *Gotham* above and you can see it in the NYU panels. An afficionado might argue that *Gotham* is a higher quality font, which matters. However, most people might not notice if it were substituted?
My focus here is on fonts. I understand it is not possible to disentangle this from overall design. However, looking at more general design issues is not my goal, although I do make occasional comments.
## The fonts ecosystem
I am a little surprised that libraries are not more alert to font choices. For design reasons, for sure. But fonts may also involve expenditure, and they involve choices about values. One would expect values-driven organizations like libraries to have more of a point of view about where they invest or how they choose to present themselves. Here are some of the factors that might influence a point of view.
> Google in particular also exercises considerable cultural power: the free and convenient distribution of fonts has created considerable conformity of use around its popular fonts.
### Business ecosystem
There is a diverse ecosystem around font design and distribution. You have three dominant distribution players who are very differently situated (Google, Adobe and Monotype); you can [rent](https://fontstand.com/?ref=lorcandempsey.net) fonts or license them as [works in progress](https://www.futurefonts.xyz/?ref=lorcandempsey.net); there are edgy independent font designers (e.g. [Nan](https://www.nan.xyz/fonts/?ref=lorcandempsey.net)), small independent foundries with one or a few designers (e.g. [Connary Fagen](https://connary.com/?ref=lorcandempsey.net), [Flavia Zimbardi](https://flaviazim.com/?ref=lorcandempsey.net)), established boutique design houses (e.g. Klim, [Dalton Maag](https://www.daltonmaag.com/library?ref=lorcandempsey.net)), and multi-faceted foundries with large catalogs (e.g. [Canada Type](https://canadatype.com/?ref=lorcandempsey.net), [Indian Type Foundry](https://www.indiantypefoundry.com/?ref=lorcandempsey.net), [Typotheque](https://www.typotheque.com/?ref=lorcandempsey.net)); there are distributors who work with independent foundries, as an alternative to the big distributors (e.g. [I love Typography](https://fonts.ilovetypography.com/?ref=lorcandempsey.net) or [Vllg](https://vllg.com/fonts?ref=lorcandempsey.net) or [Type Network](https://store.typenetwork.com/?ref=lorcandempsey.net)). Foundries provide retail fonts for licensing and also do significant custom work (see the very nice [work](https://www.pentagram.com/work/syracuse-university/story?ref=lorcandempsey.net) commissioned by Syracuse University, with a lovely back story extending into special collections, for example, or the striking [RISD](https://identity.risd.edu/how-we-look?ref=lorcandempsey.net) font, apt, it seems to me, for a design school). There are associations, prizes, and venues for discussion and commentary. Aspects of this ecosystem are described further below.
### Values
[The 2023 PRINT Typography Report: Why Type Empathy Matters2023 has barely come into vision, but a new objective in typography is clear—type empathy.PRINT MagazineMeg Farmer](https://www.printmag.com/typography/the-2023-print-typography-report-why-type-empathy-matters/?ref=lorcandempsey.net)
Emphasises the increasing importance of values-driven work and choices
As in any community of reasonable scale, there are oppositional and alternative perspectives, complaints about commercial enclosure of classical work (e.g. by Monotype), disagreement about licensing and royalty terms, concern about hegemonic, western views (*Helvetica* is universal or neutral? Really?). There is a history of hidden labor by women (see the marvellous [Ange Degheest](https://eyeondesign.aiga.org/presenting-ange-degheest-pioneering-20th-century-female-type-designer/?ref=lorcandempsey.net) project), [lack](https://www.itsnicethat.com/features/global-type-female-representation-in-type-design-nadine-chahine-chantra-malee-aasawari-kulkarni-insights-graphic-design-200323?ref=lorcandempsey.net) of women in leadership positions, and low [numbers](https://library.typographica.org/black-type-designers-foundry-owners?ref=lorcandempsey.net) of designers of color.
There is also great variability of font availability across cultural and language groups, which has an impact on cultural expressiveness and identity (see this intersection of the personal, professional and political in a [discussion](https://www.youtube.com/watch?v=1YmyY22hpOg&ref=lorcandempsey.net) of the politics of Arabic type design by designer Nadine Chahine, now the CEO of [I Love Typography](https://fonts.ilovetypography.com/?ref=lorcandempsey.net)). There are mission-directed sites such as the marvelous libre and open source collection at [Velvetyne](https://velvetyne.fr/?ref=lorcandempsey.net), home of typographic quirk and quiddity, and the [Bye Bye Binary Type Library](https://typotheque.genderfluid.space/?ref=lorcandempsey.net).
The Harvard Library has a useful and untypical (for a library) set of typographic [guidelines](https://library.harvard.edu/brand-guidelines?ref=lorcandempsey.net) which visibly and effectively carry through into their website. They use two very common Google fonts, *Lora* and, again, *Montserrat* (in a minor fork, *Trueno*). As of this writing, Google Fonts notes that [Lora](https://fonts.google.com/specimen/Lora/about?ref=lorcandempsey.net) is used in over 2M websites, and [Montserrat](https://fonts.google.com/specimen/Montserrat/about?ref=lorcandempsey.net) in over 16M. The Google Fonts API served up Montserrat an eye-brow raising 9.44 billion times in the week this was written. Harvard uses Fontlibrary and Fontsquirrel (part of the Dribble group), two sources of free fonts, to download the fonts, and these fonts are also available in other places. So the actual deployment numbers will be higher that those reported by Google.
The Harvard Library website notes that the fonts are open source and as such aligned with one of its guiding principles. However, are there other open source choices than two of the most common fonts in the world, part, some might argue of a Google monoculture? And I also wonder if a better values choice would be to put some design money into the creative ecosystem? In what I expect was a purposeful decision, The Mellon Foundation uses the highly acclaimed *Halyard* ('[a bold visionary statement](https://typographica.org/typeface-reviews/halyard/?ref=lorcandempsey.net)') on its website , "a robust sans designed by the first Black American type designer Joshua Darden (with Eben Sorkin and Lucas Sharp)" \[[Pentagram](https://www.pentagram.com/work/the-mellon-foundation/story?ref=lorcandempsey.net)\]. I noticed a while ago that The National Museum of African American History & Culture uses another super-family, [*Freight*](https://nmaahc.si.edu/about/brand-guide/typography?ref=lorcandempsey.net), designed by Darden.
[Letters for a LibraryThere are designers and creatives who are capable of delving into many analog mediums at once (this maybe calligraphy, or origami, or whatever.) Their projects seem to have exciting new approaches, ofAlphabettesNamrata Goyal](https://www.alphabettes.org/letters-for-a-library/?ref=lorcandempsey.net)
Typography site **Alphabettes.org* : "Our loose network is here to support and promote the work of all women and nonbinary people in our fields." This is an article by Namrata Goyal, the creator of **Biblio*, one of the very few typefaces created for or by a library.
### Fonts for free and fee
> Avoiding (for now) the enormous topic of free fonts and their effect on the type design scene, license-free typefaces play their role in servicing big and small studios. The result, however, is bland, overly familiar and encourages a world of identical brand identities and graphic design projects. // Alternatives to Google Fonts — Part 1, [Pangram Pangram](https://pangrampangram.com/blogs/journal/alternatives-to-google-fonts?ref=lorcandempsey.net)
There are four principal models for acquiring fonts. As noted above, there is great variety within this ecosystem:
1. **Free fonts**: There are many sources of free fonts, notably of course Google Fonts. Fontshare from Indian Type Foundry is another convenient source, including their own fonts and a curated selection of others. There are many other free fonts from other sources. I mention some below.
2. **Subscription-based services**: In this model a subscription allows you to access a library of fonts for use for as long as the subscription lasts. Adobe Fonts is a major subscription service, with a large library of commercial fonts. Monotype also offers this option, as does Typesquare, a service of major Japanese foundry, Morisawa, and others.
3. **Purchasing licenses**: Licences to use fonts can be purchased from individual foundries, from indie aggregators such I Love Typography and some others mentioned above, from aggregators of creative assets such as Envato Elements, or from font aggregators such as Monotype, Fontspring (now part of Dribble), and others. Typically, you can buy typefaces by a font family or by single instances (e.g. Regular, Regular Italic, Bold, Bold Italic, ...). Prices vary considerably from a few dollars from some of the creative asset aggregators to much higher for designer or classic fonts.
4. **Custom fonts:** You may commission custom fonts from a foundry or designer.
It is worth noting the not uncommon sentiment from (commercial) designer foundry Pangram Pangram above. Some will argue that paid-for fonts will deliver higher quality and distinctiveness. And that free fonts lead to bland uniformity. Discussion of free tends to be bound up with the influence of Google in this way, given the number of fonts it makes available, the convenience of using them, and, very importantly, its great distribution power. I was interested to discover that Google Fonts predominate font usage in national libraries, and I return to the question of font monoculture below.
There is also concern that money may not be flowing into the system, supporting designers. Foundries balance retail work with custom work, and interest in branding and identity is strong. I have not seen any economic analyses of the sector, but new foundries, designers and fonts emerge regularly.
There are many fine free fonts. And given the vast range of paid for fonts it is inevitable that some are less good than others. Needs also vary: sometimes designer distinction may be wanted, sometimes something reliable which blends in.
While Google creates or subsidizes the creation of free fonts, there are many other sources. Of course, many of these will become available on Google Fonts (and elsewhere). Here are some examples:
- **Tech companies** are a major source of open and free fonts. They may develop them for their own purpose and then release them for general use. For example, *IBM Plex* is a comprehensive and much admired super-family of fonts (sans, serif, mono) which has a fascinating [microsite](https://www.ibm.com/plex/?ref=lorcandempsey.net) describing design choices in the context of IBM history and brand, and locating choices in an overall typographic design space. *DM* (sans, serif, mono) is a font family created by British designer foundry Colophon for Google's DeepMind, and you will see *DM Serif* used in the national libraries of Finland and Spain. *DM Serif* is based on *Source Serif Pro*, Adobe's first open source font, which is widely used (it is often paired with Klim's *Sohne* in *Medium* posts). Its companion is *Source Sans Pro* and there is a nice monospace also. (*Source Sans Pro* is used on the websites of the National Library of Mexico and Biblioteca Nazionale Centrale di Firenze. The National Library of Israel uses *Assistant* which is a Hebrew [match](https://medium.com/@bennathan/assistant-family-hebrew-typeface-design-for-google-fonts-6cb64efab555?ref=lorcandempsey.net) of *Source Sans Pro*.) *Fira Sans* and *Zilla Slab* were commissioned by Mozilla (they are currently used on the NISO website). More recently, GitHub [released](https://github.blog/2022-12-02-introducing-mona-sans-and-hubot-sans/?ref=lorcandempsey.net) the very nice *Mona Sans* and *Hubot Sans*. These fonts tend to be of good quality and are widely used; some of them feature high in Google's usage statistics. There are many more.
- Another source is **public** or national bodies. I discuss some national examples below (e.g. the very popular *PT Sans* and *Serif,* and *Public Sans*). *Plus Jakarta Sans* is a non-national [example](https://www.tokotype.com/custom-fonts/plusjakarta?ref=lorcandempsey.net) with interesting variations, and there is a Dubai [font](https://dubaifont.com/?ref=lorcandempsey.net) (developed by Nadine Chahine, who [talks](https://www.designweek.co.uk/issues/15-21-may-2017/monotypes-nadine-chahine-designing-new-typeface-dubai/?ref=lorcandempsey.net) interestingly about rationale, tone, the relationship between Arabic and Latin, and the political protests about the font).
- And then, many **organizations** who commission fonts may make them more widely available. This is the case with Brill, the publishers, [Cooper Hewitt](https://www.cooperhewitt.org/open-source-at-cooper-hewitt/cooper-hewitt-the-typeface-by-chester-jenkins/?ref=lorcandempsey.net), the BBC, the French national research organization, INRIA, Radio Canada, the brand agency, [Instrument](https://www.instrument.com/about/?ref=lorcandempsey.net), and many, many others.
**Note:** [Brill](https://brill.com/page/BrillFont/brill-typeface?ref=lorcandempsey.net) is especially interesting from a library point of view. It commissioned the typeface from [Tiro Typeworks](http://www.tiro.com/?ref=lorcandempsey.net), who specialise in multiscript work. A design goal is to successfully accommodate the full range of challenges that might be encountered by a scholarly publisher in the humanities, across current and historic languages, philosophical logic, and so on. And to do so in a way that allows a consistent 'Brill' look and feel.
And finally, the font comparison may not always be carried out on a level playing field. Not unnaturally, a website that goes for a designer or distinctive font will probably also invest in design, which enhances the overall contribution of the font and displays it to advantage. Free fonts may end up quite often on sites with less distinctive design attention.
### A note on three distribution platforms
While there are various distributors, three mentioned above are very important: Google, Adobe and Monotype. Each has a different business model and position. These companies have scaled their platforms to the network level where they effectively aggregate supply (fonts, foundries, designers) and demand (designers, publishers, website managers, and so on). We see the platform concentration familiar from the dynamics of the web in general. While their market power may be resisted by some foundries, they channel a large part of font distribution.
Google in particular also exercises considerable cultural power: the free and convenient distribution of fonts has created considerable conformity of use around its popular fonts. Font identification app *Fonts Ninja* [claims](https://t.co/vFIDkeTdbS?ref=lorcandempsey.net) that 65% of websites use one of the following four fonts: *Roboto*, *Montserrat*, *Open Sans*, and *Lato,* the four most popular fonts on Google. (Perhaps we could call them collectively ROMoLa - Roboto, Open Sans, MOntserrat, LAto.)
Google Font analytics ... big numbers
As noted **Google Fonts** plays a central role in the provision of free and open source fonts, as part of their general work in making the web work more effectively. They developed *Roboto* for their own use, as part of Android. *Noto Sans* is a part of an ambitious project by Google and partners to develop aesthetically aligned and consistently rendering fonts for all scripts represented in Unicode, and there is now an extensive family of *Noto* fonts covering many languages and scripts. And they subsidize the creation of many other fonts where they see gaps.
> However, **there is nothing wrong about Open Sans specifically,** my point is that it’s just **overused,** it’s the new Arial. And I guess most people might use it just because it’s popular. When something has so many views it can’t be bad, right? Wrong! Choosing a typeface is an opportunity for your website, app or digital product to show personality, be memorable and stand out among its competition. And if you’re just using Open Sans you’re missing out on that. // Stop using Open Sans – Why your font choice matters, [Oliver Schöndorfer](https://pimpmytype.com/open-sans/?ref=lorcandempsey.net)
Adobe occupies a different space in virtue of the centrality of *Creative Cloud* applications in the creative, web design, publishing and related industries. Users of those applications have subscription access to the wide collection of commercial and other fonts in **Adobe Fonts**.Adobe also creates its own fonts (*Adobe Originals*), and is responsible for the widely used open source *Source* family of fonts (sans, serif, code).
**Monotype** is different again in that its focus is on font creation and distribution: it is a typeface company. It is a major foundry which at once does custom typographic work, designs retail fonts, and aggregates fonts from others for distribution. It has actively consolidated other foundries and distributors over the years, including Linotype, Fontshop, Berthold, ITC, Bitstream and so on. Recently it acquired leading independent foundry Hoefler&Co which publishes *Gotham* among others. In this way, Monotype has acquired the IP of many classic typefaces which are not available in other ways. They maintain several storefronts including myfonts.com, fontshop, and fonts.com.
### A note on discovery
Such is the range of fonts and distribution channels there is a general discovery issue. And this is why there is a huge volume of guidance and commentary about choice of fonts. There are endless lists of free fonts, or general fonts, often in the form of thinly disguised product marketing.
This favors the large platforms, especially Google and Adobe (for those with a subscription) as non-initiate users are unlikely to look beyond them. Google is open and readily available. And Adobe is similarly available directly in the workflow to many in the creative, publishing, web design and related industries in virtue of the widespread use (and subscription to) Adobe products. It also makes it difficult for independent foundries to avoid placing their fonts with the large platforms. Unless they have achieved considerable success and associated gravitational attraction it is difficult for small or independent foundries to attract purchasers independently.
## Some national library examples (CENL)
I have mentioned individual national library choices at various places throughout this piece. I have not systematically looked at all national libraries, but I have looked at a lot! In general, the popular Google Fonts (Roboto, Montserrat, *etc.*) seem to be used by a majority.
In a modest effort to reduce some of the randomness in my exploration, I did look through all the libraries on the CENL (Conference of European National Libraries) membership [list](https://www.cenl.org/member-libraries/?ref=lorcandempsey.net). Rather than enumerating the various uses of Google Fonts, I thought I would mention the ones that used different or distinctive fonts. I am not saying that these are necessarily the best (however one defines that), and I have referenced other CENL libraries in other places.
As discussed above, Kris Sowersby wondered if fonts could have a regional or national accent: "The British have Gill Sans, the French, Garamond, the Italians, Bodoni, the Swiss, Helvetica." What about the national libraries in the countries that Sowersby mentions? Is there a national dimension in their font choices, do they have a regional accent? The answer to the question seems to be: *mostly not*. I cover all the countries in Sowersby's list below, including Germany and Italy even though they are indeed using Google fonts.
##### The British Library
The British Library has an extensive [website](https://www.bl.uk/?ref=lorcandempsey.net). It uses *Arial* throughout. See Sowersby's description of *Arial* above: 'It's boring but it works.'
*Gill Sans* is certainly seen as characteristically British. However, given [biographical](https://www.worldcat.org/title/20013396?ref=lorcandempsey.net) revelations about Gill, it may not be thought to be an appropriate choice for a national institution. Maybe [*Johnston*](https://en.wikipedia.org/wiki/Johnston%5F%28typeface%29?ref=lorcandempsey.net) might be apt, the font used on the London Underground. Edward Johnston was a mentor of Gill's and several modern interpretations of the font exist (including *Hoxton North* by the foundry Northern Block, located in the North of England). Elsewhere there is a rich legacy in *Caslon*, *Baskerville* or, in what would be a nice move, the [work](https://www.a2-type.co.uk/search?q=margaret+calvert&ref=lorcandempsey.net) of Margaret Calvert (who jointly designed fonts used in British road, rail and underground). And of course, more than one can be used. However, as I note in conclusion below, identity is not singular.
I recently read about the typeface created for Jony Ives' company, [LoveFrom](https://www.lovefrom.com/?ref=lorcandempsey.net). It is based on *Baskerville* and is used in some quite lovely work which the [article](https://www.fastcompany.com/90888571/jony-ive-spent-the-last-4-years-perfecting-his-typeface-heres-why-hell-never-be-done?ref=lorcandempsey.net) references. Perhaps The British Library could commission the person who did so much to shape design in the 21st Century (while creating Apple's hugely impactful products), and whose company font is based on *Baskerville,* to develop a font for the ***British*** Library?
An earlier article ... showing font in use
**Note:** The designers researched background for *LoveFrom Serif* in Cambridge University Library, and some pictures of Baskerville's metal punches are reproduced in the article. Reading the background stories on fonts it is interesting how much time designers spend in libraries and archives researching antecedents and influences.
> Reading the background stories on fonts it is interesting how much time designers spend in libraries and archives researching antecedents and influences.
##### The National Library of the Czech Republic
The National Library of the Czech Republic uses a mix of *Arial* and *Tusar Deco*. Upon investigation, I was very interested to discover that [*Tusar Deco*](https://www.stormtype.com/typefaces/2035?ref=lorcandempsey.net) was a variation of *Tusar*, a typeface by the well known Storm Type Foundry, which was in turn was a recreation of *Tusarova antikva.* The latter was the only typeface created in the 1920s by Slavoboj Tusar, the brother of a former Czech prime minister. Storm have several historical recreations, connecting to earlier periods in Czech history. František Štorm has a very interesting historical and personal statement on the website (dated 2015). He talks about digitizing the "masterpieces of our national typographic tradition" dating from before the iron curtain. He also talks about the "emotional impact" of a typeface, alongside its functionality, and its ability to contribute to a unique identity.
> Typefaces have their souls much like drawings, paintings or music. Latin alphabet is nothing but a composition of fine-tuned elements, orchestrated with passion. The strongest imperative in today's design is originality, and as there are thousands of indistinguishable fonts out there, we should ask for unique typefaces. // [Storm Type Foundry](https://www.stormtype.com/about%5Fus?ref=lorcandempsey.net)
Of course, not everybody who looks at the National Library will grasp this background, but the font is distinctive, and connects in an interesting way with a broader history. I know little about the history or about how Tusar the designer was perceived. However, I had thought I might see more examples like this, where there was some local cultural connection. It would be nice to swap in a better substitute for *Arial* to complement *Tusar*!
**Tusar Deco*
##### Royal Danish Library
I was curious what motivated the choices on the The Royal Library website. They use two typefaces with some personality which support the library well without being intrusive or overly familiar. The dominant font on the home page and used throughout for headings is [*Noway*](https://www.atipofoundry.com/fonts/noway?ref=lorcandempsey.net)*,* a tidy sans serif distributed by Atipo, a Spanish foundry with a novel 'pay what you want' model. It originated in a commission to design a font for Luton Airport (both signage and identity), so shares something with *Frutiger*. In fact, in [discussing](https://www.atipofoundry.com/custom/london-luton-airport?ref=lorcandempsey.net) the design they compare it with both *Frutiger* and *DIN*, and characterise it in this way: "the font has a technical air but with a humanist beat which, together with rounded ends, make it friendly; with personality without being strident." I think this is a reasonable description and I was struck with the very clean design when I first opened the site. They have altered the tracking to tighten it up a little.
It is paired with *Noticia Text* which is used for body text. This is a slab serif which is [available](https://fonts.google.com/specimen/Noticia+Text/about?ref=lorcandempsey.net) on Google Fonts, and which is designed for running text.
##### Deutsche Nationalbibliothek (DNB)
Sowersby does not mention Germany in the list above. If he had he might have suggested [*DIN*](https://www.typewolf.com/din?ref=lorcandempsey.net) as the national typeface, now widely used in many interpretations, or something in a *Blackletter* style.
I have already discussed the DNB above, as a good example of how Google fonts can work well with good typographical layout. I described there some things that I liked about the site. *Montserrat* is the font used on the home page and for headings. *Crimson Text* is used for body text throughout the site (it is also on Google Fonts). This is a so-called 'old style' font, a serif font influenced by classic *Garamond* typefaces and developed for book production. I think it works well, and pairs well for the headings. And as noted above, I like the use of color throughout.
##### The National Library of Estonia
I was excited to see that the library has actually got its own font, [*RaRa Sans*](https://defol.io/kuldmuna/2021-rara-sans?ref=lorcandempsey.net), one of the very few commissioned – or intended for use – by a library. It is a geometric sans by Estonian designer, Anton Koovit, based on his retail font, *UCity Pro* (see the background [here](https://fatype.com/typefaces/ucity/font%5Finfo?ref=lorcandempsey.net)). The site also uses the very popular font [*Inter*](https://rsms.me/inter/?ref=lorcandempsey.net)for body text *(*whose designer*,* Rasmus Andersson, is from nearby Sweden), available on Google Fonts and elsewhere. There is also a third sans serif font in use: *PT Root UI*. This is from well-known Russian foundry ParaType.
**RaRa Sans* (heading under feature picture) and **PT Root UI* mixed in first two panels. **RaRa Sans* in third.
I wondered why they mixed three sans serif fonts in this way. I was pleased to come across another library custom font, and would be interested to know more about the rationale and intended use. *RaRa Sans* seems to be used throughout in the Digilab [area](https://digilab.rara.ee/?ref=lorcandempsey.net) (third panel) and, I thought, looks well. I thought the body text looked small, but then I often do.
Incidentally, I discovered that the library is in the process of moving to a new building, which will be more open, social and welcoming.
> Spending time in the library should be more exciting and natural than hanging out in a shopping centre. A warm, bright and interesting place in the cold season, pleasantly cool and ever interesting in the warm summer. // [RaRa](https://www.rara.ee/en/reconstruction/?ref=lorcandempsey.net)
##### Bibliothèque nationale de France
The BNF was a little surprising to me. The heading or display font on the [home page](https://www.bnf.fr/fr?ref=lorcandempsey.net) is *Gabriela Stencil*, an elegant, high contrast font used in all caps. It is a font in the so-called *Didone* style, reminiscent of the 19th Century (as is *Bodoni*, Sowersby's Italian mention). It is quite distinctive and the atmosphere it creates is one of ... luxury and style? The stencil feature amplifies this feeling. However, the text font used is *Roboto*, the Google font created for Android, and, as noted, one of the most widely used fonts in the world (the condensed version is used). This seems strange given the historic position of the BNF in relation to the advances of Google, but also in the context of French particularism and national identity. Perhaps it is just an acknowledgement of the increasingly default nature of Google fonts on the web? As noted, Roboto is very widely used in national libraries. That said, while the text is small, it is used with good spacing and hierarchy.
##### The National Library of Ireland
The National Library of Ireland unveiled a welcome web redesign recently. They actually use two fonts from Klim. The headings are *Feijoa Display,* the earliest Klim font, and the body text is, yes, you guessed it .... *National*!
From the Klim [description](https://klim.co.nz/retail-fonts/feijoa/?ref=lorcandempsey.net) of *Feijoa*: "It’s based on the principle that ‘a straight line is a dead line’, which explains the warm, curvaceous nature of the individual letterforms." I think this works well with *National* throughout the website and indeed this is the pairing [recommended](https://www.typewolf.com/feijoa?ref=lorcandempsey.net) on *Typewolf*.
It is also somewhat on trend*.* See the use of *Clearface* in the National Library of Norway. I mentioned the Mellon Foundation and Ithaka - each uses a flowing serif font for headings. And more generally, one can see the influence of *arts and crafts*, *art deco* and *art nouveau* appear more frequently?
They have an issue which is common for universities, who often have crests or logos with more 'classic' fonts than they choose for the website. There is a something of a clash between the website fonts and the logotype here, which is really in a rather different style. Perhaps the rounded 'n' is meant to echo the dome of the building (a feature of the rather fine logo that this replaced several years ago)?
##### Italy
Italy has two central national libraries, one each in Florence and Rome. The [Biblioteca Nazionale Centrale di Firenze](https://www.bncf.firenze.sbn.it/?ref=lorcandempsey.net) uses a popular Google Font, *Playfair Display*, for headings, paired with Adobe-created and open sourced *Source Sans Pro* for text. *Source Sans Pro* also features highly on the list of most popular Google Fonts above. This is another site using mainstream free fonts to good effect. There is no specifically Italian emphasis as far as I can see. At the time of writing, I could not connect to the national central library in Rome.
##### The National Library of Luxemburg
OK, so this is a highlight for me. After all that *Roboto* and *Open Sans* my heart leapt to see this:
Lettering on entrance, signage, web font
Simply great. The library worked with Pentagram to develop identity, signage and font. The headline font is quirky and readable, unique and memorable. It is also used in signage and is designed in a modular way as the signs are put together from alphabetical/numeric cubes. I really like that the typeface on the [website](https://bnl.public.lu/en.html?ref=lorcandempsey.net) and the physical signage are continuous with each other in this way, underlining the singular identity and service. Then, they don't just opt to pair it with *Roboto* or *Montserrat.* They use a classic sans serif, *Trade Gothic,* with nice typographic variation (compressed in navigation header, occasionally all caps, white space). *Trade Gothic* dates in its original version from 1948, and so preceded *Helvetica* and *Univers* and their influence.
Pentagram has a [description](https://www.pentagram.com/work/bibliotheque-nationale-du-luxembourg?ref=lorcandempsey.net) of the design project, including some lovely pictures (I hope it is OK that I copied two of the pictures above).
> I really like that the typeface on the website and the physical signage are continuous with each other in this way, underlining the singular identity and service.
##### The National Library of Norway
Three typefaces
The picture above shows three typefaces: *Roboto* (in the header navigation bar on top and in the button, and used throughout) and then two serif fonts, *Clearface* (the headline, and used for headings) and *GT Sectra* (the text paragraph, and used throughout for text and some headings). *Clearface* is a font originally designed in the early 20th Century by prolific American designer Morris Fuller Benton. Wikipedia [notes](https://en.wikipedia.org/wiki/Clearface?ref=lorcandempsey.net) the influence of the arts and crafts movement, drawing attention to its "warm curving design." Incidentally, Kris Sowersby [writes](https://klim.co.nz/blog/family-design-information/?ref=lorcandempsey.net) admiringly about *Clearface* as he introduces a modern reworking of it.
*GT Sectra* is a designer font from Swiss foundry Grilli Type. I like its jagged calligraphic appearance. I think it provides really nice readable text here. One of the nice things about foundry fonts is that they are often accompanied by detailed accounts of origin, influence, design considerations, and so on. Here is Grilli Type [discussing](https://www.grillitype.com/blog/typeface-stories/gt-sectra-development?ref=lorcandempsey.net) the development of GT Sectra.
I am also increasingly drawn to expressive and readable serif fonts, in both headings and especially in body text. My sense is that this may become more common, as welcome relief from the predominance of sans serif on the web? They go with storytelling. Speaking of which, I liked the *Stories from the collections* [section](https://www.nb.no/historier-fra-samlingen/?ref=lorcandempsey.net) of the site which includes a section on *Norwegian black metal*.
I also really liked how they used a monospace font (*Courier*) in the special feature on the *Norwegian black metal* exhibition.
I have a soft spot for monospace fonts
So, a lot to like here. What is slightly puzzling to me is why they use two serif fonts, each individually nice, but which may clash a little, and especially given those serif choices, why they didn't go for a more distinctive sans serif than *Roboto* (acknowledging that it is perfectly functional here).
##### The National Library of Poland
The National Library of Poland also uses Klim fonts. It uses a wide version of *Söhne* in all caps for feature text (see the boxed text in the screenshot). It uses *Tiempos Headline* for headings, a serif font designed for editorial purposes which looks well here. And then it uses *Roboto* for text. Again, it is interesting to note the popularity of *Roboto* for text, and to wonder if they considered using either of the two other fonts for this.
##### The National Library of Sweden: interesting in multiple ways
I really liked this site and think it is more generally interesting and indicative of a broad trend. The library leads with a slab serif, [*Sentinel*](https://www.typewolf.com/sentinel?ref=lorcandempsey.net), from prestige foundry Hoefler&Co (now owned by Monotype). It is paired with Google's *Roboto*.
A website which tells a story
I have recently been arguing that library websites should move from a focus on interactivity to a focus on storytelling, as part of an overall **relational turn**. I think that this website moves in that direction. I like that it separates clearly its services to the public from its services to other libraries. It leads with a large picture on the home page and uses pictures regularly throughout. There is a consistent grid structure.
And the font actually works very well. It reminds me very much of a newspaper font (the *Guardian*, for example, uses a slab serif). Its lines are of contrasting thickness. In fact, its weight seems to lend some weight to the story it is telling. It works in headings (which look like newspaper headlines) and in text.
It is strong enough to help knit the website into a coherent layer which opens out to other resources when necessary. Sometimes, in contrast, library websites can seem to be a thin signposting layer which sits on top of other resources.
And although the *Sentinel* font may not have particular Swedish resonance (that I know of), the site itself communicates strongly about what it has to offer and its contribution. The font alone is not creating the whole effect, but it supports it, with an even, unifying, and consistently strong presence.
Incidentally, I also like the logotype here. It is distinctive but unobtrusive, it is visible but does not set up a separate focal point.
> I have recently been arguing that library websites should move from a focus on interactivity to a focus on storytelling, as part of an overall relational turn.
##### Bibliothèque nationale suisse
OK, so maybe the [Swiss National Library](https://www.nb.admin.ch/snl/fr/home.html?ref=lorcandempsey.net) is using *Helvetica*? Well, not quite. It is using *Frutiger Neue*. Swiss type designer, Adrian Frutiger, is seen by many as the preeminent (Western) type designer of the 20th Century (maybe alongside Matthew Carter, designer of Microsoft fonts *Georgia* and *Verdana*, among many others, and also the wonderful MIT logo and the custom *Yale* font). Frutiger is responsible for many typefaces, but is probably most well known for three which span the main sans serif categories. The pioneering *Univers* is a so-called neo-grotesque, similar to and a near contemporary of, *Helvetica*. *Avenir* is a geometric sans, and I discussed its use on the *Five Books* site above. *Frutiger* is a humanist font based on work originally done for signage at Charles de Gaulle Airport. It is widely admired, and Wikipedia [references](https://en.wikipedia.org/wiki/Frutiger%5F%28typeface%29?ref=lorcandempsey.net) this remark by type designer, entrepreneur and font guru Erik Spiekermann: "the best general typeface ever."
So this seems a very apt choice for this particular library, in a country with a special place in (Western) typeface history. Of the national libraries mentioned so far, this is the one whose font choice has most lined up to some aspect of national identity.
## National fonts, guidelines and cultural expressiveness
### Government developed fonts
There does not seem to be a general pattern here, and while there are some national fonts they seem to have different motivations. By 'national' here, I am meaning fonts developed, commissioned or authorised by a government. This is different from Sowersby's sense of 'national' in my opening discussion where he wondered if some fonts had a national or regional 'accent', *Gill Sans* and British, for example.
I wondered whether some proportion of national libraries might use a national font of some sort. Of the libraries I looked at (and I did not look at every national library), the only one I found was Thailand. I was surprised to see that the National Library of Russia used *Open Sans*, given the *PT* fonts mentioned below.
I became aware of the Moldovan national font, *Onest*, recently. I do not know enough to comment on the motivation or the scale of its aspiration:
> This is the first Moldovan made typeface created with a mere goal — to make communication between the state and the citizen honest and understandable.
>
> Also, to bring Moldova's image closer to that of a modern, open country. // [Onest](https://onest.md/en?ref=lorcandempsey.net)
*Onest* is openly available for others to use. It is not currently used in the Moldovan National Library which uses Microsoft font *Calibri*.
*DIN* is an interesting case here. It is seen as quasi-official or national as it was initiated and managed by the national German standards organization (DIN) and was widely deployed in Germany. Developed for industrial and signage purposes, it was simple, engineered and legible. Following some more modern interpretations, it has become very popular and there are now many derivatives and reinterpretations. While it has a slight tech vibe, it is also used much more widely. It is the font of choice of ETH Zurich for example, and a version is used in the National Library of Iceland [website](https://landsbokasafn.is/?ref=lorcandempsey.net).
*Public Sans* is a font developed for the [United States Web Design System](https://public-sans.digital.gov/?ref=lorcandempsey.net). It is actually used by the National Library of Finland where it is paired quite effectively with the strong *DM Serif* for headings. However, *Public Sans* is not used by the Library of Congress which uses *Roboto Slab* for headings, pairing it with the very commonly used Google Font *Open Sans* for text.
There is also actually a national Finnish font, developed to promote Finnish exports. It is called [*Finlandica*](https://fonts.google.com/specimen/Finlandica/about?ref=lorcandempsey.net)and is available on Google Fonts: "Like the Finnhorse it's a breed suitable both as riding horse and workhorse."
There is a collection of [Thai](https://en.wikipedia.org/wiki/National%5FFonts?ref=lorcandempsey.net) national fonts, developed by the government to reduce reliance on overseas commercial sources. Updated versions are available on Google fonts. One does appear to be in use at the National Library of Thailand.
Maybe most interestingly here, I note the very popular *Public Type* (PT) superfamily developed under the *Public Types of the Russian Federation* initiative: *PT Sans* and *PT Serif*. These are [created](https://company.paratype.com/pt-sans-pt-serif?ref=lorcandempsey.net) by Russian foundry ParaType with "the financial support of the Federal Agency for Press and Mass Media." Interestingly, *PT Mono* was added with support from Google Fonts. The principal developer is Alexandra Korolkova (see this [interview](https://www.myfonts.com/pages/newsletters-cc-201410?ref=lorcandempsey.net) from 2014 describing the development of the PT family and other work).
*PT Sans* is used on the [website](https://www.landesbibliothek.li/?ref=lorcandempsey.net) of the National Library of Lichtenstein. *PT Serif* is used to good effect on the [website](https://www.lnb.lt/?ref=lorcandempsey.net) of the National Library of Lithuania where it is paired with the rounded geometric sans, *Quicksand*. All available through Google Fonts and elsewhere.
### National guidelines
Many university library readers will be very aware that their website needs to follow university style guidelines. There may in fact be no discretion at the library level. I wondered whether there might be a similar situation with national libraries and the government authorities within which they sat. However, this wasn't immediately obvious and would take some time to investigate.
It is the case with Library and Archives Canada, for example. LAC uses the very popular Google Font *Lato* for headings, and *Noto Sans* for text. I was a little surprised when I first saw this, thinking they might have gone with more distinctive – or perhaps Canadian – options. However, it actually inherits those decisions from the federal government, of which it is a part. Then of course, one might ask a similar question about choices at the federal level. The federal [mandate](https://design.canada.ca/styles/typography.html?ref=lorcandempsey.net) includes *Noto Sans* for text. I did wonder if this was because of *Noto*'s support of indigenous languages, but no mention is made of that aspect in the mandate (see *BC Sans* in the next section).
### Cultural diversity and expressiveness
> Ultimately, typefaces are a kind of "critical infrastructure" for each culture, a medium to store and transmit emotional tone. // Susanna Zaraysky, [Google](https://blog.google/outreach-initiatives/accessibility/preserving-endangered-languages-noto-fonts/?ref=lorcandempsey.net)
Fonts make language visible, and allow it to be shared across space and time. To achieve that, there is quite a bit of work which we may now take for granted in, say, an English, French or German linguistic context, involving orthographies, scripts, Unicode, Opentype, fonts and a variety of professional skills.
I was very struck by this passage, noting how making typographic choices based on aesthetic considerations depends on an evolved language infrastructure that is variably available across language groups.
> Many of these majority languages, such as English, are well supported by hundreds or thousands of typefaces. In addition, Unicode compliance and interoperability are increasingly taken for granted by users. Speakers of minority languages served by minority scripts and orthographies are not afforded the same ease of use. This typographical abundance leaves users free to focus their attention on typeface aesthetics, with choices motivated more by visual appeal and less by whether the typeface actually supports the characters and diacritics of a given orthography. Aesthetic considerations remain a luxury that most speakers of the Indigenous languages spoken in North America regrettably still cannot afford, as many of these languages struggle to identify a handful of typefaces that accommodate the core needs of their orthographies. For speakers of such languages, visual ‘look and feel’ unfortunately often remains a secondary consideration, outweighed by the central importance of correct formatting and Unicode compliance. // Julia Schillo, Mark Turin. Applications and innovations in typeface design for North American Indigenous languages. Book 2.0, 2020, 10 (1), pp.71-98\. \[[pdf](https://shs.hal.science/halshs-03083476/file/2020Schillo%5FTurin%5Ftypeface%5F2020.pdf?ref=lorcandempsey.net)\]
There are important cultural and political issues associated with fonts, and their availability is bound up with cultural diversity and expressiveness. Issues include:
- In a digital environment, we depend on language infrastructure to communicate: Unicode implementation, fonts, keyboards, software. If those are limited or absent, it restricts use and may further endanger a minority language, or cut it off from more general use, written transmission, and so on.
- If font choices are limited, it limits cultural diversity and expressive potential (Nadine Chahine discusses this in relation to the recent historical evolution of Arabic typefaces in this video [The politics of Arabic type design](https://www.youtube.com/watch?v=1YmyY22hpOg&t=1s&ref=lorcandempsey.net), which, as I noted above, is an intersection of the political, personal and professional. From the description: "**Typefaces embody the unspoken messages in our words**, which is why it’s more important than ever that there is plurality for the voices of the Arabic culture.")
- Multiscript typefaces support consistent treatment across different languages. The *Public Type* *(PT)* family was developed in Russia to meet the objective that "the nationwide font must be multilingual" to provide consistent typography across 70+ Russian languages "based on the Cyrillic alphabet." Working across scripts also raises issues for international communication, something that has become more of an issue as trans-national commercial and cultural activity has increased. Pfizer's use of *Noto* is mentioned below as an example. One emphasis here is to try to give equal standing to the history and characteristics of various writing systems, rather than leading with a Latin-centric approach.
> There is new demand for global scripts in Southeast Asia, China, Japan and the Persian Gulf region, where corporations including AirBnb and Uber make use of culturally-specific fonts in their communications with a growing network of sophisticated customers. And to put it bluntly, type design has long had a Eurocentric focus that excluded many of the world’s writing systems. // Is It Possible to Create A Truly Global Typeface? Angela Riechers talking to Peter Bi'lak, Typotheque, [AIGA Eye on Design](https://eyeondesign.aiga.org/ping-a-single-type-family-for-three-billion-native-speakers/?ref=lorcandempsey.net)
Some foundries have specialised in working across scripts and languages. The [Rosetta Type Foundry](https://rosettatype.com/?ref=lorcandempsey.net) creates "original fonts for a polyphonic world" which has "enabled people to read better in their native language." Ek Type is an Indian foundry which works across Indian languages (an example of their work presented [here](https://design.google/library/anek-multiscript?ref=lorcandempsey.net), together with a discussion of the design challenges of creating a multiscript typeface). Typotheque also specialises in support for multiple languages. Writing about the launch of support across a range of fonts for Georgian, they [note](https://www.typotheque.com/fonts/georgian?ref=lorcandempsey.net) "At Typotheque, we understand that typography is not just a commercial enterprise, but that it also has a cultural and political component."
Here are some Canadian examples, to indicate the type of work that is going on in our 'polyphonic' world. Not at all complete, just indicative. Canada is interesting given the diversity of languages, the intersection of the practical and the political, and given how choice and availability of writing system (and font) entails questions of identity, colonialism, and, in recent years, reconciliation.
**Note:** For some background, see this [list](https://guides.library.ubc.ca/xwi7xwaresearchguide?ref=lorcandempsey.net) of X̱wi7x̱wa Research Guides, notably the [one](https://guides.library.ubc.ca/aboriginallanguages?ref=lorcandempsey.net) on language. X̱wi7x̱wa Library is a "centre for academic and community Indigenous scholarship" at UBC.
- The quote at the beginning of this section is from a [description](https://blog.google/outreach-initiatives/accessibility/preserving-endangered-languages-noto-fonts/?ref=lorcandempsey.net) of *Noto*, with a little about current status. I was interested to [read](https://www2.gov.bc.ca/gov/content/governments/services-for-government/policies-procedures/bc-visual-identity/bc-sans?ref=lorcandempsey.net) about [*BC Sans*](https://www2.gov.bc.ca/gov/content/governments/services-for-government/policies-procedures/bc-visual-identity/bc-sans?ref=lorcandempsey.net), which adapts *Noto Sans* with additional characters and syllabic glyphs. It is is mandated on British Columbia websites as part of the goal to support Indigenous languages. As noted above, *Noto* aims to provide fonts for all scripts covered in Unicode.
- A pragmatic blog [post](https://blog.mothertongues.org/tutorial-syllabics-fonts/?ref=lorcandempsey.net) on the *Mother Tongues* website explains the tofu phenomenon (*Noto*\=no tofu), shows how easy it is to embed Google fonts, and enumerates some typefaces to display Cree syllabics. It also links to [*Languagegeek Fonts*](https://www.languagegeek.com/font/fontdownload.html?ref=lorcandempsey.net#AlgonAndInu), the source of relevant fonts including *Aboriginal Sans* and *Aboriginal Serif,* as well as historical and technical commentary on fonts and writing systems.
- Langara College (Vancouver, Canada) commissioned TypeTogether to extend the *Adelle* font to to support Halkomelem, a language spoken in British Columbia. They worked with the xʷməθkʷəy̓əm (Musqueam) people on this and on the name of the College. Langara's visual identity [guidelines](https://langara.ca/departments/communications-marketing/brand/visual-identity.html?ref=lorcandempsey.net) note: "To acknowledge our connection with Musqueam, we have designed a Musqueam name logo to work in family with our Langara logo. Neither of these logos are primary nor secondary. They are equal."
> Vanessa Campbell of the Musqueam Language Office said, *“This collaboration with Langara and TypeTogether is an opportunity to share our culture and language with more people in Vancouver. It also helps to revitalize our language by giving us additional tools to share it with others.”* // [TypeTogether](https://www.type-together.com/langara?ref=lorcandempsey.net)
- In parallel, also in Vancouver, Tiro Typeworks, who specialise in multilingual font work, worked with *Whitney*, the font in use at the University of British Columbia, to create *Whitney Salishan*. *Whitney* is a commercial font from Hoefler&Co who may market a commercial version of *Whitney Salishan*.
> “We first started creating Whitney-based characters for hən̓q̓əmin̓əm̓ words on an as-needed basis for plaques and other special projects around 2014,” says Matt Warburton, design manager for UBC Brand and Marketing. “It became clear that we needed a sans-serif font—a custom version of Whitney that would let us typeset in the language of the Indigenous partners and hosts of UBC.” // Reconciliation, one keystroke at a time, [*UBC News*](https://news.ubc.ca/2023/05/31/new-ubc-font-whitney-salishan-language/?ref=lorcandempsey.net)
**Note:** From [*Wikipedia*](https://en.wikipedia.org/wiki/Halkomelem?ref=lorcandempsey.net)*:* hǝn̓q̓ǝmin̓ǝm̓, or Musqueam, is a dialect of the language Hul'qumi'num, whose anglicized name is Halkomelem.
- Typotheque worked collaboratively with Nattilik and Carrier communities in Canada to prepare Syllabics support across several [fonts](https://www.typotheque.com/fonts/syllabics?ref=lorcandempsey.net), which required proposed additions to Unicode. The video about the project shows the cultural and emotional importance of having appropriate font support.
Emotional, cultural, practical
I think this is a fascinating topic, and I included these very brief notes here given the importance of cultural expressiveness to national libraries. That said, I am not very knowledgeable about how active national libraries are here, although it seems to me that it should be an area of attention and support. I was very impressed to see some support for minority and other languages on the National Library of Sweden site:
[](https://www.kb.se/languages/davvisamegiella.html?ref=lorcandempsey.net)
Davvisámegiella (nordsamiska)
[Applications and innovations in typeface design for North American Indigenous languagesIn this contribution, we draw attention to prevailing issues that many speakers of Indigenous North American languages face when typing their languages, and identify examples of typefaces that have been developed and harnessed by historically marginalized language communities. We offer an overview o…HAL SHS : Sciences humaines et socialesJulia Schillo](https://shs.hal.science/halshs-03083476/?ref=lorcandempsey.net)
Scholarly review ... from which the extended quote above comes
## Final reflections: Google, monoculture, identity
Font designer, accountant, and Velvetyne founder, Frank Adebiaye, has an interesting [meditation](https://www.nan.xyz/txt/the-tragicomedy-of-digital-fonts/?ref=lorcandempsey.net) on the ascent of Google Fonts and its impact on the font ecosystem.
> Google on the other end is the gateway to a web and mobile-first digital experience. In that scheme type is only a part of this digital experience. Iconic typefaces are not that important in this new context.
He points to how *Roboto* was released in an early form which was iteratively improved. He also notes how *Gotham* lost out to *Montserrat*. He points to the use of *Noto* by Pfizer and highlights how they [talk](https://id.pfizer.com/pfizer-login?ref=lorcandempsey.net) about it: "Accessible, inclusive, and free. The future will be written in *Noto Sans*."
> Noto Sans is a font designed for tomorrow. Developed by Google to internationalize the internet, it is philosophically and aesthetically aligned with the new Pfizer.
This raises a very pragmatic issue. Pfizer operates globally, and needs to communicate across languages and scripts. The investment by Google in *Noto* facilitates this.
These fonts are **familiar, accessible and available**. For this reason, it might make sense for national libraries to use them.
On the other hand, I have noted the pushback against uniformity above. Does accepting the Google Fonts default options create a monoculture on the web? I was certainly surprised at the extent to which national libraries have adopted *Roboto* and the other top Google fonts. If you had to pick any organization that constitutionally was not aligned with a global monoculture then that organization might be a national library?
I wondered whether conversely the national library might select a font that aligned in some way with **identity**. But we [know](https://www.lorcandempsey.net/memory-institutions-redux/) that national identity is complex and not singular. I very much liked that the Swiss National Library uses *Frutiger*, but maybe, somebody might argue, [*Lucette*](https://www.futurefonts.xyz/alice-savoie/lucette?ref=lorcandempsey.net) would be a good choice, a font that commemorates Lucette Girard who worked with Frutiger and other male designers (when it is completed). I wondered above about some options for the British Library, but were they more English than British perhaps, excluding Wales, Scotland and Northern Ireland? How would one encompass Britishness today? I was intrigued by the choice of *Tusar Deco* by the National Library of the Czech Republic but I have no sense of how it would be seen across the population.
> I also queried whether conversely the national library might select a font that aligned in some way with **identity**. But we know that national identity is complex and not singular.
I loved the Luxembourg **custom font**. I was also pleased to see *RaRa Sans* from the Estonian National Library. I would like to see more national libraries commission fonts for use which align with how they would like to present themselves and which say something about their roles and the traditions they represent. As I noted, companies regularly commission custom typefaces. Universities also commission typefaces, Yale perhaps most famously, but also others; I mention Syracuse and RISD above. I am interested that more national libraries do not do this. Perhaps it appears profligate or maybe unnecessary? I think it would be good to consider supporting the local type industry in this way.
Finally, of course, there are wonderfully creative designers and foundries. It would be nice to see more **distinctive** fonts on national library websites, and interesting pairings. It would be good to see national libraries invest modestly in the creative industries in this way, and to think about storytelling, business and values issues as they do so. Of course, given the dominance of Google Fonts on national library sites, I realise that this may not be a shared view!
## Coda
In thinking about a national library which seems well placed to commission a custom font, I presumptuously mentioned the British Library, as I had been very taken by Jony Ive's work with LoveFrom.
[](https://www.lovefrom.com/?ref=lorcandempsey.net)
The LoveFrom font, in the logotype designed by Peter Saville
The National Library of Argentina also comes immediately to mind. There is a concentration of interesting local resources which span typographic expertise and awareness, relevant custom work, and Argentinian context. Of course, as Sowersby points out, we live in a network world (and it was Pentagram that worked with the National Library of Luxembourg), but it is also good to look to the resources close by.
*Montserrat* is named for a district in Buenos Aires and the principal designer is [Julieta Ulanovsky](https://linktr.ee/julietaulanovsky?ref=lorcandempsey.net), based there. Buenos Aires is also home to several notable foundries. For example Huerta Tipográfica and Omnibus-Type, each of which has several popular fonts available on Google Fonts. Among others, Omnibus-Type is creator of the popular [Archivo](https://www.omnibus-type.com/fonts/archivo/?ref=lorcandempsey.net) font, and [Museo Moderna](https://www.omnibus-type.com/fonts/museomoderno/?ref=lorcandempsey.net), specially created for the Buenos Aires Museum of Modern Art. Huerta Tipográfica created *Alegreya,* discussed above, and the lovely *Piazzolla* (see [review](https://pimpmytype.com/piazzolla/?ref=lorcandempsey.net) on PimpMyType, which actually currently uses *Piazzolla* itself for body text). It is also the home of foundry Sudtipos, which has done some high profile [custom work](https://www.sudtipos.com/customs?ref=lorcandempsey.net), and the practice of [Fer Cozzi](https://fercozzi.com/?ref=lorcandempsey.net). The prolific [Impallari Type](https://www.impallari.com/?ref=lorcandempsey.net) is based in Rosario, who is the creator of, or collaborator on, many popular Google Fonts. These include the revivals *Libre Franklin* and *Libre Baskerville* (used by the Royal Library in Belgium), as well as popular fonts such as *Encode Sans* (used by the University of Washington) and *Cabin* (used by The Bodleian Libraries at Oxford). They have experience of national work as *Public Sans*, the US Government font, is based on *Libre Franklin*. PampaType is based in Córdoba, Argentina, and among other things has typefaces named after that somewhat well known librarian of the National Library, Jorge Luis Borges (perhaps a sans addition to the family might be the basis for a national library font?), and also created [*Reforma*](https://www.pampatype.com/reforma?ref=lorcandempsey.net), the very interesting custom typeface for the University of Córdoba \[[review](https://pimpmytype.com/reforma/?ref=lorcandempsey.net)\]. The University of Buenos Aires is a center of typographic education.
The National Library of Argentina currently uses *Roboto* throughout. There is a lot of opportunity to explore some other avenues!
**Picture:** I took the feature picture in Dublin during IFLA 2022\.
**Note:** There is a note about fonts used on this site in the [*Colophon*](https://www.lorcandempsey.net/colophon/).
**Updates:** Added FontLibrary to Fontsquirrel (both sources of free fonts), 15 June '23\.
##
### Generative AI and large language models: background and contexts
URL: https://www.lorcandempsey.net/intro-gen-ai/
Last updated: 2024-02-21T01:31:51.000Z
Google has a [Machine learning glossary](https://developers.google.com/machine-learning/glossary?ref=lorcandempsey.net) which includes succinct definitions with some expansion for developers. The New York Times recently provided a more high level and shorter [list](https://www.nytimes.com/article/ai-artificial-intelligence-glossary.html?ref=lorcandempsey.net) of terms in generative AI.
## The age of generative AI and the large language model
It looks like generative AI will be broadly deployed across industries, in education, science, retail and recreation. Everywhere.
Current discussion ranges from enthusiastic technology boosterism about complete transformation to apocalyptic scenarios about AI takeover, autonomous military agents, and worse.
Comparisons with earlier technologies seem apt, but also vary in suggested importance. (Geoffrey Hinton wryly observed in an interview that it may be as big as the invention of the wheel.)
Like those earlier technologies - the web or mobile, for example - progress is not linear or predictable. It will be enacted in practices which will evolve and influence further development, and will take unimagined directions as a result. It has the potential to engage deeply with human behaviours to create compounding effects in a progressively networked environment. Think of how mobile technologies and interpersonal communications reshaped each other, and how the app store or the iPod/iPhone evolved in response to use.
> The click-bait is strong, and it can be difficult to separate the spectacular but short-lived demonstration from the real trend.
It is likely to become a routine part of office, search, social and other applications. And while some of this will appear magic, much of it will be very mundane.
The [outcomes](https://www.repository.cam.ac.uk/items/6e251bf7-2cb2-4ff9-ab7d-3091ad13e802?ref=lorcandempsey.net) will be productive, and also problematic. There is the dilution of social trust and confidence as synthesized communication or creation is indiscernible from human forms; there is the social impact on employment, work quality and exploited labor; there is potential for further concentration of economic or cultural power; there is propagation of harmful and historically dominant perspectives.
This is a descriptive overview of some current developments in generative AI, looking broadly. The treatment is necessarily limited, mostly by my own comprehension. My purpose is to provide some ****background context** for those working in libraries as a ****prelude** to discussing ****library issues and directions** in subsequent posts. While I mention libraries and related areas occasionally, I have deliberately kept this general and not picked up on library implications. The immediate prompt (sic) was that I was writing a note on libraries and AI, in part based on a [recent](https://www.youtube.com/watch?v=uQ7ckgVfGRQ&ref=lorcandempsey.net) [presentation](https://figshare.com/articles/presentation/Evolving%5Flibrary%5Fdiscovery%5F10%5Fdirections/22213861?ref=lorcandempsey.net) on discovery, and I realised I needed to know more about some of the background myself.
There is of course now a large technical and research literature, as well as an avalanche of popular exposition and commentary in text, podcasts, and on YouTube. The click-bait is strong, and it can be difficult to separate the spectacular but short-lived demonstration from the real trend.
Accordingly, I include quite a few links to further sources of information and I also quote liberally. Much of what I discuss or link to will be superseded quickly.
Do [get in touch](https://www.lorcandempsey.net/contact/) if you feel I make an error of judgement or emphasis.
- [Brief orientation](https://www.lorcandempsey.net/p/2fd4d55c-021b-488c-be5d-a016771b45fa/#brief-orientation)
- [Three strands in current evolution and debate](https://www.lorcandempsey.net/p/2fd4d55c-021b-488c-be5d-a016771b45fa/#three-strands-in-current-evolution-and-debate)
- 1.[ Major attention and investment](https://www.lorcandempsey.net/p/2fd4d55c-021b-488c-be5d-a016771b45fa/#%E2%91%A0-major-attention-and-investment)
- 2.[ Rapid continuing evolution](https://www.lorcandempsey.net/p/2fd4d55c-021b-488c-be5d-a016771b45fa/#%E2%91%A1-rapid-continuing-evolution)
- 3.[ Social concerns](https://www.lorcandempsey.net/p/2fd4d55c-021b-488c-be5d-a016771b45fa/#%E2%91%A2-concerns)
- [Conclusion](https://www.lorcandempsey.net/p/2fd4d55c-021b-488c-be5d-a016771b45fa/#conclusion)
This is a long post! The sections (above) can be read independently and there is more detail in the table of contents. There are quite a few examples in **Section one* if you want to skim or jump for example.
## Brief orientation
### Large language model
ChatGPT rests on a large language model. A large language model (LLM) is a neural network which is typically trained on large amounts of Internet and other data. It generates responses to inputs ('prompts'), based on inferences over the statistical patterns it has learned through training.
This ability is used in applications such as personalization, entity extraction, classification, machine translation, text summarization, and sentiment analysis. It can also generate new outputs, such as poetry, code and, alas, content marketing. Being able to iteratively process and produce text also allows it to follow instructions or rules, to pass instructions between processes, to interact with external tools and knowledge bases, to generate prompts for agents, and so on.
This ability means that we can use LLMs to manage multiple interactions through text interfaces. This potentially gives them compounding powers, as multiple tools, data sources or knowledge bases can work together iteratively ... and is also a cause of concern about control and unanticipated behaviors where they go beyond rules or act autonomously.
LLMs accumulate knowledge about the world. But their responses are based on inferences about language patterns rather than about what is 'known' to be true, or what is arithmetically correct. Of course, given the scale of the data they have been trained on, and the nature of the tuning they receive, they may appear to know a lot, but then will occasionally fabricate plausible but fictitious responses, may reflect historically dominant perspectives about religion, gender or race, or will not recognise relevant experiences or information that has been suppressed or marginalized in the record.
I liked this succinct account by Daniel Hook of *Digital Science*:
> What can seem like magic is actually an application of statistics – at their hearts Large Language Models (LLMs) have two central qualities: i) the ability to take a question and work out what patterns need to be matched to answer the question from a vast sea of data; ii) the ability to take a vast sea of data and “reverse” the pattern-matching process to become a pattern creation process. Both of these qualities are statistical in nature, which means that there is a certain chance the engine will not understand your question in the right way, and there is another separate probability that the response it returns is fictitious (an effect commonly referred to as “hallucination”). // [Daniel Hook](https://www.digital-science.com/tldr/article/tinker-researcher-prompter-wizard/?ref=lorcandempsey.net)
And here is a more succinct [statement](https://writings.stephenwolfram.com/2023/02/what-is-chatgpt-doing-and-why-does-it-work/?ref=lorcandempsey.net) by Stephen Wolfram from his extended discussion of ChatGPT: '... it’s just saying things that “sound right” based on what things “sounded like” in its training material.'
I used 'text' above rather than 'language.' Language is integral to how we think of ourselves as human. When we talk to somebody, our memories, our experiences of being in the world, our reciprocal expectations are in play. Removing the human from language has major cultural and personal ramifications we have not yet experienced. I was struck by this sardonically dystopian discussion of AI a while ago in a post on the website of the writing app *iA*. It concludes with brief poignant comments about language as a human bridge and about what is lost when one side of the bridge is disconnected.
[AI and the End of WritingSoon, we won’t need to write much any longer. Artificial Intelligence will do it for us.iAOliver Reichenstein](https://ia.net/topics/the-end-of-writing-ia-on-ai?ref=lorcandempsey.net)
### Generative Pre-trained Transformer
ChatGPT galvanized public attention to technologies which had been known within labs and companies for several years. GPT refers to a family of language models developed by OpenAI. Other language models have similar architectures. GPT-4, the model underlying ChatGPT is an example of what has come to be called a **foundation model**.
> In recent years, a new successful paradigm for building AI systems has emerged: Train one model on a huge amount of data and adapt it to many applications. We call such a model a foundation model. // Center for Research on Foundation Models, [Stanford](https://crfm.stanford.edu/?ref=lorcandempsey.net)
It is useful to break down the letters in **GPT** for context.
- The 'g' is generative as in 'generative AI.' It underlines that the model generates answers, or new code, images or text. It does this by inference over the patterns it has built in training given a particular input or 'prompt.'
- The 'p' stands for 'pre-trained', indicating a first training phase in which the model processes large amounts of data without any explicit tuning or adjustment. It learns about patterns and structure in the data, which it represents as weights. In subsequent phases, the model may be tuned or specialised in various ways.
- The 't' in GPT stands for 'transformer.' Developed by Google in 2017, the transformer model is the neural network architecture which forms the basis of most current large language models (*Attention is all you need*, the [paper](https://arxiv.org/abs/1706.03762?ref=lorcandempsey.net) introducing the model). The transformer defines the learning model, and generates the parameters which characterise it. It is common to describe an LLM in terms of the number of parameters it has: the more parameters, the more complex and capable it is. Parameters represent variable components that can be adjusted as the model learns, during pre-training or tuning. Weights are one parameter; another important one is **embeddings**. Embeddings are a numerical representation of tokens (words, phrases, ...) which can be used to estimate mutual semantic proximity ('river' and 'bank' are close in one sense of 'bank', and more distant in another).
Three further topics might be noted here.
First, **emergent abilities**. It has been claimed that as models have scaled, unforeseen capabilities have emerged \[[pdf](https://arxiv.org/pdf/2206.07682.pdf?ref=lorcandempsey.net)\]. These include the ability to be interactively coached by prompts ('in context learning'), to do some arithmetic, and others. However, more recently these claims have been challenged \[[pdf](https://arxiv.org/pdf/2304.15004.pdf?ref=lorcandempsey.net)\], suggesting that emergent abilities are creations of the analysis rather than actual model attributes. This question is quite important, because emergent abilities have become a central part of the generative AI [narrative](https://hai.stanford.edu/news/ais-ostensible-emergent-abilities-are-mirage?ref=lorcandempsey.net), whether one is looking forward to increasing capabilities or warning against unpredictable outcomes. For example, the now famous [letter](https://futureoflife.org/open-letter/pause-giant-ai-experiments/?ref=lorcandempsey.net) calling for a pause in AI development warns against 'the dangerous race to ever-larger unpredictable black-box models with emergent capabilities.' *BIG-bench* is a cross-industry initiative looking at characterizing model behaviors as they scale and 'improve' \[[pdf](https://arxiv.org/pdf/2206.04615.pdf?ref=lorcandempsey.net)\]. I was amused to see this observation: 'Also surprising was the ability of language models to identify a movie from a string of emojis representing the plot.'
Second, **multimodal** models. Generative models are well established, if developing rapidly. Historically models may have worked on text, or image or some other mode. There is growing interest in having models which can work across modes. GPT-4 and the latest Google models have some multi-modal capability - they can work with images and text, as can, say, *Midjourney* or *DALL-E*. This is important for practical applications reasons (doing image captioning or text to image, for example). It also diversifies the inputs into the model. In an interesting development, Meta has [released](https://www.theverge.com/2023/5/9/23716558/meta-imagebind-open-source-multisensory-modal-ai-model-research?ref=lorcandempsey.net) an experimental multi-modal open source model, *ImageBind*, which can work across six types of data in a single embedding space: visual (in the form of both image and video); thermal (infrared images); text; audio; depth information; and movement readings generated by an inertial measuring unit, or IMU.
And third, **embeddings** and **vector databases**. Embeddings are important in the context of potential discovery applications, supporting services such as personalization, clustering, and so on. OpenAI, Hugging Face, Cohere and others offer embedding APIs to generate embeddings for external resources which can then be stored and used to generate some of those services. This has given some lift to vector databases, which seem likely to become progressively more widely used to manage embeddings. There are commercial and open source options (*Weaviate*, *Pinecone*, *Chroma*, etc.). Cohere recently made embeddings for multiple language versions of Wikipedia [available](https://txt.cohere.com/embedding-archives-wikipedia/?ref=lorcandempsey.net) on Hugging Face. These can be used to support search and other applications, and similarity measures work across languages.
LLMs do not have experiential knowledge of the world or 'common sense.' This touches on major research questions in several disciplines. Yejin Choi summarizes in her title: **Why AI Is Incredibly Smart — and Shockingly Stupid*.
## Three strands in current evolution and debate
I focus on three areas here: major attention and investment across all domains, rapid continuing evolution of technologies and applications, and social concerns about harmful or undesirable features.
### 1 Major attention and investment
Major attention and investment is flowing into this space, across existing and new organizations. Just to give a sense of the range of applications, here are some examples which illustrate broader trends.
- **Coaching and learning assistants**. Khan Academy has [developed](https://blog.khanacademy.org/harnessing-ai-so-that-all-students-benefit-a-nonprofit-approach-for-equal-access/?ref=lorcandempsey.net) *Khanmigo*, a ChatGPT based interactive tutor which can be embedded in the learning experience. They are careful to highlight the 'guardrails' they have built into the application, and are very optimistic about its positive impact on learning. It is anticipated that this kind of tutoring co-pilot may be deployed in many contexts. For example, Chegg has [announced](https://www.businesswire.com/news/home/20230417005324/en/Chegg-announces-CheggMate-the-new-AI-companion-built-with-GPT-4?ref=lorcandempsey.net) that it is working with GPT-4 to deliver *CheggMate*, "an AI conversational learning companion." This may have been a defensive move; it was also recently [reported](https://www.cnbc.com/2023/05/02/chegg-drops-more-than-40percent-after-saying-chatgpt-is-killing-its-business.html?ref=lorcandempsey.net) that Chegg's shares had dropped 40% given concerns about the impact of ChatGPT on its business. Pearson has [issued](https://www.standard.co.uk/business/pearson-takes-legal-action-over-use-of-its-content-to-train-ai-b1079807.html?ref=lorcandempsey.net) a cease and desist notice to an (unnamed) AI company who has been using its content, and has said it will train its own models.
- **Consumer navigation/assistance.** Expedia [has](https://www.expediagroup.com/investors/news-and-events/financial-releases/news/news-details/2023/Chatgpt-Wrote-This-Press-Release--No-It-Didnt-But-It-Can-Now-Assist-With-Travel-Planning-In-The-Expedia-App/default.aspx?ref=lorcandempsey.net) a two-way integration with ChatGPT - there is an Expedia plugin to allow ChatGPT to access Expedia details, and Expedia uses ChatGPT to provide enhanced guidance on its own site. Other consumer sites have worked with ChatGPT to provide [plugins](https://openai.com/blog/chatgpt-plugins?ref=lorcandempsey.net). Form filling, intelligent assistants, enquiry services, information pages, and so on, will likely see progressive AI upgrades. Wendy's has just [announced](https://www.theverge.com/2023/5/9/23716825/wendys-ai-drive-thru-google-llm?ref=lorcandempsey.net) a collaboration with Google to develop a chatbot to take orders at the drive-thru.
- **Competitive workflows/intelligence.** Organizations are reviewing operations and workflows, looking for efficiencies, new capacities, and competitive advantage. A couple of announcements from PWC provide an example. It [reports](https://www.pwc.com/us/en/about-us/newsroom/press-releases/pwc-us-makes-billion-investment-in-ai-capabilities.html?ref=lorcandempsey.net) it is investing over $1B in scaling its ability to support and advise clients in developing AI-supported approaches. It also recently [announced](https://www.pwc.com/gx/en/news-room/press-releases/2023/pwc-announces-strategic-alliance-with-harvey-positioning-pwcs-legal-business-solutions-at-the-forefront-of-legal-generative-ai.html?ref=lorcandempsey.net) an agreement with Harvey, a startup specialising in AI services to legal firms, to provide PWC staff with "human led and technology enabled legal solutions in a range of areas, including contract analysis, regulatory compliance, claims management, due diligence and broader legal advisory and legal consulting services." It will build proprietary language models with Harvey to support its business.
- **Content generation/marketing.** Linkedin now [uses](https://venturebeat.com/ai/how-linkedin-released-new-chatgpt-based-ai-tools-in-just-3-months/?ref=lorcandempsey.net) ChatGPT to "include generative AI-powered collaborative articles, job descriptions and personalized writing suggestions for LinkedIn profiles." The collaborative articles I have seen have been somewhat bland, which underlines a concern many have that we will be flooded by robotic text - in adverts, press releases, content marketing, articles - as it becomes trivially easy to generate text. Canadian company [Cohere](https://cohere.com/business?ref=lorcandempsey.net) offers a range of content marketing, search, recommendation, summarization services based on its language models built to support business applications.
- **Code.** The *GitHub Copilot*, which writes code based on prompts, is acclerating code development. You can also ask ChatGPT itself to generate code for you, to find mistakes or suggest improvements. Amazon has recently released [CodeWhisperer](https://www.theverge.com/2023/4/13/23681796/amazon-ai-coding-assistant-codewhisperer-microsoft?ref=lorcandempsey.net), a competitor, and made it free to use for individual developers. There has also been concern here about unauthorised or illegal reuse of existing code in training sets. Partly in response, [BigCode](https://www.bigcode-project.org/docs/about/mission/?ref=lorcandempsey.net) is an initiative by Hugging Face and others to develop models based on code which is permissively licensed and to remove identifying features. They have released some models, and describe the approach [here](https://arxiv.org/pdf/2305.06161.pdf?ref=lorcandempsey.net).
- **Productivity.** Microsoft is promising integration across its full range of products to improve productivity (please don't mention *Clippy*). Other apps will increasingly include (and certainly advertise) AI features - *Notion*, *Grammarly*, and so on.
- **Publishing.** The publishing workflow will be significantly modifed by AI support. A group recently [published](https://upstream.force11.org/an-initial-scholarly-ai-taxonomy/?ref=lorcandempsey.net) an interesting taxonomy of areas where AI would have an impact on scholarly publishing: Extract, Validate, Generate, Analyse, Reformat, Discover, Translate. A major question is the role of AI in the generation of submissions to publishers and the issues it poses in terms of creation and authenticity. It seems likely that we will see synthetic creations across the cultural genres - art, music, literature - which pose major cultural and legal questions.
- **Image generation.** Adobe is trialling *Firefly*, an 'AI art generator, as competition to Midjourney and others.' Adobe is training the application on its own reservoir of images, to which it has rights.
- **Google.** For once, Google is playing catchup and has released Bard, its chat application. It is interesting to note how carefully, tentatively almost, it describes its potential and potential pitfalls. And it has been cautious elsewhere. It is not releasing a public demo of [*Imagen*](https://imagen.research.google/?ref=lorcandempsey.net), its text to image service given concerns about harmful or inappropriate materials (see further below). However, Google's work in this area has been the subject of ongoing public debate. Several years ago, Timnit Gebru, co-lead of its internal Ethical Artificial Intelligence Team left Google after disagreement over a paper critiquing AI and language models (since [published](https://dl.acm.org/doi/10.1145/3442188.3445922?ref=lorcandempsey.net): *On the Dangers of Stochastic Parrots: Can Language Models Be Too Big?*). More recently, Geoffrey Hinton, neural network pioneer, [resigned](https://arstechnica.com/information-technology/2023/05/warning-of-ais-danger-pioneer-geoffrey-hinton-quits-google-to-speak-freely/?ref=lorcandempsey.net) from his position at Google so that he could more readily express his concerns about general AI directions, especially given increased commercial competition. And, from a different perspective, an [internal memo](https://www.semianalysis.com/p/google-we-have-no-moat-and-neither?ref=lorcandempsey.net) was recently leaked, documenting what it claimed to be technical and business competitive missteps by Google. Google has since [announced](https://www.theverge.com/2023/5/12/23721037/google-ai-progress-search-docs-starline-video-calls?ref=lorcandempsey.net) a broad range of AI augmentations across its product suite, including search.
- **Developers, apps.** As important as these more visible intitiatives is the explosion of general interest as individual developers and organizations experiment with language models, tools and applications. Check out the number of openly available language models on [Hugging Face](https://huggingface.co/models?ref=lorcandempsey.net) or the number of extensions/plugins appearing for applications (see the Visual Studio Code [Marketplace](https://marketplace.visualstudio.com/search?term=chatgpt&target=VSCode&category=All%20categories&sortBy=Relevance&ref=lorcandempsey.net) for example or Wordpress [plugins](https://wordpress.org/plugins/search/chatgpt/?ref=lorcandempsey.net)).
> It is likely to become a routine part of office, search, social and other applications. And while some of this will appear magic, much of it will be very mundane.
A discussion of applications in **research** and **education**, which of course are of critical importance to libraries, is too big a task to attempt here and is outside my scope. There is already a large literature and a diverse body of commentary and opinion. They are especially interesting given their knowledge intensive nature and the critical role of social trust and confidence. The Jisc *Primer* (see below) introduces generative AI before discussing areas relevant to education. It notes the early concern about assessment and academic integrity, and then covers some examples of use in teaching and learning, of use as a time-saving tool, and of use by students. AI is already broadly used in research disciplines, in many different ways and at different points in the life cycle, and this will continue to grow. This is especially the case in medical, engineering and STEM disciplines, but will be apply across all disciplines. See for example this discussion of the potential use of AI in computational social sciences \[[pdf](https://arxiv.org/pdf/2305.03514.pdf?ref=lorcandempsey.net)\]. A major issue is the transparency of the training and tuning models. Results need to be understandable and reproducible. A telling example of how books were represented in training data was provided in a paper with the arresting title: *Speak, Memory: An Archaeology of Books Known to ChatGPT/GPT-4* \[[pdf](https://arxiv.org/pdf/2305.00118.pdf?ref=lorcandempsey.net)\]. They found many books in copyright, and also found that some categories were disproportionately over-represented: science/fiction and fantasy and popular out of copyright works, for example. For cultural analytics research, they argue that this supports a case for open models with known training data.
[A Generative AI Primer - National centre for AIThe primer is intended as a short introduction to generative AI, exploring some of the main points and areas relevant to education, including two main elements: an introduction to Generative AI technology and the implications of generative AI on educationNational centre for AIMichael Webb](https://nationalcentreforai.jiscinvolve.org/wp/2023/05/11/generative-ai-primer/?ref=lorcandempsey.net)
The UK national agency for education support, Jisc, has a primer on Generative AI which has a special focus on applications in education. It plans to keep it up to date.
### 2 Rapid continuing evolution
The inner workings of these large models are not well understood and they have shown unpredictable results. OpenAI chooses a strange and telling analogy here as they describe the unsupervised LLM training - building the model is 'more similar to training a dog than to ordinary programming.'
> Unlike ordinary software, our models are massive neural networks. Their behaviors are learned from a broad range of data, not programmed explicitly. Though not a perfect analogy, the process is more similar to training a dog than to ordinary programming. An initial “pre-training” phase comes first, in which the model learns to predict the next word in a sentence, informed by its exposure to lots of Internet text (and to a vast array of perspectives). This is followed by a second phase in which we “fine-tune” our models to narrow down system behavior. // [OpenAI](https://openai.com/blog/how-should-ai-systems-behave?ref=lorcandempsey.net)
Here are some areas of attention and interest:
#### A diversity of models
OpenAI, Google and Microsoft and others are competing strongly to provide foundation models, given the potential rewards. Amazon has built out its offerings a little more slowly, and is partnering with various LLM developers. Startups such as AI21 Labs and Anthropicare also active. These will be important elements of what is a diversifying environment, and LLMs will be components in a range of platform services offered by these commercial players.
> OpenAI chooses a bizarre and telling analogy here - building the model is 'more similar to training a dog than to ordinary programming.'
There is also a very active interest in smaller models, which may be run in local environments, or are outside of the control of the larger commercial players. Many of these are open source. There has been a lot of [work](https://medium.com/geekculture/list-of-open-sourced-fine-tuned-large-language-models-llm-8d95a2e0dc76?ref=lorcandempsey.net) based on [LLaMA](https://ai.facebook.com/blog/large-language-model-llama-meta-ai/?ref=lorcandempsey.net), a set of models provided by Meta (with names like *Alpaca*, *Vicuna*, and .... *Koala*). Current licensing restricts these to research uses, so there has also been growing activity around commercially usable models. Databricks recently [released](https://www.databricks.com/blog/2023/04/12/dolly-first-open-commercially-viable-instruction-tuned-llm?ref=lorcandempsey.net) *Dolly 2.0*, an open source model which is available for commercial use. They also released the training data for use by others.
Mosaic ML, a company supporting organizations in training their models, has also developed and [released](https://www.mosaicml.com/blog/mpt-7b?ref=lorcandempsey.net) several open source models which can be used commercially. It has also released what it calls an *LLM Foundry*, a library for training and fine-tuning models. There is a base model and some tuned models. Especially interesting is *MPT-7B-StoryWriter-65k+*, a model optimised for reading and writing stories.
Many others are also active here and many models are appearing. This was highlighted in the infamous leaked *Google Memo.* It underlined the challenge of smaller open source LLMs to Google, stressing that it has no competitive moat, and that, indeed, the scale of its activity may be slowing it down.
> While our models still hold a slight edge in terms of quality, the [gap is closing astonishingly quickly](https://arxiv.org/pdf/2303.16199.pdf?ref=lorcandempsey.net). Open-source models are faster, more customizable, more private, and pound-for-pound more capable. They are [doing things with $100 and 13B params](https://lmsys.org/blog/2023-03-30-vicuna/?ref=lorcandempsey.net) that we struggle with at $10M and 540B. And they are doing so in weeks, not months. // [Google "We Have No Moat, And Neither Does OpenAI"](https://www.semianalysis.com/p/google-we-have-no-moat-and-neither?ref=lorcandempsey.net)
At the same time, many specialist models are also appearing. These may be commercial and proprietary, as in the PWC/Harvey and Bloomberg examples I mention elsewhere. Or they may be open or research-oriented, such as those provided by the [National Library of Sweden](https://blogs.nvidia.com/blog/2023/01/23/sweden-library-ai-open-source/?ref=lorcandempsey.net), or proposed by [Core](https://blog.core.ac.uk/2023/03/17/core-gpt-combining-open-access-research-and-ai-for-credible-trustworthy-question-answering/?ref=lorcandempsey.net) (an open access aggregator) and the [Allen Institute for AI](https://blog.allenai.org/announcing-ai2-olmo-an-open-language-model-made-by-scientists-for-scientists-ab761e4e9b76?ref=lorcandempsey.net). Intel and the Argonne National Laboratory have [announced](https://www.intel.com/content/www/us/en/newsroom/news/intel-delivers-ai-accelerated-hpc-performance.html?ref=lorcandempsey.net#gs.yg1xei) a series of LLMs to support the scientific research community, although not much detail is provided (at the time of writing). More general models may be also specialised through use of domain specific instruction sets at tuning stage. Google has [announced](https://www.theverge.com/2023/5/10/23718046/google-ai-palm-2-language-model-bard-io?ref=lorcandempsey.net) specialised models for cybersecurity and medical applications, for example, based on its latest *PaLM 2* model. Although it has not published many technical details, LexisNexis has [released](https://www.lexisnexis.com/community/pressroom/b/news/posts/lexisnexis-announces-launch-of-lexis-ai-commercial-preview-most-comprehensive-global-legal-generative-ai-platform?ref=lorcandempsey.net) a product, *Lexis+ AI*, which leverages several language models, including, it seems, some trained on Lexis materials.
So, in this emergent phase there is much activity around a diverse set of models, tools and additional data. A race to capture commercial advantage sits alongside open, research and community initiatives. Hugging Face has emerged as an important aggregator for open models, as well as for data sets and other components. Models may be adapted or tuned for other purposes. This rapid innovation, development, and interaction between models and developers sits alongside growing debate about about transparency (of training data among other topics) and responsible uses.
[List of Open Sourced Fine-Tuned Large Language Models (LLM)An incomplete list of open-sourced fine-tuned Large Language Models (LLM) you can run locally on your computerGeek CultureSung Kim](https://medium.com/geekculture/list-of-open-sourced-fine-tuned-large-language-models-llm-8d95a2e0dc76?ref=lorcandempsey.net)
A (currently) updated list of open source LLMs.
#### Refinement or specialization: Fine-tuning, moderation, and alignment
Following the 'unsupervised' generation of the large language model, it is 'tuned' in later phases. Tuning alters parameters of the model to optimise the performance of LLMs for some purpose, to mitigate harmful behaviors, to specialise to particular application areas, and so on. Methods include using a specialist data set targeted to a particular domain, provision of instruction sets with question/response examples, human feedback, and others. Retraining large models is expensive, and finding ways to improve their performance or to improve the performance of smaller models is important. Similarly, it may be beneficial to tune an existing model to a particular application domain. Developing economic and efficient tuning approaches is also an intense [R&D](https://arxiv.org/abs/2106.09685?ref=lorcandempsey.net) [focus](https://huggingface.co/blog/peft?ref=lorcandempsey.net), especially as more models targeted at lower power machines appear.
OpenAI highlights the use of human feedback to optimize the model.
> The data is a web-scale corpus of data including correct and incorrect solutions to math problems, weak and strong reasoning, self-contradictory and consistent statements, and representing a great variety of ideologies and ideas.
> So when prompted with a question, the base model can respond in a wide variety of ways that might be far from a user’s intent. To align it with the user’s intent within guardrails, we fine-tune the model’s behavior using reinforcement learning with human feedback ([RLHF](https://openai.com/research/learning-from-human-preferences?ref=lorcandempsey.net)). // [Open.AI](https://openai.com/research/gpt-4?ref=lorcandempsey.net)
OpenAI also published [safety standards ](https://openai.com/safety-standards?ref=lorcandempsey.net)and has a Moderation language model which it has also externalised to API users.
> The Moderation models are designed to check whether content complies with OpenAI's [usage policies](https://openai.com/policies/usage-policies?ref=lorcandempsey.net). The models provide classification capabilities that look for content in the following categories: hate, hate/threatening, self-harm, sexual, sexual/minors, violence, and violence/graphic. You can find out more in our [moderation guide](https://platform.openai.com/docs/guides/moderation/overview?ref=lorcandempsey.net). // [Open.AI](https://platform.openai.com/docs/models/moderation?ref=lorcandempsey.net)
OpenAI externalised the RLHF work to contractors, involving labor practices that are attracting more attention as discussed further below. Databricks took a 'gamification' approach among its employees to generate a dataset for tuning. *Open Assistant* works with its users in a crowdsourcing way to develop data for tuning \[[pdf](https://www.ykilcher.com/oa-paper?ref=lorcandempsey.net)\]. *GPT4All*, a chat model from Nomic AI, asks its users can it capture interactions for further training.
Tuning data is also becoming a sharable resource, and subject to questions about transparency and process. For example, Stable AI [reports](https://stability.ai/blog/stablevicuna-open-source-rlhf-chatbot?ref=lorcandempsey.net) how it has tuned an open source model, *StableVicuna*, using RLHF data from several sources, including Open Assistant.
> Reinforcement Learning by Human Feedback is just parenting for a supernaturally precocious child.
>
> — Geoffrey Hinton (@geoffreyhinton) [March 15, 2023](https://twitter.com/geoffreyhinton/status/1636110447442112513?ref%5Fsrc=twsrc%5Etfw&ref=lorcandempsey.net)
Tweet by Geoffrey Hinton - major figure in neural network development.
The question of 'alignment', mentioned in the OpenAI quote, is key, although use of the term is elastic depending on one's view of threats. Tuning aims to align the outputs of the model with human expectations or values. This is a very practical issue in terms of effective deployment and use of LLMs in production applications. Of course it also raises important policy and ethical issues. Which values, one might ask? Does one seek to remove potentially harmful data from the training materials, or try to tune the language models to recognise it and respond appropriately? How does one train models to understand that there are different points of view or values, and respond appropriately? And in an age of culture wars, fake news, ideological divergences, and very real wars, 'alignment' takes on sinister overtones.
This work sits alongside the very real concerns that we do not know enough about how the models work to anticipate or prevent potential harmful effects as they get more capable. Research organization Eleuther.ai initially focused on providing open LLMs but has pivoted to researching AI interpretability and alignment as more models are available. There are several organizations devoted to alignment research ([Redwood Research](https://www.redwoodresearch.org/?ref=lorcandempsey.net), [Conjecture](https://www.conjecture.dev/?ref=lorcandempsey.net)) and LLM provider Anthropic has put a special [emphasis](https://www.anthropic.com/index/core-views-on-ai-safety?ref=lorcandempsey.net) on safety and alignment. And several organizations more broadly research and advocate in favor of positive directions. [Dair](https://www.dair-institute.org/?ref=lorcandempsey.net) is a research institute founded by Timnit Gebru "rooted in the belief that AI is not inevitable, its harms are preventable, and when its production and deployment include diverse perspectives and deliberate processes it can be beneficial."
#### The return of content
Alex Zhavoronkov had an interesting piece in *Forbes* where he argues that content generators/owners are the unexpected winners as LLMs become more widely used. The value of dense, verified information resources increases as they provide training and validation resources for LLMs in contrast to the vast uncurated heterogeneous training data. Maybe naturally, he points to *Forbes* as a deep reservoir of business knowledge. He also highlights the potential of scientific publishers, *Nature* and others, whose content is currently mostly paywalled and isolated from training sets. He highlights not only their unique content, but also the domain expertise they can potentially marshall through their staffs and contributors.
[The Unexpected Winners Of The ChatGPT Generative AI RevolutionGenerative AI is taking the world by the storm with billions invested in infrastructure, data, and people. The ability to generate human-level responses to complex queries is expected to transform publishing. But publishers may be the biggest winners of the generative AI revolution.ForbesAlex Zhavoronkov, PhD](https://www.forbes.com/sites/alexzhavoronkov/2023/02/23/the-unexpected-winners-of-the-chatgpt-generative-ai-revolution/?sh=5687d1e212b0&ref=lorcandempsey.net)
*Nature* of course is part of the Holtzbrinck group which is also home to Digital Science. Zhavoronkov mentions Elsevier and Digital Science and notes recent investments which well position them now.
A good example from a different domain is provided by Bloomberg, which has released details of what it claims is the largest domain-specific model, BloombergGPT. This is created from a combination of Bloomberg's deep historical reservoir of financial data as well as from more general publicly available resources. It claims that this outperforms other models considerably on financial tasks, while performing as well or better on more general tasks.
> “The quality of machine learning and NLP models comes down to the data you put into them,” explained Gideon Mann, Head of Bloomberg’s ML Product and Research team. “Thanks to the collection of financial documents Bloomberg has curated over four decades, we were able to carefully create a large and clean, domain-specific dataset to train a LLM that is best suited for financial use cases. We’re excited to use BloombergGPT to improve existing NLP workflows, while also imagining new ways to put this model to work to delight our customers.” // [Bloomberg](https://www.bloomberg.com/company/press/bloomberggpt-50-billion-parameter-llm-tuned-finance/?linkId=207795121&ref=lorcandempsey.net)
The model will be integrated into Bloomberg services, and *Forbes* [speculates](https://www.forbes.com/sites/jamielsheikh/2023/04/05/the-chatgpt-of-finance-is-here-bloomberg-is-combining-ai-and-fintech/?sh=32e5b36f3081&ref=lorcandempsey.net) that it will not be publicly released given the competitive edge it gives Bloomberg. *Forbes* also speculates about potential applications: creating an initial draft of a SEC filing, summarizing content, providing organization diagrams for companies, and noting linkages between people and companies; automatically generated market reports and summaries for clients; custom financial reports.
Bloomberg claims that it achieved this with a relatively small team. This prompts the question about what other organizations might do. I have mentioned some in the legal field elsewhere. Medical and pharmaceutical industries are obvious areas where there is already a lot of work. Would IEEE or ACS/CAS develop domain specific models in engineering and chemistry, respectively?
Libraries, cultural and research organizations have potentially much to contribute here. It will be interesting to see what large publishers do, particularly what I call the **scholarly communication service providers** mentioned above (Elsevier, Holtzbrinck/Digital Science, Clarivate). These have a combination of deep content, workflow systems, and analytics services across the research workflow. They have already built out research graphs of researchers, institutions, and research outputs. The National Library of Sweden has been a pioneer also, building models on Swedish language materials, and cooperating with other national libraries. I will look at some initiatives in this space in a future post.
Specialist, domain or national data sets are are also interesting in the context of resistance to the 'black box' nature of the current foundation models, unease about some of the content of uncurated web scrapes, and concern about the WEIRD (Western, Educated, Industrial, Rich, Democratic) attributes of current models. We will likely see more LLMs specialised by subject, by country or language group, or in other ways, alongside and overlapping with the push to open models.
#### Platform competition
There is a major commercial focus on providing services which in different ways allow development, deployment and orchestration of language models. It is likely that on-demand, cloud-based LLM platforms which offer access to foundation models, as well as to a range of development, customization, deployment and other tools will be important. The goal will be to streamline operations around the creation and deployment of models in the same way as has happened with other pieces of critical infrastructure.
OpenAI has pushed strongly to become a platform which can be widely leveraged. It has developed API and plugin frameworks, and has adjusted its API pricing to be more attractive. It has a clear goal to make ChatGPT and related offerings a central platform provider in this emerging industry.
Microsoft is a major investor in OpenAI and has moved quickly to integrate AI into products, to release Bing Chat, and to look at cloud-based infrastructure services. Nvidia is also a big player here. Predictably, Amazon has been [active](https://aws.amazon.com/generative-ai/?ref=lorcandempsey.net). It recently launched [*Bedrock*](https://aws.amazon.com/bedrock/?ref=lorcandempsey.net) ("privately customize FMs with your own data, and easily integrate and deploy them into your applications") and [*Titan*](https://aws.amazon.com/bedrock/titan/?ref=lorcandempsey.net) (several foundation models), to work alongside *Sagemaker*, a set of services for building and managing LLM infrastructure and workflows. Fixie is a new [platform company](https://blog.fixie.ai/introducing-fixie-ai-a-new-way-to-build-with-large-language-models-d4e1aeee6b81?ref=lorcandempsey.net) which aims to provide enterprise customers with LLM-powered workflows integrating agents, tools and data.
Again, the commercial stakes are very high here, so these and other companies are moving rapidly.
The position of Hugging Face is very interesting. It has emerged as a central player in terms of providing a platform for open models, transformers and other components. At the same time it has innovated around the use of models, itself and with partners, and has supported important work on awareness, policy and governance.
It will also be interesting to see how strong the non-commercial presence is. There are many research-oriented specialist models. Will a community of research or public interest form around particular providers or infrastructure?
> Today we're thrilled to announce our new undertaking to collaboratively build the best open language model in the world: AI2 OLMo.
>
> Uniquely open, 70B parameters, coming early 2024 – join us
>
> — Allen Institute for AI (@allen\_ai) [May 11, 2023](https://twitter.com/allen%5Fai/status/1656697211345055752?ref%5Fsrc=twsrc%5Etfw&ref=lorcandempsey.net)
A modest aspiration: the best open language model in the world \[Tweet\]
#### Guiding the model: prompt engineering and in-context learning
'Prompt engineering' has also quickly entered the general vocabulary. It has been found that results can be interactively improved by 'guiding' the LLM in various ways, by providing examples of expected answers for example. Much of this will also be automated as agents interact with models, multiple prompts are programmatically passed to the LLM, prompts are embedded in templates not visible to the use, and so on. A prompt might include particular instructions (asking the LLM to adopt a particular role, for example, or requesting a particular course of action if it does not know the answer), context (demonstration examples of answers, for example), directions for the format of the response, as well as an actual question.
Related to this, a major unanticipated 'emergent ability' is the improvement in responses that can be achieved by '[in context learning](https://arxiv.org/pdf/2301.00234.pdf?ref=lorcandempsey.net)' : 'In context learning is a paradigm that allows language models to learn tasks given only a few examples in the form of demonstration.' It is 'in context' because it is not based on changing the underlying model, but on improving results in a particular interaction. The language model can be influenced by examples in inferring outputs. So, if you are asking it to develop a slogan for your organization, for example, you could include examples of good slogans from other organizations in the prompt.
A body of good practice is developing here, and, many guidelines and tools are emerging. Prompt engineering has been identified as a new skill, with learned expertise. It has also been recognized as analogous to coding - one instructs the LLM how to behave with sequences of prompts. (Although, again, bear in mind the remark above about training a dog!)
An important factor here is the size of the **context window**. The context window is the number of tokens (words or phrases) that can be input and considered at the same time by the LLM. One advance of GPT-4 was to enlarge the context window, meaning it could handle longer more complex prompts. However, recently we have seen major advances here. I note *MPT-7B-StoryWriter-65k+* elsewhere, which is optimised for working with stories and can accept 65K tokens, large enough, for example, to process a novel without having to break it up into multiple prompts. The [example](https://huggingface.co/mosaicml/mpt-7b-storywriter?ref=lorcandempsey.net) they give is of inputting the whole of *The Great Gatsby* and having it write an epilogue. Anthropic has announced that their *Claude* service now operates with a context window of 100k tokens. One potential benefit of such large context windows is that it allows single documents to be input for analysis - they give examples of asking questions about a piece of legislation, a research paper, an annual report or financial statement, or maybe an entire codebase.
[Prompt Engineering Guide – NextraA Comprehensive Overview of Prompt Engineering\-->](https://www.promptingguide.ai/?ref=lorcandempsey.net)
An overview of tools, guidelines and other resources produced by dair.ai
#### Building tools and workflows: agents
Discussion of agents is possibly the most wildly divergent in this space, with topics ranging from controlled business workflow solutions to apocalyptic science fiction scenarios in which autonomous agents do harm.
LLMs have structural limits as assistants. They are based on their training data, which is a snapshot in time. They are unconnected to the world, so they do not search for answers interactively or use external tools. They have functional limits, for example they do not do complex mathematical reasoning. And they typically complete only one task at a time. We are familiar, for example, with ChatGPT telling us that it is not connected to the internet and cannot answer questions about current events.
This has led to growing interest in connecting LLMs to external knowledge resources and tools. However, more than this, there is interest in using the reasoning powers of LLMs to manage more complex, multi-faceted tasks. This has led to the emergence of agents and agent frameworks.
In this context, the LLM is used to support a rules-based framework in which
- programming tools, specialist LLMs, search engines, knowledge bases, and so on, are orchestrated to achieve tasks;
- the natural language abilities of the LLM are leveraged to allow it to plan -- to break down tasks, and to sequence and connect tools to achieve them;
- the LLM may proceed autonomously, using intermediate results to generate new prompts or initiate sub-activities until it completes.
[Auto-GPT](https://github.com/Significant-Gravitas/Auto-GPT?ref=lorcandempsey.net) has galvanized attention here. Several other frameworks have also appeared and the term *Auto-GPT* is sometimes used generically to refer to LLM-based agent frameworks.
> This has led to growing interest in connecting LLMs to external knowledge resources and tools. However, more than this, there is interest in using the reasoning powers of LLMs to manage more complex, multi-faceted tasks. This has led to the emergence of agents and agent frameworks.
Langchain is a general framework and library of components for developing applications, including agents, which use language models. They [argue](https://docs.langchain.com/docs/?ref=lorcandempsey.net) that the most 'powerful and differentiated' LLM-based applications will be **data-aware** (connecting to external data) and will be **agentic** (allow an LLM to interact with its environment). Langchain facilitates the plug and play composition of components to build LLM-based applications, abstracting interaction with a range of needed components into Langchain interfaces. Components they have built include language and embedding models, prompt templates, indexes (working with embeddings and vector databases), identified agents (to control interactions between LLMs and tools), and some others.
Frameworks like this are important because they help facilitate the construction of more complex applications. These may be reasonably straightforward (a conversational interface to documentation or PDF documents, comparison shopping app, integration with calculators or knowledge resources) or may involve more complex, iterative interactions.
Hugging Face has also [introduced](https://huggingface.co/docs/transformers/transformers%5Fagents?ref=lorcandempsey.net) an agents framework, *Transformers Agent*, which seems similar in concept to LangChain and allows developers to work with an LLM to orchestrate tools on Hugging Face. This is also the space where [Fixie](https://www.fixie.ai/?ref=lorcandempsey.net) hopes to make an impact, using the capabilities of LLMs to allow businesses build workflows and processes. A marketplace of agents will support this.
[LangChain AI Handbook | PineconeThe handbook to the LangChain library for building applications around generative AI and large language models (LLMs).Pinecone](https://www.pinecone.io/learn/series/langchain/?ref=lorcandempsey.net)
This Handbook with parallel videos and code examples is a readable overview of LLM topics
At this stage, publicly visible agents have been relatively simple. The ability to use the language model to orchestrate a conversational interface, tools and knowledge resources is of great interest. We will certainly see more interactions of this kind in controlled business applications, on consumer sites, and elsewhere. Especially if they do in fact reduce 'stitching costs.' In a library context, one could see it used in acquisitions, discovery, inter library lending - wherever current operations depend on articulating several processes or tools.
#### Transparency and evaluation
As models are more widely used there is growing interest in transparency, evaluation and documentation, even if there aren't standard agreed practices or nomenclature. From the variety of work here, I mention a couple of initiatives at Hugging Face, given its centrality.
In a paper describing evaluation frameworks at Hugging Face, the authors provide some background on identified issues (reproducibility, centralization, and coverage) and review other work \[[pdf](https://arxiv.org/pdf/2210.01970.pdf?ref=lorcandempsey.net)\].
> Evaluation is a crucial cornerstone of machine learning – not only can it help us guage whether and how much progress we are making as a field, it can also help determine which model is most suitable for deployment in a given use case. However, while the progress made in terms of hardware and algorithms might look incredible to a ML practitioner from several decades ago, the way we evaluate models has changed very little. In fact, there is an emerging consensus that in order to meaningfully track progress in our field, we need to address serious issues in the way in which we evaluate ML systems \[....\].
They introduce [*Evaluate*](https://github.com/huggingface/evaluate?ref=lorcandempsey.net) (as set of tools to facilitate evaluation of models and datasets) and [*Evaluation on the hub*](https://huggingface.co/spaces/autoevaluate/model-evaluator?dataset=acronym%5Fidentification&ref=lorcandempsey.net) (a platform that supports largescale automatic evaluation).
Hugging Face also provide [*Leaderboards*](https://huggingface.co/spaces/autoevaluate/leaderboards?dataset=-any-&only%5Fverified=0&task=-any-&metric=exact%5Fmatch&ref=lorcandempsey.net), which show evaluation results. The [*Open LLM Leaderboard*](https://huggingface.co/spaces/HuggingFaceH4/open%5Fllm%5Fleaderboard?ref=lorcandempsey.net) lists openly available LLMs against a particular set of benchmarks.
In related work, Hugging Face have also developed a framework for documentation, and have implemented *Model Cards,* a standardized approach to description with supporting tools and guidelines. They [introduce](https://huggingface.co/blog/model-cards?ref=lorcandempsey.net) them as follows:
> Model cards are an important documentation framework for understanding, sharing, and improving machine learning models. When done well, a model card can serve as a *boundary object*, a single artefact that is accessible to people with different backgrounds and goals in understanding models - including developers, students, policymakers, ethicists, and those impacted by machine learning models.
They also provide a [review](https://huggingface.co/docs/hub/model-card-landscape-analysis?ref=lorcandempsey.net) of related and previous work.
> Since Model Cards were proposed by [Mitchell et al. (2018)](https://arxiv.org/abs/1810.03993?ref=lorcandempsey.net), inspired by the major documentation framework efforts of Data Statements for Natural Language Processing [(Bender & Friedman, 2018)](https://aclanthology.org/Q18-1041/?ref=lorcandempsey.net) and Datasheets for Datasets [(Gebru et al., 2018)](https://www.fatml.org/media/documents/datasheets%5Ffor%5Fdatasets.pdf?ref=lorcandempsey.net), the landscape of machine learning documentation has expanded and evolved. A plethora of documentation tools and templates for data, models, and ML systems have been proposed and developed - reflecting the incredible work of hundreds of researchers, impacted community members, advocates, and other stakeholders. //
Some of those working on the topics above were authors on the *Stochastic Parrot* paper. In that paper, the authors [talk](https://dl.acm.org/doi/10.1145/3442188.3445922?ref=lorcandempsey.net) about 'documentation debt', where data sets are undocumented and become too large to retrospectively document. Interestingly, they reference [work](https://arxiv.org/pdf/1912.10389.pdf?ref=lorcandempsey.net) which suggests that archival principles may provide useful lessons in data collection and documentation.
There is clear overlap with the interests of libraries, archives, data repositories and other curatorial groups in this area. In that context, I was also interested to see a group of researchers associated with Argonne National Laboratory [show](https://www.nature.com/articles/s41597-022-01712-9?ref=lorcandempsey.net) how the FAIR principles can be applied to language models.
Given the black box nature of the models there is also concerns about how they are used to guide decisions in important life areas open to bias - in law enforcement, education, social services, and so on. There may be very little understanding of how important decisions are being made. This is a regulatory driver as shown in this Brookings discussion of developments in California and elsewhere.
> Generally, the bills introduce new protections when AI or other automated systems are used to help make consequential decisions—[whether a worker receives a bonus](https://www.vice.com/en/article/88npjv/amazons-ai-cameras-are-punishing-drivers-for-mistakes-they-didnt-make?ref=lorcandempsey.net), [a student gets into college](https://www.brookings.edu/research/enrollment-algorithms-are-contributing-to-the-crises-of-higher-education/?ref=lorcandempsey.net), or [a senior receives their public benefits](https://www.technologyreview.com/2020/12/04/1013068/algorithms-create-a-poverty-trap-lawyers-fight-back/?ref=lorcandempsey.net). These systems, often working opaquely, are increasingly used in a wide variety of impactful settings. As motivation, Assemblymember Bauer-Kahan’s office cites demonstrated algorithmic harms in [healthcare](https://www.science.org/doi/10.1126/science.aax2342?ref=lorcandempsey.net), [housing advertising](https://www.hud.gov/sites/dfiles/Main/documents/HUD%5Fv%5FFacebook.pdf?ref=lorcandempsey.net), and [hiring](https://www.reuters.com/article/us-amazon-com-jobs-automation-insight/amazon-scraps-secret-ai-recruiting-tool-that-showed-bias-against-women-idUSKCN1MK08G?ref=lorcandempsey.net), and there have unfortunately been [many](https://incidentdatabase.ai/?ref=lorcandempsey.net) other such instances of harm. // [Brookings](https://www.brookings.edu/blog/techtank/2023/03/22/how-california-and-other-states-are-tackling-ai-legislation/?ref=lorcandempsey.net)
[THE LANDSCAPE OF ML DOCUMENTATION TOOLSWe’re on a journey to advance and democratize artificial intelligence through open source and open science.](https://huggingface.co/docs/hub/model-card-landscape-analysis?ref=lorcandempsey.net)
A review of LLM documentation approaches
#### Hardware
Several technical factors have come together in the current generation of LLMs. The availability of massive amounts of data through webscale gathering and the transformer architecture from Google are central. A third factor is the increased performance of specialist hardware, to deal with the massive memory and compute requirements of LLM processing. Nvidia has been an especially strong player here, and its GPUs are widely used by AI companies and inrastructure providers. However, again, given the belief in massively increased demand, others have also been developing their own custom chips to reduce reliance on Nvidia. The competitive race is on at the hardware level also. See announcements from Microsoft [and](https://arstechnica.com/gadgets/2023/05/microsoft-and-amd-are-allegedly-teaming-up-to-combat-nvidias-ai-dominance/?ref=lorcandempsey.net) AMD, for example, or [Meta](https://www.theverge.com/2023/5/18/23728678/meta-ai-new-chip-mtia-msvp-datacenter?ref=lorcandempsey.net) (which is also working on data center design 'that will be “AI-optimized” and “faster and more cost-effective to build”').
There is some [speculation](https://www.forbes.com/sites/sap/2023/03/21/if-you-think-ai-is-hot-wait-until-it-meets-quantum-computing/?sh=6ce3c67b1ff6&ref=lorcandempsey.net) about the impact of quantum computing further out, which could deliver major performance improvements.
At the same time, many of the open source newer models are designed to run with much smaller memory and compute requirements, aiming to put them within reach of a broad range of players.
#### Research interconnections
There are strong interconnections between research universities, startups and the large commercial players in terms of shared research, development and of course the movement of people. Many of the papers describing advances have shared academic and industrial authorship.
Several years ago, this is how *The Verge* reported when neural network pioneers Hinton (recently left Google), Bengio and LeCun won the Turing Prize. And they have students and former collaborators throughout the industry.
> All three have since taken up prominent places in the AI research ecosystem, straddling academia and industry. Hinton splits his time between Google and the University of Toronto; Bengio is a professor at the University of Montreal and started an AI company called Element AI; while LeCun is Facebook’s chief AI scientist and a professor at NYU. // [The Verge](https://www.theverge.com/2019/3/27/18280665/ai-godfathers-turing-award-2018-yoshua-bengio-geoffrey-hinton-yann-lecun?ref=lorcandempsey.net)
The Stanford AI Index for 2023 [notes](https://aiindex.stanford.edu/wp-content/uploads/2023/04/HAI%5FAI-Index-Report-2023%5FCHAPTER%5F1-1.pdf?ref=lorcandempsey.net) that industry produced 32 significant machine learning models in 2022, compared to 3 from academia. It cited the increased data and compute resources needed as a factor here. However, one wonders whether there might be some rebalancing in their next report given university involvement in the rise of open source models discussed above.
The leaked Google memo is interesting in this context:
> But holding on to a competitive advantage in technology becomes even harder now that cutting edge research in LLMs is affordable. Research institutions all over the world are building on each other’s work, exploring the solution space in a breadth-first way that far outstrips our own capacity. We can try to hold tightly to our secrets while outside innovation dilutes their value, or we can try to learn from each other. // [Google "We Have No Moat, And Neither Does OpenAI"](https://www.semianalysis.com/p/google-we-have-no-moat-and-neither?ref=lorcandempsey.net)
*arXiv* has become very visible given the common practice of disseminating technical accounts there. While this may give them an academic patina, not all then go through submission/refereeing/publication processes.
This role is recognised on the Hugging Face Hub. If a dataset card includes a link to a paper on *arXiv*, the hub will convert the *arXiv* ID into an actionable link to the paper and it can also find other models on the Hub that cite the same paper.
Hugging Face also has a paper [notification](https://huggingface.co/papers?ref=lorcandempsey.net) service.
### 3 Social concerns
Calling for government regulation and referencing much reported recent arguments for a pause in AI development, a Guardian editorial summarises:
> More importantly, focusing on apocalyptic scenarios – AI refusing to shut down when instructed, or even posing humans an existential threat – overlooks the pressing ethical challenges that are already evident, as critics of the letter [have pointed out](https://www.theguardian.com/technology/2023/mar/31/ai-research-pause-elon-musk-chatgpt?ref=lorcandempsey.net). Fake articles [circulating](https://www.theguardian.com/commentisfree/2023/apr/06/ai-chatgpt-guardian-technology-risks-fake-article?ref=lorcandempsey.net) on the web or citations of non-existent articles are the tip of the misinformation iceberg. AI’s [incorrect](https://www.bbc.co.uk/news/technology-65202597?ref=lorcandempsey.net) claims may end up in court. Faulty, harmful, invisible and unaccountable decision-making is likely to entrench discrimination and inequality. Creative workers may lose their living thanks to technology that has scraped their past work without acknowledgment or repayment. // [The Guardian view on regulating AI: it won’t wait, so governments can’t](https://www.theguardian.com/commentisfree/2023/apr/07/the-guardian-view-on-regulating-ai-it-wont-wait-so-governments-cant?ref=lorcandempsey.net)
#### Wrong or harmful results
We know that LLMs 'hallucinate' plausible-sounding outputs which are factually incorrect or fictitious. In addition, they can reflect biased or harmful views learned from the training data. They may normalize dominant patterns in their training data (doctors are men and nurses are women, for example).
In a discussion about their *Imagen* service, Google is very positive about the technical achievements and overall performance of the system ("unprecedented photorealism"). However, they are not releasing it because of concerns about social harm. I provide an extended quote here for two reasons. First, it is direct account of the issues with training data. And second, this is actually Google talking about these issues.
> Second, the data requirements of text-to-image models have led researchers to rely heavily on large, mostly uncurated, web-scraped datasets. While this approach has enabled rapid algorithmic advances in recent years, datasets of this nature often reflect social stereotypes, oppressive viewpoints, and derogatory, or otherwise harmful, associations to marginalized identity groups. While a subset of our training data was filtered to removed noise and undesirable content, such as pornographic imagery and toxic language, we also utilized LAION-400M dataset which is known to contain a wide range of inappropriate content including pornographic imagery, racist slurs, and harmful social stereotypes. Imagen relies on text encoders trained on uncurated web-scale data, and thus inherits the social biases and limitations of large language models. As such, there is a risk that Imagen has encoded harmful stereotypes and representations, which guides our decision to not release Imagen for public use without further safeguards in place.
> Preliminary assessment also suggests Imagen encodes several social biases and stereotypes, including an overall bias towards generating images of people with lighter skin tones and a tendency for images portraying different professions to align with Western gender stereotypes. Finally, even when we focus generations away from people, our preliminary analysis indicates Imagen encodes a range of social and cultural biases when generating images of activities, events, and objects. // [Google](https://imagen.research.google/?ref=lorcandempsey.net)
The discussion above is about images. Of course, the same issues arise with text. This was one of the principal strands in the [Stochastic Parrot](https://dl.acm.org/doi/10.1145/3442188.3445922?ref=lorcandempsey.net) paper mentioned above, which was the subject of contention with Google:
> In summary, LMs trained on large, uncurated, static datasets from the Web encode hegemonic views that are harmful to marginalized populations. We thus emphasize the need to invest significant resources into curating and documenting LM training data.
The authors note for example the majority male participation in Reddit or contribution to Wikipedia.
This point is also made in a brief [review](https://nationalcentreforai.jiscinvolve.org/wp/2023/01/26/exploring-the-potential-for-bias-in-chatgpt/?ref=lorcandempsey.net) of bias on the Jisc *National Centre for AI* site, which notes the young, male and American character of Reddit. They look at research studies on GPT-3 outputs which variously show gender stereotypes, increased toxic text when a disability is mentioned, and anti-Muslim bias. They discussion bias in training data, and also note that it may be introduced at later stages - with RLHF, for example, and in training the Moderation API in OpenAI.
One disturbing finding of the *BIG-bench* benchmarking activity noted above was that "model performance on social bias metrics often grows worse with increasing scale." They note that this can be mitigated by prompting, and also suggest that the approach of the [LaMDA](https://arxiv.org/abs/2201.08239?ref=lorcandempsey.net) model "to improve model safety and reduce harmful biases will become a crucial component in future language models."
[Evaluating Language Model Bias with 🤗 EvaluateWe’re on a journey to advance and democratize artificial intelligence through open source and open science.sasha Sasha Luccioni](https://huggingface.co/blog/evaluating-llm-bias?ref=lorcandempsey.net)
Using Hugging Face tools to explore bias in language models
#### Authenticity, creation and intellectual property
LLMs raise fundamental questions about expertise and trust, the nature of creation, authenticity, rights, and the reuse of training and other input materials. These all entail major social, ethical and legal issues. They also raise concerns about manipulation, deliberately deceptive fake or false outputs, and bad actors. These are issues about social confidence and trust, and the broad erosion of this trust and confidence worries many.
There will be major policy and practice discussions in coming years. Think of the complexity of issues in education, the law, or medicine, for example, seeking to balance benefit and caution.
Full discussion is beyond my scope and competence, but here are some examples which illustrate some of these broad issues:
- Scientific journals have had to clarify policies about submissions. For example, Springer Nature [added](https://www.nature.com/articles/d41586-023-00191-1?ref=lorcandempsey.net) two policies to their guidelines. No LLM will be accepted as an author on the basis that they cannot be held accountable for the work they produce. And second, any use of LLM approaches needs to be documented in submitted papers. They argue that such steps are essential to the transparency scientific work demands.
- What is the intellectual and cultural record? For the first time, we will see the wholesale creation of images, videos and text by machines. This raises questions about what should be collected and maintained.
- Reddit and Stackoverflow have [stated](https://www.wired.com/story/stack-overflow-will-charge-ai-giants-for-training-data/?ref=lorcandempsey.net) that they want compensation for being used as training data for Large Language Models. The potential value of such repositories of questions and answers is clear; what is now less clear is how much, if at all, LLM creators will be willing to pay for important sources. (It is interesting to note Arxiv and PLOS on some lists of training data inputs.) Of course, given the broad harvest of web materials in training data there is much that owners/publishers may argue is inappropriate use. Others may also join Reddit in this way, and some may take legal steps to seek to prevent use of their data.
- There is growing interest in apps and tools which can tell what creations are synthesised by AI. Indeed, OpenAI itself has produced [one](https://platform.openai.com/ai-text-classifier?ref=lorcandempsey.net): "This classifier is available as a free tool to spark discussions on AI literacy." Although they note that it is not always accurate or may easily be tricked. Given concerns in education, it is not surprising seeing plagiarism detection company Turnitin [provide](https://www.turnitin.com/solutions/ai-writing?ref=lorcandempsey.net) support here as well.
- LLMs are potentially powerful scholarly tools in cultural analytics and related areas, prospecting recorded knowledge for meaningful patterns. However, such work will be influenced -- in unknown ways -- by the composition of training or instruction data. As noted above, a recent [study](https://arxiv.org/pdf/2305.00118.pdf?ref=lorcandempsey.net) showed that GPT-4's knowledge of books naturally reflects what is popular on the web, which turns out to include popular books out of copyright, science fiction/fantasy, and some other categories.
- The LLM model has at its core questions about what it is reasonable to 'generate' from other materials. This raises legal and ethical questions about credit, intellectual property, fair use, and about the creative process itself. A recent case involving AI-generated material purporting to be *Drake* was [widely noted](https://www.theguardian.com/music/2023/apr/18/ai-song-featuring-fake-drake-and-weeknd-vocals-pulled-from-streaming-services?ref=lorcandempsey.net). What is the status of AI-generated music in response to the prompt: 'play me music in the style of *Big Thief*'? (Looking back to Napster and other industry trends, Rick Beato, music producer and YouTuber, [argues](https://youtu.be/-eAQOhDNLt4?ref=lorcandempsey.net) that that labels and distributors will find ways to work with AI-generated music for economic reasons.) A group of creators have published an [open letter](https://artisticinquiry.org/AI-Open-Letter?ref=lorcandempsey.net) expressing concern about the generation of art work: "Generative AI art is vampirical, feasting on past generations of artwork even as it sucks the lifeblood from living artists." The Getty case against Stability AI is symptomatic:
> Getty Images claims Stability AI ‘unlawfully’ scraped millions of images from its site. It’s a significant escalation in the developing legal battles between generative AI firms and content creators. // [The Verge](https://www.theverge.com/2023/1/17/23558516/ai-art-copyright-stable-diffusion-getty-images-lawsuit?ref=lorcandempsey.net)
Questions about **copyright** are connected with many of these issues. Pam Samuelson summarises issues from a US perspective in the presentation linked to below. From the description:
> The urgent questions today focus on whether ingesting in-copyright works as training data is copyright infringement and whether the outputs of AI programs are infringing derivative works of the ingested images. Four recent lawsuits, one involving GitHub’s Copilot and three involving Stable Diffusion, will address these issues.
She suggests that it will take several years for some of these questions to be resolved through the courts. In her opinion, ingesting in-copyright works for the purposes of training will be seen as fair use. She also covers recent cases in which the US Copyright Office ruled that synthesized art works were not covered by copyright, as copyright protection requires some human authorship. She described the recent case of *Zarya of the Dawn*, a graphic work where the text was humanly authored but the images were created using *Midjourney*. *The Art Newspaper* [reports](https://www.theartnewspaper.com/2023/05/04/us-copyright-office-artificial-intelligence-art-regulation?ref=lorcandempsey.net): "The Copyright Office granted copyright to the book as a whole but not to the individual images in the book, claiming that these images were not sufficiently produced by the artist."
Pamela Samuelson, Richard M. Sherman Distinguished Professor of Law, UC Berkeley, discusses several of the recent suits around content and generative AI.
The US Copyright Office has launched a [micro-site](https://www.copyright.gov/ai/?ref=lorcandempsey.net) to record developments as it explores issues around AI and copyright. And this is in one country. Copyright and broader regulatory contexts will vary by jurisdiction which will add complexity.
#### Relaxed ethical and safety frameworks
There was one very topical concern in the general warnings that Geoff Hinton sounded: that the release of ChatGPT, and Microsoft's involvement, had resulted in increased urgency within Google which might cause a less responsible approach. These echoes a general concern that the desire to gain first mover advantage – or not to be left behind – is causing Microsoft, Google and others to dangerously relax guidelines in the race to release products. There have been some high profile arguments within each company, and *The New York Times* recently documented internal and external concerns.
> The surprising success of ChatGPT has led to a willingness at Microsoft and Google to take greater risks with their ethical guidelines set up over the years to ensure their technology does not cause societal problems, according to 15 current and former employees and internal documents from the companies. // [NYT](https://www.nytimes.com/2023/04/07/technology/ai-chatbots-google-microsoft.html?ref=lorcandempsey.net)
The article notes how Google "pushed out" Timnit Gebru and Margaret Mitchell over the [*Stochastic Parrots*](https://dl.acm.org/doi/10.1145/3442188.3445922?ref=lorcandempsey.net) paper, and discusses the subsequent treatment of ethics and oversight activities at both Google and Microsoft as they rushed to release products.
[‘There was all sorts of toxic behaviour’: Timnit Gebru on her sacking by Google, AI’s dangers and big tech’s biasesThe Ethiopian-born computer scientist lost her job after pointing out the inequalities built into AI. But after decades working with technology companies, she knows all too much about discriminationThe GuardianJohn Harris](https://www.theguardian.com/lifeandstyle/2023/may/22/there-was-all-sorts-of-toxic-behaviour-timnit-gebru-on-her-sacking-by-google-ais-dangers-and-big-techs-biases?ref=lorcandempsey.net)
An interview with Timnit Gebru
#### Concentration effects: the rich get richer
We can see a dynamic familiar from the web emerging. There is a natural concentration around foundation models and the large infrastructure required to build and manage them. Think of how Amazon, Google and Facebook emerged as dominant players in the web. Current leaders in LLM infrastructure want to repeat that dominance. At the same time, there is an explosion of work around tools, apps, plugins, and smaller LLMs, aiming to diffuse capacity throughout the environment.
Despite this broad activity, there is a concern that LLM infrastructure will be concentrated in a few hands, which gives large players economic advantage, and little incentive to explain the internal workings of models, the data used, and so on. There are also concerns about the way in which this concentration may give a small number of players influence over the way in which we see and understand ideas, issues and identities, given the potential role of generative AI in communications, the media, and content creation.
#### Environmental impact of large scale computing
LLMs consume large amounts of compute power, especially during training. They contribute to the general concern about the environmental impact of large scale computing, which was highlighted during peak Blockchain discussions.
> Big models emit big carbon emissions numbers – through large numbers of parameters in the models, power usage effectiveness of data centers, and even grid efficiency. The heaviest carbon emitter by far was GPT-3, but even the relatively more efficient BLOOM took 433 MWh of power to train, which would be enough to power the average American home for 41 years. // [HAI, 2023 State of AI in 14 Charts](https://hai.stanford.edu/news/2023-state-ai-14-charts?ref=lorcandempsey.net)
Sasha Luccioni, a researcher with the interesting title of 'climate lead' at Hugging Face, [discusses](https://arstechnica.com/gadgets/2023/04/generative-ai-is-cool-but-lets-not-forget-its-human-and-environmental-costs/?ref=lorcandempsey.net) these environmental impacts in a general account of LLM social issues.
> There are also concerns about the way in which this concentration may give a small number of players influence over the way in which we see and understand ideas, issues and identities, given the potential role of generative AI in communications, the media, and content creation.
#### Hidden labor and exploitation
Luccioni also notes the potentially harmful effects of participation in the RLHF process discussed above, as workers have to read and flag large volumes of harmful materials deemed not suitable for reuse. The Jisc post below discusses this hidden labor in a little more detail, as large companies, and their contractors, hire people to do data labelling, transcription, object identification in images, and other tasks. They note that this work is poorly recompensed and that the workers have few rights. They point to this [description](https://restofworld.org/2021/refugees-machine-learning-big-tech/?ref=lorcandempsey.net) of work being carried out in refugee camps in Kenya and elsewhere, in poor conditions, and in heavily surveilled settings.
[Hidden Workers powering AI - National centre for AIHidden Workers powering AI Many people are aware of various AI tools and technologies but most of us aren’t aware of invisible workers involved in the production of AI. This blog post focuses on hidden labour involved in AI production. We aim to raise awareness and educate educational institutions…National centre for AIAyesha Fraz](https://nationalcentreforai.jiscinvolve.org/wp/2023/03/08/hidden-workers-powering-ai/?ref=lorcandempsey.net)
Timnit Gebru and colleagues from the Dair Institute [provide](https://www.noemamag.com/the-exploited-labor-behind-artificial-intelligence/?ref=lorcandempsey.net) some historical context for the emergence of hidden labor in the development of AI, discuss more examples of this hidden labor, and strongly argue "that supporting transnational worker organizing efforts should be a priority in discussions pertaining to AI ethics."
#### Regulating
There has been a rush of regulatory interest, in part given the explosion of media interest and speculation. Italy temporarily banned ChatGPT pending clarification about compliance with EU regulations. The ban is now lifted but other countries are also investigating. The White House has [announced](https://www.whitehouse.gov/briefing-room/statements-releases/2023/05/04/fact-sheet-biden-harris-administration-announces-new-actions-to-promote-responsible-ai-innovation-that-protects-americans-rights-and-safety/?ref=lorcandempsey.net) various steps towards regulation, for example, and there is a UK regulatory [investigation](https://www.gov.uk/government/news/cma-launches-initial-review-of-artificial-intelligence-models?ref=lorcandempsey.net).
> Italy was the first country to make a move. On March 31st, it highlighted four ways it believed OpenAI was breaking GDPR: allowing ChatGPT to provide inaccurate or misleading information, failing to notify users of its data collection practices, failing to meet any of the [six possible legal justifications](https://ico.org.uk/for-organisations/guide-to-data-protection/guide-to-the-general-data-protection-regulation-gdpr/lawful-basis-for-processing/?ref=lorcandempsey.net) for processing personal data, and failing to adequately prevent children under 13 years old using the service. It ordered OpenAI to immediately stop using personal information collected from Italian citizens in its training data for ChatGPT. // [The Verge](https://www.theverge.com/2023/5/5/23709833/openai-chatgpt-gdpr-ai-regulation-europe-eu-italy?ref=lorcandempsey.net)
Lina Kahn, the chair of the US Federal Trade Commission, has compared the emergence of AI with that of Web 2.0\. She notes some of the bad outcomes there, including concentration of power and invasive tracking mechanisms. And she warns about potential issues with AI: firms engaging in unfair competition or collusion, 'turbocharged' fraud, automated discrimination.
> The trajectory of the Web 2.0 era was not inevitable — it was instead shaped by a broad range of policy choices. And we now face another moment of choice. As the use of A.I. becomes more widespread, public officials have a responsibility to ensure this hard-learned history doesn’t repeat itself. // [*New York Times*](https://www.nytimes.com/2023/05/03/opinion/ai-lina-khan-ftc-technology.html?ref=lorcandempsey.net)
Chinese authorities are proposing strong regulation, which goes beyond current capabilities, according to one analysis:
> It mandates that models must be “accurate and true,” adhere to a particular worldview, and avoid discriminating by race, faith, and gender. The document also introduces specific constraints about the way these models are built. Addressing these requirements involves tackling open problems in AI like hallucination, alignment, and bias, for which robust solutions do not currently exist. // [Freedom to Tinker](https://freedom-to-tinker.com/2023/04/16/decoding-chinas-ambitious-generative-ai-regulations/?ref=lorcandempsey.net), Princeton's Center for Information Technology Policy
This chilling comment by the authors underlines the issues around 'alignment':
> One could imagine a future where different countries implement generative models trained on customized corpora that encode drastically different worldviews and value systems.
[You Can’t Regulate What You Don’t UnderstandOr, Why AI Regulations Should Begin with Mandated DisclosuresO’Reilly MediaTim O’Reilly](https://www.oreilly.com/content/you-cant-regulate-what-you-dont-understand-2/?ref=lorcandempsey.net)
Tim O'Reilly argues against premature regulation
While there is general agreement that regulation is desirable, much depends on what it looks like. Regulation is more of a question at this stage than an answer; it has to be designed. One would not want to design regulations in a way that favors the large incumbents, for example, by making it difficult for smaller players to comply or get started.
This point is made by Yannic Kilcher (of Open Assistant) in a video [commentary](https://www.youtube.com/watch?v=I72%5FGJHzH3Y&ref=lorcandempsey.net) on US Senate [hearings](https://www.nytimes.com/2023/05/16/technology/openai-altman-artificial-intelligence-regulation.html?ref=lorcandempsey.net) on AI oversight. He goes on to argue that openness is the best approach here, so that people can see how the model is working and what data has been used to train it. Stability AI also [argue](https://stability.ai/blog/stability-ai-letter-us-senate-ai-oversight?ref=lorcandempsey.net) for openness in their submission to the hearings: "Open models and open datasets will help to improve safety through transparency, foster competition, and ensure the United States retains strategic leadership in critical AI capabilities."
Finally, I was interested to read about AI-free spaces or sanctuaries.
> To implement AI-free sanctuaries, regulations allowing us to preserve our [cognitive and mental harm](https://www.law.kuleuven.be/citip/blog/my-brain-hurts-can-the-ai-act-adequately-protect-cognitive-and-or-mental-harm-by-ai-software-part-2/?ref=lorcandempsey.net) should be enforced. A starting point would consist in enforcing a new generation of rights – “neurorights” – that would protect our cognitive liberty amid the rapid progress of neurotechnologies. [Roberto Andorno and Marcello Ienca](https://lsspjournal.biomedcentral.com/articles/10.1186/s40504-017-0050-1?ref=lorcandempsey.net) hold that the *right to mental integrity* – already protected by the European Court of Human Rights – should go beyond the cases of mental illness and address unauthorised intrusions, including by AI systems. // Antonio Pele, It’s time for us to talk about creating AI-free spaces, [*The Conversation*](https://theconversation.com/its-time-for-us-to-talk-about-creating-ai-free-spaces-202176?ref=lorcandempsey.net)
#### The impact on employment
One of the [factors](https://www.wired.com/story/hollywood-screenwriters-artificial-intelligence-guardrails/?ref=lorcandempsey.net) in the screen writers' strike in Hollywood is agreement over uses of AI, which could potentially be used to accelerate script development or in other areas of work. However, [according](https://www.theinformation.com/articles/while-hollywood-writers-fret-about-ai-visual-effects-workers-welcome-it?ref=lorcandempsey.net) to *The Information*: 'While Hollywood Writers Fret About AI, Visual Effects Workers Welcome It.' And at the same time, studios are looking at AI across the range of what they do - looking at data about what to make, who to cast, how to distribute; more seamlessly aging actors, dubbing or translating; and so on.
I thought the example interesting as it shows impact in a highly creative field. More generally the impact on work will again be both productive and problematic. The impact on an area like libraries, for example, will be multi-faceted and variable. This is especially so given the deeply relational nature of the work, closely engaged with research and education, publishing, the creative industries and a variety of technology providers.
While it is interesting to consider reports like [this one](https://www.key4biz.it/wp-content/uploads/2023/03/Global-Economics-Analyst%5F-The-Potentially-Large-Effects-of-Artificial-Intelligence-on-Economic-Growth-Briggs%5FKodnani.pdf?ref=lorcandempsey.net) from Goldman Sachs or this [research](https://papers.ssrn.com/sol3/papers.cfm?abstract%5Fid=4414065&ref=lorcandempsey.net) from Ed Felten and colleagues which look at the exposure of particular occupations to AI, it is not entirely clear what to make of them. One finding from the latter report is "that highly-educated, highly-paid, white-collar occupations may be most exposed to generative AI."
Certainly, predictions like the one in the Goldman Sachs report that up to a quarter of jobs might be displaced by AI are driving regulator interest. Which is fueled also by headline-grabbing statements from high profile CEOs (of [British Telecom](https://www.bbc.com/news/business-65631168?ref=lorcandempsey.net) and [IBM](https://www.reuters.com/technology/ibm-pause-hiring-plans-replace-7800-jobs-with-ai-bloomberg-news-2023-05-01/?ref=lorcandempsey.net), for example) forecasting reduced staff as AI moves into backoffice and other areas. There will be increased advocacy and action from industry groups, unions, and others. It
There are very real human consequences in terms of uncertainty about futures, changing job requirements, the need to learn new skills or to cope with additional demands, or to face job loss. This follows on several stressful years. The cumulative effect of these pressures can be draining, and empathy can be difficult. However, empathy, education and appropriate transparency will be critical in the workplace. This is certainly important in libraries given the exposure to AI in different ways across the range of services.
> However, empathy, education and appropriate transparency will be critical in the workplace.
#### Major unintended event
LLMs will manage more processes; judgements are based on chatbot responses; code written by LLMs may be running in critical areas; agents may initiate unwelcome processes. Given gaps in knowledge and susceptibility to error, concerns have been expressed about over-reliance on LLM outputs and activities.
One response is at the regulatory level, but individual organizations will also have to manage risk in new ways, and put in place procedures and processes to mitigate potential missteps. This has led to yet another word becoming more popular: 'guardrails.' Guardrails are programmable rules or constraints which guide the behavior of an LLM-based application to reduce undesired outcomes. However, it is not possible to anticipate all the ways in which such precautions would be needed.
Beyond this, there are broader concerns about the malicious use of AI where serious harm may be caused. In crime or war settings, for example. So-called 'dual use' applications are a concern, where an LLM may be used for both productive and malicious purposes. See for example this discussion of an agent-based architecture "capable of autonomously designing, planning, and executing complex scientific experiments" \[[pdf](https://arxiv.org/ftp/arxiv/papers/2304/2304.05332.pdf?ref=lorcandempsey.net)\]. While the authors claim some impressive results, they caution against harmful use of such approaches, and examine the potential use of molecular machine learning models to produce illicit drugs or chemical weapons. The authors call for the AI companies to work with the scientific community to address these dual use concerns.
Concerns are also voiced by those working within generative AI. As mentioned above, Geoffrey Hinton, a pioneer of neural networks and generative AI, stepped down from his role at Google so that he might comment more freely about what he saw as threats caused by increased commercial competition and potential bad actors.
> Hinton's long-term worry is that future AI systems could threaten humanity as they learn unexpected behavior from vast amounts of data. "The idea that this stuff could actually get smarter than people—a few people believed that," he told the Times. "But most people thought it was way off. And I thought it was way off. I thought it was 30 to 50 years or even longer away. Obviously, I no longer think that." // [Ars Technica](https://arstechnica.com/information-technology/2023/05/warning-of-ais-danger-pioneer-geoffrey-hinton-quits-google-to-speak-freely/?ref=lorcandempsey.net)
This received a lot of public attention, and I mentioned some of these concerns in relationship to 'alignment' above. Anthropic is the creator of the *Claude* model and is seen as a major competitor to Google and OpenAI. This is from the Anthropic website:
> So far, no one knows how to train very powerful AI systems to be robustly helpful, honest, and harmless. Furthermore, rapid AI progress will be disruptive to society and may trigger competitive races that could lead corporations or nations to deploy untrustworthy AI systems. The results of this could be catastrophic, either because AI systems strategically pursue dangerous goals, or because these systems make more innocent mistakes in high-stakes situations. // [Anthropic](https://www.anthropic.com/index/core-views-on-ai-safety?ref=lorcandempsey.net)
## Conclusion
As I write, announcements come out by the minute, of new models, new applications, new concerns.
Four capacities seem central (as I think about future library applications):
1. **Language models.** There will be an interconnected mix of models, providers and business models. Large foundation models from the big providers will live alongside locally deployable open source models from commercial and research organizations alongside models specialized for particular domains or applications. The transparency, curation and ownership of models (and tuning data) are now live issues in the context of research use, alignment with expectations, overall bias, and responsible civic behavior.
2. **Conversational interfaces.** We will get used to conversational interfaces (or maybe 'ChUI' - the Chat User Interface). This may result in a partial shift from 'looking for things' to 'asking questions about what one wants to know' in some cases. In turn this means that organizations may begin to document what they do more fully on their websites, given the textual abilities of discovery, assistant, and other applications.
3. **Agents and workflows.** The text interfacing capacities of LLMs will be used more widely to create workflows, interaction with tools and knowledge bases, and so on. LLMs will support orchestration frameworks for tools, data and agents to build workflows and applications that get jobs done.
4. **Embeddings and Vector databases.** Vector databases are important for managing embeddings which will drive new discovery and related services. Embedding APIs are available from several organizations.
Several areas stand out where there is a strong intersection between social policy, education and advocacy:
1. **Social confidence and trust: alignment.** Major work needs to be done on alignment at all levels, to mitigate hallucination, to guard against harmful behaviors, to reduce bias, and also on difficult issues of understanding and directing LLM behaviors. However, there will be ongoing concern that powerful capacities are available to criminal or political bad actors, and that social trust and confidence may be eroded by the inability to distinguish between human and synthesized communications.
2. **Transparency.** We don't know what training data, tuning data and other sources are used by the foundation models in general use. This makes them unsuitable for some types of research use; it also raises more general questions about behaviors and response. We also know that some services capture user prompts for tuning. Tolerances may vary here, as the history of search and social apps have shown, but it can be important to know what one is using. Models with more purposefully curated training and tuning data may become more common. Documentation, evaluation and interpretability are important elements of productive use, and there are interesting intersections here with archival and library practice and skills.
3. **Regulation.** Self regulation and appropriate government activities are both important. The example of social media is not a good one, either from the point of view of vendor positioning or the ability to regulate. But such is the public debate that regulation seems inevitable. Hopefully, it will take account of lessons learned from the Web 2.0 era, but also proceed carefully as issues become understood.
4. **Hidden labour and exploitation.** We should be aware of the hidden labour involved in building services, and do what we can as users and as buyers to raise awareness, and to make choices.
Generative AI is being deployed and adopted at scale. It will be routine and surprising, productive and problematical, unobtrusive and spectacular, welcome and unwelcome.
I was very struck by the OpenAI comment that training the large language model is more like training a dog than writing software. An obvious rejoinder is that we hope it does not bite the hand that feeds it. However, it seems better to resist the comparison and hope that the large language model evolves into a responsibly managed machine which is used in productive ways.
**Feature picture:** The feature picture is a piece by A.K.Burns, which I took at an [exhibition](https://wexarts.org/exhibitions/ak-burns-space-we-are?ref=lorcandempsey.net) of her work at the Wexner Center for the Arts, The Ohio State University.
**Acknowledgement:** I am grateful to Karim Boughida, Sandra Collins and Ian Mulvany for commenting on a draft.
**Update:** 5/29/23 I added paragraphs to the content and regulation sections.
This is a general background post. I do plan to look at some more specific issues around research content, libraries, and related in future posts.
### Hallucination and collections
URL: https://www.lorcandempsey.net/hallucination-and-collections/
Last updated: 2023-11-12T08:12:58.000Z
I realise that my thinking on library collections may not be as well formed as it could be, but really ...? 😉
When I experiment with Chatbot interfaces I tend to have some standard queries. I ask whether the concept of the Irish diaspora is a helpful one in the context of either British or US politics. I also ask about library collections, in particular about the three models I have been writing and speaking about in recent years: [*collective collections*](https://www.lorcandempsey.net/operationalizing-a-collective-collection/), the [*inside out collection*](https://www.lorcandempsey.net/collection-directions-accelerated/), and the [*facilitated collection*](https://www.lorcandempsey.net/the-facilitated-collection-redux-a-note-on-collections-as-a-service-the-university-of-california-and-elsevier/).
These are the oddest results I have received from my chatbot experiments. Maybe they are having a day off? Maybe I missed a necessary configuration? Maybe my thoughts on library collections are completely incoherent?
I was trying Hugging Chat and it was using the *OpenAssistant LLaMa 30B SFT 6* model.
First off, what is the *collective collection*?

OK, so much for that. What about the *inside out collection*?

mmm ... OK, and the *facilitated collection*?

It is of course easy to poke fun. And other results with other models can be so impressive. I do not know what is going on here ... perhaps it is a temporary glitch.
GPT-4 does somewhat better. First with a terse prompt.

A reminder that contra some expectations, GhatGPT is not a search engine. Then with some more guidance ...

This shows the importance of the prompt, giving a fuller answer than the first. Although this puts me in my place ...

It is interesting that it offers an interpretation based on the text itself. That said, Bard does 'know' more ...

And finally ...

I would not pose the *inside out collection* as competitive with the *acquired collection*, and I wonder is this partly influenced by somebody else writing about it.
I haven't done a deeper dive to see what I can find out about what is going on here. I note that my website is not part of the Google C4 collection [analysed](https://www.washingtonpost.com/technology/interactive/2023/ai-chatbot-learning/?ref=lorcandempsey.net) by *The Washington Post*.
**Added 16 May 2023\.** OpenAI has just expanded the capabilities of ChatGPT to include web browsing. This is an important step. Here is ChatGPT on the collective collection with web browsing switched on:

And here for the first time I actually get named. It is also interesting to see the three collecting modes mentioned, although maybe the second should be *collective collections*?

Also interesting to see a name-check here. This is an OK answer, but I was especially interested to see the last paragraph which I thought did a good job without directly copying anything I am aware of.

Incidentally, I was interested to come across this article by Leo Lo recently: [The CLEAR path: A framework for enhancing information literacy through prompt engineering](https://www.sciencedirect.com/science/article/abs/pii/S0099133323000599?ref=lorcandempsey.net).
**Coda:** I had asked HuggingChat about the Irish diaspora in a previous question. The 'memory' of that may have been interfering.
### The technology career ladder
URL: https://www.lorcandempsey.net/technology-is-not-on-the-outside/
Last updated: 2025-04-24T17:15:36.000Z
This post is jointly written with [Karen Estlund](https://karenestlund.com/?ref=lorcandempsey.net), Dean of Libraries at Colorado State University.
## Library technology and library directors
In an exchange with Karen Estlund recently, she described how she had been asked by a search firm to compose a justification for a nominated colleague to explain why and how technology leadership was relevant to a library dean position. She noted that this attitude was consistent with her own experiences as a technology leader. And she could also see that colleagues with similar backgrounds were having similar issues as they applied for director or other leadership positions. Recruiters or university administrators did not always seem to see candidates with a technology background as having had the same preparation for leadership that their peers in other parts of the library had.
I checked in with a couple of other colleagues. There was some variation in perception. One colleague with a strong technology background noted quite positive experiences and had actually experienced a demand for candidates with their experience.
Of course, search committees (and recruiters) can be very variable in terms of focus and expectations. And within universities, there may be great variety in what is expected of the library or the library director. This is especially so at the moment as the range of what a research library does may not be fully understood or perceived by faculty and administration.
Further discussion prompted a very quick examination of the ARL membership, based on a first pass by Karen. It is a manageable number and we have some familiarity with personnel. We were curious about the career paths of directors and how many might have technology backgrounds. We are grateful to Mary Lee Kennedy and ARL staff for providing data for validation. We note some numbers in the next section.
At the same time, the exchanges made us think about why technology leaders are potentially good candidates for director roles, having skills and experience in some cases that are increasingly important. Thoughts fell into three areas. First, a good technology leader is a good leader first, and a good technology leader second. So an attitude like the one noted above limits the field. Second, it displays a rather old-fashioned view of technology as something discrete and separate, and not something that is deeply meshed with the use, management and creation of information resources across research and learning. And third, it potentially downplays the importance of the critical judgement that a library director needs in relation to technology. We go on to expand a little on these points below.
## Some numbers
First a note on definition. 'Technology' is a pretty elastic term, and doesn't map neatly onto either job titles or experiences. This is especially the case as technology responsibilities have expanded into areas like the digital humanities or data management. It is also pretty relative. What one person views as a technology role may be seen by another as a more general management role. For the purposes of this very impressionistic investigation we take a technology leader as somebody who has had significant technology experience, leading to an AUL-type role with technology management responsibilities.
Interpreting this quite generously, we estimated that about 14% of ARL directors had what would be generally recognised as a technology background. It should be noted that a small number of these were recruited into roles that had technology responsibilities associated with or aligned with the library director role, making a candidate with technology experience a clearer option.
Is this what one might expect? Is it more? Is it less? An important factor to consider here is the large turnover in ARL leadership in recent years. Well over half the ARL dean/directors, 69, have been hired into their current role since 2018, with three additional announced to start by June 2023\. Of those, 54 were new as directors to ARL, i.e. had not previously served as director at another ARL institution.
Given the importance of technology for the library and also, critically, for the university of which it is a part, one might expect the number of directors with a technology background to be higher? Especially given the large number of deans/directors who have been hired into their position in the last five years or so?
## Some potential attributes of technology leaders
### 1 A successful technology leader is a successful leader
To be successful, a technology leader has to exercise many general skills. Contrary to stereotype or caricature, they do not operate on standalone systems (are there any standalone systems?) or work in a social vacuum.
They will organize teams and motivate colleagues. They will think about the skills needed in their teams, and plan for succession. They will think about the diversity of their teams, and whether the workload, culture, and development opportunities create inclusive conditions where all feel they can succeed. In all of these cases, technology considerations may include special challenges, given competition for scarce talent, the need for continuous skills development and learning, and the historic demographics of the technology field.
They will understand the strategic priorities of the library and know how to gather the opinions, requirements, and preferences necessary to develop good systems support. They will engage with service partners in other parts of the university – information technology, administration, research office, online learning – to make sure that library systems work well and connect. They will work hard to position the library as a desired partner in campus system discussions. They will keep up to date with trends in learning, research and administration so as to be able to prepare for evolving services, to be open to co-creation with peers in other parts of the university, to become effective advocates for useful library development work. They will learn how to negotiate with vendors and to develop productive relations with key suppliers. The technology leader is a first contact, ambassador and advocate for the library in these and other ways.
They will be effective members of management teams; they will be critical advocates; they will understand how to argue positively for resources within organizational goals. They will certainly have to deal with pushback and have difficult discussions, have to compromise goals and expectations, and have to manage disappointment or low morale. Hidden labor permeates library work, and, given the nature of development and support work, technology leaders need to be mindful of impacts across their teams.
Of course, not all technology leaders will excel in all of these areas, but it is impossible to be a good technology leader without developing strong relational, communication and advocacy skills, the types of skills that a director needs.
### 2 Technology is not a niche
It seems strange to have to say it, but technology is pretty pervasive. I like the distinction Wanda Orlikowski makes between 'technology as artifact' and 'technology in practice' \[see for example here [pdf](https://www.dhi.ac.uk/san/waysofbeing/data/data-crone-orlikowski-2008b.pdf?ref=lorcandempsey.net)\]. In the former perspective we see technology as static, as residing in a particular system, as separately observable. However, this is quite misleading and can have limiting consequences.
If a **course reserve system** or **resource list application** is seen as a 'system' to be worked on, the results will be less good than if the starting point is how to mobilise library resources to enrich the learning experience within an online flow. The institutional repository is another example. This may have struggled because it was seen as a separate system: its development was not cognizant enough of researcher workflows, web discoverability and scholarly incentives. As r-infrastructure evolves, the role of the repository in relation to Research Information Management, expertise profiling, and research data management is being looked at as part of a set of related approaches. These are examples of how it makes more sense to think of 'technology in practice.' In a context where many library experiences may be mobile, where increasingly sophisticated workflows tie researchers, apps and resources together, where mixed learning environments are the norm, where we read and write digitally, we need to consciously recognize the mutual entailment of technology, behaviors and organizational development.
Now, one would hope that a technology leader would think about applications in the context of evolving behaviors and needs in this way. And a good one would. However, the central point here is that recruiters and administrators should recognise that technology is not just about systems development or that a technology background is somehow less relevant or less mainstream than one in collections or access services.
### 3 Library leaders need to make technology judgements
At one stage, the integrated library system was the central technology concern. Then of course things [changed](https://www.lorcandempsey.net/the-ils-the-digital-library-and-the-research-library/) and it was one part of a wider range of digital responsibilities. Two things are relevant here. First, this expanded agenda attracted people into the profession who wanted to work to create the digital environments of the future, to engage with those advancing scholarship and learning in digital environments. Those people now want to bring that enthusiasm and energy to library director positions. Second, we went through a period when library technology experience was in short supply and where directors had often little experience with managing technology systems. This created something of an imbalance in decision-making and perspective, where leadership may have deferred to those with technical knowledge.
> Good leaders will be drawn from across the full range of the library, from technology, special collections, collections, public services or elsewhere. The technology career ladder in libraries should reach all the way to the top for suitable candidates. To imagine otherwise is counter-productively limiting.
A library director today has to be able to make calls across library operations, and as just discussed, this inevitably means understanding technology ramifications. Advised by colleagues, for sure, but an effective director needs to be informed enough to have good judgement. Do we buy or build? Will this approach allow us to share data or interconnect with other campus systems? What is the impact on support and cost over the long term of a particular open source solution? Will this vendor be in business in five years? Does this grant funding opportunity involve colleagues in useful learning and advance our position, or does it involve too high an opportunity cost and a shiny distraction?
In discussion with colleagues on campus, they have to be informed advocates for the capabilities of the library, or the potential capabilities. Similar issues are in play at the consortial level, especially where there is a desire to strengthen shared infrastructure. When should we advocate for a shared approach? When is local control and management more important?
Somebody who has come up through a library technology path may or may not be more effective here. However, again, the key point is to note that technology judgement is interwoven with library decisions all the time.
Good leaders will be drawn from across the full range of the library, from technology, special collections, collections, public services or elsewhere. The technology career ladder in libraries should reach all the way to the top for suitable candidates. To imagine otherwise is counter-productively limiting.
**Feature picture:** I took the picture on a visit to Purdue University Libraries a few years ago.
**Acknowledgements:** Thanks to MacKenzie Smith and Mary Lee Kennedy for input, and to Mary Lee Kennedy and colleagues for kindly providing data about appointments. Opinions expressed are ours.
### Incorrigibly plural: notes about fonts
URL: https://www.lorcandempsey.net/font-notes/
Last updated: 2026-02-28T22:43:01.000Z
I have become increasingly interested in fonts over the last couple of years, exploring something of the history as well as the enormous volume and variety of current activity. I will post an occasional note about them here, acknowledging my amateur status. The fonts on this entry are from two sources, each with an intriguing and significant story that speaks to diversity and its lack.
## Ange Degheest
First, the body text and captions are set in fonts from a collection of typefaces by [Ange Degheest](https://velvetyne.fr/degheest/?ref=lorcandempsey.net), a fictional designer wonderfully realised by students at The European Academy of Art in Brittany. Read more [here](https://eyeondesign.aiga.org/presenting-ange-degheest-pioneering-20th-century-female-type-designer/?ref=lorcandempsey.net). They were highlighting how female type designers where either hidden or absent from the record. The body is in Latitude, and the captions and quotations are in Abordage, both by Eugénie Bidaut. The fonts are distributed together [in one download](https://velvetyne.fr/fonts/degheest/?ref=lorcandempsey.net) on Velvetyne, the wonderful site for open source fonts.
> [Eugénie Bidaut](http://xn--eugniebidaut-deb.eu/?ref=lorcandempsey.net), one of the former students, says, “Type design history is very masculine. In the history of midcentury French type design, there is only one woman, Lucette Girard, who collaborated with Adrian Frutiger and other male designers. We were searching for someone to identify with, and were not interested in doing a revival of the work of an old white man, so we decided to invent a person who was missing.” // [Meet Ange Degheest, Pioneering 20th-Century Female Type Designer](https://eyeondesign.aiga.org/presenting-ange-degheest-pioneering-20th-century-female-type-designer/?ref=lorcandempsey.net), AIGA Eye on Design, Angela Riechers
It was after reading this that I came across Alice Savoie's [Lucette](https://www.futurefonts.xyz/alice-savoie/lucette?ref=lorcandempsey.net) typeface. Alice Savoie contributes an [afterword](https://www.poem-editions.com/products/degheest?ref=lorcandempsey.net) to a pamphlet on Ange Degheest.
More from Eugénie Bidaut [here](https://xn--eugniebidaut-deb.eu/?ref=lorcandempsey.net). Especially interesting for French speakers/readers may be Adelphe.
## Soyuz Grotesk
> Indeed, for a New York designer in 1980 the Swiss Style must have seemed universal and omnipresent — the typographic modernism was an already well-established practice with decades of history. In most other parts of the world, though, the situation was largely different. // Soyuz Grotesk, [Roman Gornitsky](https://letters.temporarystate.net/entry/1/?ref=lorcandempsey.net)
The headings and and button text are in Soyuz Grotesk by Roman Gornitsky of The Temporary State. It is an adaptation back into Latin of a Russian adaptation of Helvetica. The conceit here is that it is done as if without knowledge of the original Helvetica, or of the Latin practices of which it is a part. I love the 'r' in this context. Read more [here](https://letters.temporarystate.net/entry/1/?ref=lorcandempsey.net) and [here](https://typographica.org/typeface-reviews/soyuz-grotesk/?ref=lorcandempsey.net). It has only one case, a reminder that upper and lower case are not universal.
> Rarely a typeface comes as a reflection of some current situation—usually it is in the consideration of the past or imaginary future. // Roman Gornitsky in interview with Brian Huddlestone, [The Gradient](https://walkerart.org/magazine/sovereign-typesetting-an-interview-with-typefaces-of-the-temporary-state?ref=lorcandempsey.net)
For a review of [Wremena](https://typefaces.temporarystate.net/preview/Wremena?ref=lorcandempsey.net), a Times-like font by The Temporary State which is also freely available see [Pimp My Type](https://pimpmytype.com/wremena/?ref=lorcandempsey.net).
**Note**: Title phrase from Louis MacNeice's [Snow](https://www.poetryfoundation.org/poems/91395/snow-582b58513ffae?ref=lorcandempsey.net).
### Reflections .. on my last day at OCLC
URL: https://www.lorcandempsey.net/reflections-on-my-last-day-at-oclc/
Last updated: 2022-11-02T23:52:30.000Z
Today was my last day at OCLC. After 21 years.
Much has changed over that time. And I have been very lucky to work for an organization which has helped influence that change. I have also been extraordinarily lucky to work with great colleagues and to have had the opportunity to interact with so many librarians around the world in different roles and contexts.
I have been fortunate to work for Skip Prichard, the current CEO, as well as for Jay Jordan, the previous CEO who recruited me, both of whom have supported me personally and also the important work in research and membership as an integral part of what OCLC does.
I thought I would share some reflections about my work and about OCLC. OCLC is a great place to work. There is a collegial culture, and people work there because they are committed to the mission.
In preparing this post, I realise that it complements the more reflective, personal remarks on career, on the challenges of the last few years, and on libraries generally, published here a while ago:
[Advice to an LIS graduate student: reflecting life and careerI got an email in October last year from Achilles Escudero-Kontostathis, a graduate student in LIS at Catholic University, Washington DC. He asked if I could talk about what I valued or found essential for a library student to know.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/letter-to-an-lis-graduate-student/)
## A personal perspective
I was initially recruited to oversee OCLC Research although my responsibilities have grown over the years. Within OCLC Research, it has been rewarding to be able to facilitate impactful work - generating knowledge, evidence and models which have helped to influence practice, to inform policy, and to increase confidence in planning.
I am proud of the work that my colleagues have done here, creating a real difference for academic and public libraries around the world. Rather than singling out particular initiatives or outputs, here is a brief overview with links to further details:
- [User Research](https://www.oclc.org/research/areas/user-studies.html?ref=lorcandempsey.net): Influential work on interaction with library services, on network behaviors, as well as deeper dives into researcher practice and expecations.
- [Data science & metadata research](https://www.oclc.org/research/areas/data-science.html?ref=lorcandempsey.net): Early work with Dublin Core; development of VIAF and FAST contributing to entity-based metadata approaches; development of IIIF support in OCLC services; ArchiveGrid, WorldCat Identities and various prototypes.
- [Libraries as community catalysts](https://www.oclc.org/research/areas/community-catalysts.html?ref=lorcandempsey.net): The WebJunction learning platform and important projects on professional development, on library support in the Opioid epidemic, on the patterns of public support for library funding, and a range of projects on small and rural libraries. We were very pleased to step up to support the REALM project during the pandemic. The recent Reimagine Descriptive Worklows initiative lays out an important agenda.
- [Research collections and support](https://www.oclc.org/research/areas/research-collections.html?ref=lorcandempsey.net): Ongoing important work around special collections and archives, alongside definitional work on research data management and research information management. Much of this work has been done in deep engagement with Research Library Partnership colleagues.
- [Library as enterprise](https://www.oclc.org/research/areas/library-enterprise.html?ref=lorcandempsey.net): Exploration of how libraries are organized to get work done, in terms of service patterns, collaborative structures, and relationship to parent organizations. This is an area that deserves more attention.
- [Collective collections](https://www.oclc.org/research/areas/systemwide-library.html?ref=lorcandempsey.net): Leveraging OCLC's unique view of aggregated metadata to characterise patterns in library collecting, to provide an empirical basis for thinking about collaborative direction and structures, and to explore the composition of the scholarly and cultural record.
[News, events, and reports | OCLC ResearchOCLC’s Research accelerates and scales learning, innovation, and collaboration to advance libraries and librarianship. Since 1978, we have carried out research and made technological advances that enhance the value of library services and improve the productivity of librarians and library users. We…OCLC](https://www.oclc.org/research/home.html?ref=lorcandempsey.net)
In my own work and thinking, I have worked directly with talented and dedicated colleagues throughout OCLC. One learns by the daily osmosis of interactions, as well as more deliberately. I really do feel lifted up - benefiting from broad expertise and experience. I will sorely miss that collegial personal network.
I have also loved the opportunities to interact with and learn from library colleagues from all types of libraries and from all parts of the world. This is very important to me: it is good to have that varied perspective and to see recurrent concerns, but also to see how services are manifest in very different environments. From this point of view I have enjoyed the opportunity to meet and talk with library colleagues in situ, at local events or in visits.
This is a major reason that I have been grateful to have had responsibility for Membership in recent years and to be able to work with my member relations colleagues. This group works with Councils and the governance structure of OCLC. The Chair of the Board is always a librarian, and I have enjoyed working with the many distinguished librarians who have served on the Board and Councils.
[Membership in action: Libraries are stronger together | OCLCWhat you do with OCLC makes all libraries stronger. Learn how individuals, groups, and libraries make an impact.OCLC](https://www.oclc.org/en/membership.html?cmpid=md%5Fmem&ref=lorcandempsey.net)
Finally, I have been pleased to be able to sustain my own writing and presenting, drawing on the wisdom of my colleagues and interactions with the library community (links at top of page!).
## Thinking about OCLC
When asked about OCLC, I say that it allows libraries to **collaborate at scale** to get their work done. To enable this sharing, OCLC has built a network which connects thousands of libraries around the world. Of course, there is a stronger emphasis in the US and in those countries where there is greater use of OCLC services. Libraries mobilize this network to increase their impact and to do their work more efficiently … for resource sharing, for discovery, for shared cataloging and for new services like decision support.
Collaboration is underpinned by WorldCat and associated data resources, a unified view of collections from those libraries. Libraries reflect popular interest. They also reflect scholarly interest and have collected the published output of nations over time. Accordingly, library collections are a central place where world literature is stewarded and defined. As a result, WorldCat is probably the best approximation readily available to the published scholarly and cultural record. It is important shared infrastructure. Of course, this is not to overlook either the limitations in coverage of WorldCat itself, or in the collecting practices of libraries.
OCLC has also connected those libraries to hundreds of consumer sites (Google Books and Google, for example), content (publishers and metadata providers, for example) and systems providers, who also benefit from the operational scale of the network.
So, in this way, the OCLC network allows libraries to **collaborate at scale** in an unprecedented way. OCLC was a collaborative platform before we spoke about platforms. It supported library logistics before we spoke about logistics. Because of its broad and unparalleled reach it allows libraries of all types to participate in the benefits of the network it has created. And because of its governance model, it has no other purpose than to serve libraries. WorldCat itself is a unique resource, created by libraries, OCLC, and partners, all working together. WorldCat and related resources help to configure the library network OCLC supports.
Libraries, the public, scholars, and others in turn benefit from WorldCat and associated data resources, notably because of its ability to provide a high level collective perspective. It operates in a rich ecosystem of institutional and consortial or regional perspectives, in the US and elsewhere.
OCLC plays a critical and unique role in that ecosystem, and it evolves as the ecosystem evolves. Its role is multifaceted, given the variety of ways in which libraries and others use WorldCat and participate in the network it supports. Briefly, here are some examples ..
1. *An operational view of a large library network, which creates efficiencies in how libraries work together and with their partners.*
- Network visibility – WorldCat and related data resources configures the network so that libraries, collections and services are visible and actionable in a collective way. The library network can also then be efficiently connected to Google Books, GoodReads or other services.
- Reduced interaction costs – greater efficiency in finding a record when wanted for cataloging, in locating a volume to request in interlibrary lending, or to search through the published documentary literature.
- Optimized library logistics – view of broad library network facilitates efficient resource sharing and calibration of individual collections against groups or the whole for offsite storage etc.
1. *A unified view of the published scholarly and cultural record stewarded within that network*
- Scholars, genealogists, authors, enthusiasts, learners and others can readily search the published knowledge in WorldCat because it brings together the collections of thousands of libraries.
1. *Automated operations at scale to increase efficiencies within the library network*
- Application of data science techniques for quality control and upgrade at the collective level – harmonization, clustering, deduplication, upgrade of data.
- Automated cataloging and collection level processing – supply of and automatic update of records for whole collections (for ebooks, for example, open access materials, or other collections). Working directly with publishers to register and update collections in WorldCat as content is purchased by libraries
## Looking forward
It has been rewarding being a part of this evolution. I will miss the work and most of all I will miss colleagues and the broad library interaction.
[Collections are changing](https://www.lorcandempsey.net/collection-directions-accelerated/). In recent years I have been talking about collective collections (managing collections above the individual library level), the facilitated collection (managing interactions with resources beyond the locally acquired collection), and the inside out collection (managing and disclosing unique institutional assets such as archives, research data and other scholarly material). Libraries are exploring controlled digital lending, prospective collection coordination, reparative resource description, and the varieties of open access. OCLC will be working with libraries to develop solutions as collections continue to evolve.
On the immediate horizon, I look forward to the refreshed Worldcat.org, to the progressive roll out of linked data approaches, and to further developments in how library visibility on the web can be enhanced. Further out, there is more work underway as OCLC partners with libraries to meet and anticipate developing needs.
Everybody at OCLC - the executive team and colleagues across the organization - is focused on helping libraries create a stronger future. I know that they will produce great things over the next few years. I also expect to be able to collaborate with my current colleagues in other ways and roles. And I certainly look forward to watching and cheering from the sidelines!
**Note:** The author was VP, Membership and Research, & Chief Strategist, OCLC, when this post was written.
**Acknowledgement:** Thank you to the colleagues who read this in draft and improved it with feedback.
**Picture:** The feature image is a slightly blurry night time shot of OCLC HQ in Dublin, Ohio. Taken by the author on his way home one evening.
### Reflecting life and career: advice to an LIS graduate student
URL: https://www.lorcandempsey.net/letter-to-an-lis-graduate-student/
Last updated: 2025-04-24T17:18:06.000Z
I got an email in October last year from Achilles Escudero-Kontostathis, a graduate student in [LIS](https://lis.catholic.edu/?ref=lorcandempsey.net) at Catholic University, Washington DC. He asked if I could talk about what I valued or found essential for a library student to know. What is some of the best advice I could give to students like him? Achilles noted he was interested in my life and career. We are more reflective about focus and direction after recent years, so I thought I would rest on an autobiographical approach.
## Recognize the value of experience, aptitude and attitude
I was a college dropout. For several years, I worked in temporary jobs, or, well, sometimes, I did not. This included a spell of over eight months working on a production line in Continental Gummiwerke in Korbach, Germany, as one of a group of Irish gastarbeiters. I certainly read a lot, quite often in the library at University College Dublin, looking out over the lake to Dublin Bay, or in public libraries around the city, benefiting from and growing to appreciate that vital social infrastructure (although I would not have used that expression back then). Dublin City Council (then known as Dublin Corporation, the local authority which included Dublin City public libraries) extended me a lifeline, as recruitment was based on the results of one's closing exams in secondary (aka high) school. And so I began a career in libraries, as a library assistant in the Dublin city system. It was hierarchical and rigid, as you might expect from a local government bureaucracy of the 1980s. However, that is not the experience that has mostly stayed with me. I remember those years affectionately, especially valuing the collegial working and social atmosphere with peers.
I was particularly pleased to work for a while in the imposing Rathmines branch, with which I was very familiar as a child. I grew up several miles from there, in a suburb built in the 1960s. Once I had read all the books in our smaller more local branch, I would take the bus to Rathmines. For me, Rathmines was an introduction to institutional gravity and civic opportunity. I remember the impact on a young child of the granite steps worn away by footsteps over the years, the brass railings, the William Morris glass stained window, the linoleum, the sense of a building rooted in its environment and not merely laid down on top of it. It was a touching experience to go back as a staff member, and to see the hidden working interiors of the building, the corridors and basement of additional collections, the comfortably shabby staff room.

Rathmines Public Library
I worked in several branches during those years, and I spent a year on 'relief' work, where we processed books in the morning and then were sent out to replace staff on leave on the afternoon or evening shifts. I enjoyed cycling to parts of the city I did not know. Occasionally, we would go to the cinema in the afternoon if we were on evening shifts. I remember seeing David Lynch's *Dune* and *Once Upon a Time in America* in one marathon afternoon session.
> For me, Rathmines was an introduction to institutional gravity and civic opportunity. I remember the impact on a young child of the granite steps worn away by footsteps over the years, the brass railings, the William Morris glass stained window, the linoleum, the sense of a building rooted in its environment and not merely laid down on top of it.
I also came to respect the senior library assistants who ran operations in many of these libraries. Many were expert in so many ways, especially as they got to know not only the books in the lives of their readers, but also the readers in the lives of their books. Later, in library school, I found the expression 'paraprofessional' jarring. On moving to the US, I had a similar reaction to the strong distinction between 'staff' (a generic word, after all) and 'librarian' (see the discussion of 'staff' morale [here](https://www.tandfonline.com/doi/full/10.1080/01930826.2022.2026119?ref=lorcandempsey.net)). I do think the MLS is important. There is specific expertise of importance, and some indeed that is transferable to other domains. I also think it is important to understand and appreciate the history and values of the profession. However, it is also important to acknowledge that libraries depend on a variety of skills and capacities to succeed, and we should respect all of those contributions.
## Do not be discouraged
While working, I took some time off to complete my undergraduate degree (in English Language & Literature). This was something of a challenge, as things weren't as flexible then. My thoughts then turned to the longer term. Dublin Corporation had a scheme under which it sent selected qualified library assistants to library school in University College Dublin (UCD), paying tuition and salary. I applied for one of the Dublin Corporation places. However, they decided that I was not librarian material and I was not selected. Only temporarily discouraged, and convinced I wanted to be a librarian, I decided to take a career break, borrowed some money, and headed off to UCD. I knew what I wanted to do. I haven't looked back.

The National Library of Ireland
## You always have more to learn
We are doubly immigrant (my wife, Ann Lennon, is also from Dublin and also a librarian). We moved from Ireland to the UK as part of the last wave of economic emigration before the economic boom of the 1990s ("the Celtic Tiger"), at a time when public service jobs in Ireland were difficult to find. Our children were born in Bristol (the Portland of the UK, I read recently), and we loved living for a while in Camberwell, in South East London. Years later, we moved from the UK to the US, arriving just a couple of months before 9/11\. Ireland, the UK and the US certainly share a lot, not least a language (notwithstanding George Bernard Shaw's purported remark about England and the US being countries divided by a common language). However, they are also very different. Think of the role of government or public spending, of how race influences social and cultural contexts, of attitudes to flags and emblems and what they signify, or of the role and character of religious belief. And of course, the experience of moving as an Irish person to England in the late eighties is very different than moving later as an Irish person to the US. This movement between countries has made us very aware of multiple identities, of power relations embedded in language and accent, and of the subtle, and often less than subtle, influence of national stereotypes, both good and bad.
This has meant that I am used to being at an angle to things, I have learned to try never to take anything for granted, and I understand only too well from experience that I do not always have perfect or even very good judgement or intuition. I understand that my background affects how I behave or how I think and importantly how I can seem to others. I always have more to learn, whatever the situation, and it is dangerous to rush to quick judgement.

The interior of the IM Pei-designed public library in that architectural marvel, Columbus Indiana. There is a Henry Moore sculpture in front of the library, which Pei suggested so that its curves would provide a contrast with the angles of the library.
## Work with people who can teach you things
I have been extraordinarily lucky in my career. In Jisc and OCLC I have worked for service organizations that, in very different ways, allow libraries to collaboratively scale their capacities and impact. Jisc is a national agency which provides networking, infrastructure, licensing and advisory services to UK post-secondary educational institutions. OCLC provides shared infrastructure and data services to thousands of libraries around the world. I have managed two very influential library research and policy units, UKOLN (at the University of Bath) and OCLC Research, in the UK and US respectively. The work that my colleagues have done in these units has had influential and far-reaching impact. I joke that my modest success is down to the fact that I have always worked with people who are smarter than I am. But I am not really joking - I have always worked with smart, dedicated people, ambitious to make a difference. They have made me better.
> This has meant that I am used to being at an angle to things, I have learned to try never to take anything for granted, and I understand only too well from experience that I do not always have perfect or even very good judgement or intuition.
## Be curious. Visit.
Talking to people working in libraries and visiting different types of libraries enriches your sense of what is important and again improves judgement and intuition.
Larger conferences play an important role in our community. However, I much prefer smaller events, state or regional meetings, or indeed visits to individual libraries. When people are in situ, and are comfortable talking about experiences and challenges, one can learn and appreciate so much.
I also like to visit libraries as a tourist, to look around, to see what is going on and to watch the people using them. Whenever we travel, we visit libraries (our children had seen all the national libraries in the UK and Ireland at a very young age). Whenever I am at an event, I head out if I have any spare time (as when [I visited](https://www.lorcandempsey.net/calgary-public-library-a-civic-presence/) the very nice Calgary Public Library). Although I am often associated with the digital, I am very drawn to library places and to the very practical as well as symbolic role good spaces play in community settings.


Eoghan and Eavan at the British Library, c 2006
## Grow into your voice - Focus on equity and empathy
We have been pleased to work on the [REALM](https://www.oclc.org/realm/home.html?ref=lorcandempsey.net) project at OCLC, assisting libraries, archives and museums navigate pandemic issues. In a recent meeting, attendees were asked where they needed most help. These were the two top responses:
1. How to support self-care and morale
2. Centering diversity, inclusion, and equity during a crisis
This emphasis is not surprising, given the experiences we have seen in stretched and stressful work environments, but it is worth calling out. And although I do not work in a library, I am lucky at OCLC to be able to interact with many who do, across libraries of all types. The increased focus on staff morale and self-care has been especially noticeable as the pandemic proceeded and accumulated stresses become more apparent.
> Although I am often associated with the digital, I am very drawn to library places and to the very practical as well as symbolic role good spaces play in community settings.
In fact, these experiences make me recognize that I tend to talk about 'the library' in my writing on libraries and their directions, rather than about the people who are doing the work or on the capacities needed to move in particular directions. I should be more thoughtful about this. There is always more to learn ...
The murder of George Floyd crystalized attention to deep structural issues of racism, as one instance of a pattern of violence against African Americans in the US. As a white person who had lived here for 20 years, I was still shocked to see a white woman in Central Park act knowingly in the context of a structural imbalance of power as she called the police. Or to listen to the African-American mayor of Atlanta open her remarks about rioting by saying that she had warned her son to stay at home, because despite her high office she could not protect him. Libraries and other organizations recognized a need to purposefully move past mere statements of equality, to recognize harm or omission and to begin to repair damaging and exclusive practices. (The [Reckoning Initiative](https://protect-us.mimecast.com/s/sSL3C2kXA7tZ83BNf97j6%5F?domain=library.unc.edu/&ref=lorcandempsey.net) at the University Libraries, UNC Chapel Hill, represents a notable example of an initiative to scale learning, recognition and change across the organization.)
The pandemic has highlighted these racial inequalities. It has also underlined economic inequities, the digital divide, the importance of available social infrastructure, especially for those that critically rely on library spaces and extended services. Libraries have been asked to step up to additional roles and to reshape services.
So, there is now additional pressure on our organizations and the people who work in them, already stretched by developments over the last few years as they take on additional assignments or manage through budget changes. Libraries faced immediate issues around staffing shortages, reconceiving services for online or curbside delivery, managing through political or policy differences. Library workers have been asked to do work they are not prepared for, to deal with difficult patrons, or to take on additional roles. Organizational and hierarchical differences have been emphasized by the uneven need to be physically present at work or to deal with patrons. The cumulative effect of these pressures can be draining, and empathy can be difficult. In this context, a colleague drew my attention some time ago to the important work of Kaetrena Davis Kendrick on [empathy and self-preservation](https://kaetrenadaviskendrick.wordpress.com/?ref=lorcandempsey.net) in the workplace.
At the same time, I believe that the REALM responses point to a longer term sea-change in sensibilities and expectations. This may be unevenly manifested, but underlines the need for the library to recognize the importance of equity and empathy, in terms of both value created and values embraced. We know that libraries are social organizations supporting mental wellness, social cohesion, and personal and community development. Current experience has fore-grounded these roles.
Of course, equity and empathy can just be labels, verbal Febreze that masks underlying realities. They need to be supported and developed in real ways. I am trying to listen more, to ask more questions, to take active measures to understand different experiences and perspectives (of our colleagues and in communities served), to respect time thresholds between work and life, to actively extend the range of my reading and media consumption as well as who I follow on social media, to try and step aside when appropriate, or to promote the voice and contribution of colleagues. I need to pause to check bias.
> Of course, equity and empathy can just be labels, verbal Febreze that masks underlying realities. They need to be supported and developed in real ways.
But this is not just an individual responsibility, and ramifies through institutional and social contexts. There is a responsibility for those of us in positions of authority to be open to uncomfortable feedback, to resist the performative or facadist, to recognize how privilege may prevent us from understanding or seeing issues, or from understanding how difficult it may be for somebody to speak up, and to create the space and momentum for change.
So, this is actually an extraordinary time to be entering the library profession. It is also a difficult time, as noted above. I believe that an important pandemic effect will be a reexamination of library identity and the emergence of a more holistic view of the library, across network and place. Libraries have had to think about how to deliver a fuller library service online. Defining the library in terms of expertise and services, rather than in terms of a building and collections is an ongoing challenge.
All of this makes it a time when new ideas and voices need to be heard. It is a time when it is important for those coming new to library work to bring their perspectives on value and values to that work.


Dayton Metro Library; New Americans Center at Los Angeles Public Library; Explaining the mural at Hilltop branch, Columbus Metropolitan Libraries; UIUC; Calgary Central Library; Images on Case Western Reserve University library elevators; Castletownbere, Ireland; E&E at DLR Lexicon, Dun Laoghaire; Irish mobile library.
## Reading and writing
It may sound glib, but it is good to read and write. It is important to read around our area, to think about social or cultural contexts. For example, my thinking about library technology has been influenced by the sociotechnical theory and research of Wanda Orlikowski, which a colleague introduced me to several years ago. It may be beneficial, for example, depending on one's focus, to read about the dynamics of higher education or about placemaking or urban planning.
Writing is useful as a way of working through your thoughts, as a way of prefabricating positions or arguments, as a way of becoming more fluent in a topic.
I have always combined my work responsibilities with my writing and speaking. My early focus was very much on the emerging apparatus of metadata, networking and technologies, flowing from my day to day work interests. However, over time there has been an evolution from the specialist to the more social or organizational, which is maybe not surprising in a typical career trajectory? It also reflects of course the changing reality of digital and the network during these years, as they have become progressively more entangled with our behaviors and social organization.
> Writing is useful as a way of working through your thoughts, as a way of prefabricating positions or arguments, as a way of becoming more fluent in a topic.
I write to be read, so I try to publish in open access resources, or to make an open access copy available. As a profession we should be careful about what and how we publish. Here is an annotated overview of my writing and writing interests, including a note about influences.
[WritingI have written widely over the years. Topics have evolved, but follow a general chronological arc from the technical, through the description of evolving digital systems and services, to organizational and institutional issues.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/writing/)
## Bring your interests to work
Our working lives are inevitably variably interesting. It is good to have special interests, where we have some expertise or enjoyment. Sometimes, if we are lucky, this may support a special contribution in a work context (maybe a language?), but will certainly more generally provide sustenance.
A modest example. In library school, the course I enjoyed most (and did best in) was Children's Literature. I did not anticipate working in this area: I chose to do this given a general literary interest, but I was also influenced by the fact that [my father](https://www.worldcat.org/identities/viaf-315628761/?ref=lorcandempsey.net) was a teacher and had written a series of readers when we were growing up. We were lucky in an inspirational lecturer on the course, Pat Donlon, later the National Librarian of Ireland. I remember the pleasure of writing about the Ahlbergs, looking at how *Peepo!* works in particular. And later as our own children were growing up, I remember the delight of discovering, say, the lovely Katie Morag books by Mairi Hedderwick, set on a beautifully illustrated Scottish island, or the poignant *Tree of Cranes* by Japanese-American writer, Allen Say, more significant for us given its touching treatment of cultural negotiation.

Our copy of Peepo! In the US, it is published as Peek-a-boo!
For me, the international dimension of library work is another example. Given our background I have always been interested in the international and comparative element of libraries. I have been lucky in my positions to have been able to travel. And I did a lot of early work in various capacities with the European Commission when it had [a libraries program](https://liberquarterly.eu/article/view/10850?ref=lorcandempsey.net). OCLC serves libraries around the world, and I welcome the opportunities that provides to visit and engage. I have been pleased to work in recent years with our [Global Council](https://www.oclc.org/en/membership/councils/directory.html?ref=lorcandempsey.net), an engaged international group. Of course, this is not possible for everybody, but that international dimension is particularly enriching, in terms of exploring similarity and difference across different cultures, social and political contexts, and professional traditions.
## And finally, there are many paths
My family doesn't always like it when I am the driver ... I favor the scenic route, the diversion to see a new town or feature of interest, the long way home.
People take different views of their careers or expectations. Some have goals, some are more opportunistic. My own experiences have certainly not followed a straight line. While my career has some unity of emphasis, I have also made major lateral moves in unanticipated ways, between jobs, between countries, and between interests. So take chances and understand that there are many paths!
**Pictures:** All pictures by the author. The feature picture includes windows from seeral libraries. Clockwise from upper left: DLR Lexicon, Dun Laoghaire (created by children, after Matisse); Burns Library, Boston College (by Richard King, an associate of important Irish artist, Harry Clarke); National Library of Australia (by Leonard French); Rathmines Public Library, Dublin (by William Morris).
**Note:** This entry was first drafted before the [announcement](https://www.oclc.org/en/news/releases/2022/20220121-lorcan-dempsey-retires.html?ref=lorcandempsey.net) about my latest move, as I transition into the next chapter ...
**Acknowledgements:** I am grateful to Ann Lennon for advice about an earlier draft, as well as to Eavan and Eoghan Dempsey. And also to my OCLC colleagues Pam Bailey, Kathleen Gesinger, Andy Havens, Erica Melko, Bob Murphy, Sharon Streams and Steph Waite. Thanks too to Aedín Ní Bhróithe Clements, Earl B. Givens Jr., David Lankes, Cathal McCauley,James Neal, Margaret StokesandJohn Wilkin. Of course, all opinions (and memories) are my own.

The National Library of Scotland
**Updates:** 4/10/22: Small editorial update. Comment about accents added. 1/26/23: pull quotes added. 2/24/2024: Turned text to headings, generated TOC. 1/2/24: Caption on feature picture moved to note.
### Workflow is the new content 1: looking at research support and engagement
URL: https://www.lorcandempsey.net/workflow-is-the-new-content/
Last updated: 2025-09-15T21:05:36.000Z
Writing [here](https://www.lorcandempsey.net/orweblog/one-handed-writing-the-blog/) in 2017, I noted that my occasional blog entries tended to balloon into article proportions. One was on research workflows, very much from a library point of view. I reviewed the draft and decided to publish it here, splitting it into three linked entries. While I have updated it somewhat, it retains references from back then. It is largely descriptive, and is meant to frame an area of interest. Much has been written on these general topics in the interim, as well as much more specialist coverage of particular areas.
I originally imagined three posts. However, as time moved on, this seemed less sensible and the material I originally envisaged will be generally incorporated elsewhere. I kept the '1' in the title for continuity of naming!
## Workflow is the new content
The digital environment makes workflow support more important, as activities, content, and communications are tied together on the network in various combinations. This is especially the case as more of our activity moves to the cloud. Think of the interesting interaction of social media, computational engines, and chess, for example, or of the mix of social and functional capacities in an application like Strava, used by athletes to track and compare performance as well to connect with other athletes. In a library or research environment this trend is also clear. Think of reading and ebooks, or of the evolution of citation management applications from simple lists to fuller scholarly platforms. Research practices, and the support provided by libraries, publishers, community and disciplinary projects and others, provide an intriguing example, as workflows produce, manage and consume content, enable collaboration, and tie devices together to get things done. Increasingly, we are aware of how digital workflows are an important element of information use, and moreover how the evolution of workflow, data, and behaviors are mutually constitutive.
I have been using the phrase "workflow is the new content" in presentations for several years now. It is probably too emphatic a statement, but it has resonated.
> Increasingly, we are aware of how digital workflows are an important element of information use, and moreover how the evolution of workflow, data, and behaviors are mutually constitutive.
In these posts I focus on research workflows. More particularly, I look very specifically at **library support and partnership** in the research process. Here are some headlines:
### A complex, emergent ecosystem
Digital research practices are emergent, with multiple stakeholders, diverse service providers, and a profusion of approaches across disciplines and institutions. There is a huge range of activity in collaborative research communities, labs, universities and research centers, as well as in individual work practices. This activity is so wide-ranging, so pervasive, and of interest to so many, that it generates a rich ecosystem of communities, systems, services and data resources. This will never be enclosed by any one set of services, nor of course will it necessarily always intersect with the library.
### Open: Policy and mandates
The movement to open access is complicated, with many strands. While it may have no single destination, it is a clear broad direction. Different strands create different workflow requirements (e.g. institutional repositories, compliance monitoring, managing APCs, and so on). National governments, research funders, and individual institutions are developing policies around research evaluation, open access, open science more broadly, and related issues. Some countries have research evaluation frameworks in place (e.g. the UK) which can very strongly influence research and publishing practices. Plan S represents a coalition of funding interests putting in place a policy framework for the publication of outputs from the research they fund. Depending on the context, such policy apparatus creates a need for tracking and compliance workflows. We can see how, for example, the national research evaluation frameworks in the UK have promoted early wide adoption of institutional repositories, followed by widespread adoption of research information management systems. And these in turn need to work together, and with other emerging research infrastructure. At the same time, it is clear that the industry supporting scholarly communications is evolving to adapt services and business models to retain and grow revenues in a changed environment. In parallel, a range of community and advocacy groups has emerged, variously convening stakeholders around tools, guidance and lobbying work.
### Research analytics and the prestige economy: the research reputation industrial complex
Ranking and assessment have become an integral part of higher education. University rankings have become very influential and universities have become more purposeful in understanding how they work and how they might be influenced. At the same time, impact factors, citation counts, and so on, play a role in the assessment of individual researchers. Of course, this is seen by many to be distorting the research system and introducing harmful incentives, and is certainly resisted by some.
For example, as part of its move to open science, the University of Utrecht decided that it would no longer count impact factors, the h-index, and so on, in its recognition and reward [frameworks](https://www.uu.nl/en/research/open-science/tracks/recognition-and-rewards?ref=lorcandempsey.net). It is also interesting to see continuing [extensive coverage](https://www.uu.nl/en/organisation/profile/facts-and-figures/utrecht-university-in-rankings?ref=lorcandempsey.net) of how well Utrecht performs in global rankings which in part also rely on that same 'research reputation industrial complex.' However, the University carefully qualifies any apparent endorsement of the rankings, noting amongst other factors that they depend too much on scoring and competition, whereas science depends on collaboration.
In this context, note the [Declaration on Research Assessment](https://sfdora.org/read/?ref=lorcandempsey.net), an initiative to change the basis of scholarly assessment. Three companies, especially, are heavily invested in this space. In the absence of a general industry category I call these three organizations **scholarly communication service vendors**. Elsevier, Clarivate \[[1](#footnote)\], and Digital Science, are variably positioning themselves to support research analytics and assessment (as well as broader research workflow services, as discussed later). Each presents a graph-based view of the core of scientific knowledge as represented in the literature, through Scopus, Web of Science and Dimensions, respectively. Increasingly they want to document research entities (researchers, outputs, organizations, etc), they want to analyze research knowledge as represented by those entities, and they want to visualize research patterns and relationships. And then to provide a variety of decision support, discovery and evaluative services on top of those structures.
### Market for workflow services
Given the need for workflow support, the uncertain transition to new and open publishing models, the growing market for research analytics, the need to grow and diversify revenue opportunities across campus (and elsewhere), major publishers and other organizations have been developing research workflow and analytics solutions. The evolution of Elsevier, Clarivate and Digital Science (as part of the Holtzbrinck group, also containing Springer-Nature) has been noted. These companies are diversifying their capacities through a mix of build and buy strategies. At the same time, groups looking at open and non-profit approaches have also emerged in a rich pattern of organizational models and activities (including advocacy, service and infrastructure development, training and awareness, and so on). In fact, one motivation for some of these organizations and for those that support them is to resist the role of for-profit companies in this space. Examples include the Center for Open Science, SCOSS (Sustainability Coalition for Open Science Services), OpenAIRE, and OurResearch.
### Library support and partnership
Libraries are responding in different ways, individually and collaboratively. They may offer advice and referral, education and training, and may build or otherwise provide tools and services for their researchers. The library is also an expert partner for advice about evolving scholarly communication, about appropriate use of assessment and metrics, about available tools and services, and about discovering research outputs elsewhere. See this [nice summary](https://hangingtogether.org/libraries-are-essential-partners-in-research-information-management-rim/?ref=lorcandempsey.net), for example, of the value the library brings to research information management discussions on campus. Support has moved beyond the original institutional repository to encompass a variety of services, which often need to work together and with other campus services. At the same time, libraries are working in variably patterned campus partnerships to provide services: [social interoperability](https://www.oclc.org/research/publications/2020/oclcresearch-social-interoperability-research-support.html?ref=lorcandempsey.net) on campus is key. Increasingly, the library is positioning itself as a research partner to researchers and to research administration. Becoming involved in working with researcher workflows like this is especially important for libraries in two important ways. First, it requires cross campus discussions, establishing the library as a campus partner around research-critical activities. Second, it provides an opportunity to engage with researchers, labs, departments, and so on, in new ways, which is especially important when the pandemic has reduced interaction, and collections-based interactions may be changing. Finally, the library may be the only stakeholder that is actively interested in the long term retention and use of research outputs, a major topic in itself.
### Computation and data
The computational nature of much research leads to the generation, consumption and processing of large amounts of data. This may be at individual, research group, institutional or disciplinary level. This creates a need for data management and tools support. At the same time, as the volume of publications grows, publishers and others are looking at ways of supporting computational reading at scale, mining text for insights and patterns. And finally, the automation of workflows and the generation of data of course go hand in hand, as activities are tracked and measured. The appropriate use of such tracking data is itself an important question.
## Life cycles: characterizing research ecosystems
This interest in digital workflow support has resulted in many conceptualizations of the research life cycle, and mappings of tools, workflows and advice to these. These conceptualizations are important to solution providers (to characterize distinctive disciplinary workflows, for example) and to institutions implementing workflow solutions (to clarify if the right mix of solutions is on offer, or to highlight where critical service gaps exist).
Consider, for example, this example from Carnegie Mellon University which shows how it provisions support services in different phases of a research lifecycle
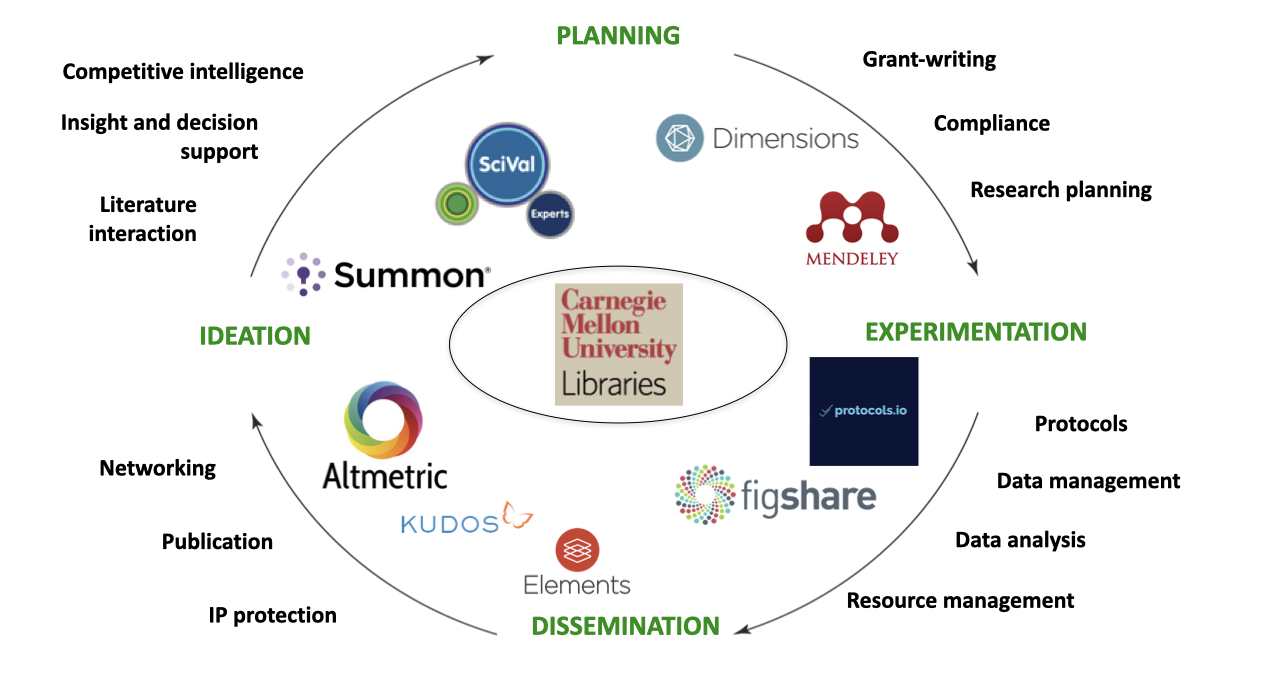
Carnegie Mellon University Libraries - research lifecycle.
This is interesting because it highlights how choices have to be made about how broadly to **scope** research workflow and other services, and also how to **source** research support services. Carnegie Mellon has a particularly extensive set of services and it is also interesting in that it has a partnership with Digital Science (which offers a suite of workflow solutions), alongside other providers. Other institutions may make different choices, prioritizing open source alternatives for example.
Many other examples of research lifecycle diagrams exist. The abundance of such visualizations is evidence of growing attention to workflows and how to support them. For instance, the [Open Science Framework](https://www.cos.io/products/osf?ref=lorcandempsey.net) diagram describes a broad service ecosystem. It is interesting to note the variety of services mentioned, and also how many involve the discovery, management and disclosure of content of various types. The OSF schematic shows how content and workflow needs throughout the lifecycle create support opportunities for both publishers and libraries, which in turn creates more potential for both partnership and competition between these and other stakeholders.
As the Carnegie Mellon example shows, research lifecycle schematics are also helpful for describing institution-scale infrastructure. This [example](https://library.ucf.edu/about/departments/scholarly-communication/overview-research-lifecycle/?ref=lorcandempsey.net) from the University of Central Florida depicts research workflows as a sequence of inter-related cycles, each dependent on a different mix of campus-level services. The UCF graphic emphasizes the variety of potentially involved actors on campus, underlining again the important social interoperability component of research support/engagement.
## Workflows: tying people, data and applications together
As research behaviors are enacted in data-rich computational environments the way in which library support and partnership is thought of changes. Again, what is of special interest here is where workflows increasingly manage, generate and consume content. This motivates new services from libraries, publishers and a whole range of service providers and community initiatives. What are some of the areas where workflow support is important? Here are some areas where there the library is potentially a strong partner:
### Curation and sharing of research outputs: the evolving scholarly record
In the print world, the final article or book was the main output. In a digital environment, the research process generates a variety of sharable research outputs: these include preprints/articles, software, research data, textual corpora, methods, and workflows. The curation and purposeful disclosure of these resources is a growing interest of researchers and research groups, universities, and libraries. It is also of interest to those who fund research and are interested in reproducibility, access, and so on. Disclosure may take several forms: on an institutional website, depositing in a local or disciplinary repository, sharing metadata with aggregators, and so on. Researchers themselves may share outputs in a variety of venues, some of which may have a discipline- or a format-specific focus. Here are some examples: [Arxiv](https://arxiv.org/?ref=lorcandempsey.net) for papers in the high energy physics community, the [Biologic Specimen and Data Repository](https://biolincc.nhlbi.nih.gov/home/?ref=lorcandempsey.net) for biospecimans or data sets, and [myexperiments.org](http://myexperiments.org/?ref=lorcandempsey.net) for workflows. General-purpose tools may also be used (e.g. GitHub for data and software). The rise of ResearchGate has been interesting in this context, building additional network value around research interests and paper sharing. And in a common pattern, there is also a non-profit initiative in Humanities Commons, built on Commons in a Box software (developed by CUNY and others, based on WordPress and other technologies). Furthermore, in some countries there is national attention to the creation and sharing of research outputs ([RDNL](https://researchdata.nl/?ref=lorcandempsey.net) and [ARDC](https://ardc.edu.au/about%5Fus/?ref=lorcandempsey.net) in The Netherlands and Australia respectively, for example, which focus on research data). Again, an important driver is national or funder imperatives to share research data, eprints, or other research outputs.
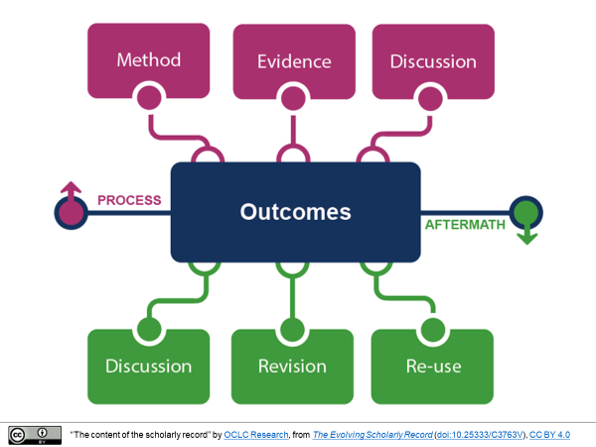
Components of the evolving scholarly record
### Identity and reputation management
For many researchers there is increasingly a blurring of content, workflow and network identity as they disclose and share publications and experience in Google Scholar, ResearchGate, or other scholarly communication networks as part of ongoing work. These services create additional network value. At the same time, their institutions are similarly curating and disclosing profiles through [research information management systems](https://www.lorcandempsey.net/orweblog/research-information-management-systems-a-new-service-category/) or other systems. Visibility and impact are very important to researchers and to institutions, especially in the dynamics of the research reputation industrial complex as noted above.
### Changing publishing models
The scholarly communication ecosystem is being transformed, as the pandemic accelerates research, as funders push towards open science, as new licensing models continue to evolve, and as data, methods and other outputs are published. Funder mandates or national policies may impose requirements on researchers, publishers and universities. Different open access paths may include different decision points, information needs and workflows. Universities are tracking publication for internal purposes, but now also to assure compliance with various mandates, or to track APCs or other aspects of licenses. This all creates additional requirements for managing publishing workflows.
### And more
But of course there is a much broader context where workflow is important. For example ...
- **Process support:** Think of laboratory information systems, electronic lab notebooks, and scientific workflow systems (e.g. [Taverna](https://taverna.incubator.apache.org/?ref=lorcandempsey.net)), which provide 'prefabricated' workflow support, articulating tools around particular processes. And at the same time, researchers assemble their own workflow from many tools - collaborative working and document sharing for instance, or data analysis and visualization approaches. The [Open Science Framework](https://osf.io/?ref=lorcandempsey.net), mentioned above, aims to provide an integrated platform for the management of research projects and the outputs associated with them.
- **Instruments and infrastructure.** Much research, especially in STEM subjects requires access to expensive or specialized scientific instruments and other infrastructure. This may again be provided in various ways, within and across institutions. Ithaka S+R recently [described](https://sr.ithaka.org/publications/what-is-a-research-core/?ref=lorcandempsey.net) developments on campus with Research Cores, a response in which, typically, the Office of Research secures shared provision.
Increasingly, workflows manage, produce and consume content of interest. Later posts in this series consider some further aspects of this evolving area in more detail.
\[1\] Clarivate has recently purchased ProQuest. The author works for OCLC which has some products which compete with ProQuest products.
**Acknowledgements:** Thanks to my colleagues Rebecca Bryant, Ixchel Faniel, Brian Lavoie, Constance Malpas, and Titia van der Werf for commenting on a draft, and also to Keith Webster for his helpful observations. All interpretation and views are of course mine.
**Pictures:** The feature picture was taken by me in 2019 in the Taylor Family Digital Library at the University of Calgary. The CMU Libraries lifecycle picture was kindly supplied by Keith Webster.
**Updates:** (11 Nov 2022) Flow of opening amended. Number of parts reduced from 4 to 3\. (15 May 2023) I added the label 'scholarly communication service vendors.' (15 Sept 2025) Amended to note that it was a self-standing post, and not part, as originally envisaged, of a series.
### Presentations: Collection directions, pandemic effects, Belgium, Italy
URL: https://www.lorcandempsey.net/presentations-collection-directions-pandemic-effects-belgium-and-italy/
Last updated: 2023-05-19T02:22:07.000Z
## Rethinking professional assembly
A clear pandemic effect will be a rethinking of professional assembly. When does it make sense to think about a face to face event? When and how do you do hybrid events? And how many events will go to online only? Of course, it is not just a choice of mode. Our sense of how to present online is different than it might be in person. It is likely we will see more polls or other ways of interaction, more ways of breaking up events into effective chunks, and new kinds of experience influenced by gaming and other approaches. It will be important to think about social interaction in this context. Of course, face to face events will also change, to emphasise those elements where they deliver special value.
Here are some pointers about delivering effective online events from my colleagues:
[Virtual is Here to Stay: Making Online Sessions Fun and FocusedLearn strategies to plan, design and host live online meetings or presentations that will energize, inform, and encourage your audience.WebJunction](https://www.webjunction.org/events/webjunction/virtual-is-here-to-stay.html?ref=lorcandempsey.net)
## Informatie aan Zee and Bibliostar
I was disappointed recently not to be able to travel to Ostende to present at [Informatie aan Zee 2021](https://www.vvbad.be/Informatie-Aan-Zee-2021?ref=lorcandempsey.net), the conference of VVBAD the professional association for the information sectors in Flanders.
I delivered this presentation online talking about how the pandemic is influencing library orientation and strategies, and then focusing on collections. I presented a modified version of the material a while before at the Bibliostar conference in Milan, again regretting that I could not attend.
This presentation is pretty much delivered as it might have been live, but I did miss the audience, the questions, the interaction.
## Presentation, video, interview
Here is the presentation:
[Collection DirectionsThis is a presentation presented at Informatie aan Zee in Belgium and in modified form at Bibliostar in Italy. It discusses some Pandemic Effects and how various collections trends are being affected.figshare](https://figshare.com/articles/presentation/CollectionDirectionsOstendeBibliostar%5Fpptx/17001154?ref=lorcandempsey.net)
Here is the video that was shown to Informatie aan Zie:
I was pleased to do an interview with Paul Buschmann for the VVBAD publication *Meta: Tijdschrift voor bibliotheek & archief*, 2021 (7) p.22-23\.
[Collection directions and pandemic effectsInterview: Collection directions and pandemic effectsVVBADPaul Buschmann](https://www.vvbad.be/meta/meta-nummer-20217/collection-directions-and-pandemic-effects?ref=lorcandempsey.net)
Related to the Bibliostar event, there was a translation of a [recent blog entry](https://www.lorcandempsey.net/collection-directions-accelerated/) on similar topics in the publication associated with the event. (A copy is also available [here](https://www.oclc.org/content/dam/oclc/email/EMEA/it-landing-page/gli-effetti-della-pandemia-stanno-accelerando-lo-sviluppo-delle-collezioni.pdf?ref=lorcandempsey.net).)
[La biblioteca piattaforma della conoscenza - AA. VV. - Ebook Editrice BibliograficaCompra Ebook La biblioteca piattaforma della conoscenza di AA. VV. edito da Editrice Bibliografica nella collana Il cantiere biblioteca.www.editricebibliografica.itAA. VV.](https://www.editricebibliografica.it/scheda-ebook/aa-vv/la-biblioteca-piattaforma-della-conoscenza-9788893574280-579588.html?ref=lorcandempsey.net)
### Presentation: Two Metadata Directions
URL: https://www.lorcandempsey.net/presentation-two-metadata-directions/
Last updated: 2022-11-08T19:59:34.000Z
## Conference
I was pleased to deliver a presentation at the Eurasian Academic Libraries Conference - 2021, organized by The Nazarbayev University Library and the Association of University Libraries in the Republic of Kazakhstan. Thanks to April Manabat of Nazarbayev University for the invitation and support. I was asked to talk about metadata and to mention OCLC developments. The conference topic was: *Contemporary Trends in Information Organization in the Academic Library Environment.*
Further information here:
[Nazarbayev University LibGuides: Eurasian Academic Libraries Conference - 2021: HomeNazarbayev University LibGuides: Eurasian Academic Libraries Conference - 2021: HomeNazarbayev University LibGuides at Nazarbayev University](https://nu.kz.libguides.com/EALC-2021/home?ref=lorcandempsey.net)
## Topic
I spoke about two trends in metadata developments: entification and pluralization. Each of these is important and I provided an example under each head of a related initiative at OCLC.
I discuss these trends in more detail in a recent blog entry, which recapitulated and extends the material presented at the conference:
[Two metadata directions in librariesMetadata practice is evolving. I discuss two important trends here: entification and pluralization.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/metadata-directions/)
## Presentation materials
The slides as presented are here:
[kazak.pptxThis is a presentation about trends in metadata, focusing on two important issues. The first is entification, moving from strings to things. The second is pluralization, as we seek to better represent the diversity of perspectives, experiences and memories. It discusses an OCLC initiative associated…figshare](https://figshare.com/articles/presentation/kazak%5Fpptx/15057288?ref=lorcandempsey.net)
Here is a video recording of my presentation:
The conference organizers have made the full video of the sessions available. Here is the video for day two, which should begin as I begin speaking. Move back to see more of the presentations.
As we prepared the video, I did reflect on the future of conferences and conference-going. Clearly, much to work through here, and we are certainly seeing new and engaging online and hybrid experiences. In writing the accompanying blog entry, I finished with this observation:
> The Pandemic is affecting how we think about work travel and the design of events, although in as yet unclear ways. One pandemic effect, certainly, has been the ability to think about both audiences and speakers differently. It is unlikely that I would have attended this conference had it been face to face, however, I readily agreed to be an online participant. // [Two Metadata Directions](https://www.lorcandempsey.net/metadata-directions/)
### Two metadata directions
URL: https://www.lorcandempsey.net/metadata-directions/
Last updated: 2023-01-17T18:05:52.000Z
This short piece is based on a presentation I delivered by video to the [Eurasian Academic Libraries Conference - 2021](https://nu.kz.libguides.com/EALC-2021/home?ref=lorcandempsey.net), organized by The Nazarbayev University Library and the Association of University Libraries in the Republic of Kazakhstan. Thanks to April Manabat of Nazarbayev University for the invitation and for encouragement as I prepared the presentation and blog entry. I was asked to talk about metadata and to mention OCLC developments. The conference topic was: **Contemporary Trends in Information Organization in the Academic Library Environment.*
## The growing role and value of metadata
Libraries are very used to managing metadata for information resources - for books, images, journal articles and other resources. Metadata practice is rich and varied. We also work with geospatial data, archives, images, and many other specialist resources. Authority work has focused on people, places and things (subjects). Archivists are concerned about evidential integrity, context and provenance. And so on.
In the network environment, general metadata requirements have continued to evolve in various ways:
**Information resource diversification**. We want to discover, manage or otherwise interact with a progressively broader range of resources, research data, for example, or open educational resources.
**Resource type diversification**. However, we are also increasingly interested in more resource types than informational alone. The network connects together many entities or types of resource in new ways, and interaction between these entities requires advance knowledge, often provided by metadata, to be efficient. Workflows tie people, applications and devices together to get things done. To be effective, each of these resources needs to be described. Social applications like Strava tie together people, activities, places, and so on. Scholarly engines like Google Scholar, Semantic Scholar, Scopus or Dimensions tie together research outputs, researchers, funders, and institutions. The advance knowledge required for these workflows and environments to work well is provided by metadata and so we are increasingly interested in metadata about a broad range of entities.
**Functional diversification**. We want to discover, manage, request or buy resources. We also want to provide context about resources, ascertain their validity or integrity over time, determine their provenance. We want to compare resources, collect data about usage, track and measure. We want to make connections between entities, understand relationships, and actually create new knowledge. We do not just want to find individual information resources or people, we want to make sense of networks of people, resources, institutions, and so on and the relations between them.
**Source diversification.** I have [spoken about](https://www.lorcandempsey.net/orweblog/four-sources-of-metadata-about-things/) four sources of metadata in the past. Versions of these are becoming more important, but so is how they are used together to tackle the growing demands on metadata in digital environments.
1. *Professional.* Our primary model of metadata has been a *professional* one, where librarians, abstract writers, archivists and so on are the primary source. Libraries have streamlined metadata creation and provision for acquired resources. Many libraries, archives and others, devote professional attention and expertise to unique resources - special collections, archives, digitised and born-digital materials, institutional research outputs, faculty profiles, and so on.
2. *Community.* I described the second as crowdsourced, and certainly the collection of contributions in this way has been of importance, in digital projects, community initiatives and in other places. However, one might extend this to a broader *community* source. The subject of the description or the communities from which the resources originate are an increasingly important source. This is especially the case as we pluralize description as I discuss further below. An interesting example here is [Local Contexts](https://localcontexts.org/?ref=lorcandempsey.net) which works with collecting institutions and Indigenous communities and "provides a new set of procedural workflows that emphasize vetting content, collaborative curation, ethical management and sustained outreach practices within institutions."
3. *Programmatically promoted.* The programmatic promotion of metadata is becoming increasingly important. We will see more algorithmically generated metadata, as natural language processing, entity recognition, machine learning, image recognition, and other approaches become more common. This is especially the case as we move towards more entity-based approaches where the algorithmic identification of entities and relationships across various resources becomes important. At the same time, we are more aware of the need for [responsible operations](https://www.oclc.org/research/publications/2019/oclcresearch-responsible-operations-data-science-machine-learning-ai.html?ref=lorcandempsey.net), where dominant perspectives also influence construction of algorithms and learning sets.
4. *Intentional.* A fourth source is intentional data, or usage data, data about how resources are downloaded, cited, linked and so on. This may be used to rate and rank, or to refine other descriptions. Again, appropriate use of this data needs to be responsibly managed.
**Perspective diversification.** A purported feature of much *professional* metadata activity has been neutral or objective description. However, we are aware that to be 'neutral' can actually mean to be aligned with dominant perspectives. We know that metadata and subject description have very often been partial, harmful or unknowing about the resources described, or have continued obsolescent or superseded perspectives, or have not described resources or people in ways that a relevant community expects or can easily find. This may be in relation to race, gender, nationality, sexual orientation, or other contexts. This awareness leads directly into the second direction I discuss below, pluralization. It also highlights the increasing reliance on *community* perspectives. It is important to understand context, cultural protocols, community meanings and expectations, through more reciprocal approaches. And as noted above, use of *programmatically promoted* or *intentional* data needs to be responsibly approached, alert to ways in which preferences or bias can be present.
So we want to make metadata work harder, but we also need more metadata and more types of metadata. Metadata helps us to work in network environments.
A more formal definition of metadata might run something like: "schematized assertions about a resource of interest." However, as we think about navigating increasingly digital workflows and environments, I like to think about metadata in this general way:
> data which relieves a potential user (whether human or machine) of having to have full advance knowledge of the existence or characteristics of a resource of potential interest in the environment.
Metadata allows applications and users to act more intelligently, and this becomes more important in our increasingly involved digital workflows and environments.
Given this importance, and given the importance of such digital environments to our working, learning and social lives, it also becomes more important to think about how metadata is created, who controls it, how it is used, and how it is stewarded over time. Metadata is about both value and values.
In this short piece, and in the presentation on which it is based, I limit my attention to two important directions. Certainly, this is a part only of the larger picture of evolving metadata creation, use and design in libraries and beyond.
> So we want to make metadata work harder, but we also need more metadata and more types of metadata. Metadata helps us to work in network environments.
## Two metadata directions
I want to talk about two important directions here.
1. Entification.
2. Pluralization.
### Entification: strings and things
Google popularized the notion of moving from 'strings' to 'things' when it introduced the Google [knowledge graph](https://www.blog.google/products/search/introducing-knowledge-graph-things-not/?ref=lorcandempsey.net). By this we mean that it is difficult to rely on string matching for effective search, management or measurement of resources. Strings are ambiguous. What we are actually interested in are the 'things' themselves, actual entities which may be referred to in different ways.
Entification involves establishing a singular identity for 'things' so that they can be operationalized in applications, gathering information about those 'things,' and relating those 'things' to other entities of interest.
Research information management and the scholarly ecosystem provide a good example of this. This image shows a variety of entities of interest in a research information management system.
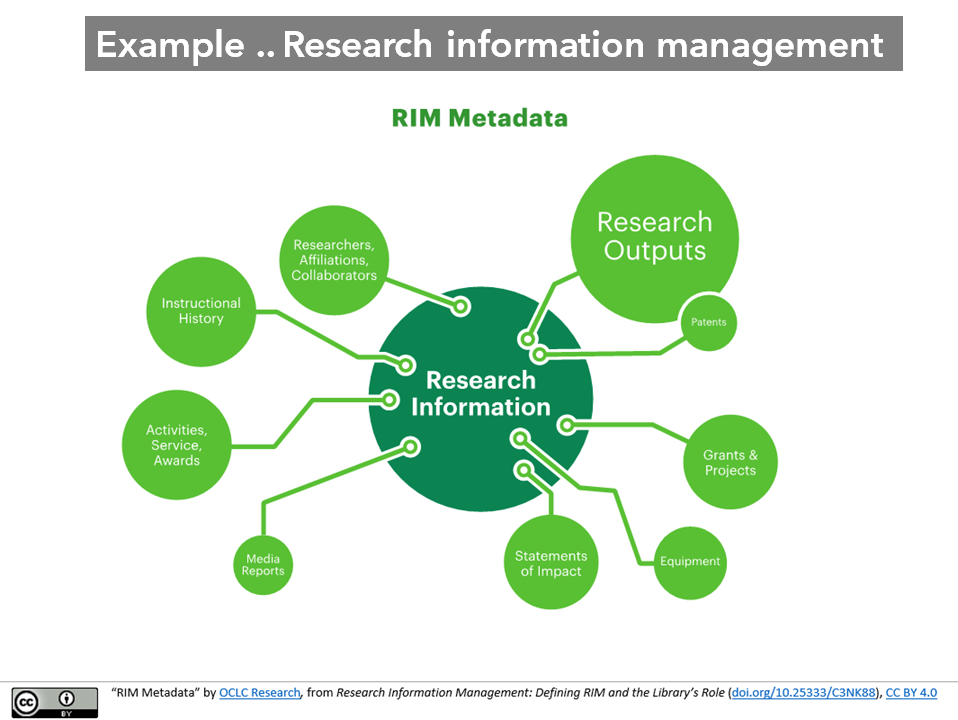
These include researchers, research outputs, institutions, grants and other entities. Relationships between these include affiliation (researcher to institution), collaborator (researcher to researcher), authorship (researcher to research output), and so on. We want to know that the professor who got this grant is the same one as the one who teaches this course or published that paper.
These identities could be (and are) established within each system or service. So, this means that a Research Information Management System does not only return strings that match a text search. It can facilitate the prospecting of a body of institutional research outputs, a set of scholars, a collection of labs and departments, and so on, and allow links to related works, scholars and institutions to be made.
Similarly, a scholarly engine like Scopus, or Semantic Scholar, or Dimensions will bring together scholarly entities and offer access to a more or less rich network of results. Of course, in this case, the metadata may be under less close control. Typically, they will also be using metadata sourced in the four ways I described above, as 'professionally created' metadata works with metadata contributed by, say, individual researchers, as entities may be established and related programmatically, and as usage data helps organize resources.
Wikidata is an important resource in this context, as a globally addressable identity base for entities of all types.
Of course one wants to work with entities across systems and services. Researchers move between institutions, collaborate with others, cite research outputs, and so on. One may need to determine whether an identity in one context refers to the same entity as an identity in another context. So important entity backbone services have emerged which allow entities to be identified across systems and services by assigning globally unique identifiers. These include Orcid for researchers, DOI for research outputs, and the emerging [ROR](https://ror.org/?ref=lorcandempsey.net) for institutions.
These initiatives aim to create a singular identity for resources, gather some metadata about them, and make this available for other services to use. So a researcher may have an Orcid, for example, which is associated with a list of research outputs, an affiliation, and so on. This Orcid identity may then be used across services, supporting global identification and contextualization.
Here, for example, is a profile generated programmatically by Dimensions (from Digital Science) for my colleague Lynn Connaway. It aims to generate a description, but then also to recognize and link to other entities (e.g. topics, institutions, or collaborators). Again, the goal is to present a profile, and then to allow us to prospect a body of work and its connections. It pulls data from various places. We are accustomed to this more generally now with Knowledge Cards in Google (underpinned by Google's knowledge graph).
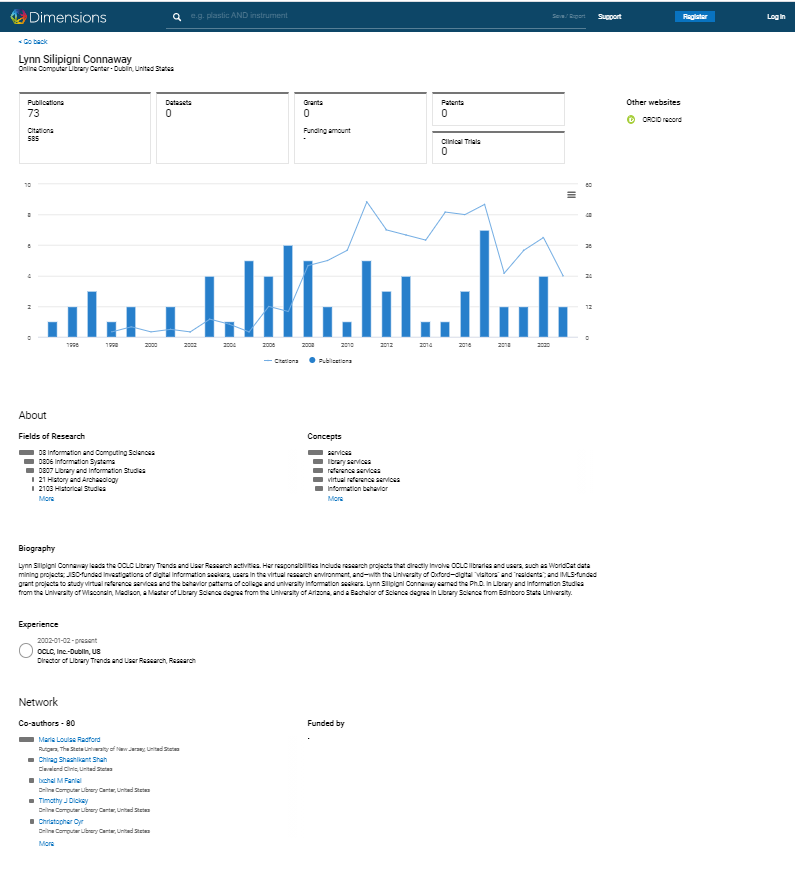
Of course, this is not complete, and there has been some interesting discussion about improved use of identifiers from the scholarly entity backbone services. Meadows and Jones [talk about](https://scholarlykitchen.sspnet.org/2021/06/22/making-the-case-for-a-pid-optimized-world/?ref=lorcandempsey.net) the practical advantages to scholarly communication of a 'PID-optimized world.' (PID=persistent identifier.)
In these systems and services, the entities I have been talking about will typically be nodes in an underlying knowledge graph or ontology.
> Today, KGs are used extensively in anything from search engines and chatbots to product recommenders and autonomous systems. In data science, common use cases are around adding identifiers and descriptions to data of various modalities to enable sense-making, integration, and explainable analysis. \[...\]
>
> A knowledge graph organises and integrates data according to an ontology, which is called the schema of the knowledge graph, and applies a reasoner to derive new knowledge. Knowledge graphs can be created from scratch, e.g., by domain experts, learned from unstructured or semi-structured data sources, or assembled from existing knowledge graphs, typically aided by various semi-automatic or automated data validation and integration mechanisms. // [The Alan Turing Institute](https://www.turing.ac.uk/research/interest-groups/knowledge-graphs?ref=lorcandempsey.net)
The knowledge graph may be internal to a particular service (Google for example) or may be used within a domain or globally. Again, Wikidata is important because it publishes its underlying knowledge graph and can be used to provide context, matches, and so on for other resources.
The Library of Congress, other national libraries, OCLC ,and others now manage entity backbones for the library community, sometimes rooted in traditional authority files. There is a growing awareness of the usefulness of entity-based approaches and of the importance of identifiers in this context.
In this way, it is expected that applications will be able to work across these services. For example, an Orcid identity may be matched with identifiers from other services, VIAF for example, to provide additional context or detail, or Wikidata to provide demographic or other data not typically found in bibliographic services.
In this way, we can expect to see a decentralized infrastructure which can be tied together to achieve particular goals.
### Pluralizing description
> “Nobody should be compelled to us a slur to search a catalogue” - [@mentionthewar](https://twitter.com/mentionthewar?ref%5Fsrc=twsrc%5Etfw&ref=lorcandempsey.net) [#DCDC21](https://twitter.com/hashtag/DCDC21?src=hash&ref%5Fsrc=twsrc%5Etfw&ref=lorcandempsey.net)
>
> — David Prosser (@RLUK\_David) [June 29, 2021](https://twitter.com/RLUK%5FDavid/status/1409800387184451587?ref%5Fsrc=twsrc%5Etfw&ref=lorcandempsey.net)
Systems of description are inevitably both explicitly and implicitly constructed within particular perspectives. Metadata and subject description have long been criticized for embodying dominant perspectives, and for actively shunning or overlooking the experiences, memories or expectations of parts of the communities they serve. They may also contain superseded, obsolescent or harmful descriptions.
Libraries have spoken about "knowledge organization" but such a phrase has to reckon with two challenges. First, it is acknowledged that there are different knowledges.
> The TK Labels support the inclusion of local protocols for access and use to cultural heritage that is digitally circulating outside community contexts. The TK Labels identify and clarify community-specific rules and responsibilities regarding access and future use of traditional knowledge. This includes sacred and/or ceremonial material, material that has gender restrictions, seasonal conditions of use and/or materials specifically designed for outreach purposes. // Local Contexts, [\[Traditional Knowledge\] labels](https://localcontexts.org/labels/traditional-knowledge-labels/?ref=lorcandempsey.net)
Second, knowledge may be contested, where it has been constructed within particular power relations and dominant perspectives.
> Others described “the look of horror” on the face of someone who has been told to search using the term “Indians of North America.” Students — Indigenous as well as settler—who work with the collections point out to staff the many incorrect or outdated terms they encounter. // **[Towards respectful and inclusive description](https://hangingtogether.org/?p=8770&ref=lorcandempsey.net)**
My Research Library Partnership colleagues [carried out a survey](https://hangingtogether.org/?p=6378&ref=lorcandempsey.net) on Equity, Diversity and Inclusion in 2017\. While it is interesting to note the mention of archival description as among the most changed features, there was clearly a sense that metadata description and terminologies required attention, and there was an intention to address these next.
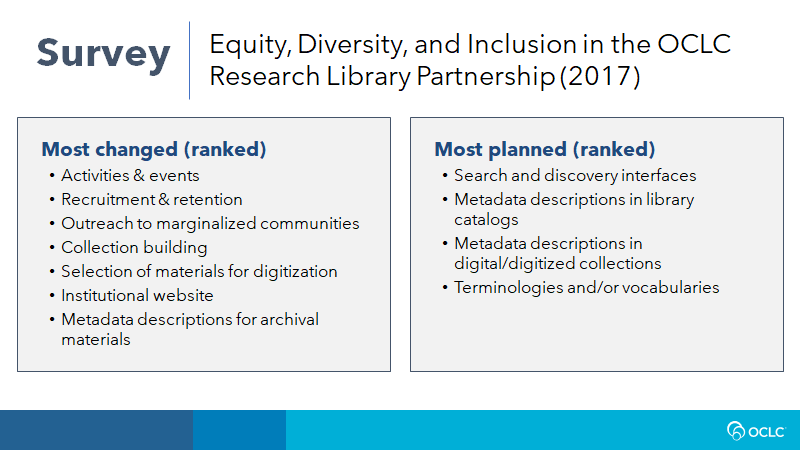
Such work may be retrospective, including remediation of existing description by linking to or substituting more appropriate descriptions. And there is certainly now a strong prospective focus, working on pluralizing description, on decentering dominant perspectives to respectfully and appropriately describe resources.
This work has been pronounced in Australia, New Zealand and Canada, countries which recognize the need to address harmful practices in relation to Indigenous populations. In early 2020, my RLP colleagues interviewed 41 library staff from 21 institutions in Australia, New Zealand, Canada and the US to talk about respectful and inclusive description:
> Of those interviewed, no one felt they were doing an adequate job of outreach to communities. Several people weren’t even sure how to go about connecting with stakeholder communities. Some brought up the possibility of working with a campus or community-based Indigenous center. These organizations can be a locus for making connections and holding conversations. A few working in a university setting have found strong allies and partners to advocate for increased resources in faculty members of the Indigenous Studies department (or similar unit). Those with the most developed outreach efforts saw those activities as being anchored in exchanges that originated at the reference desk, such as when tribal members came into the library to learn something about their own history, language or culture using materials that are stewarded by the library. Engaging with these communities to understand needs offers the opportunity to transform interactions with them from one-time transactions to ongoing, meaningful relationships. Learning how Indigenous community members use and relate to these materials can decenter default approaches to description and inspire more culturally appropriate ways. Some institutions have developed fellowships to foster increased use of materials by community members. // [Towards respectful and inclusive description](https://hangingtogether.org/?p=8770&ref=lorcandempsey.net)
The murder of George Floyd in the US caused a general personal, institutional and community reckoning with racism. This has extended to addressing bias in library collections and descriptions.
> Materials in our collections, which comprise a part of the cultural and historical record, may depict offensive and objectionable perspectives, imagery, and norms. While we have control over description of our collections, we cannot alter the content. We are committed to reassessing and modifying description when possible so that it more accurately and transparently reflects the content of materials that are harmful and triggering in any way and for any reason.
>
> As librarians and archivists at NYU Libraries, we are actively confronting and remediating how we describe our collection materials. We know that language can and does perpetuate harm, and the work we are undertaking centers on anti-oppressive practices. We are also making reparative changes, all to ensure that the descriptive language we use upholds and enacts our values of inclusion, diversity, equity, belonging, and accessibility. // NYU Libraries, Archival Collections Management, [Statement on Harmful Language](https://guides.nyu.edu/archival-collections-management/inclusive?ref=lorcandempsey.net).
Many individual libraries, archives and other organizations are now taking steps to address these issues in their catalogs. The National Library of Scotland has produced an interesting [Inclusive Terminology](https://drive.google.com/file/d/1C3fjqUi0nmAjhghzAO2FXxUbdbqX0fJo/view?ref=lorcandempsey.net) guide and glossary, which includes a list of areas of attention.
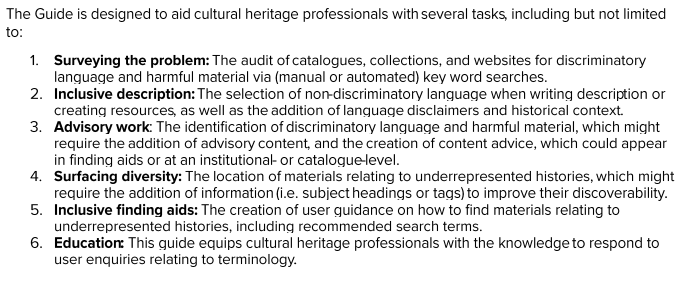
Of course, the two directions I have mentioned can be connected, as entification and linking strategies may offer ways of pluralizing description in the future:
> Other magic included technical solutions, such as linked data solutions, specifically, mapping inappropriate terms to more appropriate ones, or connecting the numerous alternative terms with the single concept they represent. For example, preferred names and terms may vary by community, generation, and context—what is considered incorrect or inappropriate may be a matter of perspective. Systems can also play a role: the discovery layers should have a disclaimer stating that users may find terms that are not currently considered appropriate. Terms that are known to be offensive terms could be blurred out (with an option to reveal them). // [Towards respectful and inclusive description](https://hangingtogether.org/?p=8770&ref=lorcandempsey.net)
## OCLC Initiatives
Now I will turn to discuss one important initiative OCLC has under each of these two directions.
### Entification at OCLC: towards a shared entity management infrastructure
> For linked data to move into common use, libraries need reliable and persistent identifiers and metadata for the critical entities they rely on. This project \[SEMI\] begins to build that infrastructure and advances the whole field // Lorcan Dempsey
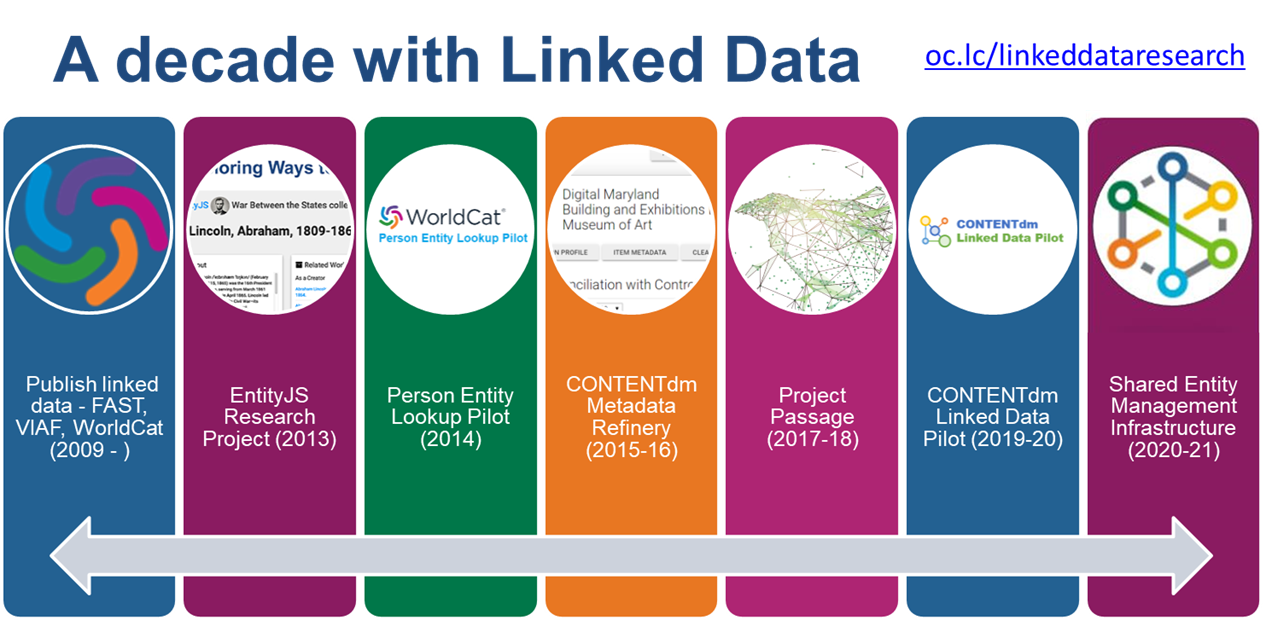
OCLC has long worked with entification in the context of several linked data initiatives. VIAF (the Virtual International Authority File) has been foundational here. This brings together name authority files from national libraries around the world, and establishes a singular identity for persons across them. It adds bibliographic and other data for context. And it matches to some other identifiers. VIAF has become an important source of identity data for persons in the library community.
Project Passage is also an important landmark. In this project we worked with Wikibase to experiment with linked data and entification at scale. My colleague Andrew Pace provides an overview of the lessons learned:
- The building blocks of Wikibase can be used to create structured data with a precision that exceeds current library standards.
- The Wikibase platform enables user-driven ontology design but raises concerns about how to manage and maintain ontologies.
- The Wikibase platform, supplemented with OCLC’s enhancements and stand-alone utilities, enables librarians to see the results of their effort in a discovery interface without leaving the metadata-creation workflow.
- Robust tools are required for local data management. To populate knowledge graphs with library metadata, tools that facilitate the import and enhancement of data created elsewhere are recommended.
- The pilot underscored the need for interoperability between data sources, both for ingest and export.
- The traditional distinction between authority and bibliographic data disappears in a Wikibase description.
These initiatives paved the way for SEMI (Shared Entity Management Infrastructure). Supported by the Andrew W. Mellon Foundation, SEMI is building the infrastructure which will support OCLC's production entity management services. The goal is to have infrastructure which allows libraries to create, manage and use entity data at scale. The initial focus is on providing infrastructure for work and person entities. It is advancing with input from a broad base of partners and a variety of data inputs, and will be released for general use in 2022\.
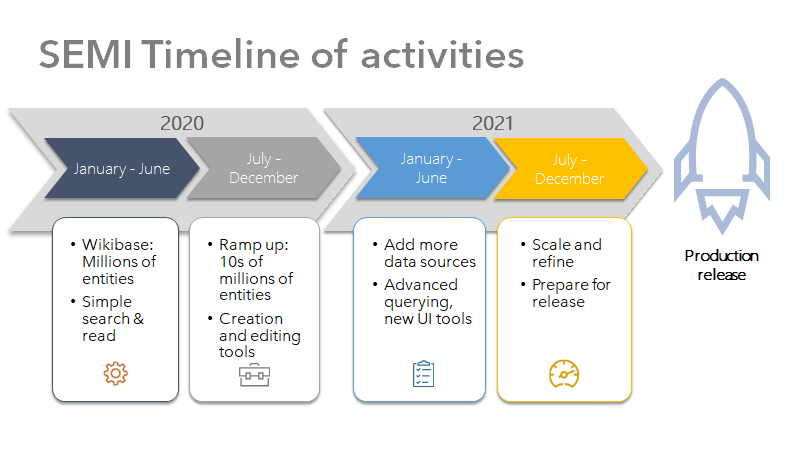
### Pluralization at OCLC: towards reimagining descriptive workflows
OCLC recognizes its important role in the library metadata environment and has been reviewing its own vocabulary and practices. For example, it has deprecated the term 'master record' in favor of 'WorldCat record.'
It was also recognized that there were multiple community and institutional initiatives which were proceeding independently and that there would be value in a convening to discuss shared directions.
Accordingly, again supported by the Andrew W Mellon Foundation, OCLC, in consultation with [Shift Collective](https://www.shiftcollective.us/collective?ref=lorcandempsey.net) and an advisory group of community leaders, is developing a program to consider these issues at scale. The following activities are being undertaken over several months:
- Convene a conversation of community stakeholders about how to address the systemic issues of bias and racial equity within our current collection description infrastructure.
- Share with member libraries the need to build more inclusive and equitable library collections and to provide description approaches that promote effective representation and discovery of previously neglected or mis-characterized peoples, events, and experiences.
- Develop a community agenda that will be of great value in clarifying issues for those who do knowledge work in libraries, archives, and museums, identifying priority areas for attention from these institutions, and providing valuable guidance for those national agencies and suppliers.
It is hoped that the community agenda will help mobilize activity across communities of interest, and will also provide useful input into OCLC development directions.
## Find out more .. resources to check out
The OCLC Research Library Partners Metadata Managers Focus Group is an important venue for discussion of metadata directions and community needs. This report synthesizes six years (2015-2020) of discussion, and traces how metadata services are evolving:
[Transitioning to the Next Generation of MetadataOCLCOCLC](https://www.oclc.org/research/publications/2020/oclcresearch-transitioning-next-generation-metadata.html?ref=lorcandempsey.net)
This post brings together a series of international discussions about the report and its ramifications for services, staffs and organization.
> [Next-generation metadata and the semantic continuum](https://hangingtogether.org/?p=9292&ref=lorcandempsey.net)
For updates about OCLC's SEMI initiative, see here:
[WorldCat - Shared entity management infrastructure | OCLCLearn more about how OCLC is developing a sharedOCLC](https://www.oclc.org/en/worldcat/oclc-and-linked-data/shared-entity-management-infrastructure.html?ref=lorcandempsey.net)
For more about about reimagining descriptive workflows, see here:
[Reimagine Descriptive WorkflowsOCLC has been awarded a grant from The Andrew W. Mellon Foundation to convene a diverse group of experts, practitioners, and community members to determine ways to improve descriptive practices, tools, infrastructure and workflows in libraries and archives. The multi-day virtual convening is part of…OCLC](https://www.oclc.org/research/areas/community-catalysts/reimagine-descriptive-workflows.html?ref=lorcandempsey.net)
The Project Passage summary and report is here:
[Creating Library Linked Data with Wikibase: Lessons Learned from Project PassageThe OCLC Research linked data Wikibase prototype (“Project Passage”) provided a sandbox in which librarians from 16 US institutions could experiment with creating linked data to describe resources—without requiring knowledge of the technical machinery of linked data. This report provides an overview…OCLCOCLC](https://www.oclc.org/research/publications/2019/oclcresearch-creating-library-linked-data-with-wikibase-project-passage.html?ref=lorcandempsey.net)
**Acknowledgements:** Thanks to my colleagues John Chapman, Rachel Frick, Erica Melko, Andrew Pace and Merrilee Proffitt for providing material and/or advice as I prepared the presentation and this entry. Again, thanks to April Manabat of Nazarbayev University for the invitation and for encouragement along the way. For more information about the Conference, check out these pages:
[Nazarbayev University LibGuides: Eurasian Academic Libraries Conference - 2021: HomeNazarbayev University LibGuides: Eurasian Academic Libraries Conference - 2021: HomeNazarbayev University LibGuides at Nazarbayev University](https://nu.kz.libguides.com/EALC-2021/home?ref=lorcandempsey.net)
**Picture:** I took the feature picture at Sydney Airport, Australia (through a window). The Pandemic is affecting how we think about work travel and the design of events, although in as yet unclear ways. One pandemic effect, certainly, has been the ability to think about both audiences and speakers differently. It is unlikely that I would have attended this conference had it been face to face, however, I readily agreed to be an online participant.
### Working with Ghost: a review
URL: https://www.lorcandempsey.net/working-with-ghost/
Last updated: 2023-02-02T04:32:58.000Z
Note 12 December 2022: I updated the theme to Tuuli from Biron Themes in November, 2022\.
## The choice
In looking at building a personal site, there seemed to be some very clear tradeoffs, between prefabrication and control, between time spent writing and time spent building. Especially as a secondary goal for me in starting a new web presence is to learn a little more about front-end web technologies, while starting from a low knowledge base (CSS, Handlebars, JavaScript). Some options:
- WordPress is the most obvious choice. WordPress powers a surprisingly large part of today's web and of course there is a massive ecosystem - hosting sites, website builder layers, themes, plugins and so on. There are multiple choices, options, and additions for everything. [I have used](https://blog.oclc.org/lorcand/?ref=lorcandempsey.net) WordPress for a long time, admittedly in a simple and work-supported way. And I also had a simple personal WP deployment as a placeholder on this URL for some years. However, I found the sheer volume of WP choices and opportunities a little oppressive and bloated. Of course, I understand one could constrain this and that the ecosystem is evolving but I was interested in looking at more modern approaches. And I just felt like a change.
- One could use a website builder like the very popular Squarespace. However, I resisted the packaged and closed nature of this option.
- The most attractive option was a static site builder, like Jekyll, Gatsby or Hugo. The most attractive philosophically, I should say, but maybe not practically. I thought the technical lift might be too great for me, unless I was prepared to invest quite a bit of time, and it did seem to me that I would need pretty active support. In retrospect, maybe I should have spent some time with Jekyll or Hugo given the growing ecosystem available.
- I wanted to do more than one can do on Medium or [Tumblr](https://lorcand-blog.tumblr.com/?ref=lorcandempsey.net).
- I have been interested to see the growing popularity of Substack, but I was not sure I would have the discipline to send out a regular newsletter, at least not now.
In this context, Ghost looked more and more interesting, for a variety of reasons. I was attracted by the non-profit status and culture of Ghost, its commitment to open source, its vision of enabling creativity and writing on the web, and its modern design. I confess I was overinfluenced by these factors, perhaps irrationally so. But most important I was interesting in a good publishing experience coupled with an opportunity to be that bit closer to the building process.
A few things about Ghost:
1. In [describing](https://ghost.org/features/?ref=lorcandempsey.net) itself, Ghost foregrounds its role as a writing platform and very much ties itself to an independent writing/journalism/publishing movement. This is perhaps most closely associated in more general discussion with the popularity of Substack, although it was also interesting to see the recent acquisition of Revue by Twitter. ([Craig Mod](https://craigmod.com/essays/successful%5Fmemberships/?ref=lorcandempsey.net) writes: 2020: the year “Substack” entered the realm of “Kleenex.”) Ghost supports this role by providing a very engaging editing interface, the capacity to manage membership and subscription newsletters, and support for paid subscriptions. This was attractive, as it provides a framework for sharing, even when one doesn't implement the paid subscription options. While it might be interesting to experiment with the paid newsletter model, we operate in a very small community and I am not very confident that this site would aggregate very much in the way of paid membership :-) Anyway, this is not planned here, although I am interested in the membership functionality to facilitate mail updates and comments. Ghost also emphasizes its support for startups developing a web presence, and there are some nice examples on the list below.
2. Ghost is also a small and very focused organization (21 employees according to the website), and is also supported by voluntary code contribution. The Ghost Foundation is registered in Singapore, but I did not see anything immediately about a board or governance. It seems still to have that startup energy and culture.
3. Ghost is a headless CMS, a [growing category](https://jamstack.org/headless-cms/?ref=lorcandempsey.net) of provider. Simply, it focuses on backend content management, exposing content through APIs. It does not focus on frontend presentation. If you have the dev capacity you can build your own front end. Or you can rely on themes. Ghost ships with Handlebars.js, a templating language which provides a themes layer. There is a default theme, and a small industry of theme creators. More about this below.
[Headless CMS - Top Content Management Systems | JamstackCheck out this showcase of some of the best, open source headless CMSes. This is community-drive so be sure to submit your favorite CMS today!Jamstack.org](https://jamstack.org/headless-cms/?ref=lorcandempsey.net)
[Ghost Customers – A showcase of real sites built with GhostLearn about Ghost customers and why thousands of businesses rely on Ghost to build professional publishing websites. #1 CMS for privacy, security and speed.Ghost - The Professional Publishing Platform](https://ghost.org/customers/?ref=lorcandempsey.net)
## The execution
So, how has it gone? My remarks here are confined to the hosted version, Ghost(Pro), and also rest on my experiences as a non-initiate single user, rather than somebody with more development experience or an organization with some development capacity. I feel it is important to emphasize this, as I fully understand that the system may not be optimized for my level of expertise. That said, I remain reasonably positive about the overall experience.
### Ghost
Ghost emphasizes writing. And it has a very nice editor that really focuses you on the words in front of you. Markdown can be used 'in the flow' and there is unobtrusive elegant support for embedding video, images, raw HTML code, and so on (although it doesn't have the extensive options of, say, Notion). It hides the clutter of functionality. On one side of the page, you can open up a dashboard that gives access to general Ghost features, and, on the other, to a dashboard that gives access to publishing, SEO and other options for that page. It is nicely designed.
It usefully includes some things:
- SSL - although you have to register your domain with a third party, Ghost provides SSL at no additional cost.
- SEO,CDN, security and speed - reading reviews I was reassured that Ghost was making good design and engineering choices more connected to the future than some other options. See the review below for a brief overview of these areas from a more knowledgable perspective than mine. SEO is integral, not provided through a plugin. You can configure for social media, add keywords, Google snippet text, and so on. I have not experienced how well this works yet, as I have only just published the site. It also sits on a content distribution network, has good security options, and says it does backup (although, apparently you cannot roll the site back to a previous version). It provides a nice option to do a JSON dump of the entire site in a few seconds.
- Membership and paid options, as noted above. Mail distribution is built into Ghost, although you need to provide your own email to receive notifications/replies. Here is an [example](https://thechocolatelife.com/?ref=lorcandempsey.net) of a site with premium membership options deployed.
Ghost suggests that it can be used out of the box by the non-technical writer. This may be mostly true if you are prepared to accept what comes out of the box, and do not need to change the theme. But in practice, there are some areas where you may need to do a little more which exposes you to CSS or Handlebars. There are two design choices that mean that starting up with Ghost is a little more challenging than starting up with, say, Medium or Squarespace. The first is the Ghost development focus on the functional core, creating a need either for third party integrations or for custom theme work to implement desired features. And the second is the reliance on themes rather than any inbuilt design layer.
### Third party integrations
The clear focus on core capabilities means that functionality seen as more peripheral becomes literally so, as it is passed to third-party integrations. This is the case with comments, for example, although of course this is now common as the widespread use of Disqus shows. I am experimenting with Cove here, which is built specifically for Ghost and handily sits on top of its membership model. Similarly, contact forms are provided through third parties. I am using Formspree here. Depending on choices, in some cases this will add subscription cost, especially if one wants to avoid the perennial spam problem. Ghost is not a large organization and this discipline does mean that there is a welcome focus on enhancing the core (blogging, membership, subscription). However, it is surprising that search is not natively provided. Typically, this is managed in different ways on a per-theme basis. And in fact, given the volume of posts I have imported, I have run into issues with the theme-provided search - it was hanging when it was trying to search the full text, so I have limited it to titles for the moment. I will need to look at other options - it would be better if this were natively provided.
Some integrations are built in: Unsplash for images, Slack, Stripe for payments, and some more. Others can be managed through Zapier, a third-party integration app. Integrations supported in this way are described here:
[Ghost Integrations – Connect your favourite Tools & Apps to your siteKeep your stack aligned and integrate your most used tools & apps with your Ghost site: automation, analytics, marketing, support and much more! 👉Ghost - The Professional Publishing Platform](https://ghost.org/integrations/?ref=lorcandempsey.net)
There is no support for plugins, so, while you are not tempted to load up on unnecessary plugins, you also may be short of readymade and basic functionality. Philosophically, I find this quite pleasing, focusing on simplicity and the task in hand. However, again from a practical point of view, it means that things that might be simple to do in another environment (pulling out tweetable quotes, for example, or having an archive, organized by month or some other period, or creating a table of contents) have to be custom crafted here. And of course, in turn, this requires some technical knowledge.
### Themes
You can build your own theme or website if you are able, and there are some 'starter' themes around for those who wish to develop their own. It also comes with a default theme (Casper - geddit?). I need to go with an existing theme.
My experience with themes has been very variable. The first I tried turned out not to be developed or supported any more, so I got a refund. I tried a couple for which I had to chase for documentation and responses were delayed or non-existent. However, I also had a very good experience with another developer who was interested in how his theme was being used or could be improved. I settled on Krabi which is more expensive than most (and I notice the price has gone up since I subscribed). It was used in some nice sites, and, at that price, I expected it to be well-supported. Given the subscription price of any individual theme, development needs to be a volume business, if it is not a labor of love. There is naturally a line between implementation support on one side, and customization or development advice on the other, and you are not really paying enough for the latter.
This means that you have to settle for being constrained by the capacities of your chosen theme, or you have to have enough knowledge to make adaptations yourself if you want to change design or features. Of course, if you are happy with theme choices or do not have additional functional requirements, then it is not a big issue. Although it does mean that you don't have the control you might have hoped for. The irony here is that while you may have been attracted to Ghost by the promise of openness and control you may end up being limited by the options supported in the theme you have chosen.
There are occasions when you do need to know a little more. Membership is one. Ghost has a newly developed membership Portal which natively provides elegant membership management functionality. However, this is recent, so similar functionality is built into themes. On this site, I have a signup/in button (the Portal) and signup forms (the theme). I can also link to Portal functionality (e.g. [signup here](#/portal/signup/free)). I could of course do away with one approach but it took me a while to figure out how to hide all pay options, what to show where, and so on. This requires some editing of theme files.
Given its design, Ghost is very flexible, but you do have the development skills to take fuller advantage of its possibilities. If you do have those skills, I can see that it could be quite powerful and rewarding.
Incidentally, the business ecosystem around themes is fascinating: I would be very interested to read an analysis of the economics and distribution of theme development. Themes are created by all sorts, by small companies, solo operators, and sometimes as a sideline to other work. It is very much a global activity. And of course, the WordPress theme building ecosystem is enormous.
Ghost has [acquired](https://ghost.org/changelog/iveel/?ref=lorcandempsey.net) a small theme developer, and it is bundling free themes with its new lowest subscription tier which does not allow you to customise themes or to use premium (i.e. paid-for) themes.
## The learning curve is in the wrong place
Of course, the well-known problem here is that the learning curve is in the wrong place. When you are setting things up is precisely when you need to know what you are doing. And things that become simple with familiarity can be tedious, frustrating or time-consuming when you don't know what you are doing.
Making adaptations does require some knowledge of Handlebars and CSS. Copying from other parts of the theme or from other themes, trial and error, and some learning will help move things along. Becoming familiar with the structure of the theme, the classes used, the syntax of Handlebars and CSS, and so on, comes with experience. And such learning is truly accompanied by many small pleasures.
I did end up wanting to do quite a bit of reformatting. But given that I was learning as I was going, it is somewhat inelegant, to say the least. A glance at the Inspect Panel will quickly show this! I have probably over-loaded the code injection facility (the ability to adapt styling etc at the point of page/post creation). Although I have certainly made changes to the theme, I did not want to make too many, as, when it is updated, I have to reconcile my changes and the new version. Deploying an updated theme is somewhat tedious if you have edited existing theme files. Reconciliation is a time-consuming manual process. There is certainly a tradeoff between how much you want to implement your own style choices, and how much you are happy to go with the theme.
And of course, if one makes local changes to the theme without being very familiar with its overall structure, then predictably enough one may create unanticipated issues elsewhere. With more time and experience I would hope to clean things up, and to do things more efficiently and elegantly.
There are a couple of things in particular I would like to see:
- The ability to present archive pages for blog entries - not individually listed (this won't scale with the number of entries I have, over many years), but rather a chronological list of months and a link to a page for each month which shows the list of posts for that month.
- The ability to send out a monthly digest, which gives title/excerpt of each post in that month. The default behavior is that it is possible to send each post to your members. A digest would be nice.
I did not see a theme which did these things for me. And I understand that Ghost is certainly flexible enough to support that functionality. However, it is currently beyond my capability.
I should note that Ghost does point to some experts who can provide for-fee development services, and there are occasional enquiries on the Forum looking for freelance design or development input.
One drawback of the general themes environment is that you have to buy before you try. One of the reasons I began using Krabi was that it offered a refund if things did not work out in early stages. But this is not common. This means that the initial choice may be based on surface style. One does begin to develop better cues - is there online documentation and what does it look like, for example. However, it would also be good to be able to assess the clarity of the file structure of the theme, check whether there is helpful commenting, and so on.
Note 1 February 2023\. I took some of the detail out of this section.
## The curse of knowledge
Ghost support is very responsive and friendly. There is a forum for discussion of technical questions, which does not get hyper-active. There is extensive documentation, a little confusingly divided between developer and general guidance. There is a refreshingly personal nature to some of this, given the scale and culture of Ghost. It is a welcome contrast to the scripted customer support we have become used to, sometimes tied to an upsell agenda.
However, the curse of knowledge is a very real factor here, which is not really surprising - maybe? - given the demographic of Ghost users, who, I imagine, lean more technical than, say, a general blogging audience?
Nor are theme developers really set up to hand-hold their unsophisticated subscribers through the learning journey. Ditto in the case of some third-party applications (e.g. Cove, where my chat questions about implementation have gone unanswered).
> You are suffering from [the curse of knowledge](https://en.wikipedia.org/wiki/Curse%5Fof%5Fknowledge?ref=lorcandempsey.net) when you know things that the other person does not and you have forgotten what it’s like to *not* have this knowledge. This makes it harder for you to identify with the other person’s situation and explain things in a manner that is easily understandable to someone who is a novice. // [Lifehack](https://www.lifehack.org/articles/communication/are-you-suffering-from-the-curse-knowledge.html?ref=lorcandempsey.net)
The signal of the curse of knowledge is that little word 'just', which often crops up in answers to questions. "Just insert this line in the theme." "Just run this script." "Just adapt the CSS."
As I describe in the next section, I have imported almost two thousand blog entries from another environment. I would like to be able to provide a chronological overview archive of these, showing the entries by month, for example. This is not a very unusual feature in blogging environments but is not available in the theme I am using, or natively in Ghost. I did ask about it in the Forum and the response was that it was straightforward to build using the Ghost API. Well, yes ....
## The future
I have moved 15 years of so of work over from my [work blog](https://blog.oclc.org/lorcand/?ref=lorcandempsey.net) (over 1,900 entries) \[update: now redirected\]. Even with some help, there were glitches. I have cosmetically upgraded entries that were widely referenced or influential, and tagged them [classics](https://www.lorcandempsey.net/tag/classics/). I may add more. And time permitting, I will fix formatting in other posts that might get some attention. (I do have a redirection issue - internal links in the WP blog resolve to an archive entry of the post, which has a different URL. With some help I am working on that. \[update: thanks to great work by Libchalk, who did additional scripting around redirection, this now works as expected\])
Even though it may continue to exist elsewhere, I wanted to bring the archive under my own control. I have created a separate 'collection' for them so that they are under their own [particular path](https://www.lorcandempsey.net/orweblog/) and will redirect from the original. A 'record' of the major contributions exists as the [book of the blog](https://www.lorcandempsey.net/orweblog/the-book-of-the-blog/) which does ensure some durability.
[The book of the blogNot very many blogs end up as books. This one did!LorcanDempsey.netLorcan](https://www.lorcandempsey.net/orweblog/book-of-the-blog/)
Ghost is an evolving system, so some things will get easier. However, there is something very attractive about its spareness, and the design choices it has made. I do feel that a little more help could be provided though - if it is to be more attractive to the individual blogger. And remember, that has been my perspective here, understanding that there are other types of user. I mentioned search, the table of contents and chronological archive above. I was aware in the transfer of entries from the other site that Ghost did not have some of the bulk editing tools of WordPress - the ability to merge tags for example.
I have enjoyed my Ghost experience. And after many years it has been interesting to peek under the hood again, being exposed to brackets in curly and angled varieties. It has been been nice, if occasionally frustrating, figuring out how to do things and seeing the changes ramify through the web version. Even if it takes a while for things to work or you have to unpick mistakes, or you can't figure out what to do. And you know that you are tangling things up a bit.
Maybe there is something a little sentimental about this, but if you want to focus on writing, are prepared to do without bells and whistles, and if you want to learn, it is quite satisfying.
## Coda - after Ghost 4 release
So, the above was largely written a little while ago, before the release of Ghost 4\. This introduced evolved functionality, some design changes, a rebranding, and was generally greeted positively. It clearly represents a major commitment by the small team. Developments are described here:
[Ghost 4.0Almost exactly 8 years ago, we announced the first prototype of Ghost onKickstarter. Today, over 20,000 commits later we’re releasing Ghost 4.0\[https://ghost.org/features/\], the latest major version of the product, as wellas small refresh of our brand. If you’re short on time, here are the abbre…ChangelogTeam Ghost](https://ghost.org/changelog/4/?ref=lorcandempsey.net)
The design refresh has changed the simple arrangement which appealed to me above, changing how things are presented, adding links to Ghost materials, moving some functionality to a settings section, and so on. However, the editing experience remains engaging and they have added a very useful preview feature, showing what the post will look like on different devices. They have added a cheaper hosting option for those that are prepared to use one of a set of free themes without additional customization.
They have also moved the membership and subscription Portal UI into production making it a core part of the platform. There has been some discussion about this from those that do not want to use the functionality and would like easily to switch it off. I am sure something will be done to address this in time.
What I found most interesting in the discussion was the reaffirmation of the strategic centrality to Ghost of the paid subscription model, and the focus on the "creator economy." From the Changelog:
> Memberships, subscriptions and the creator economy as a whole is a *noisy* space right now. Many companies building products in this space weren't around 8 years ago, and most won't be around 8 years from now. We will be.
> Decentralised, open source technology is methodical, powerful, and inevitable.
I don't have any insight into Ghost's numbers. Or into how their users break down across the range from personal to startup/corporate (without membership) to unpaid and paid independent creators.
The future of that independent creator economy is certainly pretty interesting and something I might talk about again. At the same time, I hope that Ghost continues to be an effective platform for the rest of us. I admire the achievement of the Ghost team. I have grown to like it and enjoy working with it ... even in my limited way!
**Picture:** I took the feature picture at Ruskin Park in Camberwell, London.
### A new web presence: transitions and towers
URL: https://www.lorcandempsey.net/transitions/
Last updated: 2022-12-14T19:07:20.000Z
## A brief tour
There are pages about writing, career and life, the usual stuff. I especially enjoyed providing an overview of my writing, thinking about continuity and evolution. As I note, I hope to write more about social and institutional aspects of libraries in the future.
[WritingI have written widely over the years. Topics have evolved, but follow a general chronological arc from the technical, through the description of evolving digital systems and services, to organizational and institutional issues.LorcanDempsey.netLorcan’s posts](https://www.lorcandempsey.net/writing/)
[Career stuffThe career to date .. a bit more detail.LorcanDempsey.netLorcan’s posts](https://www.lorcandempsey.net/cv/)
[LorcanDempsey.netWelcome! This is a place to bring together my work on library services and directions.LorcanDempsey.netLorcan’s posts](https://www.lorcandempsey.net/about/)
I have ported over the content from Lorcan Dempsey's Weblog, and say a little more about that below. Earlier manifestations will redirect to here, which is now where I will blog.
## Join
I have implemented a membership feature. This is of course optional but you should [sign up](#/portal/signup/free) if you are interested in receiving updates or if you would like to comment on any entries. More details here:
[Join?Membership - spread the loveWhy join? Only join if you wish to enjoy some additional features. Specifically, memberscan comment on posts and members can receive updates when significant newcontent is added. Signup to join. You can then opt in to receive updates. Once you are a member, you n…LorcanDempsey.netLorcan’s posts](https://www.lorcandempsey.net/membership/)
## Lorcan Dempsey's Weblog: Orweblog
Over many years, I accumulated a lot of content at this venue. Over one thousand nine hundred posts I discovered when we moved it. I am very proud of that achievement. Many posts are referenced and linked to in the literature and elsewhere. A variety of concepts was first introduced and explicated here, before being amplified in presentations, other writing and in my work generally. It stands as a record of many years of thinking and contribution.
Blogging has become much less frequent in recent years. In some ways, my trajectory has followed the trajectory of blogging generally, peaking some years ago. However, more recently, it has been interesting seeing the growth of Substack, Revue, Patreon and other manifestations of the independent creator trend, this time often accompanied by a revenue model.
I observed some blogging dynamics in this post a while ago:
> Because I don’t blog all that often any more, I find that when I sit down to do an entry I have too much stuff to say. I end up writing a short article rather than a blog entry. Indeed, I have a couple of pieces that are lying around and have grown to several thousand words.
I do hope to recapture some of that blogging fluency here.
[One handed writing - the blogRecently @mishdalton \[https://twitter.com/mishdalton\] pointed me at an article\[https://www.nytimes.com/2017/08/25/opinion/tips-for-aspiring-op-ed-writers.html?mcubz=1\] about writing op-eds for the New York Times. I was immediately struck by howapplicable much of what was said was to blog writing.…LorcanDempsey.netLorcan’s posts](https://www.lorcandempsey.net/orweblog/one-handed-writing-the-blog/)
Some notes about the Lorcan Dempsey Weblog content on this site:
- To facilitate redirection and also to identify it here, I have given the imported content its own path .. /orweblog/{entry}. It can also be seen in the navigation the top of the page.
- I have also tagged some important or influential posts as '\*Classics' to elevate them in the new site.
- I have mapped categories in the older blog to tags here, which have a more prominent role in navigation. The mapping isn't perfect, and I have lost some definition. But it works well.
- There will be occasional glitches with formatting, links, or missing images, but overall the transition has worked reasonably well once various issues were identified and addressed.
- I am grateful to Brian Pichman of [libchalk](https://libchalkhosting.com/?ref=lorcandempsey.net) (who host some OCLC blogs) for the patient and expert support he provided as we moved.
[\*Classics - LorcanDempsey.netSignificant or influential posts. This selection is seeded by select posts from Lorcan Dempsey’s Weblog, my blog at OCLC.LorcanDempsey.netLorcan’s posts 19 May 2020](https://www.lorcandempsey.net/tag/classics/)
Note 14 December 2022: I recently removed the 'orweblog' collection within this site. It was not needed for referral, and was really a distraction, albeit a minor one. URLs with 'orweblog' in the path should just redirect appropriately here.
## The Poolbeg Towers
> I have always felt a touch of nostalgia when visiting Lorcan Dempsey's weblog – nothing to do with the content, but rather the masthead of the webpage, which carries a panoramic photograph of his home city, Dublin, resting on Sandymount Strand in the foreground with its two Pigeon House towers and sweeping across the sea to Howth Head at the other side of Dublin Bay. // *Rónán O’Beirne, Library and Information Research, Volume 39 Number 121, 2015.*
Continuous with my blogging identity over so many years, I do carry over the twin towers at Poolbeg, an iconic Dublin landmark. These featured in the banner picture of Lorcan Dempsey's Weblog for many years, and are the feature picture of this post.
I am grateful to my son Eoghan for creating a mark for this blog which incorporates the towers.

Here is the picture from the original blog .. somewhat low resolution.

The towers have always been special, standing in the arc of the bay. At the foot of the South Great Wall, which stretches out into the sea. They look out over the city, the traffic of the port, and the emigrant ships. And in turn, they look back at the towers. In the time since we have left Dublin, they have become more pervasive as an icon and emblem of the city, despite also being threatened with demolition.
And as a special bonus here is Lisa Hannigan singing Snow. The towers are in the background.
**Picture:** I took the feature picture on Sandymount Strand in Dublin. Maybe I should find a better picture, but somehow the focus here seemed right. These are now much photographed.
### The book of the blog
URL: https://www.lorcandempsey.net/book-of-the-blog/
Last updated: 2022-11-04T17:21:03.000Z
### The book
I blogged for many years at Lorcan Dempsey's Weblog. We have ported the entries to this venue, and previous URLs should redirect.
I was very pleased that ALA Publishing agreed to publish a book of the blog and also that they agreed we could make a version open for all. It is released by Facet in the UK.
The blog was very influential for several years, popularizing various themes and phrases.
I am grateful to Ken Varnum for working with me on this – he turned a mountain of words into a book.


### Get the book
The book is available in these places.
[Amazon (US)](https://www.amazon.com/Network-Reshapes-Library-Libraries-Services/dp/0838912338/ref=sr%5F1%5F1?ie=UTF8&qid=1447087547&sr=8-1&keywords=lorcan+dempsey&ref=lorcandempsey.net)
[Amazon (UK)](https://www.amazon.co.uk/Network-Reshapes-Library-Libraries-Services/dp/1783300418/ref=sr%5F1%5Ffkmr0%5F1?ie=UTF8&qid=1447362181&sr=8-1-fkmr0&keywords=lorcan+dempsey+cilip&ref=lorcandempsey.net)
[ALA](https://www.alastore.ala.org/content/network-reshapes-library-lorcan-dempsey-libraries-services-and-networks%E2%80%94eeditions-e-book?ref=lorcandempsey.net)
[Facet Publishing](https://www.facetpublishing.co.uk/page/detail/?k=9781783300419%2A&ref=lorcandempsey.net)
[Download free PDF](https://www.oclc.org/content/dam/research/publications/books/dempsey-network-reshapes-library.pdf?ref=lorcandempsey.net)
[Worldcat](https://www.worldcat.org/title/network-reshapes-the-library-lorcan-dempsey-on-libraries-services-and-networks/oclc/892430197?ref=lorcandempsey.net)
### The movie
Ken Varnum interviewed me about the book. There is an introduction and a longer version. Video definitely adds years and lbs ...
### Presentation: College, consortium, collaboration, collective collection
URL: https://www.lorcandempsey.net/college-consortium-collaboration-collective-collection/
Last updated: 2024-12-28T16:00:33.000Z
### Presentation
Although library collaboration is common and many libraries collaborate through many organizations, it is a relatively unexamined aspect of library work. Many descriptions exist, but little from the point of view of organization and motivation. In this presentation, Constance Malpas and I presented a framework for thinking about library collaboration to the Boston Library Consortium Board of Directors, and drew out some of the challenges successful collaborations face. We emphasized that collaboration is a set of strategic and tactical choices, that it is very influenced by people and politics, and that collective action poses problems.
These dynamics are very much alive in questions around collective collections. The presentation looked briefly at these. It considered retrospective collection coordination (digitization, resource sharing, shared print) which currently tends to be layered over relatively autonomously developed collections, optimized at the institutional level, and prospective collection development (where libraries work together to optimize at the system level through collaborative collection development, licensing and so on).
[College, consortium, collaboration, collective collectionA presentation to the Board of Directors of Boston Library Consortium. Although library collaboration is common and many libraries collaborate through many organizations, it is a relatively unexamined aspect of library work. Many descriptions exist, but little from the point of view of organization …figshare](https://figshare.com/articles/presentation/College%5Fconsortium%5Fcollaboration%5Fcollective%5Fcollection/13669619?ref=lorcandempsey.net)
Dempsey, Lorcan; Malpas, Constance (2021): College, consortium, collaboration, collective collection. figshare. Presentation.
### Other material
Here is an earlier presentation about the dynamics of collaboration, presented to ICOLC.
[Library consortia: scale, opportunity, challengeThis presentation describes some of the dynamics, challenges and opportunities for consortia. It was presented at the ICOLC meeting in Vancouver (8 April 2019).figshare](https://figshare.com/articles/presentation/Library%5Fconsortia%5Fscale%5Fopportunity%5Fchallenge/13670719?ref=lorcandempsey.net)
Our thinking is influenced by the work we did with BTAA.
[Operationalizing the BIG Collective Collection: A Case Study of Consolidation vs AutonomyPrepared in collaboration with the Big Ten Academic Alliance (BTAA) Library Initiatives, this report presents a framework for operationalizing the BTAA collective collection—a collection managed collaboratively across a network of libraries—and is focused specifically on the ”purchased” or print col…OCLCOCLC](https://www.oclc.org/research/publications/2019/oclcresearch-operationalizing-the-BIG-collective-collection.html?ref=lorcandempsey.net)
And some thoughts on collaboration.
[The powers of library consortia 1: how consortia scale capacity, learning, innovation and influenceLibraries and related organizations group together in a variety of ways to get their work done. They consort where there are scale advantages: to lobby, for example, to negotiate and license, to reduce costs, or to build shared infrastructure.LorcanDempsey.netLorcan’s posts](https://www.lorcandempsey.net/the-powers-of-library-consortia-1-how-consortia-scale-capacity-learning-innovation-and-influence/)
**Picture:** I took the picture of 'We live here' by Christina Grote. It is the tiled surface of a park bench in Gahanna, Ohio, supported by the Gahanna Parks and Recreation Foundation.
### Presentation: The RLUK Digital Shift Forum
URL: https://www.lorcandempsey.net/presenting-to-rluk-digital-shift/
Last updated: 2022-11-03T02:10:39.000Z
## Presentation
Here is how the session was described:
> Beyond the scramble of the current situation, universities will be looking at long term pandemic effects. This clearly has implications for libraries, as they cleave more closely to university strategies. This presentation looks at some pandemic effects, and considers how it will likely accelerate some collection directions already evident. It also emphasised two important collection imperatives – for optimisation and for pluralisation. In this talk Lorcan explores how different national systemic characteristics play into developments, sketching differences between UKI and the US.
I was pleased to participate in this series of discussions to help further conversation around RLUK’s [manifesto for the digital shift in research libraries](https://www.rluk.ac.uk/digital-shift-manifesto/?ref=lorcandempsey.net).
Here are the slides.
[Pandemic effects and collection directionsBeyond the scramble of the current situation, universities will be looking at long term pandemic effects. This clearly has implications for libraries, as they cleave more closely to university strategies. This presentation looks at some pandemic effects, and considers how it will likely accelerate s…figshare](https://figshare.com/articles/presentation/Pandemic%5Feffects%5Fand%5Fcollection%5Fdirections/13670698?ref=lorcandempsey.net)
## Other material
The presentation drew on the following blog entry.
[Collection directions accelerated? Pandemic effects.Over the past few years I have been talking about three systemic ways in which collections, broadly understood, are evolving in a network environment. They are: the collective collection, the facilitated collection, and the inside-out collection.LorcanDempsey.netLorcan](https://www.lorcandempsey.net/collection-directions-accelerated/)
### From Lorcan Dempsey's Weblog to LorcanDempsey.net
URL: https://www.lorcandempsey.net/place-on-the-web/
Last updated: 2021-04-30T19:40:12.000Z
## LorcanDempsey.net
This is my web home going forward. Enjoy .. and get in touch. Here is the home page.
[LorcanDempsey.netA place on the web to gather the writings and thoughts of Lorcan Dempsey, librarian.LorcanDempsey.netLorcan’s posts 26 Apr 2021](https://www.lorcandempsey.net/)
## Lorcan Dempsey's Weblog - orweblog
I blogged for many years at Lorcan Dempsey's Weblog. I have migrated the posts to this site, and given them a designated path: Lorcandempsey.net/weblog/{entry}. Here is the 'top' page:
[LorcanDempsey.net (Page 1)LorcanDempsey.netLorcan’s posts 27 Mar 2021](https://www.lorcandempsey.net/orweblog/)
Inevitably, in the transition, there were some glitches. You may notice occasional spacing problems, image or link issues, and the tweeting functionality is not nicely formatted. I am sure there are other issues as well.
Overall, though, given that there are almost 2,000 posts, the move worked very well. This is all down to the heroic efforts of Brian Pichman, of [Libchalk](https://libchalkhosting.com/?ref=lorcandempsey.net), who made the move for me.
[Libchalk Landing PageLogo](https://www.libchalk.com/?ref=lorcandempsey.net)
##
**Photograph.** I took the opening photograph of star bricks here in Columbus, Ohio. Star bricks are to be found in various places throughout Ohio and beyond (on the sidewalk in downtown Richmond, Indiana, for example). They were made in Nelsonville, in southeast Ohio. I collected pictures of them for a while:
[30+ Star Bricks ideas | nelsonville, brick, picturesJan 22, 2018 - Pictures of Star Bricks. . See more ideas about nelsonville, brick, pictures.Pinterest](https://www.pinterest.com/lorcand/star-bricks/?ref=lorcandempsey.net)
### Collection directions accelerated? Pandemic effects
URL: https://www.lorcandempsey.net/collection-directions-accelerated/
Last updated: 2024-12-16T02:16:09.000Z
In different ways, each moves beyond the carefully constructed and locally acquired collection.
I believe that we will see accelerated broad adoption of these approaches post-pandemic, as collections activity further peels away from the locally acquired collection. In this piece, I speculate about collections in relation to these three directions, and also briefly introduce three additional cross-cutting collection contexts (**optimizing**, **pluralizing** and **computational reading** at scale).
Of course, academic libraries are very focused on the needs of their parent universities or colleges. The pandemic has sharpened discussion about higher education mission and focus. A central consideration for libraries then is the growing importance of the **optimised collection.** Libraries will increasingly want to optimize their collections against criteria flowing from institutional priorities sharpened by the pandemic response.
This may highlight tensions among the directions I discuss, especially where choices have to be made in an environment of reduced resources. Where a priority is to provide immediate and convenient online curricular support for education, a chosen optimization may be to rely more heavily on vendor offerings, adding ebook collections, streaming services, and other resources. Different choices might be made if one wants to optimize for openness, or for pluralized collections which represent the interests and experiences of local communities. A push to more optimally distribute collections within a consortium means making difficult choices about the locally acquired collections. Does greater investment in inside-out collections - focusing more attention on special collections and scholarly resources which are distinctive to an institution - mean investing less in more commodity resources? Such trade-offs are apparent throughout the discussion below.
Three drivers are important in creating "pandemic effects."
1. **Libraries will be very focused on campus strategies,** as everybody considers priorities, investment, mission. And universities and colleges themselves will be very focused on sharpening priorities.
2. **The move online has re-patterned behaviors and expectations,** which will only partly be reversed. It has accelerated a move already underway, may reveal unmet demand, and will further encourage reexamination of existing practices and investments.
3. **Libraries will have significant downward pressure on budgets,** which will lead to greater optimization, collective action, and a turn to facilitated approaches.
Together, these prompt major rethinking of collections at several levels.
## The library identity ... a critical moment for print?
The print collection has been central to the identity, value, and organization of the library. It remains important and its continued stewardship is a responsibility recognized by many libraries.
However, the forced migration online may mark a final transition into a more full digital identity for the library. This is not a simple transition, and telling the library story in this new environment is not straightforward.
It does seem like a moment of real consequence, as decisions which have been quickly taken in recent weeks may determine the dominant ongoing profile of services. While digital library usage may have dominated for some time, and while digital consumes the larger part of academic library budgets, print still looms disproportionately large in terms of identity, organizational structures, and investment of time.
> While digital library usage may have dominated for some time, and while digital consumes the larger part of academic library budgets, print still looms disproportionately large in terms of identity, organizational structures, and investment of time.
There will certainly now be pressure to further move resources and people out of acquiring, processing and managing print collections and into other areas. This will encourage a broad move to more collective management of the print collection, as discussed further below. At the same time, the local print collection may become more specialized to local community and regional interests.
The shift also underlines the importance of digital surrogates, as the [Internet Archive](https://blog.archive.org/2020/04/07/the-national-emergency-library-who-needs-it-who-reads-it-lessons-from-the-first-two-weeks/?ref=lorcandempsey.net) (not without complaint) and [HathiTrust](https://www.hathitrust.org/ETAS-Description?ref=lorcandempsey.net) have stepped in to provide substitute services. The role of, and future relationship between, HathiTrust, Jstor, and CRL as stewards of materials digitized by the community becomes a strategic question of some importance for those organizations and for the libraries they serve.
As we move out of crisis mode, we will certainly see a careful reconsideration of controlled digital lending and lobbying around the existing law covering use and reuse of digital materials.
One broad pandemic effect is that a public health dimension will be an important part of all public facilities and services. It will be interesting to see whether health concerns about handling physical materials have any impact on perceptions of print.

[Operationalizing the BIG collective collection](https://www.oclc.org/research/publications/2019/oclcresearch-operationalizing-the-BIG-collective-collection.html?ref=lorcandempsey.net)
## The shift towards the collective collection
As we discuss in the [BTAA report on operationalizing collective collections](https://www.oclc.org/research/publications/2019/oclcresearch-operationalizing-the-BIG-collective-collection.html?ref=lorcandempsey.net), there is always a tradeoff in consortial activity between local autonomy and collective consolidation. This means that a desire for local control often trumps systemwide efficiency. The pandemic will make cooperation a growing necessity across a broader range of library activity, and motivate stronger collective responses. Libraries will need to reconsider what they do locally, focusing where they can create distinctive local impact, and share where it is more efficient.
Libraries license resources at a local and collective level. There is a patchwork of consortia and other agencies who work collectively for libraries in this context. At the same time the licensing environment has become more complex, as multiple paths to open are being pursued, as transformational agreements are being put in place, as the big deal is questioned, and as funder and government mandates are enacted. There is also more opportunity for shared licensing of learning resources, open access discovery aggregations, ebook collections, and so on. What sort of pressure will we see to more strongly coordinate this negotiation landscape? The range of interests is diversifying. The relationship with publishing and publishers is also changing as scholarly communications evolves. Again, different interests may be prioritized depending on institutional priorities. Arrangements are complicated by the mix of research intensity across consortium members, in the context of a shift from pay to read to pay to publish models. Some libraries will be more focused than others on reshaping the scholarly communications landscape.
Collective print collections will assume greater importance, as the economies and efficiencies of shared print management are explored. However, moving to a genuinely collective collection involves clear strategic commitment to shared approaches as well as supporting infrastructure and policy work.
We have made a [distinction ](https://blog.oclc.org/lorcand/2451-2/?ref=lorcandempsey.net)between retrospective collections coordination and prospective collections coordination.
The former includes resource sharing, shared digitization, and shared print management - layering these approaches over autonomously created collections. The latter includes a more coordinated approach to building and managing collections across a consortium - optimizing at the system level rather than at the individual library level. Such prospective collection coordination would require some move of budget and decision-making to the center. In this model shared print is not a retrospective rationalization of the collective collection, but a formative element of its development.
To be effective, initiatives will really have to begin to take this more holistic view of collecting activities at the network level, and make actual decisions to coordinate more and to move resources into shared activity.
For example, it is widely accepted that prospective collection development makes sense, collaboratively developing collections against a shared need. However, the collective action problem, where decisions continue to be driven by individual local considerations, has dampened developments. Will one pandemic effect be to finally tip libraries into more collaborative approaches to collection coordination, as pressures to optimize investment and collections across consortia grow?
> Will one pandemic effect be to finally tip libraries into more collaborative approaches to collection coordination, as pressures to optimize investment and collections across consortia grow?
## The shift towards the facilitated collection
We have seen a progressive shift from the locally acquired just-in-case collection to the collection as a service, facilitating access by researchers and learners to resources of potential interest wherever they are.
The goal is to optimally satisfy research and learning needs from a facilitated network of resources (local, collaborative, open, commercial, etc.) rather than to rely only on the careful construction of a locally acquired collection alone. This includes a broad array of services - resource sharing, demand driven acquisition, spot acquisitions, pointing people to a range of freely available resources, more purposefully coordinating access to open resources, and so on.
Several pressures in the current environment encourage this trend, including the budget pressures and the move online. Factors include:
- The move to open. There will be a greater focus on open access resources and open educational resources, for budget reasons but also reflecting general resource trends.
- The need to more directly support curricular needs. The need to support online learning more directly will encourage the facilitated approach, as libraries provide resources tailored to curricular interests.
- A focus on the readily available. An online environment favors the immediately accessible and convenient, wherever it is available.
We also see this trend in the evolution from subject to liaison support, and in the progressive broadening of the ‘literacy’ role - from bibliographic instruction, to digital literacies, to broad consultation around the complexities of the emerging information environment. In each case again, there is a peeling away of support from the local collection to focus more clearly on research and learning behaviors in a broader information environment. A broader critical literacy encompasses thinking about relevant resources, researcher reputation, copyright, publishing choices and OA, data consultancy, and advice around surveillance, algorithmic retrieval, and #fake in a complex evolving environment. These issues have been highlighted in the pandemic context, where science, politics and public policy issues are entwined in intricate ways.

The facilitated collection
## The shift towards the inside out collection
In the sciences, as in other sectors, developments are now jumping over regular process and practices to respond urgently to the new environment, with potential long lasting impact on [research culture](https://www.timeshighereducation.com/news/crisis-us-researchers-see-prospect-durable-gains?ref=lorcandempsey.net). The work practices of science are [changing and trends accelerating](https://www.nytimes.com/2020/04/21/magazine/coronavirus-scientific-journals-research.html?ref=lorcandempsey.net). There is an urgency around greater collaboration (across disciplines, organizations and countries), greater speed in reporting results, and greater use of open channels. There is also some concern about assessing validity and relevance as review processes are compressed or short-circuited. This means that research libraries will more purposefully partner to curate, manage and make more discoverable research outputs like preprints and research data. Research institutions will also be more focused on showcasing expertise and potential contribution through outward facing faculty profiles.
These resources are "**inside out**" in the sense that there is a strong motivation to share them broadly with those outside the institution. For research libraries, the pandemic strengthens the need to work with faculty and research partners to optimize workflows and support the effective dissemination of research outputs.
## Optimizing, pluralizing, and computational reading
In talking to colleagues and in recent presentations, I have become more aware of three cross-cutting emphases in collecting. I was writing about these just as the current situation was breaking and I will return to them in more depth in the future. I thought it useful to record a preliminary note here in the context of the pandemic, especially given the central role of optimization and the growing interest in computational reading.
- **Optimizing.** Libraries will be very focused on reducing the overall collections spend, because of budget reductions and as they shift resource and attention to diversifying expertise and deepening engagement with their communities. At the same time, local decisions are increasingly being made in the context of collaborative arrangements (as with collective collections) or in the context of what may be sourced elsewhere on the network (facilitated access to open access materials, spot acquisitions, document delivery, and so on). There is a stronger need to target spending (acquire what is needed, use what is acquired), libraries will be more strongly focusing on local curricular, research or community interests, and as noted the pivot to open will be more pronounced. Libraries will be more strongly optimizing collections against particular goals in these ways, and as noted above those goals will now often be shaped by pandemic-influenced institutional priorities. In this way, the differences in how one thinks about collection building in different institutions will be highlighted.
- **Pluralizing.** Libraries are actively working to pluralize their collections, services and engagement in what will become a more important area of attention. They are thinking about how descriptive practices respect and can express the characteristics and cultural expectations of served communities. They are supporting their communities in creating their own archives or collections. Libraries are also engaging with those communities to better understand values and expectations, and they recognize the need to diversify their own staff and perspectives. More than that, they are recognizing their own entanglements in dominant cultures and institutional settings, and trying to understand where to consciously de-center historically dominant perspectives. Look for example at the initiative to [de-center whiteness](https://www.gold.ac.uk/library/about/liberate-our-library/?ref=lorcandempsey.net) in Goldsmiths Library, University of London, and the strong focus on recognizing Indigenous peoples in Canadian libraries.
- **Computational reading** or **reading at collection scale**. The pandemic has highlighted the need to mine large collections of literature and data, and several initiatives are pulling together research resources for computational analysis. Collections currently serve a close reading model – article by article, chapter by chapter. We have been seeing a growing interest in reading at the scale of a collection, where programs mine collections of data for trends, discovery and insight. This work may now be specialist or boutique, but will become more common for clear reasons. Libraries are providing more support - for example, Boston College Libraries provide [several pages of guidance](https://libguides.bc.edu/textdatamining/overview?ref=lorcandempsey.net) on Text and Data Mining. The pandemic will accelerate this interest.
> More than that, they are recognizing their own entanglements in dominant cultures and institutional settings, and trying to understand where to consciously de-center historically dominant perspectives.
## Some final notes
There is much to be said about ongoing implications of these collection directions. I note three final ones here.
- **A holistic online experience**. The circumstances now encourage consideration of a holistic online offering of the library ‘service’, as there is a forced separation from the library as ‘building’ which is still so influential in general perceptions of the value and identify of the library. This means providing richer interactions and experiences in the online setting. Providing convenient and guided experiences across collective, facilitated and locally acquired collections is still a challenge. How do you provide "[full library discovery](https://blog.oclc.org/lorcand/full-library-discovery/?ref=lorcandempsey.net)" across the range of resources of potential interest?
- **Curation of the scholarly and cultural record is fragmented.** Two issues come to mind. As libraries move to more facilitated or collective approaches, the responsibilities towards the scholarly or cultural record become more diffuse. And of course, that record is additionally spread across an extraordinarily complex range of resources: news is generated situationally from databases, large companies stream video and music and have no motivation to preserve what they do, large parts of our cultural memory are created on YouTube or social networking sites and so on. And secondly, especially given increased focus on institutional mission in a time of financial difficulty, fewer libraries may feel a collective responsibility here.
- **A moment for consortia**. [Consortia are an integral part of library operations](https://blog.oclc.org/lorcand/the-powers-of-library-consortia-1-how-consortia-scale-capacity-learning-innovation-and-influence/?ref=lorcandempsey.net), and are central to the management of collective collections, licensing and other collections-related activities. Consortia can increase both impact and efficiency of library operations. This seems like a moment for libraries to take a much more strongly strategic view of the collective opportunities available to them, recognising the instrumental value of consortia to advance their goals.
> This seems like a moment for libraries to take a much more strongly strategic view of the collective opportunities available to them, recognising the instrumental value of consortia to advance their goals.
We do not know when we will crest the horizon. The pandemic is accelerating some change already underway, forcing strategic reassessments, and underlining the need to focus on institutional needs. Collections will be more collective, facilitated, optimized, and pluralised. Inside out collections and computational reading will become of greater interest. However, not all libraries will be equally interested in all of these directions, especially as they look to sharpened institutional priorities. And trade-offs between the directions (e.g. pluralization vs optimization for value) will be highlighted as decisions are made about resource allocation. As in other areas, pandemic effects are important, evolving and uncertain.
## Acknowledgements
Thank you to Constance Malpas and Greg Eow for helpful comments, although of course they are not responsible for how I have used their input. In particular, thanks to Greg for noting how a pandemic effect is to highlight some inherent tension between these directions, something that deserves fuller exploration in the future.
**Picture:** I took the feature picture in the library at Pepperdine University.
**Note:** This entry has been cosmetically amended on 27 March 2021 to include feature picture and headings. Blockquotes added 5 November 2022\.
### Calgary Central Library: combining intimacy and civic statement
URL: https://www.lorcandempsey.net/calgary-public-library-a-civic-presence/
Last updated: 2023-03-15T18:52:56.000Z
### A significant space
It was moving, uplifting, and .... reassuring. It combined intimacy of experience with monumental civic statement, and just seemed so right in so many ways.
Organized as a set of curved spaces around a central eye-shaped atrium, it conveyed both spaciousness and focus; it fitted a lot in without being crowded. Warm wood, raw concrete and white walls were complemented by splashes of color on floors, furniture, beautiful and effective signage, bright doors. It had an organic and aesthetic unity that flowed naturally from the design.
[Central Library | Calgary Public LibraryCentral Library is located in Calgary’s East Village, directly east of City Hall. Take a tour or discover each level of the building for yourself, with public art, a children’s library, cafes, Indigenous resources, resident experts, and of course, books!Calgary Public Library](https://calgarylibrary.ca/read-learn-and-explore/central-library/?ref=lorcandempsey-net)
A honeycomb/hexagonal motif ran through the building, again providing variation within continuity.
It opened out onto the city, bringing in light and views, but it also had an enclosed and private feel, a place where you could be unobserved (indeed, I tried to avoid taking pictures of people, as it seemed wrong to step on this right to be unobserved). The range of services was delightful, and I mean delight-full, and wonderfully presented.
I loved the reader recommendations under 4 Ps (place, prose, plot, people - Nancy Pearl?). There were areas for newcomers (immigrants) and job seekers; meeting rooms (I thought there might be more); a maker space; a beautiful, bright engaging children's area and an area restricted to teens; a hip coffee shop; a lovely auditorium. There were spaces for quiet study (including a very nice and deliberately retro reading room on the upper floor) and extensive banks of PCs. However, despite extensive provision, because of the shape of the building the PCs did not crowd out books, or other areas, or come to dominate the view.

Gloriously, I thought, there was a great expanse of books and related materials, filling the curved spaces in bright, well signed, spaced out shelving. In central areas there was a Create Space, a space designed to be interactive and to engage library visitors in dialog about issues (there was an intriguing set of exercises around information and misinformation while I was there), and an art space. I have only had a quick look at the website, but I love that the visual identity of the library and the physical appearance of the building mesh so nicely. The library logo is wonderful and echoes a central design element.
### Background
[Calgary’s new Central LibraryCalgary’s new Central Library has opened its doors to the public. The building, designed in collaboration with DIALOG, aims to welcome over twice as m...Snøhetta](https://snohetta.com/projects/407-calgary39s-new-central-library?ref=lorcandempsey.net)
The library was designed by a partnership involving Snohetta, who have designed several landmark libraries in recent years. I was interested to read that indeed there was a 'fun to serious' motif with lower floors being more active and the reading room occupying the top. It is also built over a light railway line.


**Picture:** I took the pictures during a visit to the library, 10 September 2019\.
**Provenance:** I originally published this post on 11 September, 2019, on Facebook. Slightly adapted here.
### Collective collections: Prospective and retrospective collection coordination
URL: https://www.lorcandempsey.net/2451-2/
Last updated: 2026-09-03T01:29:45.000Z
## Coordinating collective collections
Collective collections are collections addressed at a level above the individual institution. I introduced our [recent report](https://www.oclc.org/research/publications/2019/oclcresearch-operationalizing-the-BIG-collective-collection.html?ref=lorcandempsey.net) on operationalizing collective collections in [my last post](https://blog.oclc.org/lorcand/operationalizing-a-collective-collection/?ref=lorcandempsey.net), where I noted that there is a trend towards more managed collective collections, particularly within consortial settings. Collection coordination is central to building collective collections.
In the report we make an important distinction between two approaches to coordinating collective collections: *retrospective collection coordination* and *prospective collection coordination*. This is really about the level of coordination of collection development strategy and practice across a consortium or group. (I comment on our terminology choice at the end of this brief post.)
> In the current model, collections are optimized locally and only retrospectively considered consortially.
## Retrospective collection coordination
In the current model, collections are optimized locally and only retrospectively considered consortially. Shared approaches are layered over relatively autonomously developed collections. We can identify three important strands of retrospective collections activity, in each of which the BTAA has been active:
1. **Resource sharing**: providing access to the resources of the full network to all members. Of course, resource sharing is evolving in interesting ways, becoming a channel for interacting with a variety of fulfilment networks, spot acquisitions, open access resources, and so on. One outcome of this is that we will see greater convergence between discovery, resource sharing, collection development and acquisitions. We can expect to see the links between these service areas become more automated and data driven. So, in a simple example, acquisition of articles or books may be triggered at some level of demand as indicated by discovery or resource sharing patterns of use.
2. **Shared print**: coordinating stewardship of the print and scholarly record at the network level. This has been a major consortial interest in recent years. It is being coordinated by existing resource sharing networks, but new affiliations have also emerged to address shared print specifically, and we are seeing nascent collaboration across these.
3. **Digitization:** selective digitization of collections. Digitization was given a boost by the Google initiative, and Hathi Trust has emerged as an important collaboration, consolidating access, management and preservation.
> Shared print and resource sharing are alike aspects of collections logistics.
These areas have tended to be managed independently. There is great opportunity to coordinate them more strongly at the consortial level. Shared print and resource sharing are alike aspects of collections logistics, for example, thinking about optimal distribution of collections for rapid delivery across a consortium. ReCAP is particularly interesting in this regard, representing a hub which consolidates print collections, a logistical infrastructure, and stewardship responsibilities. And digitization could be driven by demand in context. This begins to move us towards a more prospective model.
## Prospective collection coordination
A prospective collection coordination model offers stronger coordination of collecting activity across the network. This could be based on some division of collecting responsibilities and better awareness of systemwide distribution of collections, or even on a move of some decision-making and budget to the center (shared acquisition of e-books for example, or of open access collections). In this model, collecting activity could be optimized across the network rather than at the individual library level. An approach might be based on type of material, or publisher, or subject. Over time, addressing particular needs at a shared level might allow institutions to specialize in areas of local expertise or distinctive research interests. In this model shared print is not a retrospective rationalization of the collective collection, but a formative element of its development.
> In this model shared print is not a retrospective rationalization of the collective collection, but a formative element of its development.
Of course, consortia are used to working with a version of this model for licensed materials, but it is not common for purchased or print materials.
While attractive in theory, prospective collection coordination has proved difficult in practice and is not widely adopted outside of some niche areas. There is some concern that coordination costs are high, potentially reducing local responsiveness (to particular faculty or learning needs), and there is reluctance to surrender local decision making or local control over budgets.
While there is some acceptance that the retrospective model of coordinating relatively autonomous collections model is inefficient, it has been easier to achieve in practice than a prospective model. This is because it does not require strong coordination of institutional collection strategies. It also seems that the risks of working with legacy collections are perceived to be less than those associated with prospective collection development, which will require a new level of mutual interdependence and ceding of control or budget.
In our discussions with BTAA and other librarians we sensed a real desire to make progress with a prospective coordination model, while acknowledging the difficulties.
Of course, the two are not mutually exclusive and if prospective collection coordination were to become more common it would exist in concert with the retrospective approaches we identify. More optimal distribution of collections would make the whole system more efficient.

## A note on words
We found the use of ‘coordination’ and ‘prospective’/’retrospective’ useful in various ways.
> In particular, “collaborative collection development” comes with a host of strong opinions and memories of less than successful outcomes.
Our use of coordination has two aspects. First, and more broadly, we discuss library consortial activity as involving various degrees of coordination along a spectrum from consolidation to relative autonomy. “Coordination” admits of some possible variability in approach. In particular we wanted to emphasise that the degree of coordination is a negotiated outcome – not a defined given. This is related to the second motivation. It is free of the legacy associations or preconceptions that “collection development” or “collaborative collection development” often inspire. In particular, “collaborative collection development” comes with a host of strong opinions and memories of less than successful outcomes. In summary, “Collection coordination” acknowledges a discretionary approach and is neutral in respect of past practice or expectations.
Our use of “retrospective” and “prospective” is influenced by Karla Strieb’s usage: “S[hared Collections: Collaborative Stewardship, Chapter 1: Collaboration: The Master Key to Unlocking Twenty-First-Century Library Collections](https://kb.osu.edu/handle/1811/68031?ref=lorcandempsey.net).”
**Acknowledgements:** This blog entry is based on the text of [Operationalizing the Big Collective Collection](https://www.lorcandempsey.net/2451-2/consolidates%20print%20collections,%20a%20logistical%20infrastructure,%20and%20stewardship%20responsibilities) by Lorcan Dempsey, Constance Malpas, and Mark Sandler.
Our thinking was influenced by a broad range of discussions with colleagues in BTAA libraries, in OCLC, and in other organizations with an interest in these topics. A full list of acknowledgements is included in the report.
**Picture:** I took the picture of the Wilson Library at the University of Minnesota.
**Note:** Cosmetic amendments on 31 March 2021 include addition of feature image, addition of headings and improved spacing.
### Operationalizing a collective collection
URL: https://www.lorcandempsey.net/operationalizing-a-collective-collection/
Last updated: 2024-10-03T05:22:31.000Z
## Collective collections: what and why?
We are pleased to publish a [discussion paper](https://www.oclc.org/research/publications/2019/oclcresearch-operationalizing-the-BIG-collective-collection.html?ref=lorcandempsey.net) this week in collaboration with BTAA. It looks at choices that need to be made when operationalizing the BTAA collective collection.
In this introductory post, I briefly introduce some thoughts about operationalizing collective collections, drawing on the report.
Collective collections are collections addressed at a level above the individual institution, in a network context. OCLC Research has done [a lot of work](https://www.oclc.org/research/publications/library/2013/2013-09r.html?ref=lorcandempsey.net) over the last few years looking at collective collections issues.
> Collective collections are collections addressed at a level above the individual institution, in a network context.
We can characterize a collective collection by reach, by level of coordination, and by services offered. For example, a collective collection may be broad and loosely coordinated (e.g., all the materials visible through WorldCat) or it may be closely circumscribed and tightly coordinated or consolidated (e.g., the shared collection in ReCAP).
At the WorldCat collective collection level, available services include discoverability and resource sharing. OCLC also provides [services](https://www.oclc.org/en/sustainable-collections.html?ref=lorcandempsey.net) which allow libraries and consortia to visualise collections and model decisions in the context of the overall collective collection. At the ReCAP shared collection level, available services include discoverability, resource sharing, consolidated management, and preservation of the print scholarly record.
[Naturally enough](https://blog.oclc.org/lorcand/the-powers-of-library-consortia-1-how-consortia-scale-capacity-learning-innovation-and-influence/?ref=lorcandempsey.net), given their resource sharing role, consortia are major players in relation to collective collections. And we certainly see a trend toward more managed collective collections in consortial contexts. This is for several reasons:
1. to **extend the reach of materials** available to users beyond those available at one library
2. to make their management **more efficient** (by sharing costs and responsibilities)
3. to coordinate collections above the individual library level, allowing individual libraries to **specialize** and contribute more extensively within a defined network of responsibilities
4. to collaboratively steward the **scholarly and cultural record**
In BTAA, as elsewhere, the collective collection was guided by the “invisible hand” of aggregate local policies and decisions. Historically, collections evolved autonomously and locally within individual libraries. Stewardship of this collective resource was a benign side-effect of the massive distribution involved in the print model. To some extent this is still the dominant model for “purchased” or “print” collections.
> As libraries manage down print collections, explore shared print models, and digitize collections this “invisible hand” approach is less adequate.
As libraries manage down print collections, explore shared print models, and digitize collections this “invisible hand” approach is less adequate. This is even more so as libraries unevenly reduce acquisitions of print collections, as more prospective collection coordination approaches emerge (where libraries collaborate to acquire in particular areas or from particular publishers), and as ebook collection become more commonplace. Indeed, print collections have come to share some of the characteristics of digital collections where distribution does not necessarily involve physical redundancy in multiple locations, and more active intervention or conscious coordination within a network of explicit commitments is desirable.
## Attributes of a consciously coordinated collective collection
In the report, we describe four attributes of a more consciously coordinated collective collection, as shown below. Each involves decisions about investment of attention and resources.
The discussion here draws on the work of Brian Lavoie and Constance Malpas in [*Stewardship of the Evolving Scholarly Record: From the Invisible Hand to Conscious Coordination*](https://www.oclc.org/research/publications/2015/oclcresearch-esr-stewardship-2015.html?ref=lorcandempsey.net). It adapts the framework presented there for these specific purposes.

1. **Explicit commitments**: More purposeful coordination depends on agreed strategies, processes for decision making and resource allocation, and broadly adopted policy frameworks. The most important element is an actual commitment to manage, build and share collections in a more coordinated way. Processes for decision making, resource allocation, oversight and review, sourcing, and so on, need to be developed.
2. **Efficient network fulfillment**: An effective applications framework is required to allow users to easily discover resources of interest and to have them delivered quickly. We argue that in addition to discovery and delivery, BTAA should increasingly consider aggregating transaction data to support decision-making, which we refer to as dashboard functionality in the report. The applications framework is a principal focus of the influential [D2D reports](https://www.btaa.org/library/discover-to-deliver/reports?ref=lorcandempsey.net) published by BTAA in recent years.
3. **Optimally distributed collections**: Current approaches are layered over autonomously developed collections. More purposeful coordination of collections across the libraries will improve the overall performance of the network. This includes investigation of prospective collection development, shared print initiatives, selective digitization, the utilization of shared repositories as logistical hubs, and so on.
4. **Systemwide awareness**: Effective management depends on good intelligence about the stocks and flows within the network: a unified view of the whole collection and how it is distributed, what ILL flows there are, and so on. Ideally, one would benefit from a unified view of shared print commitments, of items with digital surrogates, and of transaction data. A consolidated view of ILL policies, which could be looked up by applications, would also benefit.
We argue that each of these areas would benefit from stronger coordination to improve the efficiency and impact of collective collections.
The report covers each of these areas in some detail and places the discussion in the context of consortial choices around consolidation and autonomy.
It also emphasizes the importance of strategy, organizational, policy and process choices alongside the often discussed applications and collections choices.
We hope it is generally useful as libraries and consortia continue to evolve how the print collection is increasingly managed in collaborative settings.
**Acknowledgements:**
This blog entry is based on the text of *Operationalizing the BIG Collective Collection* by Lorcan Dempsey, Constance Malpas, and Mark Sandler.
The report also draws on our thinking about library consortia:
Dempsey, Lorcan (2019) “[What Collaboration Means to Me: Library collaboration is hard; effective collaboration is harder](https://digitalcommons.du.edu/collaborativelibrarianship/vol10/iss4/3?ref=lorcandempsey.net),” *Collaborative Librarianship*: Vol. 10 : Iss. 4 , Article 3.
Our thinking was influenced by a broad range of discussions with colleagues in BTAA libraries, in OCLC, and in other organizations with an interest in these topics. A full list of acknowledgements is included in the report
**Picture:** Adapted from pictures in the report. Original by Constance Malpas.
**Note:** Cosmetic amendments on 28 March 2021, including adding feature picture and headings.
### The facilitated collection redux: a note on collections as a service, the University of California, and Elsevier
URL: https://www.lorcandempsey.net/the-facilitated-collection-redux-a-note-on-collections-as-a-service-the-university-of-california-and-elsevier/
Last updated: 2026-08-29T17:36:20.000Z
## UC and Elsevier
A tremor was felt in *The Force* on February 28 2019 as the University of California announced that it had terminated its contract with Elsevier. This was widely seen as a landmark event in the ongoing contest over the future of scholarly communication.
In part this is because of the scale of the University of California: the [press release](https://www.universityofcalifornia.edu/press-room/uc-terminates-subscriptions-worlds-largest-scientific-publisher-push-open-access-publicly?ref=lorcandempsey.net) notes that the University of California accounts for 10% of research outputs in the US. In aggregate it represents an extraordinary richness of teaching, research and service capacities, across major universities, health facilities, research labs, and an array of associated organizations.
It is also interesting that the UC is structured in a way that this scale can be leveraged. A critical element of the UC’s position is the administrative and academic buy-in it has achieved across the organization for this step, the latter facilitated by a systemwide academic senate. It also has [capacity for collective action](https://blog.oclc.org/lorcand/the-powers-of-library-consortia-1-how-consortia-scale-capacity-learning-innovation-and-influence/?ref=lorcandempsey.net) through the UC Office of the President which [focuses its efforts](https://www.universityofcalifornia.edu/uc-system/stewardship?ref=lorcandempsey.net) “where we think a systemwide perspective adds the most value.” This is the organizational home of the California Digital Library, which leverages the scale of UC in negotiating and managing licensed resources.
Of course, this makes CDL and UC different from other major research university (and library) groupings – Ivy Plus or BTAA, for example – which gather independent institutions, and which don’t readily have the same level of shared capacity and organizational alignment.
The announcement generated several strands of conversation and comment. MacKenzie Smith, UC Davis University Librarian and Vice Provost, [saw it](https://theconversation.com/university-of-californias-break-with-the-biggest-academic-publisher-could-shake-up-scholarly-publishing-for-good-112941?ref=lorcandempsey.net) “as a harbinger of a tectonic shift in how universities and their faculty share research, build reputations and preserve knowledge in the digital age.” Judy Ruttenberg [applauded](https://policynotes.arl.org/?p=1827&ref=lorcandempsey.net) the UC commitment to support faculty publishing charges in the transition from a pay to read to a pay to publish model. While it was seen as a significant event for open access, it is also important in the context of the big deal which has so characterized library licensing of journal material in recent years. Collection development AULs Kosokoff and Brundy [noted that](https://blogs.library.duke.edu/scholcomm/?ref=lorcandempsey.net) “We are not aware of any academic institution that does not have renegotiation of big deals in its plans” and Roger Schonfeld [suggested that](https://scholarlykitchen.sspnet.org/2019/03/07/value-big-deal-leakage/?ref=lorcandempsey.net) the value of the big deal is in decline and argues that a major factor here is the weakened pricing power of publishers. Statements of support appeared from other libraries and library organizations. For example, Betsy Wilson, Vice Provost for Digital Initiatives and Dean of University Libraries at the University of Washington, [wrote with colleagues](https://sites.uw.edu/libstrat/2019/03/07/our-values-scholarly-communication/?ref=lorcandempsey.net) that “The negotiations between UC and Elsevier are part of an accelerating, worldwide movement to transform scholarly communication, to ensure knowledge is shared broadly and without barriers, and to further enhance inquiry and discovery.”
However, as momentous as this event was for discussion about open access and the big deal, I want to focus here on another element of the announcement and how it intersects with some collection trends I have been talking about over the last few years. This is the guidance that the UC provides to its community for alternative access to content published in Elsevier journals (what they interestingly call “Elsevier articles”). It underlines that the classic local collecting model is changing, and that a range of different services around collections are emerging. Collections are a service alongside others. In particular, it highlights the move to what I have called the facilitated collection.
## Collection directions
At the core of library collections has been the bought print collections and more recently the licensed electronic collection. Together, we might call these the ‘acquired collection’, locally managed and immediately available. Increasingly, we are seeing that the centrality of the acquired collection to the library service and identity is an artifact of particular phases of library development.
While the acquired collection is certainly still preponderantly important (just look at library budgets), I have suggested three ways in which the network has changed how we think about collections and their boundaries. The type of attention we give collections changes as libraries think more about institutional outputs (research data, preprints, ..), as researchers and learners inhabit a rich network of scholarly and cultural resources, tools and services, and as reduced interaction costs in a network environment mean that libraries collaborate more readily.
Of course, there are other ways in which the collections environment is changing but in the last few years I have found some resonance for these three ways of talking about change, and have characterized them as follows:
| **Environmental trend** | **Library response** |
| --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Reconfiguration of research work by the network/digital environment.** | **The inside-out library.** |
| Research is collaborative, facilitated by automated workflows (laboratory information systems, scientific workflow systems, lab notebooks, citation management, scholarly networking sites, …) and generates a variety of potentially sharable research artifacts (software, research data, preprints/articles, textual corpora, workflows, ..). | Support researcher workflow and the creation, stewardship and disclosure of institutional research outputs (research data, preprints, expertise profiles, …) with advice, expertise and services.Make special collections and archives more accessible to researchers. |
| **Reconfiguration of the information space by the network/digital environment.** | **The facilitated collection.** |
| Researchers and learners inhabit a network environment rich in information resources – for research, for communication, for archiving, for social sharing, and so on. These are general purpose (github, WikiPedia) or specialized (Amazon, arXiv, Figshare, Google Scholar, etc). ‘Localness’ is no longer a determining influence in information use. And, in fact, the network encourages the opposite trend—towards network level concentration and specialization. The acquired library collection is one resource among many of potential interest. | In this context, we see a progressive shift from the locally acquired just-in-case collection to the collection as a service, facilitating access by researchers to resources of potential interest wherever they are. We see this also in evolution from subject to liaison, and in the progressive broadening of the ‘literacy’ role - from bibliographic instruction, to digital literacies, to broad consultation around the complexities of the emerging information environment. The latter encompasses thinking about relevant resources, researcher reputation, copyright, publishing choices and OA, data consultancy, and advice around surveillance, algorithmic retrieval, and #fake in a complex evolving environment.Arrange for a coordinated mix of local, external and collaborative resources responding to varied user needs. This activity peels away from the locally managed collection and grows to include advice and consultancy about creation and information practices in complex environment. |
| **Reconfiguration of library collaboration by network/digital environment.** | **The collective collection.** |
| The network reduces the interaction costs of collaboration, facilitating more shared and collaborative approaches. | Increasingly organize collections at the network or systemwide level (shared print, digital aggregations, …). |
I am particularly interested in the **facilitated collection** and to to some extent **the inside-out collection** here. I discuss these collection directions more fully elsewhere.
[Library collections in the life of the user: two directions | LIBER Quarterly: The Journal of the Association of European Research LibrariesCreative Commons LicenseAuthors Lorcan Dempsey OCLC, Dublin, OH, US](https://liberquarterly.eu/article/view/10870?ref=lorcandempsey.net)
The UC announcement highlights this refocusing of attention, even if Elsevier does come back to the table.
## Collections as a service: the UC guidance
So, what does the UC say about access to articles? The [UC advice](https://osc.universityofcalifornia.edu/open-access-at-uc/publisher-negotiations/alternative-access-to-articles/?ref=lorcandempsey.net) clusters in four areas:
1. **Install browser plug-ins.** The OA Button and Unpaywall are noted; Kopernio could also be mentioned. Discovery service providers are also adding metadata about OA resources from these or other providers - 1Science, for example, recently acquired by Elsevier. WorldCat Discovery has a program of including metadata from various OA resources as well as links from Unpaywall.
2. **Search for open access copies.** The guidance points to various preprint archives (eScholarship at UC, arXiv, bioRxiv, PsyArXiv, …) and, as further evidence of its centrality, notes that Google Scholar should enable the discovery of preprints through those archives. Interestingly, there is an explicit note here that the University Libraries do not endorse the use of Sci-Hub for access to articles.
3. **Get it from the Library.** The library participates in various resource sharing networks for supply of articles, or can facilitate spot article purchase, and so on. The UC integrates Reprints Desk (also integrated with OCLC’s ILL management system, Tipasa) for single article access.
4. **Use your network.** The guidance suggests contacting an author directly, or through scholarly networking sites (ResearchGate, Mendeley, …), or by making a request on Twitter with the [#icanhazpdf](https://twitter.com/search?q=%23icanhazpdf&ref=lorcandempsey.net) This is an evolving area, but it is interesting to note how for some researchers there is a blurred boundary between scholarly identity, workflow and content, as they disclose work outputs in various profiling and scholarly networking services. Of course this underlines issues around rights in preprints and the occasionally contested relationship between such sites and publishers.
[](https://osc.universityofcalifornia.edu/wp-content/uploads/2019/01/AlternativeAccess%5FUC.pdf?ref=lorcandempsey.net)
## The facilitated collection
As a major research enterprise, UC Libraries invest heavily in bought and licensed materials, and will continue to do so. That said, this step suggests that the libraries will be facilitating access to a range of articles outside of the local licensed collection.
This UC guidance directs people away from the library website, and to resources that, in some cases, might once have been deprecated by the library. Of course, that these are plausible options promoted here is testament to the fact that they have become widely used, popular methods of access. So, the UC guidance underlines a shift that has already been taking place for some time as access to journal materials has diversified in a network environment.
More widely, academic libraries of all sizes are looking at such approaches, some more than others. This is driven by budget reasons, but also by local decisions around privileging open access or stepping away from various deals.
This is a confusing environment.
- The move to open access in various forms is advancing but without a single trajectory. There is a variety of national open access initiatives, different funder mandates, and variously developed institutional regimes. Materials will be made available open access in different ways (institutional repositories, publisher websites, subject repositories, …) and with different conditions attached.
- The licensing model, and the [big deal](https://sparcopen.org/our-work/big-deal-cancellation-tracking/?ref=lorcandempsey.net), that have so characterized collection building activity in recent years, continue to be pressured and library organizations are responding in different ways. Single article purchase or ‘loan’ may become more common. Transition will involve an uneven mix of pay to publish and pay to read options.
- The routes by which research materials are available have diversified and new publishing models are emerging (megajournals, for example) as publishers position themselves in a changing context. The uneasy relationship between publishers and social research systems will evolve. The larger commercial publishers are extending the range of productivity, aggregation, and other product options they make available. Acquisitions by Elsevier in recent years are telling (Mendeley, Bepress, Pure, SSRN, Hivebench, 1Science, …).
- At the same time, there is growing interest for open access to other linked research artifacts - research data, methods, software – which further complicates the ecosystem.
- Access to the journal literature is fragmented in various ways, albeit with Google Scholar as a notable unifying funnel to a large part of the scholarly universe.
What this means is that the library view is shifting somewhat from management of a locally acquired collection to facilitating access to a broader range of scholarly resources. Here, the value relates to the ability to meet research and learning needs in the best ways available using a variety of resources, whether or not they are owned or licensed locally; and also to mobilizing library expertise in assisting faculty and students be effective in a complex information environment.
The facilitated collection becomes a more important part of what a library does in this diversified context.
## The inside-out library collection
While this evolving environment creates some demand for advice in a changing environment, at the same time libraries are providing more services around the creation, curation and appropriate disclosure of institutional research outputs (preprints, research data, expertise profiles, and so on).
The UC advice notes eScholarship, the UC institutional repository as a source of articles.
This underlines the importance of the inside-out library as described above (see [Mark Dahl](https://drive.google.com/file/d/16ZUU4X3IJnqM6BdBw2tzfBKnnjwbKKTw/view?ref=lorcandempsey.net) and [Aaron Tay](http://musingsaboutlibrarianship.blogspot.com/2018/12/6-inside-out-activities-librarians-are.html?ref=lorcandempsey.net) on inside out library services). There is a natural connection between a focus on open access and a focus on the inside out library.
For example, in a striking characterization, Kristin Antelman and colleagues [talk about](https://www.cni.org/topics/digital-curation/from-stock-to-flows?ref=lorcandempsey.net) “disinvesting from pseudo-stock (rented access to journals) while redirecting resources toward Caltech-contextualized stock (institutional bibliography) and open infrastructure.” Turner and Billings [describe](https://works.bepress.com/christine%5Fturner/7/?ref=lorcandempsey.net) “flipping” their collections at UMass Amherst, through a twin focus on managing and disclosing unique institutional materials and on investing more in access to open content and infrastructure: “As the libraries developed the means of producing and providing open access to the University’s scholarship, teaching materials and special collections, it also dedicated financial and staff resources to OA resources, systems and organizations outside the University.”
And of course, what libraries make available in this way become in part what other libraries facilitate access to - especially as institutional materials find their way into institutional or subject repositories, are indexed by Google Scholar, are listed on faculty profiles, and so on.
## Finally …
The UC action has galvanized attention. For Elsevier, the financial impact may be less of an issue than the potential loss of participation in their journals of UC authors, editors, and reviewers. This is because of the scale of the UC research enterprise. For faculty elsewhere, it is potentially important as an exemplary event – the example of UC authors may have more of an influence than the exhortation of their library. For other consortia and libraries it is a call to action.
It is certainly a strong signal that the scholarly ecosystem is really changing, and the surrounding discussion underlines some of those changes. We do not yet know what the new equilibrium will be.
In the interim, the facilitated collection and the inside-out library collection are gaining more attention as libraries think about collections as a service.
Thanks to MacKenzie Smith, University Librarian and Vice Provost, UC Davis, for commenting on a draft of this post.
**Picture:** I took the feature picture in the main library at UCLA.
**Note:** This post was cosmetically amended on 27 March 2021 to include feature picture and headings, and to adjust images. It was also very lightly edited for tense.
### Memory institutions redux: pluralizing memories and a stay against forgetting
URL: https://www.lorcandempsey.net/memory-institutions-redux/
Last updated: 2025-02-28T01:20:27.000Z
## Pluralized memories
Memory, as we know, is complicated, and I sometimes hesitate before using the term. The complications are certainly alive in this *Decade of Centenaries* period in Ireland. One is often reminded of how alternative and contested memories have been common across Irish diasporas and histories.
Growing up in Dublin, one of my favorite places was the elegant [War Memorial Gardens](http://www.heritageireland.ie/en/dublin/warmemorialgardens/?ref=lorcandempsey.net) in Kilmainham. Designed by [Lutyens](http://www.worldcat.org/identities/lccn-n81094255/?ref=lorcandempsey.net), the architect of Empire, they combine monumental grandeur with a sense of proportion and calm, leading down to the river Liffey. They commemorate the Irish dead in the First World War. In another time and place, these gardens would have been seen as a national treasure, a gracious contribution to the public commemorative record. However, they were marked by sad and long neglect. In part, they might have seemed overly grand. Also, commemorating those who died in a British uniform didn’t fit well into the political narrative of the Irish state post independence.
Some relevant context for this attitude is provided by Irish philosopher [Richard Kearney](http://www.worldcat.org/identities/lccn-n83225708/?ref=lorcandempsey.net) (based at that diaspora center of Irish Studies, Boston College) as he [discusses](https://lareviewofbooks.org/article/double-remembrance/?ref=lorcandempsey.net) Irish centenary celebrations in 2016:
> A YEAR of double remembrance for the Irish, 2016 marks the centenary of Ireland’s Easter Rising against Britain, when almost 500 Irish citizens died, and it commemorates the Battle of the Somme in Flanders, in which 3,500 Irish expired in a single day fighting in British uniform against Germany.
He describes the tension between these double remembrances:
> Why? Because Official History after 1916 decreed you could not be Irish and British at once. A binary logic of either/or trumped a dialectical one of both/and. The complex muddle of events was replaced by Grand Narratives of opposed nations. ...
> ... This is why commemorating 1916 is a drama. The options are decisive. Either one repeats the divisive narratives of militarist history (British versus Irish, Loyalist versus Nationalist, North versus South), or one complicates and pluralizes memory by retrieving stories of “crossed identity” — for example, tales of siblings, neighbors, friends, and lovers, who found themselves on opposite sides at that historic moment.
And what about those tales of siblings, neighbors, friends and lovers? The Archives of RTÉ (the Irish national public broadcaster) provide an interesting lesson. This organization does an admirable job in outreach and amplification. This is from the [introduction](http://www.rte.ie/archives/exhibitions/1011-ireland-and-the-great-war/?ref=lorcandempsey.net) by Myles Dungan to their exhibition on World War 1:
> In some respects this collection of RTÉ archive material is a microcosm of that Irish psyche. ... Its archive reflects Irish preoccupations. Its omissions point towards our blind spots. On the debit side is the fact that, as a repository of oral history the RTÉ catalogue includes barely thirty first-hand Irish witnesses of the First World War. On the merit side is the fact that it includes all of thirty first-hand witnesses of the Great War in a time of calculated and culpable amnesia.
A ‘calculated and culpable amnesia’ is an interesting and strong phrase, introduced here to place the actions of the archive in the context of an overall political/cultural trend which wanted to emphasise the ‘Irishness’ of an independent Ireland. But ‘Irishness’ was often defined negatively in relation to ‘Englishness’ or 'Britishness', with implications for what becomes part of the historical or commemorative record.
Linking these two texts, there is a contrast then between at least two conceptions of memory. First, there is an 'Official History' which entails a 'Grand Narrative' which in turn requires a **calculated and culpable amnesia**, a selective remembering and forgetting in the archive. Or, in the example above, the neglect of a monument to the Irish dead in the First World War. Second, there is a **complicated and pluralized memory**, a fuller record of mixed identities and experience based on stories which have to be retrieved. But such a pluralized memory often depends upon the archive or library or museum which intervenes to save and keep those memories.
The centenary celebrations underlined how attitudes around this double remembrance had changed, as the country embraced the memory of those dead in the Great War.
Memory was also pluralised in another way. There was an active recovery of the memories, experiences and [contributions](https://www.nytimes.com/interactive/2016/03/16/opinion/eight-women-of-irelands-1916-easter-rising.html?ref=lorcandempsey.net) of women to the Easter Rising, hitherto poorly represented in historic and commemorative work. And interestingly, "[what we know of women’s participation in the Rising has been transformed by the material released from the Military Archives over the past decade](https://www.rte.ie/centuryireland/index.php/articles/women-of-the-rising?ref=lorcandempsey.net)."
Such a pluralized memory is an example of "endangered knowledge," a compelling phrase used by the guest editors of a [special issue](https://kula.uvic.ca/collections/special/endangered-knowledge/?ref=lorcandempsey.net) of the new journal [Kula](https://kula.uvic.ca/?ref=lorcandempsey.net). They [write](https://kula.uvic.ca/articles/10.5334/kula.60/?ref=lorcandempsey.net):
> We present here theoretical and practical considerations of questions relating to archival salvage and erasure, the persistence of the public record, indigenous knowledge, and the politics of loss. Although imperfect and blunt, our term ‘endangered knowledge’ is meant to conjure a larger set of emerging ideas that cross disciplinary, practical, and professional boundaries. ....
> In soliciting contributions, we sought to explore endangerment as a critical category of analysis for records, data, collections, languages, ecosystems, and networks—and to consider the cultural and existential stakes of the dissemination and preservation of material at risk of disappearing, whether that risk stems from inherent ephemerality, environmental loss, a lack of proper preservation measures and care, or acts of deliberate erasure.
"Acts of deliberate erasure" reminded me of "calculated and culpable amnesia." The contributions to the special issue talk of the variety of ways in which the memories or knowledge of communities may be endangered. These include those that arise from the always already interpreted nature of collecting, where materials may not align with an official or accepted narrative, where descriptive or organizing practices assimilate materials to the collector's perspective, or where the experiences and memories of particular communities may be overlooked or shunned.

A part of the War Memorial Gardens
## Memory institutions redux
I am [sometimes credited](https://www.wikiwand.com/en/Memory%5Finstitution?ref=lorcandempsey.net) with introducing the phrase 'memory institution' in a library context, although other earlier uses have been noted. This was in the context of a working group and [report](https://www.ariadne.ac.uk/issue/22/dempsey/?ref=lorcandempsey.net) of the European Commission which looked at shared interests across libraries, archives and museums. In this group, it was a necessary step as we found ourselves stumbling repeatedly over vocabulary.
I think 'memory institution' is a useful shorthand, a necessarily reductive convenience which allows conciseness in discussion across these domains.
However, I do not think we should lean too heavily on it for various reasons. The three domains have different orientations and curatorial traditions, and have important roles that may or may not be encompassed by the term. And certainly, there is a very sophisticated and nuanced literature and legacy of discussion about the relations between experience, memory, representation, history, authority and institutions. Perhaps more so in the archival community, given the closeness between the archive, history and government, than in libraries. Concepts such as [memory work](https://www.wikiwand.com/en/Memory%5Fwork?ref=lorcandempsey.net) and [imagined communities](https://www.wikiwand.com/en/Imagined%5Fcommunity?ref=lorcandempsey.net) have made us more aware of the complex interplay between mediation, experience, power, community identity and the memory institution.
The 1916 example above highlights some general issues that arise as we think about how memory institutions support cultural identity and memory.
- ***Authority***. We now recognize that collecting reflects dominant or received structures - differently of course in difference contexts, and more or less explicitly. Experiences of the Great War were elided in the archive because they were elided in the ideology of the Irish Free State. Other authority structures may be in play, around attitudes, discipline, belief, gender, politics, ....
- ***Recognition***. Social or collective identity is important for individual identity formation, and it is important for people to recognize those collective identities in cultural and educational institutions.
- ***Fugitive***. The environment of knowledge production and sharing has changed. Of course, not all experience or memory is committed to fixed texts, and oral or visual materials may be important. But in print cultures also, pamphlets, posters, video may not have been collected. This has become a major issue in a digital environment given the importance of the web and social media, and of major changes in how materials are created, distributed and consumed. Think of how news has moved from relative static programming or newspapers to complex databases which will have a variety of manifestations, and to a multitude of web and video services. Think of how we create and experience music, video and movies. This extends and complicates the role of memory institutions. For example, the National Library of Ireland issued a [call ](https://www.nli.ie/en/community-collecting.aspx?ref=lorcandempsey.net)to the public to nominate websites which they believe "best remembered the events of 1916" and should be archived. It also greatly diversifies the range of institutions with an interest in cultural (or scholarly) memory and experience. The role of community archives is notable. The Documenting the Now project provides a fascinating [exploration](https://inkdroid.org/2018/11/08/ferguson-principles/?ref=lorcandempsey.net) of issues involved in capturing social media around the Ferguson protests, including a discussion of the application of archival principles.
- ***Context***. Materials may be assimilated to the context of the collecting institution, ignoring or ignorant of how meaning is generated in their originating environment or of cultural protocols which are important for how they are described, organized or shared. This a general issue, but has become of keen interest in relation to a heightened awareness about indigenous knowledge.
So, while acknowledging its convenience as a term, these factors prompt me to have two hesitations about 'memory institution.'
The first is major and I can only gesture towards it here. The political and commercial forces which have made fact and news problematical, the scale of social media and other network communication in a 'post-scarcity' world, and the social diversification of curatorial interests further complicate our sense of collective memory and of its guardianship. New network level organizations have emerged (*e.g.* Internet Archive, Wikipedia). The scope of existing memory institutions will evolve in this complex environment in which a diffuse pattern of institutions is stepping up to a memory role. The focus on the border between Northern Ireland and the Republic in Brexit discussion has highlighted the evolving complexities of identity (British, English, Northern Irish, Irish, European) and contested memories. How will the multiple voices and contexts be recorded?
The second is that it suggests a passivity, an unproblematic filling of receptacles with memory. But this is far from the case. Thinking about institutions which resist 'culpable amnesia' and which 'pluralize memories' is to acknowledge their very active recognition and recovery of experiences, memories and the texts which convey them.
I turn to an example from a more recent period in Irish history. The Linen Hall Library in Belfast has created the [Northern Irish Political Collection](https://linenhall.com/about-us/collections/?ref=lorcandempsey.net).
> The collection has grown to some 350,000 items including books, pamphlets, leaflets, posters, manifestos, press releases and cuttings, audio-visual material and periodicals, encompassing all shades of opinion. Political and social archives include that of the Northern Ireland Civil Rights Association, the Northern Ireland Women’s Rights Association, the Peace People, and the Northern Ireland Women’s Coalition archives. A living collection which is added to by acquisition and donation, it is a definitive archive of national and international significance.
This is a remarkable achievement, documenting all elements of the Northern Irish troubles - the "[subversive and the seditious](https://www.historyireland.com/20th-century-contemporary-history/the-northern-ireland-political-collection-at-the-linen-hall-library-11/?ref=lorcandempsey.net)"; posters, pins and pamphlets as well as books and journals; fugitive materials from underground groups.
Robert Fisk, the journalist, noted\*:
> … No politician, no government can conceal the sins and omissions of the past or conceal the possibilities for the future when an ordinary member of the public can walk into the Linen Hall Library and find the record of what all sides said in 1969 or 1974, 1989 or today.
High praise ... but so appropriate for a memory institution which has actively and farsightedly captured the plural memories of a contested time and is a vital stay against cultural or political amnesia.
\* Formerly on the website of the Library, but no longer apparently there. Quoted [here](https://www.academia.edu/7950623/Piecing%5FTogether%5Fthe%5FExploded%5FFragments%5FThe%5FImportance%5Fand%5FUnreliability%5Fof%5Fthe%5FArchival%5FProject%5Fas%5FReflected%5Fin%5Fthe%5FArchives%5Fof%5Fthe%5FLinen%5FHall%5FLibrary%5FBelfast%5Fthe%5FNational%5FArchives%5FDublin%5Fand%5Fthe%5Fworks%5Fof%5FCiaran%5FCarson?ref=lorcandempsey.net).
**Acknowledgement:** I am grateful to the following for advice as I completed this entry: Aedín Ní Bhróithe Clements,Christian Dupont**,** John Fitzgerald, Constance Malpas, Bethany Nowviski.
**Note:** 12/8/18\. Edited slightly for clarity and presentation. Brexit reference added. 4/4/2021\. Cosmetic changes, and feature picture added. 8/22/2023\. Cosmetic changes and sentence added to feature paragraph. Fisk link fixed. 10/19/2024\. Substituted my own picture of War Memorial Gardens for prior Wikimedia one. Added sentence about 'too grand.'
**Picture:** I took the opening picture of Los Angeles Public Library.
### University Futures are shaping Library Futures
URL: https://www.lorcandempsey.net/university-futures-are-shaping-library-futures/
Last updated: 2024-10-10T18:16:51.000Z
This blog entry is written to accompany [University Futures, Library Futures: Aligning library strategies with institutional directions](https://www.oclc.org/research/publications/2018/oclcresearch-university-futures-library-futures/report.html?ref=lorcandempsey.net). This is a collaboration between Ithaka S+R and OCLC Research, and is supported by the Andrew W. Mellon Foundation. There is a companion [blog entry](https://sr.ithaka.org/blog/universities-are-changing-and-so-are-their-libraries/?ref=lorcandempsey.net) by Deanna Marcum and Roger Schonfeld. The report looks at how libraries are aligning service investments in support of institutional missions in an evolving higher education system.
## Driving around Ohio: the scale and diversity of the US university system
When we first came to the US, we were keen to explore. We drove around Ohio and gradually widened our radius over long weekends and other breaks. Indeed, we did this for quite a while … pretty much until the children protested and would no longer let us. One feature helped pattern our trips: the presence of a university or college. This was not especially limiting, because it seemed there was a university around every corner.
We were amazed by the richness of the US university system, and by its diversity in so many dimensions – size, setting, mission, focus, public/private. Ohio University dating from 1804 is the oldest University in Ohio, located in Athens, a relaxed college town opening up to an Appalachian hinterland. There is great variety in the thirteen other public universities in the Ohio system, which includes institutions with a strong regional focus, as well as those which attract international attention. The University of Cincinnati’s ambition is evident in its fine campus marked by signature ‘starchitect’ buildings. There are Kent State and Bowling Green universities; Cleveland State, Akron and Youngstown State in urban rust belt settings; Miami (get the t-shirt: “Miami was a university before Florida was a state”); and others. The youngest university in the system is Shawnee State, founded in 1986, “offering a highly personalized, affordable, and accessible education dedicated to the exploration of emerging technologies and emerging ideas.”
Of course this system also includes The Ohio State University, an academic powerhouse which sits in the global circuits of research and scholarship, as well as being central to the economic, social and cultural life of Columbus and Ohio. These large land-grant public institutions are a major achievement of the US system.
There are the well-known liberal arts colleges in picturesque chocolate box settings (Kenyon, Wooster, Denison, Oberlin). There is a leading private research university which is an important anchor in the cultural and educational quarter of Cleveland, Case Western Reserve University.
But beyond some of these better-known institutions, there is the very broad range of small private colleges dotted across the state, such as Urbana University (home of the Johnny Appleseed Museum), and the two, yes two, universities in Tiffin, Ohio. Tiffin is home to Heidelberg University, a liberal arts college, and Tiffin University, a private university which “provides a personal and practical education for motivated students who want real-world experience and results.” “There are no ‘ivory towers’ at Tiffin University” as it says on its website. We were also interested in the importance of religious communities, and how many universities offer an education in an explicitly values-based setting. One thinks of the Franciscan University of Steubenville or Ashland University (“affirms Christian values as a core element of the University’s institutional identity”).
This is just a brief reminder of the scale and diversity of the university system. I emphasize it, because when we talk about higher education we sometimes overlook this variety. And of course, this is just to look at the non-profit four year system. It does not consider community colleges (who of course have an important relationship to the public university system), for-profit institutions, and others.
This variety is now part of the intense debate about mission, organization and direction in higher education. This is driven by multiple factors, including sustainability, affordability and inclusion, research evaluation and the associated influence of rankings, and increased recognition of the diversification and distinctiveness of mission. Universities are making choices about direction and focus, and thinking about how to differentiate themselves.
As universities change and grow, so do libraries. And there is a very active discussion about academic library directions. Against the university background sketched above, such discussion shares two interesting features.
First, it sometimes proceeds without reference to the universities of which libraries are a part. However, the report argues that the most important long-term influence on the library is the requirement placed on it by changing patterns of research and learning. These changing patterns, in turn, are shaped by the focus of the parent university or college and the directions it is taking.
> This presumption of homogeneity encourages a view of academic libraries in which the research library is seen as a terminal point in evolution, rather than as one type among others. However, where universities and colleges seek to differentiate themselves this presumption is increasingly misleading.
Second, it often presumes some homogeneity of approach or direction, different only in degree among libraries. This presumption of homogeneity encourages a view of academic libraries in which the research library is seen as a terminal point in evolution, rather than as one type among others. However, where universities and colleges seek to differentiate themselves this presumption is increasingly misleading. The models of excellence for libraries supporting, say, an elite comprehensive research university, a liberal arts college devoted to broad-based student learning, or an increasingly career-oriented public institution will be very different from each other.
> The models of excellence for libraries supporting, say, an elite comprehensive research university, a liberal arts college .., or an increasingly career-oriented public institution will be very different from each other.
These features motivated this study. We contend that different types of academic libraries will be on different vectors, influenced by the types of universities or colleges they support. Accordingly, we set out to characterize the ways in which universities differ from each other, to develop a new way of characterizing library service areas, and then to look at how well library choices about service investments in those service areas are lining up to the type of university they are in. As we expected, we are indeed seeing important shifts.
## Thinking about universities … differently
Our approach to the university typology relied on national survey data compiled by the US Department of Education in the Integrated Postsecondary Educational Data System (IPEDS), and was led by Constance Malpas and Rona Stein. We computed institutional profiles for 1500 colleges and universities, focused on two primary dimensions. The first dimension characterizes the balance of institutional attention devoted to three poles:
- research (specifically, doctoral level scholarship),
- liberal education (arts-and-sciences focused baccalaureate education),
- career preparation (professional degree and non-degree certificate programs).
The second dimension characterizes the mode of educational provision, on a continuum between residential and convenience:
- traditional residential programs are designed for full-time, on-campus students
- more flexible offerings (convenience) are designed for ‘new traditional’ students, including part-time, adult, and distance learners.
Applying this working model to a large segment of the US higher education sector makes it possible to distinguish important differences in institutional direction. A key benefit is that it allows visualization of institutional ‘types’ based on the relative emphasis of educational activity and mode of provision. ***Figure 1*** shows an application of this kind of visualization, comparing average values for two different cohorts with distinctively different institutional profiles: members of the Oberlin Group association of liberal arts colleges, and members of the Association of American Universities, which gathers leading research universities in the US.

Figure 1
***Figure 2*** shows a library application. These pictures represent the parent institutions of two academic library consortia. The analysis here shows clearly how the libraries in one consortium support broadly peer institutions (on the right, where the triangles overlap), while the libraries in the other support universities with a spread of emphases (on the left, where the triangles diverge).
In a group of peers, the intersection of interests may be broad, and members may look to the consortium across a variety of activities. In this case prioritization becomes an importance consideration. Where the intersection of interests is smaller (because of size or type of institution, for example), then the common areas for consortial attention may be more limited (focused on resource sharing, for example).

Figure 2
## Telling the academic library story differently – student success/retention, research support and community engagement
Historically, the library service was strongly associated with the collection. As the library engages more with the research and learning life of the university, so the nature of the service is shifting. The report presents a framework for thinking about library services in terms of investments in particular areas. And we explore how libraries are investing against those areas. Roger and Deanna describe our approach [here](https://sr.ithaka.org/blog/universities-are-changing-and-so-are-their-libraries?ref=lorcandempsey.net).
And we do indeed observe how libraries increasingly present their services in ways that align with the main lines of university activity, which will tend to cluster around student success, research productivity and then maybe some form of community engagement. The relative emphasis will vary by type of institution.
For example, Ohio State University Libraries recently published a [succinct strategic statement](https://library.osu.edu/strategic-directions?ref=lorcandempsey.net). The first three directions are: *Equip students for lifelong success*; *empower knowledge creators*; *engage for broader impact*. In this way, the library is lining up to university objectives. And if we were to judge its excellence, it would be in terms of how much it helped to make students and researchers more successful in their work. Not, in terms of collection size or gate counts. The library story is very much about how it contributes to institutional goals.
> And if we were to judge its excellence, it would be in terms of how much it helped to make students and researchers more successful in their work. Not, in terms of collection size or gate counts.
Based on the patterns noted here, we can observe several trends. Academic libraries in research intensive institutions are increasingly preoccupied with support for digital research workflows and are making substantial investments in appropriate software and services, alongside continued investment in traditional, collection-centric activities. College and university libraries in institutions with a learning and teaching emphasis position themselves more explicitly as partners in instructional design and collaborative learning. Libraries in institutions that are pivoting toward more career-directed programming are creating space for career counseling services within the library, aligning library services with ‘real world’ work experience and promoting the library as a partner in preparing for life after college. These service patterns reflect strategic choices that promote increased alignment of library activity with broader institutional interests and over time, will result in a more diversified academic library landscape.
Similarly, a shift from a residential focus to more convenience-based offerings potentially calls for a different approach to library services, a more focused tailoring around course requirements or greater visibility in learning and teaching workflows.
Academic libraries are in an interesting phase of development as they engage more with the life of their institutions. We hope that this report provides useful evidence and arguments to help them plan with confidence and position with effect.
Related reading:
- Dempsey L., Malpas C. (2018) [Academic Library Futures in a Diversified University System](https://doi.org/10.1007/978-981-13-0194-0%5F4?ref=lorcandempsey.net). In: Gleason N. (eds) Higher Education in the Era of the Fourth Industrial Revolution. Palgrave Macmillan, Singapore
**Acknowledgements**
The OCLC team was Constance Malpas, Rona Stein, and Lorcan Dempsey. The Ithaka team was Deanna Marcum and Roger Schonfeld. Constance Malpas managed the project. Erin Schadt oversaw the production of the report. We are very grateful to the Andrew W Mellon Foundation for support during this project.
I would like to record a personal note of thanks to Constance Malpas for all her work on this report and for conversations which have helped shape my thinking about libraries and their futures.
**Note:** This blog entry draws on some of the text from [this article](https://doi.org/10.1007/978-981-13-0194-0%5F4?ref=lorcandempsey.net).
**Note:** Slight updates on 10/21/18.
**Note:** Edited for appearance on transition here 29 March 2021, including feature picture and spacing.
**Picture:** I took the feature picture at Otterbein University, Westerville, Ohio.
### A reservoir not an ocean - visualizing and operationalizing collective collections
URL: https://www.lorcandempsey.net/books-reservoirs-and-oceans/
Last updated: 2022-11-09T04:50:10.000Z
When I think of the Google Books initiative now, three things stick with me. The first is simply what an audacious idea it was – to digitize all the books. The second is that without it, the book literature is less accessible than the web literature, which seems a pity. Google Books has allowed fine-grained discovery over the topics, people, places and so on which otherwise would largely be hidden between the covers.
The third is more subtle, but marks an interesting shift in how we think about library collections and books in general. Before the initiative, we thought of the books in library collections as a vast expanse. We could not see the edges. They were like an ocean. Afterwards, the aggregate library collection appeared more bounded, more finite. More like a reservoir which could be measured and managed. And as Google spoke with various libraries about filling out parts of their digital corpus this became clearer. Indeed, it made it more realistic to actually talk about an ‘aggregate library collection.’
> WorldCat represents the holdings of thousands of libraries around the world. It is the best available proxy for the aggregate library collection and by extension for the scholarly and cultural record of which libraries are the steward.
## The empirical basis
OCLC and WorldCat have played an important role in this shift also. WorldCat represents the holdings of thousands of libraries around the world. It is the best available proxy for the aggregate library collection and by extension for the scholarly and cultural record of which libraries are the steward. In recent years, we have looked at providing an empirical base for discussions about that aggregate collection. This has meant that we can talk about the aggregate library collection or the collective library collection while having a real sense of its contours, in whole or at different levels (the collections in a particular region, for example, or the intellectual output of a particular country). While much of work has been in North America, we have also done work with library collections elsewhere.
In fact, an [important early analysis](https://www.dlib.org/dlib/september05/lavoie/09lavoie.html?ref=lorcandempsey.net) of this kind was of the original ‘Google 5’ libraries who participated in the ‘Google Print Library Project.’ The findings here have been confirmed over subsequent investigations, largely carried out by Constance Malpas and Brian Lavoie. Especially notable is the finding that, in my colleague Brian Lavoie’s words, rareness is common – many libraries do in fact have materials that are not widely held. Which in turn leads to the need to have wide library participation to ensure broad coverage of the published record (in resource sharing, digitization, or other initiatives).
Brian has [just written about some of that work](https://blogs.lse.ac.uk/impactofsocialsciences/2018/09/19/how-information-about-library-collections-represents-a-treasure-trove-for-research-in-the-humanities-and-social-sciences/?ref=lorcandempsey.net) – mining WorldCat for insights about the aggregate library collection and the characteristics of the scholarly and cultural record it represents. He presents an updated version of a map of library collections in the US and Canada, originally created several years ago by our colleague J.D. Shipengrover for our [**Print management at mega-scale*](https://www.oclc.org/research/publications/library/2012/2012-05r.html?ref=lorcandempsey.net) report. This shows the concentration of library collections laid out over Richard Florida’s mega-regions framework.
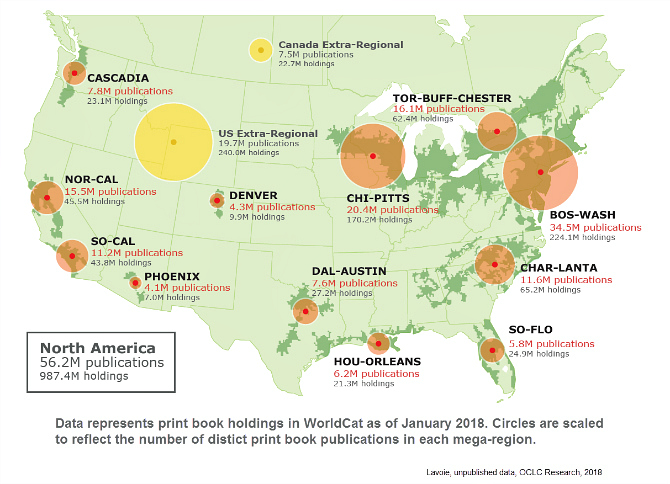
## A reservoir of books
I think that this picture – and the [variety of analyses](https://www.oclc.org/research/publications/library/2013/2013-09r.html?ref=lorcandempsey.net) that accompany it – has been influential in the shift I mentioned above – the shift to thinking about library collections as a reservoir. It puts a real shape on the distribution of the aggregate North American library collection, quantifies it, and hints at the type of regional discussion about shared management that we are now seeing.
> Reading this piece by Brian Lavoie reminded me how much I love the map of potential “mega-scale libraries,” were we to combine our print holdings regionally. [https://t.co/jBnKOfUmPr](https://t.co/jBnKOfUmPr?ref=lorcandempsey.net) // [pic.twitter.com/4lhbJ5JBRL](https://t.co/4lhbJ5JBRL?ref=lorcandempsey.net) // Dan Cohen (@dancohen) [September 20, 2018](https://twitter.com/dancohen/status/1042855506241626113?ref%5Fsrc=twsrc%5Etfw&ref=lorcandempsey.net)
An important aspect of this more bounded view is the emergence of what I call collective collections – where collections are addressed at various aggregate levels above the individual institution.
A collective collection might be realized at different levels of integration: through data (a visualization, for example), or through discovery (what is available through a particular discovery interface), or through federating applications as in consortial borrowing (what is available for lending), or through actual physical consolidation (at CRL, CAVAL, ReCAP, or some other shared storage), or through some other agreement. A collective collection might also be at different geographic scales: state, regional, national and so on.
## Observations on collective collections
Here are some brief observations about collective collections, in terms of how they are managed and in terms of implications for their use.
1. **Visualising and analysing the collective collection**: Where we have aggregate metadata or full-text from collective collections, we can visualize them in interesting ways, identify patterns in their composition, and draw out useful inferences touching on a range of issues. This might be about the management and disposition of collections (as in the [mega-scale report](https://www.oclc.org/research/publications/library/2012/2012-05r.html?ref=lorcandempsey.net) mentioned above) or about the body of knowledge represented by those collections (as for example, in [our study of the Irish published record](https://www.oclc.org/research/publications/2018/oclcresearch-irish-published-record.html?ref=lorcandempsey.net), summarized [here](https://www.irishtimes.com/culture/books/what-is-the-most-popular-irish-book-1.3136544?ref=lorcandempsey.net)). Of particular interest in the latter case, is the recent [announcement](https://www.hathitrust.org/blogs/perspectives-from-hathitrust/hathitrust-research-center-extends-non-consumptive-research-tools?ref=lorcandempsey.net) that the HathiTrust Research Center now “provides access to the text of the complete 16.7-million-item HathiTrust corpus for non-consumptive research, such as data mining and computational analysis, including items protected by copyright.**“*
2. **Operationalizing the collective collection**: In recent years, the management of print library collections at the collective level has become an active area of discussion, planning and implementation. Existing organizations have taken this on as an activity (e.g BTAA) and some new organizations have emerged (e.g. WEST, EAST). Managing the collective collections of these groups has had a regional flavor, which makes sense from a logistics point of view.
Decisions about consolidating print collections are also influenced by the availability of digital surrogates. The Internet Archive and Google Books are important in this context. The role of HathiTrust is of special interest, given its mission to preserve the scholarly record and the fact that it is a collaboratively managed within the library community. The relationship between the digital resource curated by HathiTrust, the print resource curated by CRL, and the arrangements put in place by shared print collaborations will be more closely managed within an evolving ecosystem of services.
These activities are about retrospective collection development, configuring materials that have already been added to library collections. At the same time, the changing role of the book collection, the emergence of shared approaches to management, and the availability of new analytics services will make prospective, collaborative collection development more feasible than it has been in the past, as libraries do actually think about building and maintaining their collections in a collective context.
3. **Calibrating the collective collection**: WorldCat (and union catalogues in other parts of the world) have emerged as important sources of comparative intelligence as libraries begin to look at print collections in aggregate and think about managing particular collective collections. And also as libraries want to calibrate their collections against a regional, national or broader context. Or as they want to calibrate their collection against existing digitized collections. Or as they want to think about prospective collection development in collaboration with peers. Having intelligence about collections at various aggregate levels is now increasingly important, as libraries want to make responsible decisions within a regional group or in the context of general availability, and as groups want to make decisions about coverage and overlap.
Increasingly, libraries want to balance individual managing down of collections with a collective responsibility to the print scholarly and cultural record. And of course, different libraries and groups will recognise different responsibilities here. The ability to record retention commitments in WorldCat is an important infrastructural element, as libraries and groups can disclose important intelligence about their collections to help decision making.
> Increasingly, libraries want to balance individual managing down of collections within a collective responsibility to the print scholarly and cultural record.
The management of collective collections also influence how libraries organize themselves and their services. Here are two areas of note in this context ….
1. **Collaboration at scale**. Operationalising collective collections will happen inside consortial arrangements, existing, or as noted above, newly created. Much of this activity will have a regional scale, given the logistics of print materials. Although there is also a desire to aggregate or coordinate at higher levels and certainly there is advantage in having consistent policy frameworks. At some stage we might expect to see a level of coordination which assures the integrity of the print scholarly and cultural record.
At the same time, some activity may be better carried out at network scale. It is useful to have data at this level for example and OCLC supports a network of over 16000 libraries who collaborate at scale to describe, discover and share their collections. This has resulted in important infrastructure in WorldCat and associated services which is widely relied on. HathiTrust is in an interesting situation – will it evolve the organizational and sustainability models for it to become a persistent part of infrastructure, widely relied on in the library community and beyond? Will it scale to support library collaboration at network level?
In this way, the collective collection throws up questions about models and issues of collaboration at several levels. [I have discussed many of these questions elsewhere](https://blog.oclc.org/lorcand/the-powers-of-library-consortia-1-how-consortia-scale-capacity-learning-innovation-and-influence/?ref=lorcandempsey.net).
2. **Library logistics**. Logistics is about moving materials quickly and efficiently through networks. Library operations increasingly have a logistics flavor – thinking about how best to manage stocks and flows. We will see increasing interaction between collection development, resource sharing, shared print and digitization as libraries look at an ecosystem of services around effective management and delivery of collections. This will be multiscalar (Ohio State participates in OhioLINK, BTAA and HathiTrust, for example). And it will involve interesting decisions about consolidation vs federation (of collections, data and applications), which in turn involves various tradeoffs, notably between efficiency and control at different levels (what sort of authority, for example, will individual libraries cede to consortia of which they are a part).
Libraries have entered a phase where they are now looking at managing print collections as a finite resource, and where there is systemwide attention to collective collections. Collections are reservoirs to be managed. We are in a period of organizational design and innovation as new frameworks for thinking about and managing collective collections are put in place.
> Libraries have entered a phase where they are now looking at managing print collections as a finite resource, and where there is systemwide attention to collective collections.
Thanks to my colleague Brian Lavoie for comments on an earlier version of this post.
**Related entries:**
- [Systemic change: CIC and Google](https://www.lorcandempsey.net/orweblog/systemic-change-cic-and-google/)
- [The anatomy of an aggregate collection](https://www.lorcandempsey.net/orweblog/the-anatomy-of-an-aggregate-collection/) (a discussion of the original Google 5 analysis).
**Picture:** I took the feature picture at the Hoover Dam and Reservoir, Ohio.
**Note:** Cosmetically amended on 27 March 2021 to add headings and feature picture. Summary sentence and pullquotes added 8 November 2022\.
### The powers of library consortia 4: scoping, sourcing and scaling
URL: https://www.lorcandempsey.net/the-powers-of-library-consortia-4-scoping-sourcing-and-scaling/
Last updated: 2023-06-12T02:11:26.000Z
1. [The powers of library consortia 1: How consortia scale capacity, learning, innovation and influence](https://www.lorcandempsey.net/the-powers-of-library-consortia-1-how-consortia-scale-capacity-learning-innovation-and-influence/)
2. [The powers of library consortia 2: Soft power and purposeful mobilization: scaling learning and innovation](https://www.lorcandempsey.net/the-powers-of-library-consortia-2-soft-power-and-purposeful-mobilization-scaling-learning-and-innovation/)
3. [The powers of library consortia 3: Scaling influence and capacity](https://www.lorcandempsey.net/the-powers-of-library-consortia-3-scaling-influence-and-capacity-for-impact-and-efficiency/)
4. ****The powers of library consortia 4: Scoping, sourcing and right-scaling**
In the previous blog posts in this series, I have spoken about four areas where consortia scale library capabilities: capacity, learning, innovation and influence. In considering general consortial or group activity and its relation to institutional investment (of dollars or of attention/expertise), the opening post also introduced three important axes where choices are made: scoping, sourcing and (right)scaling. Here, I amplify those introductory remarks.

While the range and diversity of consortial activity is enormous, some of the important ways in which they are different relate to these three axes. Again, given that diversity, this is a preliminary and impressionistic discussion.
## Scoping
What should consortia do? What is the right scope?
****Single or multipurpose?** As discussed in the first post in this series, there is an interesting balance between economies of scope (where, for example, it makes sense for members to concentrate a variety of different functions with an organization, PALNI being one example) and economies of scale (where the costs of providing a service, including infrastructure, marketing, R&D, etc., are spread across many participants, as in HathiTrust). The former case may favor the trend I have already noted, where a consortium evolves into a general collaborative vehicle that members reflexively turn to when new or shared needs arise. Of course, this does not mean a consortium can do everything – there is a cap depending on resourcing, and libraries have to decide how much resource they transfer into a consortium, how much of their staff time is devoted to committee and collaborative working, which of their activities might be shared across consortium members, and, indeed, which consortia to turn to for which needs.
****Peer or multitype.** The intersection of interests between members of a consortium is an important driver of priorities and activities.

Consider for example these two pictures, which represent the parent institutions of two academic library consortia. These are drawn from our [University Futures, Library Futures](https://www.oclc.org/research/publications/2018/oclcresearch-university-futures-library-futures.html?ref=lorcandempsey.net) work, where we have developed a method to characterize higher education institutions based on [IPEDS data](https://nces.ed.gov/ipeds/?ref=lorcandempsey.net). We characterize universities based on their distance from three poles: research, liberal education, and career-preparedness. The triangles show how individual universities are positioned relative to these poles. The analysis here shows clearly how the libraries in one consortium support broadly peer institutions (on the right, where the triangles overlap), while the libraries in the other support universities with a spread of emphases (on the left, where the triangles diverge).
In a group of peers, the intersection of interests may be broad, and members may look to the consortium across a variety of activities. In this case prioritization becomes an importance consideration. Where the intersection of interests is smaller (because of size or type of institution, for example), then the common areas for consortial attention may be more limited (focused on resource sharing, for example). And in this case, finding those common areas of attention becomes important.
****Right-scoping and optimization.** It does not make sense for all organizations to operate equally across all four areas I have mentioned – each requires different skills and orientations, and it is difficult to optimize across all. For this reason, right-scoping is a critical issue – which activities does it make sense to pursue?
Think of capacity and influence, for example. Scaling capacity benefits from an operational focus and economies of scale. Scaling influence involves political and advocacy skills, the broadest possible base of representation to give weight to assumed positions, and agility across a potentially broad range of areas. So, in each case success requires very different attributes and it may not make sense – or be possible – to optimize a single organization for both together.
Does this suggest that organizations should not try to scale both capacity and influence? In this context, one could argue it made sense for RLUK, for example, to transfer the management of COPAC (union catalogue) to Jisc (who is now contracting with OCLC to provide the service), because, as a strategic organization, it makes sense for RLUK to scope its activity towards influence and innovation, not operational services (capacity). What about CARL and Portage, or ARL and SHARE? In each case the organization has played a central role in incubating an approach (scaling innovation); does it make sense for the organization to actually run the service long term (scaling capacity)? Not least, this would present a significant opportunity cost, but it may also tie up a whole range of capacities and investments. Does it make more sense to continue to encourage learning and innovation within the powerful network each organization manages? And to work with partners to operationalize such services?
As noted above, advocacy – scaling influence – was a critical part of the early development of HathiTrust. It was pushing policy boundaries, and it probably needed to be in advance of positions taken by community organizations focused on scaling influence. While these policy issues remain important, HathiTrust is increasingly likely to work with and through those organizations (e.g. ARL or ALA) to scale influence, so that it remains very focused on scaling capacity, on the operation of a major service and its sustainability.
So, I think that there are interesting questions for groups who would like to scale both capacity and influence, to build shared services and to lobby for change. However, organizations which scale capacity or influence are both now increasingly important venues for scaling learning and innovation. As already discussed, a major reason for this is that they convene networks of libraries, within which shared practices can emerge.
Those organizations set up to encourage systemwide change are an interesting example. These seek to scale influence, providing a shared advocacy and lobbying focus. Think of scholarly communication, for example. SPARC has a change agenda. COAR is a membership organization supporting the development of green open access, by supporting the emergence of networks of repositories. In each case, scaling innovation is the goal but scaling learning is also critical, as they wish to provide members with evidence and argument in support of change.
****Continuity and evolution.** Organizations need to evolve and scoping questions will be affected by the changing environment and needs of members. The evolution of shared print has been interesting here, where in some cases a shared print program has been taken on by existing organizations (e.g. BTAA), while in others new organizations have formed (e.g. WEST). In this way, just as scoping is an issue for existing organizations, so it is an issue for new organizations. When does a specific need lead to a new organization rather than the evolution or adaptation of a current one?
One response to this, particularly aiming to scale, strengthen and focus innovation, is the emergence of Educopia, Duraspace, and other organizations as incubators for new initiatives seeking to spread cost and risk. Ithaka was also established with an explicit mission to incubate non-profit startups in the education space.
Libraries and consortia will think about disinvesting and investing. When should a group cease to exist, or give up particular activities because they are sub-scale or no longer make sense? This can be difficult, given natural organizational inertia, and existing personal and institutional investments.
At the same time, consortia may grow, whether by adding members (by expanding into adjacent geographic regions, for example), by securing more investment from members (by expanding scope, for example), or by diversifying funding (by providing for-fee services to non-members, for example, or by seeking grant funding). As discussed in the opening post, a diversification of funding may result in some diversification of accountability. This in turn raises issues of governance, to make responsibilities and accountabilities more explicit.
## Sourcing
I noted in the first post that there are three common patterns through which shared services are sourced: public provision through national/state coordination and/or funding; consortial activity; and third-party provision (through a vendor).
Of course, each has its own characteristics, which may be variably present in any individual case. And each approach will have benefits and drawbacks. Public provision is a useful way of securing shared infrastructure, but community influence may be lacking or management may be bureaucratic. Consortial activity gives responsibility to members but coordination costs may be high. With a third party, control is exercised through contractual relationships, but direct influence may be surrendered for efficiency. And so on.
My focus in these posts has been on the second of these, the consortial model, acknowledging that in practice the three overlap or blend into each other, and will often occur in combination. In particular, of course, the first two will often procure services from the third to achieve their goals. OhioLINK or the Orbis Cascade Alliance, for example, will source some systems capacity with third parties.
There are two levels of interest here. First individual libraries have to make choices about how to source a shared service – do they look to a consortium or a vendor? Do they encourage a national provider – e.g. Jisc or the National Library of Australia – to provide a service? Do they establish a new consortium around a particular need (e.g. Library Publishing Coalition or Open Textbook Alliance)?
Second, consortia have to decide how to source services – do they build them themselves, look to a third party, look to a center of expertise within the consortium, and so on.
In practice, the issues in each of these cases can be similar. Here, I am mostly interested in the issues libraries face in terms of electing a consortial approach.
As the trend towards collaborative systems and services grows, sourcing issues come to the fore and libraries and consortia will more actively manage organizational frameworks around collaborative service development. A variety of issues is important here.
****Structure, staffing, organization.** Is the group organized to get the desired job done? One aspect of this is the accumulated trust that seems to be so important in streamlining decisions and actions. Another is governance: is the group organized to efficiently make binding decisions? A recent [presentation](https://www.cni.org/wp-content/uploads/2017/12/cni%5Ftale%5Fmcgeary.pdf?ref=lorcandempsey.net) noted the challenges of making decisions within the Ivy Plus group given the lack of a formal governance structure, for example.
****Agency.** A second aspect relates to agency, also discussed in the first post. Is some new organizational arrangement required to advance a collaborative agenda? This in turn raises the question of when a separate organization should be set up (as has happened with various new shared print initiatives in the US) or whether an existing center of excellence assumes responsibility (as has happened to some extent with the University of Michigan and HathiTrust, where the University hosts and operates the service on behalf of the membership).
Some collaborative activity may be based on closely supervised activity – relying on temporary staff assignments and local resources. A contrasting approach is to buy a complete service from a third-party provider. Clearly, in between there are variably structured approaches depending on how resources, staffing, and so on are secured across the group. This points to a crucial issue, which is the balance between efficiency and control. One wants to ensure alignment with the original mission while also ceding sufficient authority to the consortium management to advance without continued checking.
As noted in the introduction, the dynamic changes as a group gets bigger (and it is inefficient for all members to participate equally in decision making), or more complex (in terms of types of members or sources of funding, for example), or changes over time (as when founding members or strong guiding voices recede or are replaced).
These issues make frameworks for governance, accountability and alignment very important , and they need to address topics like scope, evaluation, ownership of data or IPR, development of requirements, sharing of innovation, and so on.
****Resourcing.** One might note that collaboration and shared infrastructure are not cheap. And greater collaboration involves greater investment in shared activities. But what is the appropriate level of investment here? And how do libraries think about where best to invest?
I would argue that we do not have a good sense of levels of investment in different collaborative activities at the moment, nor do we have a sense of what level of investment is appropriate. And inevitably libraries are differently situated with respect to collaborative work – a library which is part of a strong regional or peer consortium with a track record of shared investment and new service development is in a very different situation to one which is not a part of such a consortium.
As a community, we also incur considerable development costs around the design and development of new organizations. And while organizations like Educopia, Duraspace or others provide incubation services, the community as a whole does not have robust support for this, nor are there strong mechanisms for coordinating new initiatives.
All of this confirms that sourcing will be a subject of increasingly active debate in coming years, and issues of mission, alignment, governance, investment and business model will become more central in a mixed environment of collaboratively and externally sourced provision. It also means that choices around sourcing patterns need to become more informed. When should a group build a new activity itself or source it with a third-party provider? When should an individual library buy a service from a third party or instead participate with a consortial group to develop a similar service that is more community-driven? What level of coordination would be helpful, and how could it be enacted?
Sourcing and scaling are intimately connected. As libraries explore collaborative solutions, they need to decide at what scale to participate.
## Right-scaling
In many ways consortial or group working is about right-scaling, finding the appropriate level at which to do something. Groups must decide what the optimum level for their work is. And individual libraries must decide at what level to consort in the context of any particular activity. There are three common patterns in the consortial examples I have given in these posts:
1. regional/national groups which scale to a particular region or jurisdiction,
2. functional or peer groups which may operate at different scales,
3. groups where achieving as broad scale as possible is important, to aggregate influence or to build community infrastructure.
And of course libraries may belong to groups at all of these levels.
The regional grouping is a very common pattern for organizations that scale capacity. This may be at a country level (see UKB in The Netherlands, for example), at a state level (see OhioLINK for example), or within some other contiguous area (see the Orbis Cascade Alliance, which spans the states of Washington, Oregon and Idaho). It seems likely that one reason for the strength of local or regional groups is that that they facilitate informal learning and innovation through their networks, something that may be less strong at wider levels where personal interaction within a ‘known community’ is less strong.
Regional groupings are also very important in relation to shared infrastructure, a shared ILS for example. An interesting recent development has been the emergence of groups built around shared print management: typically, these have a regional logistics dimension as infrastructure for consolidation and delivery is important (WEST, EAST, MI-SPI, FLARE, White Rose Consortium, for example). However, the emergence of the Rosemont Shared Print Alliance in the US suggests that higher level coordination is also desirable. And certainly, one wants aspects of this work to scale to the network level in the context of stewardship of the (national or global) print scholarly and cultural record.
While the regional dimension remains strong, and may be reinforced by state or national funding, we also see examples where sustainability, service or other factors encourage growth and collaboration. For example, resource sharing networks may talk to each other, or a consortium may grow beyond its regional base. This is exemplified by NERL, which has grown its core membership beyond the North East United States, and has also added an affiliate category for libraries who are not core members but who want to participate in some of the benefits of shared negotiation.
Typically, libraries scale influence at the level of a particular political entity where policy is made. So, it is typical to have representative associations at the national level (ALA, ARL, ULC; RLUK, CILIP, SCONUL, CAUL; and so on), or, in the EU for example (LIBER).
And, as noted above libraries come together in various peer groups (e.g. BTAA, acknowledging that this sits under the parent BTAA organization) and functional or specialist groups (e.g. DPC, DPN), at various scales.
Right-scaling is of great current interest, even if it is not usually designated this way or explicitly called out in discussion. I conclude with two important right-scaling issues.
First, libraries need to decide at what scale certain activities should be carried out (scalar emphasis) – and the answer may be at several. Think of shared print or research data management for example, each of very focused interest now. Libraries may make investments at local, consortial, national levels, or with third parties. For example, Ohio State University is part of the OhioLINK, BTAA and HathiTrust shared print regimes, and will have to think about the nature and level of participation in each over time. Monash University provides local workflow for research data management through a third-party provider (FigShare) while at the same time it backs up data to a state-wide system and relies on a national scale service for discovery. Such multi-scalar activity will become more common, and again poses investment and service choices.
Second, despite considerable collaborative activity libraries face a collective action issue, which works against scale. There are many libraries, each with its own goals and objectives, and coordination costs are high. One of the main advantages of the regional consortium – or of national frameworks in countries that have them – is that they entail some coordination capacity. However, this coordination capacity is often lacking at higher levels, nationally within the US, for example, or internationally. For this reason, broad based network-level shared infrastructure is lacking. Cameron Neylon [writes interestingly](https://cameronneylon.net/blog/against-the-2-5-commitment/?ref=lorcandempsey.net) about this: “Any proposal that starts ‘we’ll just get all the universities to do X’ is basically doomed to failure from the start.” That is, they are doomed unless, he suggests, coordination mechanisms are actually built in.
Neylon is writing about scholarly communication infrastructure, and, in fact, scholarly communication is an interesting example for library cooperation. There appears to be growing consortial interest in research support infrastructure (research data management, scholarly publishing platforms, ….), as libraries are not always well-placed to develop approaches individually. See for example the work of the Scholars Portal in Ontario, one of the clearest examples of research support offered consortially.
What gives the topic some urgency, though, is recent developments in research workflow services and questions about sourcing the means of scholarly production with such services. In particular, the progressive acquisition of research workflow and administration services by Elsevier (e.g. bepress, Mendeley, SSRN, Pure, HiveBench) has highlighted issues of ownership and control. In parallel the Holtzbrinck family of services (which includes Springer Nature and the Digital Science portfolio of research workflow and productivity services) has also highlighted the growing interest of the larger publishers in research workflow. Workflow, one might say, is the new content.
As Neylon argues, a small number of large publishers can decide on direction and move quickly, in a way that collaborative initiatives often cannot.
Against this background, it is interesting to note David Lewis’s [proposal](http://hdl.handle.net/1805/14063?ref=lorcandempsey.net) that libraries collectively contribute a portion of their budget to support community-based scholarly infrastructure providers in a more coordinated way. This potentially addresses both a coordination and an investment problem, although to levels which are probably unprecedented.
It remains the case, though, that while libraries collaborate massively, massive library collaborations are rare. In terms of scaling influence, there are several trans-national organizations (IFLA and LIBER for example). In terms of scaling infrastructure, OCLC has built a network of thousands of libraries around the world but is a striking exception. In this context the future of Hathi Trust is intriguing – will it be sustained as a part of global library infrastructure and what is the path towards that? Will DPLA and Europeana find a way to sustain operations as a crucial part of shared library infrastructure, beyond the funding impulses in which they started?
## Conclusion
In this series of posts, I have given examples of how libraries consort to get their work done. They have a long history of collaborative activity of different kinds and at different levels. There is a huge variety of consortial organizations. The US environment is especially complex, as libraries potentially collaborate in multiple layered arrangements.
I have had two purposes.
1. I argue that it has become ****centrally important for libraries to find good ways of scaling learning and innovation**, so as to remain responsive to the changing behaviors and expectations of their users.
2. I want to suggest some ways of looking at consortia, notably thinking in terms of two simple schematics. First, I have suggested that ****consortia help scale influence, learning, innovation and capacity across libraries**. And, second, that ****scoping, sourcing and right-scaling are important axes of choice** as consortia position their services.
Here are some concluding observations …
****Consortial issues are underexamined …***
- Despite this history and extensive descriptive discussion of consortia, the broad shape of consortial activity is surprisingly under-explored in terms of organizational development and economics. There is a broad general literature on related topics and much relevant activity in other domains which could be usefully looked at.
- From one perspective, it is not surprising that there are open questions about consortial activity. Collaboration is difficult. Parent institutions are focused on local value, and it may sometimes be difficult to justify or explain investment in cross institutional activity. Requirements change in ways that don’t always align with consortial evolution. It may be challenging to take a systemwide view from an individual library perspective. However, there are some striking areas where we might have greater consensus.
- These include agreement about appropriate levels of investment in shared activity, patterns of when and how to consort, models of successful consortial activity, and a view of optimum sourcing and scaling choices in particular circumstances. And, critically, about network level shared activity (where the network is at national or higher level).
****Scaling learning and innovation is a central driver …***
- The research and learning practices of library users are changing, the information environment is diversifying, and cooperative service opportunities are amplified, all under the influence of network and digital approaches. The imperative to understand this environment and to evaluate appropriate responses is strong.
- Groups play an increasingly central role as they mobilize their networks to scale learning and move innovation into practice. Learning and innovation are emergent features of shared practices and interaction.
- The soft power of consortia to convene and scale learning and innovation should be explicitly encouraged, acknowledging there will be increased competition among venues with a specific focus on scaling learning and innovation.
****Libraries will need to rationalize their affiliations …***
- Collectively libraries invest a major resource in maintaining and participating in consortial organizations. It may seem that the opportunity costs of participation are sometimes too high, that the general lack of planned coherence can be a drag on development, that effort may be diffused across redundant organizations with unclear scope. And that all of this can prevent any one organization from achieving the scale efficiencies or impact that are really possible.
- At the same time, additional investment in shared capacity may actually be needed to achieve the benefits libraries need most.
- This creates an inevitable tension: libraries need to collaborate more, and more effectively, and need better organizational frameworks to do so; yet they may find that the current configuration of collaborations is not yielding the desired results. Accordingly, there is a feeling that libraries participate in shared activities both too much and not enough.
- However, it is not simply more collaboration that is needed – it is a strategic view of collaboration, especially where there are new infrastructure demands (for example, for shared digital preservation, web archiving or research data management), increased challenges for advocacy (around value and values), and growing competition between libraries and other network information service providers (for example, for research support services).
- This underlines how individual library reliance on consortial activity is variable. And we should see libraries become more purposeful about what portion of their budget to earmark for collective activities that advance their mission faster, more cheaply, or otherwise more effectively than going it alone, and about ensuring that those dollars are directed to the organizations that can achieve what is desired.
Libraries can scale services and influence in several ways. The consortial approach will remain a central if challenging choice, all the more challenging as libraries need to work hard to work together effectively.
****Acknowledgements.** I am grateful to the following people for generous comments on earlier drafts: Gwen Evans, Mike Furlough, Kevin Guthrie, Susan Haigh, Brian Lavoie, Kirsten Leonard, John MacColl, Constance Malpas, Barbara Preece, Judy Ruttenberg, Katherine Skinner, John Wilkin, Nicola Wright. Of course, I alone am responsible for the use to which I have put their advice and they do not necessarily share any of the views expressed here! I presented some of this material at the JULAC 50th Anniversary Conference in Hong Kong, and I benefited from the views outlined in the formal responses of Peter Sidorko and Louise Jones. I am especially grateful to my colleague Constance Malpas for extensive commentary.
**Picture:** I took the feature picture of St Ignatius of Loyola at Xavier University. Xavier is a member of OhioLINK, which has been a pioneering library consortium.
**Note:** I made some cosmetic amendments including addition of feature picture and headings on 20 March 2021\.
### The powers of library consortia 3: scaling influence and capacity for impact and efficiency
URL: https://www.lorcandempsey.net/the-powers-of-library-consortia-3-scaling-influence-and-capacity-for-impact-and-efficiency/
Last updated: 2024-12-22T21:21:22.000Z
1. [The powers of library consortia 1: How consortia scale capacity, learning, innovation and influence](https://www.lorcandempsey.net/the-powers-of-library-consortia-1-how-consortia-scale-capacity-learning-innovation-and-influence/)
2. [The powers of library consortia 2: Soft power and purposeful mobilization: scaling learning and innovation](https://www.lorcandempsey.net/the-powers-of-library-consortia-2-soft-power-and-purposeful-mobilization-scaling-learning-and-innovation/)
3. **The powers of library consortia 3: Scaling influence and capacity**
4. [The powers of library consortia 4: Scoping, sourcing and scaling](https://www.lorcandempsey.net/the-powers-of-library-consortia-4-scoping-sourcing-and-scaling/)
They are now more important than ever as libraries seek to increase impact and efficiency by working together and as issues of value and values come to the fore in changing service, funding and political contexts.

## Scaling capacity
Libraries and related organizations group together to scale capacities such as infrastructure, expertise or services. Motivations are to achieve economies of scale (through shared systems infrastructure, for example), or to increase impact (through an aggregate discovery service, for example), or to concentrate expertise and resources (through negotiation services, or training provision, for example). Think of the following which occur in various combinations.
- There are many library and educational organizations whose primary purpose is to combine **purchasing power** and to negotiate and license on behalf of a group. Examples here would be CRKN in Canada, Jisc Collections in the UK or NERL in the US. This is a core competence of such groups and may be leveraged more broadly on occasion. For example, OhioLINK is working on textbook licensing with the Ohio Department of Education.
- It often makes sense to share **infrastructure** across groups of libraries. Think of the ILS in Orbis Cascade Alliance or PALNI, for example. Or the way HathiTrust or CRL concentrate the infrastructure required to manage digitized and print collections respectively. Or the national/regional bibliographic infrastructure organizations that provide union catalog, resource sharing and other services in many parts of the world (Bibsys in Norway, for example, or ABES, DBC, and IZUM in France, Denmark and Slovenia respectively). Or how the Digital Preservation Network – and its participant nodes – aims to create shared distributed preservation infrastructure in the US. Or how the California Digital Library or The Scholar’s Portal provide a range of infrastructure services to the University of California and Ontario academic libraries, respectively. The nature of infrastructure provision evolves as library services evolve. So, for example, various consortia are now looking at shared provision of research support services (research data management, institutional repository, scholarly publishing, and so on).
- We are seeing greater consolidation of **collections** or **data**. HathiTrust, just mentioned, is an interesting example, where a centralized, network-level resource is now seen to make sense for many reasons. We are beginning to see greater concentration of print collections also, as collective stores emerge (Recap or UKRR for example), and as individual libraries manage down their collections. CRL has long been active in this area. In response to this trend, some existing consortia have developed shared print programs (e.g. BTAA) while some new ones have also been formed to address the issue (e.g. West). In some cases we are beginning to see consortia move to more formal shared arrangements to jointly manage their ‘collective collections.’ Research data management also provides interesting group examples where universities are thinking about where best to manage data, and we see consortial (e.g. 4tu.datacentre in the Netherlands) and national responses (e.g. CARL Portage in Canada, ANDS in Australia, or DANS in the Netherlands). Of course, the journal literature has been consolidated for a while, and lends itself to provision by a small number of third party providers (publishers, aggregators). That said, some library organizations continue to locally load data where it aligns with a local mission of access or ownership. OhioLINK is an example.
- **Discovery** naturally moves to the network level. We are now familiar with large gravitational hubs which aggregate audiences for discovery – Google, Google Scholar, ResearchGate, and so on. Similarly, DPLA or WorldCat scale discovery to the network level in the library community. Discovery is also important at the consortial level, where an organization like OhioLINK or BTAA aggregates both discovery and fulfilment within their domain. And over the next few years we will see the further evolution of **discovery to delivery** networks which progressively streamline the logistics of moving library materials between shared and local nodes of the relevant collective collection, informed by richer decision support systems. Libraries Australia, Sabinet in South Africa, the Ivies Plus group, and JULAC provide additional examples. Of special interest here is the shift from discovery to **discoverability**. In an environment where discovery increasingly happens elsewhere (in Google, Google Scholar, Wikipedia, ResearchGate, and so on), libraries become more interested in effectively disclosing their resources to network services, to making them more discoverable. Services like DPLA and WorldCat.org play a role here, as do other aggregation services.
- **Expertise** is an important shared resource, and consortia are useful mechanisms for shared acquisition of scarce expertise, for sharing expertise across members, or for concentrating expertise around particular consortial activities.
- Consortia may provide various other services where it does not make sense for all members to individually and redundantly develop their own capacity – copyright clearance, accessibility assessment, and so on, depending on local circumstances and scale.
Of course, it is usual for many organizations, including some mentioned above, to work across multiple areas. The Scholars Portal is an especially interesting provider of multiple shared services (digital storage, inter library lending, negotiation/licensing, local loading of content, research data management, and others) to members of OCUL (Ontario Council of University Libraries). OCLC scales capacity in important ways for the library community. It has created networks which allow thousands of libraries to collaborate at scale to catalog materials, to share collections, and to make those collections more discoverable.
At a more broadly educational level, an organization like Internet 2 scales shared capacity to the national level, with an explicit mission of managing infrastructure so that individual researchers and institutions do not have to.
Scaling capacity is difficult. The coordination costs are high – between libraries and between groups and their providers. Personalities and politics are at play in any collaborative activity. For many organizations there is a learning curve as they build capacity. Once in place, it may be difficult to create economies of scale, to generate investment for infrastructure development, to sustain the service. And one can point to examples where services have not continued.
Where there is a sustained need, and where coordination costs go down, third party providers may step in to run the service. However, such transitions are also difficult. In fact, the sourcing question is a central one for groups. Should they build a service or contract with a third party to provide it? Some consortia have local development capacity and may consider building shared services themselves (see the Scholars’ Portal services provided by OCUL, for example). Others do not have this capacity but do have an active role in negotiating and contracting for services with third parties. Of course, each approach may be pursued side by side.
However achieved, scaling capacity is crucial. It does not make sense for individual libraries to locally develop all the capacity they need. That said, there is no consistent pattern: libraries are variably inserted in collaborative arrangements, and the number and quality of those arrangements are always being reviewed.
These issues make the discussion of sourcing and rightscaling central, and I return to this in the fourth blog entry in this series.
## Scaling influence
Many library groups have an advocacy or representative role.
Those that represent the professional interests of individual members (e.g. ALA, Lianza) typically exist at national or other jurisdictional levels, and often play a leading advocacy role in lobbying government organizations on behalf of library interests and those of their users. Given their individual membership model, we do not usually think of these groups as consortia. However, their interests do overlap with those collaborative organizations who represent the institutional interests of certain types of library (e.g. ARL, ULC, LIBER or RLUK). Again, these typically exist at national or other jurisdictional level and the public policy interest is central. These organizations certainly have consortial characteristics, pulling together library members, and their activities sometimes overlap with more service-oriented consortia.
A collaborative group may also exist to exert influence within a particular topic. SPARC is a notable example here, seeking to aggregate the influence of members around open access issues. COAR is another example, advocating on behalf of the repository community and open access.
Scaling influence may be especially important in an emerging area where service or policy norms are lacking or where existing norms may be challenged. This was important for HathiTrust in its early days, for example, as it explored what was possible in the copyright environment. The Open Text Network provides an interesting current example.
Of course, these organizations also engage in other activities – some provide shared infrastructure or negotiation services. The extent to which they scale capacity in this way, taking on operational services, is an interesting scoping question to which I return in the next post. Many have a strong role in mobilizing their networks around scaling learning and innovation. In fact, such mobilization is probably key to success for those organizations that persist.
The emphasis on scaling influence has become much stronger in recent years, as libraries focus on value and values, on positioning and taking positions, in a contested environment.
**Value and positioning**. Libraries are embedded in complex and evolving policy, service and funding environments, and are keen to ensure that their actual and potential contribution is recognized. This is especially the case where there is downward pressure on public funding, where there are many players in the network information environment who appear to offer substitute services, and where the practices of research, learning and creative work are diversifying. The role of the library itself is changing, as it engages more strongly and in different ways with the life of its community. This makes it important to clearly communicate the contribution of the library, and to develop strong stories which help refashion the expectations the community has of the library. It also makes it important to develop an evidence base that individual libraries can draw upon. The recent *From Awareness to Funding* work by PLA and OCLC is a good example here.
[From Awareness to FundingOCLC has partnered with the American Library Association (ALA) and its Public Library Association (PLA) division to investigate current perceptions and support among US voters and how they may have shifted since 2008.OCLCOCLC](https://www.oclc.org/research/publications/2018/oclcresearch-awareness-to-funding.html?ref=lorcandempsey.net)
**Values and taking positions**. Libraries are partners and advocates in the creative lives of their communities. They advocate for the interests of those communities, and this means taking a position when potentially conflicting interests are in play – in relation to copyright, for example, to scholarly communication, to net neutrality, to access to public information. They are advocates for the interests of researchers, learners and citizens as creators and consumers of information in a changing environment, for the interests of communities as they preserve their identity and experiences, for the interests of citizens as they access resources for personal development or civic engagement.
Where the value and values of libraries are contested it is critical that the library community scales its influence purposefully and effectively. This prompts an obvious question – is the library community too fragmented here as elsewhere? There are many groups keen to exert influence: when does one organization engage with an issue or leave it to others? How do organizations align their positions? Should there be a leading voice? Would efforts to influence policy be strengthened by groups acting in concert?
Libraries are interested in creating powerful stories about their role and in developing shared evidence and arguments in support of these. This is as they seek both to position the library within their local institutions and to influence public policy and funding agencies.
Library organizations who scale influence have a special responsibility when faced with political, funding and service uncertainty, and in a time of surveillance, algorithmic retrieval and polarized media. They need to be strong advocates for library value and values, and to be effective resources for individual libraries.
**Acknowledgements.** I am grateful to the following people for generous comments on earlier drafts: Gwen Evans, Mike Furlough, Kevin Guthrie, Susan Haigh, Brian Lavoie, Kirsten Leonard, Rick Lugg, John MacColl, Constance Malpas, Barbara Preece, Judy Ruttenberg, Katherine Skinner, John Wilkin, Nicola Wright. Of course, I alone am responsible for the use to which I have put their advice and they do not necessarily share any of the views expressed here! I presented some of this material at the JULAC 50th Anniversary Conference in Hong Kong, and I benefited from the views outlined in the formal responses of Peter Sidorko and Louise Jones.
**Picture:** I took the feature picture in the lobby of the The Hotel at Oberlin. The wall art is by the great Maya Lin, who grew up in southeast Ohio. Oberlin College is a member of OhioLINK, which has been a pioneering library consortium. One of the students in the background is reading a book with an OhioLINK wrapper on it.
**Note:** I made some cosmetic amendments including adding the feature picture and headings on 18 March 2021\.
### The powers of library consortia 2: soft power and purposeful mobilization: scaling learning and innovation
URL: https://www.lorcandempsey.net/the-powers-of-library-consortia-2-soft-power-and-purposeful-mobilization-scaling-learning-and-innovation/
Last updated: 2023-03-09T03:23:59.000Z
#
This is the second of 4 blog posts about library consortia. I will link to the others here as they appear:
1. [The powers of library consortia 1: How consortia scale capacity, learning, innovation and influence](https://www.lorcandempsey.net/the-powers-of-library-consortia-1-how-consortia-scale-capacity-learning-innovation-and-influence/)
2. ****The powers of library consortia 2: Soft power and purposeful mobilization: scaling learning and innovation**
3. [The powers of library consortia 3: Scaling influence and capacity](https://www.lorcandempsey.net/the-powers-of-library-consortia-3-scaling-influence-and-capacity-for-impact-and-efficiency/)
4. [The powers of library consortia 4: Scoping, sourcing and scaling](https://www.lorcandempsey.net/the-powers-of-library-consortia-4-scoping-sourcing-and-scaling/)
While one might first think of scaling capacity (e.g. shared infrastructure) or scaling influence (e.g. lobbying government on public policy issues affecting scholarly communication) in connection with library consortia, learning and innovation are increasingly central.

## Learning and innovation
Learning and innovation have become crucial for successful library activity. As the practices and expectations of library users – as creators and users of information in their research, learning and general lives – continue to change and as the information environment continues to diversify, it becomes increasingly important for libraries to be able to respond quickly. To do this effectively, the library needs to understand directions and develop responsive services. And this in turn depends on effectively scaling learning and innovation within and across libraries.
### Scaling learning
Professional development or continuing education is an important part of many groups’ activities. The group may provide some economies of provision or shared expertise, and for this reason could have been included in the later scaling capacity section.
However, I am thinking here of learning in a broader sense. John Hagel talks about the importance of learning and the exchange of tacit knowledge in environments of uncertainty like ours:
> **In rapidly changing environments, it’s important to realize that tacit knowledge trumps explicit knowledge**. The latter can be articulated and written down and it usually takes time before it can be expressed clearly and coherently to others. Tacit knowledge is within our heads and we have a hard time even expressing it to ourselves, much less to anyone else. **Because tacit knowledge is generally newer knowledge, emerging from new experiences that we’ve encountered, it’s often the most valuable knowledge, providing us with insight into how to act in a rapidly evolving environment.**
>
> **Tacit knowledge becomes accessible through shared practice**
>
> **Because it’s so hard to express, tacit knowledge is not easily accessible.** **The best way to access it is to work together and to observe the practices that emerge from this tacit knowledge.** By working together, we also develop deeper, trust-based relationships that create a safer environment for us to explore new insights with others in our group that we have a hard time expressing to ourselves. \[[Scaling Learning in an Exponential World. Edge Perspectives by John Hagel](http://edgeperspectives.typepad.com/edge%5Fperspectives/2016/10/scaling-learning-in-an-exponential-world.html?ref=lorcandempsey.net).\]
The importance of learning through shared practices highlights the importance of people networks. Those networks in turn foster trust and ongoing serendipitous interactions. While there may be some concern about groupthink, trust also encourages an environment of frank discussion and challenge.
This provides the context for my thinking about two related aspects of library groups.
First, there are those groups which have an explicit and central role in facilitating professional networks, communities of practice, leadership development and peer learning. This may be the primary focus of some groups. Think, for example, in their different ways, of CNI, the OCLC Research Library Partnership (RLP), DLF, or the DPC (in the UK). Or it may be one element of a group’s activity. LIBER, for example, notes on its website: “Moreover, we contribute towards the development of innovative library leaders through our many conferences, workshops and seminars.” Think of the ALA divisions, LLAMA, ACRL or LITA, for example, where professional development is a driver of participation. One of the stated purposes of ARL is “fostering the exchange of ideas and expertise.” And it now has an explicitly programmatic approach to scaling learning through the ARL Academy, which aims to give attention to communities of practice, leadership development and workforce transformation. RLUK’s initiatives around unique and distinctive collections is a further example of a programmatic approach. JULAC, the consortium of university libraries in Hong Kong, also has a programmatic approach to creating learning opportunities across the libraries.
This learning role is also an important and explicit part of more functionally specific groups, Duraspace, the Digital Preservation Coalition or the Library Publishing Coalition, for example, or the Data Curation Network, which was explicitly created to scale expertise across the members. The Library Publishing Coalition notes that it “fosters collaboration, knowledge-sharing, and the development of common practices for library publishers.”
The second way in which scaling learning is important for groups relates to what I have called the ‘soft power’ of groups. I spoke to a library director a couple of years ago who was trying to join a larger regional consortium. Scaling capacity was certainly an important driver, around digital infrastructure, shared systems and negotiation. However, scaling learning was an equally strong incentive. She wanted her colleagues to mix with their peers in a broader group, to have a community within which to understand shared print, research data management, the different strands of open access, and other emerging service areas. Having such a peer group also gave access to “evidence and arguments” which could be used in discussions with administration and faculty in her own institution. The group would make her library smarter in terms of direction and local advocacy. In this way, the group scales learning across the members, and engagement in shared practices potentially accelerates local developments. Groups allow library staff to network with each other, to discuss direction, to come to shared decisions, to ‘pool uncertainty’ (and to reduce uncertainty as shared perspectives shed light on problems), and to build confidence in judgements. Staff can work with peers from other institutions, or mix with people with different experience and perspectives. Managing committees and working groups provides leadership and other development opportunities. In this way, a group may be an important factor in individual advancement or succession planning as participation becomes a platform for personal development as opportunities arise within the consortium.
Librarians come together around shared practices. The value of this soft power should not be underestimated. This is a central reason for the persistence of many groups.
### Scaling innovation
When we think of innovation, we tend to think of novel or interesting new approaches. These may arise in multiple contexts: in libraries, from vendors, and so on.
However, for an innovation to have impact beyond its original context it must be adopted by a wider group. At the same time, an institution will want to adopt appropriate innovation from elsewhere. Much innovation needs to become systemic to have an impact or to become economical. Innovation is especially important, again, in an environment where research and learning behaviors are changing and in turn changing the demands placed on libraries. Innovations may be around workflow, use of spaces, services, technology, and so on.
The University Innovation Alliance is an interesting experiment in relation to what I mean by scaling innovation. A group of public research universities dedicated to increasing access and student success, they are looking at techniques for diffusing the innovation of individual institutions across the group to see what works on a larger scale. The goal is to leverage individual institutional successes, while reducing redundant experimentation within the group. It is an example of a consortium explicitly focused on scaling innovation: they will “innovate, scale and diffuse.” Their first focus is learning analytics, looking at how developments at pioneer institutions might be adapted by others.
The UIA has a three-stage scaling model:
1. Identifying new solutions.
2. Scaling proven innovations.
3. Communication and diffusion.
We have yet to see what impact the UIA has, but the motivation and the approach are intriguing.
Scaling innovation is an important part of library groups, although there is not a library group with the very specific focus of the UIA. The Urban Libraries Council, for example, holds an annual competition to demonstrate innovation in several categories. A part of the purpose is to promote innovation by example across the membership. The Lyrasis Catalyst Fund provides another example, which supports projects with potential community wide impact. SCELC has a competitive Project Initiatives Fund to advance its strategic initiatives.
Creating a network is central to each of the examples above – a network in which new approaches can be socialized and embedded. This is an important aspect of library (and related) consortial activity. This may be in specialist groups like the Open Text Network or Data Curation Network. Or it may be more general – Educopia or Duraspace, for example, have a mission to develop networks which support diffusion and adoption of innovations. Likewise, CNI, the OCLC Research Library Partnership or DLF have an important goal to help socialize and embed innovation. This is certainly also the case with broader groups: Jisc in the UK comes to mind which has a very specific goal of helping to identify, incubate and diffuse innovation.
Again, the soft power of consortia is important here: ‘network making’ helps diffuse innovation, moving it into practice. However, there is also scope for more purposeful work to scale innovation across institutions, which is what makes the example of the UIA interesting.
## Conclusion
Scaling learning and innovation is actually a central part of library groups and consortia. Often this is a by-product of the “soft power” of such groups, bringing people together around shared practices and problems, mobilizing the trust networks they have created. In this way learning and innovation are emergent – building on the sharing of knowledge and experience in ongoing organizational relationships. From the point of view of consortium staff this is a critically important and valuable benefit, even if it is not always called out explicitly as a service. It would make sense to make it more explicit.
We are also seeing more purposeful approaches, which recognize the importance of learning and innovation – and their intimate connection – in an environment of uncertainty and change. As libraries work to be more active partners and advocates for their communities, they recognize the need to be more responsive and adaptive. This makes it vital to have good mechanisms for scaling learning and innovation within and across libraries, and through the collaboration networks which consortia create.
****Acknowledgements.** I am grateful to the following people for generous comments on earlier drafts: Gwen Evans, Mike Furlough, Kevin Guthrie, Susan Haigh, Brian Lavoie, Kirsten Leonard, Rick Lugg, John MacColl, Constance Malpas, Barbara Preece, Judy Ruttenberg, Katherine Skinner, John Wilkin, Nicola Wright. Of course, I alone am responsible for the use to which I have put their advice and they do not necessarily share any of the views expressed here! I presented some of this material at the JULAC 50th Anniversary Conference in Hong Kong, and I benefited from the views outlined in the formal responses of Peter Sidorko and Louise Jones.
**Picture:** I took the feature picture of the Thompson Library at Ohio State University. OSU is a member of OhioLINK, a pioneering library consortium.
**Note:** I made some cosmetic updates including adding picture and headings on 20 March 2021\.
### The powers of library consortia 1: how consortia scale capacity, learning, innovation and influence
URL: https://www.lorcandempsey.net/the-powers-of-library-consortia-1-how-consortia-scale-capacity-learning-innovation-and-influence/
Last updated: 2026-08-29T17:37:03.000Z
This is the first of 4 blog posts about library consortia. I will link to the others here as they appear:
1. **The powers of library consortia 1: How consortia scale capacity, learning, innovation and influence**
2. [The powers of library consortia 2: Soft power and purposeful mobilization: scaling learning and innovation](https://www.lorcandempsey.net/the-powers-of-library-consortia-2-soft-power-and-purposeful-mobilization-scaling-learning-and-innovation/)
3. [The powers of library consortia 3: Scaling influence and capacity](https://www.lorcandempsey.net/the-powers-of-library-consortia-3-scaling-influence-and-capacity-for-impact-and-efficiency/)
4. [The powers of library consortia 4: Scoping, sourcing and scaling](https://www.lorcandempsey.net/the-powers-of-library-consortia-4-scoping-sourcing-and-scaling/)
## Scaling capacity, learning, innovation and influence
Libraries and related organizations group together in a variety of ways to get their work done. They consort where there are scale advantages: to lobby, for example, to negotiate and license, to reduce costs, or to build shared infrastructure. The ‘soft power’ of such groups is also important – the relationship building, the trust, the sharing of learning and innovation that comes from working together over time is an important reason that such groups persist.
In each case, libraries recognize that collective action or building shared capacity delivers scale benefits.

In this context, it is interesting to think about collaboration for scale in four areas: influence, learning, innovation and capacity. Some collaborative organizations span several of these areas, some are more specialized. In all these areas consortial or collective activity potentially creates scale advantages.
Organizations which primarily **scale influence** have an advocacy or representative role, and are often at national (e.g. ALA, RLUK) or international (e.g. LIBER, IFLA) levels, or come together around particular issues (e.g. SPARC around open access). A regional dimension is often very important for organizations which **scale capacity** (e.g. OhioLINK or OCUL), either for logistical reasons or because there is public support (at the level of a state or province, or at national level). Other organizations may pull together peer groups (e.g. PALNI or Ivies Plus) or particular functional or interest groups (e.g. DPN or Duraspace). And in an environment of evolving user expectations and behaviors, there is a growing recognition that libraries need to think purposefully about shared approaches to **learning** and **innovation** which better prepare them to respond to new needs. Some groups are focused on learning and innovation (e.g. CNI or the Digital Preservation Coalition), while it is also increasingly an important part of all groups.
Of course, groups come into existence and persist for different reasons and in different ways. But they often have overlapping roles and individual libraries typically support several. The organizational context of collaborative or consortial activity is surprisingly little explored in the library literature, in terms of incentives, organizational patterns, successful models, etc. There is certainly a descriptive body of work about classic library consortia (such consortia are often organized around some combination of licensing, resource sharing and training, or sometimes manage a shared library system), but the more general perspective is missing. **It is this gap which prompts this series of blog entries.**
In four blog entries I am going to consider library consortia or collaborative organizations using this framework. I have two purposes:
1. The first is to ask some questions about the shape and dynamics of consortia, in order to contribute to thinking about an important and underexamined topic. Clearly, this can only be preliminary and suggestive in this form; I offer some observations, rather than a full grounded analysis. I use some simple heuristic frameworks to structure my discussion (scaling influence/learning/innovation/capacity and scoping/sourcing/rightscaling), while acknowledging that a fuller treatment might generate better approaches. I would note in particular that there is a large literature on organizations across several disciplines which would provide a valuable context for the examination of collaborative library work.
2. The second is to underline how scaling learning and innovation have become important shared concerns in complex times, and deserve increased investment of both attention and resources.
In this introductory post I put consortial activity in the context of other approaches to scaling, and I touch on some general issues that will be discussed in more detail in later posts. In particular I am interested in scoping, sourcing and (right)scaling, three ways in which choices about collaborative activity need to be made.
## Patterns of scaling
Of course, collaborative activity is only one way in which libraries acquire shared services or connect to broader resources, or in other words scale their capabilities. Reductively, one can point to three patterns which deliver shared library services at a level above the institution.
1. Public – Shared infrastructure or services is provided through a public agency or with public support, often involving national (or regional) coordination. Think variously of services historically provided by Jisc in the UK, or the regional bibliographic networks in Germany, or Libraries Australia, or Bibsys in Norway. This is a common pattern outside the US, although within the US there is often some support through state-supported agencies (e.g. OhioLINK).
2. Collaborative – A group of libraries works together to get something done. Formality, size and scope vary enormously. This collaboration often takes the form of a consortium, and libraries support many consortia.
3. Third party – A shared service can be bought from a provider (publisher, system vendor, aggregator, etc). Consultancy is another example of a third party service, as a way of scaling learning by tapping into broader expertise or experience. Of course, this is a major way in which libraries scale their services – for example this is largely how they acquire the journal literature, automation, and other central services.
These three patterns may be layered or blurred in various ways. A library may collaboratively source a service through a consortium, but the consortium may then contract with a third party to actually provide it (a shared library management system for example, or a digital preservation service). In fact, one important function of collaborative or public provision is to efficiently or cost-effectively procure shared services from third parties. Publicly supported groups may have a strong collaborative element, or have contributions from members; OhioLINK is an example here. Jisc in the UK describes itself as a ‘membership’ organization – it is moving from its centrally publicly funded model to one in which universities and others subscribe to benefit from services.
So, while library collaboration (typically through consortia) is my major focus here, intersections with public and third party provision are frequent.
## Contrasts in consortial activity
The variety of library collaborations is great, and this translates into great variety of consortial organizations and directions. These also change over time. By way of example, I note three important contrasts about consortial activity here.
- **Single-purpose or multi-purpose.** Some groups may specialize around one function or direction. SPARC for example is focused on an open agenda. HathiTrust is focused on preservation of and access to the digitized collections of its members, in support – more broadly – of the preservation of the scholarly and cultural record. However, other groups may do many things. Take PALNI for example. PALNI is a consortium of private academic libraries in Indiana, and provides a range of services around a deep collaboration focus – sharing infrastructure, expertise, and other capabilities of member libraries. PALNI will adapt to support the changing priorities of its members, and so, for example, it recently developed programmatic support for digital scholarship. In this way, there may be an interesting balance between economies of scope (where, for example, it makes sense for members to centralise a variety of different functions with a consortium, including shared infrastructure and attention to evolving service areas) and economies of scale (where the costs of providing a service, including infrastructure, marketing, R&D, etc, are spread across many participants, as in, for example, HathiTrust). Of course, many third-party providers exploit economies of scale to deliver services in focused areas (e.g. cloud system providers, aggregators, publishers). A related issue here is the relative homogeneity of members. The intersection of member interests bounds the scope of the consortium. Where a consortium comprises members of different types (large, small; academic, public) then the intersection of interests may need be quite tightly scoped (resource sharing, for example) to achieve desired advantages and the consortium may be focused on those. Where consortium members form more of a peer group, then the intersection of interests is greater, and the consortium may move shared concerns forward across a broader range.
- **Agent or provider.** There is no one model of collaboration. Libraries may work together informally to get things done. They may add progressively more structure: convene member working groups, hire staff, hire an executive director, constitute the collaboration as an independent entity. Of course, once the collaboration is structured as an independent entity, it has to sustain itself and issues of alignment and governance come to the fore. Over time, this may become more important as original personalities or organizational contexts may change, new requirements may emerge, activities may grow or become more diverse. As the organization grows, it may outgrow the ability or interest of members to entirely support its activities through dues and it may seek to diversify revenue streams by offering additional services, applying for grants, and so on. This means that the balance between the group as a direct agent of the member library interest, a collective resource to be directed, as it were, and the group as a provider to the libraries, independently developing potential products, can change. As a provider, the consortium needs to supply support and training, upgrade the service in line with user expectations, and generally offer the support that libraries might expect from third party providers. This means in turn that services are potentially compared with those of third party providers – think of, for example, of a shared institutional repository provided by the consortium, and the comparison to, say, bepress. This service relationship can change the dynamic between members and consortium. Size is an important factor here also, given that as an organization grows it may be difficult for all members to directly participate in decision making. One important dynamic is where the membership is no longer a mutually ‘known community’ with regular social interaction. Other factors are diversification of funding, or different types of library served. As size or complexity grows in this way, so likely does the focus on representative and decision-making structures in governance, and on the role, accountability and authority of the executive director. Typically, an executive director will be accountable to the membership for decisions through a representative Board. The balance between agent and provider is an important contributor to the sense of ownership and belonging that members will have towards a consortium, as is the participation in governance mechanisms.
- **Collective action and rightscaling.** Consortia are effectively a response to a collective action question (is it more efficient to solve some questions in a group, or to turn to a group to acquire capabilities you cannot generate internally?), which in turn raises a right-scaling question (at what level is action desirable, or what is the optimum size of a group?). For many issues, a regional scale is important, where personal networks within that known community are an important part of the value a consortium delivers. For others, especially in a network environment, it makes sense to scale to much broader groups. For example, OCLC has built platforms on which thousands of libraries collaborate at scale around cataloging, resource sharing and discoverability. Jisc provides infrastructure solutions which scale to the national level. Scale also becomes an important part of scoping decisions. There is one network-level HathiTrust, for example, which makes more sense than multiple regional ones. This again underlines the diversity of consortial activity, from locally-constituted groups to large providers of community infrastructure.
In each of these cases, there is a spectrum of choices or evolving stages. One of the more interesting things about this space is how groups can evolve: consortia may change over time as circumstances and environment change.
So, for example think of a group that is set up to serve a single purpose – over time, this purpose may shift, or other activities may be added. In some cases, a consortium can evolve into a general collaborative apparatus that members reflexively turn to when new or shared needs arise. In this way they may reduce the cost of building a new service, partnership or network from scratch. However, it also means that the consortium needs to be clear about what the appropriate response is – developing a service, contracting for a service, ruling it out of scope, and so on. Consortia may also want to attract new members, and evolve services in that context. The evolution of Lyrasis in recent years is an interesting example of diversification.
Similarly, the transition from agent to provider may be prompted by various steps. For example a university hosted consortium is a common model. However, a decision may be made to independently incorporate to get more flexibility – to avoid university procurement or HR processes for example. If a group develops shared infrastructure, there may be a decision to diversify revenue or to grow membership to support greater capital investment for R&D, platform development, and so on.
Finally, it may make sense to carry out some activity at a broader level. The ‘O’ in OCLC originally stood for Ohio: it was an organization set up to provide shared services to Ohio colleges. It has grown to serve thousands of libraries around the world, as the services it provides benefit from network effects. HathiTrust was originally set up at a BTAA level. It quickly grew to operate at a national scale, and is also looking at an international membership model. In other cases, an organization may deliberately restrict growth; trusted interaction with a known local ‘known community’ may be an important attribute which the group wishes to maintain.
These three cases are examples respectively of what I later discuss under scoping (what is the appropriate range of activity?), sourcing (how should the activity be procured?) and rightscaling (at what level should the activity be carried out?).
## Conclusion
For convenience in these posts, I use the terms ‘consortia’ or ‘collaborative groups’ to refer to organizations which support some form of general collective activity, and which are supported by libraries, acknowledging that this may not always be the term used in a specific context.
Given the scale of the US – in terms of both the size of the sector and geographic extent – and the comparative absence of the overarching national public provision which is present in many other countries, it offers many examples of collaborative activity at different levels. While I emphasize the US in my examples, I also include some developments from other countries. In general, where I provide examples, I do not comment on how effective or efficient a particular approach is.
**Acknowledgements.** I am grateful to the following people for generous comments on earlier drafts: Gwen Evans, Mike Furlough, Kevin Guthrie, Susan Haigh, Brian Lavoie, Kirsten Leonard, Rick Lugg, John MacColl, Constance Malpas, Barbara Preece, Judy Ruttenberg, Katherine Skinner, John Wilkin, Nicola Wright. Of course, I alone am responsible for the use to which I have put their advice and they do not necessarily share any of the views expressed here! I presented some of this material at the JULAC 50th Anniversary Conference in Hong Kong, and I benefited from the views outlined in the formal responses of Peter Sidorko and Louise Jones.
**Picture:** I took the feature picture in the Kelvin Library at Case Western Reserve University. CWRU is a member of OhioLINK, a pioneer among library consortia.
**Note:** I made some cosmetic updates on 19 March 2021, including adding a feature picture and headings.
### One handed writing - the blog
URL: https://www.lorcandempsey.net/one-handed-writing-the-blog/
Last updated: 2022-11-08T15:24:32.000Z
Recently [@mishdalton](https://twitter.com/mishdalton?ref=lorcandempsey.net) pointed me at [an article](https://www.nytimes.com/2017/08/25/opinion/tips-for-aspiring-op-ed-writers.html?mcubz=1&ref=lorcandempsey.net) about writing op-eds for the New York Times. I was immediately struck by how applicable much of what was said was to blog writing.
The advice is pragmatic and not surprising: get to the point quickly, have an opinion, be direct and avoid padding, anticipate and counter potential objections to your argument, avoid clichés, and so on.
Older readers may remember when I blogged more frequently. Heck, there is even a book \[[ALA](https://www.alastore.ala.org/detail.aspx?ID=11196&ref=lorcandempsey.net)\]\[[free PDF](https://www.oclc.org/content/dam/research/publications/books/dempsey-network-reshapes-library.pdf?ref=lorcandempsey.net)\].
Clearly, times have changed since the peak of personal blogging. This is certainly the case in the library community. Personal blogging now sits in a diverse ecosystem of commentary, news and opinion.
I liked this paragraph in the NYT piece:
> The purpose of an op-ed is to offer an opinion. It is not a news analysis or a weighing up of alternative views. It requires a clear thesis, backed by rigorously marshaled evidence, in the service of a persuasive argument. Harry Truman once quipped that he wished he could hire only one-handed economists — just to get away from their “on the one hand, on the other” advice. Op-ed pages are for one-handed writers.
I think this is often true of good blog entries also.
Because I don’t blog all that often any more, I find that when I sit down to do an entry I have too much stuff to say. I end up writing a short article rather than a blog entry. Indeed, I have a couple of pieces that are lying around and have grown to several thousand words. One is on the evolving research support environment, and how the larger publishers are developing workflow services (“workflow is the new content”). One is on how scaling learning and innovation is an important part of the “soft power” of consortial activity.
Now these longer pieces may have an argument. For example, I think that library focus on the institutional repository may have delayed recognition of the broader changes in workflow support and publisher direction. However, the argument may be submerged in the two-handed comprehensiveness of the longer piece. Rather than being underlined in the one-handed directness of a blog entry on a single topic.
Anyway, this is all by way of saying that I plan to blog a little more frequently. I miss the direct connection it gives you with people. I liked it when people I had not met before would engage me at events about something I had recently written. Now I just have to make some time …
p.s. Incidentally, I liked how the piece called out cliches. People who say that they want to think outside the box, don’t.
**Picture:** I took the feature image outside the American Visionary Art Museum in Baltimore.
**Note:** Cosmetic updates on 4 April 2021 to improve spacing and add picture.
### Libraries and the curse of knowledge
URL: https://www.lorcandempsey.net/libraries-and-the-curse-of-knowledge/
Last updated: 2023-05-02T03:32:17.000Z
## The curse of knowledge
In his recent book on writing (*[The Sense of Style](https://www.worldcat.org/oclc/870919633?ref=lorcandempsey.net)*), Steven Pinker suggests that the economic concept of the curse of knowledge is the main cause of bad writing.
He explains it this way:
> Call it the Curse of Knowledge: a difficulty in imagining what it is like for someone else not to know something that you know. \[…\] It simply doesn’t occur to the writer that her readers don’t know what she knows – that they haven’t mastered the patois of her guild, can’t divine the missing steps that seem too obvious to mention, have no way to visualize a scene that to her is as clear as day. And so she doesn’t bother to explain the jargon, or spell out the logic, or supply the necessary detail.
Here is [Wikipedia](https://www.wikiwand.com/en/Curse%5Fof%5Fknowledge?ref=lorcandempsey.net) on the curse of knowledge:
> The curse of knowledge is a cognitive bias that leads better-informed parties to find it extremely difficult to think about problems from the perspective of lesser-informed parties.
And [LifeHacker](https://www.lifehack.org/articles/communication/are-you-suffering-from-the-curse-knowledge.html?ref=lorcandempsey.net) amplifies:
> If we extrapolate these results to communication in general, it means that we think people understand what we’re saying a hell of a lot more often than they actually do—because we’re so used to knowing the things we know that we expect others to know it as well.
In summary it is very difficult to **unknow** something that you already know, and it can be difficult to imagine what it is like not to know it. This creates a potential communication gap. On the one side, the curse of knowledge may make it hard for somebody to understand why others simply do not get what they are talking about. On the other, an audience may miss the point entirely, because they do not share the context of the speaker. To communicate effectively we may have to step outside our own usual standpoint.
This phenomenon has well known practical consequences. For example, an expert or authority on a topic is not always the best person to explain it to a non-initiate audience. It also helps to explain the value of an editor, who can review a communication from a different standpoint than the author’s, recognizing, for example, where there needs to be further clarification of an issue.
Since reading about the curse of knowledge in Pinker’s book it has certainly prompted me to think about about my own communications behavior. Yes, I could often do more work to unpack what I am trying to say, or rely less on expressions which depend on some prior understanding or context. And I certainly know from followup conversation or questions at conferences that people can sometimes miss entirely what I thought was clear. (Yes, really.) I have become more alert to obvious preparation, learning more in advance about the composition of the audience for example.
Pinker has some general and straightforward advice for escaping the curse of knowledge. He recommends cutting out abstraction, watching for use of jargon, having materials checked by a third party, and so on.
## The curse of knowledge and libraries
More broadly, I have been struck by how widely applicable the concept appears to be in a library context, in big and small ways. Here are some examples ….
### Communicating as if for the first time
Libraries are now very aware of how they need to move beyond jargon in describing their services – in signage, in informational materials, or in user interfaces. The goal is to be clearly **understood** by those who **do not already understand** library structures or specialist terminology. To be clearly understood, one cannot presume that potential users already understand how the library works, or is structured, or what jargon is used to describe services.
One example here is discovery. In retrospect, the term OPAC was probably not very helpful? Or think how we expect users to understand the differences between catalog, articles, ejournals, databases, and so on.
### Stories and concrete ideas communicate direction and value
In their popular book on communicating ideas successfully, *[Made to stick](https://www.worldcat.org/oclc/68786839?ref=lorcandempsey.net)*, Chip and Dan Heath label the curse of knowledge the “villain of the story,” the principal impediment to “making ideas stick.”
They suggest that concrete language and telling stories counter the curse of knowledge and make ideas and statements “stickier.”
This seems very relevant to communication between the library and its constituency.
One important recent example here is the discussion about library value. When talking about library value there is a danger of talking about value in terms that make sense to librarians, or which depends on prior understanding of library activities, rather than talking about value in terms of contribution to the goals of the organization which the library serves.
I was interested to see our new neighbor at Ohio State, Damon Jaggars, put it this way in a [recent post](https://library.osu.edu/blogs/osulstaff/2016/02/29/from-the-director-february-29-2016-drinking-from-the-fire-hose/?ref=lorcandempsey.net):
> … the Libraries must position itself as an active, engaged participant in solving university-level problems *(Looking outside ourselves).*
The library has to look outside itself (avoiding the curse of knowledge) and position itself in terms that the university values. And he explicitly talks about communication:
> the Libraries must become more sophisticated in how it identifies and presents its stories of success and impact to external stakeholders (*Success enables success*).
The Columbus Metropolitan Library [strategic plan](https://www.columbuslibrary.org/sites/default/files/uploads/docs/Strategic%5FPlan%5F2016.pdf?ref=lorcandempsey.net) for 2016 is also instructive. Look at the ‘strategies and outcomes’ page. Their focus is on “young minds”, “my library”, and “life skills”. They express their direction in terms of community goals.
### All library users are not experts
In her book, *[Reflective teaching, effective learning : instructional literacy for library educators](https://www.worldcat.org/title/reflective-teaching-effective-learning-instructional-literacy-for-library-educators/oclc/609871178?ref=lorcandempsey.net)*, Char Booth discusses the curse of knowledge in relation to library instruction, and makes some interesting general points.
> Libraries are created for nerds by meta-nerds, so it is not surprising that library educators tend to suffer from an acute case of the “Curse of Knowledge” as we go about instruction. \[…\] The problem with libraries is that the people who use them are usually not experts, yet we tend to orient ourselves towards expert users. \[…\] I would estimate that, in any given library, four out of five people are on the path of least resistance, yet our learning objects, information products, and buildings are often directed towards the one self-directed learner – the one who most closely resemble us. \[4\]
She talks about challenging this issue in instruction by adopting a purposefully learner-focused stance. She describes the WIIFM (what’s in it for me) approach in relation to students: “Effective educators appeal to the self-interest of their learners by identifying and explicitly communicating this benefit in practical terms during instruction.” \[13\]
### The value of diversity
A diversity of opinion and background challenges the curse of knowledge. It makes us more aware of our own particular standpoint and can make us step outside it to be more clearly understood. In this way, diversity helps to generate non-routine or new approaches, avoiding group think (the curse of knowledge at group level?).
This is one potential advantage of the trend towards recruiting outside the MLS, looking for different backgrounds in education, community knowledge, technology, legal, disciplinary knowledge, data management, languages, and so on.
However, it also highlights the centrality of diversity to library services, values and identity. The library is a community service, whose value depends on real connections to the community it serves – whether that community is a college or a neighborhood. Users, and, importantly, potential users, of the library should feel understood and recognized by library people and the service they provide. This in turn means that the library needs to work to understand the experiences and expectations of their communities. This can be a challenge, and is one reason why diversity of library people is so important.
This is a much bigger topic than this blog post is addressing. However, as noted above, diversity within the library challenges the curse of knowledge. And the diversity of library communities demands that the curse of knowledge be challenged.
In this context, I liked this [comment](https://www.inthelibrarywiththeleadpipe.org/2015/why-diversity-matters-a-roundtable-discussion-on-racial-and-ethnic-diversity-in-librarianship/?ref=lorcandempsey.net) by Isabel Gonzalez-Smith “Diversity matters because we all play a part in the messages we disseminate, regardless of how we identify.” She goes on to ask: “What is the message that our collections, library staff representation, research, or programming gives to the communities we serve?”
Deliberately raising awareness here is important. For this reason, it is sensible to see dedicated recommendations about recruitment, education and retention called out in the recent Final Report of the ALA Task Force on Equity, Diversity, and Inclusion. \[[pdf](https://connect.ala.org/files/TFEDIFinalReport%202016-06-06.pdf?ref=lorcandempsey.net)\]
Finally, libraries are also working hard to challenge the curse of knowledge among library users, who may have routine or outdated views of the library. I was interested in [the connection made](https://pdxscholar.library.pdx.edu/cgi/viewcontent.cgi?article=1164&context=ulib%5Ffac&ref=lorcandempsey.net) by Pho and Masland between stereotypes and diversity.
> Changing user perceptions about librarians is a long process and isn’t solved with any quick answers. But having a diverse library workforce helps create an environment that is potentially more comfortable for a diverse community of patrons. The workforce shapes the leadership of the library, helps build a culture of inclusion, and educates our students on library research.
### The library in the life of the user
Recently, I have been characterizing a major shift in libraries as a shift from thinking about the user in the life of the library to thinking about the library in the life of the user.
The former model involves thinking in terms of **our** collections, **our** systems, **our** buildings. The latter involves thinking more clearly about the communities we serve, and their changing needs. About how we get into the flow of users’ research and learning. It also means communicating value in terms which are readily understandable in the context of the problems our users and host institutions want to solve. It means solving university or community problems.
Overcoming habitual ways of thinking, professional jargon, and other elements of the curse of knowledge are an important part of this.
**Note:** updated, 6/19/2016
**Picture:** I took the feature picture in the City Hall at Buffalo. Marble carving on the wall. I am reminded of the salmon of knowledge.
**Note:** This entry has been cosmetically amended on 27 March 2021 to include feature picture and headings, and to adjust spacing.
### The facilitated collection
URL: https://www.lorcandempsey.net/towards-the-facilitated-collection/
Last updated: 2022-11-05T05:30:47.000Z
Collections have been central to library identity – we have discussed how library collections are changing in a network environment elsewhere ([Collection Directions: The Evolution of Library Collections and Collecting ](https://www.oclc.org/content/dam/research/publications/library/2014/oclcresearch-collection-directions-preprint-2014.pdf?ref=lorcandempsey.net)– PDF). Support for the discovery, curation and creation of resources in research and learning practices continues to evolve. In this blog entry I discuss one element of these changes, the emergence of what I call the **facilitated collection**, a coordinated mix of local, external and collaborative services assembled around user needs
## Collections and a print logic
Library collections were strongly shaped by a **print logic**. This required the distribution of print copies to multiple local destinations. In this way, materials could be closer to the user, to allow immediate access. This had two consequences. First, collections were assembled on a ‘just in case’ basis. And, second, the size of the collection was strongly associated with the goodness of the collection. The larger the local collection, the more potential local requirements could be met. The library collection was an **owned** collection. Of course, the library collection is no longer entirely owned (think of the importance of licensed collections, for example) but this was an important shaping influence on our collections and still influences our thinking about them. And, certainly, the size of a locally owned collection is still important in popular perceptions of ‘goodness’. Just look at library job adverts or university promotional materials for potential students where it is common to mention collection size.
## The facilitated collection is organized according to a network logic
The network environment is very different in several important ways. These are well-known, but it is useful to list some.
1. The need for local physical distribution is much diminished as materials are available on the network. The print model was one of scarcity, requiring distribution to local nodes. The network model is one of abundance, encouraging aggregation at [central hubs](https://www.google.com/search?q=gravitational+hubs+lorcan&ref=lorcandempsey.net). The network is rich with informational opportunities – think of reference (Wikipedia), education (Khan Academy), discovery (Google Scholar, Amazon, Goodreads), research networking and social discovery (ResearchGate), software management (Github), data storage and manipulation (OpenRefine, FigShare), and so on.
2. Discovery has been peeled away from the local collection, and a variety of network-level discovery venues exist (Google, Google Scholar, ResearchGate, and so on). [Discovery often happens elsewhere](https://www.google.com/search?q=discovery+happens+elsewhere+lorcan&oq=discovery+happens+elsewhere+lorcan&ref=lorcandempsey.net), often going far beyond the collection.
3. Creation activity happens in a digital environment, with a growth of interest in the process as well as the products of scholarship and learning. Support for digital scholarship and research data management is emerging as services around creation join those around discovery or consumption. We see a blurring between content, workflow and identity (think about researcher profiles and research networking sites). There is a growing interest in sharing research and learning outputs from the institution with external users – research data, for example. Together, these are becoming an important focus for academic libraries.
[](https://storage.ghost.io/c/77/c7/77c7bb74-1d53-4c6c-a1fc-8e2ccb21b6d2/content/images/wordpress/2016/01/collectionsspectrum.png?ref=lorcandempsey.net)
Collections spectrum
The emergence of the **facilitated collection** is one element of this changing picture. The facilitated collection is organized according to a **network logic**, where a coordinated mix of local, external and collaborative services are assembled around user needs. This aims to meet research and learning needs in the best ways available, and not just by assembling material locally. This is actually a significant shift in how the library thinks about what it does.
Here are some central strands of the **facilitated collection**.
### 1\. The external collection
Libraries now provide access to many network resources they do not own or license. These include guided access to Google Scholar (there is an incentive to provide proxied access to this so that links to licensed resources work in a well-seamed way), inclusion of ‘free’ ebook resources in the catalog (e.g. HathiTrust collections), or pointing to various resources with the very popular LibGuides or other resource guides. Indeed, resource guides are an interesting signal of the facilitated collection as they are organized around user interests rather than around local collections. They may point to local collections, but typically also to externally available resources. The library discovery layer provides another example, where libraries may provide discovery access to resources which they do not hold.
### 2\. The move to licensed and just-in-time
A large part of academic library collections is now licensed. First abstracting and indexing services, then e-journals, then ebooks. This has moved the library away from a local ownership to a licensing model, with known questions about scholarly communication policy. For my purposes here, though, this means that the collection is more elastic as titles are added or dropped, as needs, budgets or priorities change. More recently, we have seen the emergence of DDA, implemented in various ways. I include it here, because again, it represents a move away from the just in case, owned collection, based on librarian judgement, towards a model which is built around patron behaviors. The library is facilitating access to required materials, rather than always anticipating what those requirements are.
### 3\. Shared - or collective - collections
However large, a purely local collection seems increasingly partial when placed in the context of the universe of potentially interesting resources. There is a growing trend to place local collections in a broader network context. While discussing the future of libraries, John Wilkin \[[pdf](https://hdl.handle.net/2142/79053?ref=lorcandempsey.net)\] has distinguished between what is best done locally (the management of space is the obvious example here) and what is best done at the network level. Interestingly, he asserts that the “best example of an activity that can be done most appropriately in a networked context is curation.” And we can indeed see how several manifestations of such collective collections have emerged successively in recent years. Here are some examples.
1. The ‘borrowed’ collection. Libraries have long organized in resource sharing networks, through OCLC, or through various regional or national infrastructures. Often, these are associated with union catalogs which describe the ‘collective collection’ available for borrowing. A library may belong to several networks. For example, our neighbor in Columbus, Ohio State University, will share resources in OhioLink, CIC, and OCLC. WorldCat has emerged an an important registry of the borrowable collective collection, spanning thousands of libraries. In this way, the library can facilitate access to a broader collection than is available locally.
2. The ‘shared print’ collection. The shared print collection is a natural evolution of resource sharing networks, as local collections are managed down and collaborative approaches to collection management emerge. And indeed, we see OhioLink and the CIC also turn their attention to such shared management. A large part – perhaps the majority? – of library collections will be under shared management within the next decade. In this way, curation of the collective print record is beginning to be advanced in a network context.
3. The ‘shared digital’ collection. As libraries digitize their collections, it has become clear that very few individual institutions are strong gravitational hubs in themselves. Materials digitized from local collections release greater value when aggregated within larger collections, [which can aggregate both supply and demand](https://www.dlib.org/dlib/april06/dempsey/04dempsey.html?ref=lorcandempsey.net). In different ways, for example, we have seen HathiTrust, DPLA and Trove, emerge to create these aggregations, aiming to more efficiently unite collections and their potential users. WorldCat also aggregates digital materials through the [digital collections gateway](https://www.oclc.org/digital-gateway.en.html?ref=lorcandempsey.net).
4. The [evolving scholarly record](https://www.oclc.org/research/publications/library/2014/oclcresearch-evolving-scholarly-record-2014-overview.html?ref=lorcandempsey.net). At one time, [the scholarly record](https://www.oclc.org/research/publications/library/2014/oclcresearch-evolving-scholarly-record-2014-overview.html?ref=lorcandempsey.net) comprised the final outputs of research – the journal articles and books. Now, increasingly, there is an interest in a variety of other outputs: methods, working papers, research data, preprints, and so on. In some regimes there is also growing government or funder interest in ensuring broad access to these materials through mandates. Institutions have developed mechanisms for managing and disclosing these, and they are collected into many services for management and/or discovery. These include disciplinary repositories (e.g. arXiv), third party services (e.g. FigShare), national infrastructure services (e.g. [Research Data Australia](https://researchdata.ands.org.au/?ref=lorcandempsey.net) or [Narcis](https://www.narcis.nl/?Language=en&ref=lorcandempsey.net) in the Netherlands), collaborative approaches like the nascent [Share](https://www.share-research.org/?ref=lorcandempsey.net) in the US, and so on. So, while research outputs will feature in a variety of venues, including of course publisher services, we are also seeing collaborative educational initiatives in this space.
In each of these cases we can see a shift of focus from locally owned or managed resources to a shared or collective arrangement at the network level. Developments are uneven, but a trend is apparent.
As always, it is instructive to watch job adverts at innovative institutions for signals of change. Consider this interesting [advert](https://chroniclevitae.com/jobs/0000898229-01?ref=lorcandempsey.net) for an AUL for ‘content and collections’ at the University of Minnesota. It talks about support for local creation (copyright, open scholarship and publishing) which hasn’t been my focus here. But it also makes involvement in shared collections a large part of the role. It makes the increasingly multi-institutional nature of collections clear (‘works collaboratively with other institutions to develop services at scale’ and ‘shaping Libraries programs to contribute digital content to the broader scholarly community’). The advert also makes the multi-scalar nature of this clear: “The AUL contributes to the strategic development of local, regional, and national strategies in preservation, digitization, and access.” Conscious community coordination around shared collections at the network level has become an important activity for many libraries.
[](https://storage.ghost.io/c/77/c7/77c7bb74-1d53-4c6c-a1fc-8e2ccb21b6d2/content/images/wordpress/2016/01/fullcollectionspectrum.png?ref=lorcandempsey.net)
The facilitated collection
## Some issues around the facilitated collection - towards collections as a service
Our sense of what the library collection is continues to evolve. This is a quick sketch, illustrating a direction. However, it is helpful to note some of the questions it raises. One can cluster these into core issues of organization, stewardship and discovery.
1. Management of the owned collection (and subsequently the borrowed and licensed collection) shaped library organization (technical services, automation, resource sharing, etc) until recently. New organizational arrangements are emerging, but have not yet crystallized into a general pattern. Consider how libraries are providing support for digital humanities, scholarly communication or digital scholarship in different ways, for example, often aligned with a collections function. I have mentioned job adverts as a useful signal about directions – the increased use of ‘strategist’ in collections job titles is symptomatic of a shift, as people in those roles are asked to make more decisions about allocation of resources and attention. The facilitated collection as I have described it does not map onto a single library service or organizational category – it is emergent and spans organizational categories.
2. In the ‘owned’ library, libraries had physical custody of the item, which supported clear stewardship lines. This has now changed completely. In fact, the facilitated collection involves different levels of custodial relationship with its components, which can complicate stewardship arrangements. Notably, of course, the licensed collection poses well-known questions around long term stewardship of the electronic journal literature. Stewardship of shared collections require conscious coordination of institutional actions, interests and policies. Think of the policy and service frameworks that are emerging around shared print initiatives such as the Western Regional Storage Trust ([WEST](https://www.cdlib.org/services/west/?ref=lorcandempsey.net)) or the Michigan Shared Print Intiative ([Mi-SPI](https://members.mcls.org/cms/sitem.cfm/library%5Ftools/mi-spi/?ref=lorcandempsey.net)). Or think about discussion of metadata rights in digital aggregations. Going further, what responsibility, if any, does the library take for external resources it points to? This may involve reliance on information partnerships, or in many cases, on no formal relationship at all (as for example where a library loads records for Project Gutenberg into its catalog). This variety in stewardship arrangements, and the emergence of shared collections, complicates the notion of the local collection. It also makes counting difficult or less relevant. For example, local collection counts can change significantly as libraries experiment with plugging in various content sources (think again of Project Gutenberg records in the catalog).
3. As discovery options increase in the broader network environment, so the relationship between collections and discovery shifts. Demand or patron driven acquisition provides an interesting example. It represents an inversion of the historic discovery/collection relationship: before, the collection drove discovery (the catalog), here discovery drives the collection.
There is some discussion about a shift **from collections to services**. Another way of thinking about what I have called the facilitated collection here is to move towards thinking about **collections as a service**. Libraries will continue to build collections, although the level of activity will differ across libraries. At the same time, it seems likely that facilitated collections of various types will grow in importance.
**Acknowledgements:** Thanks to Constance Malpas and Brian Lavoie for helpful comments on this post.
**Picture:** The feature image is a current (3 April 2021) representation of the collections spectrum.
**Note:** Cosmetic amendments on 3 April 2021 to add headings and feature image, and to fix spacing.
### Research information management systems: a new service category?
URL: https://www.lorcandempsey.net/research-information-management-systems-a-new-service-category/
Last updated: 2026-08-29T17:37:36.000Z
RIM is supported by a particular system category, the Research Information Management System (RIMs), sometimes referred to by an earlier name, the CRIS (Current Research Information System).
For reasons discussed below, this area has been more prominent outside the US, but interest is also now growing in the US. See for example, the mention of RIMs in the Library [FY15 Strategic Goals](http://www.dartmouth.edu/~library/home/about/mission.html?ref=lorcandempsey.net) at Dartmouth College.
## Research information management
The name is unfortunately confusing – a reserved sense living alongside more general senses. What is the reserved sense? Broadly, RIM is used to refer to the integrated management of information about the research life-cycle, and about the entities which are party to it (e.g. researchers, research outputs, organizations, grants, facilities, ..). The aim is to synchronize data across parts of the university, reducing the burden to all involved of collecting and managing data about the research process. An outcome is to provide greater visibility onto institutional research activity. Motivations include better internal reporting and analytics, support for compliance and assessment, and improved reputation management through more organized disclosure of research expertise and outputs.
A major driver has been the need to streamline the provision of data to various national university research assessment exercises (for example, in the UK, Denmark and Australia). Without integrated support, responding to these is costly, with activities fragmented across the Office of Research, individual schools or departments, and other support units, including, sometimes, the library. (See [this report](http://www.oclc.org/content/dam/research/publications/library/2009/2009-09.pdf?urlm=162926&ref=lorcandempsey.net) on national assessment regimes and the roles of libraries.)
Some of the functional areas covered by a RIM system may be:
- **Award management and identification of award opportunities**. Matching of interests to potential funding sources. Supporting management of and communication around grant and contracts activity.
- **Publications management**. Collecting data about researcher publications. Often this will be done by searching in external sources (Scopus and Web of Science, for example) to help populate profiles, and to provide alerts to keep them up to date.
- **Coordination and publishing of expertise profiles**. Centralized upkeep of expertise profiles. Pulling of data from various systems. This may be for internal reporting or assessment purposes, to support individual researchers in providing personal data in a variety of required forms (e.g. for different granting agencies), and for publishing to the web through an institutional research portal or other venue.
- **Research analytics/reporting**. Providing management information about research activity and interests, across departments, groups and individuals.
- **Compliance with internal/external mandates**.
- **Support of open access**. Synchronization with institutional repository. Managing deposit requirements. Integration with sources of information about Open Access policies.
To meet these goals, a RIM system will integrate data from a variety of internal and external systems. Typically, a university will currently manage information about these processes across a variety of administrative and academic departments. Required data also has to be pulled from external systems, notably data about funding opportunities and publications.
## Products
Several products have emerged specifically to support RIM in recent years. This is an important reason for suggesting that it is emerging as a recognized service category.
- **Pure** (Elsevier). “Pure aggregates your organization’s research information from numerous internal and external sources, and ensures the data that drives your strategic decisions is trusted, comprehensive and accessible in real time. A highly versatile system, Pure enables your organization to build reports, carry out performance assessments, manage researcher profiles, enable expertise identification and more, all while reducing administrative burden for researchers, faculty and staff.” \[[Pure](http://www.elsevier.com/online-tools/research-intelligence/products-and-services/pure?ref=lorcandempsey.net)\]
- **Converis** (Thomson Reuters). “Converis is the only fully configurable research information management system that can manage the complete research lifecycle, from the earliest due diligence in the grant process through the final publication and application of research results. With Converis, understand the full scope of your organization’s contributions by building scholarly profiles based on our publishing and citations data–then layer in your institutional data to more specifically track success within your organization.” \[[Converis](http://thomsonreuters.com/converis/?ref=lorcandempsey.net)\]
- **Symplectic Elements**. “A driving force of our approach is to minimise the administrative burden placed on academic staff during their research. We work with our clients to provide industry leading software services and integrations that automate the capture, reduce the manual input, improve the quality and expedite the transfer of rich data at their institution.”\[[Symplectic](http://symplectic.co.uk/about/?ref=lorcandempsey.net)\]
Pure and Converis are parts of broader sets of research management and analytics services from, respectively, Elsevier ([Elsevier research intelligence](http://www.elsevier.com/research-intelligence?ref=lorcandempsey.net)) and Thomson Reuters ([Research management and evaluation](http://thomsonreuters.com/scholarly-scientific-research/research-management-and-evaluation/?ref=lorcandempsey.net)). Each is a recent acquisition, providing an institutional approach alongside the aggregate, network level approach of each company’s broader research analytics and management services.
Symplectic is a member of the very interesting Digital Science portfolio. Digital Science is a company set up by Macmillan Publishers to incubate start-ups focused on scientific workflow and research productivity. These include, for example, [Figshare](http://www.digital-science.com/products/figshare?ref=lorcandempsey.net) and [Altmetric](http://www.digital-science.com/products/altmetric?ref=lorcandempsey.net).
Other products are also relevant here. As RIM is an emerging area, it is natural to expect some overlap with other functions. For example, there is definitely overlap with backoffice research administration systems – [Ideate](http://ideate.com/?ref=lorcandempsey.net) from Consilience or solutions from [infoEd Global](http://infoedglobal.com/?ref=lorcandempsey.net), for example. And also with more publicly oriented profiling and expertise systems on the front office side.
With respect to the latter, Pure and Symplectic both note that they can interface to [VIVO](http://www.vivoweb.org/?ref=lorcandempsey.net). Furthermore, Symplectic [can provide](http://symplectic.co.uk/press/duraspace-appoint-symplectic-first-official-rsp-vivo/?ref=lorcandempsey.net) “VIVO services that cover installation, support, hosting and integration for institutions looking to join the VIVO network”. It also [provides implementation support](http://symplectic.co.uk/services/profiles-rns/?ref=lorcandempsey.net) for the [Profiles Research Networking Software](http://profiles.catalyst.harvard.edu/?ref=lorcandempsey.net).
As I discuss further below, one interesting question for libraries is the relationship between the RIMs or CRIS and the institutional repository. Extensions have been written for both Dspace and Eprints to provide some RIMs-like support. For example, [Dspace-Cris](http://cineca.github.io/dspace-cris/index.html?ref=lorcandempsey.net) extends the Dspace model to cater for the Cerif entities. This is based on work done for the [Scholar’s Hub](http://hub.hku.hk/?ref=lorcandempsey.net) at Hong Kong University.
It is also interesting to note that none of the three open source educational community organizations – Kuali, The Duraspace Foundation, or The Apereo Foundation – has a directly comparable offering, although there are some adjacent activities. In particular, [Kuali Coeus for Research Administration](http://www.kuali.org/kc?ref=lorcandempsey.net) is “a comprehensive system to manage the complexities of research administration needs from the faculty researcher through grants administration to federal funding agencies”, based on work at MIT. Duraspace is now the organizational home for VIVO.
Finally, there are some national approaches to providing RIMs or CRIS functionality, associated with a national view of research outputs. This is the case in [South Africa](https://info.rims.ac.za/?ref=lorcandempsey.net), [Norway](http://www.cristin.no/english/system/?ref=lorcandempsey.net) and [The Netherlands](http://www.uu.nl/EN/informationfor/intstaffandvisitors/itfacilitiesandorganisation/ictvoorzieningen/metis/Pages/Metis.aspx?ref=lorcandempsey.net), for example.
## Standards
Another signal that this is an emerging service category is the existence of active standards activities. Two are especially relevant here: [CERIF](http://www.eurocris.org/Index.php?page=CERIFintroduction&t=1&ref=lorcandempsey.net) (Common European Research Information Format) from EuroCRIS, which provides a format for exchange of data between RIM systems, and the [Casrai dictionary](http://casrai.org/standards/dictionary/?ref=lorcandempsey.net). CASRAI is the *Consortia Advancing Standards in Research Administration Information*.
## Libraries
So, what about research information management (in this reserved sense) and libraries? One of the interesting things to happen in recent years is that a variety of other campus players are developing service agendas around digital information management that may overlap with library interests. This has happened with IT, learning and teaching support, and with the University press, for example. This coincides with another trend, the growing interest in tracking, managing and disclosing the research and learning outputs of the institution: research data, learning materials, expertise profiles, research reports and papers, and so on. The convergence of these two trends means that the library now has shared interests with the Office of Research, as well as with other campus partners. As both the local institutional and public science policy interest in university outputs grows, this will become a more important area, and the library will increasingly be a partner. Research Information Management is a part of a slowly emerging view of how institutional digital materials will be managed more holistically, with a clear connection to researcher identity.
As noted above, this interest has been more pronounced outside the US to date, but will I think become a more general interest in coming years. It will also become of more general interest to libraries. Here are some contact points.
- **The institutional repository boundary.** It is acknowledged that Institutional Repositories (IRs) have been a mixed success. One reason for this is that they are to one side of researcher workflows, and not necessarily aligned with researcher incentives. Although also an additional administrative overhead, Research Information Management is better aligned with organizational and external incentives. See for example this [presentation](http://www.slideshare.net/ULCCEvents/implementing-a-cris-with-pure/11?ref=lorcandempsey.net) (from Royal Holloway, U of London) which notes that faculty are more interested in the CRIS than they had been in the IR, ‘because it does more for them’. It also notes that the library no longer talks about the ‘repository’ but about updating profiles and loading full-text. There is a clear intersection between RIMs and the institutional repository and the boundary may be managed in different ways. Hong Kong University, for example, has evolved its institutional repository to include RIMs or CRIS features. Look at the [publications](http://scholar.google.com/citations?user=M2Nuhm0AAAAJ&ref=lorcandempsey.net) or [presentations](http://www.slideshare.net/DavidPalmer1/presentations?ref=lorcandempsey.net) of David Palmer, who has led this development, for more detail. There is a strong focus here on improved reputation management on the web through effective disclosure of researcher profiles and outputs. Movement in the other direction has also occurred, where a RIMs or CRIS is used to support IR-like services. Quite often, however, the RIMs and IR are working as part of an integrated workflow, as described [here](http://www.abdn.ac.uk/library/research-support/research-outputs/aura/?ref=lorcandempsey.net).
- **Management and disclosure of research outputs and expertise.** There is a growing interest in researcher and research profiles, and the RIMs may support the creation and management of a ‘research portal’ on campus. An important part of this is assisting researchers to more easily manager their profiles, including prompting with new publications from searches of external sources. See the [research portal](http://pure.qub.ac.uk/portal/?ref=lorcandempsey.net) at Queen’s University Belfast for an example of a site supported by Pure. Related to this is general awareness about promotion, effective publishing, bibliometrics, and management of online research identity. Some libraries are supporting the assignment of ORCIDs. The [presentations](http://www.slideshare.net/Wowter/presentations?ref=lorcandempsey.net) of Wouter Gerritsma, of Wageningen University in The Netherlands, provide useful pointers and experiences.
- **Compliance with mandates/reporting**. The role of RIMs in supporting research assessment regimes in various countries was mentioned earlier: without such workflow support, participation was expensive and inefficient. Similar issues are arising as compliance to institutional or national mandates needs to be managed. Earlier this year, the California Digital Library [announced](http://www.cdlib.org/cdlinfo/2014/03/03/the-university-of-california-awards-contract-to-symplectic-for-the-implementation-of-a-publication-harvesting-system-to-support-ucs-open-access-policy/?ref=lorcandempsey.net) that it had contracted with Symplectic “to implement a publication harvesting system in support of the UC Open Access Policy”. US Universities are now considering the impact of the OSTP memo “Increasing Access to the Results of Federally Funded Scientific Research,” \[[PDF](http://www.whitehouse.gov/sites/default/files/microsites/ostp/ostp%5Fpublic%5Faccess%5Fmemo%5F2013.pdf?ref=lorcandempsey.net)\] which directs funding agencies with an annual R&D budget over $100 million to develop a public access plan for disseminating the results of their research. ICPSR summarises the memo and its implications [here](http://www.icpsr.umich.edu/icpsrweb/content/datamanagement/ostp.html?ref=lorcandempsey.net). It is not yet clear how this will be implemented, but it is an example of the growing science and research policy interest in the organized disclosure of information about, and access to, the outputs of publicly funded research. This drives a University wide interest in research information management. In this context, [SHARE](http://www.arl.org/focus-areas/shared-access-research-ecosystem-share?ref=lorcandempsey.net#.VE29N%5FnF-So) may provide some focus for greater RIM awareness.
- **Management of institutional digital materials.** I suggest above that RIM is one strand of the growing campus interest in managing institutional materials – research data, video, expertise profiles, and so on. Clearly, the relationship between research information management, whatever becomes of the institutional repository, and the management of research data is close. This is especially the case in the US, given the inclusion of research data within the scope of the OSTP memo. The library provides a natural institutional partner and potential home for some of this activity, and also expertise in what Arlitsch and colleagues call ‘new knowledge work’, thinking about the identifiers and markup that the web expects.
Whether or not Research Information Management become a new service category in the US in quite the way I have discussed it here, it is clear the issues raised will provide important opportunities for libraries to become further involved in supporting the research life of the university.
**Picture:** The feature picture is a screenshot of the public face of the research information management system at the University of Bath. I worked at Bath for several years, and a colleague kindly populated with RIM with some of my publications after I left.
**Note:** I made some cosmetic updates on 4 March 2021 on transition to the new platform, to include adding a feature picture and headings. I resisted the temptation to update it as quite a bit has happened in intervening years. It has been [cited](https://scholar.google.com/scholar?cluster=13023256206177556187&ref=lorcandempsey.net) quite a few times as an introduction to the topic. Work by colleagues at OCLC Research has done much to advance the RIM agenda in the US and elsewhere.
[An Increasing Role for Libraries in Research Information ManagementResearch Information Management (RIM) is the aggregation, curation and utilization of information about research and is emerging as a part of scholarly communications practice in many university libraries.OCLC](https://www.oclc.org/research/areas/research-collections/rim.html?ref=lorcandempsey.net)
### The decentered library network presence
URL: https://www.lorcandempsey.net/the-decentered-library-network-presence/
Last updated: 2022-11-07T17:04:42.000Z
## Two trends: centripetal and centrifugal
Think of two trends in the development of the library’s network presence. These have emerged successively and continue to operate together.
1. A centripetal trend producing a library network presence **centered** on the institutional website, as the library wants to offer an integrated service.
2. A centrifugal trend, unbundling functionality and placing it in a variety of **decentered** network presences, as the library wants to be in the flow of its users (think of how communication has been unbundled to social networking sites for example, or of how metadata may be shared with various aggregation sites, or of how a resolver may be configured for use with a third party site).
The decentered library network presence is an important component of library service although it still appears to be an emergent interest in strategic or organizational terms.
In the **centripetal trend**, the focus was on integration around a singular, ‘**centered**‘ network presence: the library website. The library website was the principal de facto network manifestation of the library, and the integration of library services in the website was a goal. Early examples of this were discussions around ‘portals’, one-stop-shops and metasearch. Later, this trend continued with more consolidated approaches which overcame some of the cost and inefficiencies of integration. Included here were the use of unified search systems often deploying integrated discovery layer products, the use of resource guides to manage resources with a consistent approach, the adoption of content management systems. Service consolidation, a stronger focus on providing a coherent user experience, a move to cloudsourced applications (discovery and resource guides for example), and an emerging emphasis on [full library discovery](https://blog.oclc.org/lorcand/archives/002214.html?ref=lorcandempsey.net) help create a more unified experience at the library website.
In the **centrifugal trend**, the network library presence is **decentered**, unbundled or decoupled to an evolving ecosystem of services, each with a particular focus or scope. Think for example of how aspects of user engagement have been unbundled to various social networking sites (Facebook, Twitter, Pinterest, Flickr, …), or of how parts of the discovery experience has been unbundled to Google Scholar or PubMed or to a cloud-based discovery layer, or of how some library services are atomized and delivered as mobile apps, toolbar applications, or ‘widgets’ in learning management systems and other web environments external to the library’s. The library website is now a part, albeit an important part, of this evolving network presence. In this way, the library network presence has been decentered, subject to a centrifugal trend to multiple network locations potentially closer to user workflows. There are two important drivers here. One is the desire to reach into user workflows, acknowledging that potential library users may not always come to the library website. A second is the desire to make institutional resources (digitized special collections, research and learning materials, for example) available to external audiences in more effective ways. This is an aspect of the ‘[inside-out library](https://blog.oclc.org/lorcand/archives/002102.html?ref=lorcandempsey.net)‘.
## A decentered library network presence.
Here are some strands of the ‘decentered’ library network presence.
- **Unbundled engagement and communication**. Several activities may have been decoupled from the website and sourced with web-scale services. For example, engagement and communications activities may be sourced with Twitter, Facebook, and WordPress. Promotional activity may take place on YouTube, Flickr, and Pinterest.
- **Syndication**: We can define syndication as creating connections to library information services in other environments, by placing data, content or services in those other environments. Library resources may be made available, for example, as widgets in the learning management system, as an RSS feed, or in a LibX-style toolbar. There is also strong interest in apps for mobile phone and tablets. The library may syndicate data to other environments, passively through OAI-PMH harvesting or newer linked data approaches, or by more active transfers to WorldCat or some other metadata aggregation. The library may configure a resolver to ensure well-seamed access from Google Scholar or Pubmed Central, which is also a form of service syndication. The goal is to make the library resources [discoverable](https://blog.oclc.org/lorcand/archives/002206.html?ref=lorcandempsey.net) in user workflows. The University of Minnesota [discoverability](https://blog.oclc.org/lorcand/archives/002153.html?ref=lorcandempsey.net) reports are well worth reading in this context.
- **Cloudsourcing**: Integration of systems and services, sourced from the cloud. It is now becoming more common to externalise systems provision to third party providers: think of the discovery layers that libraries are deploying in the cloud for example, or the LibGuides resource guides. The move to cloud providers is a major direction here, and one of the motivations is to reduce some of the systems integration complexity, while improving the user experience. By cloudsourcing here, I am referring to the selective move of library operations to the cloud. Of course, the unbundled communication activity is also sourced from the cloud, but is typically from non-library providers. As noted above, cloudsourcing can support the centripetal trend as external resources may be integrated in the website, but it also supports the centrifugal trend as services may be made available as independent external destinations, or may be syndicated to other network presences (e.g. access to a central index API).
Now, despite the fact that there is quite a bit of activity supporting what I am calling here the decentered network presence, it has not crystallized as a service or organizational category for the library. It is an area of emergent interest. There seem to be at least three factors at play.
- **Unquantified**. Libraries don’t have a holistic view of traffic against their entire network presence. The difficulty of compiling statistics across services is well known. Libraries are working across multiple environments and systems, with intermittent availability of good data about usage, no consistent approach across systems, and usually no aggregate view. This means that the library’s knowledge of the use of its own services, and of the benefits of particular approaches, is limited in important ways. At the same time, while there is awareness of the benefits of better data, a data-driven approach to engagement, resource allocation, or service development is not yet prevalent. Anecdotal and local evidence shows the importance of syndicated approaches (including Google referrals) in general traffic against library resources, but we do not have a general picture.
- **Pre-strategic**. The importance of unbundled communication, syndication and cloudsourcing is agreed. However, strategic attention to these areas is often rather more emergent than deliberate (in the sense in which [Mintzberg](https://en.wikipedia.org/wiki/Henry%5FMintzberg?ref=lorcandempsey.net#Contribution%5Fto%5Fbusiness%5Fstrategy%5Ftheory) uses these terms). Attention may be opportunistic, although is likely to be increasingly patterned in future.
- **Spanning organizational boundaries.** A variety of parts of the library is interested in a network presence, and attention to these topics may not always be pulled together in a single planning context. This is clear of social networking, but may also be the case with the other areas I mention.
Clearly, there are different dynamics at play in the components of the decentered network presence of the library. However, we can expect a more holistic view to emerge in coming years.
**Related entries:**
- [Full library discovery](https://www.lorcandempsey.net/orweblog/full-library-discovery/)
- [Discovery vs discoverability](https://www.lorcandempsey.net/orweblog/discovery-vs-discoverability/)
- [There is more to discovery than you think](https://www.lorcandempsey.net/orweblog/there-is-more-to-discovery-than-you-think/)
- [Outside-in and inside-out redux](https://www.lorcandempsey.net/orweblog/outside-in-and-inside-out-redux/)
**Picture:** I took the feature image in Kettle's Yard, in Cambridge, UK.
**Note:** Cosmetic updates on transition to new site on 30 March 2021, including spacing and addition of headings.
### Roses are red .... the top love stories?
URL: https://www.lorcandempsey.net/roses-are-red-the-top-love-stories/
Last updated: 2022-11-07T18:13:30.000Z
One of the nice things about [WorldCat](https://oclc.org/en-US/worldcat.html?ref=lorcandempsey.net) is that is has sufficient scale to be a good proxy for a large part of the scholarly and cultural record. The aggregate holdings of thousands of libraries contain not just books, but movies, music, and so on. It is not complete but it gives good results.
In honor of St Valentine’s day, my colleagues JD Shipengrover and Diane Vizine-Goetz have produced [a list](https://www.oclc.org/research/lists/toplovestories.html?ref=lorcandempsey.net) of the most widely held love stories in libraries – the most widely held books and the most widely held movies.
Here are the lists … It is interesting seeing the similarities between the two.
## Books
1. Pride and Prejudice
2. Jane Eyre
3. Wuthering Heights
4. Emma
5. Sense and Sensibility
6. The Great Gatsby
7. Anna Karenina
8. The Return of the Native
9. The Portrait of a Lady
10. Mansfield Park
## Movies
1. Jane Eyre
2. Gone With the Wind
3. Pride and Prejudice
4. Emma
5. West Side Story
6. Sense and Sensibility
7. The Sound of Music
8. Romeo & Juliet
9. Titanic
10. The Princess Bride
These lists are based on a fiction (books and movies) subset of Worldcat, using the genre data in the records. The data is clustered at the work level, to consolidate editions and so on. A little more context is at the [list page](https://www.oclc.org/research/lists/toplovestories.html?ref=lorcandempsey.net).
**Picture:** I took this picture of my copy of *Persuasion*, not on the list I know, but I do prefer it to *Pride and Prejudice* and *Emma*.
**Note:** Cosmetically amended on 31 March to add feature image, better spacing, headings.
### Full library discovery
URL: https://www.lorcandempsey.net/full-library-discovery/
Last updated: 2026-08-29T17:39:17.000Z
## Full collection discovery
The scope of library discovery services continues to evolve. We might characterise the situation we are in now as *full collection discovery*. The model is of a cloud-based, central index, where the goal has been unified results across collection types delivered in a single search box.The full collection includes material from the catalog, journal articles, and sometimes local digital repository material. Several so-called ‘discovery layer’ products (including Worldcat Local) are now used to provide this functionality.
From this stage, I think we can see several interesting evolutions in scope, as change continues.
- The integration of full-text or other content-based search.
- The integration of materials that are not held by the library, but which are interesting and available to users – open access materials, for example, or learning resources like Khan Academy videos, or collections like the HathiTrust.
- Integration of potentially available materials to support demand driven acquisition.
- The integration of more semantic data about entities (works, authors, subjects, …) and their relationships as the focus shifts away from records about invidual items to data about the ‘things’ of potential interest.
- The integration of recommendations based on usage data or on content-based connections.
## Full library discovery
Here, I want to focus on another scope evolution which we are beginning to see in various manifestations. This is a trend to ‘full library discovery’, where discovery goes beyond the collections to include a fuller range of library capacities. In current services, a library user is usually presented with a collection search, and a range of web pages about other library services or expertise. The two are separated in the website experience, but may not be separate in the user expectation of the library. If I am interested in *demographics*, for example, why not find a curated resource guide or the name of a subject specialist as well as relevant articles or books when I do a search?
And, indeed, we are beginning to see discovery environments which provide a layer over not only the collections, but also potentially over the library website, library staff and expertise, resource guides, and so on. In other words, we are seeing approaches to *full library discovery* emerge.
I have written about Stanford and Michigan in this context before, and I draw on [that post](https://blog.oclc.org/lorcand/archives/002202.html?ref=lorcandempsey.net) here.
> \[The [U Michigan Libraries site](https://www.lib.umich.edu/mlibrary/search/libguides%3Bwebsite%3Bdigitalcollections%3Bsearchtools%3Bmirlyn%3Bejournals/demographics?ref=lorcandempsey.net)\] works well to project the library on the web as a unified service. A central part of this is the integrated search over collections, library website, LibGuides and library staff profiles. The return of relevant subject specialists which match the query in a separate results pane is particularly interesting. And is in line with my view that if libraries wish to be seen as expert, then their expertise must be visible.
> The [Stanford site](https://library.stanford.edu/?ref=lorcandempsey.net) offers a Search everything tab, with this amplifying tagline: “Not sure where to start? Try this.”. What I like about it is that the examples searches shown emphasise the ‘full library’ aspect of what is on offer here: they are very deliberately pitching this at a broader level than books and articles. The example searches are ‘renew books, dissertations, feminist studies, worldcat’: they are about questions people may have when they come to the library website, not only about items they might find in the collection. // [Two things prompted by a new website: space as a service and full library discovery](https://blog.oclc.org/lorcand/archives/002202.html?ref=lorcandempsey.net)
[](https://www.lorcandempsey.net/lorcand/lorcan/eavanbolandstanford.PNG)
So, what types of things are being included, or could be included?
- People and Expertise. The Michigan and Stanford examples show a discovery service which provides access to relevant staff profiles in the search results.
- Resource guides. These represent an investment of library expertise in curation against specific subjects or interests. It makes sense for them to be discoverable alongside the collections to which they refer
- The library website. This is a source of information about the range of library services, people and facilities. It may also include events, information about specialist equipment or expertise, and so on. Again, we are seeing the library website included in search results alongside the collections discovery service. (How to distinguish between a website search and a collections search is an interesting question in library website design … it is not always clear.) As noted below, a focus on full library discovery may encourage libraries to present information about particular areas of activity in ways which support more specific indexing, searching and presentation of results (presenting events for example, or library services).
- Pointers to search-specific further information resources, where they can be ascertained.
## Tools and Website design
And what implications does this have for tools and website design?
- One is the use of Drupal, Blacklight and other frameworks to deliver unified results across several resources. These may pull articles and other resouces from the ‘discovery layer’ service.
- Related to this is the ‘Bento box’ style of presenting search results, as not only may it be difficult or confusing to rank results across different types of resources, but a tabular presentation like this may make more sense to users. Bento Box is a nice expression introduced by Tito Sierra to refer to the results which are presented in resource-specific tiles or panes (see [the Stanford results above](https://library.stanford.edu/search/all?search=eavan%20boland&ref=lorcandempsey.net) for a nice example).
- There may be some rethinking of how events, services, staff profiles and expertise, and other library activities are represented and indexed. Typically, now, these are represented on flat web pages. A more structured approach may make sense to facilitate discovery in this way.
- Related to this need is the increased use of resource guides – in many cases Libguides. In particular they are often used as a simple content management framework for various type of information about the library, and not only for lists of information resources.
The collection remains central to the library experience. However, as library services evolve beyond the collection so it makes sense for discovery services to represent more of what the library does and can provide.
This blog entry expands the second part of [Two things prompted by a new website: space as a service and full library discovery](https://blog.oclc.org/lorcand/archives/002202.html?ref=lorcandempsey.net).
**Picture:** I took the feature image at Stanford University. Jim Michalko is inspecting the Andy Goldsworthy sculpture.
**Note:** Cosmetic updates on 1 April 2021 to fix spacing, and to add picture and headings.
### Three challenges: Engaging, rightscaling and innovating
URL: https://www.lorcandempsey.net/three-challenges-engaging-rightscaling-and-innovating/
Last updated: 2026-08-29T15:56:15.000Z
I was in Australia recently, primarily to attend the conference intriguingly entitled ‘[The edge of the world](https://theta.edu.au/?ref=lorcandempsey.net)‘. The presentation I gave is embedded below. This was the latest Theta conference, the Australian parallel to Educause. More recently, I was pleased to attend parts of the CIC Center for Library Initiatives [conference](https://www.cic.net/calendar/conferences/library/2013/home?ref=lorcandempsey.net), hosted by The Ohio State University, here in Columbus. Finally, Kurt de Belder recently gave a [presentation](https://www.oclc.org/research/news/2013/05-31.html?ref=lorcandempsey.net) at OCLC in our Distinguished Speaker Series, in which he spoke about the transformation of the academic library.
In Hobart, after some introductory material, I spoke about three challenges for libraries: a shift to engagement, rightscaling infrastructure, and innovation, notably institutional innovation. I only attended some of the sessions at the CIC meeting but I was struck by the correspondences between what I heard there and the challenges I identified. It also seemed to me that much of what Kurt spoke about aligned well with these challenges.
This blog entry briefly talks about each challenge and illustrates them with examples from the CIC conference and Kurt’s presentation.
## Introduction
Engagement, infrastructure and innovation are related of course. As engagement becomes more important, libraries are reducing local infrastructure where it does not make a distinctive local impact (print collections and systems, for example). Greater engagement means that there may be a need for new services which requires innovation. Over time innovations may become established and generate infrastructure requirements, which may be provided in different ways.
Libraries always did these three things, but I think the nature of the current challenge is different. Libraries are looking at more and different ways of engaging with their users as patterns of research, learning and personal information use change in a network environment, and are actively looking to re-allocate resources to support his shift. At the same time, the emergence of the network makes it possible to chose to source infrastructure in different ways and at different levels, introducing new choices and partner opportunities.
## 1\. The shift to engagement
By engagement, I mean that libraries are working to create distinctive value in the research, learning and teaching workflows of their users in ways which go beyond the provision of collections.
In this context, Kurt de Belder speaks about the library as an active partner in knowledge. Scott Walter spoke recently about [the service turn](https://blog.oclc.org/lorcand/archives/002152.html?ref=lorcandempsey.net), a direction in which libraries aim for distinction in the services they offer, as the distinctive value of collections is less strong, and content is less scarce
And I was struck by this formulation by the University of Minnesota Libraries:
> In alignment with the University’s strategic positioning, the University Libraries have re-conceived goals, shifting from a collection-centric focus to one that is engagement-based. // [](https://directors.arl.org/file/show/uminnesota.pdf?ref=lorcandempsey.net)[PDF](https://crl.acrl.org/content/72/1/6.full.pdf?ref=lorcandempsey.net)
Think of these trends:
- Users used to build their workflows around libraries. Now the library needs to build services around user workflows, especially as those workflows form around broader network services. So, for example we see libraries expose their knowledge bases to Google Scholar; introduce support for Mendeley and Zotero alongside Endnote or Refworks; reach out to provide curricular or grants support; and other ways in which they more directly support changing workflows. Kurt de Belder spoke about their support for researchers through VREs (virtual research environments), systems to support group working and research workflow (in their case, based on the [Sharepoint toolkit](https://research.microsoft.com/en-us/projects/vre/?ref=lorcandempsey.net) developed by Microsoft Research).
- Libraries used to acquire and organize ‘published’ materials. Now they are engaged with the full range of creation, management and disclosure of learning and scholarly resources. For example, we are seeing library provide copyright, publishing, or bibliometric advice; engage with the emerging scholarly publishing practices of their faculty; explore research data management strategies; actively promote institutional research and learning outputs through the institutional repository; … This means that promoting institutional materials on the network becomes more important.
- Library spaces used to be configured around the management and use of print collections; now they are configured around engagement with researchers and learners, around experiences, expertise, and specialist facilities. For example, libraries provide better spaces for social interaction around learning or communication tasks; they promote access to specialist data, GIS, or other expertise; and they mount exhibitions which highlight relevant aspects of special collections and archives.
These are all examples of how libraries are reallocating resource and effort to engage more strongly with the learning and research lives of their users, focused on improving the learning experience, making research more productive and research outputs more visible.
One signal of this shift is the debate around the library subject or liaison role. Kurt de Belder describes a shift in Leiden University from collection specialists to outreach which is ‘service and expertise based’. Liaison librarians will partner around ‘data curation, copyright, text and data-mining, e-publishing and dissemination, GIS, datasets’.
Clearly, given its topic, the CIC conference focused on new forms of engagement with the faculty around curation and dissemination of research outputs, around new forms of scholarly publishing, and around publishing support and advisory services.
Four things occurred to me as I listened, specific to this particular discussion about publishing support, but which might be generalised to other emerging forms of engagement with research and learning.
1. These are areas where libraries are exploring a range of services, which means that each library’s approach will be different. And each library’s activity will be differently situated in relationship to other campus services. This was very clear in the final panel session where participants spoke about how services were organized. There is no consistent organizational pattern, for example, for the relationship between copyright and other advisory services, library publishing services, university press, research data management, and institutional repository. In this context, I was also interested to recently see how Penn State had aligned special collections and scholarly publishing services in [one division](https://www.libraries.psu.edu/psul/admin/adrsc.html?ref=lorcandempsey.net).
2. It is sometimes difficult to discern between edge cases and emerging services: are alternative forms of monograph peer review and publication going to emerge as important categories for example, or will they remain experimental?
3. There is a balance between doing extensive custom work for one faculty member or department and the ability to scale services effectively across a campus community.
4. Emergent areas live beside established practices. This may lead to a more plural environment, or over time to disruption or absorption. Think of the various scenarios that might play out with open access publishing and alt-metrics for example. There were CIC panels in each of these areas, with participation by representatives from Elsevier and Thompson Reuters.
For me, this discussion underlined the innovation challenge I discuss below. Exploration and experiment has to turn into something repeatable and scalable if it is to become part of the library portfolio. And much of the required innovation is around the institutions through which we organize to get work done – think of the changing relationship of University Press and Library, for example.
## 2\. Rightscaling
Libraries were predominantly ‘institution-scale’ – they provided services at the level of the institution for their local users. However, their users now look to the network for information services (e.g. Google Scholar, Wikipedia, …). And libraries now look to the network to collaborate or to source services (e.g. HathiTrust, cloud-based discovery or management systems, shared systems infrastructure, …). At the same time, we are seeing a growing interest in shared management of the collective print collection, as regional and other consortia emerge to rebalance print management across groups of libraries.
In this environment the need for local infrastructure declines (e.g. extensive print collections, redundantly deployed local systems which provide necessary but not distinctive services). The scale advantage of different ways of doing things manifests itself in both impact and efficiency. Think of HathiTrust. It has more impact, because it acts as a gravitational hub on the nework. And it is more efficient to consolidate this activity rather than spread it redundantly across many libraries.
Print collections provide an interesting example of emerging infrastructure consolidation. In seven years time, say, a large part of the existing print collection in libraries will have moved into shared management, with a reduced local footprint. The opportunity costs of locally managing large print collections which release progressively less value into research and learning are becoming too pressing for this not to happen. There is a low engagement return on this infrastructure investment.
At the CIC meeting, scale came up in several contexts. John Wilkin spoke about how the consolidation of publishing activities in one unit and the sharing of infrastructure across them allowed the separate activities to benefit from scale, and achieve a level of activity that would have been impossible if they had remained separate, scattered across the University of Michigan. Charles Watkinson mentioned that it was usual to outsource technical infrastructure at Purdue. And in his closing remarks, Mark Sandler mentioned previous discussions about a single university press for the CIC. He suggested that it might be more reasonable to explore a model in which backoffice infrastructure was shared, but where engagement with research, author relations, press identity, remained individual to each campus. In the vocabulary used here, he was speculating that infrastructure might scale to the level of a regional consortium, while engagement might remain at institution-scale.
On a national scale, Kurt de Belder spoke about the Dutch bibliographic infastructure, currently provided in partnership with OCLC. He reported discussion about whether there continued to be a need for national-sscale services in the current network envioronment, and whether in fact they should go to more global provision at the network level.
Of course, although rightscaling is an important infrastructure issue, it is not limited to infrastructure. Kurt also spoke about [the lack of scale](https://www.slideshare.net/kurtdebelder/transformation-of-the-academic-library-oclc/46?ref=lorcandempsey.net) as a broader library issue. He argued that each individual library could not specialize in the range of expertise required to deliver current services. He spoke, for example, about research data management services in the context of the full range of disciplines on a campus. In this context, he spoke for national and international collaboration around networks of provision to get local jobs done.
These examples show how rightscaling has become a central question for libraries. Do I build something myself? Do I do it collaboratively? Do I outsource it to a third party? Again, look at discovery systems or library management systems in this context, or look at the trend to managing down print collections alongside emerging shared print initiatives. Think of the models in use for preservation (LOCKSS, Portico). Think of newer services like analytics or recommendations where an institutional perspective may not scale and collaborative or third party approaches will be necessary. Think of how important it is to make sure that your resolver is correctly configured in Scholar or PubMed. Questions increasingly arise around cloud provision, around collaboration, or around outsourcing to third parties.
As libraries want to emphasize impact and engagement, and de-emphasize activities which do not create distinctive local value, rightscaling becomes a key question.
## 3\. Institutional innovation
As behaviors and structures shift, innovation becomes central.
I think of two big trends here. The first is a shift – well underway – from thinking about the library as a fixed set of services (bureaucratic) to thinking about it as an organization which reconfigures to map changes in its user environment and expectations (enterprise). The second shift is around institutional innovation and the learning that flows from it.
I wrote about the first of these shifts a while ago.
> Historically, libraries enjoyed stability and a shared understanding of goals. This in turn favored a focus on managing and improving the means towards those goals – building the collection, providing reference service, creating efficiencies in technical processing, and so on. This was the focus of professional practice and education. Much of this work is inherently bureaucratic. However, in an environment of change while overall mission and values may remain the same, new and shifting goals become the norm. Think of greater integration in the learning and research process through greater curriculum support, data curation, scholarly publishing, or support for grant writing or expertise profiles. Think of network based reading services, or jobseeking and homework support. As goals shift in a changing environment, so does the need to think about how to marshall the means to meet them. This may need reorganization, new staff skills, changing priorities, reallocation of staff and resources, and so on. It requires a shift from bureaucracy to enterprise, an adaptive organization that reviews and reshapes what it does in light of changing requirements. // [The Enterprising Librarian](https://blog.oclc.org/lorcand/archives/002201.html?ref=lorcandempsey.net)
Coping with change requires an enterprising orientation, one which recognizes that resources and effort must be continually adapted to meet the needs of the library user.
Institutional innovation is the second trend I note here, one which is inevitable as internal and external partnerships rebalance effort. Libraries have to develop new and routine ways of collaborating to achieve their goals, which involves evolution of organizational, cultural and communication approaches. At the same time they have to negotiate internal boundaries and forge new structures within institutions. In each case, they are developing new ‘relationship architectures’ (to use a phrase of Hagel and Seely Brown’s).
Think for example of the institutional innovation required to move to shared systems and collections in the Orbis Cascade Alliance or 2CUL for example.
Or think of the innovative approach which makes new relationships within institutions (with Learning and Teaching Support, with the Office of Research, the University Press, emerging e-research infrastructure, IT, etc, for example, or with various educational or social services in a public setting). Evolving such relationships requires an enterprising approach and ensures continual learning, as staff interact with colleagues elsewhere to evolve new structures and services.
We are used to thinking of innovation in relation to startups. Here is a definition from [Steve Blank](https://steveblank.com/2010/01/25/whats-a-startup-first-principles/?ref=lorcandempsey.net): “a startup is an organization formed to search for a repeatable and scalable business model”. This is useful as it reminds us that to be successful. In library terms, innovation has to result in repeatable and scalable services which can be supported over time. And this brings us back to the type of engagement that is valuable and the infrastructure that is required to support it.
Much of the discussion around the examples I have used is an exploration of how to make identified new services repeatable and scalable, and of how to evolve the skills and organizational settings to support them.
**[Rightscaling, engagement, learning: reconfiguring the library for a network environment ](https://www.slideshare.net/lisld/hobart-19178013?ref=lorcandempsey.net "Rightscaling, engagement, learning: reconfiguring the library for a network environment ")** from **[Lorcan Dempsey](https://www.slideshare.net/lisld?ref=lorcandempsey.net)**
**Acknowledgements**
The framework used here is influenced by the categories used in Unbundling the corporation, Harvard Business Review, 77, 2\. January 1, 1999.
Institutional change and learning is discussed by John Hagel and John Seely Brown in [Institutional innovation: creating smarter organizations to scale learning](https://www.scribd.com/doc/129958072/Institutional-Innovation-Creating-Smarter-Organizations-to-Scale-Learning?ref=lorcandempsey.net), (January 01, 1999).
**Picture:** I took the feature image in Hobart, Tasmania.
**Note:** Cosmetically amended on 1 April 2021 to add feature image and headings, and to improve spacing. Introduction shortened 11 November 2022\.
### Names and identities: looking at Flann O'Brien
URL: https://www.lorcandempsey.net/names-and-identities-looking-at-flann-obrien/
Last updated: 2023-12-12T19:44:39.000Z
## The plurality of Flann O'Brien
Names and identities are a major focus of interest for OCLC Research. I adapt this discussion of our work in this area from the recent [OCLC Research Quarterly Highlights](https://www.oclc.org/research/publications/newsletters/quarterlyhighlights/2012-13q3.html?ref=lorcandempsey.net).
We know very well that names are not always straightforward. [Brian O’Nolan](https://en.wikipedia.org/wiki/Brian%5FO%27Nolan?ref=lorcandempsey.net) and Brian Ó Nualláin are the English and Irish versions, respectively, of the name of the person who is more commonly known to us as the author [Flann O’Brien](https://www.worldcat.org/search?q=Flann+O%27Brien&ref=lorcandempsey.net).
But things are more complicated. Flann O’Brien was the ‘identity’ he chose when writing novels in English. As the prolific author of satirical columns in the *Irish Times*, he was known as Myles na gCopaleen, under which identity he also wrote an Irish language novel (and it should be noted that this turns up under different spellings, Myles na Gopaleen, for example). I take it that Flann O’Brien and Myles na gCopaleen are examples of what ISNI (more of which later) calls ‘public identities’ for Brian O’Nolan. Of course, it does not stop here, as Flann O’Brien was also known by several other names.
More generally, even if most people’s names and identities are less complicated than this, there is not a one-to-one relationship between names and people. This means that the relationship between people and their names and identities has become something that is managed in a variety of places. Of course, different choices can be made in those places. If I do a search on Wikipedia for either Flann O’Brien or Myles na gCopaleen, for example, I get directed to the page for ‘Brian O’Nolan’. Wikipedia directs us to the person Brian O’Nolan, rather than to any of his assumed identities. Libraries have for a long time had an apparatus to manage this plurality: authority control. And national library authority files have different practices in how they roll names up to one or more identities.
[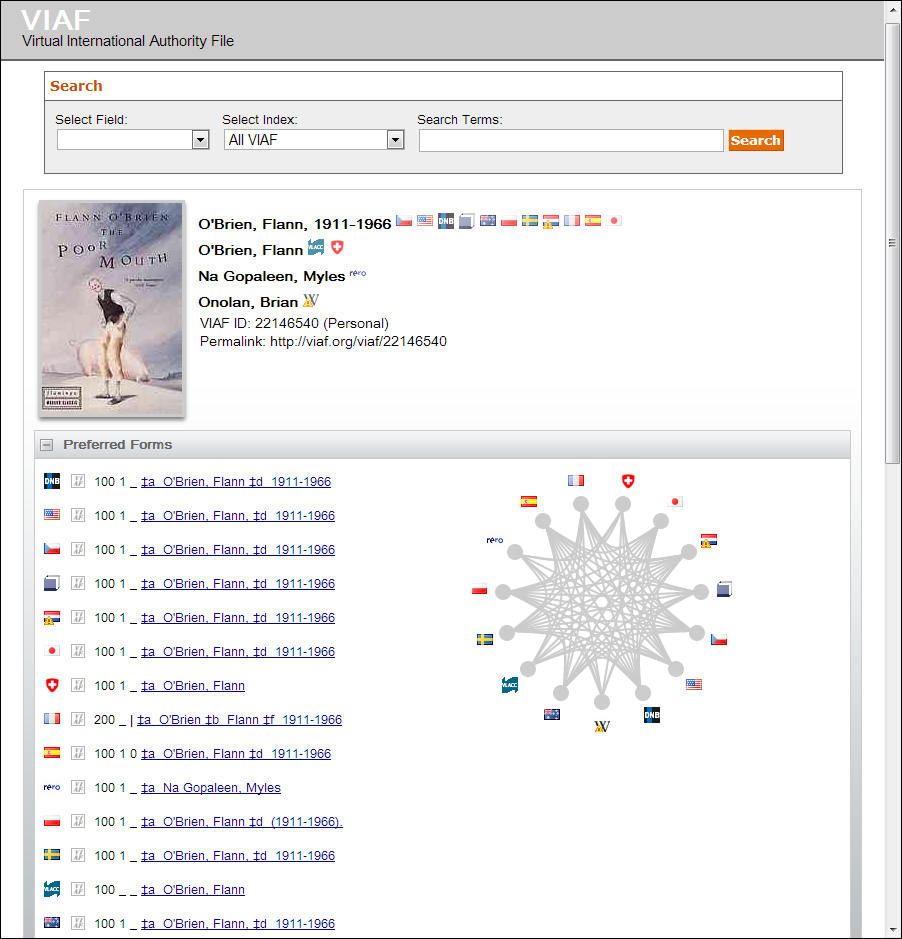](https://viaf.org/viaf/22146540/?ref=lorcandempsey.net)
## Authority control and VIAF
Authority control has typically been organized on a country by country basis: national libraries organize national authority files. As the network unifies information spaces globally, purely national files have less utility. Recognising this issue, OCLC Research has been working with national libraries around the world to synthesise authority files into what we call the Virtual International Authority File, [VIAF](https://viaf.oclc.org/?ref=lorcandempsey.net). VIAF now brings together names from those files into 24 million clusters, and assigns each of these a unique ID. Matches are not made simply on name text strings–contextual data from the authority files (e.g., birth date) and associated bibliographic data are also used. Further work is being done to increase the value of this consolidated resource. For example, the VIAFbot initiative creates links between Wikipedia and VIAF, inserting a VIAF link on appropriate Wikipedia pages. And VIAF now treats Wikipedia as a contributory source, ingesting names from Wikipedia alongside names from national authority files. In this way, there is a direct, actionable link between the global, addressable knowledge base that (the English) Wikipedia has become and library files, enhancing the value of each. The Wikipedia page for Brian O’Nolan has a link to the VIAF entry for Flann O’Brien. Importantly, from this we can assert that the “thing” or “person” described by [https://en.wikipedia.org/wiki/Brian\_O’Nolan](https://en.wikipedia.org/wiki/Brian%5FO'Nolan?ref=lorcandempsey.net) is the same as the “thing” or “person” described by [https://viaf.org/viaf/22146540/](https://viaf.org/viaf/22146540/?ref=lorcandempsey.net). We are looking at other language Wikipedias also.
VIAF has quickly become a major source of data about names. It gives a unique identifier to those entities–people, organizations, and others–which are the creators or subjects of works, gathers names which designate them, and contextualizes them with associated metadata. OCLC and the participating national libraries hope to see VIAF become an important backbone reference in the emerging web of data. And for this reason, we have made it openly available as linked data.
## VIAF, ISNI, Orcid
Of course, there are also other important initiatives, notably ISNI and ORCID. As the web becomes more central to scholarly and cultural activity, and as more information work is automated, identity and disambiguation are increasingly important. People are resources which need to be discoverable, referencable, and relatable. Accordingly, names and their relationship to the people they designate has become a key interest in the cultural, educational and creative fields.
Because of our work with VIAF we are closely connected with both ISNI and ORCID. The International Standard Name Identifier ([ISNI](https://www.isni.org/?ref=lorcandempsey.net)) is an ISO standard ([ISO 27729](https://www.iso.org/iso/catalogue%5Fdetail?csnumber=44292&ref=lorcandempsey.net)) that uniquely identifies “the identities used publicly by individuals or organizations involved in creating, producing, managing and distributing content.” It is managed by a consortium of national libraries, rights organizations and others. The ability to unambiguously designate a person is important in a rights environment. VIAF provided data to seed the ISNI pool of people data and OCLC provides the infrastructure to manage ISNIs. ISNIs have begun to be added to VIAF. [ORCID](https://orcid.org/?ref=lorcandempsey.net) emerges from the scholarly publishing arena where the consistent identification of researchers has always been an issue. Here again, as more services are built on the programmatic manipulation of data about publications, researchers and institutions, unambiguous designation has become a goal. OCLC Research participates on the ORCID Board and the relationship between VIAF and ORCID is being discussed.
We expect to see various relationships between ISNI, VIAF and ORCID as they evolve.
## Other names initiatives
Alongside this involvement in these important formal initiatives, we have some other important interests in names. These include:
- The source of information about names in the above initiatives is the creator themselves, or expert metadata creators. However, we also expect to complement this work by programmatically identifying names. We are exploring automatic recognition, extraction, and disambiguation of named entities (e.g., the names of people, places, and organizations) from digital texts. This work will be increasingly important, as manual description methods will not scale.
- We provide Worldcat Identity pages into the Worldcat.org environment. Here is the page for Flann O’Brien: [https://www.worldcat.org/wcidentities/lccn-n50-1905](https://www.worldcat.org/wcidentities/lccn-n50-1905?ref=lorcandempsey.net). Worldcat Identities has a summary page for every name in [WorldCat](https://www.oclc.org/worldcat/default.htm?ref=lorcandempsey.net) (currently over 40 million names) including named persons, organizations and fictitious characters. The pages include information derived from WorldCat and other sources (including [VIAF](https://www.oclc.org/viaf/default.htm?ref=lorcandempsey.net)) alongside unique data derived or created through a variety of special processing activities (e.g., WorldCat Identities provides statistical data about how widely held a work is). A typical WorldCat Identities page will include a list of most widely held-by-libraries works by and about the identity, a list of variant forms of name the identity has been known by, a tag cloud of places, topics, etc. closely related to works by and about the person, links to co-authors, and more. While Worldcat Identities and VIAF are developed from different directions, we are looking at closer links between them.
- We have been working with a group of Syriac scholars, looking at issues around accepting a feed of names into VIAF from a scholarly community rather than from a national authority file. See [https://hangingtogether.org/?m=201303](https://hangingtogether.org/?m=201303&ref=lorcandempsey.net) for some discussion. In general, it is likely that VIAF will synthesise data from other additional sources which go beyond national authority files.
- Given growing library interest in the names and identities of their institution’s researchers, the partial nature of national authority files (they typically only include creators of works which have been catalogued), and the emerging variety of identifier approaches, we have instituted a working group to explore issues around names, researchers, libraries, and national authority files. [https://oclc.org/research/activities/registering-researchers.html](https://oclc.org/research/activities/registering-researchers.html?ref=lorcandempsey.net) The initial aim is to produce a report which looks at the role of authority files as library and researcher needs change.
We are pleased to be doing this important work as part of an emerging infrastructure around names and identities. We welcome enquiries or comments–to me or directly to colleagues working on these initiatives. Further details can be found on these pages:
- VIAF – [https://www.oclc.org/viaf.en.html](https://www.oclc.org/viaf.en.html?ref=lorcandempsey.net)
- WorldCat Identities – [https://www.oclc.org/research/activities/identities.html](https://www.oclc.org/research/activities/identities.html?ref=lorcandempsey.net)
- Registering Researchers in Authority Files – [https://oclc.org/research/activities/registering-researchers.html](https://oclc.org/research/activities/registering-researchers.html?ref=lorcandempsey.net)
**Picture:** The picture is a screen shot of part of Flann O'Brien's Viaf entry.
**Note:** Amended cosmetically on 31 March 2021 with picture, headings and improved spacing.
### Defining the library ... reflexively
URL: https://www.lorcandempsey.net/defining-the-library-reflexively/
Last updated: 2022-11-05T04:12:42.000Z
## The generative library
It occurred to me recently that the library definitions I most like have a reflexive quality. Dan Chudnov, for example, is admirably succinct and direct:
> My professional mission as a librarian is this:
> **Help people build their own libraries.**
> That’s it. That’s all I care about. // [One big library](https://onebiglibrary.net/story/because-this-is-the-business-weve-chosen?ref=lorcandempsey.net)
This is from 2006\. Interestingly, in the interim we have seen big growth in the personal ‘library’ – think of Mendeley or Goodreads for example.
Here are two from very different writers, each expressing the generative capacity of the library in a very pithy way …
> People should think not so much of the books that have gone into the National Library but rather of the books that have come out of it. A library, after all, feeds the people that go in there. // Quoted in [Kissane, Noel. 1994\. Treasures from the National Library of Ireland. \[Drogheda\]: The Boyne Valley Honey Co](https://www.worldcat.org/oclc/807065234?ref=lorcandempsey.net).
This is Irish writer Seán O’Faoláin and the library he talks about is the National Library of Ireland.
The second is Daniel Dennett’s oft-noted …
> A scholar is just a library’s way of making another library. // [Memes and the exploitation of imagination](https://ase.tufts.edu/cogstud/papers/memeimag.htm?ref=lorcandempsey.net)
Now, Dennett’s remarks are in the context of Richard Dawkins’ argument about how memes mirror the behavior of genes, ” just different kinds of replicators evolving in different media at different rates”. While he wants to argue that this is a good way of thinking about ideas, he acknowledges that it is unsettling, “even appalling”: “….I am not initially attracted by the idea of my brain as a sort of dungheap in which the larvae of other people’s ideas renew themselves, before sending out copies of themselves in an informational Diaspora”.
I like the way each of these emphasises the role of the library in a cycle of creation and recreation. The library is not an end in itself but an institution which helps create new knowledge.
## Evidence, argument and agenda
And finally, here are another two which come at a similar idea from different perspectives …
First, Ross Atkinson, a refreshingly cerebral librarian, has written:
> Because the purpose and result of absorbing information is always finally to produce further information, i.e., to continue the conversation, the function of the library must be understood as one that assists members of the community both in taking particular positions and in recognizing and assessing the positions taken by others. // Contingency and contradiction: The place(s) of the library at the dawn of the new millennium. *Journal of the American Society for Information Science and Technology*, Volume 52, Issue 1, Pages 3-11.
The opening here echoes the generative theme of the last two. But what drew me to this was the latter part, which emphasises the library’s role in providing the material and evidential base for debate and enquiry.
This leads directly into what is for me the most affecting of these accounts, coming from Irish writer and journalist, Fintan O’Toole. He is writing about public libraries in Dublin, libraries which I also heavily used and later worked in for a while.
> The library should not provide an argument for a particular case, but demonstrate that there is always another case to be made. The notion that the library is a place that has no agenda other than allowing people to invent their own agendas is what makes it an indispensable resource for a democracy. It is where we can learn not just to be readers, but to be the authors of our own destiny. // Reading, writing and rebelling : growing up with public libraries in: [The university of the people : celebrating Ireland’s public libraries](https://www.worldcat.org/oclc/57235376?ref=lorcandempsey.net)
O’Toole’s essay is a marvellous tribute to public libraries. It does not appear to be available online, but I quoted from it at length [here](https://blog.oclc.org/lorcand/archives/000624.html?ref=lorcandempsey.net).
‘Agenda’ may be a more loaded word than Atkinson’s ‘position’ but I immediately associated the two in my mind. The idea that a library is a place which “has no agenda other than allowing people to invent their own agendas” resonates strongly. Of course, to achieve this goal, libraries do indeed have to have an agenda.
**Picture:** I took the feature picture of Ballyroan public public library. Ballyroan is a Dublin suburb.
**Note:** Cosmetic stylistic updates on transition to new platform, 28 March 2021, including addition of feature picture and headings.
### Twit-therapy .. a quick note
URL: https://www.lorcandempsey.net/twit-therapy-a-quick-note/
Last updated: 2020-10-28T09:04:12.000Z
I am reading *Bedsit Disco Queen: how I grew up and tried to be a pop star*, a memoir by [Tracey Thorn](https://www.traceythorn.com/?ref=lorcandempsey.net). Here is a quick note to record what I thought was an interesting discussion about Twitter.
Thorn writes about frustration with record company and producer, and goes on to say …
> If I had a time machine and could go back in it, to this particular point, where the self-doubt and anxiety was beginning to set in and it felt like the walls were closing around us. I know exactly what I would do. I would invent Twitter.
> I firmly believe that Twitter might have been my salvation. For instance, I could have come home from that depressing meeting at the record-company office and tweeted about it and got it off my chest, and you would all have tweeted back at me with supportive comments, witty put-downs and descriptions of similar experiences in your own workplace. We would have bonded over it , and I would have felt less alone and more like there were people out there who understood what I was on about and wanted me to keep going on about it. Just laughing about it would have defused its corrosive potential. Twitter is the arena in which we share all the shit, and laughing it off, and are made stronger. …. \[[Bedsit Disco Queen](https://www.goodreads.com/book/show/16128925-bedsit-disco-queen?ref=lorcandempsey.net), p.194\]
p.s. I am reading it in hardback as it is a book I would like to own and keep. And yes, as [I discussed the other day](https://blog.oclc.org/lorcand/archives/002203.html?ref=lorcandempsey.net), I do miss being able to highlight.
p.p.s. I am surprised they kept ‘bedsit’ in the title for a US audience.
The big hit on Jools ….
Related entry:
- [A note about Tracey Thorn](https://blog.oclc.org/lorcand/archives/002096.html?ref=lorcandempsey.net) …
### A fragmented reading experience: locally and anecdotally speaking ..
URL: https://www.lorcandempsey.net/a-fragmented-reading-experience-locally-and-anecdotally-speaking/
Last updated: 2021-06-08T00:30:22.000Z
## Growing fragmentation
In February 2011 I noted …
> A while ago I was interested to observe that I had begun to resist buying paperback novels. … In thinking about it, I realised that I only wanted to buy the experience not the physical item. My bag and our house is already cluttered enough. I wanted the few hours entertainment the book provided, not the small burden of owning a bundle of paper to be shelved. // [Buying books and/or experiences: a consumer view](https://blog.oclc.org/lorcand/archives/002158.html?ref=lorcandempsey.net)
In other cases I still wanted to buy a physical item.
In the interim, the reconfiguration of publishing by the network continues. We are even more aware of the staggering impact of Amazon on the book industry, questions about the future of print ‘n mortar stores are more stark, there is consolidation among publishers, publishing and reading options proliferate.
While I am professionally aware day to day of that background, I have been interested in how my reading behaviors continue to shift. The pull of digital is stronger. The benefits of portability, availability, and search weigh heavier. However, my reading has become fragmented in ways that complicate my life as a consumer.
It is fragmented in terms of actual reading experience (Kindle vs print vs other). It is fragmented in terms of collection, where what is on my shelves is joined by what is on my Kindle (in its various manifestations), or elsewhere. It is fragmented in terms of discoverability (store vs website). I often have to chose between grades of experience, and the choices involve tradeoffs (portability vs aesthetics, for example).
Of course, it is also fragmented in terms of ownership, where my ability to resell, share or move an ebook is limited in various ways. This is a major issue, although it is not my main focus here.
Here are some rather ordinary anecdotal examples …..
## Anecdote 1: highlighting
I was in the [Acorn Bookshop](https://www.acornbookshop.com/?ref=lorcandempsey.net), a used bookstore in Grandview, Ohio, a while ago (which incidentally, is the bookstore which features in the movie, [Liberal Arts](https://acornbookshop.com/Acorn%5FLibartsMovie.html?ref=lorcandempsey.net)). I was pleased to find a [Nicholas Blake](https://www.worldcat.org/wcidentities/lccn-n90-609288?ref=lorcandempsey.net) novel, *[End of Chapter](https://www.worldcat.org/oclc/1233501?ref=lorcandempsey.net)*. Blake is the name under which [Cecil Day Lewis](https://www.worldcat.org/wcidentities/lccn-n80-67088?ref=lorcandempsey.net), poet and father of Daniel, wrote mystery novels. I have wanted to read one of his novels for years, without having been quite motivated enough to go out and get one (he does not figure in the catalog of the Columbus Metropolitan Library). Coincidentally, I was able to buy another couple of Blake novels in Caveat Emptor Books on a trip to Bloomington, Indiana, around the same time.
*[End of Chapter](https://www.worldcat.org/oclc/1233501?ref=lorcandempsey.net)* is set in a publishing house, and, as one might expect, is quite a nice read in a somewhat old-fashioned way. This meant that as I read I kept wanting to highlight sentences for saving to my Kindle space. Not being able to do so created a nagging friction as I read, which is a typical reaction now when I read an interesting book in print. I would always have been an inveterate maker of marginal pencil marks. Even if I rarely went back to them, they were there for future reference … just in case. I now want to save highlights as I read.
This requirement has also made cross-platform differences in the Kindle app a frustration. For a while highlighting was not possible in Cloud Reader, though it now is. The major issue I have with my Windows Phone – with which otherwise I am very happy – is that the Kindle app does not allow me to highlight text. This means that I don’t read books during those [interstitial reading moments](https://blog.oclc.org/lorcand/archives/002081.html?ref=lorcandempsey.net) on the phone. I can’t bring myself to read an e-book which does not have the highlighting option.
And highlighting is important – see Steven Johnson’s interesting post from which this line jumped out …
> This ability to capture important clips in real-time as I’m reading a book has probably been the single most important advance in my reading life since the Web came along. // [Your outboard memory](https://medium.com/the-writers-room/bcf82e3cc73?ref=lorcandempsey.net)
## Anecdote 2: choosing between benefits
I was going to buy *[Ambiguous Republic: Ireland in the 1970s](https://www.amazon.com/Ambiguous-Republic-Ireland-1970s-ebook/dp/B009M5SPYM/ref=sr%5F1%5F5?s=books&ie=UTF8&qid=1361894673&sr=1-5&ref=lorcandempsey.net)* by Diarmaid Ferriter when it came out last year. Although it is a bit dispiriting to realise that you are now old enough that the period in which you grew up is the topic of a major historical work. However, do I go with hardback or Kindle?
I want the benefits of the digital, but there are also some pleasures of ownership associated with a physical book like this. These don’t really have an analog in the current e-book environment. This pleasure is also in contrast to the poverty of the Kindle collection experience. It is unclear to me why they do not do a better job of allowing you to manage collections in a congenial way – this seems like a big miss, but presumably their data shows that this is not a big enough requirement to push aside other development needs? I am sure this will get better in the future.
I would certainly lightly annotate a paper version of a book like this, but as I say above I would prefer to keep those passages online now.
A couple of times I have expressed frustration on Twitter or Facebook about having to chose in this way, and in each case somebody responded with the example of music, where, if you buy Vinyl you can also download MP3s. I would be willing to pay extra to get digital and print for some types of books, ones like this one. This point was also made by Nicholas Carr …
> There’s a lesson here, I think, for book publishers. Readers today are forced to choose between buying a physical book or an ebook, but a lot of them would really like to have both on hand – so they’d be able, for instance, to curl up with the print edition while at home (and keep it on their shelves) but also be able to load the ebook onto their e-reader when they go on a trip. In fact, bundling a free electronic copy with a physical product would have a much bigger impact in the book business than in the music business. After all, in order to play vinyl you have to buy a turntable, and most people aren’t going to do that. So vinyl may be a bright spot for record companies, but it’s not likely to become an enormous bright spot. The only technology you need to read a print book is the eyes you were born with, and print continues, for the moment, to be the leading format for books. If you start giving away downloads with print copies, you shake things up in a pretty big way. // [Rough Type](https://www.roughtype.com/?p=1573&ref=lorcandempsey.net)
It seems unlikely that an e-version would be available with the hardback without some price increase. But I probably would not pay the premium that you pay for vinyl. I do not know what price point would persuade me, but I would certainly pay more. I now have several books where I have bought both print and e versions.
My indecision meant I did not buy the Ferriter book when I first saw it – I did not know which way to go. As I write this, however, I went back and bought the hardback. Although, when I get around to reading it, I know that I will be thinking of how I miss the digital highlighting feature 🙂 And I definitely won’t be reading it on a plane, as I won’t want to carry a book of this size around with me.
## Anecdote 3: borrowing
I bought [Information wants to be shared](https://www.amazon.com/Information-Wants-Be-Shared-ebook/dp/B009G1WCGO?ref=lorcandempsey.net) by [Joshua Gans](https://www.worldcat.org/wcidentities/lccn-n99-280635?ref=lorcandempsey.net) last year. I bought it on the basis of a [blog entry](https://memex.naughtons.org/archives/2012/10/03/17200?ref=lorcandempsey.net) by John Naughton, who bought it on the basis of the Amazon abstract. On Amazon.com, it appears to be only available as an ebook. Now, normally for this type of item – which I would like to read, but not necessarily buy – I would suggest to the very fine folks at the OCLC Library that they acquire it. However, acquiring an ebook for lending from Amazon is not an option. So, as it was just $4.99, I went ahead and bought it. This touches on major policy and business issues, but as a consumer it is a way in which previous behaviors don’t map onto current options.
Of course, these may be the ‘morbid symptoms’ that accompany transition between orders. And we will always have choices. I just hope we have some better ones soon … as the reconfiguration continues.
**Picture:** I took the picture of the book in the feature image recently. It was so nice I had to buy it, whether or not I end up reading it.
**Note:** Cosmetic amendments made 31 Mary 2021, including addition of image, spacing and headings.
### Systemwide organization - sourcing and scaling redux
URL: https://www.lorcandempsey.net/systemwide-organization-sourcing-and-scaling-redux/
Last updated: 2021-06-07T23:49:10.000Z
## A systemwide perspective
Think of the close collaboration within the Orbis Cascade Alliance for example, where academic libraries in Washington and Oregon are moving to a shared systems infrastructure. Or think of the various initiatives looking at managing down individual print collections within a coordinated collective framework, WEST, for example. Or think of collaboratively sourced initiatives to tackle new service areas, Hathi Trust for example.
Of course, in many countries there are publicly funded bodies who are charged with managing shared services, development work, or community R&D. Think of how union catalogs or license negotiations are provided in many countries, or the role in national provision of some national libraries, or the national work of educational organizations like JISC in the UK.
At the same time, libraries are looking to simplify their infrastructure requirements through cloud-based approaches. Think of the wide deployment of Libguides for example, or of the growing adoption of discovery layer products, or of the move to cloud based systems infrastructure (resolver, ILS).
In each of these cases, libraries are looking at different models of sourcing their needs – collaborative, public, and third party respectively. They are also looking at doing things at different scales – shared with a group (e.g. Orbis Cascade Alliance), at national or regional level (e.g. Libraries Australia), or working with a supplier at the institutional level (e.g. cloud-based discovery layers). Sourcing and scaling now pose interesting policy and service questions across library services.
Recognizing the importance of these questions, OCLC Research has organized some of our activity in a new program area to address them: [system-wide organization](https://www.oclc.org/research/activities/swo.html?ref=lorcandempsey.net). Our early work in this area has focused on the [collective print collection](https://www.oclc.org/nextspace/012/research.htm?ref=lorcandempsey.net), mining our data to provide community intelligence to support decisions about the future configuration of print collections. The influential “Cloud Library” report ([Cloud-sourcing Research Collections](https://www.oclc.org/research/news/2011/01-06.html?ref=lorcandempsey.net)) provided a framing context for this work, and was followed up more recently with [Print Management at ‘Mega-scale’](https://www.oclc.org/research/publications/library/2012/2012-05r.html?ref=lorcandempsey.net), which is the first study of its kind, showing the geographic concentrations of collections. This work has been very purposefully connected with policy and organizational issues and we work closely with most of the major initiatives tackling this question. We have also carried out the largest study of circulation data to date, the [OhioLINK Collection and Circulation Analysis](https://www.oclc.org/research/activities/ohiolink.html?ref=lorcandempsey.net), and are preparing a synthesis of those findings.
Another strand of current activity is exploring through Worldcat how national literatures are represented in the global library resource, and a case study will be published soon. This focus continues our earlier work on mining Worldcat to reveal characteristics of the collective library collection (see for example our original [analysis](https://www.dlib.org/dlib/september05/lavoie/09lavoie.html?ref=lorcandempsey.net) of the collections in libraries working with Google on digitization, or our [analysis](https://www.dlib.org/dlib/november09/lavoie/11lavoie.html?ref=lorcandempsey.net) of the aggregate print book resource likely in copyright).
While early work has focused on applying data analysis to policy and service questions, we are now working with individual libraries to think about the wider context of sourcing and scaling across the breadth of their work. Here is how we describe it on the theme’s web pages:
> System-wide organization explores the shift from local provisioning of library collections and services to increased reliance on cooperative infrastructure, collective collections, shared technology platforms, and “above-the-institution” management strategies. At the same time, we examine the array of collections and services that are best provided at the level of the local institution. Our research agenda in system-wide organization aims to improve our understanding of the factors that guide institutions in their sourcing and scaling choices as they seek maximum impact and efficient provision of library collections and services.
Libraries are embarked on a shift to greater engagement with the research, learning and development lives of their users, and reconfiguring space, services, expertise and infrastructure to facilitate this. Our agenda is being designed to provide examples and research findings which assist in this shift.
## Further Information:
### Reports and articles
1. Constance Malpas. [Cloud-sourcing Research Collections: Managing Print in the Mass-digitized Library Environment](https://www.lorcandempsey.net/research/news/2011/01-06.html)
2. Constance Malpas, Brian Lavoie and JD Shipengrover. [Print Management at ‘Mega-scale’: a Regional Perspective on Print Book Collections in North America](https://www.lorcandempsey.net/research/publications/library/2012/2012-05r.html)
3. Brian Lavoie and Lorcan Dempsey. [Beyond 1923: Characteristics of Potentially In-copyright Print Books in Library Collections](https://www.dlib.org/dlib/november09/lavoie/11lavoie.html?ref=lorcandempsey.net)
4. Brian Lavoie, Lynn Silipigni Connaway, and Lorcan Dempsey. [Anatomy of Aggregate Collections: The Example of Google Print for Libraries](https://www.dlib.org/dlib/september05/lavoie/09lavoie.html?ref=lorcandempsey.net)
### Blog entries
1. [Sourcing and scaling](https://blog.oclc.org/lorcand/archives/002058.html?ref=lorcandempsey.net)
2. [Untangling the library systems environment](https://blog.oclc.org/lorcand/archives/002015.html?ref=lorcandempsey.net) (see discussion of scalar emphasis)
3. [Sourcing and scaling: the University of California](https://blog.oclc.org/lorcand/archives/002175.html?ref=lorcandempsey.net)
### OCLC Research Activity Pages
1. [System-wide Organization](https://www.oclc.org/research/activities/swo.html?ref=lorcandempsey.net)
2. [Managing the Collective Collection](https://www.oclc.org/nextspace/012/research.htm?ref=lorcandempsey.net)
3. [OhioLINK Collection and Circulation Analysis](https://www.oclc.org/research/activities/ohiolink.html?ref=lorcandempsey.net)
**Note:** This entry adapts the introductory message in the [OCLC Research Quarterly Highlights, Issue 7, October-December 2012.](https://www.oclc.org/research/publications/newsletters/quarterlyhighlights/2012-13q2.html?ref=lorcandempsey.net)
**Picture:** I took the feature picture in Seattle, home to several Orbis Cascade Alliance members.
**Note:** Cosmetic updates on 29 April 2021 to add headings and feature picture.
### Discovery vs discoverability ...
URL: https://www.lorcandempsey.net/discovery-vs-discoverability/
Last updated: 2022-11-07T14:46:07.000Z
## Inside-out and outside-in: libraries, collections, services
I have been interested in the different dynamics of the **inside-out** and **outside-in** library for a while (see [here](https://www.liberquarterly.eu/articles/10.18352/lq.10170/?ref=lorcandempsey.net) for example). One especially interesting characteristic is the quite different approach to discovery in each case, even though this distinction has not yet crystallized in clear service categories.
I was struck by the distinction during a recent discussion of ‘discoverability’ in a publishing context, where the focus was on the active marketing of resources through a variety of channels. This is an emphasis that has not been common in a library environment, but, which, I argue here, is becoming more important. It is not enough simply to make resources available on the network; more active promotion is required if they are to be discovered.
What do I mean by **outside-in** and **inside-out**?
Throughout much of their existence, libraries have managed an **outside-in** range of resources: they have acquired books, journals, databases, and other materials from external sources and provided discovery systems for their local constituency over what they own or license. They aggregated scarce materials, services, and expertise close to their users. They provided a local gateway which was central to many of their users’ information lives.
The discovery focus was very much on improving a set of well-known systems that provide access to the collection (acknowledging that the library had in fact little direct influence over how access to the journal literature was presented). And this remains the main focus. This discovery apparatus has evolved, and now comprises catalog, A to Z lists, resource guides, maybe a discovery layer product, and other services. ‘Discoverability’ might be interpreted in the context of how well those systems served their users.
## Network shifts
However, in a digital and network world, there have been two major changes, which shift the focus towards **inside-out**.
First, access and discovery have now scaled to the level of the network: they are web scale. If I want to know if a particular book exists I may look in Google Book Search or in Amazon, or in a social reading site, in a library aggregation like Worldcat, and so on. My options have multiplied and the breadth of interest of the local gateway is diminished: it provides access only to a part of what I am potentially interested in. As research and learning information resources have become abundant in this environment, the library collection and its discovery systems are no longer the necessary gateway for library users. While much of the discovery focus of the library is still on those destination or gateway systems which provide access to its collection, much of their users’ discovery experience is in fact happening elsewhere.
Second, the institution is also a producer of a range of information resources: digitized images or special collections, learning and research materials, research data, administrative records (website, prospectuses, etc.), faculty expertise and profile data, and so on. How effectively to disclose this material is of growing interest across libraries or across the institutions of which the library is a part. This presents an **inside-out** challenge, as here the library wants the material to be discovered by their own constituency but usually also by a general web population.
These factors shift the discoverability challenge significantly. The challenge is not now only to improve local systems, it is to make library resources discoverable in **other** venues and systems, in the places where their users are having their discovery experiences.These include Google Scholar or Google Books, for example, or Goodreads, or Mendeley, or Amazon. It is also to promote institutionally created and managed resources to others. This involves more active engagement across a range of channels.
Think of a couple of obvious examples. Libraries have worked to make their knowledge bases visible to Google Scholar because they want to link available library resources to their users’ discovery experience. They want to make their resources discoverable in Scholar. Users should be able to access a copy of a resource the library has acquired wherever the discovery takes place. In fact, having an institutional resolver work with a variety of services (e.g. Mendeley, Pubmed Central) is increasingly important, and it would be very interesting to see some research which shows the balance between internally and externally generated resolver traffic across a group of libraries. Anecdotal evidence suggests the growing importance of external sources.
Second, think of the recurrent discussion about the discoverability of institutional repository resources in Google and what steps should be taken to improve it (see for example the work by Kenning Arlitsch and colleagues \[[pdf](https://www.oclc.org/resources/research/events/20120316seo.pdf?ref=lorcandempsey.net)\]).
## Inside-out: approaches
We have not yet seen clear integrated library strategies emerge for the inside-out case, but various approaches have emerged ….
- Collection-specific interpretation and promotion through social media or other targeted activity – see [here](https://pinterest.com/lorcand/librarians-talking-about-collections-they-love/?ref=lorcandempsey.net) for some blogs about special collections and archives, for example.
- Syndication. While this term may not be generally understood I use it here to cover the idea of placing links, metadata or services in the flow of potential users. Syndication is a major activity of OCLC as Worldcat enables linking, for example, between Google Books and other services and individual library collections.
- Links. Adding links for relevant resources to Wikipedia, for example. Or to course pages, etc.
- Metadata. Providing metadata about collections to relevant aggregations (the University of Minnesota ‘discoverability’ [reports](https://conservancy.umn.edu/handle/48258?ref=lorcandempsey.net) do an interesting analysis of aggregations relevant to their collections). Adding RSS feeds where appropriate.
- Services. Adding ‘share’ buttons to resouces (to facilitate tweeting, pinning, etc). Creating widgets, mobile apps, toolbars, … In some cases, providing protocol level access to resources.
- Search engine optimization. Working to ensure that crawling and indexing are as efficient as they can be. SEO is, effectively, promoting interoperability with search engines through use of good practices.
There is growing interest in connecting the library’s collections to external discovery environments so that the value of the library investment is actually released for those for whom it was made. There is also now a parallel interest in making institutional resources (research and learning materials, digitized special materials, faculty expertise, etc) more actively discoverable. In each case, there is a shift towards inside-out thinking, as the library thinks about promotion and visibility in external services. In our network environment, it is clear that ‘discoverability’ involves an array of changing, tactical responses, working across a range of services and approaches. This active attention will become a stronger focus for libraries.
Related:
- Lorcan Dempsey. [Thirteen Ways of Looking at Libraries, Discovery, and the Catalog: Scale, Workflow, Attention.](https://www.educause.edu/ero/article/thirteen-ways-looking-libraries-discovery-and-catalog-scale-workflow-attention?ref=lorcandempsey.net) Educause Review Online, December 10, 2012.
- [Outside-in and inside-out redux](https://blog.oclc.org/lorcand/archives/002102.html?ref=lorcandempsey.net)
- [Discoverability – a report that’s worth a look](https://blog.oclc.org/lorcand/archives/002012.html?ref=lorcandempsey.net)
**Picture:** I took the feature picture in Whetstone Park of Roses, Columbus. Europeana is a European aggregation of metadata about digital materials.
**Note:** This entry has been cosmetically amended on 28 March 2021 to include feature picture and headings, and to adjust spacing.
### The President, the election and big data
URL: https://www.lorcandempsey.net/the-president-the-election-and-big-data/
Last updated: 2021-03-27T19:46:22.000Z
A little over four years ago I wrote a post about the presidential primary results, suggesting that an important political threshold had been crossed. The network – and notably the use of social and mobile – was centrally influential.
> Whatever your political orientation, it is clear that Obama has been remarkably successful at mobilizing people and money through the network. …. the combination of social networking techniques and the diffusion of connectivity through mobile and other devices have allowed Obama’s campaign to scale very effectively, both in terms of numbers participating and amount of funds raised. \[[Candidate 2.0 and crowdfunding](https://blog.oclc.org/lorcand/archives/001639.html?ref=lorcandempsey.net)\]
This year, we may have seen yet another important threshold crossed – as the data-driven campaign has been ushered in. [Big data](https://blog.oclc.org/lorcand/archives/002196.html?ref=lorcandempsey.net) has come to the election.The Obama campaign approach is described in the [widely observed article](https://swampland.time.com/2012/11/07/inside-the-secret-world-of-quants-and-data-crunchers-who-helped-obama-win/?ref=lorcandempsey.net) by Michael Scherer in *Time Magazine*. He describes a ‘metric driven campaign’ managed by a highly secretive analytics department.
> The “scientists” created regular briefings on their work for the President and top aides in the White House’s Roosevelt Room, but public details were in short supply as the campaign guarded what it believed to be its biggest institutional advantage over Mitt Romney’s campaign: its data. \[[Inside the Secret World of the Data Crunchers Who Helped Obama Win](https://swampland.time.com/2012/11/07/inside-the-secret-world-of-quants-and-data-crunchers-who-helped-obama-win/?ref=lorcandempsey.net)\]
The article describes how the team analysed data to identify donors, voters and efficient ad placements. Patterns in the data influenced which celebrities were asked to address which audiences and persuaded Obama to answer questions on Reddit.
> That data-driven decisionmaking played a huge role in creating a second term for the 44th President and will be one of the more closely studied elements of the 2012 cycle. It’s another sign that the role of the campaign pros in Washington who make decisions on hunches and experience is rapidly dwindling, being replaced by the work of quants and computer coders who can crack massive data sets for insight. As one official put it, the time of “guys sitting in a back room smoking cigars, saying ‘We always buy 60 Minutes'” is over. In politics, the era of big data has arrived. \[[Inside the Secret World of the Data Crunchers Who Helped Obama Win](https://swampland.time.com/2012/11/07/inside-the-secret-world-of-quants-and-data-crunchers-who-helped-obama-win/?ref=lorcandempsey.net)\]
Analytics is now a major activity, as transaction or ‘intentional’ data is aggregated and mined for insight …. and the Obama campaign appears to have relied heavily on ‘campaign analytics’. Having collected a lot of data they used it as a strategic resource. One side-effect is to further embed the importance of quantitative methods in the popular consciousness. Increasingly, as we yield up data in more of our interactions it is mined to predict behaviors, to adapt systems, to improve services. Pandora, as I note in the blog entry above, does our listening for us.
As more material is digital, as more business processes are automated, and as more activities shed usage data, organizations are manipulating larger amounts of relatively unstructured data and extracting value from it. We have become used to recommendations based on buying or navigation patterns. Within the library field, patterns of download, holdings or resolution are being mined to improve services. We are seeing the emergence of predictive analytics in education. Altmetrics based on user behaviors of various types are a topic of rich discussion. We are collecting data and making it work harder everywhere ….Coda: John Naughton has a [nice column](https://www.guardian.co.uk/technology/2012/nov/11/obama-data-voter-statistics-victory?ref=lorcandempsey.net) on the importance of data for the campaign and more generally.
Related entries:
- [Big data .. big trend](https://blog.oclc.org/lorcand/archives/002196.html?ref=lorcandempsey.net)
- [Candidate 2.0 and crowd-funding](https://blog.oclc.org/lorcand/archives/001639.html?ref=lorcandempsey.net)
- [Libraries and the Informational Future: Some Notes](https://www.oclc.org/research/news/2012/10-11.html?ref=lorcandempsey.net)
Note: updated 11/12/12
### Two things prompted by a new website: space as a service and full library discovery
URL: https://www.lorcandempsey.net/two-things-prompted-by-a-new-website-space-as-a-service-and-full-library-discovery/
Last updated: 2022-12-31T22:01:07.000Z
Drawn by a Tweet I looked at [Stanford's very nice new library website](https://library.stanford.edu/?ref=lorcandempsey.net) just now. I only spent a few minutes there but I was immediately and strongly struck by two things. Each makes so much sense that I imagine they will become routine.
The first was the foregrounding of **library space as a service**. The second was what I might call **full library discovery**, the ability to **discover the full capacity of the library**, not just the collections, with a single search.
## Library space as a service
A shift is underway in library space, from being configured around collections to being configured around research, learning and related social behaviors. In this way, space is an important aspect of how a library engages with its users; it is a service in itself, not only part of the infrastructure to manage collections.
This is recognized here in that two of the elements in the nice central navigation strip are about space, *Library hours* and *Places to study*.
[](https://library.stanford.edu/?ref=lorcandempsey.net)
If you look at *Library* hours, it tells you what is open **now**, as you look at it. It is not just a static list of times and locations.
If you look at the *Places to study* tab it opens out interestingly to allow you to filter by your requirement – for individual study, for quiet, for group study, for particular facilities, and so on.
[](https://library.stanford.edu/?ref=lorcandempsey.net)
## From full collection to full library discovery
There has been a major focus on integrated discovery services in recent years, with the model of a cloud-based, central index over catalog, article and related data becoming common. The goal has been ‘full collection discovery’ delivered in a single search box.
We are now seeing an extension of this ambition to cover ‘full library’ discovery where services, staff profiles and expertise, or other aspects of library provision are made discoverable alongside, and in the same search environment, as the collections.
I have [written before](https://blog.oclc.org/lorcand/archives/002007.html?ref=lorcandempsey.net) about the University of Michigan site, which is a good example. It works well to project the library on the web as a unified service. A central part of this is the integrated search over collections, library website, LibGuides and library staff profiles. The return of relevant subject specialists which match the query in a separate results pane is particularly interesting. And is in line with [my view](https://blog.oclc.org/lorcand/archives/002086.html?ref=lorcandempsey.net) that if libraries wish to be seen as expert, then their expertise must be visible.
The Stanford site offers a *Search everything* tab, with this amplifying tagline: *“Not sure where to start? Try this.”*. What I like about it is that the examples searches shown emphasise the ‘full library’ aspect of what is on offer here: they are very deliberately pitching this at a broader level than books and articles. The example searches are *‘renew books, dissertations, feminist studies, worldcat’*: they are about questions people may have when they come to the library website, not only about items they might find in the collection.
Now, in practice results work better sometimes than others, but the general principle is good and you can see how it can be improved over time. In an accompanying [blog description](https://chrisbourg.wordpress.com/2012/08/28/awesome-library-website-pt-3-lift-off/?ref=lorcandempsey.net), Chris Bourg repeats [Feminist studies](https://library.stanford.edu/search/all?search=feminist%20studies&ref=lorcandempsey.net) as an example. Note the the staff profile pages returned in the library website search.
[](https://library.stanford.edu/search/all?search=feminist%20studies&ref=lorcandempsey.net)
As libraries move in this direction, several trends are apparent. One is the use of Drupal, Blacklight and other ‘container’ frameworks to deliver unified services. A second is a rethinking of how services, staff profiles and expertise, and other library activities are represented and indexed. The increased use of resource guides – in many cases Libguides – is one aspect of this, in particular as they are used as a simple content management framework for various type of information about the library, and not only for lists of information resources. Another is the ‘[Bento box](https://www.twylah.com/lorcanD/topics/bento?ref=lorcandempsey.net)‘ style results, as not only may it be difficult or confusing to rank results across different types of resources, but a tabular presentation like this may make more sense to users.
For more information about Stanford design decisions and ambitions see the justifiably proud [blog entries](https://chrisbourg.wordpress.com/2012/08/28/awesome-library-website-pt-3-lift-off/?ref=lorcandempsey.net) by Chris Bourg.
**Related entries:**
- [3 stages of library web-sites …](https://blog.oclc.org/lorcand/archives/002129.html?ref=lorcandempsey.net)
- [The library website: a unified service?](https://blog.oclc.org/lorcand/archives/002007.html?ref=lorcandempsey.net)
- [Discovery layers – Top Tech Trends 2](https://blog.oclc.org/lorcand/archives/002116.html?ref=lorcandempsey.net)
- [A web-siting at the University of Michigan](https://blog.oclc.org/lorcand/archives/001985.html?ref=lorcandempsey.net)
- [People are entry points too … redux](https://blog.oclc.org/lorcand/archives/002086.html?ref=lorcandempsey.net)
### The enterprising librarian ...
URL: https://www.lorcandempsey.net/the-enterprising-librarian/
Last updated: 2022-11-14T05:05:10.000Z
## The entrepreneur
I participated in an [interesting event](https://sils.unc.edu/events/2012/ip2050?ref=lorcandempsey.net) at the School of Information and Library Science at UNC a while ago. It was a symposium to consider the ‘information professional’ of 2050\. Yes, that is 2050 🙂 There was a mix of people. Some in LIS education; some in libraries; and some in industry.
One word that was used a lot was ‘entrepreneur’. It was used in two related ways. First was entrepreneur with a big ‘E’, where schools are preparing people with the skills and outlook to found or go into startups. Second was entrepreneur with a little ‘e’, where schools are preparing people to work flexibly in dynamic environments which value enterprise.
I was interested in this theme as it chimed with a quote from Manuel Castells I had used in my written submission to the Symposium (these will be published later in the year). My focus was on libraries, not on the broader information field. Here is the Castells quote …
> In a dynamic, evolutionary perspective there is a fundamental difference between two types of organizations: organizations for which the reproduction of their system of means becomes their main organizational goal; and organizations in which goals, and the change of goals, shape and endlessly reshape the structure of means. I call the first type of organizations bureaucracies; the second type, enterprises. // Castells, Manuel. *The Rise of the Network Society*. Malden, MA: Wiley-Blackwell, 2010\. Print.
This is quite dense, and needs to be unpicked a little in relation to libraries. Historically, libraries enjoyed stability and a shared understanding of goals. This in turn favored a focus on managing and improving the means towards those goals – building the collection, providing reference service, creating efficiencies in technical processing, and so on. This was the focus of professional practice and education. Much of this work is inherently bureaucratic. However, in an environment of change while overall mission and values may remain the same, new and shifting goals become the norm. Think of greater integration in the learning and research process through greater curriculum support, data curation, scholarly publishing, or support for grant writing or expertise profiles. Think of network based reading services, or jobseeking and homework support. As goals shift in a changing environment, so does the need to think about how to marshall the means to meet them. This may need reorganization, new staff skills, changing priorities, reallocation of staff and resources, and so on. It requires a shift from bureaucracy to enterprise, an adaptive organization that reviews and reshapes what it does in light of changing requirements.
## The enterprising librarian
Now, just after I had written my submission I came across an interesting looking book by Bethan Ruddock: [The new professional’s toolkit](https://www.worldcat.org/oclc/758076068). I was very taken with the table of contents and the OCLC Library kindly acquired a copy for me. Here is the table of contents:
- 1\. Project management
- 2\. Teaching, training & communicating
- 3\. Meeting your users needs and measuring success
- 4\. Marketing your service and engaging stakeholders
- 5\. Using technologies
- 6\. Getting and staying online
- 7\. Generating funding and doing more with less
- 8\. Managing money – budgets & negotiating
- 9\. Information ethics and copyright
- 10\. Up-skilling and professional development
- 11\. Networking and promoting yourself
- 12\. Professional involvement & career development
Each chapter includes practioner case studies, some from her colleagues at Manchester. Readers will find [some familiar names](https://lisnewprofs.com/contributors/?ref=lorcandempsey.net) there, including for example Amanda Hill, Bohyun Kim, Lukas Koster, Jenica Rogers. An [expanded table of contents](https://lisnewprofs.com/table-of-contents/?ref=lorcandempsey.net) with links to some of the case studies is on the book blog. I paste in the fuller list at the end of this entry for reference. Now, Bethan talks about information professionals broadly in the preface but this looks like a publisher-encouraged widening of focus (I may be wrong :-). In the Introduction, she notes it is aimed at librarians and archivists.
What struck me immediately about this list was how the focus was very much on generic skills applied in a library or archival context. And those skills are very much about managing an enterprise: many are explicitly about managing in a changing environment. Importantly, much of the material is about **positioning** oneself or one’s organization in relation to other players, a theme that becomes more important in dynamic environments of multiple stakeholders. So, for example, there is material about budgets; but there is also material about negotiating, about raising money from other sources, about demonstrating value. There is little material here about management as such, which surely would have featured in an equivalent volume some years ago, but there is material on managing projects, on training and communication, and on assessing needs and evaluating services. There is also a strong emphasis on personal skills and positioning, with discussions of personal branding in a networked environment, skills development, and professional involvement. It is taken for granted that communication, marketing, assessment, promotion and brand management are central activities for the organization and the individual. For example …
> It is not just your organization and services that need promoting: you also need to promote yourself and for many of the same reasons. This isn’t about boasting about how great you are, but about making people aware of of your unique skills and expertise, so they can call on them as necessary.
> Just as your users won’t know how your service can help them unless you specifically tell them, people won’t know what you personally have to offer unless you make it obvious. In the workplace, you as a peson can inspire trust and reliance in a way that your library or archive as a service can never do. Your users are much more likely to connect with your pesonal expertise: ‘The information service can do that. I read it on a leaflet’ is a much less powerful message than: ‘Bethan can do that. She was talking to me about it last week.’ Your knowledge, expertise and personal skills can be a very valuable asset to your organization.
This echoed a comment I have been using in presentations recently: “if the library wishes to be seen as expert, its expertise must be visible”.
The book does focus on the individual rather than the organization, so the technology chapters, for example, are somewhat impressionistic, but they do hand off to interesting and informative case studies. And one can look elsewhere for the detail.
This ‘toolkit’ covers some of what I took to be entrepreneurial skills. Or in language I prefer in this context, it covers some of the skills the library enterprise needs to include, and the enterprising librarian needs to have.
Here is the [expanded list of contents](https://lisnewprofs.com/table-of-contents/?ref=lorcandempsey.net).
1\. Project management
- What is a project?
- Finding project work
- Case study: Librarian to Project Manager (Annette Earl)
- Methodologies and tools
- Case study: the Blyton project (Hannah Green)
2\. Teaching, training & communicating
- Effective communication
- Teaching and training
- Case study: how to run training sessions (Lisa Jeskins | full version)
- Further qualifications (includes vignettes from Lynne Meehan | full version and Edith Speller | full version )
- Case study: ALT games and learning (Rosie Jones)
- Case study: Rhymetime for everyone (Linsey Chrisman)
- Presenting to professional peers
- Case study: how to make your first presentation a winning one (Bronagh McCrudden)
- Case study: how to write for publication (Jo Alcock)
3\. Meeting your users needs and measuring success
- Case study: the SLA Alignment Project (Amy Affelt)
- Case study: evaluating the impact of your library (David Streatfield)
- Encouraging user participation
- Evidence-gathering tools
4\. Marketing your service and engaging stakeholders
- What is marketing?
- Plan your marketing
- Case study: identifying and working with stakeholders (Michael Stead)
- Case study: creating customer-friendly e-reader experiences (Alison Circle)
- Case study: embedded librarianship (Reece Dano)
5\. Utilising technologies
- The move towards automation
- Case study: how to become a zen master of technology (Bohyun Kim)
- Case study: I, Shambrarian (Lukas Koster | full version)
- Technology for the non-technical
- Case study: introduction to sustainable digital preservation (Beccy Shipman)
- Repositories
6\. Getting and staying online
- Case study: interoperability and sustainability (Jane Stevenson)
- Case study: social media in the big city (Sue Lawson)
- Case study: Deseronto Archives (Amanda Hill)
- Social media tools
7\. Generating funding and doing more with less
- Demonstrating value
- Finding more funding
- Case study: how to identify funding sources (Caroline Williams)
- Case study: the Big Lottery Award: Luton’s experience (Fiona Marriott)
- Case study: Veria Public Library (Ioannis Trohopoulos, Dimitris Protopsaltou, and Dick Hartley)
8\. Managing money – budgets & negotiating
- Budgets
- Case study: how to manage your budget (Laura Wilkinson)
- Negotiating
- Case study: consortia and negoatiating (Michael Stead)
9\. Information ethics and copyright
- Case study: an introduction to information ethics (David McMenemy)
- Case study: how to start out in copyright (Emily Goodhand)
- Case study: copyright in archives (Tim Padfield)
10\. Up-skilling and professional development
- Case study: how to assess yourself (Deborah Dalley | full version)
- Bodies of professional knowledge
- Case study: SLA’s Competencies for Information Professionals of the 21st Century (Dee Magnoni)
- Case study: CPD on a shoestring (Laura Woods)
- Case study: how to get the most out of training and development (Gil Young)
- Case study: long-distance mentoring (Emily Hopkins)
- Case study: how to be a mentor (Jenica Rogers)
11\. Networking and promoting yourself
- Case study: personal branding (Kathy Ennis)
- Case study: how to build your information professional brand (Ned Potter)
- Networking
- Case study: professional networking (Maria Cotera)
- Case study: solo librarian, Cafcass (Jo Wood)
- Case study: solo records manager, TWI (Lee Pretlove)
12\. Professional involvement & career development
- Conferences
- Case study: how to write a successful conference proposal (Chris Rhodes)
- Case study: how to work an exhibition stand (Lisa Charnock)
- Case study: how to apply for awards (Laura Woods)
- Unconferences
- Case study: professional involvement for personal development (Lauren Smith)
- Case study: joining a professional organisation (Fiona Bradley)
- Other professional involvement (includes vignettes from Sarah Wachter | full version and Rebecca Goldman)
- Case study: tips for career planning success (Sarah Johnson)
- Top tips for CV and interview success (Suzanne Wheatley | full version)
- How did we get here? (includes vignettes from Maria Robertson | full version, Linda Butt | full version, and Aileen Marshall | full version)
### Making things of interest Discoverable, Referencable, Relatable, ...
URL: https://www.lorcandempsey.net/making-things-of-interest-discoverable-referencable-relatable/
Last updated: 2023-11-26T22:10:11.000Z
I came across the Ernest Hemingway phrase ‘gradually, then suddenly’ in an online discussion recently. Here is the context on the useful Goodreads [quotable quote page](https://www.goodreads.com/quotes/show/102579?ref=lorcandempsey.net).
It seemed a statement appropriate to our times, and especially apt to a recent phenomenon: the growing importance of large-scale knowledge bases which collect data about entities and make relationships between them. Wikipedia is already an ‘[addressable knowledgebase](https://blog.oclc.org/lorcand/archives/001264.html?ref=lorcandempsey.net)‘, which creates huge value. DBpedia aims to add structure to this. Perhaps more importantly, Wikidata is an initiative to create a machine- and human-readable knowledge base of all the entities in Wikipedia and allow them to be augmented with further data and links.
This is one of several examples, which although different in purpose, scope and sustainability model, collect and organize data about ‘things’. These are important because they collect and organize data in ways that support answering questions, and are machine-processable. They make ‘facts’ or ‘things’ discoverable, referencable, relatable. They become reference points on the web, or support services that become reference points on the web.
- [Freebase](https://www.freebase.com/?ref=lorcandempsey.net): “An entity graph of people, places and things”. Freebase is now owned by Google and is a contributor to their newly publicized Knowledge Graph (more below). Alongside this, it is worth noting the strong interest in [Schema.org](https://schema.org/?ref=lorcandempsey.net), a way of adding descriptive markup to web pages. It is sponsered by Google, Microsoft, Yahoo and Yandex. An important role is that it allows search engines to harvest structured data.
- [DBpedia](https://dbpedia.org/About?ref=lorcandempsey.net)/Wikipedia/Wikidata. “The DBpedia knowledge base currently describes more than 3.64 million things, out of which 1.83 million are classified in a consistent Ontology, including 416,000 persons, 526,000 places, 106,000 music albums, 60,000 films, 17,500 video games, 169,000 organisations, 183,000 species and 5,400 diseases.” As mentioned above, Wikidata is an initiative of the Wikimedia Foundation which will create an editable knowledge base of entities in Wikipedia. This will allow structured data about those entities to be shared across Wikipedia and across different language versions of Wikipedia, and with others. It will show up in the ‘info boxes’ on Wikipedia.
- [Factual](https://www.factual.com/about?ref=lorcandempsey.net): Aims to “1\. Extract both unstructured and structured data from millions of sources. 2\. Clean, standardize, and canonicalize the data. 3\. Merge, de-dupe, and map entities across multiple sources.”
- [Wolfram Alpha](https://www.wolframalpha.com/?ref=lorcandempsey.net) “..a computational knowledge engine: it generates output by doing computations from its own internal knowledge base, instead of searching the web and returning links.”
Think of two important recent developments: Siri and Google’s inclusion of Knowledge Graph data in its results. Siri created a splash when it appeared. Among the sources it uses to provide answers are Yelp and Wolfram Alpha. Here is a results page from Google. The panel on the right shows the Knowledge Graph data …
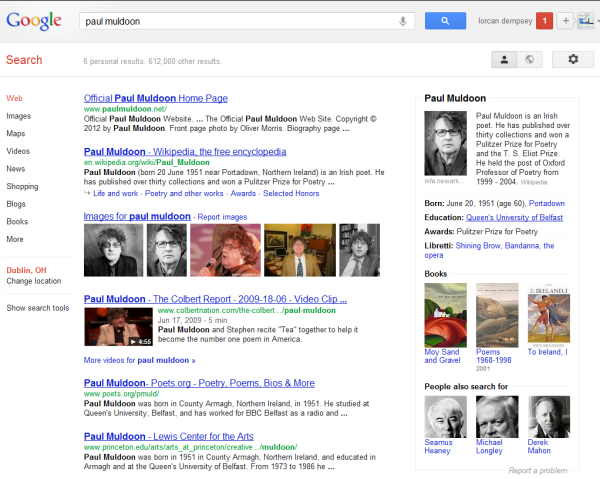
And here is how Google describes the rationale of the knowledge graph:
> But we all know that \[taj mahal\] has a much richer meaning. You might think of one of the world’s most beautiful monuments, or a Grammy Award-winning musician, or possibly even a casino in Atlantic City, NJ. Or, depending on when you last ate, the nearest Indian restaurant. It’s why we’ve been working on an intelligent model–in geek-speak, a “graph”–that understands real-world entities and their relationships to one another: things, not strings.The Knowledge Graph enables you to search for things, people or places that Google knows about–landmarks, celebrities, cities, sports teams, buildings, geographical features, movies, celestial objects, works of art and more–and instantly get information that’s relevant to your query. This is a critical first step towards building the next generation of search, which taps into the collective intelligence of the web and understands the world a bit more like people do.Google’s Knowledge Graph isn’t just rooted in public sources such as Freebase, Wikipedia and the CIA World Factbook. It’s also augmented at a much larger scale–because we’re focused on comprehensive breadth and depth. It currently contains more than 500 million objects, as well as more than 3.5 billion facts about and relationships between these different objects. And it’s tuned based on what people search for, and what we find out on the web. \[[Introducing the Knowledge Graph: things, not strings](https://googleblog.blogspot.com/2012/05/introducing-knowledge-graph-things-not.html?ref=lorcandempsey.net)\]
The phrase ‘things, not strings’ is telling.
One of the added values of library descriptive practice has been that it provides structured data about the ‘things’ of interest in a body of literature: authors, works, illustrators, places, subjects, and so on. A major motivation for library linked data is to more widely release that value and to make those ‘things’ more discoverable, referencable, and relatable on the web – in ways in which other services can build on. An important aspect of this is to link the ‘things’ established in library resources to ‘things’ established in these emerging webscale knowledgebases. If this does not happen, library resources will be less valuable and the library contribution may be overlooked.
[Viaf](https://www.viaf.org/?ref=lorcandempsey.net) is an example here. It synthesises data about people – their names and bibliographic contexts – from multiple national libraries and makes it available in a way that makes an identity readily referencable:
[Paul Muldoon](https://viaf.org/viaf/64048541/?ref=lorcandempsey.net)
We provide a lot of contextual data, including links to different names, creations, and so on. And we relate it in various ways to other resources, including Worldcat, Wikipedia, some national library authority files, and so on. And links to Viaf are appearing in other places, including Freebase.
We hope that this ‘relatedness’ will become richer, but also that applications will begin to exploit the referencability and relatability we and the participating national libraries are providing.
Related entries:
- [Linking not typing … knowledge organization at the network level](https://blog.oclc.org/lorcand/archives/002195.html?ref=lorcandempsey.net)
- [Wikipedia again: an addressable knowledge base](https://blog.oclc.org/lorcand/archives/001264.html?ref=lorcandempsey.net)
### Big data .. big trend
URL: https://www.lorcandempsey.net/big-data-big-trend/
Last updated: 2020-10-28T09:04:53.000Z
\[*I spoke at the Lita Top Technology Trends at Dallas. I had a trend in reserve – *big data* – but did not use it. Here is something along the lines of what I might have said …*\]
Big Data is a big trend, but as with expressions for other newly forming areas, it may evoke different things for different people.
A few years ago, academic libraries might have thought of scientific or biomedical data when they heard the expression ‘big data’. In particular, the publication of *[The Fourth Paradigm: data-intensive scientific discovery](https://research.microsoft.com/en-us/collaboration/fourthparadigm/default.aspx?ref=lorcandempsey.net)* helped crystallise awareness of developments in scientific practice.
More recently, however, big data has become a much more general term, across various domains. Indeed, it is now common to read about big data in the general business press. One comes across it in government and medicine, and in education. For example, a recent [article](https://www.insidehighered.com/news/2012/02/01/using-big-data-predict-online-student-success?ref=lorcandempsey.net) in *Inside Higher Ed* talks about ‘big data’ and ‘predictive analytics’ in relation to course data and student retention. There are two interesting aspects of this, one, the data, and, two, the management environment …
The rise of webscale services which handle large amounts of users, transactions and data has made the management of big data a more visible issue. At the same time, as more material is digital, as more business processes are automated, and as more activities shed usage data, organizations are having to cope with greater volume and variety of relatively unstructured data. Analytics, the extraction of intelligence from usage data has become a major activity. Here is a helpful characterization by Edd Dumbill on O’Reilly Radar.
> As a catch-all term, “big data” can be pretty nebulous, in the same way that the term “cloud” covers diverse technologies. Input data to big data systems could be chatter from social networks, web server logs, traffic flow sensors, satellite imagery, broadcast audio streams, banking transactions, MP3s of rock music, the content of web pages, scans of government documents, GPS trails, telemetry from automobiles, financial market data, the list goes on. Are these all really the same thing? \[[What is big data?](https://radar.oreilly.com/2012/01/what-is-big-data.html?ref=lorcandempsey.net)\]
In a brief discussion of big data as a possible trend on FaceBook, Leslie Johnston provided an interesting perspective on issues from the Library of Congress.
> Our collections are not just discovered by people and looked at, they are discovered by processes and analyzed using increasingly sophisticated tools in the hands of individual researchers, using just laptops. And we not only have TB/PB of digital collections, we will have billions of items, so fully manual processing/cataloging is rapidly becoming a thing of the past.
Leslie expanded on some of the actual data …
> - 5 million newspaper pages, images with OCR, available via API, used in NSF digging into data project for data mining, combined with other collections used in new visualizations, and in an image analysis project.
> - 5 billion files of all types in a single institutional web archive – researchers do not search for and view individual archived sites, they analyze sites over time, and characterize entire corpuses, such as campaign web sites over 10 years.
> - Extreme example: over 50 billion tweets: many research requests received to do linguistic analysis, graph analysis, track geographic spread of news stories, etc.
> - Collection of 100s of thousands of electronic journal articles, which require article-level discovery: they don’t all come with metadata and no one can afford to create it manually.
The remark about manual creation of metadata is one example where current processing methods do not scale. Leslie also notes:
> And we cannot do manual individual file QA for mass digitization or catalog web archives or tweets without automated extraction. And when we start talking about video and audio, it all requires automated extraction or processing. I know of one request that we process a video to produce an audio-only track so that a transcript could then be automatically generated. LC has 20 PB of video and audio. Can you imagine what it would take to provide that level of service? Researchers started asking a few years ago to get files so they could do it themselves.
The Library of Congress may be a special case, but other organizations are facing similar issues. We are familiar with discussions about research data curation in university settings. Referring to the university challenge, Leslie then points to another interesting example.
> I hear this from research libraries, but also from archives, especially state archives that are mandated to take in all state records, physical and electronic. Email archives are already Big Data for a lot of state archives.
Indeed, national or state institutions with responsibility for public records are reconfiguring organizations and systems to manage large volumes of e-records. My colleague Jackie Dooley pointed me at the recent [Presidential Mandate on Managing Government Records](https://www.whitehouse.gov/the-press-office/2011/11/28/presidential-memorandum-managing-government-records?ref=lorcandempsey.net) which has implications for agencies and NARA.
In this context, it is not surprising that we are seeing a growing interest in data mining across domains (Leslie mentions the ‘[digging into data](https://www.diggingintodata.org/?ref=lorcandempsey.net)‘ challenge). The term ‘data scientist’ is cropping up in job ads and position titles. A couple of years ago, Hal Varian’s comments on the importance of data and the skills required to analyse it were widely noticed.
> The ability to take data – to be able to understand it, to process it, to extract value from it, to visualize it, to communicate it’s going to be a hugely important skill in the next decades, not only at the professional level but even at the educational level for elementary school kids, for high school kids, for college kids. Because now we really do have essentially free and ubiquitous data. So the complementary scarce factor is the ability to understand that data and extract value from it. \[[Hal Varian on how the web challenges managers – reg required](https://www.mckinseyquarterly.com/Hal%5FVarian%5Fon%5Fhow%5Fthe%5FWeb%5Fchallenges%5Fmanagers%5F2286?ref=lorcandempsey.net)\]
It is clear from this discussion that existing systems are not well suited to manage and analyse these types of data, and this introduces the second topic, the management environment. Indeed, for Dumbill, this is **the** defining characteristic of big data:
> Big data is data that exceeds the processing capacity of conventional database systems. The data is too big, moves too fast, or doesn’t fit the strictures of your database architectures. To gain value from this data, you must choose an alternative way to process it.
And alternative ways have been emerging, assisted by the webscale companies who had to face these challenges early on. Google provided MapReduce, described by Edd Dumbill as follows:
> The important innovation of MapReduce is the ability to take a query over a dataset, divide it, and run it in parallel over multiple nodes. Distributing the computation solves the issue of data too large to fit onto a single machine. Combine this technique with commodity Linux servers and you have a cost-effective alternative to massive computing arrays. \[[What is Apache Hadoop](https://radar.oreilly.com/2012/02/what-is-apache-hadoop.html?ref=lorcandempsey.net)\]
MapReduce is a central part of Hadoop, whose development was supported by Yahoo, and whose further development is now supported within the Apache Software Foundation.
> Hadoop brings the ability to cheaply process large amounts of data, regardless of its structure. By large, we mean from 10-100 gigabytes and above. How is this different from what went before?
> Existing enterprise data warehouses and relational databases excel at processing structured data and can store massive amounts of data, though at a cost: This requirement for structure restricts the kinds of data that can be processed, and it imposes an inertia that makes data warehouses unsuited for agile exploration of massive heterogenous data. The amount of effort required to warehouse data often means that valuable data sources in organizations are never mined. This is where Hadoop can make a big difference. \[[What is Apache Hadoop](https://radar.oreilly.com/2012/02/what-is-apache-hadoop.html?ref=lorcandempsey.net)\]
The availability of the Hadoop family of technologies (again, nicely [described](https://radar.oreilly.com/2012/02/what-is-apache-hadoop.html?ref=lorcandempsey.net) by Dumbill) and cheap commodity hardware has made processing of large amounts of data more accessible. Cloud options are also emerging, from Amazon, Microsoft and others. Uptake has been rapid.
So, while Hadoop and related technologies have emerged in the context of the Big Data requirements of webscale companies, they are becoming more widely deployed. Their scalability, coupled with lower cost, have made them an attractive option across a range of data processing tasks. They may be used with ‘big data’ and not so big data.
In this way, my big data trend may more realistically be two trends. We are indeed having to process greater volume and variety of data. The description of data management at the Library of Congress provides some nice examples. Several technologies, notably the Hadoop framework, have emerged as a result of such challenges. However, these are now also finding more broad adoption as they reduce costs and provide greater flexibility.
**Coda:** In OCLC research we have been using MapReduce [for several years](https://outgoing.typepad.com/outgoing/2005/06/mapreduce%5Fand%5Fw.html?ref=lorcandempsey.net) and more recently have been using Hadoop. We have been also working with colleagues elsewhere in OCLC as we look at where and how Hadoop might provide benefits.
### Linking not typing ... knowledge organization at the network level
URL: https://www.lorcandempsey.net/linking-not-typing-knowledge-organization-at-the-network-level/
Last updated: 2020-10-28T09:04:56.000Z
‘Knowledge organization’ seems a slightly quaint term now, but we don’t have a better in general use. Take the catalogue. This has been a knowledge organization tool. When an item is added, the goal is that it is related to the network of knowledge that is represented in the catalogue. In theory, this is achieved through ‘adjacency’ and cross reference, notably with reference to authors, subjects and works. In practice this has worked variably well.
In parallel with bibliographic data, the library community, notably national libraries, have developed ‘authorities’ for authors and subjects to facilitate this structure. From our current vantage point, I think we can see three stages in the development of these tools.
1\. Label. In the first, subject and name authorities provide lists from which values for relevant fields were chosen. Effectively, they constrain the range and format of subject or name data, providing an agreed text label for a concept or name. Examples are LCSH, Dewey, and the Library of Congress Name Authority File. These provide some structuring devices for local catalogues, but those systems do not exploit the full structure of the authority systems from which the values are taken. Think of what is done, or not done, with classification for example. The classification system may not be used to provide interesting navigation options in the local system, and more than likely is not connected back to the fuller structure of the source scheme. That said, having a consistent label is an advantage, and facilitates matching within and between systems.
2\. Data. The second stage is that these authority systems are being considered as resources in themselves, and not just as sources of controlled values for bibliographic description. So, we are seeing the Library of Congress, for example, making LCSH and the Name Authority File available as linked data. OCLC is working with a group of national libraries to synthesize name authority files and make them available as an integrated resource in the [VIAF](https://www.viaf.org/?ref=lorcandempsey.net) service. [FAST](https://experimental.worldcat.org/fast/?ref=lorcandempsey.net) has recently been made available in this way. The [Digital Author Identifier](https://www.surffoundation.nl/en/themas/openonderzoek/infrastructuur/Pages/digitalauthoridentifierdai.aspx?ref=lorcandempsey.net), a national Dutch system for identifying researchers, is interesting in this context. In this arrangement, there is collaboration between the apparatus for uniquely identifying researchers and the national authority file.
3\. Network. In a third stage, as these network-level resources become more richly linkable and as local environments exploit that linking ability it becomes possible to do more. This type of linking has only just begun though, and it will be interesting to see how it develops. In this context, a URI is added to the label, making it actionable and globally unique. As an example, think again of the catalogue. The structuring devices we employ are about structuring relationships \*within\* the catalogue. This would be turned inside out if we not only imported values, but also linked those labels to those external resources. In this way, the item represented could be re-placed in the broad network of knowledge established by the authority file from which it comes.
Of course, alongside this, they may also link to, or draw data from, other navigational, contextual, identifying or structuring resources such as DBpedia, MusicBrainz or Geonames. These and other reference points are likely to be important webscale identity and knowledge organization services. In a sense, more generally, this has already happened, as people orient themselves by links to Wikipedia, MusicBrainz, IMDB and other network level resources.
As in other areas of our activity, we need to think about how activities whose natural level was once local are now moving up to the network level. And once they are at the network level, they have to live alongside other approaches.
If this were to become more common, there are some implications …
**From records to entities** … we ship data around in ‘records’, bundles about individual items, and our systems are structured around managing these records. We do not tend to manage data about other things of interest to us to the same extent: authors, places, people, concepts, works, and so on, the types of things we have in authority files. What would happen if we more clearly described an item by linking it to these files? More generally, we can see stronger interest emerging in some of these other entities, personal names especially. Think for example of how Amazon has created people pages or the growing interest in researcher identification. Or of places, as geolocation services take hold. Freebase is creating an ‘[entity graph](https://wiki.freebase.com/wiki/What%5Fis%5FFreebase%3F?ref=lorcandempsey.net)‘ giving IDs to millions of entities (people, places and things).
Much of the library linked data discussion has been about making that local record-based data available in different ways. As interesting is the discussion about what key resources libraries will want to link to, and **how they might be sustained**. An important question for national libraries and others who manage some of the schemes mentioned above is how to move into this third phase. What would this mean for library systems or for library data of this type? What resources are important? How should they be sustained? To make this concrete, are the name authority files maintained by national libraries fit for purpose in a network world? Does it make sense to limit their scope to authors identified in a particular library workflow, cataloging, and exclude other authors (of articles, for example)? Does it make sense to limit their creation to a restricted group of specialist librarians? And so on …
Finally, as knowledge organization moves to the network level how do library resource relate to others. Can other services leverage **the accumulated investment of the library community**, or does it fade. The organized relationship between the Deutsche Nationalbibliothek and Wikipedia in Germany is an interesting example here, where the German Wikipedia explicitly takes advantage of the structuring work done by the DNB. Wikipedia itself is very interesting in this regard, as it has effectively become an ‘addressible knowledgebase’. If I want to tell you about a new concept or movement, or refer you to a place, or mention a person, I can send you a Wikipedia link. What would be required for Wikipedia to take advantage of ‘knowledge organization’ approaches developed in the library community?
Related entry:
- [Nostalgia, the Dublin Irish Festival and variant forms of names](https://blog.oclc.org/lorcand/archives/002185.html?ref=lorcandempsey.net)
### End of the digest ....
URL: https://www.lorcandempsey.net/end-of-the-digest/
Last updated: 2020-10-28T09:04:58.000Z
For almost as long as this blog has been going we have had an associated digest. This has gone out to over 800 people. The frequency of the digest has changed as the frequency of posting has gone down. We have decided that it is now time to turn off the digest. While the blog continues, it has become more a venue for occasional comment than a steady stream. Thank you to all those who have subscribed to the digest, and I hope you continue to read entries in the future.
And, as a reminder, I am on Twitter at [https://www.twitter.com/LorcanD](https://www.twitter.com/LorcanD?ref=lorcandempsey.net).
### Social reading
URL: https://www.lorcandempsey.net/social-reading/
Last updated: 2022-11-08T16:13:41.000Z
It seems to me I have heard the phrase ‘social reading’ more often recently. That said, it also seems to me that its use has been a little vague, largely, I expect, because it has no precise referent: the activities to which it refers are not sufficiently coalesced.
That said, it does seem that as we move into a digital environment a social dimension become stronger, while private reading of course continues.
See Bob Stein’s comment introducing his ‘taxonomy of social reading’.
> When I grew up in the 50s, reading and writing were activities conducted alone and in silence. Twenty years from now, as my grandchildren come of age, I expect these formerly solitary behaviors will be perceived as highly social — something we do, more often than not, with others. This insight comes in large part from a series of experiments conducted over the past five years with my colleagues at The Institute for the Future of the Book. They strongly suggest that when we move texts from the printed page to a networked screen, the social aspect of reading and writing moves to the foreground. \[[A taxonomy of social reading](https://futureofthebook.org/social-reading/introduction/?ref=lorcandempsey.net)\]
The fate of reading itself is a much-discussed issue. A major part of Nick Carr’s *The Shallows* was a regretful discussion of the decline of deep contemplative reading. And Steven Berlin Johnson’s critique of *The Shallows* last year was called ‘[Yes, People Still Read, but Now It’s Social](https://www.nytimes.com/2010/06/20/business/20unbox.html?src=tp&ref=lorcandempsey.net)‘.
Here are a few notes in three successively more networked stages:
- groups: scaling social reading,
- sites: from cataloging to scrobbling,
- texts: social micro reading.
These have no virtue other than as scaffolding for this blog entry.
We are familiar with group reading activity in the book club or reading group. It is not surprising to see network services emerge to support this activity in various ways (e.g. [Reading group Choices](https://www.readinggroups.org/?ref=lorcandempsey.net) or from the [Read: the Reading Agency](https://www.readinggroups.org/?ref=lorcandempsey.net)). Libraries of course also provide support (see [Hennepin County](https://www.hclib.org/pub/bookspace/BookClubs.cfm?ref=lorcandempsey.net) or [Suffolk Libraries](https://suffolkreads.wordpress.com/adults/bookgroups/?ref=lorcandempsey.net), for example). Network support has allowed these activities to scale across bigger groups, altering the experience. See for example the [support for groups](https://www.goodreads.com/group/active?ref=header) in Goodreads. [A state of writing](https://astateofwriting.org.au/?ref=lorcandempsey.net) is a social network around reading and writing in Queensland (although it is not clear how active it is).
There are several sites on the web which allow people to catalogue and share their book collections: Goodreads, LibraryThing, Shelfari, Anobii, and others. In this context, books are social objects. It [has been argued](https://blog.oclc.org/lorcand/archives/001601.html?ref=lorcandempsey.net) that successful social networks are those which form around such social objects, through which people connect and share themselves (music, photos, video, links, holidays, or other shared interests). We are becoming used to selective disclosure and selective socialization through affinity groups within such social networks. These books sites variously connect readers, books, authors and publishers.
WeReads owned by FlipKart. Shelfari by Amazon. Anobii by HMV.
### Collections are library assets
URL: https://www.lorcandempsey.net/collections-are-library-assets/
Last updated: 2022-12-06T21:20:47.000Z
## Business school writing
I quite like using the word ‘assets’ with reference to library collections. We tend to think of assets in positive terms, as things that are valuable. More of that later.
I was interested to see Rick Anderson remark on the vocabulary used by my colleague Constance Malpas a while ago. This was in the context of a generous note about Constance’s *“Cloud-sourcing Research Collections: Managing Print in the Mass-digitized Library Environment.” \[[pdf](https://www.oclc.org/research/publications/library/2011/2011-01.pdf?ref=lorcandempsey.net)\]*.
> I confess that I giggle and shudder simultaneously at the thought of referring publicly to books in our collection as “inventory that is increasingly devalued as an institutional asset.” That kind of business-school-flavored language will, not to put too fine a point on it, utterly freak out significant segments of any university faculty, not to mention library staff. // [The Scholarly Kitchen](https://scholarlykitchen.sspnet.org/2011/02/28/the-digitized-book-corpus-and-the-cracking-dam/?ref=lorcandempsey.net)
The ‘business’ reference is apt, and I confess that my sense of ‘asset’ in general conversation has indeed been subtly transformed by the narrower acounting sense. For example in the glossary to Robert C Higgins’ *Analysis for financial management*\* we read that an asset is ‘Anything with value in exchange’. And turning, as one does, to Wikipedia, I read an [accounting definition](https://en.wikipedia.org/wiki/Asset?ref=lorcandempsey.net): ‘An asset is a resource controlled by the entity as a result of past events and from which future economic benefits are expected to flow to the entity’.
What is relevant here is the idea that assets are things from which you release value. You expect a return. But assets are not ends in themselves. They are means towards creating value. Of course, this is important because assets have associated costs. Managing collections, for example, is not cost-free.
I remember being struck by some sentences about assets in Higgins’ book when I read them first a few years ago:
> Some newcomers to finance believe assets are a good thing: the more the better. The reality is just the opposite: Unless a company is about to go out of business, its value is in the income stream it generates, and its assets are simply a necessary means to this end. Indeed, the ideal company would be one that produced income without any assets; then no investment would be required, and returns would be infinite.
Yes, financial metrics lend clarity here, but are not relevent to libraries for whom the question of value is different and less susceptible to measurement.
## Library collections and assets
However, it has been interesting see the growing debate about print ‘assets’ in libraries. As the pressure to repurpose space grows and as the print collection releases progressively less value in research and learning, there is a growing interest in managing down print assets. Not unexpectedly, this is in parallel with an emerging interest in securing system-wide preservation of the collective print record. (I provide some examples in the related entries listed below.)
It is clear that research libraries no longer see collections as ends in themselves, or they do not necessarily equate the size of the collection with the value of the library. More is not necessarily better. They also recognise the opportunity costs of managing large print collections.
As we rethink collections, I think we are seeing them more as assets in the sense I have discussed here, as investment is driven by a stronger sense of how they will be used to generate value in research and learning. Of course, some libraries have thought this way for longer: think of how a busy public library manages its collection. And of course, some libraries will continue to have a mission-driven responsibility to collect significant portions of the scholarly record, although we will probably see more collective approaches here.
Anyway, to get a sense of what I mean, Rick Anderson’s [presentations](https://www.slideshare.net/CharlestonConference/let-them-eat-everything-by-rick-anderson-university-of-utah?ref=lorcandempsey.net) might help …
**Related entries:**
- [The service turn](https://blog.oclc.org/lorcand/archives/002152.html?ref=lorcandempsey.net)
- [The collections shift](https://blog.oclc.org/lorcand/archives/002160.html?ref=lorcandempsey.net)
- [Managing down collections](https://blog.oclc.org/lorcand/archives/002151.html?ref=lorcandempsey.net)
- [We’re not going anywhere … Ok, we lied …](https://blog.oclc.org/lorcand/archives/002106.html?ref=lorcandempsey.net)
\* It is always a pleasure to read something that is well written. This is a very nice example of fine technical writing.
**Note:** Feature picture added and amended for spacing and headings on transition here 29 March 2021\.
**Picture:** I took the feature picture at Cambridge University Library's off-site facility in Ely.
### The ILS, the digital library and the research library
URL: https://www.lorcandempsey.net/the-ils-the-digital-library-and-the-research-library/
Last updated: 2023-02-10T20:13:33.000Z
I have been interested to see three research libraries look for senior digital library posts in recent months.
- [Associate Director for Digital Library Programmes and Information Technologies](https://www.lisjobnet.com/job-ads/762-a110606-associate-director-for-digital-library-programmes-and-information-technologies/?ref=lorcandempsey.net), Bodleian Libraries, University of Oxford.
- [Associate Vice President for Digital Programs and Technology Services](https://academicjobs.columbia.edu/applicants/jsp/shared/frameset/Frameset.jsp?time=1313628502453&ref=lorcandempsey.net), Columbia University Libraries/Information Services.
- [Head of Digital Library](https://www.jobs.ed.ac.uk/vacancies/index.cfm?fuseaction=vacancies.furtherdetails&vacancy%5Fref=3014396&ref=lorcandempsey.net), Information Services, The University of Edinburgh.
**Note**: given the nature of these resources, the links may not continue to work indefinitely.
These are different posts in different institutions but there is the common ground that you might expect as research libraries look at creating digital infrastructure, engage with research data needs, explore new modes of scholarly communication, and so on. Each is challenging and interesting and offers a wonderful opportunity to be centrally involved in advancing how libraries support changing research and learning practices.
However, I was struck by something else they have in common. Responsibility for the integrated library system (or library management system) appears to be a part of each post, yet it is not foregrounded in the position description. For these libraries, maybe, the ILS is a necessary part of doing business, but is not the site of major development. Designing and developing digital infrastructure now includes the ILS but is no longer led by it. Or maybe there is some other reason?
Considerable time and effort goes into these systems, and they will be reconfigured in coming years. Picking up on my opening remarks though, it is interesting to see where the adverts place the emphasis.
**Note**: formatting changes 10 Feb 2023.
### Preserving musical heritage ...
URL: https://www.lorcandempsey.net/preserving-musical-heritage/
Last updated: 2022-11-08T15:28:41.000Z
One of the casualties of the London riots last week was a Sony distribution warehouse.
> The building, owned by Sony DADC, was also the main HQ for the UK’s biggest distributor of independent music, Pias. \[[More than 1.5m CDs destroyed in Sony warehouse fire](https://www.bbc.co.uk/newsbeat/14490635?ref=lorcandempsey.net)\]
Interestingly, Sony looked after the stock of more than 150 record labels at the warehouse. According to the BBC story quoted above “As well as CDs, the 20,000 sq m (215,000 sq ft) centre was used to store DVDs, Blu-ray discs and discs used for PlayStation Portable games.”
It was depressing reading about the impact on the affected independent labels and artists and the music stores who depend on them (see, for example this [NME blog](https://www.nme.com/blog/index.php?blog=10&title=london%5Friots&more=1&c=1&tb=1&pb=1&ref=lorcandempsey.net) entry and this [Guardian article](https://www.guardian.co.uk/music/musicblog/2011/aug/11/how-pias-fire-affects-labels?intcmp=239&ref=lorcandempsey.net)). Several support initiatives for labels have been set up. I immediately thought about the heightened awareness about distribution, supply chain management and risk following the Japanese earthquakes earlier this year (see this [NYT story](https://www.nytimes.com/2011/03/20/business/20supply.html?pagewanted=all&ref=lorcandempsey.net) for example).
One of the consequences of the arson is that some of the labels may not re-issue physical formats of the music. See this note on the Buzzin’ Fly label, for example:
> **09.08.11 Buzzin’ Fly stock goes up in flames in warehouse fire during London riots**
> London, 13h33 , temperature 21°, humidity 72%, clear. Virtually all Buzzin’ Fly and Strange Feeling stock was destroyed in an arson attack on the Sony DADC warehouse in Enfield last night during the London riots. The warehouse contained all records distributed by our distributor, PIAS. Other labels are also badly hit. There are a handful of copies of some releases (and a full download catalogue) left on sale on the Buzzin’ Fly online shop, but beyond that it is unlikely much of our stock will ever be repressed if at all. A huge slice of the label’s history has been destroyed. \[[Buzzin’ Fly Records](https://www.buzzinfly.com/buzzed.html?ref=lorcandempsey.net)\]
However, it made me realise that I knew little about how well, or not, libraries and other memory institutions (in this case, this seems an appropriate term) are prepared for preservation of digital music.
### Nostalgia, the Dublin Irish Festival, and variant forms of names
URL: https://www.lorcandempsey.net/nostalgia-the-dublin-irish-festival-and-variant-forms-of-names/
Last updated: 2023-12-09T08:31:53.000Z
The [Dublin Irish Festival](https://www.dublinirishfestival.org/?ref=lorcandempsey.net) is on this weekend – Dublin, Ohio, that is. I notice that Moya Brennan is [performing](https://www.dublinirishfestival.org/artist/?ref=lorcandempsey.net).
As some folks will know, Moya Brennan is an Irish singer who was a member of the well-known family group, [Clannad](https://www.clannad.ie/biography/index.html?ref=lorcandempsey.net). They emerged in the 70s, playing very much in a traditional irish music idiom. As they evolved, they developed a style that was influential in the emergence of the sort of new age, ‘celtic’ music that became popular and has some well-known practitioners.
One of the most vivid memories I have of secondary school is when they put on a concert there (before they were very well known). We had never seen anything like it – songs in Irish, but with a double bass and a harp, long hair, and influences from other types of music.
At that time, Moya was known as Máire Ní Bhraonáin. And indeed, if you look at Worldcat identities page for ‘Moya Brennan’, you will see ‘Brennan, Máire’ and ‘Ní Bhraonáin, Máire’ listed as alternatives. (The latter puts the surname in its Irish form.)
‘Moya’ is an assumed name, perhaps sounding something like the Irish pronunciation of ‘Máire’. ‘Moya Brennan’ is presumably a more memorable name to have outside Ireland than ‘Máire Ní Bhraonáin’.
Worldcat Identities does a reasonable job with related Identities, which you can see and follow in the graphical form at the [Worldcat Identities Network page](https://experimental.worldcat.org/IDNetwork/display.html?query=lccn-no98-100171&ref=lorcandempsey.net). It pulls together the other members of Clannad – her brothers (Brennans) and uncles (Duggans) – and some others.
Interestingly, however, Identities, drawing on the underlying bib data, does not reveal what many people might feel is her most interesting related identity.
This is her more famous sister, who was briefly part of Clannad, and whose name is Eithne Ni Bhraonain. Eithne is somewhat better known as ……. [Enya](https://www.worldcat.org/wcidentities/lccn-n91-122258?ref=lorcandempsey.net).
Now, as the relationships in Identities – mined from the bib records – are ‘bibliographic’, there is no reason that family or other relationships which are not somehow represented in the bibliographic data should be present. In fact, as my colleague Diane Vizine-Goetz pointed out there is a relationship in the bibliographic data, but at a very low threshold. See the names collocated in the statement of responsibility in this [Danish record](https://www.worldcat.org/oclc/470985067?ref=lorcandempsey.net) (the names are not consistently controlled in WC).
It seems to me that having the relationships made visible in Identities makes me want to see other important relationships – whether or not they are supported by bibliographic relationships. Not having them there seems to me to be an important limitation. This is because I am seeing things through a names or identity filter and the Identity becomes a subject of interest in itself. We are seeing more of this. Open Library, Amazon, Google Scholar, Trove and others all now present ‘author’ pages, because authors or creators are important topics of interest in themselves, as well as pivots for searching.
This prompts these brief observations about some inevitable futures if library practices in this area are to continue to be relevant:
- As I suggested the last time I spoke about variant forms of Irish names ([Name authorities, crowdsourcing, and Máire Mhac an tSaoi](https://www.lorcandempsey.net/name-authorities-crowdsourcing-and-maire-mhac-an-tsaoi/)), it would be nice to make suggestions to LC or the National Library of Ireland or the BL or … However, I have no way of easily doing that. Authorities work – and think NACO here – is a professional activity, hedged around by rules and procedures; it is after all ‘authorities’ work. However, it would seem sensible to open it up to suggestion and information.
- We now have access to several related online sources of data about people and names. Think of the related Wikipedia, Dbpedia and Freebase for example. It would be good to be able to programmatically mine them to enhance the data libraries manage. In Identities, we match names in Wikipedia and link to them when we are reasonably confident the link is correct, but it is not easy to extract relationship information.
- One could change authorities practice to record significant related people who are not supported by bibliographic relationships. This seems sensible to me, although it runs counter to the trend to reduce effort – unless a parallel mechanism is found to more widely share the task of creation. One probably would not want to record that [Lorcan Dempsey](https://www.worldcat.org/wcidentities/lccn-n90-602202?ref=lorcandempsey.net) is [Laurence Dempsey’s](https://www.worldcat.org/wcidentities/np-dempsey,%20laurence?ref=lorcandempsey.net) son; but it would be interesting to know that Martin Amis is Kingsley Amis’s son, and not just let a general relationship emerge because they are both the subject of a book, for example. One might note here in passing that it would be nice to consistently type those relationships.
- Finally, the current model in library catalogs is one in which centralised creation of ‘knowledge organization’ systems (subject/name authorities in particular) is matched by decentralised application of those systems in local environments. There is some consistency, but in general local application don’t make best use of the data, there may be some variability in application, and links back to the fuller knowledge systems are not present. As more activities move to the network level, it is worth thinking more seriously about network level knowledge organization also, where those knowledge systems become network level resources which others link to. Think of how [VIAF](https://www.viaf.org/?ref=lorcandempsey.net) or the authorities the Library of Congress makes available at [https://id.loc.gov/](https://id.loc.gov/?ref=lorcandempsey.net) might be used, for example, to provide richer context. Currently, a catalog may include, for example, a name in its controlled form: think of how the catalog could either link to, or actually incorporate, the richer data available in the authority file, or a system like Identities. In the context of this note, this would bring the design and construction of those knowledge organization systems more into focus and encourage some of the approaches mentioned above. This is alongside the work that happens in Wikipedia, or Amazon, or other sources. You can get a sense of this at the U Wisconsin Forward experimental system which pulls data from Freebase, with varying success. See for example this search for [Conor Cruise O’Brien](https://forward.library.wisconsin.edu/catalog?q=conor+cruise+o%27brien&qt=search&local=false&ref=lorcandempsey.net). It would be good to see library resources used to enrich results or local data. I will return to the topic of network level knowledge organization in a future post.
(Incidentally, ‘knowledge organization’ seems a rather antique term .. it would be nice to have a better one.)
**Update:** Picture added 12/09/2023\. Taken by me. Lunasa performing at Dublin Irish Festival.
### Worldcat Identities Network: a 'mashup'
URL: https://www.lorcandempsey.net/worldcat-identities-network-a-mashup/
Last updated: 2020-10-28T09:05:20.000Z
There has been some nice reaction to the [Worldcat Identities Network](https://www.oclc.org/research/news/2011-07-28.htm?ref=lorcandempsey.net).
[](https://experimental.worldcat.org/IDNetwork/display.html?query=lccn-n50-1905&ref=lorcandempsey.net)[](https://experimental.worldcat.org/IDNetwork/display.html?query=lccn-n50-1905&ref=lorcandempsey.net)
The initial motivation for this was to put a graphic display of [related Identities](https://www.worldcat.org/wcidentities/lccn-n50-12860?ref=lorcandempsey.net#linkassoc) into an Identities [page](https://www.worldcat.org/wcidentities/lccn-n50-12860?ref=lorcandempsey.net). This did not work out and we decided to make it available as a standalone app. The aim is to show how something could be built on top of the [Worldcat API](https://oclc.org/developer/services/WCAPI?ref=lorcandempsey.net) and the [Worldcat Identities Web Services](https://www.oclc.org/developer/services/identities?ref=lorcandempsey.net).
It is a ‘mashup’. Which prompted me to think that the peak of the mashup has passed? Or at least we do not hear as much about mashups as before? It is interesting to consider why this is the case, but that is something for a future post perhaps.
Enjoy the Worldcat Identities Network … Here – pretty randomly – is musician [Paul Brady](https://experimental.worldcat.org/IDNetwork/display.html?query=lccn-n92-12823&ref=lorcandempsey.net), artist [Richard Diebenkorn](https://experimental.worldcat.org/IDNetwork/display.html?query=lccn-n80-23105&ref=lorcandempsey.net), organizations [The Missouri Botanical Gardens](https://experimental.worldcat.org/IDNetwork/display.html?query=lccn-n80-23105&ref=lorcandempsey.net) and [Los Alamos National Laboratory](https://experimental.worldcat.org/IDNetwork/display.html?query=lccn-n82-2711&ref=lorcandempsey.net), academic and writer [Seamus Deane](https://experimental.worldcat.org/IDNetwork/display.html?query=lccn-n84-120698&ref=lorcandempsey.net), poet [Eavan Boland](https://experimental.worldcat.org/IDNetwork/display.html?query=lccn-n80-109150&ref=lorcandempsey.net), astronomer [Fred Hoyle](https://www.worldcat.org/wcidentities/lccn-n79-18031?ref=lorcandempsey.net), the interesting [Lincoln Theatre](https://experimental.worldcat.org/IDNetwork/display.html?query=nc-lincoln%20theatre%20columbus%20ohio&ref=lorcandempsey.net), Columbus, and the boat, [Brendan](https://experimental.worldcat.org/IDNetwork/display.html?query=lccn-n78-1099&ref=lorcandempsey.net).
It should be noted that there is no editorial assistance here. The data is pulled from Worldcat and Worldcat Identities. Worldcat identities is in turn programmatically mined from Worldcat. It would be nice to show the type of each relationship, but that is inconsistently and intermittently available in the bib data.
### Gamification: services and libraries
URL: https://www.lorcandempsey.net/gamification-services-and-libraries/
Last updated: 2020-10-28T09:05:23.000Z
I have been interested to see more notes in my tweetstream about peoples’ exercise or diet regimes. They are typically generated by network services as a by-product of some activity, running or cycling, for example, and are part of a motivating framework. The [Withings bathroom scale](https://www.amazon.com/Withings-WBS01-Wifi-Body-Scale/dp/B002JE2PSA?ref=lorcandempsey.net) is connected to the network, allows you to set goals and to record and access weight and other data, as well as optionally communicating progress by tweeting your weight. In a similar vein, I recently came across [stickK.com](https://www.stickk.com/?ref=lorcandempsey.net) – “the smartest way to set and achieve your goals”.
> If you’re ready to turn that goal into an accomplishment, you’re ready for stickK.
> stickK was founded on the principle that creating incentives and assigning accountability are the two most important keys to achieving a goal. Thus, the “Commitment Contract” was born.
These are all examples of the growth of gamification as a design principle, the application of game mechanics to services and systems.
[Keas.com](https://info.keas.com/employee-wellness-tin?ref=lorcandempsey.net), a company aimed at reducing corporate healthcare costs by improving employee wellness, puts the ‘power of play’ at the centre of its method:
> Keas is a social game that that promotes employee wellness. Employees form teams and earn points by making healthy choices each week, like eating better, exercising more, or even getting more sleep. Teams participate in wellness challenges and whoever gets the most points wins!
Keas is especially interesting because its co-founder and CTO is the distinguished [Adam Bosworth](https://en.wikipedia.org/wiki/Adam%5FBosworth?ref=lorcandempsey.net), who made major contributions to products and to general internet technologies while at Microsoft and BEA, before joining Google to work on Google Health.
Bosworth wrote about gamification and Keas on [Techcrunch](https://techcrunch.com/2011/06/18/web-of-games/?ref=lorcandempsey.net) recently. He quickly identified three major inflection points in the development of computer and network technologies, each bringing about an order of magnitude increase in participation: the emergence of the PC, the emergence of the GUI, and the emergence of the web and mobile phones. The next inflection point, he suggested, was not about numbers but about **engagement**. Engagement is a central aspect of gamification, and is integral to the examples I gave above. Bosworth points to a [gamification site](https://gamification.org/wiki/Gamification?ref=lorcandempsey.net) which carries this definition: “Gamification is the integration of Game Mechanics and game-thinking in non-game environments to boost Engagement, Loyalty and Fun!”.
He argues that inside the term ‘gamification’ are three important truths. First, social gaming changes engagement in “deep and dramatic ways” by appealing to the “primitive brain in all of us that wants constant rewards, social recognition and adventure”. Second, gamification will accelerate the move from physical to digital. He suggests that Groupon has shown that people like the juxtaposition of shopping and games, and that bricks-and-mortar shopping will have to become more fun if it is to slow the trend to online. And third, he forecasts the complete replacement of PCs by mobile devices within 10 years, noting that “social games lend themselves to this form factor and this form factor is location-aware and constantly with you”.
He concludes with an interesting message to developers:
> We used to teach information design. Then we taught UI design and UI interaction. But now it will be game mechanics. Within two years (if not already), lack of understanding appointment mechanics, game mechanics and leveling will be as crippling to someone who aspires to design online solutions as it is today for someone who doesn’t understand HTML and CSS and AJAX and JQuery.
Most of the examples above draw from health care and wellness, but we can see these techniques in widespread use. The Gamification website, mentioned above, has a [variety of examples](https://gamification.org/wiki/Gamification%5FIndustry?ref=lorcandempsey.net) from different industries.
I was wondering whether such approaches were feasible in a library environment when I came across [Lemon Tree](https://www2.hud.ac.uk/tali/support/proj11%5Flemon.php?ref=lorcandempsey.net), a project at the University of Huddersfield in the UK.
> Lemon Tree seeks to increase the use of library resources through a social, game based elearning platform. Users will register with the system and be able to earn points and rewards for interacting with library resources, such as leaving comments and reviews of library books. Integration with other social networks such as Twitter and Facebook will be built into the system.
There is a [project blog](https://library.hud.ac.uk/blogs/projects/lemontree/?ref=lorcandempsey.net) and it will launch in the Fall (aka Autumn). Something to watch … it will be interesting to see if incentives are strong enough to encourage strong participation. Andew Walsh, who is managing the project, writes about it briefly in an article about the Library’s work with social tools.
> The rewards users can gain through Lemon tree are developing as we see what works and what our users enjoy, with a massive range of options possible. We are particularly interested though in engaging those people who we know come into our library, but borrow very few books and rarely access our electronic resources. If we can make it fun for them to use the information resources we have and increase their usage then Lemon Tree will have succeeded for us. \[[Tweets, texts & trees](https://eprints.hud.ac.uk/11035/?ref=lorcandempsey.net).\]
I see that Andrew uses two of the words – ‘engaging’ and ‘fun’ – which were part of the definition of gamification given above. The third – ‘Loyalty’ – would be good too to see as a result too …
### Spotify and Klout: fungible influence
URL: https://www.lorcandempsey.net/spotify-and-klout-fungible-influence/
Last updated: 2020-10-28T09:05:29.000Z
Popular music streaming service Spotify has just launched in the US. For some background see the [Ars Technica story](https://arstechnica.com/media/news/2011/07/music-service-spotify-finally-to-launch-in-us-on-thursday-morning.ars?ref=lorcandempsey.net).
One of the interesting aspects of the launch was the tie-in with Klout. [Klout](https://corp.klout.com/about?ref=lorcandempsey.net) is one of several services which provide analytics around social media activity. It aims to be the ‘standard for influence’, tracking social media impact. I have spoken about Klout before ([Analysing influence .. the personal reputational hamsterwheel](https://blog.oclc.org/lorcand/archives/002176.html?ref=lorcandempsey.net)). The [business model](https://corp.klout.com/about?ref=lorcandempsey.net) includes the matching of ‘influencers’ in a particular area with providers of products and services relevant to that area. The providers may provide the influencers with ‘perks’ (upgrades, samples, etc) which positively influence their tweeting.
The ‘perk’ in the case of Spotify was an early free invite, and if the ‘influencer’ gets 5 additional people to sign up (see [here](https://klout.com/perk/Spotify/SpotifyFreeAccounts?passalong=MzEvNTkyMTUvMg&passalongSig=44c1770db70407d894dad449db0350c150b96bd1b440275ec6e4bed7341d4bb0&ref=lorcandempsey.net) for a link to my invite), then he or she gets a free pass to the premium Spotify service. Apparently, the offer was popular, or popular enough to cause Klout to go down for a while (according to [Techcrunch](https://techcrunch.com/2011/07/14/dont-have-a-free-spotify-invite-use-your-klout-perks/?ref=lorcandempsey.net)).
> Klout CEO Joe Fernandez says that Klout has partnered with Spotify to offer free invites to those Klout users who have hight scores in topics relevant to music/entertainment. We don’t know the exact number of invites, but Fernandez says Klout is working with Spotify to scale the invitations further. \[[Techcrunch](https://techcrunch.com/2011/07/14/dont-have-a-free-spotify-invite-use-your-klout-perks/?ref=lorcandempsey.net)\]
If my experience of the last few days is typical, the interest in Spotify seems to be driving new members to Klout as much as the other way around. I haven’t seen discussion of what has happened to the ‘influence’ threshold.
While there is debate about what exactly Klout measures, some concern about where this model leads, and while it is still early days, I think that this more ‘organic’ approach to promotion is interesting. As is a service based on the fungibility of influence.
Klout may or may not be successful, but this is is another example of how social and algorithmic approaches are changing our communications and media landscape. It is also a rather literal example of those ‘hidden persuaders’.
(Slightly edited for style 7/25/2011.)
### Some quotes: sizing the academic library ...
URL: https://www.lorcandempsey.net/some-quotes-sizing-the-academic-library/
Last updated: 2022-11-08T16:23:54.000Z
A couple of years ago Ross Housewright of Ithaka S+R published an article about the future of academic libraries. The thesis was that the academic library was in danger of disruption, along the lines already experienced by the corporate library. Success would depend, he argued, on shifting from a supply mode of thinking, where the library defined itself in terms of its traditional roles, to a demand mode of thinking, where the library defined itself in terms of its constituency’s expectations.
> The case of the corporate library offers us a parallel example in which many of the academic library’s roles are performed in a very different organizational context. Both corporate and academic libraries have mandates to support users by building and maintaining general collections, providing reference assistance, organizing information and resources to facilitate use, and otherwise addressing their users’ information needs. The corporate library sector, more urgently than the academic library sector, has seen the effects of disruptive change particularly in these service-oriented roles. Because of the nature of this environment, it has been forced to critically reconsider the role of the library in the modern organization as it attempts to survive. In recent years, many corporate libraries that were slow or ineffective in reacting to a changing information environment have closed, suffered severe cutbacks, or seen their functions outsourced or passed off to others within the company.3 The corporate world also offers examples of library organizations that have adapted and thrived, becoming more important than ever before to their parent institutions.4
The institutional context of academic libraries, he claims, has delayed such reconfiguration.
> Academic libraries, however, have in many ways been insulated from the full extent of change because of their position within academic institutions. The library is deeply embedded in the intellectual life of the campus, is often a source of considerable prestige for its host school, and is generally a well-respected campus institution with significant historical importance. Although these protections have slowed the pace of change in academic libraries, they have also lessened the pressure on the academic library to evolve; and to observers, it is increasingly evident that the library is becoming less relevant to campus research and teaching.
And here is how he summarises
> In general, successful corporate libraries were flexible and allocated resources with an aim of maximizing their value to their parent firm. Roles were chosen based on their contribution to the success of the parent enterprise, not on historical necessity or tradition. They were regularly reevaluated and revised to keep up with the changing needs of the company, as determined through deep engagement with the user community. Rather than arguing that users were making poor choices or complaining that information activities should be the province of the library by right, they, instead, sought to offer services to match users needs. They focused their energy on tasks that users could not effectively accomplish without their intervention and proactively sought out activities, either solo or collaborative, in which their expertise would be of value to the company. Although other variables played into many libraries’ ultimate success or failure, this value-maximizing outlook was a general theme of the more successful corporate libraries.
### Hamster wheeling ....
URL: https://www.lorcandempsey.net/hamster-wheeling/
Last updated: 2021-04-29T01:00:34.000Z
I have found the expression ‘hamster wheeling’ useful over the last few years. I tend to use it in the context of any frantic effort where the participants have to keep several things going at the same time, and where it seems that slowing down might cause something to fall off.
More specifically, it is an appropriate description for those operations, common in a digital library environment, where a set of grants are used to keep a set of people working on a set of projects. Many of us are familiar with such environments, either as participants or observers.
In this context, I was interested to see a similar expression used in a [report](https://arstechnica.com/web/news/2011/06/has-the-internet-hamsterized-journalism.ars?ref=lorcandempsey.net) recently in Ars Technica.
> But, “these additional responsibilities–and having to learn the new technologies to execute them–are time-consuming, and come at a cost. In many newsrooms, old-fashioned, shoe-leather reporting–the kind where a reporter goes into the streets and talks to people or probes a government official–has been sometimes replaced by Internet searches.”
> Thus, those “rolling deadlines” in many newsrooms are increasingly resembling the rapid iteration of the proverbial exercise device invented for the aforementioned cute domestic rodent. The observation was first made by Dean Starkman in a Columbia Journalism Review piece titled “[The Hamster Wheel](https://www.cjr.org/cover%5Fstory/the%5Fhamster%5Fwheel.php?page=all&ref=lorcandempsey.net).”
> The “Hamster Wheel” isn’t about speed, the report quotes Starkman as saying. “It’s motion for motion’s sake… volume without thought. It is news panic, a lack of discipline, an inability to say no.” // [Has the Internet “hamsterized” journalism?](https://arstechnica.com/web/news/2011/06/has-the-internet-hamsterized-journalism.ars?ref=lorcandempsey.net)
### Books, artifactually and anecdotally speaking ...
URL: https://www.lorcandempsey.net/books-artifactually-and-anecdotally-speaking/
Last updated: 2021-06-08T00:32:01.000Z
## Artifacts
Anecdotally speaking ……. it seems to me that the artifactual and design elements of print books are coming more to the fore, albeit in different ways. As the use of ebooks grows this is not really surprising, as this change creates niche opportunities for experiences focused specifically on the possibilities of the print medium. Some related trends are interesting. First, we are seeing physical books repurposed, recycled, or ‘upcycled’ to perform other functions. Second, we are seeing a focus on the aesthetics of print books, and on book arts in general. And third, we are seeing – I think? – more interest in artists’ books, in books as art, …
## Anecdotes
Here are are some examples …
We attended the [Columbus ‘eco-chic craftacular’](https://www.columbuscraftacular.com/?ref=lorcandempsey.net) a couple of weeks ago, pleasantly located only a couple of minutes walk from our house. I was interested to see ‘upcycled’ books on at least two stands, where physical books were being repurposed as notebooks and cases. I remember being in the [bookstore](https://www.newberry.org/general/bookstore.html?ref=lorcandempsey.net) in the Newberry Library last year, and being interested to see some similar examples. At the time of writing, a search on Etsy.com returns over 3.5K resuls for ‘upcycled books’ and nearly 7K for ‘recycled books (of course, not all of these are in fact recycled books, but a lot are).
The marvellous Caustic Cover Critic has an [entry](https://causticcovercritic.blogspot.com/2011/06/notting-hill-editions.html?ref=lorcandempsey.net) about a new publisher, [Notting Hill Editions](https://www.nottinghilleditions.com/?ref=lorcandempsey.net). He praises the appearance and design of the books and notes …
> Several of the many, MANY, MANY future-of-the-book-in-the-face-of-ebooks pieces that have been cropping up in newspapers and online recently have mentioned that the way for physical books to survive in the future may be for them to be beautifully made objects. Notting Hill Editions are doing this just right–the look and feel of their books remind me of the precepts set out by master printer/typographer Daniel Berkeley Updike in his lovely The Well-Made Book. // [Notting Hill Editions](https://causticcovercritic.blogspot.com/2011/06/notting-hill-editions.html?ref=lorcandempsey.net)
Peter Hirtle alerted me to the Caustic Cover Critic in a comment on a [blog entry of mine](https://blog.oclc.org/lorcand/archives/002056.html?ref=lorcandempsey.net) which discussed book covers and other artifactual properties of books, in line with the comment in the piece quoted above.
Although, [as I noted recently](https://blog.oclc.org/lorcand/archives/002158.html?ref=lorcandempsey.net), I hope that we don’t see an either/or approach to publishing, where ‘beautiful’ books feel they don’t need an electronic parallel.
\[Here are the reissued Virago classics which I discussed in the [earlier blog entry](https://blog.oclc.org/lorcand/archives/002056.html?ref=lorcandempsey.net). Of course, the original Viragos had those iconic green covers. Note the remarks about the current position of Virago in the entry.\]
[](https://www.littlebrown.co.uk/NewsEvents/News-Archive/Virago-Modern-Classics?ref=lorcandempsey.net)
Finally, and anecdotally, what about artists’ books? Again, it seems to me that I see more on this topic, most recently, for example, [The Art of the Book in California: Five Contemporary Presses](https://museum.stanford.edu/news%5Froom/book-as-art.html?ref=lorcandempsey.net), an exhibition at the Cantor Arts Center at Stanford.
We lived in Bristol for many years, near the University of the West of England’s Bower Ashton campus, home of the [Department of Art and Design](https://www1.uwe.ac.uk/cahe/ad?ref=lorcandempsey.net). The Department has a [Centre for Fine Print Research](https://www.uwe.ac.uk/sca/research/cfpr/?ref=lorcandempsey.net), with a specialisation in [Artists’ Books](https://www.bookarts.uwe.ac.uk/about.htm?ref=lorcandempsey.net). I mention it here as it provides an entry point into a range of other materials. See for example, [Sarah Bodman](https://www.bookarts.uwe.ac.uk/bodmid.htm?ref=lorcandempsey.net)‘s very recent presentation [Artists and librarians: making art in and out of books \[PDF\]](https://www.bookarts.uwe.ac.uk/sbtalkldn.pdf?ref=lorcandempsey.net).
**Picture:** The feature image is a screen shot from the pages of the Centre for Fine Print Research, showing That Little Jackdaw, by Mel Brown.
**Note:** Amended cosmetically on 31 March 2021 to include feature image, headings and to fix spacing.
### Effective web presence ...
URL: https://www.lorcandempsey.net/effective-web-presence/
Last updated: 2020-10-28T09:05:43.000Z
We are growing used to the idea that simply making things available on the web does not necessarily make them widely discovered or discoverable. I have used the phrase [‘search engine interoperability’](https://www.google.com/search?q=%22search+engine+interoperability%22+lorcan&ref=lorcandempsey.net) in these pages already. This is a play on ‘search engine optimization’, which some do not like (although I think we should not avoid using a standard industry term). We value interoperability in libraries, and have spent a lot of time thinking about it and building it into our systems and services. However, we tend to think of interoperability in rather heavily structured terms, and to think of it as between library systems, rather than as between library systems and the rest of the web.
Those responsible for library websites, repositories or other systems are indeed now thinking much more about URL patterns, good titles and descriptions, sitemaps, feeds, and so on. In this context, I think it is useful to think about search engine interoperability as managing resources in ways which promote effective crawling, indexing and ranking by search engines. Thinking, in other words, about the robot users of our systems as well as the human users.
Given the importance of this topic, it is good to see that the Strategic Content Alliance in the UK has made several resources available to provide guidance on these topics.
1. [Guide to maximising your online presence ](https://www.jisc.ac.uk/media/documents/themes/content/sca/SCAMOREGuide.pdf?ref=lorcandempsey.net)(PDF)
2. [A checklist for value from the internet ](https://www.jisc.ac.uk/media/documents/themes/content/sca/SCAMOREChecklist.pdf?ref=lorcandempsey.net)(PDF)
3. [Reports from the field – Experiences from those ‘at the coalface’ April 2011](https://www.jisc.ac.uk/media/documents/themes/content/sca/SCAMOREFieldReports.pdf?ref=lorcandempsey.net) (PDF)
In the [high level description of this work](https://www.jisc.ac.uk/whatwedo/programmes/contentalliance/reports/maximisingonlineresources.aspx?ref=lorcandempsey.net) they evoke the SEO rationale:
> In an age when media, business, government and almost every aspect of modern society vies for the users’ attention, how can we ensure that the resources that are being created through public funds reach and engage with their constituent audiences?
The materials summarise good practice as interpreted by the Strategic Content Alliance. They go beyond what is usually thought of as SEO, and stay at a pretty general level. The reports from the ‘coal face’ are interesting, as site managers talk about their experiences trying to enhance their web presence.
Some of the same ground, with examples of good and bad practice, was covered by Ed Summers of the Library of Congress in a presentation that was well received at a DPLA meeting we both attended recently. Here it is …
### Analysing influence .. the personal reputational hamsterwheel
URL: https://www.lorcandempsey.net/analysing-influence-the-personal-reputational-hamsterwheel/
Last updated: 2020-10-28T09:05:45.000Z
Analysing influence has been a central part of academic life. We are very familiar with citation analysis. This is possible because the system allows that metric to be measured and it is seen to be meaningful.
As new measures have become possible in a web environment they too have been taken up. See for example the ‘top of’ lists at [SSRN](https://www.ssrn.com/?ref=lorcandempsey.net) or the elaborate set of rankings from [RePEc](https://ideas.repec.org/top/?ref=lorcandempsey.net).
And we are also very familiar with the interest in such measures from individual researchers (it would be interesting to see some analysis of disciplinary differences here – are physicists more interested in their H-Index than geographers?). It is interesting to see influential economics blogger [Gregory N Mankiw](https://gregmankiw.blogspot.com/?ref=lorcandempsey.net) reference the RePEc list from time to time, for example, as well as other rankings.
As we began to use the web for personal interaction, new measures arose. I am thinking in particular of Technorati and blog rankings which were of interest for a while, although less so now as the blogging environment has changed.
And now we have Twitter. I have been looking at [Klout.com](https://www.klout.com/?ref=lorcandempsey.net) recently … with a mixture of intrigue and dread. Klout describes itself as the “standard for influence” and assigns scores using a proprietary algorithm based on Twitter and Facebook interactions and relationships. What is especially interesting about it is how it is trying to leverage the results of its analysis. An interview with founder Joe Fernandez provides some context. “If Klout CEO and co-founder Joe Fernandez has his way, the Klout score will become a new way of measuring people and their influence online.” He makes a comparison with credit ratings:
> “Klout is basically your social credit score,” Fernandez says. “Consumers should care because it affects the way employers, companies and everyone looks at your ability to spread information as a critical part of the attention economy today.”
They have an interesting business model.
> Then Klout matches relevant influencers to relevant brands, which provide special offers, especially perks like previews on new product launches. For example if you are influential about technology, HP might send you a free laptop. Or you could get a free upgrade at your favorite hotel.
> The idea is that these influencers will create social media buzz that can help a product take off. (People have to sign up with Klout to receive the offers.)
Klout seems to be coming over my horizon more often. I have seen several stories about its use in recruitment, where a person’s Klout score is a factor in assessment. Given this interest, it is only natural that there are also critiques of this type of twitter analysis approach in general and of Klout in particular. A moment with Google for example reveals [this](https://michelletripp.com/index.php/2010/08/31/klout-do-you-have-enough-influence-to-get-the-job/?ref=lorcandempsey.net) and [this](https://www.talentzoo.com/digital-pivot/blog%5Fnews.php?articleID=9173&ref=lorcandempsey.net).
Other services exist: [Twitalyzer](https://www.twitalyzer.com/?ref=lorcandempsey.net) (“serious analytics for social business”) for example and the interesting [PeerIndex](https://www.peerindex.net/?ref=lorcandempsey.net) (“understand your social capital”).
It is clear that personal or social analytics – based on Twitter and other services – is of great interest, and several companies are exploring how to monetise the measurement of personal reputation or influence. The Klout model suggests how such influence might be fungible and gestures to a future in which one’s score might lead to preferential access to services or products. This is an unsurprising development in a world where data about more and more of what we do is mined to provide intelligence for other services (what we spend for example, or where we go on the web).
I need to go now and catch up on my tweeting. I can’t let my score drop … I wonder could it lead to an upgrade on my next transatlantic flight 🙂
### Sourcing and scaling: the University of California
URL: https://www.lorcandempsey.net/sourcing-and-scaling-the-university-of-california/
Last updated: 2020-10-28T09:05:50.000Z
I was interested to see Heather Christenson describe The Hathi Trust as a collaboratively sourced web scale research library in a recent article (Hathi Trust: a research library at web scale. [PDF](https://www.hathitrust.org/documents/christenson-lrts-201104.pdf?ref=lorcandempsey.net)).
This reminded me of an entry I wrote a while ago about [sourcing and scaling](https://blog.oclc.org/lorcand/archives/002058.html?ref=lorcandempsey.net) (which is referenced in the article). In a shared network environment, one of the most interesting issues facing libraries is how appropriately to source and scale activities.
A few years ago, this activity would have been sourced within the institution: each library would have developed its own infrastructure, user interface, local community outreach, and so on. Now, such an impulse is questioned. It makes sense to source something like this collaboratively. And it is provided at the level of the network: its target user population is the population of web users.
Questions about sourcing and scaling are becoming much more common as the logic of the network reconfigures patterns of information production and use. What does it make sense to do at institutional level? What does it make sense to source elsewhere (repository services in the cloud, for example, or institutional email services from Google)? And what should be left entirely to other providers? At what level, or scale, is it best to do things? Locally, or within a consortium, or ….?
Think of four sourcing options: Self (provide it locally), collaborative (provide it within a group), public (provided through state or national activity), or third party (provided by another commerical or non-commercial entity).
Think of three scaling options: local or institutional, group, and web scale.
These can be put together to give a variety of options. So, for example, Tripod, the shared catalog of Swarthmore, Haverford College and Bryn Mawr, is a collaboratively sourced group solution. PubMed is a web scale public offering. And, as already noted, Hathi Trust is a collaboratively sourced web scale service.
An interesting contrast between the US and many other parts of the world is that often what is done collaboratively in the US may be done through a public agency elsewhere. For example, Christenson contrasts the HathiTrust as a collaborative activity with something that the JISC, an activity of the public higher education funding councils, might provide in the UK. It is also common in many countries outside the US to have publicly supported union catalogue and related activities.
We can observe two trends. First, there is a trend towards externalisation: libraries are looking to collaboratively source activities or to outsource them to third parties. Think of collaborative activities around managing down print collections here, the West project for example, or the growth of shared library systems (the Orbis Cascade Alliance, for example, recently issued an [RFI](https://www.orbiscascade.org/index/shared-integrated-library-system-team-2011?ref=lorcandempsey.net) about a shared integrated library system). Think of the growing interest in cloud-based sourcing of systems and services.
Second, there is a trend to ‘move up’ in the network, by doing more things at group level within consortia or public contexts (think of OhioLink or Summit), or by leveraging network level services (think of social networking sites, for example).
The current economic environment further encourages these trends. Institutions look for economies of scale through collaboration. And they also want to focus attention on high value areas, and outsource routine or shared activities.
I was reminded of these issues while reading a very interesting internal report of the University of California on library services. This is the interim report of the systemwide Library Planning Task Force, convened under the auspices of the Systemwide Library and Scholarly Information Advisory Committee ([splashpage](https://libraries.universityofcalifornia.edu/planning/taskforce/?ref=lorcandempsey.net), [PDF](https://libraries.universityofcalifornia.edu/planning/taskforce/interim%5Freport%5Fpackage%5F2011-05-09.pdf?ref=lorcandempsey.net) of report and related material).
A stark environmental picture is presented:
- The libraries will experience budget reductions of as much as $52M or 21% of their current budget base over the next six years. “To put this into perspective, this cut is greater than the total library budget of any single UC campus, and roughly equivalent to the budgets of three of our mid-sized campuses, all AAU members.”
- The libraries will likely lose the equivalent of $17M in buying power in the same period given publisher price increases. “This is equivalent to the current library materials budgets of two mid-sized campuses, and means a reduction in the systemwide acquisition rate of about 200,000 items per year.”
- Existing facilities will run out of space for new materials over the next 5-7 years, at the same time as “demand increases for extended hours and services and technologically well-equipped and flexible learning environments in the libraries’ prime campus locations”.
They go on to observe that the impact of these factors can be mitigated through collaboration. They propose four strategies:
1. Expand and collectively manage shared library services.
2. Support faculty efforts to change the system of scholarly communication.
3. Explore new sources of revenue.
4. Improve the existing framework for systemwide planning, consultation, and decision-making.
Of course, the University of California is an unusual institution, bringing together some of the world’s major universities in a shared organizational framework. One result of this shared framework has been the [California Digital Library](https://www.cdlib.org/?ref=lorcandempsey.net), which concentrates operational and innovation capacity for the whole system. CDL has been responsible for some major services, and is an active partner in the Hathi Trust. Another is the Regional Library Facilities, north and south, for managing print collections. A major recommendation is that the range of such shared services should grow, whether sourced within the UC universities or externally.
Cooperation is difficult. Especially where money flows, and impact needs to be seen, at the institutional level. However, given the existing level of shared services, the organizational framework, and the pressures described in this report, it will be interesting to watch what services the UC libraries move to a shared environment over the next few years.
p.s. The report describes the Worldcat Local-based Next Generation Melvyl described in these terms:
> The Next‐Generation Melvyl (NGM) initiative moves the discovery of information for researchers and students to the highest networked level. The initiative takes access to the highest level of aggregation and is vital for the most effective provision of information access and services. Strategically, NGM also positions the UC Libraries to provide aggregated access to a significantly increasing array of full‐text information resources: e.g., the millions of digitized books in the Google Books Project and the HathiTrust.
### Academic reputation enhancement ... redux
URL: https://www.lorcandempsey.net/academic-reputation-enhancement-redux/
Last updated: 2021-04-02T02:14:51.000Z
Two things prompted this note ….
First, there is an interesting report in the current issue of Nature on the ‘online image’ \[[editorial](https://www.nature.com/nature/journal/v473/n7346/full/473124a.html?ref=lorcandempsey.net)\] or ‘online reputation’ \[[article](https://www.nature.com/news/2011/110511/full/473138a.html?ref=lorcandempsey.net)\] of researchers and what their attitude is to it and to managing it. More of this later.
Second, I have recently returned from Bangkok where I participated in the [9th Annual Library Leadership Institute](https://lib.hku.hk/leadership/2011.html?ref=lorcandempsey.net) organised by the University of Hong Kong Libraries. Over 40 librarians from East Asia gathered for several days. The strongest cluster of themes to emerge in discussion, it seemed to me, was around the need for greater engagement in the research and learning activities of their campuses. For example, there was much discussion of repurposing space to support better learning experiences. In this context I was interested to hear several participants talk about advising faculty about publication venues and online reputation. This was partly related to university positioning in national or international ranking or assessment activities.
This connected well with one of the vendor presentations. Airani Ramli gave an interesting overview of the [SciVal suite of products](https://scival.com/?ref=lorcandempsey.net). This is an example of what I have in the past called [research analytics](https://blog.oclc.org/lorcand/archives/002089.html?ref=lorcandempsey.net) (and I notice that Thomson Reuters now collects a range of similar activities under that [heading](https://researchanalytics.thomsonreuters.com/?ref=lorcandempsey.net)).
The focus of the presentation was on how research analytics could support strategic university research directions. They could help identify comparative strengths and gaps, potential collaborators or targets for hire, and so on. Again the academic research assessment and ranking environment provided important context. In addition to the increasing visibility of international ranking exercises such as that carried out by the Times Higher, there are various national assessment regimes. I was very interested to discover that about 70% of sales of SciVal were to the research office or equivalent administrative unit in the university, and about 30% to the library. While there might be a general feeling that it is important for the library to be a partner in this type of work, it is not always the case. (I was interested to see the University of Leicester Library [advertise](https://www.jobs.ac.uk/job/ACN636/bibliometrician/?ref=lorcandempsey.net) for a Bibliometrician again recently.)
This speaks to the **institutional** interest in optimizing research performance as measured by bibliographic analysis. The Nature survey looks at **individual** researcher interest in managing their online reputation. They report that “up to 10% of scientists have considered using external services to manage their online reputations” and, in an editorial, go on to say ..
> Enhancing visibility and promoting a digital image may strike some as unsavoury, but it is not. Researchers are right to promote themselves and their work in a reasonable capacity. The Internet has provided a tremendous tool to do this effectively. // [Online image](https://www.nature.com/nature/journal/v473/n7346/full/473124a.html?ref=lorcandempsey.net)
Nature recruited 840 researchers through email and social networking sites, and they don’t discuss how this might influence their results. They also hang the story on the case of somebody who has worked with a commercial company to repair their reputation, something which I thought was a distraction from the core activity of amplifying academic reputation.
> Of 840 respondents, 77% say that their personal online reputation is important to them and 88% say that the online reputation of their work is important (see ‘A name online’). Thirteen per cent say that they have used search-optimization strategies to improve the visibility of their research, and as many as 10% say they have considered using external services to manage their online reputations (click here for the full poll results).
> Several researchers have set up biographies on the online site Wikipedia — the online encyclopaedia that practically anyone can edit — or edited entries to include references to their own papers. And many simply use social-networking sites or blog regularly about science, which can help to shape a digital persona. The poll and subsequent interviews suggest a growing recognition in the scientific community: maintaining a prominent online presence can help researchers to network with colleagues, share resources, raise money and communicate their work. “It is incredibly valuable,” says Gia Milinovich, a web producer based in London who has studied scientists’ use of Twitter. // [Online reputations: best face forward](https://www.nature.com/news/2011/110511/full/473138a.html?ref=lorcandempsey.net)
In addition to the longstanding practice of checking for citations to their work or their group’s work, many researchers are now tracking mentions on Google, and taking steps to enhance their network presence and [attract](https://blog.oclc.org/lorcand/archives/002161.html?ref=lorcandempsey.net) attention.
Against this background it is not suprising to see the many options that individuals and institutions have to create personal profiles. Think of Mendeley, Zotero and [WizFolio](https://wizfolio.com/?ref=lorcandempsey.net). Or the [Selected Works](https://works.bepress.com/?ref=lorcandempsey.net) pages from BePress and [COS Profiles](https://www.cos.com/?ref=lorcandempsey.net). Or [Vivo](https://vivoweb.org/?ref=lorcandempsey.net) or [BibApp](https://bibapp.org/?ref=lorcandempsey.net). And multiple other disciplinary, insitutional and individual approaches. The University of Hong Kong [Scholars’ Hub](https://hub.hku.hk/?ref=lorcandempsey.net), for example, includes local data alongside data pulled from Scopus and Web of Science with an aim of making HKU authors and their research “very visible”.
We have been interested in this area under our ‘[Research information management](https://www.oclc.org/research/activities/rim.htm?ref=lorcandempsey.net)‘ strand of work.
Thinking about how faculty, departments and the university effectively present themselves presents interesting internal and external boundary issues. Organizationally, there is an intersection of interests between department/school, library, marketing/PR, and Research Office, alongside the individual. And then what is it appropriate to do at the institutional level, alongside what happens in various external network services.
**Related entries:**
- [The power of pull redux … with examples](https://blog.oclc.org/lorcand/archives/002161.html?ref=lorcandempsey.net)
- [Reputation enhancement](https://blog.oclc.org/lorcand/archives/002011.html?ref=lorcandempsey.net)
### Elected ...
URL: https://www.lorcandempsey.net/elected/
Last updated: 2022-11-08T16:25:27.000Z
I thought it would be nice to record that a couple of my colleagues had recently been elected to positions of note …
[Jackie Dooley](https://www.oclc.org/research/people/dooley.htm?ref=lorcandempsey.net), Program Officer, has been elected Vice-President/President Elect for 2011/12 of the American Society of Archivists. This is really a wonderful tribute to Jackie’s contribution over many years. Most recently, Jackie has published results of a major survey of special collections and archives, *Taking Our Pulse: The OCLC Research Survey of Special Collections and Archives* \[[pdf](https://www.oclc.org/research/publications/library/2010/2010-11.pdf?ref=lorcandempsey.net)\].
[Lynn Silipigni Connaway](https://www.oclc.org/research/people/connaway.htm?ref=lorcandempsey.net), Senior Research Scientist, has been elected ALA Library Research Round Table Vice-chair/Chair-elect. Her term begins after ALA Annual. Lynn is the co-author of [Basic research methods for librarians](https://www.worldcat.org/oclc/548555591?ref=lorcandempsey.net) and leads our [user behavior studies](https://www.oclc.org/research/activities/ubs.htm?ref=lorcandempsey.net).
### Decentred network presence
URL: https://www.lorcandempsey.net/decentred-network-presence/
Last updated: 2020-10-28T09:06:03.000Z
We still tend to think of the website as the focus of institutional presence on the network. And, often, mobile or other presences are seen as somehow derivative. Clearly the importance of mobile – especially now with tablets and smartphones – has changed that view and changed the way we think about design and expectations. We are used to how Amazon, say, or Facebook, have multiple network presences with which we can interact. Think of Amazon: website, widgets, apps, Kindle, and so on.
The boundary between ‘mobile’ and fixed has dissolved into multiple connection points, each with its own grade of experience and functional expectations (the mobile phone, the desktop, the xBox or Wii, the Kindle, the media centre, the widget, the social networking site). At the same time, more functions are being externalised to network-level providers of communications and other services (e.g. social networking services, Youtube, Flickr, …). Providing service in this environment is very different than in one where the model assumes a personal desktop or laptop as the place where resources are accessed and used and the institutional website as the unified place where they are delivered. As our entry points have become more varied, what might have been on the website is being variably distributed across these entry points. So, selected information may be on a Facebook page, selected functionality may be available through apps and Widgets, selected communications may be available on Twitter, and so on.
This was made much more real to me in a very effective way when a colleague pointed me at a great presentation from [Yiibu](https://yiibu.com/?ref=lorcandempsey.net):
**[Beyond the mobile web by yiibu](https://www.slideshare.net/yiibu/beyond-themobilewebbyyiibu?ref=lorcandempsey.net "Beyond the mobile web by yiibu")**
View more [presentations](https://www.slideshare.net/?ref=lorcandempsey.net) from [yiibu](https://www.slideshare.net/yiibu?ref=lorcandempsey.net)
I liked their definition of the ‘problem space’ on [slide 61](https://www.slideshare.net/yiibu/beyond-themobilewebbyyiibu/61?ref=lorcandempsey.net) where they note that websites are now designed to operate in smaller, more varied and far less predictable environments.
However, what especially drew my attention was the discussion of building distributed experiences rather than ‘giant all-purpose containers’. This begins at [slide 119](https://www.slideshare.net/yiibu/beyond-themobilewebbyyiibu/119?ref=lorcandempsey.net) and the graphics used to illustrate trends are particularly striking. They discuss how particular activities began to be decoupled as communication, for example, moved to blogs, Twitter and Facebook. Product marketing, recruiting, and other activities may be similarly decoupled to other sites, YouTube, LinkedIn and so on. Here is a picture:
[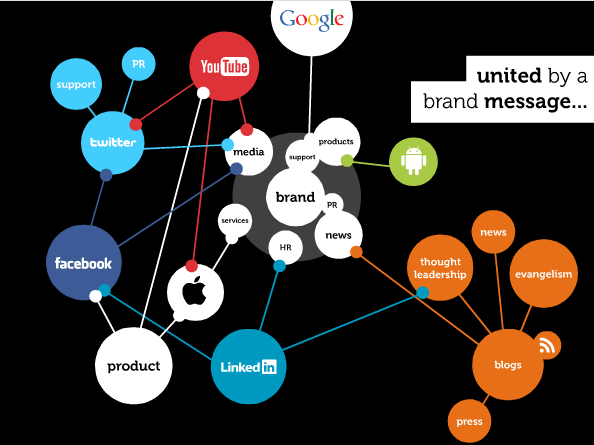](https://www.slideshare.net/yiibu/beyond-themobilewebbyyiibu/125?ref=lorcandempsey.net)
They work through examples of the distributed network presence of Google, Amazon and the BBC. They show how each is an ‘ecoystem of touchpoints, utilities and conversations’ spread out over a variety of network presences and unified by brand. Here is the Amazon ecosystem:
[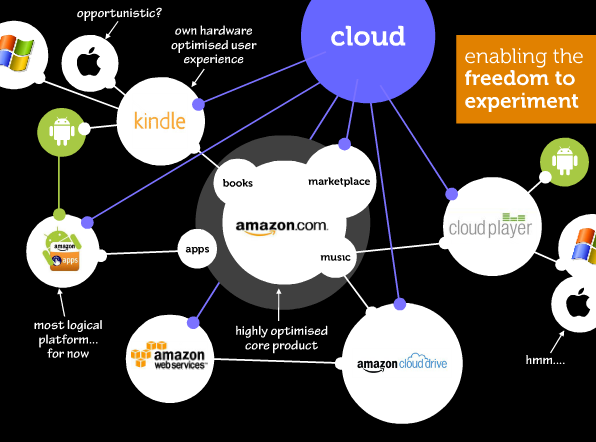](https://www.slideshare.net/yiibu/beyond-themobilewebbyyiibu/129?ref=lorcandempsey.net)
I thought this was very suggestive and immediately wondered what the equivalent picture for a library would look like.
Note: the pointer to the presentation was via [The Proverbial Lone Wolf Librarian’s Weblog](https://lonewolflibrarian.wordpress.com/?ref=lorcandempsey.net), which has a nice assembly of presentations.
### Lost in translation .. redux
URL: https://www.lorcandempsey.net/lost-in-translation-redux/
Last updated: 2020-10-28T09:06:06.000Z
I am at [The 9th Annual Library Leadership Institute](https://lib.hku.hk/leadership/2011.html?ref=lorcandempsey.net) in Bangkok. This event is organized by The University of Hong Kong [Libraries](https://www.lib.hku.hk/?ref=lorcandempsey.net) and brings together librarians from around Asia. It has a dual purpose: to develop and enhance management and leadership qualities and to enhance collaboration and foster relations between libraries.
There are just over 40 delegates and there is plenty of interaction. I am enjoying it – in general I very much prefer smaller intimate events where you get a chance to hear people discuss their achievements and challenges in a more extended way. From my point of view, as I don’t actually work in a library, this is quite important. This event has a special interest given the diversity of nationalities represented. It is interesting seeing common issues expressed against some difference of national policy and funding regimes.
In the last few years I have found larger, commercial events of less and less interest. While I understand that much of the value is in networking, I increasingly find that one is likely to have a good sense of what many speakers will say from exposure to their network presences – blogs, twitter, or papers.
I am writing this at 3.00 AM Thai time, however. I hope to go back to sleep soon 🙂 but it did bring to mind my comments [several years ago](https://blog.oclc.org/lorcand/archives/000243.html?ref=lorcandempsey.net) about Lost in Translation, slightly edited here:
> [Lost in Translation](https://www.imdb.com/title/tt0335266/?ref=lorcandempsey.net "Lost in Translation (2003)") got the screenplay Oscar. I saw this on the flight to Australia, appropriately, and again on DVD. I liked the way it showed the dislocating effect of jet lag, and the glancing sense of elsewhere the brief business visit gives.
> Note 25 March: Noted [comments](https://dervala.net/2004/02/27/lost-in-translation/?ref=lorcandempsey.net) by Dervala on *In America* and *Lost in Translation*.
p.s. I had a special interest in the Oscars that year as my [brother in law](https://www.worldcat.org/wcidentities/lccn-no2004-80421?ref=lorcandempsey.net) was the co-producer of [*In America*](https://www.worldcat.org/title/in-america/oclc/054792166?ref=lorcandempsey.net) which lost out to [*Lost in Translation*](https://www.worldcat.org/title/lost-in-translation/oclc/53816203?ref=lorcandempsey.net).
p.p.s. It is a while since I have looked at [Dervala.net](https://dervala.net/?ref=lorcandempsey.net). I notice it has not been updated for a while. When memes were popular I listed it as one of my favorite non-library blogs ([Memetic](https://blog.oclc.org/lorcand/archives/001318.html?ref=lorcandempsey.net)). “[My blog is a message in a bottle with a FedEx tracking number](https://dervala.net/about/?ref=lorcandempsey.net).”
### Advocacy: public library as amenity and necessity
URL: https://www.lorcandempsey.net/advocacy-public-library-as-amenity-and-necessity/
Last updated: 2021-03-29T04:09:35.000Z
Downward pressure on the cost of public services creates issues for public libraries. A growth in advocacy is a natural response, and this in turn creates pressing questions about value, and in particular about how different stakeholders potentially perceive value differently. Who one is addressing, and with what message, has become very important.
These topics were addressed in a strongly worded article about public libraries from Christopher Caldwell in *The Financial Times* last week. It appeared under the provocative – although misleading – title “[It is the fate of libraries to die](https://www.ft.com/cms/s/0/784d85f8-6790-11e0-9138-00144feab49a.html?ref=lorcandempsey.net)“. The context is the public debate around library cutbacks and closures in the UK.
He opens by referring to recent arguments for public libraries by author Zadie Smith, and suggests that her advocacy is misdirected. He characterizes the issue as follows:
> Libraries are imperilled for a different reason: because local councils feel they have better things to do with the money. This winter, Keith Mitchell of Oxfordshire county council, discussing the possibility of closing 20 of 43 local libraries, warned that if the libraries were not cut, something else would be, “and that will most likely be elderly care, learning difficulty care and care for people with mental health problems because those are the biggest bits of our budget”.
Caldwell has some harsh thing to say about public libraries. He calls them ‘reactionary’ for limiting borrowing rights to local residents. He asserts that “like the military sector, the library sector confounds every attempt to make it more efficient”.
He suggests a parallel with a general government dynamic: “In olden times, people wanted a state that built great monuments, even at the price of being distant. Nowadays, people prefer a state that is intimate and therapeutic, one that will solve the practical problems of day-to-day life.” Libraries are often monumental, but answer the needs of the individual. Although he presents this as an issue, I would see it as more of an achievement. Libraries have married the civic and the intimate in successful ways.
One might argue with his perceptions about public libraries, but this is less important than his main point about influencing funding decisions. In asking what makes libraries so hard to defend against cuts, he turns to an article by Eleanor Jo Rodger in *American Libraries*, [Public Libraries: necessities or amenities](https://issuu.com/seanfitzpatrick/docs/0809/49?viewMode=presentation&zoomed=true&zoomPercent=100&zoomXPos=0.5&zoomYPos=0.25338491295938104&ref=lorcandempsey.net). I have discussed the value of other work by Rodger [in these pages](https://blog.oclc.org/lorcand/archives/001424.html?ref=lorcandempsey.net), and Caldwell calls this a ‘magnificent essay’.
Rodger starts in a similar place. As public funding is reduced, public library funding will also be reduced as “there simply isn’t enough money to go around”. She repeats the important point I highlighted in the earlier post, that local government decisions will reflect **their** understanding, not ours.
She briefly reviews the ‘justification’ language of public libraries in the US, noting the founding educational impulse, the association of that with books and reading, support for an educated citizenry, and then a ‘right to information’ agenda. However, she suggests that there is currently a ‘fuzzy mix of language about importance, equity and use’ used in support of public library budgets.
She then introduces the distinction between ‘necessities’ and ‘amenities’ that appealed to Christopher Caldwell. Necessities are those things to which we have a right because they are seen to be centrally socially valuable. For example, fire and police services are justified by an appeal to the right of public safety. Amenities are those things to which we don’t believe we have a right, but which we may prefer are provided by local government because there are economies of scale in such general provision. Garbage collection is an example here.
In several very interesting paragraphs, Rodger then discusses how public library services may be seen to be both important amenities and valued necessities. For example, equity of access to information in mixed or low-income communities may be seen as a necessity. However, she suggests that most uses for most users tend to fall in the amenities category.
She then uses this distinction to talk about advocacy. Library users, she suggests, may be mobilized to advocate for the public library as amenity. On the other hand, she suggests that library supporters – who may not necessarily use the library – may believe in the transformative role of public libraries. They can be mobilized as advocates for the library as necessity, providing homework help or business information for local entrepreneurs.
Caldwell concludes his article with a recommendation for public library advocates: “As a matter of politics defending amenities may work better than defending necessities”. This is in contrast to the transformative arguments advanced by Zadie Smith, Philip Pullman and others which defend the library as necessity.
He doesn’t really say why he thinks this is so, or how he thinks different arguments play in council corridors. (Indeed, the overall continuity of the article seems interrupted in several places, as if it were shortened from a longer piece.)
It was interesting to see the issue discussed in this way in the pages of *The Financial Times*. It was also interesting to be referred again to Eleanor Jo Rodger. Her article emphasises the need to understand the motivations of those who make decisions about library funding, presents an interesting framework for characterizing library value, and notes how effective advocacy will depend on mobilising different groups depending on the values which are important to them.
p.s. Rodger notes the work of my OCLC colleagues on creating support for public library funding in the US, [*From awareness to funding*](https://www.oclc.org/reports/funding/default.htm?ref=lorcandempsey.net). This emphasises the need to target messages to particular segments, and also notes that those who most strongly support the library believe in its transformative role. This report influenced the subsequent [Geek the Library](https://www.oclc.org/us/en/reports/geekthelibrary.htm?ref=lorcandempsey.net) library advocacy framework.
### Lam-inating libraries ... redux
URL: https://www.lorcandempsey.net/lam-inating-libraries-redux/
Last updated: 2020-10-28T09:06:13.000Z
The shared interests between libraries, archives and museums (LAMs) has been an important [line of work](https://www.oclc.org/research/activities/lamsurvey/default.htm?ref=lorcandempsey.net) for OCLC Research. It is also of course a recurring service, organizational and policy issue in many contexts.
A related issue is also of considerable interest for libraries. As we move into a digital environment, library work can increasingly understand and benefit from archival and museum perspectives and professional practice.
As libraries digitize primary materials, or as they begin to curate research data or learning materials, an archival perspective becomes more important. Provenance and context are of interest, and changes to resources over time need to be tracked and managed. Appraisal practices may have lessons. The value of resources as **evidence** becomes central.
As libraries provide access to abundant digital materials, how to selectively present them or to construct narratives around them becomes more interesting. Thinking explicitly about structured learning support is a topic. The notion of **exhibition** comes into play, a central museum activity, alongside education.
Note: this is a slightly updated version of a [blog post](https://blog.oclc.org/lorcand/archives/002076.html?ref=lorcandempsey.net) I did last year. This attracted some interesting comments.
Note 2: There is probably a blogging best practice about recycling or amending entries. I have chosen to republish rather than update the content and date of the original entry. Which means that any comments do not carry over.
### A small note on sustainability, business models and words ...
URL: https://www.lorcandempsey.net/a-small-note-on-sustainability-business-models-and-words/
Last updated: 2020-10-28T09:06:16.000Z
Sustainability is an important aspect of digital library initiatives. Partly because they are often funded by grant or special monies, out of the mainstream of business as usual. For this reason, it is not surprising to see how much attention the topic has received.
Before coming to OCLC I worked for [JISC](https://www.jisc.ac.uk/?ref=lorcandempsey.net) in the UK. JISC provides shared services to UK higher and further education. An important part of this is its support for applied R&D in universities and colleges through its grant programmes. You can get a sense of the breadth and diversity of these programmes on the [website](https://www.jisc.ac.uk/whatwedo/programmes.aspx?ref=lorcandempsey.net).
You will also find guidance for what is called [Exit and sustainability plans](https://www.jisc.ac.uk/fundingopportunities/projectmanagement/planning/exit.aspx?ref=lorcandempsey.net) in the project management area of the site along with this note:
> You must develop an exit/sustainability plan on what should happen to project outputs at the end of the project, and to explore which ones should be sustained further and how.
Another example of such attention is provided by the work of Ithaka S+R on [Sustainability and revenue models for online academic resources](https://www.ithaka.org/ithaka-s-r/strategyold/sustainability-and-revenue-models-for-online-academic-resources?ref=lorcandempsey.net). I discussed this in a previous blog entry: [Entrepreneurial skills are not given out with grant letters](https://blog.oclc.org/lorcand/archives/001947.html?ref=lorcandempsey.net). I noted one of the themes of the report as follows:
> Third was the acknowledgement that projects may not naturally think of ‘value’ in business or commercial terms, and indeed there may sometimes be an antipathy to commercial enterprise. (This is not the only measure of ‘value’.) \[ [Entrepreneurial skills are not given out with grant letters](https://blog.oclc.org/lorcand/archives/001947.html?ref=lorcandempsey.net)\]
I was reminded of this a while ago when somebody resisted the use of the expression ‘business model’ in a conversation about the ‘sustainability’ of a resource on the grounds that it was not a commercial or business activity. I suppose that an important part of this is resistance to the idea that financial metrics are the only measure of value.
That said, sustainability involves securing enough revenues to continue to operate, whatever type of organization is involved.
Turning to Wikipedia, I was quite surprised at how much emphasis the entry on business models put on profit. It usefully points to a working paper providing an literature review: The business model, theoretical roots, recent developments and future research \[[PDF](https://www.iese.edu/research/pdfs/DI-0862-E.pdf?ref=lorcandempsey.net)\]. Interestingly, this paper shows that the term business model really only became popular in the mid-1990s, perhaps influenced by the search for new business models in an Internet environment. They also note a lot of variety in definition.
Anyway, all of this is by way of introduction to a modest statement: it seems to me to be reasonable to say that ‘sustainability’ involves developing a viable business model.
### Sympathy for Microsoft ...
URL: https://www.lorcandempsey.net/sympathy-for-microsoft/
Last updated: 2022-11-10T18:40:31.000Z
We are watching a handful of companies battle to support our work and learning lives, our communication, entertainment and social network. The good guys are no longer quite such good guys (Apple, Google?). And the CEO of Facebook [can characterize](https://www.fastcompany.com/1698672/underdog-microsoft-dominates-earnings-are-google-and-apple-now-the-bad-guys?ref=lorcandempsey.net) Microsoft as the underdog.
My title is prompted by the [very fair review](https://www.nytimes.com/2009/09/17/technology/personaltech/17pogue.html?ref=lorcandempsey.net) of the Zune HD by David Pogue from a couple of years ago. He suggests sympathy for Microsoft is an appropriate response because despite the many great qualities of the Zune, its success is not assured.
> No, the problem is the iPod’s head start — its catalog of music, movies, apps and accessories are ridiculously superior to the Zune’s — and the Zune’s reputation as the player for weirdos and losers. Among the under-25 set, “Zune” is a punch line.
> It’s an outdated joke; the Zune HD player isn’t perfect, but it’s every bit as joyful, polished and satisfying as its rival. The question is whether Microsoft will stick it out long enough to close the catalog gap, the ecosystem gap and the image gap. \[[Tuning In a Zippier Zune](https://www.nytimes.com/2009/09/17/technology/personaltech/17pogue.html?ref=lorcandempsey.net)\]
It looks as if his question may have just been partly answered by [current rumors](https://www.washingtonpost.com/blogs/faster-forward/post/microsoft-looks-like-its-zeroing-out-the-zune/2011/03/14/ABP3NnV%5Fblog.html?ref=lorcandempsey.net) that Microsoft is going to end of life the Zune HD device because of “tepid demand”. I say ‘partly’ because the software and Zune Pass service continue, especially as they are a part of the Windows Phone 7 configuration. Whatever the outcome, the Zune still has a tiny share of the market. The Zune HD may have arrived too late and received too little support.
Now as regular readers of this blog know, I have a Zune HD. I am one of those sad people the Zune news stories refer to in such pitying terms. I bought it a while after leaving my iPod on a plane. I was influenced by several reviews which liked it, but to be honest, I was largely motivated by a desire to get something that was not an iPod. This is partly because of the flatness of the iTunes experience, partly in resistance to total Apple envelopment of a market, and partly because of the Zune Pass subscription model.
My expectations were greatly exceeded. I love it. This is the first time I have ever been sad to hear that a consumer product might disappear. And whatever Microsoft’s business reasons, I am a little frustrated as a consumer that something I like so much has clearly not got a lot of ongoing attention. I mentioned three elements. Consider these comments …
1. Software: The software design is fluid, beautiful and incredibly responsive ([David Pogue](https://www.nytimes.com/2009/09/17/technology/personaltech/17pogue.html?ref=lorcandempsey.net)).
2. Hardware: The Zune HD continues to rank among our all-time favorites in terms of industrial design ([Engadget](https://www.engadget.com/2010/09/01/zune-hd-could-have-all-new-model-in-the-works/?ref=lorcandempsey.net))
3. Service: Once you are used to having the unlimited tracks that Spotify or Zune grants you it is difficult to revert back to the older paid-for methods of iTunes. ([Daily Telegraph](https://www.telegraph.co.uk/technology/tv-audio-reviews/8046629/Living-a-musical-life-in-the-clouds.html?ref=lorcandempsey.net))
I have found the subscription model – Zune Pass – congenial. Now, as [I have noted before](https://blog.oclc.org/lorcand/archives/002107.html?ref=lorcandempsey.net), my musical knowledge and tastes are shallow, so it may not be difficult to satisfy me. However, I have found that I now listen to more and range more widely than I would have before. Above all I love the experience. The [Metro Design](https://en.wikipedia.org/wiki/Metro%5FDesign%5FLanguage?ref=lorcandempsey.net) elements work really well. The type is lovely. Pictures are used imaginately. Navigation is natural and satisfying: it invites you to explore. It is also ideal for those [interstitial reading](https://blog.oclc.org/lorcand/archives/002081.html?ref=lorcandempsey.net) moments, as bios and related artists are included on the device. The Zune marketplace and PC software works reasonably well, although it can occasionally feel a little unfinished. Integration with TV and Xbox are welcome. It is all that bit more edgy than we expect from Microsoft. And after 18 months or so, it is still a pleasure to use. So long as you only want a music player, that is. Not many apps here.
I borrowed a Windows Phone 7 device – a Samsung Focus – from work recently. I liked it quite a bit, although I only got to use it for a couple of days. And interestingly my children liked it too. Why don’t we know more about it? asked my daughter. Again, the Metro Design elements are very attractive. That said, I wondered whether it was a bit too rich for a network environment, where you had to wait a little more for some transitions.
It will be intriguing to see how Microsoft fares with Windows Phone 7\. They have taken a risk and gone with an alternative model to the Android/iPhone screen of apps. There is imagination and pleasure here as well as utility. Of course that may not be enough, as, as Pogue notes above, the whole ecology is important. Android may still have a geeky lift and Apple a cool one, but they are also fighting for world domination nonetheless. Microsoft is certainly the underdog here; it will be interesting to see if they remain so.
I don’t follow Microsoft business activities [or organization](https://arstechnica.com/microsoft/news/2010/05/is-microsofts-shake-up-enough-to-get-ed-back-on-track.ars?ref=lorcandempsey.net) closely enough to understand the significance of the departure of Bach and Allard. Nor do I know who is responsible for the design of the Zune HD. Whoever they are, they deserve credit for making something very fine. I will miss it when the time comes to move on.
Incidental p.s. My son saved for an Motorola Atrix. He returned it because he found the Motorola Blur interface intrusive and they blocked the bootloader so he could not load alternative ROMs. In effect, the ‘geeky’ attractions of Android for him were diminished by product choices made by Motorola.
### Internal boundary changes .. the library in the institution
URL: https://www.lorcandempsey.net/internal-boundary-changes-the-library-in-the-institution/
Last updated: 2020-10-28T09:06:21.000Z
It has been interesting in recent years to see how library boundaries within universities have shifted as relationships with other campus providers potentially change.
This is natural enough as the network has changed the way in which research, learning and administration are carried out within the university in important ways, with follow-on information management and service impacts. The creation, management, manipulation and disclosure of digital materials has become integral to a wide range of university activities.Think of GIS and survey data, data-intensive science, lab-books, learning management systems, digital repositories of various sorts, digital publishing initiatives, grants and publication details.
As information management becomes pervasive of university activities, it also becomes natural to think about how information management support services are aligned across existing and new organizational units. This creates organizational choices for the University in how it arranges information management services internally, and what it choses to externalize. These changes are usually driven by local personalities, politics and cultures, although you would expect patterns to emerge over time.
In thinking about this topic, here are some examples that have arisen more or less successively in recent years.
**Library and IT services**. Libraries and IT Centres (variusly named and structured) have interacted since automation began. As with others, the library would look to the IT Centre for general support with security, networking, office support, and so on, but maybe also specific library technology support. Early discussions may have been around library automation systems, but continue around evolving infrastructure to manage digital resources. Boundary issues are common.
As requirements evolve, organizations may look at infrastructure in new ways. Interestingly, Yale has established an [Office for Digital Assets and Infrastructure](https://odai.research.yale.edu/?ref=lorcandempsey.net) organizationally distinct from both technology and library operations, but on a peer level with them. It is charged with creating the infrastructure required to manage digital institutional assets.
An early and telling example involves the development of so-called merged or converged services, a trend particularly noticeable in the UK. Approximately fifty per cent of UK academic libraries are part of larger organizational units which may include some combination of academic computing, administrative computing, elearning management, and other emerging digital infrastructure services \[1\].
**Library and elearning.** Most institutions now maintain a course management system, and within that, or associated with it, a range of information, communication and groupwork resources. From an informational point of view, think of reading lists, resource guides and course reserves. Or of the desire to make library resources visible within course management workflows (learnflows). Or of the management of course materials. Although they are now a major investment, there does not appear to be a consistent organizational pattern. So, in some cases elearning infrastructure may be managed by the library, in others by the CIO’s office, or in others in some other way. Levels of coordination between library and learning management may vary.
**Library and publishing**. As publishing processes evolve, as institutional research and learning resources are managed and disclosed to the world, and as self-publishing models are explored, so do boundaries between publishing, library and resource management come down. The University Press, or new publishing initiatives, may or may not be associated with the library. The University of Michigan has an interesting collection of activities under the [MPublishing](https://www.lib.umich.edu/mpublishing?ref=lorcandempsey.net) label: ” By bringing together the talents and resources of the University of Michigan Press, the Scholarly Publishing Office, Deep Blue (the University’s institutional repository service), the Copyright Office, and the Text Creation Partnership, MPublishing builds upon the traditional publishing strengths of the University of Michigan while creating and shaping sustainable publishing models for the future.” Mpublishing is organizationally situated as part of the library service.
**Library and research infrastructure**. As information generation, management, manipulation, and disclosure becomes integral to a larger part of research, universities are considering organizational management support for these. Data curation provides one example. In some cases these interests may have crystallized around a ‘cyberinfrastructure’ or ‘digital humanities’ organizational hub, or some capacity in a department or school; in other cases it is not formalized. Libraries are also developing services here and in some cases may host such units. It is interesting to look at the ‘[history](https://library.brown.edu/cds/about/history?ref=lorcandempsey.net)‘ of the Center for Digital Scholarship at Brown University Library.
The library has a persistent institutional role; however we have seen other areas emerge with overlapping, similar or converging functions. These have included IT, e-learning, publishing, e-research and digital humanities support, writing centres, research and publication administration. As the information management function becomes integral to more activities, and these activities are unified by the network, then the university may realign information management support.
This has led to various well documented boundary issues – between libraries and IT for example, or libraries and e-learning. It has also led to really interesting new service configurations which bring together previously disparate service areas as common interests become clear. It is surely likely that these new configurations will become more common in the next few years.
\[1\] Hanson, T. (2005). [Managing academic support services in universities: The convergence experience](https://www.worldcat.org/oclc/61301624?ref=lorcandempsey.net). London: Facet
### The library building and the library service
URL: https://www.lorcandempsey.net/the-library-building-and-the-library-service/
Last updated: 2023-12-12T02:53:54.000Z
# Library buildings
Inside Higher Ed has an interesting piece about library buildings, [From modernist to modern](https://www.insidehighered.com/layout/set/popup/layout/set/popup/news/2011/03/21/campus%5Fplanners%5Fdescribe%5Ftransformation%5Fof%5Fmodernist%5Flibraries%5Finto%5Fmodern%5Fassets?ref=lorcandempsey.net).
It talks about how Lafayette College and the University of Massachusetts at Dartmouth embarked on projects to transform the Modernist libraries “at the heart of their campuses into modern, technologically advanced, sustainable centers for learning.”
> Lafayette and UMass-Dartmouth are far from alone in facing this situation, said Robert J. Miklos, president of designLAB Architects, the designer of both projects. Hundreds of colleges (in Canada as well as the United States) were built or underwent rapid expansion during the 1960s, in the heyday of the Modernist (and Brutalist) architecture movements that took advantage of new innovations in pouring concrete and favored a blocky, rough exterior (hence the “brutal” in Brutalism).
> And given the importance of the physical library to the core business of students and faculty members in that era, those massive structures have been the “centerpiece, focal point of many American college campuses” for the intervening 50 years, said Miklos.
> Yet on many of those campuses, the Modernist structures had long since become viewed as liabilities — visually (with many modern-era students considering them eyesores), and operationally, with the facilities often lacking the common spaces colleges often desire for collaborative learning and dedicating too much space to book stacks that are no longer necessary. \[[From Modernist to modern](https://www.insidehighered.com/layout/set/popup/layout/set/popup/news/2011/03/21/campus%5Fplanners%5Fdescribe%5Ftransformation%5Fof%5Fmodernist%5Flibraries%5Finto%5Fmodern%5Fassets?ref=lorcandempsey.net)\]
## Changing library space
This touches on several topics I have raised in blog entries recently.
**Managing down print collections.** The repurposing of space goes hand in hand with the managing down and externalization of print collections. There are various drivers here, all mentioned in the article I quote above: the demands on space, the emergence of a digital corpus, the cost of managing a resource that releases progressively less value in research and learning. I believe we are moving to a situation where network-level management of the collective print collection becomes the norm, but it will take some years for service, policy and infrastructure frameworks to be worked out and evolution will be uneven. The network may be at the level of a consortium, a state or region, or a country. The West project provides an interesting example. My remarks here are based on these blog entries:
- [Emerging network-level management of the collective print collection](https://blog.oclc.org/lorcand/archives/002135.html?ref=lorcandempsey.net)
- [Managing down collections](https://blog.oclc.org/lorcand/archives/002151.html?ref=lorcandempsey.net)
**Shifting from infrastructure to engagement**. I wrote about the ‘service turn’ recently, borrowing a nice phrase from Scott Walter. Libraries are looking at the quality of their services in support of research and learning as important markers of distinction, more important, maybe, than the collections which have loomed so large in historic assessment of their worth. I suggest that ..
> …. it relates to a general move towards ‘customer relationship’ (or engagement, or research and learning support, or ..) and away from infrastructure management as the primary locus of library activity (I use these terms as used by John Hagel [here](https://edgeperspectives.typepad.com/edge%5Fperspectives/2008/09/unbundling-dell.html?ref=lorcandempsey.net)). This is not to say that infrastructure is not managed, but that it may increasingly be shared or outsourced. One interesting example of this trend is library space, which is being reshaped around library users rather than around collections.
Here is the blog entry:
- [The service turn](https://blog.oclc.org/lorcand/archives/002152.html?ref=lorcandempsey.net)
**Brutalism**. Coincidentally I wrote a [blog entry](https://blog.oclc.org/lorcand/archives/002136.html?ref=lorcandempsey.net) a while ago about the association between libraries and Brutalist architecture, a natural enough one, when one considers, as the article above does, when these libraries were built and for what purpose. I light-heartedly suggested that it might be nice to have a calendar of libraries in the Brutalist style. It looks as if you could have one every year for many years, with different examples in each!
I discuss this topic here:
- [Brutalist architecture and libraries](https://blog.oclc.org/lorcand/archives/002136.html?ref=lorcandempsey.net).
**Picture:** I took the feature picture of McLennan Library at McGill University in Montreal.
**Note:** Cosmetically amended on 19 April 2021 to add headings and feature picture.
### Children's Book Week .... Retread
URL: https://www.lorcandempsey.net/childrens-book-week-retread/
Last updated: 2021-06-08T00:34:29.000Z
*\[A discussion about children’s book Peepo! on Twitter prompt me to recycle this entry from 2006*\]
To mark Children’s Book Week folks here at OCLC are talking about children’s books that mean something to them Here are two I like …..
## [The Wool-pack](https://worldcat.org/oclc/00621582?ref=lorcandempsey.net)
One of the first ‘long’ books I remember reading was *The Wool-pack* by Cynthia Harnett; the richness of its historical description made a lasting impression. This was [first published](https://worldcat.org/oclc/00621582?ref=lorcandempsey.net) in 1951 and runs to [several editions](https://worldcat.org/oclc/00621582/editions?ref=lorcandempsey.net) under different titles.

It is set in England at around the same time that Columbus was landing on this side of the Atlantic, and follows the adventures of a young boy, his servant, and his betrothed, as they try to undo some plotting against his father, a wool merchant. I do not know enough to know how realistic the historical setting is, but the strangeness and reality of another time and place are convincingly evoked. There is a strong narrative drive. I recently read it to my own children, Eavan (11) and Eoghan (8), and they were soon caught up in the story, as well as being fascinated by the historical detail of costume and custom.
## [Peepo!](https://worldcat.org/oclc/11581671/editions?ref=lorcandempsey.net)
I took a children’s literature course in [library school](https://www.ucd.ie/sils/?ref=lorcandempsey.net); in fact this is where I got my best grades 😉 We were lucky in our teacher, Pat Donlon, then Director of the very interesting [Chester Beatty Library](https://www.cbl.ie/?ref=lorcandempsey.net), now newly housed in the grounds of Dublin Castle, and, later, the Director of the [National Library of Ireland](https://www.nli.ie/?ref=lorcandempsey.net).
[](https://www.amazon.co.uk/Peepo-Viking-Kestrel-Picture-Books/dp/0670871761?ref=lorcandempsey.net)
One assignment was to write reviews of children’s books for several different ages. Peepo! was among my choices; it is my favorite book from the marvelous Ahlbergs. The illustrations are of an England which has disappeared, if it ever existed, executed in comforting detail. But a full page is not immediately revealed. It is seen through a round spy-hole from the previous page. A rhyme conveys what the baby can see of the scene. But what the baby sees is not what the reader sees through the spy-hole. This means that when you turn the page, your attention is in the wrong place and you immediately look for what the baby sees. The playfully intricate detail leads to delighted discovery and exploration. It is a wonderful conceit and lovingly executed.
Our children liked the Ahlbergs. [Each peach pear plum](https://worldcat.org/oclc/4004412?ref=lorcandempsey.net) is fondly remembered, another I spy book. But the favorite by miles is the story of the tender-hearted [Burglar Bill](https://worldcat.org/oclc/2424959?ref=lorcandempsey.net).
Incidentally, I notice that my copy of The Wool-pack is the [Puffin edition](https://worldcat.org/oclc/4204032?ref=lorcandempsey.net). Puffin was the children’s imprint of Penguin, which I [talked about](https://blog.oclc.org/lorcand/archives/001190.html?ref=lorcandempsey.net) the other day. Our Peepo is the [1989 Picture Puffin](https://worldcat.org/isbn/0140509194?ref=lorcandempsey.net).
Originally posted [November 13 2006](https://blog.oclc.org/lorcand/archives/001203.html?ref=lorcandempsey.net).
**Picture:** I took the feature picture of our copy of this wonderful Katie Morag story.
**Note:** Cosmetically amended on 4 April 2021 to improve spacing and add feature image.
### The amplified event
URL: https://www.lorcandempsey.net/the-amplified-event/
Last updated: 2023-04-14T04:07:56.000Z
I introduced the phrase [*The Amplfied Conference*](https://blog.oclc.org/lorcand/archives/001404.html?ref=lorcandempsey.net) several years ago to describe the way in which a conference experience might be shared by people who were not physically present, through the amplification provided by a range of network tools. On reflection, of course, such amplification is also a way of enhancing the experience of people who are at the event. The phrase seemed to strike a chord and has been picked up as an umbrella term for a variety of approaches.
In particular, it has been used in UK Higher Education where there is rich support for development and awareness activities through several shared services. Here are some resources …
- [10 cheap and easy ways to amplify your event](https://www.ariadne.ac.uk/issue66/guy/?ref=lorcandempsey.net). Marieke Guy (Publication Date: 30-January-2011 Publication: Ariadne Issue 66)
- There is an Event Amplifier blog, written by Kirsty Pitkin. Kirsty works with TConsult who provide [Event Amplification](https://tconsult-ltd.com/social-media-business/event-amplification/?ref=lorcandempsey.net) services as part of their portfolio.
- Brian Kelly ran a seminar on [What can we learn from amplified events](https://www.ukoln.ac.uk/web-focus/events/seminars/girona-2010/?ref=lorcandempsey.net) at the University of Girona and the resource page for this usefully has links to a variety of materials prepared by Brian.
Brian and Marieke are among the presenters at a session on amplified events during the [JISC Conference 2011](https://www.jisc.ac.uk/events/2011/03/jisc11.aspx?ref=lorcandempsey.net) which takes place tomorrow. This will provide general background and advice about managing amplified events. Interestingly, they are running the session as part of Greening Events Project II which looks at reducing the environmental impacts of events.
> There are two main strands of work proposed in the Greening Events II project:
>
> - An Academic Event Profiler tool to allow the University of Bristol (and other universities) to systemically profile their event and travel footprints (including financial costs, Greenhouse Gas (GHG) emissions and other negative sustainability impacts) in order to provide a baseline on which to measure any subsequent reductions.
> - An Events Planning Toolkit to help event organisers think through what type of event they need to hold (physical, virtual or hybrid) and then to provide assistance in the form of guidelines and technology tools with each stage in the process to enable them to reduce the negative sustainability impacts of their event. // [Greening events II](https://www.jisc.ac.uk/whatwedo/programmes/greeningict/events2.aspx?ref=lorcandempsey.net)
>
> Brian has a blog entry describing the session – [](https://ukwebfocus.wordpress.com/2011/03/14/amplified-events-seminars-conferences-what-why-how/?ref=lorcandempsey.net)[Amplified Events, Seminars, Conferences, …: What? Why? How?](https://ukwebfocus.wordpress.com/2011/03/14/amplified-events-seminars-conferences-what-why-how/?ref=lorcandempsey.net) – and includes the presentations which will be used. These repay reading.
>
> The JISC Conference itself has prepared carefully for amplification and provides an interesting advice page: [Amplification Guidance for Online Participants](https://www.jisc.ac.uk/events/2011/03/jisc11/amplificationguide.aspx?ref=lorcandempsey.net).
>
> This includes pointers about tools and network services, including Twitter, video streaming, and LinkedIn. An event amplifier will be providing live commentary on sessions. An ‘engagement team’ will be on standby prepared to relay network audience questions to speakers and others. I thought the use of a special conference LinkedIn group was particularly interesting:
>
>> This group is provided as an open space for participants to expand their professional networks by connecting with other participants from JISC11\. Please feel free to use is space to make connections and discuss themes related to the conference.
>
> It also includes advice about maximising the value of participation and appropriate behaviors. Feedback and enquiry is encouraged.
>
> JISC has worked hard on this and has a more advanced range of amplifying services than most. However, we might expect this type of activity to become more common as physical presence is increasingly seen as only one of the possible modes of participation at events.
>
> **P.S.** The use of LinkedIn in the way described above is an interesting fit for some of the practices discussed in the Power of Pull. See my comments [here](https://blog.oclc.org/lorcand/archives/002086.html?ref=lorcandempsey.net) and [here](https://blog.oclc.org/lorcand/archives/002161.html?ref=lorcandempsey.net).
>
> **Picture:** I took the feature image of the Convention Center in Adelaide, Australia.
>
> **Note:** Cosmetically updated on 1 April 2021 to adjust spacing and to add abstract and feature image.
### The power of pull redux .. with examples
URL: https://www.lorcandempsey.net/the-power-of-pull-redux-with-examples/
Last updated: 2021-03-28T02:35:30.000Z
## The power of pull
I have written about the [*Power of Pull*](https://www.edgeperspectives.com/pop.html?ref=lorcandempsey.net) before, an interesting book by John Hagel, John Seely Brown, and Lang Davison. For a fuller discussion see the earlier blog entry ([People are entry points too … redux](https://blog.oclc.org/lorcand/archives/002086.html?ref=lorcandempsey.net)).Here is a short version. The authors discuss the shift from managing ‘knowledge stocks’ to participating in ‘knowledge flows’ as patterns of work and interaction change in a network environment. I was particularly struck by their discussion of information overload.
> It’s not so much about finding which information is most valuable, as many of those who fret about information overload would have it. Improving return on attention is more about finding and connecting with people who have the knowledge you need, particularly the tacit knowledge about how to do new things. The danger is that we all get so busy assimilating explicit knowledge that we have no time to connect with people and build the relationships through which tacit knowledge flows. We get so busy reading about steampunk, or brewing, or building networks, that we don’t actually find and connect with and learn from the people who are doing it. It’s not so much information that we need as knowledge. And knowledge means people.
What does this mean in practice? The book is largely about ways of connecting with flows of knowledge by connecting with people. In a summary blog [entry](https://www.edgeperspectives.typepad.com/?ref=lorcandempsey.net) Hagel writes “This pull approach seeks to develop scalable pull platforms that amplify our ability to draw out the people and resources when we need them and where we need them”.The authors talk of three ‘primary levels’ of pull. First there is access, the ability to find people and resources when they are needed. The second is the ability to attract valuable and relevant people and resources to you. Social networking, conferences, location in relevant geographic spikes (Nashville for country music) are important here, as is the ability to be open to and develop relationships through serendipitous encounter. The third is the ability to achieve more by learning more effectively and translating that learning into improved performance. Interestingly, the authors discuss ‘creation spaces’ which support this third level. Examples include the social interaction on World of Warcraft and the SAP Developer Network which provide support for shared attention to problems.In the earlier post I speculated sketchily about some implications for libraries. I have found since reading the book that it often comes to mind when considering particular situations; it has good explanatory power. For example, in the last couple of weeks I have seen these examples from areas adjacent to libraries which can be seen to be about the *power of pull*.
## Two examples
In the first, a recent [story](https://www.usnews.com/education/blogs/MBA-admissions-strictly-business/2011/02/25/gain-an-admissions-advantage-with-social-media?ref=lorcandempsey.net) in *US News and World Report* talks about how prospective business school students can get an ‘insider’s perspective on the b-school communities you hope to join’. Resources are: deans’ and professors’ Twitter feeds, official program Facebook pages, admissions blogs, and student blogs. I thought there were several interesting things about this.
- You will get clues based on what resources exist (does the Dean tweet?), the style and manner of these resources (does it look as if he or she does his or her own tweeting?), and their content.
- Not all the resources will be under the control of the schools: think here for example of student blogs or tweets.
- And most interesting to me here, a part of the impression a prospective student (or faculty member, for that matter) gains will be based on how their future teachers or colleagues disclose themselves on the network.
In the second, Robert McCrum, well known journalist and author, writes about authors and their work under an urgent sounding title: *[Engage with the public, or fade into the past](https://www.guardian.co.uk/books/2011/feb/27/writers-publishing-exploit-social-media?ref=lorcandempsey.net)*. He discusses how the release and dissemination of information about new publications was once tightly constrained, but now, he suggests, authors and publishers need to think about how to disclose information about themselves and their work in many ways. He writes about engaging potential reader communities through social networking.
> How does the solitary writer attract attention in the age of mass culture? One answer is to mobilise the tools of mass culture and exploit social media. This is becoming a trend. Last week a new website, bibliotastic.com, was launched to help connect aspiring authors to a wider audience. In the words of its founder, James Crawshaw, bibliotastic.com aims “to be to the book market what YouTube has become to the online video: a forum for writers to publish their work for free and for readers to decide what they like for themselves”.
> Further up the literary food chain, published writers in search of readers are increasingly experimenting with social media. At the commercial end of the business – and what writer does not want to sell books? – you find a new class of literary entrepreneur promoting themselves as a brand as much as actually sitting in lonely composition.
> Rosie Sayers, the director of Reform, a new digital promotion company, believes that every new book should have its own website, with excerpts from the book, interviews with the author and opportunities to buy the book. Writers should be blogging daily, as well as promoting themselves through Facebook and Twitter. “Authors,” she says, “should engage with whatever their readers say about them. Younger authors recognise how important an online presence is.”
> Sayers believes that there’s a new generation of readers who crave an interactive experience with writers. Is it not enough to read and enjoy the book in private? Apparently not. In search of “a new level of participation”, some writers are now inviting their online followers to “choose the title” of their work in progress, and have begun to open Twitter accounts in the name of their new books’ characters. “If you don’t engage with the social media,” claims Sayers, “you’ll get left behind.” Or, as EM Forster might have put it, only connect. \[[Engage with the public – or fade into the past](https://www.guardian.co.uk/books/2011/feb/27/writers-publishing-exploit-social-media?ref=lorcandempsey.net)\]
Now, McCrum doesn't sound entirely enthusiastic about this state of affairs, but it is interesting that he is writing the article.Three things come to mind here. The first is that something more is going on here than marketing initiatives, narrowly conceived, although many of these activities to relate to such initiatives. Which leads to the second point, which is that active disclosure of personal and institutional identity and character matters as part of ‘attracting’ potential students, readers, or others. And third, as I noted in the earlier post, I am struck by the extent to which success is seen by the *Power of pull* authors to be bound up with network participation – networks of people and resources facilitated by digital networks. The future, they seem to suggest, favors – in [Dave White’s phrase](https://blog.oclc.org/lorcand/archives/001773.html?ref=lorcandempsey.net) – the network residents. And yet, of course, much of what is discussed above is exploratory and in early days.
### The Collections shift
URL: https://www.lorcandempsey.net/the-collections-shift/
Last updated: 2023-02-26T15:27:28.000Z
A few things about library collection shifts came to my attention this week … Taken together, they underline several central trends: the move to electronic, the managing down of print collections, and the curation of institutionally-generated learning and research resources.
## Cloud-sourcing collections
Rick Anderson has a typically pointed post about *Cloud-sourcing Research Collections: Managing Print in the Mass-digitized Library Environment* \[[PDF](https://www.oclc.org/research/publications/library/2011/2011-01.pdf?ref=lorcandempsey.net)\] a report from OCLC Research prepared by Constance Malpas. Constance notes that the emergence of the mass digitized corpus of books at Google Books and Hathi Trust has the potential to transform the academic library.
Rick responds, and highlights the urgency of some of the points made in the report.
> I would put it much less cautiously than that — the emergence of a mass-digitized book corpus cannot fail to transform the academic library enterprise. The extent of the transformation will depend on several factors, of course, including the content and accessibility of the corpus — but librarians’ opinions about the mass-digitization program will have no effect at all.
> What should cause concern for academic libraries is the fact that such a corpus already exists, and is growing by the day; the dam holding it back is fragile and cracking. There is already a steady flow of water through the breaches in that dam (existing search functionality in Google Book Search; the quickly growing Hathi Trust collection), and the dam will give way entirely when some version of the Google Book Settlement is approved. …
> … After reading this report, my confidence in the long-term viability of traditional collection-building has been undermined even further. The library of the future is not going to look much like a library. We librarians need to swallow hard, let go of some of the things we love most about our jobs, and prepare ourselves — now — for the inevitable (and probably precipitous) arrival of what is behind that dam. // [The digitized book corpus and the cracking dam](https://scholarlykitchen.sspnet.org/2011/02/28/the-digitized-book-corpus-and-the-cracking-dam/?ref=lorcandempsey.net)
Some of Rick’s thoughts on collection shifting can be found in a presentation he recently gave at the Ontario Library Association Super Conference where he shared a platform with my colleague Karen Calhoun.
**[Next Generation Workflows for Next Generation Libraries](//www.slideshare.net/amarintha/next-generation-workflows-for-next-generation-libraries "Next Generation Workflows for Next Generation Libraries")** from **[Karen S Calhoun](https://www.slideshare.net/amarintha?ref=lorcandempsey.net)**
The *Cloud-sourcing research collections* report has received a lot of attention as it begins to provide an empirical and service framework within which to think about [managing down print collections](https://blog.oclc.org/lorcand/archives/002151.html?ref=lorcandempsey.net), a growing trend across libraries.
This theme was addressed at the [RLG Partnership Meeting](https://www.oclc.org/research/events/2010-06-09a.htm?ref=lorcandempsey.net) last year by David Lewis of IUPUI. The powerpoint \[[pptx](https://www.oclc.org/research/events/20100609n.pptx?ref=lorcandempsey.net)\] and audio \[[mp3](https://www5.oclc.org/downloads/research/events/20100609n.mp3?ref=lorcandempsey.net)\] of his presentation have been conveniently put together by Peter Murray:
**[Collections Futures](//www.slideshare.net/DataGazetteer/collections-futures-7109252 "Collections Futures")** from **[Peter Murray](https://www.slideshare.net/DataGazetteer?ref=lorcandempsey.net)**
Against an interesting environmental analysis, David presented the outline of academic library strategy as follows:
1. **Complete the migration from print to electronic collections**
2. **Retire legacy print collections**
3. Redevelop library space
4. Reposition library and information tools, resources, and expertise
5. **Migrate the focus of collections from purchasing materials to curating content**
## Inside-out collections
His presentation on this occasion focused on the lines in bold. In discussing a stronger emphasis on curating institutional content (point 5), he referenced a distinction I have made between ‘inside out’ and ‘outside in’ ([here](https://blog.oclc.org/lorcand/archives/002047.html?ref=lorcandempsey.net) and [here](https://blog.oclc.org/lorcand/archives/002102.html?ref=lorcandempsey.net)):
> Think, for example, of a distinction between outside-in resources, where the library is buying or licensing materials from external providers and making them accessible to a local audience (e.g. books and journals), and ‘inside-out’ resources which may be unique to an institution (e.g. digitized images, research materials) where the audience is both local and external. Thinking about an external non-institutional audience, and how to reach it, poses some new questions for the library. // [Outside-in and inside-out](https://blog.oclc.org/lorcand/archives/002047.html?ref=lorcandempsey.net)
This need for attention to ‘inside out’ is also picked up in a nicely done overview of collection development trends, *Turning collection development inside out*, by Dorothea Salo:
Coincidentally, this was to be presented at the OLA Super Conference also, but weather prevented attendance.
**Note:** Cosmetic updates on 31 March 2021 to fix spacing and broken links and to add headings.
### Buying books and/or experiences: a consumer view
URL: https://www.lorcandempsey.net/buying-books-and-or-experiences-a-consumer-view/
Last updated: 2022-11-09T19:01:03.000Z
A while ago I was interested to observe that I had begun to resist buying paperback novels. Before that, I would often come away with one from a trip to our local Border’s (sadly now closing) or sometimes buy a mystery novel in the airport (especially on the return trip when good intentions about working on the plane were likely to dissolve).
In thinking about it, I realised that I only wanted to buy the experience not the physical item. My bag and our house is already cluttered enough. I wanted the few hours entertainment the book provided, not the small burden of owning a bundle of paper to be shelved.
Now, of course there are also books I do want to own. In fact, I can observe what is almost a counter trend here. I will sometimes buy a book in lieu of reading it, or in anticipation of reading it sometime in the future. This is the case with, for example, with [*Triumph of city*](https://www.worldcat.org/title/triumph-of-the-city-how-our-greatest-invention-makes-us-richer-smarter-greener-healthier-and-happier/oclc/650211168?ref=lorcandempsey.net) by Ed Glaeser which I mentioned [in these pages](https://blog.oclc.org/lorcand/archives/002155.html?ref=lorcandempsey.net) recently. I saw a positive reference to it, it relates to an interest I have, and it is a several click operation to buy a book. I skimmed it when it arrived and put it on the shelf where it waits to be read. This may very well be a transitional form of behavior as frameworks within which to manage digital collections of books mature.
I have owned a Kindle for a little while now. If I want to buy the experience but not the object, then it is a Kindle purchase.
The Kindle has another advantage, which I have been surprised not to see more widely noted. It is nice to highlight passages which can be clipped and made available to you on the web. Historically, I transcribed passages from books I read into notebooks (now mostly disappeared), and my books at home are ‘enhanced’ with penciled marks indicating interesting passages. The Kindle functionality is very useful in this context: it effectively transcribes passages and makes them available to you in an organised way.
Putting these together raises an obvious requirement. I am unlikely to bring the Glaeser book on a trip because it is a more bulky book than I am now prepared to carry. However, I would be interested in reading it on the Kindle. And I would also like to be able to save passages from it to the network for future reference or use. The Kindle version is cheaper than the hardback which interestingly is cheaper than the paperback. But there appears to be no discount for the customer who would like to buy both Kindle and one of the two paper versions. Now, I am unlikely to want to do this for very many books but there are cases where it would be a worthwhile option. I assume we will see it offered more widely in due course.
*Coda*: Of course, ebooks raise important policy and business issues for libraries, which I do not talk about here. Eric Hellman’s blog provides a useful place to track some of these issues. Here is his discussion of the controversial recent [Harper Collins announcement](https://go-to-hellman.blogspot.com/2011/02/harpercollins-and-suspension-of-ebook.html?ref=lorcandempsey.net) for example.
**Picture:** I took the feature picture at the IFLA meeting in Wroclaw, Poland.
**Note:** Cosmetic stylistic changes and feature picture added 9 November 2022\.
### The institution and the network ... a question of scale
URL: https://www.lorcandempsey.net/the-institution-and-the-network-a-question-of-scale/
Last updated: 2020-10-28T09:06:46.000Z
I was interested to come across this passage in a presentation \[[ppt](https://www.ucl.ac.uk/library/Library-Strategy-Final.ppt?ref=lorcandempsey.net)\] about library strategy by Dr Paul Ayris of University College London:
> Challenges
>
> - Identifying the needs of UCL researchers and students, and recognising the most appropriate tools to meet these needs
> - Fitting such developments into an electronic world which now focuses work not on the local level, but at the network level
As regular readers know, ‘network level’ is a [favorite expression of mine](https://www.google.com/search?sourceid=chrome&ie=UTF-8&q=%22network+level%22+%2Blorcan&ref=lorcandempsey.net). This question is interesting because of the transition we are working our way through. Libraries tend to be institution-scale in reach as they were organized as a pre-network response to information management. In that context, institutionally based services make sense. For example, information materials were acquired and made available to the local population on a just-in-case basis. The institution remains the appropriate scale for many activities. However, researchers may now be drawn to newer network level approaches which aggregate supply and/or attention across the network, or across a discipline .. think for example of initiatives like ICPSR, SSRN, Repec, Arxiv or more generally of Google Scholar or Twitter. At what scale will researchers look for applications to do their work – institution, collaborative group, discipline, network? Where does it make sense to let services be provided by external network level providers and where should the library provide services? There is no right answer of course, and practices are shifting.
Think of some directions ….
- **Discovery**. [Discovery happens elsewhere](https://www.google.com/search?sourceid=chrome&ie=UTF-8&q=%22discovery+happens+elsewhere%22+%2Blorcan&ref=lorcandempsey.net): in Google, in Google Scholar, in Arxiv, in Mendeley, in Twitter, …. This has resulted in two broad directions. One, to create single-search access to broad data wells, so-called discovery layers solutions. Two, to think about how to syndicate library resources into other environments through APIs, data sharing or other approaches. Think of the find-in-a-library link in Google Book Search or the work Google Scholar has done with institutional resolvers. One of the reasons [I so much liked](https://blog.oclc.org/lorcand/archives/002153.html?ref=lorcandempsey.net) the recent University of Minnesota [report](https://conservancy.umn.edu/handle/99734?ref=lorcandempsey.net) on discovery is that it takes this wider environment as its problem area. It considers how the library supports effective discovery of its resources in an environment of multiple discovery services, some institutional, some external network level services.
- **Citation management**. A library may have provided support through an institutional subscription to Endnote or Refworks. More recently, faculty and students may use network level approaches such as Zotero, Mendeley and EasyBib. These approaches have their own characteristics and what we are now seeing is libraries move to provide support or advice across tools they subcribe to and those they don’t. See for example the MIT [libguide](https://libguides.mit.edu/references?ref=lorcandempsey.net) on citation management, their pages for [Zotero](https://libguides.mit.edu/zotero?ref=lorcandempsey.net), [Endnote](https://libguides.mit.edu/endnote?ref=lorcandempsey.net) and [Refworks](https://libguides.mit.edu/refworks?ref=lorcandempsey.net), which they support, and a [general overview](https://libguides.mit.edu/citation-tools?ref=lorcandempsey.net) of some other tools which may be useful.
- **Expertise/researcher profiles**. Various universities are interested in disclosing details of faculty research, grants, publications, areas of expertise, etc, and there are some elaborate approaches to this which may or may not be well integrated with CRIS or institutional repository systems. Of course, individuals will also potentially manage other network identities, within social networking environments, in professional societies, and so on. And product support for this kind of activity is emerging. Again, there will be multiple such activities and it poses interesting questions about incentives and roles.
- **Deposit of research outputs**. There are both institutional and network level venues for deposit and management of papers or data.
These comments are prompted by reading a report recently released by colleagues of Paul Ayris at UCL, the Ciber group, and Emerald Publishing: *Social media and researcher workflows* \[[pdf](https://www.ucl.ac.uk/infostudies/research/ciber/social-media-report.pdf?ref=lorcandempsey.net)\]. The research group received responses from 4-6% of a large target list, and acknowledge that the survey was deliberately aimed at those with an interest in social media. With that qualification, here are some of their findings ….
> 1 Social media have found serious application at all points of the
> research lifecycle. The three most popular social media tools in a
> research setting are those for collaborative authoring, conferencing,
> and scheduling meetings.
> 8 The most popular tools used in a professional research context tend
> to be mainstream anchor technologies or \`household brands’, like
> Skype, Google Docs, Twitter and YouTube. Researchers seem to
> be largely appropriating generic tools rather than using specialist or
> custom-built solutions and both publishers and librarians need to
> adapt to this reality. Is this a sign, perhaps, that there may be a gap
> in the market for simple bespoke tools?
> 9 The key driver for the take up of social media is pressure exerted by
> peers outside of the researcher’s own institution. Social media are
> helping to fulfill the demand for cheap, instant communication
> between researchers fuelled by the growth of collaborative and
> interdisciplinary research.
> 10 Use of social media is usually down to personal initiative, so a clear
> understanding of the capabilities and benefits of these tools is
> essential. Time-poor researchers are still unclear about the benefits
> of social media and this represents a major barrier to their take up.
> They also have serious concerns about the authenticity of crowdsourced information.
> 11 Users and non-users of social media express almost identical
> preferences when they look for scholarly information. Their first
> preference is for the open web, followed by searching licensed econtent through their libraries, followed by asking a colleague. The
> only difference we could detect in this survey between users and
> non-users is that the former are more likely to put out a general call
> for information on a list serv or social network.
> 12 We find a similar pattern with regard to research dissemination. The
> traditional channels (especially journals, conference proceedings
> and edited books) are greatly and equally favoured by both social
> media users and non-users over informal channels such as blogs.
> Researchers continue to back dissemination routes that they know
> and trust. It is clear that social media users see informal tools as a
> complement to the existing system of scholarly publishing, not as a
> replacement. As a result, personal dissemination is on a steep
> upward curve, with implications for publishers especially.
> 13 Researchers, especially senior researchers, want above all for
> publishers to make content readable on all platforms. This, together
> with more progress in linking articles to their underlying data. They
> want the basics to work well, not more \`bells and whistles’.
> 14 Researchers also sent a clear message to librarians. At the top of
> their wish list, and by a big margin, is a desire to be able to search
> across the full text of all locally-held licensed e-content using a
> simple interface like Google. This is seen as a much greater
> potential benefit than libraries moving into the social media space
> by offering users, for example, an opportunity to socially tag the
> library catalogue.
Interestingly, the authors did not include citation management in the survey. They also have a methodological note which should be consulted.
In the last few years we have seen many studies of this type – some from OCLC – which talk about researcher, student and general consumer behaviors. I think that in many of them one can see this scale question for the library. Quite often, the response is that the library should look more like these network tools. I believe this is a mistaken or at best a partial response, although some updating is useful. A more appropriate response is to consider library resources in the context of this overall environment. So, research support may provide advice and guidance on a range of tools and services not provided within the library itself. Consideration may be given to making sure that library resources are visible in important discovery venues, making sure that the institutional link resolver is properly configured for Google Scholar access for example. Images may be put on Flickr, links to special collections added to Wikipedia, videos put on Youtube or iTunes, presentations put on Slideshare, and so on. Deciding where to invest energy becomes an ongoing task.
Update: edited to restore the balance of a mistakenly truncated sentence. 3 March 11\.
### The university's curatorial role
URL: https://www.lorcandempsey.net/the-universitys-curatorial-role/
Last updated: 2022-12-06T22:25:08.000Z
I made [a note in these pages](https://blog.oclc.org/lorcand/archives/001766.html?ref=lorcandempsey.net) a couple of years ago about the University of Edinburgh’s mission statement.
> The University’s mission is the creation, dissemination and curation of knowledge.
The occasion was Chris Rusbridge’s justified [pleasure](https://digitalcuration.blogspot.com/2008/09/curation-in-university-mission.html?ref=lorcandempsey.net) at seeing the mission changed to include ‘curation’. At the time, Chris was the director of The Digital Curation Centre, based at the University.
At CNI recently I was very interested to hear Maria Bonn [talk about](https://www.cni.org/tfms/2010b.fall/Abstracts/PB-university-ruddy.html?ref=lorcandempsey.net) scholarly publishing strategy and infrastructure at the University of Michigan. She discussed how several areas of scholarly publishing had been consolidated into MPublishing, a division of the University Library. I thought the combination of services was fascinating. I also thought that it exemplified what [Scott Walter](https://netfiles.uiuc.edu/swalter/www/?ref=lorcandempsey.net) has called [the service turn](https://blog.oclc.org/lorcand/archives/002152.html?ref=lorcandempsey.net) in libraries, and, more particularly, that it was an example of leveraging several services to create a truly distinctive offering in the way he discusses will become more common for libraries.
> MPublishing is the primary academic publishing division of the University of Michigan. It creates, promotes, distributes and preserves scholarly, educational and regional materials in digital and print formats. By bringing together the talents and resources of the University of Michigan Press, the Scholarly Publishing Office, Deep Blue (the University’s institutional repository service), the Copyright Office, and the Text Creation Partnership, MPublishing builds upon the traditional publishing strengths of the University of Michigan while creating and shaping sustainable publishing models for the future.
> MPublishing is dedicated to the integrity, persistence, and durability of the scholarly record. It combines the values and experience of publishers, librarians and information technology specialists to publish and promote the best quality scholarship. By approaching the life cycle of information at every stage, from the initial spark of an idea to its delivery and long-term preservation, MPublishing takes a holistic approach to publishing that maximizes the impact of its publications both now and in the future. \[[MPublishing | MLibrary](https://www.lib.umich.edu/mpublishing?ref=lorcandempsey.net)\]
Several organizational things struck me. One was that this was not the organizational home of the Hathi Trust, although one can understand that there might be good reasons for that. The second was the mix between activities aimed at supporting effective communication and publishing of Michigan research outputs and those which involved the the university as a publisher, either through the Press or its [journals](https://www.lib.umich.edu/spo/journals.html?ref=lorcandempsey.net). The third is more general. Myself and Brian Lavoie [recently wrote about](https://www.oclc.org/us/en/nextspace/017/research.htm?ref=lorcandempsey.net) how the network is reconfiguring the organizational boundaries of the library. There is the boundary between the library and external entities; however there is also the boundary between entities within the university. I though that this was a very interesting example of how internal university activities are being reconfigured to align related activities in new ways.
One of the particular things I liked about the presentation was how Maria aligned University, Library, and MPublishing missions. The University of Michigan mission is powerfully stated:
> The mission of the University of Michigan is to serve the people of Michigan and the world through preeminence in creating, communicating, preserving and applying knowledge, art, and academic values, and in developing leaders and citizens who will challenge the present and enrich the future. \[[Mission statement](https://www.umich.edu/pres/mission.php?ref=lorcandempsey.net)\]
What jumped out at me was the word ‘preserving’, which immediately reminded me of the Edinburgh statement.
This did cause me to wonder whether Michigan and Edinburgh had explicitly provided for preservation/curation of institutional assets, and to what extent the library was seen as the place to address this issue.
**Coda:** I have [ noted](https://blog.oclc.org/lorcand/archives/002119.html?ref=lorcandempsey.net) how the use of the word ‘curation’ has developed recently. I read ‘curation’ in the University of Edinburgh’s mission as being aligned with the second sense I discuss there. Preservation is certainly an important interest of the Digital Curation Centre.
**Picture:** I took the feature image in Edinburgh, Scotland.
**Note:** Cosmetically updated on 11 April 2021 and feature image added.
### Using Wikipedia
URL: https://www.lorcandempsey.net/using-wikipedia/
Last updated: 2020-10-28T09:06:53.000Z
We still don’t appear to know what to make of Wikipedia. Consider these two cases.
First, Edward Glaeser includes a reference to Wikipedia in the acknowledgements to his new book, *[Triumph of the city](https://www.worldcat.org/oclc/650211168?ref=lorcandempsey.net)*.
> Following common practices, Wikipedia is not listed in the bibliography or citations, because any Wikipedia fact was verified with a more standard source. But I still have a great debt to the anonymous toilers of Wikipedia who made my research much easier at many points in time. I apologize if any phrases from that, or any other source, crept into my prose – one research assistant was assigned the explicit task of purging such inadvertent borrowing – but mistakes do sometimes get through. \[272-273\]
This is really quite interesting. Wikipedia appears to have been heavily used in the preparation. I wonder did any of the work involved in separate verification of detail find its way back into Wikipedia? It is also interesting that Wikipedia is not cited even when it is found to be reliable (one of the benefits of Wikipedia’s versioning is that this would be possible).
Second, my daughter (a sophomore in high school) was given an assignment to introduce errors into Wikipedia. Presumably, the intention was to demonstrate that entries could be ‘unreliable’. Now, she chose a popular page, and had her changes corrected almost straightaway, to the extent that it was not possible to complete the assignment as given. In fact, she ended up being barred from editing pages as her behavior was seen as unacceptable.
I [have described](https://blog.oclc.org/lorcand/archives/001264.html?ref=lorcandempsey.net) Wikipedia before as an addressible knowledgebase, and this is certainly one of its major advantages. It makes further information about a topic sharable with a URL, and in this way it relieves people of having to create their own context and background. A second advantage is that it gives us a first cut description of a topic, or of relations between topics, and for many purposes this suffices. I imagine that this is a major way in which it is used by Ed Glaeser above. It is also how I imagine Google Books is being used, or the related Ngram viewer. These allow quick research, which can situate an interest, and which in some cases may be followed up in other sources.
I went on to say …
> Wikipedia is a collection. … One cannot summarily judge its value in the way that one might have done when deciding whether or not to buy or recommend a reference book. Judgements about ‘authority’ and utility have to be made at the article level, and who has the time and expertise to flag individual articles in this way? Rather than continuing a tedious Wikipedia good/Wikipedia bad conversation, we should recognize the attraction it has as an addressable knowledge base, understand the variety of uses to which it is put, and remind folks of the judgments they need to make depending on those uses. \[[Wikipedia again: an addressible knowledge base](https://blog.oclc.org/lorcand/archives/001264.html?ref=lorcandempsey.net)\]
### The library network and the scholarly record
URL: https://www.lorcandempsey.net/the-library-network-and-the-scholarly-record/
Last updated: 2020-10-28T09:06:57.000Z
The library community is a highly interconnected one. Networks are motivated both by library mission and effective management of resources. This trend will accelerate as the Internet favors shared services, and libraries will see more benefit in building such shared services. The Hathi Trust is an important example. The growth of interest in sharing library systems infrastructure is another (see the Orbis Cascade Alliance RFI \[[pdf](https://www.orbiscascade.org/RFI%5F2011%5F02.pdf?ref=lorcandempsey.net)\] for a current example, or the Canadian [TriUniversity Group](https://trellis3.tug-libraries.on.ca/?ref=lorcandempsey.net) of Guelph, Waterloo and Laurier).
Any library is likely to belong to a variety of networks: for resource sharing, for cataloging, for acquisition of licensed materials, and so on. These have a variety of governance mechanisms, and operate at different scales. In some, a group of libraries explicitly connect around a shared purpose: think of OhioLink for example or the TriUniversity Group mentioned above. At a much broader scale, one might talk about the ‘public library network’ or the ‘university library network’ in a particular country.
OCLC has an interesting role here. It provides infrastructure, or a platform, which supports a large network, or networks, of libraries. This shared capacity removes the need for multiple explicit bilateral or group arrangements: libraries benefit from the network OCLC facilitates as they participate in its services. So libraries participate to share the effort of cataloging, or to make other libraries’ collections available to their users, or to share question-answering capacity. Because of the number of libraries participating, OCLC, libraries, and others, can leverage the power of this network for discovery, collection analysis and other services. For example, OCLC can provide access to the library network for users of Google Book Search. It provides access to the network [as a service](https://blog.oclc.org/lorcand/archives/002018.html?ref=lorcandempsey.net).
I have been reading *[Networks, crowds and markets](https://www.worldcat.org/title/networks-crowds-and-markets-reasoning-about-a-highly-connected-world/oclc/495616815&referer=brief%5Fresults?ref=lorcandempsey.net)* by David Easley and Jon Kleinberg. (OK, to be honest, I have read the first chapter.) I was interested early on to come across this characterization of a network:
> When people talk about the “connectedness” of a complex system, in general they are really talking about two related issues. One is connectedness at the level of structure – who is linked to whom – and the other is connectedness at the level of *behavior* – the fact that each individual’s actions has implicit consequences for the outcomes of everyone in the system. \[p.4\]
So – a small ‘behavioral’ example – if you think about the shared cataloging network, we are familiar with the phenomenon whereby some libraries wait for others to catalog an unavailable item, thereby reducing the overall effectiveness of the system.
I wrote the other day about how libraries were beginning to [manage down their print collections](https://blog.oclc.org/lorcand/archives/002151.html?ref=lorcandempsey.net). As this trend becomes more pronounced it will highlight the way in which libraries see themselves as belonging to a network which has a collective responsibility to the print scholarly record. At the moment this responsibility is weakly defined and variably accepted. Some libraries may discard materials without regard to the collective collection of the library network as a whole. Others may check Worldcat to get a quick measure of ‘rareness’. Others may have particular responsibilities defined within a consortium, state, or other group to which they belong.
Easley and Kleinberg define ‘institution’ as follows:
> Our notion of institution here is very broad. It can be any set of rules, conventions, or mechanisms that serve to synthesize individual actions into a pattern of aggregate behavior. \[p.15\]
In this sense OCLC has helped institutionalise shared cataloging. Over the next few years we will see some institutionalization of the shared responsibility to the print collections across the library network. Patterns of aggregate behavior will emerge which will need to be supported by a variety of evolving arrangements:
1. Policy and service frameworks. The [West initiative](https://www.cdlib.org/services/collections/sharedprint/westinitiative.html?ref=lorcandempsey.net) is an example of a venue in which policy and service frameworks are developing. An important aspect of West is that it provides a framework within which libraries of multiple sizes can affiliate to coordinate their print management activities or to support the overall mission. The Hathi Trust is also important here as the management of the print scholarly record will co-evolve with the management of its emerging digital surrogate. These and other initiatives are also developing sustainability models which aim to secure the shared resource.
2. Inventory infrastructure. Many institutions have developed offsite and shared storage initiatives in recent years. Digital stores are emerging. Attention is turning to how these might be managed as nodes in a network, rather than as standalone activities.
3. Registry. It is unlikely that this activity will be centralized within a particular governance structure. However, the actions of particular initiatives have consequences for others across the network, and it will be useful to have access to some ‘intelligence’ about them. It will be important to know how many copies of an item exist, who owns them, or once owned them, where they are stored, whether they are digitized, what archival commitments have been made about them, and so on. This is a potential role for Worldcat, the registry that is already central to much library network activity.
In a library meeting I attended last year there was a discussion about the number of libraries whose mission included a responsibility to the long term curation of the print scholarly record. There seemed to be some consensus that the number was about 25\. I think the number is bigger although the burden will be variably spread through a network of affiliations yet to be institutionalized.
[LorcanD](https://www.twitter.com/lorcand?ref=lorcandempsey.net) on Twitter.
### There is more to discovery than you think
URL: https://www.lorcandempsey.net/there-is-more-to-discovery-than-you-think/
Last updated: 2022-12-11T04:15:35.000Z
Colleagues at the University of Minnesota have produced [another](https://blog.oclc.org/lorcand/archives/002012.html?ref=lorcandempsey.net) must-read report on the discoverability of library resources \[[Splash page](https://conservancy.umn.edu/handle/99734?ref=lorcandempsey.net), [PDF](https://conservancy.umn.edu/bitstream/99734/3/DiscoverabilityPhase2ReportFull.pdf?ref=lorcandempsey.net)\]. Importantly, it provides a framework within which to think about evolving issues and in this way makes a real contribution to our understanding of the environment and ability to plan for change.
Much of the ‘discovery discussion’ has settled on a new library service category, the *discovery layer*. Think of Worldcat Local, Primo Central, Summon and the Ebsco Discovery Service. These have been usefully described by Jason Vaughan in a recent [report](https://www.alatechsource.org/taxonomy/term/106/web-scale-discovery-services?ref=lorcandempsey.net).
However, these are a part only of the broader discovery environment. The crucial word here is environment, because, as noted by the authors of this report, a single system or service will not address all requirements.
One environmental development in recent years has been the emergence of what I have called an [inside-out](https://blog.oclc.org/lorcand/archives/002047.html?ref=lorcandempsey.net) requirement alongside an [outside-in](https://blog.oclc.org/lorcand/archives/002047.html?ref=lorcandempsey.net) requirement. Libraries have managed an outside-in range of resources: they have acquired books, journals, databases and other materials and provided discovery systems for their local constituency over what they own or license. This has resulted in our familiar array of catalogue, resolver, metasearch, and now the integration apparatus of the discovery layer.
Of course, the institution also produces a range of information resources: digitized images or special collections, learning and research materials, research data, administrative records (website, prospectuses, etc), and so on. And how effectively to disclose this material is of growing interest across the insititutions of which the library is a part.
> Think, for example, of a distinction between outside-in resources, where the library is buying or licensing materials from external providers and making them accessible to a local audience (e.g. books and journals), and ‘inside-out’ resources which may be unique to an institution (e.g. digitized images, research materials) where the audience is both local and external. Thinking about an external non-institutional audience, and how to reach it, poses some new questions for the library. \[[Outside-in and inside-out](https://blog.oclc.org/lorcand/archives/002047.html?ref=lorcandempsey.net)\]
The discovery dynamic varies across these types of resources. The contribution of the University of Minnesota report is to try to explain that dynamic and develop response strategies.
So, among the issues they address are:
- An inventory of institutionally managed or created resources. What is the audience of each? Which need to be disclosed to the external world? How?
- An inventory and categorization of external aggregator services (e.g. Worldcat, Repec, Arxiv, Flickr, Merlot, Google, etc). To which should internal resources be disclosed, and how? Which services aggregate metadata, which aggregate content itself? Which are of interest to local audiences? Which should be integrated into local discovery systems (maybe Hathi Trust, for example)?
- A categorization of user personas, stylised descriptions of particular usage patterns. I was particularly interested to see the chart on page 13 which looks at some differences between undergraduate, graduate and faculty search behaviors. They recognize that discovery systems may need to be scoped to particular user categories. Although it is not explored in detail, they also note the need to support manipulation and personal curation of digital resources.
- A review of practices at other libraries.
- A review of metadata associated with internal resources.
An important feature is that the general discussion is tied back to the particular requirements of the University of Minnesota, which means that the relevance to other institutions should be clearer.
On a small note, I was interested in the pattern they established throughout the report to describe resources:
> The vision of a new discovery environment, that surfaced from the work of the phase 2 Discoverability group, suggests that a synthesis of tools and services need to be coordinated in such a way to enable users to discover, access, and interact with relevant data from internal, external, owned, licensed, and freely-available data sources.
Describing resources as *owned*, *licensed* and *freely-available* is probably more helpful than the print/electronic/digital schematic that is sometimes used, as it recognises a crucial element of workflow/supply chain difference that plays into how systems are built and used. (I discussed some of these issues in a Portal article a while ago, [Reconfiguring the Library Systems Environment](https://www.oclc.org/research/publications/library/2008/dempsey-portal.pdf?ref=lorcandempsey.net).)
This is a report everybody should read ….
*Note*: #FullDisclosure. I spoke about *Discovery and Delivery* at the University of Minnesota Libraries [Planning Speaker Series](https://wiki.lib.umn.edu/Staff/UniversityLibrariesSpeakerSeries?ref=lorcandempsey.net). This series was one input into the Libraries’ interesting Strategic Priorities document: *Supporting the life cycle of knowledge* \[[PDF](https://www.lib.umn.edu/pdf/ULibraries%5Fstrategic%5Fplanning.pdf?ref=lorcandempsey.net)\].
Related entries:
- [Outside-in and inside-out](https://blog.oclc.org/lorcand/archives/002047.html?ref=lorcandempsey.net)
- [Indirect discovery](https://blog.oclc.org/lorcand/archives/002105.html?ref=lorcandempsey.net)
- [Discoverability .. a report that’s worth a look](https://blog.oclc.org/lorcand/archives/002012.html?ref=lorcandempsey.net)
### The service turn ...
URL: https://www.lorcandempsey.net/the-service-turn/
Last updated: 2022-12-06T21:24:50.000Z
A while ago I spent some time looking through the [institution profiles](https://directors.arl.org/folder/files?ref=lorcandempsey.net) collected by ARL. One of the themes I noticed was the ‘service turn’, where libraries were looking at the quality of their services in support of research and learning as important markers of distinction, more important, maybe, than the collections which have loomed so large in historic ARL assessment of libraries.
Consider this from the [University of Illinois at Urbana Champaign](https://directors.arl.org/file/show/illinoisurbanachampaign.doc?ref=lorcandempsey.net) for example …
> As part of a broader re-alignment of library services ongoing since 2007 to address transformational changes in the composition of library collections, the information-use patterns of library users, and the broader environments of scholarly communication and American higher education, the Library has committed to supporting a greater variety of service models – including central services, departmental library services, embedded librarian service programs, and virtual service programs – as a key component of a vision of the future in which leading research libraries are distinguished as much by the scope and quality of their service programs as by their collections. \[.doc\]
Or this from [The University of Minnesota](https://directors.arl.org/file/show/uminnesota.pdf?ref=lorcandempsey.net) …
> In alignment with the University’s strategic positioning, the University Libraries have re-conceived goals, shifting from a collection-centric focus to one that is engagement-based. \[PDF\]
Coincidentally, at much the same time, a colleague pointed me to a brief article written by Scott Walter of UIUC, [“Distinctive Signifiers of Excellence”: Library Services and the Future of the Academic Library](https://crl.acrl.org/content/72/1/6.full.pdf?ref=lorcandempsey.net) \[PDF\].
Here is a sample ..
> There can be no question that a great library must provide access to great content, but do the seismic changes afoot in the ways in which access may be gained to content (including that found in unique artifacts) require us to ask new questions? For example, when access to content is no longer scarce, what are the services that will stand as the “primary measures of quality” and “distinctive signifiers of excellence” in the academic library? What effect might a broader understanding of distinctive services have on our appreciation for a range of libraries beyond those with the largest collections?
He provides some examples of ‘distinctive services’, including, for example, Columbia’s [Copyright Advisory Office](https://copyright.columbia.edu/copyright/?ref=lorcandempsey.net) and the [Library Assessment Program](https://www.lib.washington.edu/assessment/?ref=lorcandempsey.net) at the University of Washington.
He goes on to argue that the development of distinctive services will not be the preserve of larger libraries …
> … while the development of a distinctive library service does require vision, strategic planning, and professional expertise, it does not require access to a local collection numbering in the millions. Defining distinctive services with the clarity with which we have defined distinctive collections allows us to acknowledge that the 21st century will be marked by different, but equally valid, definitions of excellence in academic libraries, and that the manner in which individual libraries demonstrate excellence will be distinctive to the service needs, and to the opportunities to address those needs, found on each campus.
It is to this article that I owe the phrase ‘service turn’ which I use as the title above.
Two things occur to me here. One is that is relates to a general move towards ‘customer relationship’ (or engagement, or research and learning support, or ..) and away from infrastructure management as the primary locus of library activity (I use these terms as used by John Hagel [here](https://edgeperspectives.typepad.com/edge%5Fperspectives/2008/09/unbundling-dell.html?ref=lorcandempsey.net)). This is not to say that infrastructure is not managed, but that it may increasingly be shared or outsourced. One interesting example of this trend is library space, which is being reshaped around library users rather than around collections. Another is that it will be interesting to see how such new services do or don’t converge around models which can be provided collaboratively or by third parties. In other words, is local responsiveness a part of their distinctiveness?
### Managing down collections ...
URL: https://www.lorcandempsey.net/managing-down-collections/
Last updated: 2022-12-06T21:22:44.000Z
I was interested to read this from [Karen Schneider](https://freerangelibrarian.com/2010/09/04/the-west-project-the-first-shoe-drops-for-the-big-shift/?ref=lorcandempsey.net) a while ago: “Centralized mass storage for legacy print materials (paper-based books and journals) is by far the most under-observed trend in libraries today”. I agree, with the friendly qualification that the trend is about managing the relationship between local, mass storage and emerging digitised resources. Many libraries are ‘managing down’ their local print collections. The reasons for growing interest are clear and I touched on them in an earlier blog post that was partly prompted by Karen’s:
> One of the recurrent themes in these pages is that systemwide coordination of print materials is necessary as libraries begin to retire collections – to offsite storage or removing them altogether. There are various drivers here: the demands on space, the emergence of a digital corpus, the cost of managing a resource that releases progressively less value in research and learning. Print runs of journals have been an early focus, but interest is extending to books also. I believe we are moving to a situation where network-level management of the collective collection becomes the norm, but it will take some years for service, policy and infrastructure frameworks to be worked out and evolution will be uneven. The network may be at the level of a consortium, a state or region, or a country. At the moment, this trend is manifesting itself in a variety of local or group mass storage initiatives, as well as in several regional and national initiatives. \[[Emerging network level management of the collective print collection](https://blog.oclc.org/lorcand/archives/002135.html?ref=lorcandempsey.net)\]
This managing down of local collections in the context of wider systems of stewardship and provision is acquiring greater prominence, creating a need for new policy and service frameworks. In this context, I would like to note three recent items.
First, we are pleased that much of the empirical context for this discussion and quite a bit of intellectual leadership has come from OCLC Research work being done for the RLG Partnership. Constance Malpas has been leading this activity, and has been creating and supporting links between various community initiatives and relevant product areas in OCLC. A [report](https://www.oclc.org/research/news/2011-01-06.htm?ref=lorcandempsey.net) detailing the initial work that formed the basis for this activity appeared recently and we hope it, and ongoing work, help influence future planning.
> The objective of the project was to examine the feasibility of outsourcing management of low-use print books held in academic libraries to shared service providers, including large-scale print and digital repositories. The study assessed the opportunity for library space saving and cost avoidance through the systematic and intentional outsourcing of local management operations for digitized books to shared service providers and progressive downsizing of local print collections in favor of negotiated access to the digitized corpus and regionally consolidated print inventory. \[[Cloud-sourcing Research Collections: Managing Print in the Mass-digitized Library Environment](https://www.oclc.org/research/news/2011-01-06.htm?ref=lorcandempsey.net)\]
The second is the GIST Gift & De-Selection Manager from SUNY College at Geneseo. This talks to the Worldcat API, Amazon, Hathi Trust and Google books, as well as the local library system, to provide decision support:
> The Gift and De-Selection Manager is an easy to implement and easy to use open-source standalone software for automating your gift management and de-selection processing. This standalone software is part of the Getting It System Toolkit (GIST), designed to leverage data of various systems, streamline library processes, and reduce staff time for decision making. \[[Getting It System Toolkit (GIST)](https://toolkit.idsproject.org/doku.php?id=wiki:gist&ref=lorcandempsey.net#gist%5Fgift%5Fde-selection%5Fmanager)\]
I have no first-hand knowledge of this tool, nor do I know how others find it. However, it is interestingly symptomatic of the growing interest in deselection support.
And third, I recommend that folks begin reading Rick Lugg’s very interesting blog devoted to issues around this topic: [Sample & Hold: Rick Lugg’s Blog: Sustainable collections, academic libraries, and management of legacy print](https://sampleandhold-r2.blogspot.com/?ref=lorcandempsey.net). As a principal in [R2](https://www.ebookmap.net/?ref=lorcandempsey.net), Rick is well known as a consultant on library workflow efficiency. R2 have introduced a new deselection service, Sustainable Collection Services \[[pdf](https://www.ebookmap.net/pdfs/ALAFlyerV4.pdf?ref=lorcandempsey.net)\], which again compares local holdings with a variety of other sources (including Worldcat) to provide decision support.
Here is a sample from Rick’s blog:
> Historically, this level of preservation, and the security of the scholarly record, have been the province of large research libraries. Smaller libraries have counted on the larger libraries to perform these functions–to run the FDIC layer. But increasingly, even the largest of these institutions, (even when acting in concert) cannot support the entire corpus and community by themselves. There is a need for every library to contribute to the integrity of the collective collection–by committing to archive specific titles and publicizing those commitments. The most promising avenue for such disclosure is use of the MARC 583 field in a WorldCat record, and work is underway to test the viability of this approach. \[[The FDIC Layer](https://sampleandhold-r2.blogspot.com/2011/01/fdic-layer.html?ref=lorcandempsey.net)\]
### Open for business
URL: https://www.lorcandempsey.net/open-for-business/
Last updated: 2020-10-28T09:07:17.000Z
Well, I wish I could say I was back by popular demand … but that might be stretching the truth just a little 🙂
I am resuming blogging activity for the new year. This also means that we will resume sending out the digest. However, we are going to experiment with a bi-weekly approach, which probably better matches the pace of blogging.
### Hiatus
URL: https://www.lorcandempsey.net/hiatus-2/
Last updated: 2020-10-28T09:07:20.000Z
A digest of this blog is distributed to registered readers each Monday morning. This week, only this entry will be noted as new.
I have slowed down on the blogging front and am now going to take a break for a while to focus on some other commitments.
I will return later in the year. In the interim, I will switch off distribution of the digest.
You can see me on [Twitter](https://www.twitter.com/lorcand?ref=lorcandempsey.net) …..
### Evolving research life ...
URL: https://www.lorcandempsey.net/evolving-research-life/
Last updated: 2020-10-28T09:07:27.000Z
I was interviewed for the British Library’s [*Growing Knowledge: the evolution of research*](https://www.growingknowledge.bl.uk/Default.aspx?ref=lorcandempsey.net) exhibition, which opened last week. I have not seen the physical installation yet but there is an [online presence](https://www.growingknowledge.bl.uk/Default.aspx?ref=lorcandempsey.net). See the [gallery](https://www.growingknowledge.bl.uk/StartResearching.aspx?ref=lorcandempsey.net) of digital research initiatives they showcase, for example, or the network [research tools](https://www.growingknowledge.bl.uk/Tools.aspx?ref=lorcandempsey.net).
One theme is the role of the library as it evolves to support changing research behaviors, exemplified by those initiatives and tools.
In that context, I was reminded of the recent report prepared for us by Susan Kroll and Rick Forsman which explores tools and services used by researchers throughout the research life cycle.
> Researchers have quickly adapted to products that expedite their work, while rejecting those tools and services that do not offer ease of use and sizable payoff. In interviews with 38 individuals at four prominent U.S. research universities, respondents reported how they use information in the course of their research, what tools and services are most critical and benefi cial to them, where they continue to experience unmet needs, and how they prioritize use of their limited time. \[A slice of research life: information support for research in the United States [PDF](https://www.oclc.org/research/publications/library/2010/2010-15.pdf?ref=lorcandempsey.net)\]
### The infrastructure is getting thicker ..
URL: https://www.lorcandempsey.net/the-infrastructure-is-getting-thicker/
Last updated: 2024-02-09T03:15:03.000Z
Andy Powell has a nice [post](https://efoundations.typepad.com/efoundations/2010/10/what-current-trends-tell-us-about-the-future-of-federated-access-management-in-education.html?ref=lorcandempsey.net) on general trends in educational use of networking. The context is a reflection on the future of federated access management but the points he makes are more generally interesting. He talks about the economic situation, outsourcing to the cloud and shared services, the varieties of openness, changing student expectations, the growth of mobile, the changing nature of the personal-institutional relationship, the changing nature of the publisher-consumer relationship, and issues of usability.
As usual the entry is well worth reading. One thing in particular has stuck with me. He talks about the ‘personal learning environment’ (PLE), a phrase that emerged some years ago to refer to the bricolage of generally available services from which students and others might construct their learning experiences. It is often used in explicit contrast to the prefabricated workflow environments offered in the virtual learning environment (VLE). (The VLE is a UK term for the course or learning management system).
Andy has a PLE trend …
> Similarly, the emerging [personal learning environment](https://en.wikipedia.org/wiki/Personal%5FLearning%5FEnvironment?ref=lorcandempsey.net) (PLE) meme (a favorite of educational conferences currently), where lecturers and students work around their institutional VLE by choosing to use a mix of external social web services (Flickr, Blogger, Twitter, etc.) again encourages the use of external services that are not impacted by our choices around the identity and access management infrastructure and over which we have little or no control. I was somewhat sceptical about the reality of the PLE idea until recently. My son started at the City of Bath College – his letter of introduction suggested that he created himself a Google Docs account so that he could do his work there and submit it using email or Facebook. I doubt this is college policy but it was a genuine example of the PLE in practice so perhaps my scepticism is misplaced. \[[eFoundations](https://efoundations.typepad.com/efoundations/2010/10/what-current-trends-tell-us-about-the-future-of-federated-access-management-in-education.html?ref=lorcandempsey.net)\]
Now, while the reference to the PLE is apt, I wondered whether the letter was a sign of a more general trend.
We have become used to a general level of ‘infrastructure provision’ from large web providers (the emergence of apps notwithstanding). This includes search and, by now, I think, email. We pay with our attention (advertising) or may be a small fee for a ‘pro’ service (see Flickr for example). These seem to be so well entrenched that we find it difficult to imagine them reverting to more niche services for which we pay a charge.
Now there are some services which we can imagine going away. Slideshare, for example, is a very useful service. However, recently I have found its banner ads very intrusive. Maybe it will be absorbed into a bigger service? Maybe it will go away? Maybe it will rely more on its freemium model?
What about Google Docs or Facebook? These are the examples Andy gives. Have they become part of the infrastructure we expect to be available to us as part of our everyday network use? I suspect that they have. Google Docs may not have the heavy use of other services, but it is there, it is part of the Google suite, and if it does goes away it is likely that alternatives will be available (as of course some already are). We are likely to have various services as part of the ensemble Google, or Microsoft, or Apple, assembles for which we pay in various other ways.
The network application infrastructure has become thicker.
Coming back to PLEs or to the educational enterprise … neither of these services is integral to what the university or college offers. They complement or augment what is available, or they replace functions that are not especially distinctive.
Which of course prompts the question about where the university focus should be …. especially in the current environment of budget reduction.
What is distinctive and should not be ceded to third party network services?
### Influencing how you are seen in results ...
URL: https://www.lorcandempsey.net/influencing-how-you-are-seen-in-results/
Last updated: 2020-10-28T09:07:37.000Z
Two websites I regularly look at are the *The Guardian* and *Times Higher Education*. In my lazy way I will often just pop the names into Google when looking for them. I have been interested in how they are characterised in Google results, based on what they put in the Meta description tags.
Before saying something about these, here is a note from Google:
> While accurate meta descriptions can improve clickthrough, they won’t impact your ranking within search results. We frequently prefer to display meta descriptions of pages (when available) because it gives users a clear idea of the URL’s content. This directs them to good results faster and reduces the click-and-backtrack behavior that frustrates visitors and inflates web traffic metrics. \[[Google webmaster central](https://www.google.com/support/webmasters/bin/answer.py?hl=en&answer=35264&ref=lorcandempsey.net)\]
So, what does *The Guardian* want the world to see it as it comes up in Google results? What does it think will encourage people to clickthrough to its site?
This is quite interesting as it uses ‘liberal’ in an American sense. Is this a part of the Guardian’s positioning as a global website rather than just a UK newspaper?
Here is *The Times Higher* …
The reference to the World Rankings has been there for some time, before the recent publication of this year’s rankings. Again, global interest in the rankings transcends the UK focus of the publication. World rankings has been added to the title and to the description. Leading with ‘jobs’ in an interesting indicator of what it sees as important.
And speaking of rankings, here is the University of Michigan:
‘Diverse’ is also a word used by Ohio State:
University College Dublin doesn’t want anybody to be under any misapprehension about its position in the world, qualifying the title also …
The University of Warwick offers only its name, so Google steps in with its view about what might be important 😉
A very quick review of some public libraries suggested that the meta description tag is not widely used in this tactical way. Ditto for academic libraries. This is surprising given the potential influence on how people see a result. I would be interested to see some work on what influence such descriptions have on click-through rates, in particular in our domain, if it exists.
That said, here is Cleveland Public Library ..
… and Cambridge University Library …
### Books about universities ... expansion
URL: https://www.lorcandempsey.net/books-about-universities-expansion/
Last updated: 2022-11-10T18:22:57.000Z
This is a slightly expanded version of a [blog pos](https://blog.oclc.org/lorcand/archives/001883.html?ref=lorcandempsey.net)t first published in February 2009\. I was reminded of it in a discussion I had during the week with a colleague about publications about universities and thought I would bring it back.
Many of the pages in Worldcat Identities are for corporate authors, [Ohio State University](https://www.worldcat.org/identities/lccn-n79-46205?ref=lorcandempsey.net), for example.
It is interesting in these cases to see what the most widely held works about the institution in question are. Here are some examples from universities …..
So, the [list of most widely held works about](https://www.worldcat.org/identities/lccn-n79-46205?ref=lorcandempsey.net#linkworksabout) Ohio State University, maybe not unsurprisingly, has a strong football flavor. Quite a few universities have strong sporting coverage: see [Indiana University, Bloomington](https://worldcat.org/identities/lccn-n80-126367?ref=lorcandempsey.net#linkworksabout), for example, or [UCLA](https://worldcat.org/identities/lccn-n79-46090?ref=lorcandempsey.net#linkworksabout).
Thinking along these lines, I tried Notre Dame, only to discover that the [list](https://www.worldcat.org/identities/lccn-n79-22791?ref=lorcandempsey.net#linkworksabout) is dominated by mystery novels by [Ralph McInerny](https://www.worldcat.org/identities/lccn-n79-18057?ref=lorcandempsey.net).
Where an institution figures centrally in a popular work of fiction, it may not be surprising to see it in the list, although it might not be what immediately comes to mind. So, [E.M. Forster](https://www.worldcat.org/identities/lccn-n79-91231?ref=lorcandempsey.net)‘s posthumously published Maurice is recorded as the most widely held work about the University of Cambridge. There are also two writers of mysteries set in Cambridge on [the list](https://www.worldcat.org/identities/lccn-n79-18862?ref=lorcandempsey.net#linkworksabout): [Jill Paton Walsh](https://www.worldcat.org/identities/lccn-n50-80396?ref=lorcandempsey.net) and [Susanna Gregory](https://www.worldcat.org/identities/lccn-n96-57522?ref=lorcandempsey.net). [Trinity College Dublin](https://worldcat.org/identities/lccn-n79-77553?ref=lorcandempsey.net#linkworksabout)‘s list is topped by The Ginger Man by J.P. Donleavy.
This prompted me to go looking for Inspector Morse in the [University of Oxford](https://www.worldcat.org/identities/lccn-n79-95521?ref=lorcandempsey.net#linkworksabout) page, but did not find him. The two books by [John Bayley](https://www.worldcat.org/identities/lccn-n50-5533?ref=lorcandempsey.net) about his wife [Iris Murdoch](https://www.worldcat.org/identities/lccn-n80-13587?ref=lorcandempsey.net) feature in the top four, as does a novel by [Alan Hollinghurst](https://www.worldcat.org/identities/lccn-n86-822799?ref=lorcandempsey.net), *The line of beauty*.
Maybe predictably, [Humphrey Carpenter](https://www.worldcat.org/identities/lccn-n80-1545?ref=lorcandempsey.net)‘s book about the Inklings ([Tolkein](https://www.worldcat.org/identities/lccn-n79-5673?ref=lorcandempsey.net), [Lewis](https://www.worldcat.org/identities/lccn-n79-3974?ref=lorcandempsey.net) and colleagues) is also in the Oxford top four. [Cardinal Newman](https://www.worldcat.org/identities/lccn-n78-95501?ref=lorcandempsey.net) figures strongly in the [University College Dublin](https://www.worldcat.org/identities/lccn-n50-27617?ref=lorcandempsey.net) list, which is headed by a book about [Gerard Manley Hopkins](https://www.worldcat.org/identities/lccn-n80-32727?ref=lorcandempsey.net), but interestingly [Joyce](https://www.worldcat.org/identities/lccn-n79-56824?ref=lorcandempsey.net) does not figure. There are a couple of books about [Condoleeza Rice](https://www.worldcat.org/identities/lccn-n82-242801?ref=lorcandempsey.net) in the top five at [Stanford](https://www.worldcat.org/identities/lccn-n79-54636?ref=lorcandempsey.net#linkworksabout).
Gerard Manley Hopkins also figures in the entry for [Gonzaga University](https://worldcat.org/identities/lccn-n80097965/?ref=lorcandempsey.net), where again, perhaps unsurprisingly, sport leads, with basketball this time. In this case, the Hopkins presence reflects a strong historical collecting interest.
In some cases, particular events figure strongly near the top of the [list](https://www.worldcat.org/identities/lccn-n79-96729?ref=lorcandempsey.net#linkworksabout) as with the tragic shootings at Kent State University in 1970\. Events and cultural change in the 60s are well represented in books about several universities, including [Berkeley](https://www.worldcat.org/identities/lccn-n79-46084?ref=lorcandempsey.net#linkworksabout) and [Columbia](https://worldcat.org/identities/lccn-n81-24714?ref=lorcandempsey.net#linkworksabout).
Sometimes, the most widely held item might not be something that the institution would have chosen. [E.P. Thompson](https://www.worldcat.org/identities/lccn-n78-89033?ref=lorcandempsey.net)‘s book on the [University of Warwick](https://www.worldcat.org/identities/lccn-n50-59535?ref=lorcandempsey.net#linkworksabout) is an example I came across. Two of the top five on MIT’s [list](https://www.worldcat.org/identities/lccn-n79-6591?ref=lorcandempsey.net#linkworksabout) are about the MIT students who famously went to Vegas.
And of course, histories of, or administrative materials about, the institution will often feature strongly, as with [Lund](https://worldcat.org/identities/lccn-n79-58408?ref=lorcandempsey.net#linkworksabout), [Bath](https://worldcat.org/identities/lccn-n80-24621?ref=lorcandempsey.net#linkworksabout), or [Toronto](https://worldcat.org/identities/lccn-n79-75463?ref=lorcandempsey.net#linkworksabout) for example. Similarly, a founder, president or other significant figure associated with the University may feature, as with [Robert Maynard Hutchins](https://worldcat.org/identities/lccn-n50-30338?ref=lorcandempsey.net) and the [University of Chicago](https://worldcat.org/identities/lccn-n79-58404?ref=lorcandempsey.net#linkworksabout).
In some cases, the contribution of the university in a longer historical perspective is the subject, as with [Bologna](https://worldcat.org/identities/lccn-n79-43915?ref=lorcandempsey.net#linkworksabout), [Leiden](https://worldcat.org/identities/lccn-n79-58414?ref=lorcandempsey.net), or the [Université de Paris](https://worldcat.org/identities/lccn-n79-129805?ref=lorcandempsey.net#linkworksabout).
I am not sure how much to take away from this superficial exploration, but here are a few random observations …
- Much depends on the vagaries of cataloguer/classifier activity.
- I was surprised not to find more scientists, although I did not look for very long (a book about [Rutherford](https://www.worldcat.org/identities/lccn-n50-24959?ref=lorcandempsey.net) is on top of the list at [Manchester](https://www.worldcat.org/identities/lccn-n80-126193?ref=lorcandempsey.net#linkworksabout)). The absence of women was also notable; I did come across some cases where a discussion about the status of women featured, [Oberlin](https://www.worldcat.org/identities/lccn-n79-99236?ref=lorcandempsey.net#linkworksabout) and [Cornell](https://www.worldcat.org/identities/lccn-n79-21621?ref=lorcandempsey.net#linkworksabout), for example.
- The web environment has made us very aware of how what is said by others about an institution is as readily available as what it says about itself. Maybe it was always thus, but less generally visibly? For many institutions, however, histories, lives of presidents, celebrations of various types, and other such materials were heavily represented. Just as, on the web, institutional materials will also feature strongly.
- I did not explore long enough or closely enough to develop a list of recurrent issues, but this would have been interesting (the influence of sports, the status of women in education, and unrest in the sixties were all examples that did surface).
- This is something of a time sink!
**Note:** Stylistic updates 10 November 2022\. Paragraph about Gonzaga, summary note at top, and feature image all also added then. Of course, changes in collections may have affected the results if I repeated the searches today.
### "How golden is your retriever?" Maurice Line RIP
URL: https://www.lorcandempsey.net/how-golden-is-your-retriever-maurice-line-rip/
Last updated: 2020-10-28T09:07:43.000Z
My former UKOLN colleague Ruth Burt sent me a note last week noting that Maurice Line had died. Ann Chapman writes about his work at the University of Bath, where he was the first University Librarian, as follows …
> While at Bath, Line initiated a number of research projects. INFROSS, a study of social scientists’ information requirements (at the University of Bath and Newcastle University), was followed by DISISS, a study on the designs of information systems (in collaboration with the Polytechnic of North London). Taking place in parallel with both these projects was a three-year (1969-1971) Experimental Information Service in the Social Sciences, working with researchers and teachers at the Universities of Bath and Bristol.
> Line also initiated work on the development of library catalogues, encouraging technical services librarian Philip Bryant to start researching in this area. The initial Bath Mini-Catalogue Project in 1971 led to other projects looking at catalogues and bibliographic data, including the Bath University Programme of Catalogue Research, which evolved into the Centre for Catalogue Research in 1977, subsequently changing its name to the Centre for Bibliographic Research and later to UKOLN. \[[Dr Maurice Line](https://www.ukoln.ac.uk/ukoln/history/line-maurice/?ref=lorcandempsey.net)\]
Of course he went on to a senior position in the British Library (by way of one of its antecedent organizations), making multiple contributions to the development of libraries and librarianship in the UK and around the world.
The above extract shows two of his attributes: his interest in research and data, and his energy. He never forgot that libraries existed in service of others, not to perpetuate their own structures and practices.
I moved to England in the late 80s to join what had just become The Centre for Bibliographic Management at the University of Bath. Line was long gone, but some of the library staff still remembered him. I remember one telling me how he would climb the stairs two or three at a time, determined to get to the top before whoever was with him.
The phrase in the title of this post is the title of one of his articles. He made a [large contribution](https://scholar.google.com/scholar?q=maurice+line&ref=lorcandempsey.net) to the library literature, professional and more formal. These lines quoted by Andrew Pace a while ago are characteristic:
> Trying to hold on to unused publications that libraries no longer have room to house, having theological arguments about the contents of catalogue records, and indulging in the numerous other irrelevant, inappropriate or trivial activities of which librarians are so fond, with their unerring eye for the inessential. \[[Hectic Pace](https://blogs.ala.org/pace.php?title=an%5Funerring%5Feye%5Ffor%5Fthe%5Finessential&ref=lorcandempsey.net)\]
I last met Maurice Line at the [30th anniversary celebration](https://www.ukoln.ac.uk/events/anniversary-2008/?ref=lorcandempsey.net) of the founding of UKOLN, an organization he was pleased to have been involved in starting. He also participated by video in the memorial celebration of Fred Kilgour’s life, which was apt as each had contributed rather more than most to the evolution of library services.
### Presenting ....
URL: https://www.lorcandempsey.net/presenting/
Last updated: 2020-10-28T09:07:49.000Z
Although I give quite a few presentations, I don’t really present enough for them to become ends in themselves. I am thinking of this content-wise and style-wise.
Content-wise, I tend to talk about things that are currently on my mind unless I have been asked to describe a particular set of activities or address a particular topic. This means that I have a running set of themes which evolves through presentations. It also means that I find it difficult to go back to earlier themes, even if they remain relevant. And it means that presentations may not have a definitive or conclusive feel. As I say, this is because they tend to flow from current concerns rather than be crafted as statements about a particular topic.
Style-wise, for internal OCLC events, or when I am speaking with colleagues, I will tend to use an OCLC template. Otherwise, I tend to use an evolving one of my own. Partly, I must admit, because fiddling with the template seems a reasonable displacement activity when trying to prepare a presentation 😉 If I did more, I would probably aim for something more definitive.
But that is enough about me …
For the above reasons, I am quite interested in the style of presentations I see. In fact, I am probably more impressed by some nice Powerpoint (it is usually Powerpoint), or how it is used, than I should be. In recent years, we have seen several trends which depart from the heading and bullet-point style ….
- White on black. Lawrence Lessig changed presentations. Here is how Presentation Zen [characterised](https://www.presentationzen.com/presentationzen/2010/08/lawrence-lessig-on-remix-redux.html?ref=lorcandempsey.net) his style: “His rapid pace and quick slide transitions include a mix of short bursts of text, images, and video clips”. Dick Hardt [did this](https://identity20.com/media/OSCON2005/?ref=lorcandempsey.net) famously. Rather than being a reflection of the words, the presentation is a foil. Now, a Lessig presentation is a unique event. Often we see influences rather than the whole package, as in the now common use of large white phrases on a black background. When done well, this can work nicely.
- The Flickr turn. It is now common to see presentations that almost entirely comprise text superimposed on ‘found’ Flickr images, where the image is an amusing or amplifying commentary on the text. Again. this can work well when done well. It is less good at leaving a record of the presentation for others to read. And it can also be tedious or distracting, as the relevence or otherwise of the image becomes the main message of the slide.
- Prezi. And junking Powerpoint altogether, Prezi has recently emerged as an alternative approach, developed, [according to the founders](https://prezi.com/about/?ref=lorcandempsey.net), because “they felt slides limited their ability to develop and explain ideas”. Perhaps this is why I have yet to see a Prezi presentation I have enjoyed. It seems that the rationale is to be not-Powerpoint, rather than actually to be something else. And in unsophisticated hands the ‘swoosh’ effect can be offputting. Again, there is a danger of distraction as the medium intrudes on attention too much. And what would it be like seeing a series of Prezi presentations in a row?
Of course, a good presenter is usually enjoyable whatever aid they use. And those for whom presenting is central enough may take more care. That said, it is always nice to see some nice slides …. 😉
(I only recently realized the size of the market for blog themes that the WordPress platform has created. It is really quite interesting browsing some of the design sites of those who appear to make a living designing themes. It is also nice coming across a pleasingly designed blog. I am not sure, but I think that I am less swayed, though, by blog design than I am by presentation design 😉
### Changing communications ....
URL: https://www.lorcandempsey.net/changing-communications/
Last updated: 2020-10-28T09:07:53.000Z
I was struck by this comment by Om Malik as he talked about the acquisition of the TechCrunch group of blogs by AOL.
> Earlier this week, when he announced the acquisition, it dawned on me what a pivotal moment in the history of blog-based media entities it was. Five years ago, we were the upstarts, the outsiders and the crazies. Today, we are the media. Go figure! \[[Michael Arrington’s Road to Millions](https://gigaom.com/2010/09/29/michael-arringtons-road-to-millions/?ref=lorcandempsey.net)\]
It nicely captures a particular arc of development ….
Related entries:
- [Blogging \[II\]](https://blog.oclc.org/lorcand/archives/001989.html?ref=lorcandempsey.net)
- [Blogging \[I\]](https://blog.oclc.org/lorcand/archives/001948.html?ref=lorcandempsey.net)
### Sorting out demand again ....
URL: https://www.lorcandempsey.net/sorting-out-demand-again/
Last updated: 2021-04-10T03:39:53.000Z
Ask.com announced the demise of Bloglines a while ago. From October 1st the service will no longer exist. The rationale was twofold: first they wanted to focus on their core business, and second they described how the environment had changed ….
> A little perspective: when we originally acquired Bloglines in 2005, RSS was in its infancy. The concept of “push” versus “search” around information consumption had become very real, and we were bullish about the opportunity Bloglines presented for our users. Flash forward to 2010\. The Internet has undergone a major evolution. The real-time information RSS was so astute at delivering (primarily, blog feeds) is now gained through conversations, and consuming this information has become a social experience. As Steve Gillmor pointed out in TechCrunch last year , being locked in an RSS reader makes less and less sense to people as Twitter and Facebook dominate real-time information flow. Today RSS is the enabling technology – the infrastructure, the delivery system. RSS is a means to an end, not a consumer experience in and of itself. As a result, RSS aggregator usage has slowed significantly, and Bloglines isn’t the only service to feel the impact.. The writing is on the wall. \[[Bloglines update](https://blog.ask.com/2010/09/bloglines-update.html?ref=lorcandempsey.net)\]
When I saw this I was reminded of the shift from sorting out supply to sorting out demand I have [discussed](https://blog.oclc.org/lorcand/archives/002124.html?ref=lorcandempsey.net) recently.
As we have multiple channels of supply, the focus shifts to making demand more efficient. This happens through conversation as suggested above, through connections made through social environments, and through context (ranking/relating/recommending based on usage data).
Two other service announcements reinforce this trend:
Amazon offers a personal page which pulls together your recent activity and recommendations for you based on this. Recently, they announced an integration with Facebook.
[](https://www.amazon.com/gp/facebook?ref=lorcandempsey.net)
They are using Facebook to provide additional context and community around items of shared interest, connecting through the ‘[social objects](https://blog.oclc.org/lorcand/archives/001601.html?ref=lorcandempsey.net)‘ (books, movies, …) about which we disclose information.
I don’t provide a screenshot here, as the more interesting ones have details of my Facebook ‘friends’ on them.
The second is a browsing interface to Facebook pages.
[](https://www.facebook.com/pages/browser.php)
Here is TechCrunch:
> Today, it’s officially launching a Page Browser that suggests Pages you may be interested in, with an interface somewhat reminiscent of Netflix that allows you to filter by category. Suggestions are tailored based on pages you’ve previously ‘Liked’, and following a new Page simply entails clicking on its icon. \[[Facebook Wants You To ‘Like’ More Stuff, Officially Launches ‘Page Browser’](https://techcrunch.com/2010/09/24/facebook-discover-pages/?ref=lorcandempsey.net)\]
These are early and evolving steps. The mention of Netflix is apt given its investment in this area also.
The rich texture of suggestion is getting richer ….
Related entries:
- [Community is the new content](https://blog.oclc.org/lorcand/archives/002013.html?ref=lorcandempsey.net)
- [Sorting out demand – Top Tech Trend 3](https://blog.oclc.org/lorcand/archives/002124.html?ref=lorcandempsey.net)
- [The rich texture of suggestion](https://www.google.com/search?q=&ref=lorcandempsey.net)
### Library literature again ...
URL: https://www.lorcandempsey.net/library-literature-again/
Last updated: 2023-06-28T04:13:02.000Z
## Two interventions
First a mention of two recent articles ….
Rick Anderson has a very nice piece in *Educause Review* about budgets, libraries and scholarly publishers. It is an interesting reflection on systemic change, always difficult to manage as it involves reconsidering why things are done as well as how they are done.
> Scholarly publishers are looking at libraries right now and seeing what has always been the best and most reliable market for their products suddenly changing into a highly unreliable one. There is very little likelihood that library budgets will grow significantly (if at all) anytime soon; in fact, there is a strong likelihood that they will shrink again next year–in many cases, for the second year in a row. Furthermore, even if budgets begin growing again, it is highly unlikely that they will ever rise to their pre-2008 levels or that libraries will resume buying books the way they did in the past. Traditional library collection development has meant buying large amounts of materials in the hope that those materials will turn out to be what patrons need, but financial constraints are now forcing libraries to move in a more patron-driven and less speculative direction. Having figured out how to do so, most libraries will probably continue to develop their collections this way for some time to come, if not permanently. // [If I were a scholarly publisher](https://www.educause.edu/EDUCAUSE+Review/EDUCAUSEReviewMagazineVolume45/IfIWereaScholarlyPublisher/209335?ref=lorcandempsey.net)
This article is what might be called an ‘intervention’. It contributes to an important debate and deserves to be widely read by library managers. To achieve its goals it needs to be published somewhere that aggregates the attention of a senior audience. It is interesting that it is published in *Educause Review*, which aggregates the attention of a senior IT and information management audience in higher education. In that sense *Educause Review* it is a platform publication, in the way that, say, variously, *Harvard Business Review*, *IEEE Spectrum*, *Communications of the ACM*, or *Nature* are. These publications aggregate attention in their communities, and beyond. They provide a platform for their authors.
The second is an article by Ted Striphas: ‘Acknowledged Goods: Cultural Studies and the Politics of Academic Journal Publishing’. This is academic writing in the idiom of cultural studies. He argues that although the institutions of communication are central objects of study among his colleagues, those colleagues are unreflective about the institutions of scholarly communication upon which their discipline depends.
> This type of thinking is symptomatic of the sense of alienation I suspect many people in cultural studies feel from the instruments of production, distribution, and propagation of both our work and our field.8 We access these instruments all the time. We depend on them significantly for our livelihoods. What would cultural studies be without its publications, and without the formidable network of social, economic, legal, and infrastructural linkages to the publishing industry that sustains them? Nevertheless, many of us are reluctant to pause long enough to take stock of the choices we make–or that are made for us–when publishing our work, much less to consider how those choices may reverberate well beyond the immediate confines of cultural studies. // [Acknowledged goods. Worksite.](https://striphas.wikidot.com/acknowledged-goods-worksite?ref=lorcandempsey.net)
Reading this, I was struck by the parallel with the library literature. Libraries acquire and manage literature for others, and are very familiar with individual publisher practices, and the business of distribution which underlies scholarly communication. However, librarians can sometimes seem strangely unreflective about the structure of their own disciplinary literature.
## Reflections on the library literature
Here are some issues that prompt this statement ….
- I am not thinking of open access in particular here, although Doug Way recently published an interesting article exploring rates of deposit among authors of the library literature.
> To examine the open access availability of Library and Information Science (LIS) research, a study was conducted using Google Scholar to search for articles from 20 top LIS journals. The study examined whether Google Scholar was able to find any links to full text, if open access versions of the articles were available and where these articles were being hosted. The results showed the archiving of articles is not a regular practice in the field, articles are not being deposited in institutional or subject repositories at a high rate and the overall the percentage of available open access articles in LIS was similar to the findings in previous studies. // [The Open Access Availability of Library and Information Science Literature](https://works.bepress.com/doug%5Fway/2/?ref=lorcandempsey.net)
- I have not checked to see how the number of publications in our field compares to other disciplines, or if the work to find out has been done. However, we appear to have a proliferation of journals, many of little sustained interest. These are supported by editors, editorial boards, authors, purchasers. The literature is a citation farm for those involved in formal research activity, and in the US, a necessary career convenience for those librarians who work within the tenure system. I remember once sending an email to a university colleague asking had she a copy of an article. This was on the basis of a related article which I thought was very good. She responded bemusedly that I shouldn’t be reading this article, that it was just something written towards an application for tenure. There are certainly many interesting articles published, but I wonder about the system as a whole. The literature is very fragmented; few journals rise to the ‘must-read’ category.
- This last point relates to the absence of a ‘platform publication’ in the sense described above in the library community. There is no natural venue within the library literature for an intervention of the type I began with, which will aggregate the attention of a large part of library management. I wonder why this is so. Does it matter?
A personal coda: My colleague John MacColl and I founded the *Ariadne* magazine many years ago, based on an idea and proposal by John. The original purpose was probably twofold: to provide a platform publication for discussion of the future of libraries in a network environment and to provide a venue for discussion of the JISC and other digital library projects which were becoming such a feature of the higher education scene. While it does a very nice job still on the second of these, the platform aspect has probably receded.
**Related entries:**
- [Communications](https://blog.oclc.org/lorcand/archives/001394.html?ref=lorcandempsey.net)
- [Bright is the old grey](https://blog.oclc.org/lorcand/archives/001402.html?ref=lorcandempsey.net)
**Note:** Cosmetic amendments on 3 April 2021 to fix spacing and add headings.
### The idea of FRBR ...
URL: https://www.lorcandempsey.net/the-idea-of-frbr/
Last updated: 2020-10-28T09:08:11.000Z
Not having a copy of *[The Idea of a university](https://www.worldcat.org/title/idea-of-a-university/oclc/33103649/editions?referer=di&editionsView=true&ref=lorcandempsey.net)* to hand, I was looking in Google Book Search and Amazon earlier. Newman is in the news (here is the [Wall Street Journal](https://online.wsj.com/article/SB10001424052748704111704575355321702751364.html?ref=lorcandempsey.net)), and I was curious to have a quick look. Sad to say, I even did a search for library to see what he had to say on that topic.
Here is what I saw in Amazon when I did the search …

I was interested to see that they think the difference between editions is important enough to highlight. See the ‘Just so you know’ banner at the top of the page. It tells me that the text I am about to search is an instance of a different edition than the one I was originally looking at and clicked on.
Managing this type of similarity (bringing together different versions of *The Idea of a university*) and difference (discriminating between those different versions) is something that is becoming of more interest in our systems and services. And of course it is these types of relationship that underly a central part of the FRBR model.
I have become more aware that FRBR is sometimes presented as if it is some great mystery whereas what it is about is defining some useful relationships between the things that are of interest to us, so that we can usefully manage and present them.
Incidentally, it is interesting to see how Universities and Higher Education figure strongly in the FAST cloud on Newman’s Worldcat Identities page ….
[](https://www.worldcat.org/wcidentities/lccn-n78-95501?ref=lorcandempsey.net)
### Newman
URL: https://www.lorcandempsey.net/newman/
Last updated: 2022-11-08T16:37:37.000Z
And speaking of UCD …. To be a student at University College Dublin was to be very much aware of Cardinal Newman, in name at least, as he lent it to various buildings, institutions and initiatives. Cardinal Newman has been much in the news recently, in advance of his beatification by the Pope in Birmingham earlier today.
> John Henry Cardinal Newman (1801-1890) was the founding rector in 1854 of the Catholic University of Ireland, the antecedent institution of University College Dublin. Newman lived in Dublin from 1851-58 and in those years delivered the lectures and wrote the articles which were later published together as The Idea of a University, one of the most enduring texts ever written about university education. \[[UCD – Remembering John Henry Newman](https://www.ucd.ie/lifeatucd/2010/09SEPTEMBER/newman/?ref=lorcandempsey.net)\]
Here is the *Times Higher* on Newman (in a piece ‘reprinted’ in *Inside Higher Ed*), quoting Robert Anderson, emeritus professor of history at the University of Edinburgh …
> When asked about the cardinal’s impact on higher education, the professor said that Newman’s ideas were little discussed until the 20th century – and then more so in the US than in Britain. “He is seen as a spokesman for the idea of liberal education, and in some ways that is more of a live issue in America than in Britain, with liberal-arts colleges.”
> Many of Newman’s ideas do not fit with the “sort of rhetoric vice-chancellors use” when they pepper speeches with references to The Idea of a University, the professor added, and go against the modern concept of “league tables, the research university – the international model”. \[[Saintly champion of liberal values out of step with business zeitgeist](https://www.timeshighereducation.co.uk/story.asp?sectioncode=26&storycode=413529&ref=lorcandempsey.net)\]
The irony here of course is that the Times Higher has just published its [World University Rankings](https://www.timeshighereducation.co.uk/world-university-rankings/?ref=lorcandempsey.net), for the first time this year carried out in conjunction with Thomson Reuters.
Similar sentiments to Robert Anderson’s are expressed by Conall 0 Móráin in the *UCD Today* magazine as he introduces an interview with “Director of the UCD International Centre for Newman Studies, Dr Pádraic Conway about Theologian, Educationalist and UCD’s Founding Rector, John Henry Newman”. \[[PDF](https://www.ucd.ie/ucdtoday/2010/06JUN10/documents/UCD%20Today%20Summer%202010%20%5Fweb%5FPart7.pdf?ref=lorcandempsey.net)\]. He contrasts a utilitarian view of the university with Newman’s views.
This contrast, between Newman’s views on a liberal education and a perceived view of the values of some modern universities, was expressed with typical strength by Terry Eagleton recently …
> It was in the plan for his Catholic university in Dublin that Newman’s generosity of spirit can be seen at its finest. Catholics in Ireland were barred from Trinity College, Dublin, and the Queen’s Colleges, established by the British government to civilise the natives and render them less troublesome, were secular institutions where no theology was taught. Newman, however, did not insist that theology should rule in the Catholic university. He believed that pursuing any branch of knowledge for its own sake was a religious activity, since the whole of Nature was God’s creation. In The Idea of a University, he speaks up for an ‘intercommunion’ of all the principal academic disciplines and for disinterested scholarly inquiry. The task of a university is to foster intellectual culture for its own sake, which means that it can be the tool of neither church nor state. His book needs to be placed in the hands of the vandals, philistines and soulless bureaucrats who are currently destroying our places of higher learning. \[[LRB – Washed in milk](https://www.lrb.co.uk/v32/n15/terry-eagleton/washed-in-milk?ref=lorcandempsey.net)\]
**Note:** Feature picture added 8 November 2022\.
### Brutalist architecture and libraries
URL: https://www.lorcandempsey.net/brutalist-architecture-and-libraries/
Last updated: 2025-05-19T04:56:50.000Z
I was talking to Carole Moore, Chief Librarian of the University of Toronto Libraries, recently about [Robarts Library](https://www.library.utoronto.ca/robarts/?ref=lorcandempsey.net), described by [Wikipedia](https://en.wikipedia.org/wiki/Robarts%5FLibrary?ref=lorcandempsey.net) as one of “the most significant examples of brutalist architecture in North America”.
Curious, I followed the [Wikipedia link](https://en.wikipedia.org/wiki/Brutalist%5Farchitecture?ref=lorcandempsey.net) to brutalist architecture. I was interested to find several libraries mentioned there alongside Robarts.
In fact, pride of place in the article is given to the striking Geisel Library at the University of California, San Diego. It notes that it “is one of the most famous examples of brutalist architecture, and has been featured in a number of science fiction movies”.
[](https://w.wiki/BWKg?ref=lorcandempsey.net)
Geisel Library, University of California, San Diego
Ryerson University Library, also in Toronto, is listed. (Update: Ryerson is now Toronto Metropolitan University.)
[](https://w.wiki/BWKo?ref=lorcandempsey.net)
Toronto Metropolitan University, formerly Ryerson
As is the Folsom Library, Rensselaer Polytechnic Institute …
[](https://w.wiki/BWKn?ref=lorcandempsey.net)
Folsom Library, RPI
… and the Regenstein Library at the University of Chicago.
[](https://w.wiki/BWKo?ref=lorcandempsey.net)
Regenstein Library, University of Chicago
Several other libraries are mentioned.
The entry also gives one reason why there are so many examples:
> In the late 1960s, many campuses in North America were undergoing expansions and, as a result, there are a significant number of Brutalist buildings at American and Canadian universities, beginning with Paul Rudolph’s 1958[Yale Art and Architecture Building](https://en.wikipedia.org/wiki/Yale%5FArt%5Fand%5FArchitecture%5FBuilding?ref=lorcandempsey.net). \[[Wikipedia – Brutalist architecture](https://en.wikipedia.org/wiki/Brutalist%5Farchitecture?ref=lorcandempsey.net)\]
And, of course, the latter houses a library. A few moments thought will uncover others (Glasgow University Library, for example).
Examples are not limited to academic libraries alone. Birmingham Central Library comes to mind, whose “inverted ziggurat form”, [Wikipedia says](https://en.wikipedia.org/wiki/Birmingham%5FCentral%5FLibrary?ref=lorcandempsey.net), “is a powerful example of the Brutalist style.” (Update: The new Library at Birmingham was opened in 2013, replacing this building.)
Anyway, back to my conversation with Carole. I suggested that there might be interest in a calendar of Libraries in the Brutalist style. There certainly seem to be enough to handsomely fill out all twelve months and more. I would certainly buy one!
**p.s.** I regularly drive past the oddly striking Ohio Historical Center building in Columbus, which is brutalist in style and seems very much of its time.
**p.p.s.** The Wikipedia entry notes that much of the Belfield campus of University College Dublin is brutalist in style. I always liked the Wejchert buildings there, from when I was a student, although they have changed internally over the years.
[](https://www.flickr.com/photos/ajcarr/527039158/in/photolist-Nzdo3-LAdwhG-NvgXL-85pVXT-GWK5Cj-GWK5qq-GZ1jMP-TcAxwj-2k88cW6-68mdEv-2psdW4D-GWK5o1-Gaycsq-GZ1jQ4-GWK5Bh-GWK5n9-PeEuV-8917wx-GWK5BC-GWK5kA-8WKfsB-GZ1jFM-GaycvG-Gaycuu-GWK5E3-Pbm3Q-Pbmco-7p2UXe-8WNhUS-Pdnfm-7Em3C2-PdkEY-2k88cS8-75YefJ-649C2U-anraVZ-4NiZjU-s1yu9v-6TB4AY-TZLuWU?ref=lorcandempsey.net)
Arts Building, UCD. [Alun J Carr](https://www.flickr.com/photos/ajcarr/?ref=lorcandempsey.net). Attribution-NonCommercial-NoDerivs 2.0 Generic.
**Pictures:** Library pictures above are from [Wikimedia Commons](https://commons.wikimedia.org/wiki/Main%5FPage?ref=lorcandempsey.net) and link through to sources there.
**Note:** Cosmetic changes and updates 11 October 2024, 18 May 2025.
### Emerging network level management of the collective print collection
URL: https://www.lorcandempsey.net/emerging-network-level-management-of-the-collective-print-collection/
Last updated: 2022-12-10T05:30:46.000Z
One of the recurrent themes in these pages is that systemwide coordination of print materials is necessary as libraries begin to retire collections – to offsite storage or removing them altogether. There are various drivers here: the demands on space, the emergence of a digital corpus, the cost of managing a resource that releases progressively less value in research and learning. Print runs of journals have been an early focus, but interest is extending to books also. I believe we are moving to a situation where network-level management of the collective collection becomes the norm, but it will take some years for service, policy and infrastructure frameworks to be worked out and evolution will be uneven. The network may be at the level of a consortium, a state or region, or a country. At the moment, this trend is manifesting itself in a variety of local or group mass storage initiatives, as well as in several regional and national initiatives.
Last week, I came across interesting discussions of two of the more high profile initiatives in this area. These are *[WEST: toward a Western Regional Storage Trust](https://www.cdlib.org/services/collections/sharedprint/westinitiative.html?ref=lorcandempsey.net)*, a US consortium of institutions, and the *[UK Research Reserve](https://www.ukrr.ac.uk/?ref=lorcandempsey.net)*, a national approach.
Karen Schneider discusses West, placing it in the context of her own library’s needs to reclaim space to meet local needs.
> But the most significant infrastructure issue faced by the library facility is that the bulk of the space is occupied by very-low-use materials: books and journals.
> In the mid-1950s, it made sense that the bulk of the library’s space needs were occupied by then-state-of-the-art information tools. But the only way our library can maintain relevance is to reclaim the bulk of this space for 21st-century services such as information literacy instruction, faculty technology development, group study, and cultural events. We are not a museum for obsolete information technologies; to again quote our beloved Ranganathan, “The library is a living organism.” \[[Free Range Librarian](https://freerangelibrarian.com/2010/09/04/the-west-project-the-first-shoe-drops-for-the-big-shift/?ref=lorcandempsey.net)\]
The UKRR was a central topic at the [Dare to Share conference](https://www.bl.uk/blpac/dare.html?ref=lorcandempsey.net) organized by the British Library’s Preservation Advisory Centre and Research Libraries UK to consider preservation as a part of collective approaches to print management. I was not at this event, but it generated very interesting twitterage, the [presentations](https://www.bl.uk/blpac/dare.html?ref=lorcandempsey.net) are now available online, and University of Huddersfield archivist, Sarah Wickham, has written a [brief report](https://msarahwickham.wordpress.com/2010/09/06/dare-to-share-new-approaches-to-long-term-collections-management/?ref=lorcandempsey.net) of the day’s discussions.
A presentation by Deborah Shorley \[[PDF](https://www.bl.uk/blpac/pdf/dareshorley.pdf?ref=lorcandempsey.net)\] describes the UK Research Reserve: “UKRR is a HEFCE-sponsored scheme which helps UK university libraries dispose of their low use research journals, safe in the knowledge that one copy will be kept in BLDSC, with two backup copies in other UKRR libraries” (HEFCE – Higher Education Funding Council for England. BLDSC – British Library Document Supply Centre). The local reationale is raised to the national level: “We must manage our national research information infrastructure responsibly; Print material is becoming less important to researchers; UK universities urgently need more space to do their work; We can no longer cope with the ever-expanding collections in our university libraries”.
Each of these discussions notes the importance of data: to make sensible decisions you need to have good intelligence abot the collective collection of which individual libraries are part. Holdings and circulation data, especially, come to mind. This point is also raised in the very interesting presentation by Brian Clifford, which focuses on the management of books at Leeds University. \[[PDF](https://www.bl.uk/blpac/pdf/dareclifford.pdf?ref=lorcandempsey.net)\] He introduces an interesting collections typology, as a way of framing different dymanics at work across the collection:
> - Heritage: Significant & distinctive collections which continue to be developed
> - Legacy: Significant & distinctive collections: historic strengths but no longer added to
> - Self-renewing: Supporting current research & teaching
> - Finite: No longer relevant – can be considered for withdrawal
> \[[Heritage or legacy?](https://www.bl.uk/blpac/pdf/dareclifford.pdf?ref=lorcandempsey.net)\]
Brian goes on to discuss action at local, regional and national level if the library’s responsibility to their own users and to the scholarly print record are to be met.
As can be seen, the move to shared responsibility for print raises major service and policy issues, as well as very practical management issues.
An effective and efficient approach will depend on good intelligence in the form of aggregate data about collections (and Karen discusses OCLC in this context). Brian Clifford notes the balance between metrics and local knowledge in making judgements. Local knowledge will always be important, but it does seem that to scale across many institutions some shared decision criteria which can be operationalised through available data resources will be required.
### Information management on campus: CRIS, IR, CERIF, CRM, PIPAL
URL: https://www.lorcandempsey.net/information-management-on-campus-cris-ir-cerif-crm-pipal/
Last updated: 2020-10-28T09:08:24.000Z
One of the consequences of our network world is that more and more activities are ‘informationalized’: they generate data and the management of data is an important part of their operation.
We will increasingly see applications which want to mix information about researchers and publications with information about projects, organizations, and so on.
This prompts some interesting questions about the organizational context of information management on campus, and certainly provides the library with opportunities to reach out to new partners around information management issues. Current interactions probably depend on local personalities and politics, but one might expect new organizational forms to emerge over time as information management needs, repository and data infrastructure requirements, and the need to work across departmental silos become more apparent. A parallel development is the need to develop community standards for data which before was locally managed or not managed at all (CERIF, mentioned below, is an example).
Here are two areas at different stages of development which throw up some of these issues ….
An interesting example in recent years has been the management of information about campus research activity, particularly in countries where there is an emphasis on national assessments tied to funding. One sign of this has been the growth of ‘[research analytics](https://blog.oclc.org/lorcand/archives/002089.html?ref=lorcandempsey.net)‘. A related one is the emergence of a new service category, the [CRIS (Current Research Information System)](https://en.wikipedia.org/wiki/Current%5FResearch%5FInformation%5FSystem?ref=lorcandempsey.net), and several companies offer such services. There is a metadata standard – [CERIF](https://www.eurocris.org/cerif/cerif-releases/cerif-2008/?ref=lorcandempsey.net) – associated with this activity, which is managed by the [EuroCRIS](https://www.eurocris.org/public/about-eurocris/?ref=lorcandempsey.net) organization. CERIF covers data about entities of interest in the research process – persons, projects, institutions, and so on.
A related activity is the growing interest in ‘expertise’ or ‘reputation’ [systems](https://blog.oclc.org/lorcand/archives/002011.html?ref=lorcandempsey.net) which provide a managed framework for researcher interests, expertise, experience, and so on. The balance between internal personnel focus and an external focus may vary.
Of course, this prompts a natural question: what is the relationship between an institutional repository and a CRIS? There is an interesting [overview](https://eprints.ecs.soton.ac.uk/21048/?ref=lorcandempsey.net) from a technical perspective by [Les Carr](https://repositoryman.blogspot.com/?ref=lorcandempsey.net), a principal in the important [Eprints](https://www.eprints.org/?ref=lorcandempsey.net) research, advocacy and services initatiives at the University of Southampton.
Here is a discussion of repository initiatives at Trinity College Dublin which places repository development in the context of campus-wide research management issues. See slide 13 in particular for a schematic of institutional relationships.
**[Trinity College Dublin Tara DSpace Repository upgrade project presentation – Open Repositories 2010](https://www.slideshare.net/ghenrick/open-repositories-2010-tcd-tara-d-space-upgrade-presentation?ref=lorcandempsey.net "Trinity College Dublin Tara DSpace Repository upgrade project presentation - Open Repositories 2010")**
View more [presentations](https://www.slideshare.net/?ref=lorcandempsey.net) from [Gavin Henrick](https://www.slideshare.net/ghenrick?ref=lorcandempsey.net).
This interaction has been a particular interest of my colleagues working in the Research Information Management strand of our work and John MacColl has an informative report on the implications for libraries of the information management practices encouraged by research assessment regimes (see description and links [here](https://www.oclc.org/research/activities/practice/default.htm?ref=lorcandempsey.net)).
I only recently came across my second example of evolving information management practices. This one is much less well developed. Martin Hamilton, responsible for Internet Services at the University of Loughborough, pointed me at the [PIPAL study](https://jiscpipal.wordpress.com/?ref=lorcandempsey.net), which explores customer and partner relationship management issues and potential systems at the university. Now, of course, customer relationship management – CRM – is a well established business category with major industrial vendors providing on-site and cloud-based software and services. However, it is not so well developed in an academic setting. The [PIPAL report](https://jiscpipal.wordpress.com/executive-summary/?ref=lorcandempsey.net) is very clearly written and steps through issues nicely (noting that there is “a danger of alienating colleagues working in education through excessive use of business jargon”, for which reason they talk about ‘relationship management’ rather than ‘customer relationship management’). A key paragraph is as follows:
> This is the key to understanding Relationship Management – in order to understand and best exploit the relationships an organization has, it is necessary to create and then subsequently effectively curate a “database” of this information. In a traditional organization each unit would maintain its own independent database, with little or no information sharing – to the detriment of all those involved. \[[PIPaL](https://jiscpipal.wordpress.com/3-jisc-self-analysis-framework/102-2/?ref=lorcandempsey.net)\]
A University will manage relationships with organizations across the private sector, government, the not-for-profit sector, and other academic organizations. A variety of stakeholders – vice chancellor’s office, academics and academic departments, marketing, research office, enterprise office, hospitality, and so on – typically manage data about such relations. The report provides an interesting image of the systems providing data relevent to relationship management at Loughborough.

The report goes on to discuss existing relationships and workflows within the institution. It also has [a very interesting chapter](https://jiscpipal.wordpress.com/3-jisc-self-analysis-framework/3-7-technology-choices/?ref=lorcandempsey.net) on technologies, noting the potential of linked data in providing a ‘low-impact “University API”‘ to allow data to be recombined within and across institutions. Of course, one issue here is the absence of agreed vocabularies for many of the entities of potential interest.
The report is recommended as a gentle introduction to data issues around an emerging service area, and as an exploration of potential future directions. The discussion of linked data and identifiers reminds us of library discussions.
(Note: It occurs to me that the examples above are from institutions outside the US. In each case there is a convergence of local management interests and national organizing or supporting initiatives.)
### The network reconfigures library space ... mobile redux
URL: https://www.lorcandempsey.net/the-network-reconfigures-library-space-mobile-redux/
Last updated: 2022-11-08T15:14:33.000Z
So taken was I by William J Mitchell’s comments on the impact of the network and mobile communications on space that I have quoted it here a couple of times already 😉 Here it is …
> The fact that people are no longer tied to specific places for functions such as studying or learning, says Mr Mitchell, means that there is “a huge drop in demand for traditional, private, enclosed spaces” such as offices or classrooms, and simultaneously “a huge rise in demand for semi-public spaces that can be informally appropriated to ad-hoc workspaces”. This shift, he thinks, amounts to the biggest change in architecture in this century. In the 20th century architecture was about specialised structures–offices for working, cafeterias for eating, and so forth. This was necessary because workers needed to be near things such as landline phones, fax machines and filing cabinets, and because the economics of building materials favoured repetitive and simple structures, such as grid patterns for cubicles. \[[The new oases | Economist.com](https://www.economist.com/node/10950463?story%5Fid=10950463&ref=lorcandempsey.net) Behind a paywall\]
As we are more connected we are better able to ‘micro-coordinate’ our activities, postponing arrangements until they need to be made, conferring with others about what to do next or where to go up, arranging ad hoc rendezvous, checking on a detail or request. This is now routine, and as Mitchell suggests it can change the way in which we think about space. In fact when we talk about the social use of space, it is likely that such uses are also shaped by the network and mobile communications.
I have come across several examples of this recently ….
- Groupfinder is a service provided by NCSU libraries. It helps students ‘micro-coordinate’ their activities across several communications environments ..
> GroupFinder is a tool designed to help students let group members know where they are studying in the library. In a building with high use and uneven cellular service coverage, it is often difficult for students to locate a space to work in a group, and it is also challenging for groups to let latecomers know where they are working. GroupFinder is an attempt to solve these problems by providing a low-barrier method for students to broadcast their location in the building. Once an activity is posted to GroupFinder, it is displayed in a number of places:
> - The GroupFinder kiosk in the main lobby
> - The library’s e-board system
> - Any computer with an internet connection
> - The Libraries’ mobile site
> \[[Groupfinder](https://www.lib.ncsu.edu/dli/projects/groupfinder/?ref=lorcandempsey.net)\]
- The redevelopment of library space is aligned to the “huge rise in demand for semi-public spaces that can be informally appropriated to ad-hoc workspaces” that Mitchell notes. The Guardian recently discussed changing university architectures and the interaction between space and teaching and learning.
> “The most convincing new university buildings”, says Neary, “are those where students are given real responsibility for managing and supervising the spaces within which they learn, as well as acting as support for other students’ learning. The Learning Grid at the University of Warwick is the most developed form of this new kind of space.”
> Neary was at Warwick before Lincoln. Designed by the university library with architects MacCormac Jamieson Prichard, the Learning Grid is, according to its manager, Rachel Edwards, “a technology-rich, flexible and informal learning environment, open 24/7 with a capacity for 300 people”. Essentially, this is a fusion of a library and a common room. It allows disciplines to cross. It encourages students to help one another as well as themselves. It is generating fresh lines of research. “It’s been breaking down the gap between students and teachers,” says Neary, “with students becoming part of the academic project rather than consumers of dispensed knowledge.” \[[University architecture shapes up for a revolution](https://www.guardian.co.uk/education/2010/aug/31/university-architecture-revolution-students?ref=lorcandempsey.net)\]
- I noted Andy Walsh’s talk at Emtacl10 a while ago. I notice that he has [a selection of presentations and papers](https://eprints.hud.ac.uk/view/authors/Walsh=3AAndrew=3A=3A.html?ref=lorcandempsey.net) available in the University of Huddersfield repository. Together, they provide a nice overview of various ways in which library spaces and the network experiences of their users can be usefully tied together with QR Codes, mobile communications, and social network services.
### Blogging again
URL: https://www.lorcandempsey.net/blogging-again/
Last updated: 2020-10-28T09:08:32.000Z
Even if some heat has [gone out](https://blog.oclc.org/lorcand/archives/001989.html?ref=lorcandempsey.net) of the library blogosphere, there is still a fair amount of reading and writing going on. I was asked recently what I tended to look at, going beyond the well-known bigger names. Here are some of the blogs that came to mind – some others also come to mind, but they don’t sustain the reasonable amount of output that these do.
[Go to Hellman](https://go-to-hellman.blogspot.com/?ref=lorcandempsey.net) [Personanondata](https://personanondata.blogspot.com/?ref=lorcandempsey.net) [eFoundations](https://efoundations.typepad.com/?ref=lorcandempsey.net) [The Book of Trogool](https://scientopia.org/blogs/bookoftrogool/?ref=lorcandempsey.net) [Overdue ideas](https://www.meanboyfriend.com/overdue%5Fideas/?ref=lorcandempsey.net) [Synthesize, specialize, mobilize](https://synthesize-specialize-mobilize.blogspot.com/?ref=lorcandempsey.net) [Martin Hamilton’s Blog](https://blog.martinh.net/?ref=lorcandempsey.net) [HangingTogether](https://hangingtogether.org/?ref=lorcandempsey.net) [Bibliographic wilderness](https://bibwild.wordpress.com/?ref=lorcandempsey.net) [The Arcadia Project blog](https://arcadiaproject.blogspot.com/?ref=lorcandempsey.net)
Many of these are written from within a library perspective. Some dip into libraries from other perspectives. Personanondata, by Michael Cairns, covers the book industry more generally. Martin Hamilton, who is responsible for Internet Services in the IT services division at Loughborough University, is a recent blogger with a nicely reflective style. My former colleague Eric Hellman pulls together his science, business and technical experiences to provide some of the most interesting commentary on our changing environment. And Andy Powell and Pete Johnston at eFoundations combine technical pieces about metadata with more general discussion of education/information in a networked environment.
And then there’s ……
### A web-sighting: NCSU Libraries redux
URL: https://www.lorcandempsey.net/a-web-siting-ncsu-libraries-redux/
Last updated: 2023-07-04T01:24:49.000Z
Susan Rector from NCSU Libraries left a nice note on my [entry about library websites](https://news.lib.ncsu.edu/redesign?ref=lorcandempsey.net). She pointed at some [discussion](https://news.lib.ncsu.edu/redesign?ref=lorcandempsey.net) of the redesign on their libraries blog. I was particularly interested to read about their objectives with the new site:
- Streamline access to search functions and core user tasks
- Provide ways to contact librarians throughout the user experience
- Highlight core tools and provide paths to top tasks
- Promote the library through news & events messaging
- Promote new innovations in library technology and learning spaces
\[[Give us your feedback](https://news.lib.ncsu.edu/redesign/2010/07/15/give-us-your-feedback-2/?ref=lorcandempsey.net)\]
A nice list. I was interested that I had picked up on various of these things in my [few remarks](https://blog.oclc.org/lorcand/archives/002129.html?ref=lorcandempsey.net). This is more a sign that they have achieved quite a bit of what they wanted to than it is that I was being very perceptive 😉 I was particularly interested in the equal focus across all the elements of the library: the collections, the space, the services and the staff. Sometimes there is a tendency to be collections focused.
Somebody asked me why I used the expression ‘demand-influenced’ rather than something perhaps more immediately digestible like ‘user centered’. Several reasons. The first is that since talking about ‘[Sorting out demand](https://blog.oclc.org/lorcand/archives/002124.html?ref=lorcandempsey.net)‘ at the Lita Top Tech Trends event the balance between ‘sorting out supply’ and ‘sorting out demand’ has been on my mind, and seems like an important distinction. The second is that we tend to use ‘user’ rather lightly and assume that everything is done in service of the user. And the third is that ‘demand’ suggests something a little more dynamic, and measurable, than ‘user’. To me, anyway.
### 3 stages of library websites
URL: https://www.lorcandempsey.net/3-stages-of-library-websites/
Last updated: 2022-12-07T02:47:08.000Z
While writing about [subject pages and library websites](https://blog.oclc.org/lorcand/archives/002128.html?ref=lorcandempsey.net) the other day, it occurred to me that we might think of library websites in three stages – which emerged successively and continue to exist together. Always mindful of the [rule of three](https://en.wikipedia.org/wiki/Rule%5Fof%5Fthree%5F%28writing%29?ref=lorcandempsey.net) 😉
We might clumsily call these stages: \[1\] fragmentary, \[2\] integrated supply, and \[3\] demand-influenced.
**Fragmentary.** Libraries have to manage a variety of resources which are outside their control and present them to their users as best they can. This has meant that the library website has often been a thin wrapper around two sets of heterogeneous resources.
> One is the set of legacy and emerging systems, developed independently rather than as part of an overall library experience, with different fulfillment options, different metadata models, and so on (integrated library system, resolver, knowledge base, repositories, …). Another is the set of legacy database and repository boundaries that map more to historically evolved publisher configurations and business decisions than to user needs or behaviors (for example, metadata, e-Journals, eBooks, books, A&I databases, and other types of content, which may be difficult to slice and dice in useful ways). \[[Lorcan Dempsey’s Weblog – Stitching costs](https://blog.oclc.org/lorcand/archives/001785.html?ref=lorcandempsey.net)\]
**Integrated supply**. Recently, libraries have been focusing on the website in a more holistic way, as a unified service. There are several developments which have supported this. One is the move to the single, or tabbed, search box as a focal point of the website. This may sit over a metasearch product, or, more recently, over a [discovery layer](https://blog.oclc.org/lorcand/archives/002116.html?ref=lorcandempsey.net) product. Another is the adoption of a consistent content management framework which gives a similar look and feel across the website, extending to linked services (the catalog for example) where possible (I was interested to note that [SOPAC](https://thesocialopac.net/about?ref=lorcandempsey.net) and [Ting](https://blog.oclc.org/lorcand/archives/002065.html?ref=lorcandempsey.net) both advertise the integration between the catalog and the rest of the website). Others include the integration of staff interaction capabilities (making relevent staff [visible](https://blog.oclc.org/lorcand/archives/001873.html?ref=lorcandempsey.net) in appropriate places, including various ways of contacting staff or asking questions, …), and a [consistent approach](https://blog.oclc.org/lorcand/archives/002128.html?ref=lorcandempsey.net) to developing subject or course pages. I discussed some examples of unified service provision [in this post](https://blog.oclc.org/lorcand/archives/002007.html?ref=lorcandempsey.net) a while ago.
Given the fragmentation they face it is easy for libraries to see integration – the consolidation of supply – as an end in itself. However the real end is less the integration of information resources *with each other* than the integration of relevant information resources *with the working patterns of their users*. For this reason, we will begin to see more emphasis on sorting out demand as well as sorting out supply.
**Demand influenced.** I [gave some examples recently](https://blog.oclc.org/lorcand/archives/002124.html?ref=lorcandempsey.net) of how sorting out demand is becoming more important. This of course touches on core library values, connecting users to appropriate resources in convenient ways. A specific example might be the [Bookspace](https://www.hclib.org/pub/bookspace/?ref=lorcandempsey.net) section of the Hennepin County Library website.
Looking at the [North Carolina State University Libraries website](https://www.lib.ncsu.edu/?ref=lorcandempsey.net) the other day it also seemed to me that it provided a nice example of a site trying better to predict, meet and guide demand. As well as continuing to integrate the various sources of information supply. Here are a few things that occurred to me. As always, it is sensible to note that my impressions are those of an interested tourist rather than somebody who regularly uses the site ….
- **Legible.** The tabbed search box is centrally visible. Underneath this are three labels: Computing, Learning, and Courses. The first and second provide access to computing resources and learning spaces, respectively. The third provides information resources specialised to individual courses. The site is not cluttered with uncontextualised information resources, library administrivia, or brochureware.
- **Relation of virtual to physical.** This is an interesting emphasis. It is possible to book a room, to borrow computing equipment, to find out how many computers are in use. There is a service, [Groupfinder](https://www.lib.ncsu.edu/groupfinder/?ref=lorcandempsey.net), which allows you to alert others to your physical location in the library. Another is called, nicely, [Tripsaver](https://www.lib.ncsu.edu/tripsaver/?ref=lorcandempsey.net), and offers requesting/delivery options while allowing you to check status of request. There is a clock icon which links to a page of library opening times. A calendar of events is also published.
- **Library staff and expertise are very visible and users are encouraged to make contact.** Get Help and Ask Us links are visible at the top of the page. Alongside ‘help’ there is a link to an ‘expert’ in your area of study. Chat options are very visible. And users can offer Feedback on the site in general. Help with creating digital media is offered. There are links to the relevant library experts on course and resource pages.
- **The website is not the only destination.** There is a row of familiar icons at the foot of the page: Twitter, Facebook, RSS, YouTube, and Flickr. And there is a stream of news and tweets on the page. Of course, NCSU has also been a leader in mobile apps and there are several available.
### Resource/course guides and content management
URL: https://www.lorcandempsey.net/resource-course-guides-and-content-management/
Last updated: 2020-10-28T09:08:46.000Z
I have mentioned [Libguides](https://springshare.com/libguides/?ref=lorcandempsey.net) a couple of times, which seem to be quite widely used. I have been interested recently to come across some other initiatives which aim to organize subject- or course-based library resources within a consistent content management environment which reduces custom effort.
- I enjoyed listening to [Allie Flanary](https://www.pcc.edu/library/contact/profiles/allie%5Fflanary.html?ref=lorcandempsey.net) present about students and search strategies at the [Orbis Cascade Alliance Worldcat Discovery Day](https://www.orbiscascade.org/index/program?ref=lorcandempsey.net). Allie works at the Portland Community College, where the event was held. The course guides she was using caught my eye and I went back later to see how they were put together. Here is the one for [Fashion design](https://alacarte.pcc.edu/subject-guide/3-Fashion-Design?ref=lorcandempsey.net), for example. I discovered that they use [Library à la Carte](https://alacarte.library.oregonstate.edu/?ref=lorcandempsey.net), developed at Oregon State University:
> The Library à la Carte Content Management System (CMS) enables librarians to easily and quickly create dynamic web pages that integrate Web 2.0 features, such as chat and RSS feeds, with traditional library content, such as catalogs and article databases. Library à la Carte is a free open-source solution for libraries by libraries.
- A redesign of the [NCSU Library website](https://www.lib.ncsu.edu/?ref=lorcandempsey.net) highlights course-related services. Among these are course pages (see one below) which include some general resources, some course-specific resources, and a link to a librarian. I was interested to discover that these were based on a home-grown framework, *Course Views*, which is described in an [article](https://journal.code4lib.org/articles/1218?ref=lorcandempsey.net) in the Code4Lib Journal:
> The NCSU Libraries’ Course Views project, along with a locally developed widget web service, improves course-based access to library collections and services by dynamically generating library course pages for all 6000+ courses at NCSU. By automatically generating custom content when possible and showcasing authored content when available, Course Views is able to achieve full course coverage without significantly increasing staff time to create and manage content. This paper will describe the system and the use of web services to achieve scalable and sustainable delivery of course-related library content.
- I have [noted in these pages](https://blog.oclc.org/lorcand/archives/002007.html?ref=lorcandempsey.net) that I think that The [University of Michigan Libraries](https://www.lib.umich.edu/?ref=lorcandempsey.net) website does a nice job of projecting the library as a unified service rather than as a group of disjoint opportunities. In the search and browse sections they return a variety of resources organized by type as well as links to relevant librarians (as I said then, they try, literally, to put a ‘human face’ on search results). Here is the browse page for [Biological chemistry](https://www.lib.umich.edu/browse/Biological%20Chemistry?ref=lorcandempsey.net) for example. Now, there appears to be quite a lot going on under the surface here, and Ken Varnum provides a [high level view](https://mblog.lib.umich.edu/blt/archives/2009/08/the%5Fnew%5Funivers.html?ref=lorcandempsey.net) of design decisions. Interestingly, these pages include Research Guides as one category, which are based on Libguides; here is the guide for [Biological Chemistry](https://guides.lib.umich.edu/content.php?pid=27961&ref=lorcandempsey.net) for example.
[](https://www.lib.ncsu.edu/course/ENG/372?ref=lorcandempsey.net)
### QOTD: Information environments ...
URL: https://www.lorcandempsey.net/qotd-information-environments/
Last updated: 2020-10-28T09:08:49.000Z
‘Information environment’ is a vague term, vague enough to be usable in a variety of contexts. For me, as I worked for JISC before coming to OCLC, it will always be associated with the JISC [agenda](https://www.informationenvironments.org.uk/about.html?ref=lorcandempsey.net) to advance an integrated network of information resources in support of UK research and learning.
I was very interested to come across the [Information Environment Research Unit](https://www.informationenvironments.org.uk/mission-statement.html?ref=lorcandempsey.net) at the London University of the Arts earlier. The description of its scope is tantalisingly suggestive …
> The Research Unit for Information Environments proposes to be at the forefront of research about and for the information industry. ‘Information Environments’ are defined as any physical or virtual spaces where information is generated, received and experienced. The Unit is particularly interested in spaces which are populated by communities such as those found in common areas of urban spaces, museums, the Internet and learning environments, and where the exchange of ideas. Concepts and knowledge is communicated.
This is potentially very broad but it is interesting to see mention of museums and learning environments (although I didn’t see the library explicitly discussed). They suggest that this marks a new field of enquiry. Unfortunately, the Unit does not make a lot of published material available on the website and I have not yet tracked it down elsewhere. Certainly something to keep an eye on though.
### Curating the web ...
URL: https://www.lorcandempsey.net/curating-the-web/
Last updated: 2020-10-28T09:08:51.000Z
A couple of recent events interestingly relate …
First, I read in [Search Engine Land](https://searchengineland.com/srinija-srinivasan-leaves-yahoo-47997?ref=lorcandempsey.net) of the resignation from Yahoo of Srinija Srinivasan. Srinavasan was once arguably “the most powerful person in search” writes Danny Sullivan. This was when “humans edited the web” and Yahoo emerged as its central directory. Srinivasan oversaw this activity. Sullivan writes that Yahoo was better than the ‘automatic’ or ‘crawler-based’ search engines of the time such as Excite or Alta Vista: “Yahoo, in contrast, wasn’t about the sheer volume of content. It was about listing the best of the web.”
The ‘best of the web’ is an interesting phrase as it was also used by another set of services which emerged at around the same time in another part of the galaxy. These were the so-called subject gateways developed within UK higher education And they were one of many examples of humans editing the web that emerged in the academic and library communities (think of Internet Scout, CORC, BUBL, NISS Gateway, Internet Public Library, LII, and others).
The [original subject gateways](https://www.ariadne.ac.uk/issue25/subject-gateways/?ref=lorcandempsey.net) were funded in parallel with early JISC funding of electronic library developments; they came together as the [Resource Discovery Network](https://www.intute.ac.uk/publications/ior-2000-02-dempsey/?ref=lorcandempsey.net), which morphed into [Intute](https://www.intute.ac.uk/?ref=lorcandempsey.net). These projects went beyond ‘pointing’ to creating metadata for selected websites.
The connection between these is that the second event I am thinking of is the [announcement](https://www.intute.ac.uk/blog/2009/12/16/jisc-announces-intute-funding-cut/?ref=lorcandempsey.net) by JISC that the funding for Intute was being cut. This marks the end of an era, as an [article](https://www.ariadne.ac.uk/issue64/joyce-et-al/?ref=lorcandempsey.net) in the current issue of Ariadne notes.
Of course, what changed along the way was the emergence of Google and the pagerank algorithm. This was a service also based on choice, not in this case the editorial choice of compilers, but the aggregate choices made in linking behaviors.
If Yahoo, or the subject gateways which were the basis of Intute, were to be set up today, they would probably talk about ‘[curating](https://blog.oclc.org/lorcand/archives/002119.html?ref=lorcandempsey.net)‘ the web. In an era of abundance, curation is seen to have new value, although its venue is now blogs, social networks, personal collection sites, and so on. So it is interesting seeing the authors of the Ariadne article wonder if [community curation](https://www.ariadne.ac.uk/issue64/joyce-et-al/?ref=lorcandempsey.net) represents a future for Intute.
### QR Codes and exhibitions
URL: https://www.lorcandempsey.net/qr-codes-and-exhibitions/
Last updated: 2020-10-28T09:08:53.000Z
We spend some time in the very congenial [Dayton Art Institute](https://www.daytonartinstitute.org/?ref=lorcandempsey.net) this afternoon. We wandered around the [Modern Masters](https://www.daytonartinstitute.org/exhibits/2010modernmasters.html?ref=lorcandempsey.net) exhibition (from the Smithsonian American Art Museum). I was interested to see the QR codes by the pictures. Here is a somewhat fuzzy picture taken by my son on his phone:
[](/lorcand/lorcan/assets%5Fc/2010/08/daytonqr-107.html)
Now, the exhibition is an obvious place to exploit QR codes – to connect what you can see to commentary, to related work, to further information and so on. In this case, you could link to a spoken commentary on the work by local artists, or to other works in the Dayton collections by the same artist. I thought that the use of the codes in this way to tie a touring exhibition into local context was quite nice.
I didn’t immediately see a copy of a code for further information about the exhibition on the website.
I have been peripherally aware of a discussion of QR codes [in this context](https://www.google.com/search?rlz=1C1GGLS%5FenUS291US304&sourceid=chrome&ie=UTF-8&q=qr+codes+exhibitions&ref=lorcandempsey.net). And I have been watching out for various uses in our space again since hearing the very nice presentation by Andy Walsh at [Emtacl10](https://www.ariadne.ac.uk/issue64/emtacl10-rpt/?ref=lorcandempsey.net). As I [previously reported](https://blog.oclc.org/lorcand/archives/002087.html?ref=lorcandempsey.net), he noted that as library spaces became places for social activity, their specifically informational dimension was waning. And that this was a pity, and in the long term probably not very helpful for the library. He suggested that QR codes (and RFID tags) were one way of reconnecting those places to an informational dimension, and gave examples of how codes and tags could be used to link library places to information resources and services.
In this case I was interested that my (12 year old) son was very interested in the codes and scanned a couple. A small extra hook 😉
### Sorting out demand ... Top tech trend 3
URL: https://www.lorcandempsey.net/sorting-out-demand-top-tech-trend-3/
Last updated: 2020-10-28T09:08:55.000Z
\[This is 3\. Here is [1](https://blog.oclc.org/lorcand/archives/002115.html?ref=lorcandempsey.net) and [2](https://blog.oclc.org/lorcand/archives/002116.html?ref=lorcandempsey.net).\]
I was pleased to participate in LITA’s Top Tech Trends panel at ALA this year (see the [video](https://litablog.org/2010/06/video-top-tech-trends-washington-dc-annual-2010/?ref=lorcandempsey.net) and [live coverage](https://litablog.org/2010/06/top-tech-trends-liveblog-2/?ref=lorcandempsey.net)).
We were each asked to talk about three trends: current, a bit further out, and a bit further out again. In thinking about the exercise, it seemed to me that it would be interesting to talk about how services are being reconfigured in a network environment, and not just focus on technology as such. We had three minutes in which to discuss each trend.
My third trend was somewhat diffuse and was inspired by a remark I read a couple of years ago by Gavin Potter, a contestant in the competition NetFlix ran to improve its algorithm.
> “The 20th century was about sorting out supply,” Potter says. “The 21st is going to be about sorting out demand.” The Internet makes everything available, but mere availability is meaningless if the products remain unknown to potential buyers. \[[This Psychologist Might Outsmart the Math Brains Competing for the Netflix Prize](https://www.wired.com/techbiz/media/magazine/16-03/mf%5Fnetflix?currentPage=1&ref=lorcandempsey.net)\]
Libraries spend a lot of time sorting out supply. The fragmentation of supply (across suppliers, databases, formats, business models, etc) has meant that we have created quite a complex staff, systems and service environment to cope. Furthermore, this has evolved piecemeal to manage evolving patterns of provision. There are separate workflows and supply industries for bought materials (think the integrated library system and catalog), for licensed materials (think knowledge base, a to z lists, metasearch, ERM), and for digital materials (think repository infrastructure). What is more this infrastructure is institution-scale – it is repeated in each library. There is significant workflow and systems redundancy across libraries. At the same time, large buildings have also been required to support this supply, as the model has perforce been to assemble materials close to the user.
This focus on supply has been because the transaction costs – in time, effort or money – for a university, or a student or faculty member, or a member of the public, of interacting with the range of information sources is quite high, and a major role of the library is to reduce those costs by integrating the sources of supply and bringing them close to the user.
However the transaction costs for the user have come down. Google has been a major part of this. But so has the general consolidation in a network environment: Amazon, Google Books, the discovery layers I mentioned as my [second trend](https://blog.oclc.org/lorcand/archives/002116.html?ref=lorcandempsey.net), Worldcat, and so on.
As supply consolidates, attention shifts to sorting out demand. Of course, libraries have always worked here, but not as much as they might have. What might this mean in our increasingly digital environment? Here are some overlapping examples:
- Ranking, relating, recommending. We are used to systems which provide hints and hooks for us, which guide us through large collections, which make suggestions. We get alerts, reminders, recommendations. Often, sites will mobilize four sources of metadata (professional, contributed, automatic, and usage) to build such functions into their services. \[A related blog entry: [Recommendation and Ranganathan – retread](https://blog.oclc.org/lorcand/archives/002123.html?ref=lorcandempsey.net)\]
- Community is the new content. We expect services not only to know about resources on the web, but also to know about us. We are seeing services contextualised by their knowledge of people using those services and their relationships. Sites create value by facilitating the creation of community around ‘social objects’ (think of reading sites, Mendeley, BlipFoto, …). \[A related blog entry: [the context web](https://blog.oclc.org/lorcand/archives/002063.html?ref=lorcandempsey.net)\]
- Connective services. People encounter bibliographic resources in various research and learning contexts: reading lists, citation managers, personal collections, reading clubs, bibliographies, and so on. The connective tissue between these tools and library resources could be better. \[A related blog entry: [Reading lists, citation management and bibliographic tissue](https://blog.oclc.org/lorcand/archives/002092.html?ref=lorcandempsey.net)\]
- Indirect discovery. Users find materials in Amazon, in Google, in Google Scholar, in Google Book Search, and so on. How do we make connections between those services and the library? \[A related blog entry: [Indirect discovery](https://blog.oclc.org/lorcand/archives/002105.html?ref=lorcandempsey.net).\]
- Embedding in other environments. It may be appropriate to tailor materials for the course management system, for the course resource pages, for reading lists and so on. I was in Trinity College Dublin recently, where colleagues were talking about their work to adapt the Microsoft Research Information Centre framework for use by groups of humanities scholars (see the poster presented at LIBER here – [PDF](https://www.statsbiblioteket.dk/liber2010/presentations/posters/Arlene%5FHealy.pdf?ref=lorcandempsey.net)). A part of the project is to build connectors to the bibliographic resources of the library. Colleagues reported that researchers preferred interacting with selective resources in this custom environment than going to the general-purpose library pages.
- Institutional assets. Finally, one might note a major emerging area of engagement: consultation, curation, and other services around the institutional research and learning outputs that are becoming central to a wider range of activity. This is of course a big topic in itself.
I concluded my remarks by remembering one of my favorite accounts of the mission of the librarian, which seems increasingly apt as time passes. It is from Dan Chudnov and it is “[help people build their own libraries](https://onebiglibrary.net/story/because-this-is-the-business-weve-chosen?ref=lorcandempsey.net)“.
### Recommendation and Ranganathan - retread
URL: https://www.lorcandempsey.net/recommendation-and-ranganathan-retread/
Last updated: 2020-10-28T09:08:57.000Z
\[I have been quoting the distinction made by Gavin Potter, a participant in the Netflix competition, about how our emphasis is shifting from sorting out supply to sorting out demand. I thought it might be useful to re-present this entry, the one where I first noted the distinction. I could have deleted the first half, about the ‘four sources’ of metadata, but I kept it in as building services using contributed data and usage data is one of the ways in which we can begin to ‘sort out demand’.\]
From time to time, we see a discussion about the relative merits of Google, or Amazon, and library catalogs as retrieval or search engines. There is one main difference that doesn’t tend to get discussed much, and that has to do with the type of data that gets factored into the experience. Increasingly, we are seeing major web presences incorporate usage data and contributed data to extend the range of suggestions they can make to users.
In these pages I have [suggested](https://blog.oclc.org/lorcand/archives/001351.html?ref=lorcandempsey.net) that we have four sources of metadata about things. Here is a short version:
1. Professional: The curatorial professions have made major investments in knowledge organization, through the development and application of cataloging rules, controlled vocabularies, authorities, gazetteers, and so on.
2. Contributed: A major phenomenon of recent years has been the emergence of many sites which invite, aggregate and mine data contributed by users, and mobilize that data to rank, recommend and relate resources. This data includes tags, reviews, ratings, further details, and so on.
3. Programmatically promoted: We are handling more digital materials, where it is possible to programmatically identify and promote metadata from resources themselves or groups of resources. We will also do more to mine collections, including collections of metadata, to discern pattern and relations. We are increasingly familiar with clustering, entity identification, automatic classification and other approaches.
4. Intentional: I have used this term to refer to the data that we are collecting about use and usage. Pagerank is based on aggregate linking choices. Amazon recommendations are based on aggregate purchase choices.
Now, typically library catalogs use traditional information retrieval techniques over professionally produced metadata. This is not a lot of data to play with! We have just begun to see interesting things being done with the other types of data as libraries explore the use of transactional data for recommendations and look to incorporate contributed data.
Google, Amazon and other sites license professionally produced metadata. But in different ways they also use the other types of data also. So, for example, intentional data, in the form of linking patterns, is central to how Google ranks material. Google Books makes extensive use of programmatically promoted data: look at how it extracts place names and places them on a map for example. This is imperfect, but useful. Amazon makes extensive use of contributed metadata, in the form, for example, of ratings, tags or reviews. Amazon also makes interesting use of intentional data, as in its recommendation engine. It has an especially nice feature, where it shows you what people who looked at a page eventually bought. Amazon builds up a ‘rich texture of suggestion’ based on several of these types of data.
Suggestion, or recommendation, is becoming increasingly a part of our everyday web experience,and improving the quality of suggestion has become an important goal for many services. Clearly, there are commercial interests riding on this.
One interesting signal of this is the [Netflix Prize](https://www.netflixprize.com/?ref=lorcandempsey.net), a million dollars being offered by Netflix to the first entrant who can improve their recommendation engine by 10%.
A recent Wired article about the Prize talked to Jim Bennett, the VP for recommender systems. He talks about the impact of small changes in the RMSE, a measure of the typical amount a prediction misses by:
> How much difference could that possibly make? A lot, Bennett says. Netflix offers hundreds of millions of predictions a day, so a tiny reduction in the frequency of insultingly stupid movie suggestions means a lot fewer angry users. \[[This Psychologist Might Outsmart the Math Brains Competing for the Netflix Prize](https://www.wired.com/techbiz/media/magazine/16-03/mf%5Fnetflix?currentPage=2&ref=lorcandempsey.net)\]
> Over the last few years, the RMSE of Cinematch has steadily improved, as has Netflix’s success at retaining customers from month to month. Bennett can’t prove the two are related, but he’s willing to bet on his belief that they are. He refuses to speculate on the dollar value of a 10 percent improvement to Cinematch, but he’s certain it’s substantially more than $1 million. \[[This Psychologist Might Outsmart the Math Brains Competing for the Netflix Prize](https://www.wired.com/techbiz/media/magazine/16-03/mf%5Fnetflix?currentPage=2&ref=lorcandempsey.net)\]
The focus of the article is the work of ‘[just a guy in a garage](https://justaguyinagarage.blogspot.com/?ref=lorcandempsey.net)‘, Gavin Potter, and his work on taking human factors into account (for example, you might want to weigh newer ratings more heavily than older ones).
Potter echoes a theme of current discussions:
> “The 20th century was about sorting out supply,” Potter says. “The 21st is going to be about sorting out demand.” The Internet makes everything available, but mere availability is meaningless if the products remain unknown to potential buyers. \[[This Psychologist Might Outsmart the Math Brains Competing for the Netflix Prize](https://www.wired.com/techbiz/media/magazine/16-03/mf%5Fnetflix?currentPage=1&ref=lorcandempsey.net)\]
This is similar to ‘consumption management’ as discussed by Bjørn Olstad, for example.
> He talks about a move from *content management* to *consumption management*. And taking the example of Yellow Pages talks about a move from a provider view (a few details in a listing, shallow understanding) to a consumer view (recommendations, maps, directions, comparisons: a broader experience leading to a deeper understanding). This is achieved through data mining and looking across a range of resources produced by divers hands. \[[Lorcan Dempsey’s weblog: Search is more than search](https://blog.oclc.org/lorcand/archives/001120.html?ref=lorcandempsey.net)\]
I was reminded of this discussion by an article by Michael Schrage in the current issue of Technology Review about the “low, seductive whisper of automated suggestion”. He mentions the Netflix Prize and discusses the limitations and promise of recommender systems, focusing on Amazon and iTunes.
> The focus of digital personalization has shifted from what I am interested in now to what I might be interested in next. All the choices I make in the moment are absorbed into a sphere of suggestion where, after they have been statistically weighted, they are reborn as offers and advice. \[[Technology Review: Recommendation Nation](https://www.technologyreview.com/Infotech/20591/?ref=lorcandempsey.net)\]
And he concludes with the following:
> When I get good recommendations, I spend my time and money differently. Even better recommendations will dramatically increase the value of that time and money. That’s a digital future I crave and expect. I hope Internet innovators take my recommendations as seriously as I take theirs. \[[Technology Review: Recommendation Nation](https://www.technologyreview.com/Infotech/20591/page3/?ref=lorcandempsey.net)\]
I like this emphasis on the value of time. It calls to mind Ranganathan’s injunction to save the time of the user. And although expressions like ‘consumption management’ or ‘sorting out demand’ may not be uppermost in our minds, it seems to me that they are very much in the spirit of the double injunction “every book its reader” and “every reader his or her book”. As resources become more abundant and as time becomes scarcer we need better and better ways of making this match. And this includes finding better ways of aggregating and using **intentional** and **contributed** metadata alongside our professionally produced metadata.
\[Originally posted: [May 13, 2008](https://blog.oclc.org/lorcand/archives/002123.html?ref=lorcandempsey.net)\]
Related entries:
- [Four sources of metadata about things](https://blog.oclc.org/lorcand/archives/001351.html?ref=lorcandempsey.net)
- [The simple search box and the rich texture of suggestion](https://blog.oclc.org/lorcand/archives/000966.html?ref=lorcandempsey.net)
- [Lorcan Dempsey’s weblog: Search is more than search](https://blog.oclc.org/lorcand/archives/001120.html?ref=lorcandempsey.net)
### QOTD: ways of seeing: a cover
URL: https://www.lorcandempsey.net/qotd-ways-of-seeing-a-cover/
Last updated: 2021-04-03T05:10:33.000Z
In an interesting blog post on the changing nature of the book cover in a digital environment, James Bridle compares the covers of the much-discussed [Odyssey Editions](https://www.odysseyeditions.com/?ref=lorcandempsey.net) with the famous *Ways of Seeing* cover.
> The covers are typographic, and hark back in particular to the famous Pelican cover for John Berger’s Ways of Seeing, where the text starts on the front cover.
Now, I [mentioned](https://blog.oclc.org/lorcand/archives/002120.html?ref=lorcandempsey.net) the other day that I had been in various book shops in Ireland and England the other week. I brought home with me *[Penguin by design: a cover story 1935 – 2005](https://www.worldcat.org/title/penguin-by-design-a-cover-story-1935-2005/oclc/57692203&referer=brief%5Fresults?ref=lorcandempsey.net)* by Phil Baines, bought in the British Library book [shop](https://shop.bl.uk/?ref=lorcandempsey.net).
There I was interested to read the following about *Ways of Seeing* by Hans Schmoller, one of the key figures in the development of Penguin design (no source is given for the remarks).
> The book’s design was particularly disliked by Hans Schmoller. ‘Is this meant to be centred?’ was written angrily across cover proofs returned to the designer, and when the printed book was placed on his desk he promptly hurled it down the corridor in disgust.
### Navigation structure: web sitings ...
URL: https://www.lorcandempsey.net/navigation-structure-web-sitings/
Last updated: 2020-10-28T09:09:01.000Z
The following graphic was noted in a variety of places recently. It clearly struck a chord!
[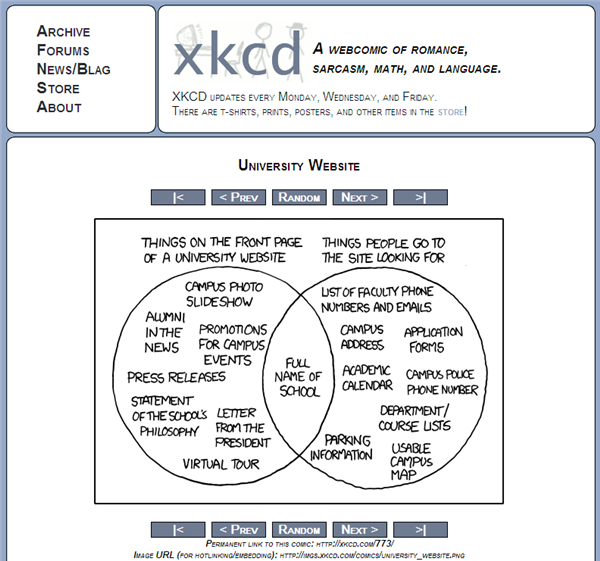](https://xkcd.com/773/?ref=lorcandempsey.net)
My own bugbear on library websites is physical address (I sometimes want to know where the library is) and director or staff contacts (which are sometimes really quite hard to find!).
This reminded me of a couple of websites which try to address this issue. In each case, the site is using ‘[intentional](https://blog.oclc.org/lorcand/archives/000822.html?ref=lorcandempsey.net)‘ or usage data to try and save the time of website users.
I like the cloud of menu items under the tabs on the home page of our neighbors, Ohio State University. I have clicked the *faculty/staff* tab. I was interested to see the link to parking permits!
[](https://www.osu.edu/?ref=lorcandempsey.net)
The other is the creation of a cloud of tags based on Delicious bookmarks on pages on the University of Southampton. This is an interesting idea, although looking at the Delicious pages it appears that it may have been too far ahead of actual practice?
[](https://www.soton.ac.uk/postgraduate/index.shtml?ref=lorcandempsey.net)
### Bookstores, curation and managing demand/consumption ...
URL: https://www.lorcandempsey.net/bookstores-curation-and-managing-demand-consumption/
Last updated: 2020-10-28T09:09:06.000Z
I have just returned to the US from a couple of weeks vacation in Ireland and England. I was more than usually struck by my bookstore (aka book shop) experiences, and this prompted the [curation entry](https://blog.oclc.org/lorcand/archives/002119.html?ref=lorcandempsey.net) I have just written.
First of all, an interesting note that I have [quoted before](https://blog.oclc.org/lorcand/archives/001566.html?ref=lorcandempsey.net) about the management of supply and demand. Gavin Potter was a competitor in the competition to improve the Netflix recommendation algorithm. He was interviewed by *Wired Magazine*:
> “The 20th century was about sorting out supply,” Potter says. “The 21st is going to be about sorting out demand.” The Internet makes everything available, but mere availability is meaningless if the products remain unknown to potential buyers. \[[This Psychologist Might Outsmart the Math Brains Competing for the Netflix Prize](https://www.wired.com/techbiz/media/magazine/16-03/mf%5Fnetflix?currentPage=1&ref=lorcandempsey.net)\]
In the physical world, sorting out supply meant providing large aggregations of materials local to potential customers/users. For many, this function has shifted to the network where Amazon and others can provide large aggregations, improved by ranking, relating and recommending based on usage data. This suggests that a role for the physical retailer may shift from managing supply to managing demand or consumption, seeking to identify and meet particular needs. Here are some examples. I should note that my remarks are those of a consumer – I certainly don’t have an internal perspective of the book retail business!
- [Herne Hill Books](https://www.hernehillbooks.com/?ref=lorcandempsey.net) is the smallest book shop I have been in! Put several people in it and it is crowded. It is in a plot of cafes and other shops beside the busy Herne Hill train station in South East London. I did not see its bigger sibling, [Clapham Books](https://www.claphambooks.com/Home.aspx?ref=lorcandempsey.net). Like other small independent shops, it has stuff covered in the reviews, some materials of local interest, some stuff reflecting the manager’s view of what might be of interest, and Scandinavian crime fiction. Here is an [appreciative](https://jacketsoff.co.uk/2010/01/22/herne-hill-books/?ref=lorcandempsey.net) note about it which points to its art, photography, travel and cookery books. It caters for the gift buyer, the impulse buyer, and in this case it is well placed to cater for the traveller. And stocks some tasteful cards or other small items. Similar, if bigger, was the [Rathgar Bookshop](https://www.therathgarbookshop.ie/?ref=lorcandempsey.net) in Dublin, which had a range of gardening books in the mix. Such shops are likely to survive based on the strength of their curation, providing enough of distinctive interest alongside a selection of more general materials to draw in customers. (And in looking at them I am reminded of a [comment](https://blog.oclc.org/lorcand/archives/000627.html?ref=lorcandempsey.net) from a while ago about the curation skills of public librarians, which I adapt slightly here: Books live in the lives of their readers. Readers also live in the lives of their books. And, in the libraries that he is talking about, I always thought that the mark of very good library staff was that they understood their collection based on the readers in the lives of its books, but also understood their readers based on the books in their lives.)
- We spent some time in Royal Festival Hall branch of Foyle’s. Larger than the shops above, it much smaller than the Charing Cross branch (which is distinctive in the breadth of its stock). However, we were struck by what appeared to be a selection very well suited to its location, and which had some interesting features, including a table of books published in the 1950s.
- I spent some time in the large Waterstone’s on Dawson St in Dublin. I was interested to see a greater emphasis than I have noticed before on staff selections and presentations. For example, in addition to straightforward staff picks, there were desert island reads and summer crime selections. The pattern was repeated throughout the store. And there is a large cafe. Across the street, Hodges Figgis is a large store, but is distinctive in that it has a large selection of materials of Irish interest. (Waterstone’s and Hodges Figgis are both owned by the HMV Group.)
I am very fond of our local Border’s. We spent a lot of time in it when we first moved to the States and our children were younger. It was comfortable and welcoming. In recent years its stock has got smaller, so, from a supply perspective, it more often than not will be lacking what I am looking for. We used to buy CDs there, but it no longer has a large collection, presumably because other people’s pattern of consumption – towards online – has changed in ways similar to our own. I used to buy English and Irish newspapers there, but it gets them late and, again, online reading has replaced some of this need. I sometimes wonder how it should develop to better ‘sort out demand’.
Related:
- [On the discrimination of curations and curators …](https://blog.oclc.org/lorcand/archives/002119.html?ref=lorcandempsey.net)
- [Recommendation and Ranganathan](https://blog.oclc.org/lorcand/archives/001566.html?ref=lorcandempsey.net)
- [Aura again: habent sua fata libelli](https://blog.oclc.org/lorcand/archives/000627.html?ref=lorcandempsey.net)
- [Libraries and the long tail](https://www.dlib.org/dlib/april06/dempsey/04dempsey.html?ref=lorcandempsey.net) (considers how the long tail argument is about better matching supply and demand through aggregation in a network environment)
### On the discrimination of curators and curations ....
URL: https://www.lorcandempsey.net/on-the-discrimination-of-curators-and-curations/
Last updated: 2020-10-28T09:09:09.000Z
As existing practices evolve and new ones emerge it often takes time for the way in which we talk about them to settle down. There may be some interim terminological confusion. This has happened in our world with ‘archive’ for example.
We can also see this happen with curation/curation/curator. In recent conversations, it seems to me that I hear overlapping senses radiating from three centres.
The first is a traditional one to do with the creation of collections of cultural objects and the their selection, management and care throughout their lifecycle. Think of museum curators in this context for example, or the curatorial staff at the British Library. We often hear this sense extended to the creation and care of an exhibition. I and others have used the phrase *[curatorial traditions](https://www.google.com/search?hl=en&q=%22curatorial+traditions%22+OR+%22curatorial+tradition%22+&btnG=Search&aq=f&aqi=&aql=&oq=&gs%5Frfai=&ref=lorcandempsey.net)* to refer to the different but related bodies of professional practice deployed in the museum, library, archive and related domains.
The other two are newer and selectively emphasise core functions of the curatorial role suggested above.
The second emphasises a preservation and stewardship role, acknowledging this as part of an overall management lifecycle. One sometimes hears this in a restricted version of ‘data curation’. And preservation is a central aspect, for example, of the work of the [Digital Curation Centre](https://www.dcc.ac.uk/digital-curation/what-digital-curation?ref=lorcandempsey.net) at Edinburgh University.
The third emphasises the selection, organization and presentation function, and may be coming to be the most widely used sense in which *curation* is used. Here is a recent comment of Michael Cairns for example:
> In recent years content curation has emerged out of the wild, wild, west of ‘mere’ content. Sites such as The Huffington Post, Red State and Politico all represent new attempts to build audiences around curated content. While they appear to be successful, at the same time there are other sites (such as Associated Content and Demand Media) contributing to the morass of filler content that can plague the web users’ experience. The buzz word ‘curation’ does carry with it some logic: As the sheer amount of information and content grows, consumers seek help parsing the good from the bad. And that’s where curation comes in. \[The curator and the docent\]
Interestingly, curation, in this sense, has been central to the value of bookstores, newspapers and libraries, and is coming to be emphasised more. In each case, the management of supply may be moving elsewhere (to Amazon in the case of books for example) or becoming simpler (as data is aggregated in discovery layer products for libraries for example), leaving it important to think harder about the management of demand or consumption (providing greater support for selection, saving time, and so on, …) of which curation, as used in this third sense, is a central part.
Related entry:
- For management of demand/consumption see [Recommendation and Ranganathan](https://blog.oclc.org/lorcand/archives/001566.html?ref=lorcandempsey.net)
### Stitching costs - retread
URL: https://www.lorcandempsey.net/stitching-costs-retread/
Last updated: 2020-10-28T09:09:11.000Z
I am on vacation and traveling this week, and so am taking the opportunity to air again an entry of a couple of years ago on what I called ‘stitching costs’ ….
We are familiar with *switching costs*, the costs of changing a supplier. I may decide not to change my phone or email arrangements, for example, because I do not want to incur the effort of notifying all my contacts. Libraries are very familiar with switching costs given the range of data migration issues involved in changing library systems. Indeed, high switching costs are one reason that libraries often stay with the same vendor for long periods.
Libraries are also familiar with high ‘integration’ costs: perhaps these might be called *stitching costs*. This means that it may be costly developing higher level services based on integration of various lower level services.
Think for example of the website integration issues libraries have where they want to provide unified access to the catalog, to licensed resources, to repositories and so on. The intermittent levels of integration we see are because the ‘stitching costs’ are high.
This is largely because they are providing a thin layer over two sets of heterogeneous resources. One is the set of legacy and emerging systems, developed independently rather than as part of an overall library experience, with different fulfillment options, different metadata models, and so on (integrated library system, resolver, knowledge base, repositories, …). Another is the set of legacy database and repository boundaries that map more to historically evolved publisher configurations and business decisions than to user needs or behaviors (for example, metadata, e-Journals, eBooks, and other types of content, which may be difficult to slice and dice in useful ways).
Or think of higher level federation across library services. We have few compelling federated services, whether these are based on metadata harvesting, metasearch, or other approaches. Again, this is partly because of high stitching costs. I [cited](https://blog.oclc.org/lorcand/archives/001779.html?ref=lorcandempsey.net) Jerry McDonough’s [article](https://balisage.net/Proceedings/html/2008/McDonough01/Balisage2008-McDonough01.html?ref=lorcandempsey.net) the other day about how abstraction and optionality in library standards design creates unhelpful variation in implementation which in turn is a barrier to efficient interoperability.
Things are changing, as it becomes more important to effectively stitch library resources into other environments and as lighter-weight approaches get adopted. However, it is useful to bear stitching costs in mind when there is discussion of approaches based on federation and interoperability. These costs may be to do with technical issues (interfaces, metadata, …), or policy issues (ILL policies in a resource sharing system, for example), or higher level organizational and resource allocation issues (who will run the federation service, etc). And they are very real.
\[This entry first [appeared](https://blog.oclc.org/lorcand/archives/001785.html?ref=lorcandempsey.net) on October 8, 2008.\]
### In the Twitter flow ..
URL: https://www.lorcandempsey.net/in-the-twitter-flow/
Last updated: 2020-10-28T09:09:13.000Z
One of the recurrent themes of this blog has been the work done by libraries to put more of their services [in the flow](https://www.google.com/search?hl=en&q=%22lorcan+dempsey%22+%22in+the+flow%22&btnG=Search&aq=f&aqi=&aql=&oq=&gs%5Frfai=&ref=lorcandempsey.net) of their users’ working, learning and research behaviors.
In this context, I was pleased to see the work by my colleagues on implementing Worldcat searches in Twitter.
Mike Teets provides [fuller details](https://community.oclc.org/cooperative/2010/06/sometimes-the-internet-is-just-not-big-enough-for-me.html?ref=lorcandempsey.net); this is just a pointer.
A tweet of the form:
> @ask4stuff muldoon wills
returns a response like this:
> [@lorcanD](https://www.twitter.com/lorcand?ref=lorcandempsey.net) We found something on muldoon wills in #Ask4Stuff, look here: [https://is.gd/dxkYA](https://is.gd/dxkYA?ref=lorcandempsey.net)
The result can be limited to a particular Worldcat Local by using a hashtag based on the institution name in that WC Local. Here is an example using Worldcat Local at Ohio State ([https://osu.worldcat.org/](https://osu.worldcat.org/?ref=lorcandempsey.net)). Note also the alternative syntax: both @ask4stuff and #ask4stuff will work.
> #ask4stuff #osu muldoon wills
returns a response like this:
> [@lorcanD](https://www.twitter.com/lorcand?ref=lorcandempsey.net) A handful of items for muldoon wills in #Ask4Stuff, at #osu, look them over at [https://is.gd/dxl2b](https://is.gd/dxl2b?ref=lorcandempsey.net)
### Discovery layers - Top Tech Trends 2
URL: https://www.lorcandempsey.net/discovery-layers-top-tech-trends-2/
Last updated: 2020-10-28T09:09:15.000Z
\[No 2 of 3\. No 1 [here](https://blog.oclc.org/lorcand/archives/002115.html?ref=lorcandempsey.net).\]
I was pleased to participate in LITA’s Top Tech Trends panel at ALA this year (see the [video](https://litablog.org/2010/06/video-top-tech-trends-washington-dc-annual-2010/?ref=lorcandempsey.net) and [live coverage](https://litablog.org/2010/06/top-tech-trends-liveblog-2/?ref=lorcandempsey.net)).
We were each asked to talk about three trends: current, a bit further out, and a bit further out again. In thinking about the exercise, it seemed to me that it would be interesting to talk about how services are being reconfigured in a network environment, and not just focus on technology as such. This is the second of three blog entries, one devoted to each of my trends. We had three minutes in which to discuss each trend.
I really only decided to talk about my second trend the day before the event. I was influenced by discussions with several people as I wandered around the exhibits hall. Opinions varied as to how important this trend is, but I chose to talk about ‘discovery layers’ because it seems to me that if these become successfully and commonly deployed they have quite far reaching implications.
What do I mean by discovery layer? A discovery layer provides a single point of access to the full library collection across bought, licensed and digital materials. Typically, a single search box is offered alongside a range of other navigation features. Products which support this approach include Worldcat Local, Summon, Primo Central, and the Ebsco Discovery Service, as well as a range of institutional, national or other initiatives.
Working with hindsight ;-), these are the points I meant to make ….
1. *The full library collection*. If they develop as anticipated (a real question), the discovery layer will become **the** view of the library collection for library patrons. In fact, for many users it may actually become the library. This has several consequences:
- What is not represented in the discovery layer will be much less visible.
- There will be pressure to incorporate more services into the discovery layer – better fulfilment for example through resource sharing, Google book search, purchase or other options.
- The integrated discovery experience will more clearly expose lack of integration with services behind, and will drive greater integration. One can see, for example, potentially more interest in the direct-to-content approach of something like PubGet.
- And as somebody suggested to me afterwards, there will need to be strategies for managing those who resist the loss of a specific database interface.
2. *A driver for other operations.* If the discovery layer becomes the central focus for access to collections, then one can imagine discovery patterns begin to affect supporting operations like selection and acquisition. The patron-driven acquisition model is being explored in the ebook market – will it be extended to other licensed materials?
3. *Data wells and the provider landscape.* A discovery layer depends on an aggregation of data – a ‘data well’ – which involves considerable coordination costs. These include the processing involved in normalizing the data and the business interactions involved in assembling the data. The level of normalization may vary – how much work, for example, do you do in clustering author names across A&I databases, catalogs, and so on. It does not make sense to do this work too many times, so one might expect a small number of providers to emerge who syndicate ‘[data wells](https://blog.oclc.org/lorcand/archives/002068.html?ref=lorcandempsey.net)‘ to others as well as use them in their own services. It will also be interesting to see how strong the tendency is to use other products from your discovery layer provider – a knowledge base in which to record licensed holdings, a resolver, and so on.
4. *Indirect discovery*. It is important to remember that a discovery layer ‘destination’ is a part only of the library user’s discovery experience. Increasingly the library needs to think about how its services are visible to users who discover their information resources in Google, in the course management system, and so on. I discussed some issues in a [recent post](https://blog.oclc.org/lorcand/archives/002105.html?ref=lorcandempsey.net).
### Mobile .. Top Tech Trends 1
URL: https://www.lorcandempsey.net/mobile-top-tech-trends-1/
Last updated: 2020-10-28T09:09:17.000Z
I was pleased to participate in LITA’s Top Tech Trends panel at ALA this year (see the [video](https://litablog.org/2010/06/video-top-tech-trends-washington-dc-annual-2010/?ref=lorcandempsey.net) and [live coverage](https://litablog.org/2010/06/top-tech-trends-liveblog-2/?ref=lorcandempsey.net)).
We were each asked to talk about three trends: current, a bit further out, and a bit further out again. In thinking about the exercise, it seemed to me that it would be interesting to talk about how services are being reconfigured in a network environment, and not just focus on technology as such. This is the first of three blog entries, one devoted to each of my trends. We had three minutes in which to discuss each trend.
The first trend I chose was somewhat broad: mobile. I discussed five ways in which mobile is impacting our services:
1. Atomization: get to relevance quickly. Mobile encourages designers to think of atomic services rather than complicated workflows or rich multilayered experiences. And to think about services that are immediately relevant and convenient. Room or equipment booking or bus time tables may become more visible, for example.
2. Localization: where you are can matter. [WolfWalk](https://www.lib.ncsu.edu/wolfwalk/?ref=lorcandempsey.net) is a nice example of a library application which is location aware. It associates materials from NCSU’s special collections with historic buildings on campus. “The application supports a map view with geotagged placemarks for 90 major sites of interest on the NCSU campus, and a browse view for quickly locating a known site by name.”
3. Imbrication: our physical and digital spaces overlap. Andy Walsh, of Huddersfield University, for example, [discusses how](https://blog.oclc.org/lorcand/archives/002087.html?ref=lorcandempsey.net) QR Codes (and RFID tags) can be used to connect library places with network information services. And I was interested to see a QR code prominently displayed on one vendor booth at ALA providing a link to further information online.
4. Socialization: microcoordination and ad hoc rendezvous affect how we think about space. Mobile communications allow us to coordinate as we go: let’s meet up in an hour in Starbuck’s; I am in Target, will I buy these ones?; I thought you were going to be here 15 minutes ago? I [have written before](https://blog.oclc.org/lorcand/archives/001898.html?ref=lorcandempsey.net) about Starbuck’s as ‘on-demand place’ for the type of ad hoc rendezvous that we are now used to. William Mitchell has written about how this affects our need for different types of space, and we can see how this impacts library space:
> “The fact that people are no longer tied to specific places for functions such as studying or learning, says Mr. Mitchell, means that there is ‘a huge drop in demand for traditional, private, enclosed spaces’ such as offices or classrooms, and simultaneously ‘a huge rise in demand for semi-public spaces that can be informally appropriated to ad hoc workspaces’. This shift, he thinks, amounts to the biggest change in architecture in this century. \[Economist. “The new oases,” (10 April, 2008). Quoted [here](https://firstmonday.org/htbin/cgiwrap/bin/ojs/index.php/fm/article/view/2291/2070?ref=lorcandempsey.net).\]
5. Mobile and cloud go together. We have multiple connection points which offer different grades of experience (the desktop, phone, xBox or Wii, GPS system, smartphone, netbook, Internet radio/music streaming, and so on). While these converge in various ways, they are also optimized for different purposes. A natural accompaniment of this mesh of connection points is a move of many services to the cloud, available on the network across these multiple devices and environments when they are needed. This means that an exclusive focus on the institutional Web site as the primary delivery mechanism and the browser as the primary consumption environment is increasingly partial.
Related:
‘Always on: Libraries in a world of permanent connectivity’
by Lorcan Dempsey
*First Monday*, Volume 14, Number 1 – 5 January 2009
[https://firstmonday.org/htbin/cgiwrap/bin/ojs/index.php/fm/article/viewArticle/2291/2070](https://firstmonday.org/htbin/cgiwrap/bin/ojs/index.php/fm/article/viewArticle/2291/2070?ref=lorcandempsey.net)
### Beyond records .. genres
URL: https://www.lorcandempsey.net/beyond-records-genres/
Last updated: 2020-10-28T09:09:19.000Z
We tend to have a very record-based view of bibliographic systems. Searches in a resource result in lists of record-based displays for items. All fields may not be indexed. This means that the data works less hard than it might, given the variety of ways in which it could be leveraged to tell us more about the body of literature a resource relates to.
The introduction of facets changed this a little. In [Worldcat Identities](https://www.worldcat.org/identities?ref=lorcandempsey.net) we are interested in bringing together a view of parties who create or are the subject of works.
My colleagues have now worked with the Worldcat.org team to provide a view of Worldcat by genre.
[](https://www.worldcat.org/genres/romantic-suspense-fiction.html?ref=lorcandempsey.net)
For some more details see the project page.
> The project applies principles of the FRBR model to aggregate author and title information and statistical association techniques to generate related subject headings (e.g., topics, characters, people, places, and organizations). The initial set of profiles is based on genre terms selected from the [Guidelines On Subject Access To Individual Works Of Fiction, Drama, Etc](https://www.worldcat.org/title/guidelines-on-subject-access-to-individual-works-of-fiction-drama-etc/oclc/44391503?ref=lorcandempsey.net). (GSAFD), 2nd edition. Genre definitions are adapted from scope notes in GSAFD, and the Library of Congress authority file and [Moving Image Genre-Form Guide](https://www.loc.gov/rr/mopic/miggen.html?ref=lorcandempsey.net). More genre/form profiles will be added over time. \[[Worldcat genres](https://www.oclc.org/research/activities/genres/default.htm?ref=lorcandempsey.net)\]
### The cloud is currently a question, not an answer
URL: https://www.lorcandempsey.net/the-cloud-is-currently-a-question-not-an-answer/
Last updated: 2020-10-28T09:09:23.000Z
I will be on the LITA [Top Technology Trends](https://www.ala.org/ala/mgrps/divs/lita/litaevents/annual2010/index.cfm?ref=lorcandempsey.net) panel on Sunday. I have yet to finalize my thoughts, but I am sure that mobile and cloud will figure. We are increasingly familiar with the twin discussions about mobilization and the cloud, and about how each trend supports the other.
> As networking spreads, we have multiple connection points which offer different grades of experience (the desktop, cell phone, xBox or Wii, GPS system, smartphone, ultra-portable notebook, and so on). While these converge in various ways, they are also optimized for different purposes. A natural accompaniment of this mesh of connection points is a move of many services to the cloud, available on the network across these multiple devices and environments. This means that an exclusive focus on the institutional Web site as the primary delivery mechanism and the browser as the primary consumption environment is increasingly partial. \[[Always on: Libraries in a world of permanent connectivity](https://firstmonday.org/htbin/cgiwrap/bin/ojs/index.php/fm/article/view/2291/2070?ref=lorcandempsey.net)\]
In each case, it is not simply a matter of moving services to a new environment. Think of two trajectories. In one, current services may be reconfigured, as where, for example, the library website is atomized and selectively offered in a mobile app or apps. In another, new service options may appear, as where, for example, the location of the user can influence the nature of the service offered.
There are various ways of characterising cloud computing: see for example the now routine distinction between software-, platform- and infrastructure-as-a-service (explored in the [Wikipedia article](https://en.wikipedia.org/wiki/Cloud%5Fcomputing?ref=lorcandempsey.net) among other places).
Here is a simple way of thinking about moving library management **applications** like the ILS to the cloud. While these will continue to exist, taken successively they involve greater reconfiguration of existing processes. Note that I am limiting the discussion to library management applications in this way – a broader discussion might include a range of other interesting possibiliites …
Consider three simple stages …
1. Hosting. A library may chose to have an application hosted by a third party. This may provide a saving for the library where the third party delivers at a lower price than the cost of local management, or where local specialist staff is not required. However, the character of the application itself does not change much.
2. Sharing. Libraries may share infrastructure and facilities meaning that spare capacity can be consolidated and reduced. The consolidation of data, infrastructure and services may also mean that services can be enhanced. Think of introduction of new features, rapid integration of new services or information resources, removal of redundant operations, and so on. Note, by sharing here I don’t mean that libraries necessarily work with the ‘same system’, although that is a possibility in some consortial arrangements; they may work with their system instance running in a shared environment.
3. Leveraging. Here, the shared environment is leveraged to create new services. Network effects are important. So, think of recommendation or analytics services based on aggregate circulation or resolver transactions. Think of the ability to more easily do collaborative collection development based on a shared view of selection and acquisitions patterns. Think of the ability to blend interlibrary loan and circulation. Now, these are things that can be done through aggregation of data or interaction between systems. The ability to do this more readily is increased in this environment, within agreed policy and service frameworks.
Libraries have worked through OCLC to build shared capacity in cataloging, resource sharing and discovery. OCLC has been working to extend these collaborative benefits to other library operations in the form of its Webscale Management Services.
Which brings me back to ALA … My colleague Andrew Pace has been leading this initiative and you can learn more about services and directions at ALA ([Webscale or bust](https://www3.oclc.org/app/ala%5Fregistration/?ref=lorcandempsey.net), Saturday 1:30 – 3:30 pm, Four Points by Sheraton, Franklin Rooms A-C). The Circulation and Acquisitions components of OCLC’s Web-scale management services will be demonstrated and will shortly be made available to early adopters. See [Andrew’s post](https://community.oclc.org/hecticpace/archive/2010/06/hoping-for-the-best-ala-ever.html?ref=lorcandempsey.net) for some more details.
### More reading ...
URL: https://www.lorcandempsey.net/more-reading/
Last updated: 2020-10-28T09:09:27.000Z
Here are some recent reports/papers produced by OCLC Research or in which we have been involved …
Kroll, Susan, and Rick Forsman. 2010\. **A Slice of Research Life: Information Support for Research in the United States.** Report commissioned by OCLC Research in support of the RLG Partnership.
Published online at: [https://www.oclc.org/research/publications/library/2010/2010-15.pdf](https://www.oclc.org/research/publications/library/2010/2010-15.pdf?ref=lorcandempsey.net) (.pdf: 1.1MB/24 pp.).
(A parallel UK report will be produced by the Research Information Network.)
Lavoie, Brian, Neil Beagrie \[first author\], and Matthew Woolard. 2010\. **Keeping Research Data Safe 2**. JISC.
Available online at: [https://www.jisc.ac.uk/publications/reports/2010/keepingresearchdatasafe2.aspx](https://www.jisc.ac.uk/publications/reports/2010/keepingresearchdatasafe2.aspx?ref=lorcandempsey.net) (.pdf: 1.5MB/89 pp.).
Massie, Dennis. 2010\. **Greening Interlibrary Loan Practices.** Report produced by OCLC Research.
Published online at: [https://www.oclc.org/research/publications/library/2010/2010-07.pdf](https://www.oclc.org/research/publications/library/2010/2010-07.pdf?ref=lorcandempsey.net) (.pdf: 833KB/64 pp.)
Ziso, Ya’aqov, Ralph leVan, and Eric Lease Morgan. 2010\. **Querying OCLC Web Services for Name, Subject, and ISBN**. *Code4Lib Journal*, 9 (2010-03-22).
Available online at: [https://journal.code4lib.org/articles/2481](https://journal.code4lib.org/articles/2481?ref=lorcandempsey.net).
Radford, Marie L., and Lynn Silipigni Connaway. 2010. **‘I Stay Away from the Unknown, I Guess.’ Measuring Impact and Understanding Critical Factors for Millennial Generation and Adult Non-users of Virtual Reference Services.** In *Online Proceedings of the Fifth Annual iConference*, University of Illinois at Urbana-Champaign, February 3-6, 2010, 26-33.
Available online at: [https://nora.lis.uiuc.edu/images/iConferences/2010papers2\_Page-Zhang.pdf](https://nora.lis.uiuc.edu/images/iConferences/2010papers2%5FPage-Zhang.pdf?ref=lorcandempsey.net) (.pdf: 292k/9 pp.).
To add to the list I provided a while ago …
Godby, Carol Jean. 2010\. **Mapping ONIX to MARC.** Report and crosswalk produced by OCLC Research.
Available online at [https://www.oclc.org/research/publications/library/2010/2010-14.pdf (report)](https://www.oclc.org/research/publications/library/2010/2010-14.pdf?ref=lorcandempsey.net) and [https://www.oclc.org/research/publications/library/2010/2010-14a.xls (crosswalk).](https://www.oclc.org/research/publications/library/2010/2010-14a.xls?ref=lorcandempsey.net)
(A welcome collaboration with Editeur.)
Silipigni Connaway, Lynn and Timothy Dickey. 2010\. **Digital information seekers: How academic libraries can support the use of digital resources**. Report produced for JISC.
Summary and links to report at:
[https://www.jisc.ac.uk/publications/briefingpapers/2010/bpdigitalinfoseekerv1.aspx](https://www.jisc.ac.uk/publications/briefingpapers/2010/bpdigitalinfoseekerv1.aspx?ref=lorcandempsey.net)
Michalko, James, Constance Malpas and Arnold Arcolio. 2010\. **Research Libraries, Risk and Systemic Change.** Report produced by OCLC Research.
Published online at: [https://www.oclc.org/research/publications/library/2010/2010-03.pdf (.pdf: 579K/20 pp.)](https://www.oclc.org/research/publications/library/2010/2010-03.pdf?ref=lorcandempsey.net)
Blue Ribbon Task Force on Sustainable Digital Preservation and Access. **Sustainable Economics for a Digital Planet: Ensuring Long-term Access to Digital Information.**
Available online at: [https://brtf.sdsc.edu/biblio/BRTF\_Final\_Report.pdf](https://brtf.sdsc.edu/biblio/BRTF%5FFinal%5FReport.pdf?ref=lorcandempsey.net)
(The Task Force was co-chaired by Brian Lavoie.)
Combs, Michele, Mark A. Matienzo, Merrilee Proffitt, and Lisa Spiro. 2010\. **Over, Under, Around, and Through: Getting Around Barriers to EAD Implementation.** Report produced by OCLC Research.
Published online at: [https://www.oclc.org/research/publications/library/2010/2010-04.pdf.(.pdf: 646K/44 pp.)](https://www.oclc.org/research/publications/library/2010/2010-04.pdf?ref=lorcandempsey.net).
MacColl, John. 2010\. **Research Assessment and the Role of the Library.** Report produced by OCLC Research.
Available online at: [https://www.oclc.org/research/publications/library/2010/2010-01.pdf](https://www.oclc.org/research/publications/library/2010/2010-01.pdf?ref=lorcandempsey.net).
Miller, Lisa, Steven K. Galbraith, et al. 2010. **“Capture and Release”: Digital Cameras in the Reading Room.** Report produced by OCLC Research.
Published online at: [https://www.oclc.org/research/publications/library/2010/2010-05.pdf](https://www.oclc.org/research/publications/library/2010/2010-05.pdf?ref=lorcandempsey.net) (.pdf: 133K/16 pp.).
Smith-Yoshimura, Karen, Catherine Argus, Timothy J. Dickey, Chew Chiat Naun, Lisa Rowlinson de Ortiz, and Hugh Taylor. 2010\. **Implications of MARC Tag Usage on Library Metadata Practices.** Report produced by OCLC Research in support of the RLG Partnership.
Available online at: [https://www.oclc.org/research/publications/library/2010/2010-06.pdf](https://www.oclc.org/research/publications/library/2010/2010-06.pdf?ref=lorcandempsey.net) (.pdf: 771K/72 pp.)
Waibel, Günter, Ralph LeVan and Bruce Washburn. 2010\. **Museum Data Exchange: Learning How to Share.** Report produced by OCLC Research.
Available online at: [https://www.oclc.org/research/publications/library/2010/2010-02.pdf](https://www.oclc.org/research/publications/library/2010/2010-02.pdf?ref=lorcandempsey.net) (.pdf: 2MB/50 pp.).
### Distinctive impact and specialization
URL: https://www.lorcandempsey.net/distinctive-impact-and-specialization/
Last updated: 2020-10-28T09:09:29.000Z
In the print era, the cost of interacting with multiple information sources was high so there were incentives for newspapers to present a complete view of news, entertainment, local affairs, and so on, to local audiences.
In the network environment, that cost goes down and there is an incentive to specialize and syndicate.
The Economist had an interesting discussion of this recently and argued that newspapers should focus on where they can make a distinctive impact. A local or regional newspaper cannot compete with the *New York Times*, for example, for international coverage, so should not try to, it argues.
> The whirlwind that swept through newsrooms harmed everybody, but much of the damage has been concentrated in areas where newspapers are least distinctive. Car and film reviewers have gone. So have science and general business reporters. Foreign bureaus have been savagely pruned. Newspapers are less complete as a result. But completeness is no longer a virtue in the newspaper business. Just look at the fate of Otis Chandler’s creation.
> Thanks to family connections, Chandler ended up in control of the Los Angeles Times in 1960\. The paper he inherited was parochial and conservative, reflecting the city it served. Chandler jettisoned the anti-union dogma and set about building a west-coast rival to the New York Times. His paper was heavy on foreign news and serious, objective reporting. The result was hugely impressive–but not, as it turned out, suited to the internet era. In the past few years the paper has suffered repeated staff cuts. In 2007 it was acquired by a property magnate and in 2008 filed for bankruptcy protection.
> The problem with such newspapers is that, although they do much that is excellent, they do little that is distinctive enough for people to pay for it. The Los Angeles Times’s foreign reporting is extremely good. But it is hard to argue that it is better than the stuff supplied by the New York Times or foreign papers–sources to which the residents of Los Angeles now have unfettered, largely free access via their laptops and iPhones. Similarly, it has never been clear why each major newspaper needs its own car reviewer: a Corolla is a Corolla, whether it is driven in Albuquerque or Atlanta. And by extension, it is not clear why presidential candidates or sport teams require huge journalistic entourages. Papers should concentrate on what they do best, which means, in many cases, local news and sport. If the rest is bought in from wire services or national outfits, readers are unlikely to complain–as long as there is enough competition between those larger providers to keep up standards (and thanks to the internet there probably is now). Specialisation generally means higher quality. \[[Not dead yet: Newspapers have cut their way out of crisis. More radical surgery will be needed](https://www.economist.com/node/16321506?ref=lorcandempsey.net)\]
How many larger providers should there be? What should the local specialties be? What is the distinctive impact of the local paper?
It struck me that libraries face similar questions. What should be done locally and what should be taken from external providers? Where should library effort be spent, and where should common solutions be good enough?
### A nice dedication to librarians by Rick Riordan
URL: https://www.lorcandempsey.net/a-nice-dedication-to-librarians-by-rick-riordan/
Last updated: 2020-10-28T09:09:35.000Z
We downloaded Rick Riordan’s latest novel, *The Red Pyramid*, to my son’s iPod Touch this afternoon. As he began to read, he came across this nice dedication:
> To all my librarian friends, champions of books, true magicians in the House of Life. Without you, this writer would be lost in the Duat.
### Music: Marcus, Morrison, Mumford, and Carr
URL: https://www.lorcandempsey.net/music-marcus-morrison-mumford-and-carr/
Last updated: 2022-11-08T16:40:25.000Z
I recently read Greil Marcus’s [book](https://www.worldcat.org/title/when-that-rough-god-goes-riding-listening-to-van-morrison/oclc/435418486?ref=lorcandempsey.net) on Van Morrison. While I have most of the Morrison oeuvre on some form of physical medium it was useful to be able to refer to my aggregate digital collection, and to the Zune marketplace and iTunes Store as backup.
I could quickly look up songs I couldn’t remember or place, and I could confirm my memory of songs Marcus did not mention (he has a particular view of where Morrison’s strengths are, and dismisses large stretches of his work).
A couple of things about this. First, I expect to be able to find – and be able to listen to – much of the stuff I look for, even though, in this case, Morrison is on record as saying that he is not a ‘download artist’ (see this [interview](https://www.youtube.com/watch?v=QVHbUPNcTiU&ref=lorcandempsey.net) with Time, for example). As I have discussed [elsewhere](https://blog.oclc.org/lorcand/archives/001730.html?ref=lorcandempsey.net), he has also resisted the youtubification of his work. The second is that this certainly leads to a ‘flattening’ of one type of experience – the work involved in finding and playing music. Search and you will find, skimming over many years’ work and many artists.
We went to hear Mumford and Sons in OSU a few weeks ago. I had been interested to see them compared to Crosby, Stills and Nash in [an NPR story](https://www.npr.org/templates/story/story.php?storyId=123891913&ref=lorcandempsey.net) before going. They responded that they had a variety of folkish influences, UK as well as US. And indeed, we thought we heard something of someone like June Tabor and a more robust version of The Waterboys in what they did. A caustic [Independent review](https://www.independent.co.uk/arts-entertainment/music/reviews/album-mumford---sons-sigh-no-more-universalisland-1797620.html?ref=lorcandempsey.net) heard The Fleet Foxes.
Again, one could trace relationships online. Here is what the Zune marketplace has to report:

Again, in one view this represents a flattening of experience as one can quickly develop a sense of relationships or influences. This type of experience is now routine, of course. We are used to being provided with hooks and hints. Artists and artists are ranked, related and recommended in the environments in which we discover, manage and share music. We can let Pandora do our listening for us.
In each of these cases I was reminded of Nicholas Carr’s discussion of music, from where the phrase ‘flattening of experience’ comes, and my remarks …
> A while ago, Nick Carr [wrote about](https://www.roughtype.com/archives/2009/11/be%5Feverywhere%5Fn%5F1.php?ref=lorcandempsey.net) this change in our experience of music. He quoted from two BBC reports. One proclaimed “a new golden age of infinite music” in which “there’s no longer any past – just an endless present”. By contrast, he notes, John Taylor, of Duran Duran, takes a more “nuanced view” which he describes as follows: “He wonders whether such easy abundance doesn’t lead to a flattening of experience: When everything’s present, nothing’s new.” He provides a quote from Taylor, who on the basis of the ‘power’ of a TV experience, went on a ten-mile cycle looking for a record, and then listened to it again and again.
>> Taylor argues that, when it comes to music or any other form of art, the price of our “endless present” is the loss of a certain “magical power” that the artist was once able to wield over the audience. I suspect he’s right. \[[Be everywhere now](https://www.roughtype.com/archives/2009/11/be%5Feverywhere%5Fn%5F1.php?ref=lorcandempsey.net)\]
> So, as a full range of music, movies and maybe books becomes available to us, so too does our engagement with it change. Our sense of ownership changes, as media are delivered as a service. The work involved in assembling a personal collection diminishes. Our sense of historical perspective may change. But, I am not so sure about the loss of a certain “magical power” or the flattening of experience. Sure experiences are different. But think of an earlier transition. This magical power may also have been felt to be lost when “mechanical reproduction” allowed live performances to be shared in the first place: a recording could never take the place of a performance, could it? \[[Stuff as a service](https://blog.oclc.org/lorcand/archives/002033.html?ref=lorcandempsey.net)\]
Carr is always suggestive. However, there is also a Kulturkritik gloominess about some of his writing. In talking about change, he quite often focuses on what we have lost, not on what we have gained.
Now, my musical experiences are limited: my knowledge and collections have been shallow. It is true that this new convenience has flattened my experience in one dimension (and I think also of Adorno’s ‘withering of experience’). However the online world has also enriched my sense of relationships and history and extended my experiences in important ways. I think I have gained more than I have lost. My musical appreciation is, in fact, deeper, because of the opportunities I now have. Both the volume and the variety of what I listen to, and what I buy, is greater than it used to be.
p.s. I would be interested to a future study of how this broad availability affects the composition of music itself.
p.p.s. I am reading Nicholas Carr’s The Shallows at the moment and was interested to see Steven Johnson’s [critique](https://www.nytimes.com/2010/06/20/business/20unbox.html?ref=business) of it in the NYT earlier today.
### We're not going anywhere .... OK, we lied ...
URL: https://www.lorcandempsey.net/were-not-going-anywhere-ok-we-lied/
Last updated: 2022-12-06T21:27:58.000Z
Last Friday I attended the [RLG Partnership Symposium](https://www.oclc.org/research/events/2010-06-11.htm?ref=lorcandempsey.net). The topic – *When the books leave the building* – reflected the growing discussion around the management of legacy print collections across the academic library system. The balance between local print, offsite print (local or shared), and emerging digitised collections, presents interesting choices. These are tactical as competing interests are managed, and strategic as decisions are made about mission, sustainability and responsibility to the scholarly record. Interestingly, the outcome of one discussion was that maybe 25 libraries in the US might see it as part of their mission to remain committed to the management of the print scholarly record.
Constance Malpas provided some interesting empircal context, looking at volumes of materials already digitized and also at volumes of materials which had been moved into offsite storage.
[The Western Regional Storage Trust](https://www.cdlib.org/services/collections/sharedprint/westinitiative.html?ref=lorcandempsey.net) is an interesting early attempt to model issues across a broad group of libraries. The deep integration envisaged by [2CUL](https://2cul.org/node/17?ref=lorcandempsey.net) provides another example of joint response amongst a range of other infrastructure issues.
Now, I had brought with me Nicholas Carr’s new book [The Shallows](https://www.worldcat.org/title/shallows-what-the-internet-is-doing-to-our-brains/oclc/449865498?ref=lorcandempsey.net) to read on the plane. Early in the book, describing his time as a Dartmouth student, he contrasts his experience with emerging digital technologies at the Kiewit Computation Center with his experience in the library:
> That was just a digital dalliance. For every hour I passed in Kiewit, I must have spent two dozen next door in Baker. I crammed for exams in the library’s cavernous reading room, looked up facts in the weighty volumes on the reference shelves, and worked part-time checking books in and out at the circulation desk. Most of my library time, though, went to wandering the long, narrow corridors of the stacks, Despite being surrounded by tens of thousands of books, I don’t remember feeling the anxiety that’s symptomatic of what we today call “information overload.” There was something calming in the reticence of all those books, their willingness to wait years, decades even, for the right reader to come along and pull them from their appointed slots. *Take your time* the books whispered to me in their dusty voices. *We’re not going anywhere.* \[*The Shallows,* p.12\]
It seems they lied 😉 While many of the books will remain on the shelves for some years to come, it is clear that the exodus has begun. The books are leaving the library.
### Indirect discovery
URL: https://www.lorcandempsey.net/indirect-discovery/
Last updated: 2020-10-28T09:09:42.000Z
I have found that the phrase [*Discovery happens elsewhere*](https://blog.oclc.org/lorcand/archives/001430.html?ref=lorcandempsey.net) has quite a bit of resonance in discussion.
Increasingly people discover websites, or encounter content from them, in a variety of places. Most clearly, this happens through network-level services like Google or Twitter, but also happens in personal services (my RSS aggregator), or services which allow me to traverse from personal to network (social networking, bookmarking, …). The library may also want to ‘place’ resources in various ways in other environments, course management systems for example.
If *discovery happens elsewhere*, then there are several important consequences for libraries. Most important is the recognition that a library’s own, locally managed or provided discovery environments – the catalog, metasearch service or discovery layer – are only a part of the picture, that there are other areas of discovery which would benefit from attention.
Libraries will also want to support *indirect discovery*. By this I mean, they will want to connect the discovery experience, whenever it happens outside of the library environment, to the possibility of fulfillment in the library.
This may happen in several ways. Importantly, it makes sense that libraries will want to *disclose* the existence of their resources into other discovery environments. Think of a library’s unique resources for example, its digitized special collections, for example, or the institutional assets it manages in an institutional repository. As with other information providers on the web, the library will want to make sure that these are exposed in ways that optimize crawling, indexing and finding by search engines. Other approaches may be sensible, adding relevant links to Wikipedia pages for example, or selectively putting images from the collection on Flickr.
For non-unique resources a library may want to disclose the fact that it holds a particular item. Think here, for example, of making sure that Google Scholar knows how to resolve article metadata to your particular library (see the [Library Links](https://scholar.google.com/intl/en/scholar/libraries.html?ref=lorcandempsey.net) program). Or of being represented in one of the several union catalogs (including Worldcat) that Google uses to direct the ‘find in a library’ link on Google Book Search.
Another approach is to ‘leverage’ a discovery environment which is outside of your control to bring people back to your environment. Here I am thinking of the use of tools like [LibX](https://libx.org/?ref=lorcandempsey.net), which may mobilize metadata found ‘elsewhere’ in a variety of ways to connect to a particular library resource. The developers report that LibX has been customised for over 700 different use environments.
Other approaches could also be discussed. We don’t yet have a routine way of supporting ‘indirect discovery’ or a shared inventory of use cases. This will be one of the more interesting development areas in coming years.
Related resources:
Lorcan Dempsey. The library catalogue in the new discovery environment. *Ariadne* Issue 48 June 2006.
[https://www.ariadne.ac.uk/issue48/dempsey/](https://www.ariadne.ac.uk/issue48/dempsey/?ref=lorcandempsey.net)
Lorcan Dempsey. [Discovery and delivery](https://wiki.lib.umn.edu/Staff/UniversityLibrariesSpeakerSeries?ref=lorcandempsey.net#dempsey). Presentation and webcast presentation from University of Minnesota speaker series.
### 3 switches
URL: https://www.lorcandempsey.net/3-switches/
Last updated: 2020-10-28T09:09:46.000Z
I have been using these three ‘switches’ as contextual background in presentations for a while:
**Consumer switch**
*Then:* More investment in business/education environments.
*Now:* More investment in consumer environments.
It used to be the case that the computer and communications capacities we had at work or in college exceeded those available to us in personal or family settings. Now this is no longer the case. Consumer sites like Amazon or Etsy set expectations for services and we have multiple computing and communications devices. Indeed, educational and work settings now often lag the consumer space (look no further than the library website). This is a significant change and will continue given the level of investment in the consumer space.
**Workflow switch**
*Then:* Expect workflows to be built around my service.
*Now:* Build services around workflows
Much of our information creation and use is now carried out on the network. This may be assisted by the prefabricated workflow supported by a course management system, a lab notebook, or a pre-print archive, for example. Or it may be assisted by the bricolage of tools we use to find and organize information resources: citation management services, bookmarks, RSS readers, twitter clients, and so on. People have varying levels of sophistication of support within an overall trend towards adopting research and learning workflows on the network. What this means is that while users may once have built their workflows around the library, now, the library needs to consider how to build its services around the user workflow, to be available where its readers are doing their work. Think for example of Netflix which works hard to make itself available in as many ways as make sense for its users. We can get a DVD. We can also stream to a PC, an xbox, an app on the iPad, and so on.
**Attention switch**
*Then:* Resources scarce; attention abundant.
*Now:* Attention scarce; resources abundant.
Library users now have many opportunities to meet their information needs, and they have many demands on their attention. No single site is the sole focus of attention and convenience is important.
### QOTD: Marcus and Morrison
URL: https://www.lorcandempsey.net/qotd-marcus-and-morrison/
Last updated: 2020-10-28T09:09:49.000Z
Greil Marcus finished an article about the reception of his recent book on Van Morrison with this lovely quote:
> Not all the stories people tell about Morrison, though, are stories of conflict, confusion, resentment, or regret. “I was talking to my father today,” a woman in Portland said. “He asked what I was doing tonight, and I told him to was going to hear someone talk about a book he’d written on Van Morrison. ‘Oh, Van Morrison!’ he said. ‘You know, I used to work with his father on the docks in Belfast. After work he’d take me to his house to listen to his records. I’d never seen anything like it. Hundreds and hundreds of 78s and LPs, jazz, blues, country music, everything. And there’d be the little boy there, dancing around the room, saying play that, Daddy! Play that!'” \[[Listening to Van Morrison by Greil Marcus](https://www.guardian.co.uk/books/2010/jun/05/listening-van-morrison-greil-marcus?ref=lorcandempsey.net)\]
Off-topic but nice: I will follow up with another post on music in a day or two …
Greil’s book was called [*Listening to Van Morrison*](https://www.faber.co.uk/work/listening-to-van-morrison/9780571254446/?ref=lorcandempsey.net) in the UK and [*When that rough god goes riding: listening to Van Morrison*](https://www.publicaffairsbooks.com/publicaffairsbooks-cgi-bin/display?book=9781586488215&ref=lorcandempsey.net) in the US.
### Outside-in and inside-out redux
URL: https://www.lorcandempsey.net/outside-in-and-inside-out-redux/
Last updated: 2026-08-31T01:49:46.000Z
I have been using this phrase, *outside-in and inside-out*, to discuss a contrast in information management practices that is becoming more important. Here is how I spoke about it a little while ago in these pages:
> Think, for example, of a distinction between outside-in resources, where the library is buying or licensing materials from external providers and making them accessible to a local audience (e.g. books and journals), and ‘inside-out’ resources which may be unique to an institution (e.g. digitized images, research materials) where the audience is both local and external. Thinking about an external non-institutional audience, and how to reach it, poses some new questions for the library. \[[Outside-in and inside-out](https://blog.oclc.org/lorcand/archives/002047.html?ref=lorcandempsey.net)\]
And here is how I have been talking about it in presentations in the context of the ‘[collections grid](https://blog.oclc.org/lorcand/archives/001897.html?ref=lorcandempsey.net)‘.
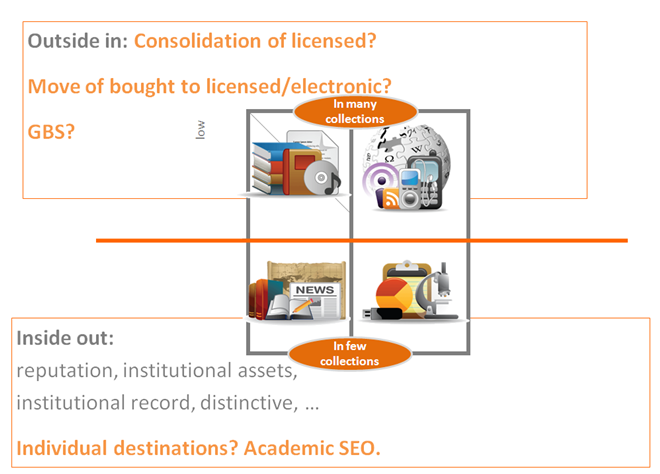
‘Below the line’ are digitized materials (special collections, slides, etc) and the digital outputs of research and learning practices. Here a set of common interests emerge, in terms of digital library infrastructure, management of unique materials (something of course archives and museums have always done), disclosure to the outside world, and so on. This requires a new set of skills and orientations and a new way of interacting with clients.
I was reminded of this when reading an interesting post by Mark Dahl earlier where he talks about this shift in concrete terms. He notes the slow diminishment of ‘above the line’ activities:
> As content shifts to the network and as discovery is disintermediated from the library, the work needed to support the library’s traditional roles as buyer, archiver, and gateway to information is slowly diminishing. \[[code4lib NW: digital initiatives presentation](https://synthesize-specialize-mobilize.blogspot.com/2010/06/code4lib-nw-digital-initiatives.html?ref=lorcandempsey.net)\]
He then discusses several ‘thematic digital projects’ where faculty are working with digital resources to enhance teaching, learning and research. One example is ‘[accessCeramics: a contemporary ceramics image resource](https://accessceramics.org/?ref=lorcandempsey.net)‘ a collaboration between the Library and the Art Department at Lewis and Clark College, where the author works.
He sees a role over and above the creation and management of document- or image- based repositories we have seen emerge in recent years, and which I mention above.
> But I think there are more interesting opportunities when we actually wade out into the messy world of teaching and research and offer up our expertise at organizing information. A way of doing this is to establish some kind of a digital initiatives program that faculty can engage with directly. We see this at large institutions such as [University of Virginia](https://www.iath.virginia.edu/?ref=lorcandempsey.net) and [Columbia](https://www.columbia.edu/ccnmtl/?ref=lorcandempsey.net), but also now increasingly at liberal arts colleges like [Hamilton](https://academics.hamilton.edu/dhi/?ref=lorcandempsey.net), [The University of Richmond](https://digitalscholarship.richmond.edu/?ref=lorcandempsey.net), and [Kenyon](https://lbis.kenyon.edu/NGLgrants?ref=lorcandempsey.net). The programs at these institutions in one way or another offer support to faculty for teaching or research related digital projects. \[[code4lib NW: digital initiatives presentation](https://synthesize-specialize-mobilize.blogspot.com/2010/06/code4lib-nw-digital-initiatives.html?ref=lorcandempsey.net)\]
(Incidentally, given the University of Virginia is mentioned, it might be appropriate to point to the [Scholars’ Lab](https://www2.lib.virginia.edu/scholarslab/about/?ref=lorcandempsey.net).)
### More on VuFind
URL: https://www.lorcandempsey.net/more-on-vufind/
Last updated: 2020-10-28T09:09:54.000Z
I wrote an [entry](https://blog.oclc.org/lorcand/archives/002100.html?ref=lorcandempsey.net) on *yufind* the other day, noting its use of xISBN to cluster editions in results. *yufind* is an implementation of VuFind. Here is another example of the clustering: [Villanova](https://library.villanova.edu/Find/Record/456712?ref=lorcandempsey.net).
As Till Kinstler points out in a [comment](https://blog.oclc.org/lorcand/archives/002100.html?ref=lorcandempsey.net#comments), and as William Denton notes in a [discussion](https://www.frbr.org/2010/06/04/last-week-in-frbr-26?ref=lorcandempsey.net) of the entry on his FRBR blog, this is a feature supported in the standard VuFind distribution.
My colleagues Karen Coombs and Xiaoming Liu sent me some further information. Apparently, the VuFind developers are looking at potential integration also of the Worldcat API and Worldcat Identities.
A companions service to xISBN is [xOCLCNUM](https://xisbn.worldcat.org/xisbnadmin/xoclcnum/api.htm?ref=lorcandempsey.net). This would give better coverage (the ISBN only applies to recent items) but I do not have a good sense of how widely available an OCLC number would be in records of catalogs run by VuFind.
### A web-siting at Yale: other editions and xISBN
URL: https://www.lorcandempsey.net/a-web-siting-at-yale-other-editions-and-xisbn/
Last updated: 2020-10-28T09:09:59.000Z
I was looking at the Vufind implementation of the Yale University Library catalog – [yufind](https://yufind.library.yale.edu/yufind/Record/4197420?ref=lorcandempsey.net) – and was interested to see that it implements a link to OCLC’s [xISBN](https://xisbn.worldcat.org/xisbnadmin/index.htm?ref=lorcandempsey.net) service to pull together other editions of a displayed result. Here is an example where several versions of *Krapp’s Last Tape* are shown in the bottom left section of the display.
[](https://yufind.library.yale.edu/yufind/Record/4197420?ref=lorcandempsey.net)
The feature, and how it is implemented, is nicely described under the label ‘[New feature: other editions](https://labs.library.yale.edu/yufind/2010/02/new%5Ffeature%5Fother%5Feditions%5F1.html?ref=lorcandempsey.net)‘.
### 'Reading at Library-scale'/'distant reading'
URL: https://www.lorcandempsey.net/reading-at-library-scale-distant-reading/
Last updated: 2021-04-01T03:30:46.000Z
Franco Moretti has an interesting short book called [*Graphs, maps, trees: abstract models for literary history*](https://www.worldcat.org/title/graphs-maps-trees-abstract-models-for-a-literary-history/oclc/60671819/editions?referer=di&editionsView=true&ref=lorcandempsey.net). He proposes a way of reading literary history which involves abstracting patterns across large stretches of a literary field rather than examining “concrete, individual works”. In particular, he works with three organizing models: graphs, maps and trees. He calls this type of reading ‘distant reading’, a method which can be applied to large bodies of literature and which yields a different form of insight than close textual analysis of a selective canon.
Via a [conference report](https://infomotions.com/blog/2010/05/cyberinfrastructure-days-at-the-university-of-notre-dame/?ref=lorcandempsey.net) by Eric Lease Morgan I recently came across John Unsworth’s use of the phrase “reading at library-scale”.
> My own research career as a faculty member, for the last 20 years, has been devoted first to understanding the impact of technology on the humanities and, more recently, to designing tools that would allow humanists to work at library-scale, using the computer as a kind of attention prosthetic that allows us to perceive patterns made up of very small pieces of information across very large expanses of text. Having perceived those patterns, of course, it is still up to us, as human beings with expertise in a relevant domain, to make sense of them and to persuade others to share that sense. \[[Abstract – reading at library scale](https://ci.nd.edu/presenters/pre%5FUnsworth.htm?ref=lorcandempsey.net)\]
Unsworth and Moretti both feature in an article published in *The Chronicle* a couple of days ago: [The humanities go Google](https://chronicle.com/article/The-Humanities-Go-Google/65713/?ref=lorcandempsey.net).
This considers ‘distant reading’ or ‘reading at library-scale’ in the context of Google Book Search.
> Data-diggers are gunning to debunk old claims based on “anecdotal” evidence and answer once-impossible questions about the evolution of ideas, language, and culture. Critics, meanwhile, worry that these stat-happy quants take the human out of the humanities. Novels aren’t commodities like bags of flour, they warn. Cranking words from deeply specific texts like grist through a mill is a recipe for lousy research, they say–and a potential disaster for the profession. \[[The humanities go Google](https://chronicle.com/article/The-Humanities-Go-Google/65713/?ref=lorcandempsey.net)\]
Now, the article sets up an opposition which may be a convenient hook for a story, but is probably less important than some of the ways in which humanities scholarship will develop when large amounts of material are available for computational analysis in this way.
In this context, I was interested to read how ‘distant reading’ involves a cross-disciplinary team: “To sort, interrogate, and interpret roughly 1,000 digital texts, scholars have brought together a data-mining gang drawn from the departments of English, history, and computer science”. Unsworth also discusses collaborative multi-disciplinary work of the type which produced [MONK](https://www.monkproject.org/?ref=lorcandempsey.net), for example.
From a library point of view it is interesting to see humanities scholarship acquiring some of the features – and support requirements – more characteristic of the sciences.
**Picture:** I took the feature picture of a couple of Moretti's titles.
**Note:** Cosmetic updates added on 31 March 2021 to fix spacing and add picture.
### Return on attention and Current Cites
URL: https://www.lorcandempsey.net/return-on-attention-and-current-cites/
Last updated: 2020-10-28T09:10:07.000Z
I was quite taken with the phrase “return on attention” while [reading](https://blog.oclc.org/lorcand/archives/002086.html?ref=lorcandempsey.net) [The Power of Pull](https://www.edgeperspectives.com/pop.html?ref=lorcandempsey.net) a while ago. I was also interested in the deprecation of the term information overload.
> It’s not so much about finding which information is most valuable, as many of those who fret about information overload would have it. Improving return on attention is more about finding and connecting with people who have the knowledge you need, particularly the tacit knowledge about how to do new things.
Forwarding a particular current awareness bulletin to colleagues the other day, I wrote: “I confess that I find this type of digest less and less useful. Or rather, maybe, their return on attention is not high enough incentive to make me want to look at them.”
However, there is one digest that I will usually look at. My colleague, Roy Tennant, [noted the other day](https://www.libraryjournal.com/blog/1090000309/post/480054448.html?ref=lorcandempsey.net) that this is the twentieth year of [*Current Cites*](https://lists.webjunction.org/currentcites/?ref=lorcandempsey.net). *Current Cites* is selected by several hands under the overall editorship of Roy. I find that it provides very good return on attention 😉
Roy deserves our congratulations for keeping *Current Cites* going for so long. I wonder is part of its success down to the variety of personal perspectives that inform the selection?
### Googling
URL: https://www.lorcandempsey.net/googling-2/
Last updated: 2020-10-28T09:10:09.000Z
Google revamped its home page a while ago, highlighting a little more some additional features such as its wonder wheel, related searches, social (which searches among your ‘friends’ on various sites), nearby, and so on.
I find the ability to limit by the date of pages in results quite useful – there are many times where you want to see ‘recent’ things.
I wonder how much some of the other features are used? I had a look at some results earlier.
Here is the wonder wheel for ‘Lorcan Dempsey’ results.

Here is what clicking on ‘related searches’ for an original search on ‘Lorcan Dempsey’ shows:

Now, I am not quite sure why these are different. Or how useful they are. I tried several other searches, more aligned with recent interests, and the results would not really motivate continued use in the future.
I hope that Google publish something about patterns of use at some stage to see how the various features are used. A while ago, Andy Powell wrote of Google:
> Google search is the benchmark of functionality and usability in Internet search – it’s what every other search engine compares themselves to and it has been pretty much since it was first released. That’s a pretty amazing track record!
> What’s been the basis of that track record? It is simplicity, at least as far as the user is concerned, that has kept it in pole position. Google search does one thing, really, really well. \[[eFoundations](https://efoundations.typepad.com/efoundations/2010/02/google-and-usability.html?ref=lorcandempsey.net)\]
He compared this with other Google services, which fell short in some way of this simplicity and clarity. We value greatly the simplicity, the ability to find things quickly. And the ability to look at news, or images, or videos, and so on. We cannot imagine living without it, in fact, and at some level understand that Google works hard to provide this quality of experience. But some other things seem less compelling: the integration of real time search or the search of your social circle for example. And some of the new features I mention here. It is almost as if Google knows this too for their addition seems a little perfunctory. They are literally marginal to the main results.
That said, I was interested in one aspect of the refining approaches where results are placed along a timeline …

It looks as if my career peaked in 1996 😉
(Minor update: 31 May 2010)
### Reading lists, citation management and bibliographic tissue
URL: https://www.lorcandempsey.net/reading-lists-citation-management-and-bibliographic-tissue/
Last updated: 2020-10-28T09:10:12.000Z
Here is something I wrote a couple of years ago under the title [Personal reference collections as digital libraries](https://blog.oclc.org/lorcand/archives/001545.html?ref=lorcandempsey.net). A little updating of examples and I think it still holds:
> We will see much more activity connecting user environments and bibliographic resources. I am thinking of citation managers, reading lists, social bookmarking sites (see citulike and unalog) and RSS feeds. Some of these may be specifically supported by the library (e.g. a citation manager service), some may be developed within an academic or scholarly context (e.g. Zotero, citulike, …), and some may be general network services. People have multiple ways of creating personal and shared collections of data and links.
> They are also an example of an increasingly important aspect of our bibliographic apparatus – we have discovery or ‘rendezvous’ experiences outside the library resource, where it would be good to be able to link back into a library service for fulfillment, or indeed into other services. … \[[Personal reference collections as digital libraries](https://blog.oclc.org/lorcand/archives/001545.html?ref=lorcandempsey.net)\]
I have written several times of such resources as a type of *bibliographic tissue*. In an ideal case they might be built from metadata conveniently pulled from several resources, catalogs, A&I services and so on, and, again ideally, they might always conveniently connect those descriptions with the appropriate described resource, whether in the library or elsewhere. Of course, we know that this does not always happen. The above quote, for example, is in the context of work at the University of Minnesota looking at how readily data in local Refworks collections could be connected back to library resources. We can expect such flows to improve: look for example at the list of databases the [Mendeley Web Importer](https://www.mendeley.com/import/?ref=lorcandempsey.net) feature works with.
Now, although libraries offer such services, in many cases students, teachers, or researchers may find their own way to support such activity and they may use services outside the library orbit.
In this context I was interested recently to learn about two initiatives.
First was the [Talis Aspire](https://www.talis.com/aspire/?ref=lorcandempsey.net) product, a description of which I encountered at the [Emtacl10](https://www.ntnu.no/ub/emtacl/?ref=lorcandempsey.net) conference. It is a shared resource list management system. I have no experience of it, but was interested in the description. It allows the list creator to pull metadata from several resources; it claims to integrate with learning management system, ILS, and other relevent campus environments; it is provided in the cloud, and claims to have social features on the way, building on top of the aggregate resource list data. Clearly, resource lists and the works included in them, are interesting [social objects](https://blog.oclc.org/lorcand/archives/001601.html?ref=lorcandempsey.net) around which some community might develop. So, it is providing a management framework which potentially strengthens the connective bibliographic tissue of the reading list.
However, the most interesting aspect of the description to me were the suggestions made around improving the quality of the educational experience for the student, increasing the productivity of the educator, and leveraging systems investment. Reading lists are central to the educational experience and improving their utility or making it easier to manage them are big gains.
Second was MyReferences, produced by the [Telstar project](https://www.open.ac.uk/blogs/telstar/?ref=lorcandempsey.net) at the Open University, which aims to provide a framework for embedding references/citations in learning management systems. Specifically, the OU team worked with RefWorks and Moodle, but are also providing a range of interesting materials about use cases, experiences, technologies, and so on.
> Owen Stephens, TELSTAR Project Manager, said: “These new tools are invaluable to the 21st century educational institution and student. There is an ever increasing wealth of resources available and hence a real need for students, course and programme teams to be able to create, manipulate, organise and store a range of citations and bibliographic references for easy use.
> There are already a number of general referencing tools available to students, but MyReferences takes the usability of these tools a step further by integrating them into online courses so the materials students commonly need to reference are already available in the format they need. Students simply select the sources they need to reference, the referencing style their institution requires and then copy and paste the result into their assignment. \[[Press Release: Referencing made easy](https://www3.open.ac.uk/media/fullstory.aspx?id=18800&ref=lorcandempsey.net)\]
In each case, there is an attempt to add value to the simple supply of bibliographic data by providing the ability to make that data work in student and teacher workflows, and by conveniently connecting workflow to useful resources.
### A note about Tracey Thorn
URL: https://www.lorcandempsey.net/a-note-about-tracey-thorn/
Last updated: 2020-10-28T09:10:14.000Z
A little off topic … I have been listening to Tracey Thorn’s new album, [Love and its opposite](https://www.buzzinfly.com/store/merchant.mvc?Screen=PROD&Store%5FCode=TBS&Product%5FCode=CD005FEEL&Category%5FCode=STRXXX&ref=lorcandempsey.net). Here are several things …
1. It has been [available for listening](https://www.strangefeelingrecords.com/ecards/loveanditsopposite%5Forder.html?ref=lorcandempsey.net) for a while on the label site, and is embedded elsewhere. Videos of live home recordings are available for some songs ([here is one](https://www.youtube.com/watch?v=09yKp8ioysU&feature=player%5Fembedded&ref=lorcandempsey.net#!) for example). Her Twitter bio is “The official home of Tracey Thorn, singer, gardener, bedsit disco queen”.
2. Thorn’s output is not prolific. She does not tour. The New Yorker [writes](https://www.newyorker.com/arts/critics/musical/2010/05/17/100517crmu%5Fmusic%5Ffrerejones?ref=lorcandempsey.net) about her: “Both the album’s themes and how it was made suggest a model that may become increasingly popular: the semi-professional musician.” The singer is quoted: “I just want to make it and then get back to my other life”. That other life is shared with Ben Watt, her partner of many years, with whom she performed as Everything But the Girl, and their three children.
3. And that other life is the inspiration for the songs. According to the [Guardian](https://www.guardian.co.uk/music/musicblog/2010/may/10/exclusive-album-preview-tracey-thorn?ref=lorcandempsey.net), she captures “the dismay of early middle age” in those around her. Her own family experience appears as well: ‘Hormones’ is a song about her relationship with her daughter.
Maybe nothing truly exceptional, but it seems very …. contemporary.
### A spectacle
URL: https://www.lorcandempsey.net/a-spectacle/
Last updated: 2020-10-28T09:10:16.000Z
I have been wearing glasses for thirty years or so. I ordered a new pair yesterday, and when I got home I had a look at all my previous pairs. Here they are:

I am sure it says something about me …..
### Aura
URL: https://www.lorcandempsey.net/aura/
Last updated: 2021-04-03T04:55:32.000Z
John Naughton has a nice column in *The Observer* today. He talks about how as part of welcoming Dan Cohen to Cambridge, the University Library prepared a display around Newton’s Principia. John enjoys the experience …
> I’ve owned a beautifully produced facsimile of the Principia for decades, so it wasn’t the novelty of seeing it that took my breath away. It was the work’s amazing presence. The centuries seemed to dissolve as we bent over the pages to read Newton’s neatly composed amendments, just as he must have crouched when he was writing them. For a few magical, eerie moments, it seemed as though he was there in the room with us.
> Afterwards, I was reminded of Walter Benjamin’s celebrated – if exasperating – essay on [The Work of Art in an Age of Mechanical Reproduction](https://www.marxists.org/reference/subject/philosophy/works/ge/benjamin.htm?ref=lorcandempsey.net) in which he tried to figure out what happens to authenticity in an age of perfect copying. “Even the most perfect reproduction of a work of art,” he wrote, “is lacking in one element: its presence in time and space, its unique existence at the place where it happens to be.” This “aura” that emanates from original works – which is, Benjamin argued, stripped away by reproduction – is hard to pin down (and Benjamin doesn’t really nail it, in my opinion) but, believe me, you know it when you feel it. And not even Google can digitise it. // [For a moment, I was in the presence of Newton’s genius](https://www.guardian.co.uk/technology/2010/may/16/networker-isaac-newton-google?ref=lorcandempsey.net)
One of the benefits – and hazards – of blog writing is that you can dip into lots of topics without following through in fuller detail. The blog is a place where you can work out a view, without necessarily developing a fuller argument. Occasionally, blog entries, or a series of blog entries, can turn into something longer. I have written several articles – [this](https://www.dlib.org/dlib/april06/dempsey/04dempsey.html?ref=lorcandempsey.net) on the long tail for example – based on earlier blog entries.
Several years ago, I talked about Benjamin’s aura in the context of digitization in several entries:
- [Aura again: haba sua fata libelli](https://blog.oclc.org/lorcand/archives/000627.html?ref=lorcandempsey.net)
- [Aura and digitization](https://blog.oclc.org/lorcand/archives/000623.html?ref=lorcandempsey.net)
- [Aura, Google Print and digitized library books](https://blog.oclc.org/lorcand/archives/000509.html?ref=lorcandempsey.net)
At the time I spent a while looking for discussions of the impact of digitization on various aspects of ‘aura’ in a library collections context: on the notion of the coherence of a collection, on the artifactual properties of books, on the provenance and patterns of ownership of books, on the nature of the reading experience, and so on. Clearly, these are topics of interest in archival and conservation domains, but I found surprisingly little relating them to library interests.
Now, Benjamin’s essay and the notion of ‘aura’ itself are certainly fashionable, and, as John Naughton points out, the concept of ‘aura’ itself remains vague. Nevertheless, it seems to me to be a very suggestive idea for us. Maybe at some stage, I will find some time to think for longer than a blog entry’s length about it 😉
\[Incidentally, John points to a copy of Benjamin’s essay on the [Marxists Internet Archive](https://www.marxists.org/?ref=lorcandempsey.net). I know nothing about this beyond what a quick look and the Wikipedia entry for it tell me. Interestingly, it has assembled a lot of material – see the entry on [James Connolly](https://www.marxists.org/archive/connolly/index.htm?ref=lorcandempsey.net) for example – and seems to be operating on a voluntary basis.\]
**Picture:** I took the feature picture of a first edition of Principia annotated by Newton at Cambridge University Library.
**Note:** Cosmetic amendments on 3 April 2021 include addition of picture and fixing spacing.
### Research analytics
URL: https://www.lorcandempsey.net/research-analytics/
Last updated: 2020-10-28T09:10:23.000Z
Analytics is big business. Organizations are increasingly turning to the analysis of transactional and other data to inform decision-making. Websites are refined based on analysis of traffic. Companies may use analytics to optimize inventory. And so on.
I was struck by the parallel with business analytics when reading some brochures about Elsevier’s SciVal. These were part of a pack distributed at the [Emtacl10](https://www.ntnu.no/ub/emtacl/?ref=lorcandempsey.net) conference in Trondheim recently. They include some quotes:
> We need reliable support to help us make smarter, defendable decisions about allocating internal funding. (Vice Chancellor for Research)
> Decision making will always be subjective, but we are trying to move to a more evidence-based model. (Development manager)
The material describes the tool in terms which would not look out of place, with appropriate substitutions, in advertising for a business analytics tool:
> Academic Executives need accurate research performance insight to make appropriate funding decisions and develop strategic blueprints that will lead their institutions to valuable breakthroughs.
Also in the pack was some material about the use of Scopus for bibliometrics. In this case, the material speaks about ‘research performance measurement’:
> Research Performance Measurement (RPM), also known as bibliometrics, is the discipline of measuring the performance of a researcher, a collection of selected articles, a journal or an institute. ….. Quantitative metrics are gaining prominence because they are easy to benchmark, objective and globally comparative; all important in global RPM.
Of course, in this area Elsevier is competing with Thomson Reuters’ [Web of Science](https://wokinfo.com/products%5Ftools/multidisciplinary/webofscience/?ref=lorcandempsey.net) and related products. Indeed, Thomson Reuters has a [Research evaluation](https://thomsonreuters.com/products%5Fservices/science/science%5Fproducts/scholarly%5Fresearch%5Fanalysis/research%5Fevaluation/?ref=lorcandempsey.net) section on its website.
One of the drivers of such measurement is the strong interest in recent years in university ranking. And this is an area also in which Thomson Reuters has become very active, with its [Global institutional profiles project](https://science.thomsonreuters.com/globalprofilesproject/?ref=lorcandempsey.net) and its partnership with the *Times Higher* to produce their widely consulted [university rankings](https://www.timeshighereducation.co.uk/story.asp?sectioncode=26&storycode=408908&navcode=105&ref=lorcandempsey.net).
Of course, this interest in research analytics and metrics is not without opposition. However, it is interesting to see Elsevier and Thomson Reuters very clearly identify this emphasis within their product offerings, and the location of bibliometrics within the broader area of research analytics and metrics services to university customers.
### QR codes again ...
URL: https://www.lorcandempsey.net/qr-codes-again/
Last updated: 2020-10-28T09:10:25.000Z
[Andy Walsh](https://librarymobiles.blogspot.com/?ref=lorcandempsey.net) of the University of Huddersfield gave a very nice presentation on QR Codes at the recent EMTACL10 conference at [NTNU](https://www.ntnu.no/ub/english/?ref=lorcandempsey.net) in Trondheim.
I particularly liked his introduction in which he provided some motivating context for his work. He noted that as library spaces became places for social activity, their specifically informational dimension was waning. And that this was a pity, and in the long term probably not very helpful for the library. He suggested that QR codes (and RFID tags) were one way of reconnecting those places to an informational dimension, and gave examples of how codes and tags could be used to link library places to information resources and services.
An [earlier presentation](https://www.slideshare.net/andy%5Fwalsh/qr-codes-text-a-librarian-and-more?ref=lorcandempsey.net) on Slideshare gives a sense of some of the topics discussed.
[](https://www.slideshare.net/andy%5Fwalsh/qr-codes-text-a-librarian-and-more?ref=lorcandempsey.net)
Prompted by Andy’s presentation, I had a quick look at some QR Code resources for libraries earlier:
- I [wrote about](https://blog.oclc.org/lorcand/archives/001923.html?ref=lorcandempsey.net) QR Codes in the University of Bath [catalogue](https://library.bath.ac.uk/uhtbin/cgisirsi/jnboMBY4hH/UNIV-BATH/41600020/9?ref=lorcandempsey.net) a while ago. The University of Huddersfield [catalogue](https://webcat.hud.ac.uk/ipac20/ipac.jsp?profile=cls&ref=lorcandempsey.net), [Kyoto University](https://op.kulib.kyoto-u.ac.jp/webopac/catdbl.do?ref=lorcandempsey.net), and [San Diego State University](https://libpac.sdsu.edu/search~S0?/Xlorcan&SORT=D/Xlorcan&SORT=D&SUBKEY=lorcan/1,4,4,B/frameset&FF=Xlorcan&SORT=D&1,1,&ref=lorcandempsey.net) also use them in this way.
- The *Library success: a best practices wiki* has a [page](https://www.libsuccess.org/index.php?title=QR%5FCodes&ref=lorcandempsey.net) on QR Codes and libraries.
- The University of Bath, noted above, has a special interest in QR Codes and Andy Ramsden maintains a [resource](https://blogs.bath.ac.uk/qrcode/?ref=lorcandempsey.net) about the use of QR codes in education. There is also a QR code [FAQ](https://www.bath.ac.uk/learningandteaching/ltfaq/index.php?sid=23557&lang=en&action=show&cat=6&ref=lorcandempsey.net).
- There is a guide to use of QR codes in libraries and education at Providence College (maintained by Chris Landry). (Via [@lisacarlucci](https://twitter.com/lisacarlucci?ref=lorcandempsey.net))
### People are entry points too ... redux
URL: https://www.lorcandempsey.net/people-are-entry-points-too-redux/
Last updated: 2022-11-04T22:02:12.000Z
I have been reading *[The power of pull](https://www.edgeperspectives.com/pop.html?ref=lorcandempsey.net)* by John Hagel III, John Seely Brown and Lang Davison. They provide a broad framework for thinking about current changes and how people and firms should position themselves to operate effectively. A major part of this is a shift from managing ‘knowledge stocks’ to being able to participate in ‘knowledge flows’.
John Hagel [writes](https://www.edgeperspectives.typepad.com/?ref=lorcandempsey.net): “This pull approach seeks to develop scalable pull platforms that amplify our ability to draw out the people and resources when we need them and where we need them”.
I was struck by this passage …
> We all talk loosely about information overload and assume that this is the real problem. In fact, we live in a world of increasing knowledge scarcity. The most valuable knowledge is in very short supply and is extremely hard to access. Information overload is a distraction. As we discussed in earlier chapters, in a world of accelerating change, the most valuable knowledge is highly distributed and may be embedded in the heads of people who are not well known and who are difficult to identify. \[…\]
> It’s not so much about finding which information is most valuable, as many of those who fret about information overload would have it. Improving return on attention is more about finding and connecting with people who have the knowledge you need, particularly the tacit knowledge about how to do new things. The danger is that we all get so busy assimilating explicit knowledge that we have no time to connect with people and build the relationships through which tacit knowledge flows. We get so busy reading about steampunk, or brewing, or building networks, that we don’t actually find and connect with and learn from the people who are doing it. It’s not so much information that we need as knowledge. And knowledge means people.
> These people and the knowledge flows they generate can then become effective filters for information more broadly. By harnessing social media such as blogs, social-network platforms, and wikis, we can begin to rely on these mechanisms to expose ourselves to information that has been curated and passed on by these people. Since we deeply understand their contexts and passions, we can begin to determine when their recommendations are most reliable and increase our return on attention for both the tacit knowledge they offer and the information they recommend to us. Our personal social and professional networks will be far more effective in filtering relevant knowledge and information than any broader social-technology tools we might access.
The authors talk of three ‘primary levels’ of pull. First there is *access*, the ability to find people and resources when they are needed. The second is the ability to *attract* valuable and relevant people and resources to you. Social networking, conferences, location in relevant geographic spikes (Nashville for country music) are important here, as is the ability to be open to and develop relationships through serendipitous encounter. The third is the ability to *achieve* more by learning more effectively and translating that learning into improved performance. Interestingly, the authors discuss ‘creation spaces’ which support this third level. Examples include the social interaction on World of Warcraft and the SAP Developer Network which provide support for shared attention to problems.
The above passage, and the book itself, are suggestive in several ways. I thought I would mention a couple of things here.
The first is that I was interested in thinking about the three levels in relation to library expertise (if libraries want to be seen as experts, then their expertise must be seen).
1. Access: is library expertise visible when people are searching for things? I have written before – [here](https://blog.oclc.org/lorcand/archives/001873.html?ref=lorcandempsey.net) for example – about such expertise being visible on websites, and also, for example, of the nice feature on the University of Michigan website which [returns appropriate library contacts](https://www.lib.umich.edu/mlibrary/search/mirlyn;website;ejournals;searchtools;deepblue/demographics?ref=lorcandempsey.net) in searches for resources.
2. Attract: how should librarians position themselves so as to seem natural partners or collaborators.
3. Achieve: as ‘creation spaces’ emerge how should librarians interact with them. One thing that comes to mind here is the role of emerging social networks for researchers, and library interaction and support. Guus van den Brekel spoke about this at the recent EMTACL10 conference \[[Slideshare](https://www.slideshare.net/digicmb/virtual-research-networks-towards-research-20?ref=lorcandempsey.net)\].
The second is that I was struck by the extent to which success is seen by the authors to be bound up with network participation – networks of people and resources facilitated by digital networks. The future, they seem to suggest, favors – In [Dave White’s phrase](https://blog.oclc.org/lorcand/archives/001773.html?ref=lorcandempsey.net) – the network residents.
### The Reader and the Law
URL: https://www.lorcandempsey.net/the-reader-and-the-law/
Last updated: 2020-10-28T09:10:29.000Z
Eddi Reader is a Scottish singer, formerly of Fairground Attraction. I was aware of Fairground Attraction but really only began listening to Eddi Reader a couple of years ago and she has become a favorite. \[[Worldcat Identity](https://www.worldcat.org/wcidentities/lccn-no97-68432?ref=lorcandempsey.net)\]\[[Soundunwound](https://www.soundunwound.com/music/eddi-reader/6843?ref=SA)\]. She sings some wonderful songs, one of which I link to below. Her musical versions of Robbie Burns’ poems received wide attention a few years ago.
Derek Law is a Scottish librarian, who recently retired as Head of the Information Resources Directorate and University Librarian at the University of Strathclyde, Glasgow. Derek played a central role in the emergence of the national framework for information services and R&D now provided by JISC. Derek was an important figure in my career in various roles over the years, from when I first moved to the UK to join what eventually became UKOLN. He is now Chair of the Board of [JISC Advance](https://www.jiscadvance.ac.uk/index?ref=lorcandempsey.net).
Imagine my pleasure recently, then, when I came across the following video on YouTube. It shows Derek Law introducing Eddi Reader as she is conferred with an honorary PhD by the University of Strathclyde.
There is a second part also. I notice that Eddi Reader has honorary PhDs from Glasgow Galedonian University, Strathclyde and Stirling University \[[Wikipedia](https://en.wikipedia.org/wiki/Eddi%5FReader?ref=lorcandempsey.net)\].
Here is one of my favorite Eddi Reader songs …
Coda: Eddi Reader [performed this song](https://www.ted.com/talks/eddi%5Freader%5Fsings%5Fkiteflyer%5Fs%5Fhill.html?ref=lorcandempsey.net) for a TED audience accompanied by Thomas Dolby. She also sang [another](https://www.ted.com/talks/eddi%5Freader%5Fsings%5Fabout%5Fwhat%5Fyou%5Fve%5Fgot.html?ref=lorcandempsey.net).
### Focusing on the distinctive ...
URL: https://www.lorcandempsey.net/focusing-on-the-distinctive/
Last updated: 2020-10-28T09:10:36.000Z
Links to a story in yesterday’s NYT are popping up around the place. Called *[Companies Slowly Join Cloud-Computing](https://www.nytimes.com/2010/04/19/technology/19cloud.html?hp&ref=lorcandempsey.net)*, it looks at recent moves by companies to source computing capacity in the cloud. There is some emphasis on Amazon’s services, but others are also discussed.
The thing which has jumped out at many people though is the note about Netflix, a major network based company:
> This year, Netflix made what looked like a peculiar choice: the DVD-by-mail company decided that over the next two years, it would move most of its Web technology — customer movie queues, search tools and the like — over to the computer servers of one of its chief rivals, Amazon.com.
The rationale was interesting:
> Kevin McEntee, Netflix’s vice president of engineering, said Netflix switched in order to “focus our innovation around finding movies, rather than building larger and larger data centers.”
> As for tethering Netflix’s future to a rival, Mr. McEntee said, “It’s in their interest to make us successful in the cloud. That’s why we felt comfortable.”
So, while the general cloud technology aspect of this is interesting, it feels less interesting than the motivating business dynamic behind Netflix’s decision. This is about focusing resources and attention on where it is going to make a distinctive impact, and not consume those resources and attention on doing something that can better be externalized to another provider.
Of course, it will be interesting to see how the arrangement progresses and if Netflix are happy with their decision.
This seems like a significant marker in the general trend towards network enabled externalization to specialist providers.
I post it here, as I have observed that ‘[sourcing and scaling](https://blog.oclc.org/lorcand/archives/002058.html?ref=lorcandempsey.net)‘ is one of the major questions facing libraries in coming years: what should be externalized and at what level should it be done.
### Reading and writing ...
URL: https://www.lorcandempsey.net/reading/
Last updated: 2022-11-08T16:44:04.000Z
We have produced or been involved in a variety of reports recently. I thought it would be interesting to do a list of some …
Godby, Carol Jean. 2010\. **Mapping ONIX to MARC.** Report and crosswalk produced by OCLC Research. Available online at [https://www.oclc.org/research/publications/library/2010/2010-14.pdf (report)](https://www.oclc.org/research/publications/library/2010/2010-14.pdf?ref=lorcandempsey.net) and [https://www.oclc.org/research/publications/library/2010/2010-14a.xls (crosswalk).](https://www.oclc.org/research/publications/library/2010/2010-14a.xls?ref=lorcandempsey.net)
(A welcome collaboration with Editeur.)
Silipigni Connaway, Lynn and Timothy Dickey. 2010\. **Digital information seekers: How academic libraries can support the use of digital resources**. Report produced for JISC. Summary and links to report at:
[https://www.jisc.ac.uk/publications/briefingpapers/2010/bpdigitalinfoseekerv1.aspx](https://www.jisc.ac.uk/publications/briefingpapers/2010/bpdigitalinfoseekerv1.aspx?ref=lorcandempsey.net)
Michalko, James, Constance Malpas and Arnold Arcolio. 2010\. **Research Libraries, Risk and Systemic Change.** Report produced by OCLC Research. Published online at: [https://www.oclc.org/research/publications/library/2010/2010-03.pdf (.pdf: 579K/20 pp.)](https://www.oclc.org/research/publications/library/2010/2010-03.pdf?ref=lorcandempsey.net)
Blue Ribbon Task Force on Sustainable Digital Preservation and Access. **Sustainable Economics for a Digital Planet: Ensuring Long-term Access to Digital Information.** Available online at:
[https://brtf.sdsc.edu/biblio/BRTF\_Final\_Report.pdf](https://brtf.sdsc.edu/biblio/BRTF%5FFinal%5FReport.pdf?ref=lorcandempsey.net)
(The Task Force was co-chaired by Brian Lavoie.)
Combs, Michele, Mark A. Matienzo, Merrilee Proffitt, and Lisa Spiro. 2010\. **Over, Under, Around, and Through: Getting Around Barriers to EAD Implementation.** Report produced by OCLC Research. Published online at: [https://www.oclc.org/research/publications/library/2010/2010-04.pdf.(.pdf: 646K/44 pp.)](https://www.oclc.org/research/publications/library/2010/2010-04.pdf?ref=lorcandempsey.net).
MacColl, John. 2010\. **Research Assessment and the Role of the Library.** Report produced by OCLC Research. Available online at: [https://www.oclc.org/research/publications/library/2010/2010-01.pdf](https://www.oclc.org/research/publications/library/2010/2010-01.pdf?ref=lorcandempsey.net).
Miller, Lisa, Steven K. Galbraith, et al. 2010. **“Capture and Release”: Digital Cameras in the Reading Room.** Report produced by OCLC Research. Published online at: [https://www.oclc.org/research/publications/library/2010/2010-05.pdf](https://www.oclc.org/research/publications/library/2010/2010-05.pdf?ref=lorcandempsey.net) (.pdf: 133K/16 pp.).
Smith-Yoshimura, Karen, Catherine Argus, Timothy J. Dickey, Chew Chiat Naun, Lisa Rowlinson de Ortiz, and Hugh Taylor. 2010\. **Implications of MARC Tag Usage on Library Metadata Practices.** Report produced by OCLC Research in support of the RLG Partnership. Available online at: [https://www.oclc.org/research/publications/library/2010/2010-06.pdf](https://www.oclc.org/research/publications/library/2010/2010-06.pdf?ref=lorcandempsey.net) (.pdf: 771K/72 pp.)
Waibel, Günter, Ralph LeVan and Bruce Washburn. 2010\. **Museum Data Exchange: Learning How to Share.** Report produced by OCLC Research. Available online at: [https://www.oclc.org/research/publications/library/2010/2010-02.pdf](https://www.oclc.org/research/publications/library/2010/2010-02.pdf?ref=lorcandempsey.net) (.pdf: 2MB/50 pp.).
### Interstitial reading
URL: https://www.lorcandempsey.net/interstitial-reading/
Last updated: 2020-10-28T09:10:41.000Z
Evan Schnittman of OUP has an [interesting post](https://www.blackplasticglasses.com/2010/03/23/digital-reading/?ref=lorcandempsey.net#more-445) in which he discusses three types of digital reading: extractive, immersive and pedagogic. It is worth a read.
Looking at his post, I was reminded of a phrase I used for a while: *interstitial reading*. We do quite a bit of reading in the interstices of our lives. The bathroom comes to mind, but I am in particular thinking about reading and travel.
[Wolfgang Schivelbusch](https://www.worldcat.org/wcidentities/lccn-n81-5225?ref=lorcandempsey.net) devotes some interesting passages to the interconnection of reading and trains in his wonderful monograph *[The railway journey: the industrialization of time and space in the 19th Century](https://www.worldcat.org/title/railway-journey-the-industrialization-of-time-and-space-in-the-19th-century/oclc/13581021?ref=lorcandempsey.net)*. He notes how reading became popular as an alternative at once to the fast disappearing view out of the window and to interaction with other passengers. He describes the emergence of book-selling and -lending operations in train stations. He quotes from the minutes of an 1860 French medical congress:
> Practically everybody passes the time reading while traveling on the train. This is so common that one rarely sees members of a certain social class embark on a journey without first purchasing the means by which they can enjoy this pastime.
He quotes an advert from John Murray: “Literature for the rail – works of information and innocent amusement”. And he provides a reference to how Hachette aimed to turn the “enforced leisure and boredom of a long trip to the enjoyment and instruction of all” through the introduction of stores in railway stations.
The story of how Allen Lane conceived of Penguin Books while on a railway platform is also well known (whether it is true or not) ([wikipedia](https://en.wikipedia.org/wiki/Allen%5FLane?ref=lorcandempsey.net)).
Reading is now an integral part of travel, and we are very familiar with the ‘opportunities’ provided in the seat pocket on an airplane, the readers on the subway or tube, and the inevitable magazine stand or bookshop at stations and airports.
More recently, mobile communications have introduced a new dimension to the ‘enforced leisure’ of those interstitial times in the airport or while waiting for a train, as people catch up on email, Facebook, Twitter, news, sports results and so on.
Now, this is by way of introduction to a note about the iPad. The iPad seems an ideal device for interstitial reading, supporting social networking, immersive reading, extractive interaction with the web, and so on. However, it does not have the portability of the magazine, newspaper or paperback. For this reason, rumours about the smaller iPad seem to make a lot of sense. The Kindle on the other hand is eminently portable, and, importantly, can be held with one hand. But it is less well able to support the full variety of interstitial reading and network interactions. For this reason, it is not surprising to see it open up as a platform to other apps, although one imagines its niche will continue to be the immersive reader, albeit one that fits such reading into the various interstices of his or her daily routine.
### An all-through system? From Onix to MARC
URL: https://www.lorcandempsey.net/an-all-through-system-from-onix-to-marc/
Last updated: 2020-10-28T09:10:43.000Z
One of the recommendations of the LC Working Group on the Future of Bibliographic Control encouraged greater reliance on an ‘all-through’ system for bibliographic data, where data created upstream by publishers and others could be mobilized downstream by libraries.
I was reminded of these words at the time.
> Records serve different requirements and needs and yet have overlapping functions, and involve redundancy of content and duplication of effort. Throughout its history, in some cases from the moment a contract is signed between author and publisher, the book has an attendant record or records – so much so that … it looks as though there already exists within the overall book community the resources to satisfy most needs. However the present arrangement of those resources is not meeting those needs. Although there is a continuity of supply of information, continuity of record content and format is intermittent: a user will not always have available at the appropriate moment a usable record of appropriate detail. \[[Bibliographic records in the book world: needs and capabilities](https://www.worldcat.org/title/bibliographic-records-in-the-book-world-needs-and-capabilities-proceedings-of-a-seminar-held-on-27-28-november-1987-at-newbury/oclc/21526308&referer?ref=lorcandempsey.net)\]
I wrote these words in 1987, in a report on a meeting of UK librarians, publishers and booksellers. Brian Green, of the International ISBN Agency and an Editeur principal, and I [wondered recently](https://blog.oclc.org/lorcand/archives/001974.html?ref=lorcandempsey.net) why more has not happened in the interim. Clearly, the various players have different incentives, their data is for different purposes, and the ways in which data has been captured and encoded reflects those differences.
This last point emerges quite clearly from a report by my colleague Jean Godby just released jointly by OCLC and [Editeur](https://www.editeur.org/?ref=lorcandempsey.net): *Mapping Onix to MARC*. Here is the summary:
> This document presents an interpretation of a crosswalk from ONIX 2.1 to MARC 21 developed by OCLC and made publicly available from the OCLC Web site and EDItEUR. This work represents a major upgrade in the statement of how data for bibliographic description can be exchanged between two standards that are widely used in the library and publishing communities. The discussion considers practical outcomes and identifies theoretical and conceptual issues that will inform the next major revision of this strategically important relationship. \[Mapping Onix to MARC [PDF](https://www.oclc.org/research/publications/library/2010/2010-14.pdf?ref=lorcandempsey.net)\]
This is a nice collaboration and I hope that it can be built upon.
Related entry (with some good comments):
- [Data flows in the book world](https://blog.oclc.org/lorcand/archives/001974.html?ref=lorcandempsey.net)
### QOTD: "the professional conservatism of professors" ...
URL: https://www.lorcandempsey.net/qotd-the-professional-conservatism-of-professors/
Last updated: 2022-11-08T16:47:07.000Z
I bought the much-noticed *[The marketplace of ideas: reform and resistance in the American university](https://www.worldcat.org/title/marketplace-of-ideas-reform-and-resistance-in-the-american-university/oclc/286488147?ref=lorcandempsey.net)* by Louis Menand in our very congenial local Border’s this morning. I will have to stop going in there to buy the paper 😉 Thanks to Google Book Search, here is a quote from page 15\. What can he mean?
[](https://books.google.com/books?id=g40PA9AIKPUC&lpg=PP1&dq=menand&pg=PP1&ref=lorcandempsey.net#v=onepage&q&f=true)
Incidentally, I noticed that Border’s were promoting the Sony Reader. I wonder are they making way for the Kobo Reader, soon to appear (see [this NYT piece](https://bits.blogs.nytimes.com/2009/12/15/borders-and-kobo-will-develop-new-e-reader/?ref=lorcandempsey.net) from the end of last year on Border’s and Kobo).
### A web-siting at The University of Rochester
URL: https://www.lorcandempsey.net/a-web-siting-at-the-university-of-rochester/
Last updated: 2020-10-28T09:10:47.000Z
I was struck by several things on the [home page](https://www.library.rochester.edu/?ref=lorcandempsey.net) of The River Campus Libraries of the University of Rochester
One was the cover flow display of a small selection of new books. It may not provide a very full experience but it is a nice hook and links to more. Another was the conveniently visible listing of libraries, opening times and notices in the upper right hand corner (although I was disappointed that the clock was not actually telling the time).
However, what prompts the blog entry is an aspect of the prominently featured search. There is a tabbed single box search of the type we are becoming increasingly accustomed. Tabs provide access to the catalog, to articles, and so on. Here is the *Catalog* search which is the current default open tab.
[](https://www.library.rochester.edu/?ref=lorcandempsey.net)
Note the additional suggestions on the right: ‘related links’. It points to additional resources of potential interest to somebody searching the catalog.
Here is the *Course resources and reserves* tab (can’t link direct to tab):

Here the ‘related links’ point to BlackBoard, and to information about copyright and placing course materials on reserve.
This is simple but useful – it places potentially useful materials unobtrusively in the workflow.
Incidentally, I was interested to see that they placed the catalog first. I wonder what drove this decision …..
### More cover notes ...
URL: https://www.lorcandempsey.net/more-cover-notes/
Last updated: 2020-10-28T09:10:50.000Z
**One of three …**
[](https://www.worldcat.org/title/books-do-furnish-a-room/oclc/58828028?ref=lorcandempsey.net)There was a [well publicized](https://online.wsj.com/article/SB10001424052748703862704575099843278537022.html?mod=googlenews%5Fwsj&ref=lorcandempsey.net) spat between Anna Ford and Martin Amis which included some discussion of the latter’s behavior at the deathbed of the former’s husband, Mark Boxer. Coincidentally, somebody asked me last week if I had read any of the books in the *A dance to the music of time* series by [Anthony Powell](https://www.worldcat.org/wcidentities/lccn-n80-39364?ref=lorcandempsey.net). Coincidental, because Boxer famously provide cover illustrations for the series. My answer to the question was that, yes, I had read some of them, and whereas I could clearly remember the covers I could actually remember very little – or nothing – of the content of the books themselves. That this is not uncommon is I suppose not unsurprising.
**Two of three …**
I wrote recently …
> Also on display in Heffer’s was a table full of David Pearson’s *Books as History* which I mentioned [in these pages](https://blog.oclc.org/lorcand/archives/001789.html?ref=lorcandempsey.net) a while ago. His theme, I suggested, was that artifactual properties of books have historic, aesthetic or other interest independent of the texts they convey. Appropriately enough, then, you could buy a signed copy of the book.
> In recent months, since reading David’s book, I have been more conscious of the physical properties of the books I come across. And wandering around Heffer’s, I did wonder if there was an increased focus on interesting covers or formats for some publishers, of which the Virago and Persephone books were striking examples. \[[Cover notes](https://blog.oclc.org/lorcand/archives/002056.html?ref=lorcandempsey.net)\]
[](https://www.worldcat.org/title/writers-britain/oclc/317473440?ref=lorcandempsey.net)I saw the nicely covered [*A writer’s Britain*](https://www.worldcat.org/title/writers-britain/oclc/317473440?ref=lorcandempsey.net) by [Margaret Drabble](https://www.worldcat.org/wcidentities/lccn-n79-55075?ref=lorcandempsey.net) a while ago. The attraction of the cover certainly created additional incentive. But I resisted buying it until today, when Border’s lured me out with their 40% Rewards Coupon. (For full effect, the back of the book has to be seen alongside the front.)
**Three of three …**
[](https://hitone.wordpress.com/2009/08/02/riverrun-covers/?ref=lorcandempsey.net)Via [@eoinpurcell](https://twitter.com/eoinpurcell?ref=lorcandempsey.net) I came across the wonderful [*Vintage Irish book covers*](https://hitone.wordpress.com/?ref=lorcandempsey.net) blog. And from there, I found the [website](https://www.hitone.ie/?ref=lorcandempsey.net) of its author, book and music cover designer, Niall McCormack. Many of the book covers on the blog are familiar and powerfully evoked other times and places.
Related entries:
- [Cover notes](https://blog.oclc.org/lorcand/archives/002056.html?ref=lorcandempsey.net)
- [Book covers and the scholarly record](https://blog.oclc.org/lorcand/archives/001913.html?ref=lorcandempsey.net)
- [The book and the cover up](https://blog.oclc.org/lorcand/archives/001815.html?ref=lorcandempsey.net)
- [Pick up a penguin, nostalgically](https://blog.oclc.org/lorcand/archives/001190.html?ref=lorcandempsey.net)
### Lam-inating libraries ....
URL: https://www.lorcandempsey.net/lam-inating-libraries/
Last updated: 2020-10-28T09:10:52.000Z
The shared interests between libraries, archives and museums (LAMs) is an important [line of work](https://www.oclc.org/research/activities/lamsurvey/default.htm?ref=lorcandempsey.net) for OCLC Research.
However, a related issue is also of considerable interest for libraries. As we move into a digital environment, library work increasingly needs to understand and benefit from archival and museum perspectives.
As libraries digitize primary materials, or as they begin to curate research data or learning materials, an archival perspective becomes more important. Provenance and context are of interest, and changes to resources over time need to be tracked and managed. The value of resources as **evidence** becomes central.
As libraries provide access to abundant digital materials, how to selectively present them or to construct narratives around them becomes more critical. The notion of **exhibition** comes into play, a central museum activity.
### Institutional sourcing ...
URL: https://www.lorcandempsey.net/institutional-sourcing/
Last updated: 2020-10-28T09:10:55.000Z
There was a nice [press release](https://www.manchester.ac.uk/aboutus/news/display/?id=5573&ref=lorcandempsey.net) last week about the digitization of a Chaucer manuscript at [Petworth House](https://www.nationaltrust.org.uk/main/w-vh/w-visits/w-findaplace/w-petworthhouse/w-petworthhouse-photo%5Fgallery.htm?ref=lorcandempsey.net) by staff from The University of Manchester’s [John Rylands Library](https://www.library.manchester.ac.uk/?ref=lorcandempsey.net).
I was interested to see the notes about the role of the library:
> It is part of a 18-month project – funded by JISC – which showcases The University of Manchester as one of the country’s leading centres for digitisation of rare books, manuscripts and archives. …
> The Centre of Digital Excellence will support universities, colleges, libraries and museums which lack the resources to carry out the specialised work. …
> Assistant Librarian Carol Burrows, from The University of Manchester, manages the project. She said: “We’re very excited to be working with the National Trust to launch this project.
> “No other organisation in the north of England specialises in the object-centred digitisation of heritage materials.
> “As the set-up costs of such facilities are prohibitive for most institutions, many can’t afford to carry out this sort of work.
> “Over the eighteen months, we will be investigating whether a Centre for Heritage Digitisation, based within The University of Manchester, will work as a commercial concern.
> “By locating the Centre within the University we will be able to draw on our exceptional body of skills and expertise.”
> Ben Showers, programme manager at JISC, said: ” What makes this project so exciting is that not only will the John Rylands Library be working with other organisations to make available online some rare and important scholarly works.
> “But they will also be exploring business models for the long term viability of digitisation.
> “JISC’s funding of this centre of excellence will help support smaller cultural organisations such as university or college archives and libraries
> “It will make available precious resources that the organisations themselves may not have the skills, resources or simply the time, to put online.” \[[Canterbury Tales to be captured on camera](https://www.manchester.ac.uk/aboutus/news/display/?id=5573&ref=lorcandempsey.net)\]
I was interested in this because it was an example of the type of [scaling and sourcing](https://blog.oclc.org/lorcand/archives/002058.html?ref=lorcandempsey.net) decisions that are going to be central to libraries over the next few years.
Most institutions do not have the scale to develop the type of digitization capacity discussed above. It will be interesting to see if there is the volume of activity and the interest in sourcing it with the John Rylands Library at the University of Manchester to make this type of commercial activity viable. Presumably, the University of Manchester decided that it did want to invest in local capacity but also wanted to explore how to spread that cost.
### Data wells: one big index
URL: https://www.lorcandempsey.net/data-wells-one-big-index/
Last updated: 2020-10-28T09:10:57.000Z
I was interested to hear the concept of a ‘data well’ discussed when I was in Sweden the other week.
It seems to be used in the sense of an infrastructure to ingest, normalise and provide integrated access to multiple streams of data. In this way, library services can be built on a consolidated data resource, rather than having to actively manage the integration as a part of those services (as happens now in the metasearch model).
The idea of a data well is integral to the [Ting project](https://gnit.dk/?ref=lorcandempsey.net) (mentioned [in these pages](https://blog.oclc.org/lorcand/archives/002065.html?ref=lorcandempsey.net) the other day), collaboratively sourced data and systems infrastructure for Danish public libraries. It was also the subject of a [tender](https://www.deff.dk/content.aspx?catguid={61D333DB-11A7-4029-AAED-9CDC62036E01}&ref=lorcandempsey.net) from DEFF, the Danish Electronic Research Library, earlier this year. In the latter case, the starting point was metadata for journal articles and ebooks.
This is clearly in line with the trend we have seen recently towards consolidation of the fragmented database infrastructure to support a better user experience. Google Scholar was an important stimulus for this activity.
In thinking about this direction a few years ago I asked a question about where this was going to happen …
> Another approach is to consolidate data resources into larger reservoirs. This has the advantage of reducing the burden of integration, and enhancing the ability to create value-added services. But how and at what level could this be done? \[[Metasearch, Google and the rest](https://blog.oclc.org/lorcand/archives/000615.html?ref=lorcandempsey.net)\]
The Danish examples are of national infrastructures (although the actual creation could be sourced with other suppliers). ‘Data wells’ of the type discussed here are also under construction by OCLC, Serials Solutions (Summon), Ebsco, Elsevier, and Ex Libris, among others. And Google Scholar continues to operate.
Two thoughts. One: the focus now is on integration; it will have to shift to creating value-added service over those integrated resources. Such added value may be created by the integrators, libraries and others. And two: how many such data wells are required?
I was interested that the two previous blog entries I was thinking of as I wrote this one are five years old! Here they are:
- [Metasearch: a boundary case](https://blog.oclc.org/lorcand/archives/000768.html?ref=lorcandempsey.net)
- [Metasearch, Google and the rest](https://blog.oclc.org/lorcand/archives/000615.html?ref=lorcandempsey.net)
### Dublin core: the first fifteen years ...
URL: https://www.lorcandempsey.net/dublin-core-the-first-fifteen-years/
Last updated: 2020-10-28T09:10:58.000Z
The Dublin Core Metadata Initiative celebrated fifteen years of existence on March 1st.
The initiative began at a [workshop](https://dublincore.org/workshops/dc1/?ref=lorcandempsey.net) in Dublin, Ohio, jointly organized by OCLC and NCSA. The [second workshop](https://dublincore.org/workshops/dc2/?ref=lorcandempsey.net) inaugurated the series which has continued to this day morphing into the annual conference along the way. It was jointly organised by [OCLC](https://www.oclc.org/research?ref=lorcandempsey.net) and [UKOLN](https://www.ukoln.ac.uk/?ref=lorcandempsey.net), at the University of Warwick.
I attended some of the earlier meetings as a participant, although my main involvement has been administrative, early on with UKOLN and latterly at OCLC. In addition to staff contributions, OCLC continued to financially support the initiative until last year when DCMI was established as an independent entity.
The Dublin Core is now widely used, and discussions about development, deployment and improvement continue. Many people and organizations around the world have worked on it. I am sure that they would all feel it is appropriate to acknowledge the central contribution of Stu Weibel. Stu’s persistence, consensual skills and emotional investment, working with his then OCLC colleague, Eric Miller, was vital to the early momentum and continued existence of the initiative.
A note on involvement ….
- [OCLC Research and the Dublin Core Metadata Initiative](https://www.oclc.org/research/activities/past/orprojects/dublincore/default.htm?ref=lorcandempsey.net)
- [UKOLN contribution to DCMI](https://www.ukoln.ac.uk/metadata/dcmi/?ref=lorcandempsey.net)
### QOTD: a new Alexandria
URL: https://www.lorcandempsey.net/qotd-a-new-alexandria/
Last updated: 2020-10-28T09:11:01.000Z
An interesting article – [Toward a new Alexandria: imagining the future of libraries](https://www.tnr.com/article/books-and-arts/toward-new-alexandria?ref=lorcandempsey.net) – by Lisbet Rausing has just appeared in *The New Republic*. It discusses the continuity of the scholarly record in a richly allusive text. I sensed three strands. First, the scholarly record is evermore diffused through media and formats, embracing source materials, and presents changes of identification and curation. Second, the licensed journal literature is enclosed behind paywalls, and current developments may extend that fate to the book literature. And third, the relevance of the scholarly record to the wider world and to future generations, and the influence of researchers, is diminished by this lack of access. Interestingly, in highlighting the responsibility of libraries, the author notes the necessity of collaborative attention and action. Here is a flavor:
> Imagine a new Library of Alexandria. Imagine an archive that contains all the natural and social sciences of the West–our source-critical, referenced, peer-reviewed data–as well as the cultural and literary heritage of the world’s civilizations, and many of the world’s most significant archives and specialist collections. Imagine that this library is electronic and in the public domain: sustainable, stable, linked, and searchable through universal semantic catalogue standards. …
> … It is clear that if a new Alexandria is to be built, it needs to be built for the long term, with an unwavering commitment to archival preservation and the public good. A true public good itself, it probably needs to be largely governmentally funded. And, while a global and cooperative venture, it needs to be hosted by one organisation that is reputable, long-standing, nonprofit, and exists in a stable jurisdiction. The Library of Congress, the flagship institution of the world’s only surviving Enlightenment republic, comes to mind. There might be other possibilities, such as the New York Public Library, or the British Library, or a consortium of the world’s leading university libraries–UCLA, Harvard, Cambridge University, and so on. \[[Toward a new Alexandria: imagining the future of libraries](https://www.tnr.com/article/books-and-arts/toward-new-alexandria?ref=lorcandempsey.net)\]
She discusses the changing scholarly record and the challenges of assuring continuity of access ..
> Scholars rightly argue that we cannot meaningfully analyze our peer-reviewed knowledge without also archiving its primary sources. But today’s knowledge quest is universal: Our primary sources encompass all the knowledge, hopes, and dreams of humanity. Our Alexandria was not burnt, our Byzantium still stands, and our Athenian academies are blossoming. And in addition to the near-infinitude of our scholarly endeavours and their materials, we want to preserve that which we have not yet incorporated into our learned canons: the near-extinct and the barely remembered, the oral traditions and the dying languages, the esoteric and the sacred–the reviled, even–and the persecuted. We want the Nazi state papers and the Lodz ghetto archives, the Soviet encyclopedias and the samizdat literature, the Maimonides commentaries and the Genizah fragments, the Ethiopians’ church songs and their memories of the recent famines….
> … You see the problem. What is the library, when the totality of experience approaches that which can be remembered? What is it when we no longer preserve only those fragments that time, fire, and barbarians have left us? When we are no longer are able to safeguard only remnants of our discourses on thought, memory, and images, but the thoughts, memories, and images themselves–complete? What do we do when we have not only the Lives of the Most Excellent Painters, Sculptors, and Architects, but also Vasari’s blog, wiki, twitter, texts, emails, chatroom, Facebook, radio interviews, TV appearances, and electronic notebooks? \[[Toward a new Alexandria: imagining the future of libraries](https://www.tnr.com/article/books-and-arts/toward-new-alexandria?ref=lorcandempsey.net)\]
She goes on to talk about publishing and the scholarly record: “their success in locking up and rendering irrelevant the output of academic research has been nothing less than astonishing”. The article talks about open access and copyright. Interestingly, she positions the argument to scholars in terms of their relevance.
> If scholars continue to hide away and lock up their knowledge, do they not risk their own irrelevance? An immediately important debate, I think, is to be had over how academics fail to engage with their natural constituency (and former students): journalists, business leaders, lawyers, entrepreneurs, politicians, and civil servants. These people are the ruling classes, if you would like. They are the ones who house and feed professors. Is it really in academics’ long-term interest to not let these well-educated and well-intentioned people as much as glance at, say, the Index of Christian Art? Is it really in their interest not to show the public their scholarly articles and academic monographs? What does this tell the public about who academics think is clubbable? And how will that affect how the public thinks about, say, federal research grants, or top-up fees? \[[Toward a new Alexandria: imagining the future of libraries](https://www.tnr.com/article/books-and-arts/toward-new-alexandria?ref=lorcandempsey.net)\]
Lisbet Rausing is a [historian of science](https://www.arcadiafund.org.uk/content/donorboard.asp?ref=lorcandempsey.net) and [philanthropist](https://www.arcadiafund.org.uk/content/default.asp?ref=lorcandempsey.net). Worth reading in full.
### Ting: collaboratively sourced library infrastructure
URL: https://www.lorcandempsey.net/ting-collaboratively-sourced-library-infrastructure/
Last updated: 2020-10-28T09:11:07.000Z
Ting is an initiative which is creating a shared systems and data infrastructure for Danish public libraries – and potentially others. At its heart is a ‘data well’, an enriched aggregate of data (see a list of data sources [here](https://spreadsheets.google.com/pub?key=pi2Jrn8MRdkjw44KxoR-WLw&ref=lorcandempsey.net)). Another important component is Ding, a Drupal-based content management system for presenting library resources.
Libraries currently participating are [Copenhagen](https://bibliotek.kk.dk/?ref=lorcandempsey.net) and [Aarhus](https://aakb.dk/?ref=lorcandempsey.net) public libraries. They are working with [DBC](https://www.dbc.dk/english?ref=lorcandempsey.net), the provider of the Danish union catalog, [bibliotek.dk](https://bibliotek.dk/?ref=lorcandempsey.net), among other services,
[](https://aakb.dk/?ref=lorcandempsey.net)
Some features of the websites are described on the [Ting blog](https://gnit.dk/2010/01/27/beta-release-af-kkbs-og-akbs-nye-hjemmesider/?ref=lorcandempsey.net). I liked the emphasis on the integration between website and database. Facets are on top of the results display rather than on the side. There is some work-based clustering. There is a nice suggestion feature on the search box.
Here is a high-level architectural view:
[](https://gnit.dk/wp-content/uploads/2008/11/diagram-over-ting-konceptet1.jpg?ref=lorcandempsey.net)
Ting is an interesting initiative. I do not have a lot of context to assess it. I do not know how well its aggregation of data will compare with others and I only spent a little while looking at the library websites. It provides an example of the shared approach I [recently suggested](https://blog.oclc.org/lorcand/archives/002058.html?ref=lorcandempsey.net) would become more important. I was introduced to it last week in a nice presentation by Mats Hernvall at a [meeting](https://www.biblioteksforeningen.org/konferens/Konf2010/informationstjanster/konf.html?ref=lorcandempsey.net) in Lund. He discussed the importance of scale and collaboration in developing library services and noted that DBC were interested in further partnerships.
Note: updated from beta to production URLs for the library websites.
### Mission of the library redux
URL: https://www.lorcandempsey.net/mission-of-the-library-redux/
Last updated: 2020-10-28T09:11:09.000Z
I heard Anders Söderbäck of the Royal Library in Sweden [speak](https://www.biblioteksforeningen.org/konferens/Konf2010/informationstjanster/konf.html?ref=lorcandempsey.net) in Lund last week on the perennial topic ‘what is a library’. He reminded us of Daniel Dennett’s remark:
[ A scholar is just a library’s way of making another library. ](https://www.freebase.com/view/guid/9202a8c04000641f800000000fd49202?ref=lorcandempsey.net)

This in turn reminded me of a post I did here a while ago about Dan Chudnov’s definition of the mission of the library:
> Dan Chudnov has an interesting post on the mission of the library. What is the all-consuming mission of the library? His answer is an interesting one, which on reflection works surprisingly well. He argues that his professional mission as a librarian is this:
>
>> Help people build their own libraries.
>> \[[Because this is the business we’ve chosen | One Big Library.](https://onebiglibrary.net/story/because-this-is-the-business-weve-chosen?ref=lorcandempsey.net)\]
>
> What I like about this is that it – if I understand it correctly – covers emerging as well as current scenarios. Examples: to help with the creation, organization and curation of locally created materials, or to help with shared bookmarking/citation management/reading list services. As I suggest [elsewhere](https://www.ariadne.ac.uk/issue46/dempsey/?ref=lorcandempsey.net) we are developing a new vocabulary of collections: playlists, reading lists, repository, … \[[Hedgehogs](https://blog.oclc.org/lorcand/archives/000961.html?ref=lorcandempsey.net)\]
Here is [Daniel Dennett](https://www.worldcat.org/wcidentities/lccn-n81-89168?ref=lorcandempsey.net) in Worldcat Identities.
Related entry:
- [What is the library](https://blog.oclc.org/lorcand/archives/000443.html?ref=lorcandempsey.net)
### The context web
URL: https://www.lorcandempsey.net/the-context-web/
Last updated: 2020-10-28T09:11:12.000Z
In preparing some recent presentations I have been talking about three primary ways of experiencing the web which emerged successively and continue to work together. Here I will call them the site-web, the search-web, and the context-web (alternatives might be site-centric, network-centric, and user-centric).
**Site-web.** Our early experience of the web tended to focus on individual websites. Enumeration of websites was common, in lists, directories and guides.
**Search-web.** Attention soon shifted to the network of websites as a whole and search quickly emerged as central to our web experience. Google rose to prominence based on the insight – expressed in its pagerank algorithm – that not all websites are equal.
Search is now our primary way of finding resources and navigating the web. This was underlined, I think, by the introduction of the single box in the Chrome browser for both URL entry and search. A while ago, I was looking for something with my son. He was amused that I was typing in a longish URL – search is how he goes to everything, even where he knows the URL.
**Context-web.** It seems to me that we are now moving to what I call for my purposes here the context-web. Search remains important but is no longer enough. We expect services not only to know about resources on the web, but also to know about us. We are seeing servces contextualised by their knowledge of people using those services and their relationships. Think about how Google is incorporating location- and social-based results in their searches. If I search for cameras, I will be shown mapped results from near Dublin Ohio and I will be shown what people in my ‘social circle’ are saying about cameras (my ‘social circle’ is what Google knows about people in my social networks – Twitter and so on). As the recent controversy about Buzz showed, Google knows quite a bit about me through my use of is services (I regularly use Search, Reader and Gmail, and dip into other services).
Facebook and Twitter also know something about me. As does Microsoft, where I have a Zune profile where I can ‘friend’ my son who has an Xbox profile (and indeed I can see his Xbox friends).
Much of the current competition we see between the big web/media companies relates to the management of our context. Google, Microsoft, Twitter, Facebook and Apple would like to be able to mobilize our context to provide more valuable services.
### Working organizations
URL: https://www.lorcandempsey.net/working-organizations/
Last updated: 2020-10-28T09:11:15.000Z
Via [@psychemedia](https://twitter.com/Psychemedia?ref=lorcandempsey.net) I saw this advert for a CIO at the Open University in the UK. I thought it was interesting for a couple of reasons. The first was the language which seemed more ‘upbeat’ than you normally see in academic institutions (but maybe I am just out of touch ;-). For example:
> First-class communication skills must accompany a global mindset leveraging strategic skills but accompanying them with a real propensity to action. The obvious challenge of this role, in this organisation, will ignite your enthusiasms. \[[Job details – Chief Information Officer](https://www3.open.ac.uk/employment/job-details.asp?id=5031&ref=lorcandempsey.net)\]
The second was the emphasis on being able to succeed in complex organizational settings, and the influencing skills required. As you would expect the job requests a focus on results, customer focus and a sense of strategic direction. But it was interesting to see how some of the organizational issues were discussed …
> This individual must be able to empathise with the differing demands of leadership where both commercial and social missions need to be clearly understood. They must possess a strong executive presence and be capable of engaging with, and,
> where appropriate, pushing back on business unit leaders in a way that is constructive and positive. They should not use the language of technology with their peers, but focus more on the implications for the University. They should naturally simplify the complex when they explain initiatives and projects.
And then the explicit mention of organizational boundaries:
> Being prepared to break down existing organisational boundaries through collaboration and cross staffing by building strong relationships based on trust with peers. \[[Candidate brief – PDF](https://apply.odgers.com/30858/30858%5FCandidate%5FBrief.pdf?ref=lorcandempsey.net)\]
I should note that I don’t have any understanding of the internal specifics here.
A couple of obvious things. Getting things done in larger organizations – where an agreed direction may depend on buy-in from multiple stakeholders – is certainly very different than it is in smaller ones where decision-making ability may be more concentrated. At the same time, it seems to me that an ability to actually get things done, and to make organizations better able to get things done, are things that have come up more in the occasional discussions I have with recruiters.
### Name, rank and serial number
URL: https://www.lorcandempsey.net/name-rank-and-serial-number/
Last updated: 2020-10-28T09:11:17.000Z
As authors are recognised as resources to be discovered, managed, ranked, and tracked, an interest in names and identifiers will continue to grow. A focus on research evaluation, reputation management, publication management drive this, as well as general information management issues in a web environment.
Historically, national libraries have managed names within their jurisdictions. The *LC Working Group on the Future of Bibliographic Control* recognized that this was a partial activity, partial in two ways. First, a national approach may not make sense in a networked world: national scale policies and coverage do not work very well at webscale. Individual files are incomplete, and there is overlap between files, sometimes with different versions of names being established and so on. And second, we are interested in many more names than are captured in the cataloging process: some researchers, for example, may only publish articles and not get captured in authority work.
Working with several national libraries we manage the [VIAF project](https://www.viaf.org/?ref=lorcandempsey.net) which is a response to the first of these issues. As part of the VIAF process we match and link names across national authority files. This resource is then made available in [several](https://outgoing.typepad.com/outgoing/2009/09/viaf-as-linked-data.html?ref=lorcandempsey.net) ways.
The second issue represents a different sort of challenge. We have recently seen two initiatives of importance emerge in the name identifier space, [ISNI](https://www.isni.org/?ref=lorcandempsey.net) and [ORCID](https://orcid.securesites.net/?ref=lorcandempsey.net). How the relationship between these evolves remains to be seen: they involve different players and starting motivations. OCLC is participating in each and we look forward to working with VIAF data to further their goals, and in turn to see how VIAF data might be enriched or extended in the process.
My colleague Thom Hickey – who manages VIAF – has a [brief article](https://www.oclc.org/nextspace/013/research.htm?ref=lorcandempsey.net) about the project in a recent issue of NextSpace.
### Sourcing and scaling
URL: https://www.lorcandempsey.net/sourcing-and-scaling/
Last updated: 2020-10-28T09:11:21.000Z
One of the major issues facing libraries as the network reconfigures processes is how appropriately to source and scale activities. What does it make sense to do at institutional level, what does it make sense to source elsewhere (repository services in the cloud, for example, or insitutional email services from Google), and what should be left entirely to other providers?
I [discussed](https://blog.oclc.org/lorcand/archives/002015.html?ref=lorcandempsey.net) ‘scaling’ from the supply side – what libraries do and how – a while ago when discussing a NISO report on resource management ..
> **Scalar emphasis** has become an important question for libraries. At what scale should things be done as institution-scale is increasingly the wrong level for many activities? Oren \[Beit-Arie\] discusses the transitional effect of the network in broader collaborative settings, where the power of the network can be leveraged to improve services. Shared cataloging and resource sharing may be earlier instances of this. Consider now the potential for recommendations where circulation or other usage data is aggregated at a higher level. Consider incentives also in this context. Where are library users most likely to want to invest their effort? Kat Hagedorn \[[ppt](https://www.niso.org/apps/group%5Fpublic/download.php/2891/hagedorn%5Flrms09niso.ppt?ref=lorcandempsey.net)\] discusses a collaborative project of the HathiTrust, New York University, and the partners in the ReCAP shared print facility with the involvement of OCLC Research and CLIR. What policy and service apparatus needs to be in place to provide confidence of supply from HathiTrust and ReCAP sufficient to allow NYU relegate materials from its own collection? Such ‘cloud library’ provision will become more common as libraries seek to transfer resource away from ‘infrastructure’ and towards user engagement. Kyle Bannerjee describes \[[ppt](https://www.niso.org/apps/group%5Fpublic/download.php/2884/banerjee%5Flrms09niso.ppt?ref=lorcandempsey.net)\] Orbis Cascade’s work with OCLC on the integration of local, consortial and global discovery and delivery of resources. He suggests that such operations should move to the highest appropriate level in the network, and speculates about what other services should also move to the network level. Rachel Bruce \[[ppt](https://www.niso.org/apps/group%5Fpublic/download.php/2888/bruce%5Fsiteversion%5Flrms09niso.ppt?ref=lorcandempsey.net)\] looks at library systems from the point of view of national-scale ‘shared services’. What these and other presentations show is how decisions about level of operation – personal, local, consortial, national, global – are as important as particular discussions of functionality or sourcing. Libraries face interesting choices about sourcing – local, commercial, collaborative, public – as they look at how to achieve goals, and as shared approaches become more crucial as resources are stretched. \[[Untangling the library systems environment](https://blog.oclc.org/lorcand/archives/002015.html?ref=lorcandempsey.net)\]
Such decisions are going to become more important, as externalization becomes more feasible and more attractive. There at least two dimensions which may be interesting to spell out.
Following from the note above, I label the first **scalar emphasis**: at what level is it appropriate to get things done. For simplicity here are three scales:
1. Institution-scale. Activity is managed within an institution with a local target audience.
2. Group-scale. Activity is managed within a supra-institutional domain whether this is a region, a consortium, or a state or a country. The audience is correspondingly grouped. In educational terms think of the activities of JISC in the UK or SurfNet in the Netherlands. In library terms think of the Hathi trust, or of Georgia Pines, or of OhioLink.
3. Web-scale. Activity is managed at the network level where we are now used to services like Amazon, Flickr, Google and YouTube provide e-commerce, collection, discovery and other functions. Here, the audience is potentially all web users.
We have seen more activity in 2 and 3 in recent years. There has been stronger consortial activity and libraries have been looking at how to exploit webscale services more (think of knowledge-base data in Google Scholar, for example, or links to special collections materials added to Wikipedia).
This then raises a sourcing decision. Again, consider three possible ways in which a product or service might be sourced:
1. Institutional. Activity is developed locally.
2. Collaborative. Activity is developed in concert with partners (e.g. purchasing consortium, shared offsite storage, open source software, ..).
3. Third party. Activity is secured from a third party service (e.g. e-journal access). A third party might be a commercial or not for profit supplier, or it might be a public provider, as a part of state or national provision. The latter is especially important in those jurisdictions where some library infrastructure may be provided as part of educational or cultural funding (see Rachel Bruce’s presentation above, for example).
As the network reduces transaction costs, it is now simpler to externalize in this way. The reduced cost and effort of collaboration and of transacting with third parties for services has made these approaches more attractive and feasible. There are also scale advantages. Although it has become common to talk about moving services to the cloud it is important to remember that important choices still have to be made. And there may not always yet be good options as the environment continues to evolve. Decisions about scaling and sourcing will be interesting for several years to come.
### Scientific publications as social objects ...
URL: https://www.lorcandempsey.net/scientific-publications-as-social-objects/
Last updated: 2020-10-28T09:11:23.000Z
The Comprendia Blog has an entry about social networks in the sciences: [Are Any Social Networks for Life Scientists Gaining Traction?](https://comprendia.com/2010/02/11/social-networks-for-life-scientists-gaining-traction/?ref=lorcandempsey.net)
It is a report of a ‘quick and dirty’ analysis of visitors to a range of sites. Not everything you might expect is included; Mendelay for example does not feature because of its local component.
> As I mentioned, this is a quick analysis, and I invite others to copy the data and add to it (here’s the [Google Spreadsheet](https://spreadsheets.google.com/ccc?key=0AhhofTutX0ZudFVqRXpNMDFETkEyQ2dVQ2o1UURzbmc&hl=en&ref=lorcandempsey.net)), but a clear trend emerged from this short study. The top site, [biomedexperts.com](https://www.biomedexperts.com/?ref=lorcandempsey.net), which has an estimated 128,000 visitors per month, utilizes scientific publications to connect and segment scientists based on interests or regions. The second most popular site, [citeulike.org](https://citeulike.org/?ref=lorcandempsey.net), is a social bookmarking site with about 100,000 visitors per month who use it to search for, store, and browse related peer-reviewed publications. What’s interesting is that these sites are based on completely different formats, but they both rely on scientific publications.
> Is it surprising that scientific publications are the ‘glue’ that is connecting and attracting scientists? Not really-when I think back to my days in the 90’s as a bench scientist, [PubMed](https://www.ncbi.nlm.nih.gov/pubmed/?ref=lorcandempsey.net) and my many folders of papers were what helped me to connect with other scientists and learn who the thought leaders of my field were. **In a sense, PubMed was scientists’ first ‘social network.’** \[[Comprendia](https://comprendia.com/2010/02/11/social-networks-for-life-scientists-gaining-traction/?ref=lorcandempsey.net)\]
An important strand in discussion of networks suggests that people connect and share themselves through ‘social objects’, pictures, books, or other shared interests, and that successful social networks are those which form around such social objects. Think of LibraryThing or GoodReads and books, or Flickr and photographs. What I thought was interesting in the post was the focus on the incentives required to create network effects and a suggestion that these related to making connections around ‘social objects’, in this case scientific publications. It is also interesting to see the suggestion that the literature itself has always had this social element.
There is also a link to an interesting post by Cameron Neylon ‘[What should social software for science look like](https://blog.openwetware.org/scienceintheopen/2009/12/09/what-should-social-software-for-science-look-like/?ref=lorcandempsey.net)‘ which discusses various scientific research outputs as social object.
Related entries:
- [Some thoughts about egos, objects and social networks …](https://blog.oclc.org/lorcand/archives/001601.html?ref=lorcandempsey.net)
- [Community is the new content](https://blog.oclc.org/lorcand/archives/002013.html?ref=lorcandempsey.net)
- [A signed network presence: people as entry points again](https://blog.oclc.org/lorcand/archives/001873.html?ref=lorcandempsey.net)
- [Social tools and science](https://blog.oclc.org/lorcand/archives/002025.html?ref=lorcandempsey.net)
### Cover notes
URL: https://www.lorcandempsey.net/cover-notes/
Last updated: 2020-10-28T09:11:26.000Z
And speaking of *The Second Sex* reminds me that the [Penguin Modern Classic edition](https://www.worldcat.org/oclc/59144780?ref=lorcandempsey.net) is one of those books with an iconic [cover](https://www.amazon.co.uk/gp/product/images/0140034633/ref=dp%5Fimage%5Ftext%5F0?ie=UTF8&n=266239&s=books&ref=lorcandempsey.net) which enters deep into the book memory. (Although i could not find this book or its cover on various Penguin sites earlier, which seemed a shame.)
The weekend issue of the *Financial Times* carries a nice column devoted to interesting book covers. Unfortunately, only a [few recent ones](https://www.ft.com/arts/books/cover?ref=lorcandempsey.net) are listed on their web pages as far as I can see. I occasionally look at the interesting [Book covers anonymous](https://bookcoversanonymous.blogspot.com/?ref=lorcandempsey.net). I was struck by the very effective use of cover art on different pages in the [Faber blog](https://www.thethoughtfox.co.uk/?ref=lorcandempsey.net) the other day when I came across it.
Thinking about covers in this way prompts me to present here again the text of an entry on book covers I wrote in November 2008:
I spent a couple of hours in Heffer’s in Cambridge a while ago. Turning a corner I was pleasantly surprised by a set of handsome books in fine covers especially set out for inspection. It turned out they were a special issue to mark the 30 year anniversary of the Virago Modern Classics.
[](https://www.littlebrown.co.uk/NewsEvents/News-Archive/Virago-Modern-Classics?ref=lorcandempsey.net)
> 2008 is the 30th anniversary of the Virago Modern Classics. To celebrate this occasion, we’ve produced a stunning set of eight hardbacks, featuring cover artwork by twentieth-century women textile designers, including Lucienne Day, Cath Kidston, Orla Kiely, Celia Birtwell, and founder of Biba, Barbara Hulanicki. This stylish collection, celebrating literature and art by women in the twentieth century even featured in the Sunday Times style barometer (going up, of course). \[[Virago Modern Classics – Little, Brown Book group](https://www.littlebrown.co.uk/NewsEvents/News-Archive/Virago-Modern-Classics?ref=lorcandempsey.net)\]
I do not know the background here, or the history of Virago in recent years. And certainly, that last sentence seems out of synch with its founding ethos. The iconic green covers loom large in my book memory.
> I consulted my colleagues, my fixation reaching such a degree that poor Harriet tells of me pinning our designer to the wall, demanding five colour covers, exquisite paper, washed tops, strings, and every production frill for my beloved new idea. Penguin used a serious male thinker – Isaac Newton? – to advertise their classics. The Virago Modern Classics list was meant to be more ebullient, a library of women’s fiction with Boadicea rather than Newton waving the flag. I chose green because it was neither blue for a boy nor pink for a girl. I saw in my mind rows of green paperbacks with luscious covers on all the bookshelves of the world. \[[Carmen Callil on Virago Modern Classics | Books | The Guardian](https://www.guardian.co.uk/books/2008/apr/26/featuresreviews.guardianreview2?ref=lorcandempsey.net)\]
[](https://www.littlebrown.co.uk/Title/9781844085262?ref=lorcandempsey.net)I immediately bought the [Barbara Pym](https://www.orlakiely.com/?ref=lorcandempsey.net) from the anniversary set. Barbara Pym is being read in our house at the moment and [Orla Kiely](https://www.orlakiely.com/?ref=lorcandempsey.net), a focus of our daughter’s unfulfilled consumer interest for a while, designed the cover. It is a nice object to own.
Near these books was a selection from the publisher [Persephone Books](https://www.persephonebooks.co.uk/index.htm?ref=lorcandempsey.net), and seeing them close by like that I wondered if the Persephone approach had influenced the Virago anniversary editions.
> We have given much thought not only to the choice of titles we will publish but also to ‘what women want’. Our books look beautiful because we believe that, whether they are on an office desk, by the Aga, or hanging in a bag over the handles of a buggy, it is important to get pleasure from how they look and feel….
> …Fabrics are as much a part of our daily lives as furnishing and dress materials, yet we rarely see them used in any other context. However, fabric design should be celebrated for its own sake; and because it is a field in which women designers have been particularly prominent we would like to use their work whenever possible. \[[Persephone Books, rediscovered twentieth century novels, neglected women writers, twentieth century female authors, out of print books, inter-war novels](https://www.persephonebooks.co.uk/pages/about/design%5Fand%5Fendpapers.htm?ref=lorcandempsey.net)\]
Also on display in Heffer’s was a table full of David Pearson’s *Books as History* which I mentioned [in these pages](https://blog.oclc.org/lorcand/archives/001789.html?ref=lorcandempsey.net) a while ago. His theme, I suggested, was that artifactual properties of books have historic, aesthetic or other interest independent of the texts they convey. Appropriately enough, then, you could buy a signed copy of the book.
[](https://www.worldcat.org/oclc/123536594?ref=lorcandempsey.net)In recent months, since reading David’s book, I have been more conscious of the physical properties of the books I come across. And wandering around Heffer’s, I did wonder if there was an increased focus on interesting covers or formats for some publishers, of which the Virago and Persephone books were striking examples.
In fact, I nearly bought Simon Armitage’s translation of *Sir Gawain and the Green Knight* because it looked very nice, and had to hurry out of the shop before I got carried away.
Related entries:
- [Book covers and the scholarly record](https://blog.oclc.org/lorcand/archives/001913.html?ref=lorcandempsey.net)
- [The book and the cover up](https://blog.oclc.org/lorcand/archives/001815.html?ref=lorcandempsey.net)
- [Pick up a penguin, nostalgically](https://blog.oclc.org/lorcand/archives/001190.html?ref=lorcandempsey.net)
### The publisher and the translation
URL: https://www.lorcandempsey.net/the-publisher-and-the-translation/
Last updated: 2020-10-28T09:11:29.000Z
I got my copy of *The London Review of Books* in the mail (aka post) today. I had seen John Naughton [discuss](https://memex.naughtons.org/archives/2010/02/08/10065?ref=lorcandempsey.net) the [review](https://www.lrb.co.uk/v32/n03/toril-moi/the-adulteress-wife?ref=lorcandempsey.net) of a new translation of [*The Second Sex*](https://www.worldcat.org/oclc/429598256?ref=lorcandempsey.net) by Toril Moi ([WC Identity](https://www.worldcat.org/identities/lccn-n85-78445?ref=lorcandempsey.net)) and I turned to read it.
The focus of the review is a critique of the translation, a not very good one Moi argues. One thing that struck me while reading it was the role of the publisher. This is especially in the light of current discussions about the publishing value chain as patterns of distribution change in a network environment.
Moi describes dissatisfaction with the [earlier translation](https://www.worldcat.org/oclc/260915?ref=lorcandempsey.net) by H.M.Parshley, partly because it cut out about 15% of the text and partly for aspects of the translation. She cites an article by Margaret Simons drawing attention to the cuts, and notes:
> After reading Simons’s essay, Beauvoir replied: ‘I was dismayed to learn the extent to which Mr Parshley misrepresented me. I wish with all my heart that you will be able to publish a new translation of it.’
> Simons’s discovery had no impact on Random House, which owns the English-language rights to the book through its imprints Knopf (for the hardback) and Vintage (for the paperback). By the time of the 50th anniversary of The Second Sex in 1999, there were still no plans for a new translation: that year, Elizabeth Fallaize and I decided to draw attention to the situation again. Fallaize, whose premature death at the end of last year Beauvoir scholars mourn, analysed the effects of the vast cuts Parshley made in the chapter on ‘The Married Woman’. I wrote about Parshley’s philosophical confusions, drew attention to a number of elementary French mistakes, and showed the way his mistranslations had affected recent feminist theory. I also wrote about the publication history, and stressed that Parshley should not be seen as the villain of the piece. A professor of zoology at Smith College, he was genuinely enthusiastic about Beauvoir’s book. It was the publisher, not Parshley, who insisted on cutting the text; in the end he cut 145 of the original 972 pages, or almost 15 per cent of the original.
> The strength of Parshley’s 57-year-old translation is that it is lively and readable. Parshley was, on all evidence, an excellent writer of English. When he understood the French, he usually found the right phrase and managed to convey nuances of irony and poetry. The most serious weaknesses are the unannounced cuts; but his complete lack of familiarity with Beauvoir’s philosophical vocabulary and the deficiencies in his knowledge of French also undermine his version of the book.
> Demand for a new translation gathered force, but the publishers resisted. In 1988, Ashbel Green, then Knopf’s vice president and senior editor, summarised their view: ‘Our feeling is that the impact of de Beauvoir’s thesis is in no way diluted by the abridgment.’ After all, the book was making money: ‘It’s a very successful book that we want to continue publishing.’
> In August 2004, Sarah Glazer published an article about the situation in the New York Times. Whether her article was the deciding factor is hard to say. In any case, at the end of 2005 Ellah Allfrey, then an editor at Cape, the British publisher of The Second Sex, persuaded Knopf to split the cost of a new translation. According to Le Monde the final cost was €35,000 (£30,000 or $50,000), one third of which was paid by grants from the French state. \[[The adulteress wife. LRB 11 February 2010](https://www.lrb.co.uk/v32/n03/toril-moi/the-adulteress-wife?ref=lorcandempsey.net)\]
New translators were found.
> In a 2007 interview with Sarah Glazer, published in Bookforum, Borde and Malovany-Chevallier dismissed doubts about their competence. They explained that they first heard about the problems with the English translation at the 50th anniversary conference on The Second Sex in Paris. After the conference, they contacted a former student, Anne-Solange Noble, the director of foreign rights at Gallimard, to propose themselves for the job, and in due course Noble told Allfrey that she ‘already knew the perfect translators’.
Based on their earlier work, Toril Moi wonders about the translators’ credentials. She then proceeds to deliver a very strong criticism of the new translation.
Now, it will be interesting to see how the publishers respond to this review, if they do at all, and whether they refute the charge that they have not been good stewards of a major work’s English expression.
### Bruges Public Library catalogue
URL: https://www.lorcandempsey.net/bruges-public-library-catalogue/
Last updated: 2020-10-28T09:11:31.000Z
Prompted by a [recent entry](https://blog.oclc.org/lorcand/archives/002047.html?ref=lorcandempsey.net), I got a note from Koen Calis, Librarian Bruges Public Library, about their catalogue, [Cabrio](https://www.brugge.be/cabrio?ref=lorcandempsey.net). Here is quite a full presentation which covers a range of interesting feature:
[Cabriology The Bruges Aquabrowser Experience](https://www.slideshare.net/kcalis/cabriology-the-bruges-aquabrowser-experience?ref=lorcandempsey.net "Cabriology The Bruges Aquabrowser Experience")
View more [presentations](https://www.slideshare.net/?ref=lorcandempsey.net) from [Koen Calis](https://www.slideshare.net/kcalis?ref=lorcandempsey.net).
I was interested in their adaptation of my colleague Robin Murray’s synthesise/specialise/mobilise framework to frame the discussion. In his note, Koen remarked that “Bruges Public library considers the horizontal discovery of local resources (heritage collections, community information, courses and events, local advisory data…) to be a very important starting point for redeveloping our library into a local knowledge hub and to enhance participation of the local community”.
### Patterns of publication and library collections as measure of technology shifts?
URL: https://www.lorcandempsey.net/patterns-of-publication-and-library-collections-as-measure-of-technology-shifts/
Last updated: 2020-10-28T09:11:36.000Z
We were pleased to [welcome](https://www.oclc.org/research/news/2010-01-28.htm?ref=lorcandempsey.net) [Dr Michelle Alexopoulos](https://www.chass.utoronto.ca/~malex/?ref=lorcandempsey.net) from the University of Toronto to OCLC last week. Michelle is an economist whose recent research has focused on creating and analyzing new measures of technical change for developed economies.
The abstract of her talk gives a flavor of some of this work, and why it was of interest to us:
> Can the patterns of library collections be used to measure economic growth and technological shifts? In this talk, Dr. Alexopoulos will unveil new indicators of technical change that, she argues, resolve many of the problems associated with traditional ones (e.g., research and development (R&D) intensity and patents). Dr. Alexopoulos’ measures are primarily derived from previous unutilized information contained in MARC21 records (available from the Library of Congress and OCLC’s WorldCat database) on new book titles in various fields of technology over the last century. Further, Dr. Alexopoulos will discuss how the indices are related to inputs into knowledge production (such as scientific advances and R&D), and demonstrate that the measures are closely correlated with the commercialization date of new technologies. Finally, she will highlight a number of questions that the new indicators can help answer. \[[Presentation splashpage](https://www.oclc.org/research/news/2010-01-28.htm?ref=lorcandempsey.net)\]
We are very interested to see Worldcat data used in this way, alongside other sources of data about book publication and use (books in print data and sales data). It was interesting hearing Michelle describe some of the reasons why books – and library catalog data – was a good candidate as an indicator:
1. Book publication is linked to changes in knowledge (consider the appearance of manuals, how-to books, …)
2. The timing is right: there is a good correspondence between the date of commercialization of a technology or process and the date of books published about it. This is supported by commercial interests of publishers in catching interest at the right time.
3. Library catalogs group books into subject classifications which can be useful for analysis purposes.
We will make the slides and audio of the presentation available soon. Some further details of the approach can be found in these publications:
- Michelle Alexopoulos, “Read All About it!! What Happens Following a Technology Shock?” American Economic Review, forthcoming. Available online as University of Toronto Department of Economics Working Paper 391 at: [https://www.economics.utoronto.ca/index.php/index/research/workingPaperDetails/391](https://www.economics.utoronto.ca/index.php/index/research/workingPaperDetails/391?ref=lorcandempsey.net).
- Michelle Alexopoulos and Jon Cohen, “Volumes of Evidence–Examining Technical Change Last Century Through a New Lens.” Available online as University of Toronto Department of Economics Working Paper 392 at: [https://www.economics.utoronto.ca/index.php/index/research/workingPaperDetails/392](https://www.economics.utoronto.ca/index.php/index/research/workingPaperDetails/392?ref=lorcandempsey.net).
- Michelle Alexopoulos and Jon Cohen, “Measuring Our Ignorance, One Book at a Time: New Indicators of Technical Change, 1909-1949” Journal of Monetary Economics 56 (4) (2009), 450-470\. Available online as University of Toronto Department of Economics Working Paper 349 at: [https://www.economics.utoronto.ca/index.php/index/research/workingPaperDetails/349](https://www.economics.utoronto.ca/index.php/index/research/workingPaperDetails/349?ref=lorcandempsey.net).
Incidentally, it was also quite interesting for OCLC colleagues to see an economist talk knowledgeably about the MARC format 😉
### All the news ...
URL: https://www.lorcandempsey.net/all-the-news/
Last updated: 2022-11-09T05:21:20.000Z
My former OCLC colleague Eric Hellman has become one of the more interesting bloggers in our space. A little while ago he wrote about the acquisition of Liblime by PTFS. He made a general opening comment …:
> The library industry has likewise been troubled by misalignment of interests between the owners of the companies and their customers. That’s why it’s important for libraries to pay close attention to the frequent mergers and acquisitions of the companies that serve them. \[[PTFS to Acquire LibLime and Move to Library Systems Premier League](https://go-to-hellman.blogspot.com/2010/01/ptfs-to-acquire-liblime-and-move-to.html?ref=lorcandempsey.net)\]
And goes on to talk about the rationale for open source (primarily to avoid vendor lock-in, Eric argues) and PTFS and Liblime positions in the market.
Here, for example, he talks about aspects of the library/vendor transaction from the vendor perspective …
> From the vendor’s point of view, the sales process is very expensive. Promises to customize the system to address customer peculiarities are common, and these add to the cost of system maintenance. Once the system has been sold, a proprietary system vendor has a guarantee of continuing profits from support contracts. Only the vendor has the system knowledge (and sometimes even the system access) to make even the most trivial changes. It’s in the support phase that the vendor and customer interests can become misaligned. The vendor has every incentive to do the least work at the highest price possible. The customer is locked into whatever system they have chosen. \[[PTFS to Acquire LibLime and Move to Library Systems Premier League](https://go-to-hellman.blogspot.com/2010/01/ptfs-to-acquire-liblime-and-move-to.html?ref=lorcandempsey.net)\]
…. and here he talks about open source ..
> The recent popularity of open source library management systems is in large part a search for business models that better align the interests of vendor and customer during the support phase. If the support vendor doesn’t perform to the library’s expectations, the library can hire a new support vendor without ditching their automation system. If a library wants to add a new feature to their system, or integrate it with a system from another vendor, they can hire a developer based on qualifications rather than access to source. The important thing to the library is not so much the access to source or the cost of the license, it’s the absence of vendor lock-in. \[[PTFS to Acquire LibLime and Move to Library Systems Premier League](https://go-to-hellman.blogspot.com/2010/01/ptfs-to-acquire-liblime-and-move-to.html?ref=lorcandempsey.net)\]
The entry was informative and interesting. I may disagree with detail or emphasis (other factors are clearly in play in the current interest in open source for example) but – importantly – my thinking has been influenced by it.
When I finished reading it I was also struck by how unusual it is to read something like this in the sources where you might expect it, in the library ‘journalism’. In general we are not well-served by library journalism (I am thinking of what is published in our ‘trade magazines’: American Libraries, Library Journal, CILIP Update, …) when it comes to this type of ‘business’ analysis. Our discussions are poorer for it.
### Talking to people
URL: https://www.lorcandempsey.net/talking-to-people/
Last updated: 2020-10-28T09:11:42.000Z
I am interviewed occasionally for a report somebody is preparing. Sometimes internal, not for publication, sometimes published. It is always interesting when reading the final outcome to see how and whether my comments were included.
My experiences vary. Sometimes I am pleased to see an appropriate trace of the conversation; sometimes I can see no evidence that I was ever spoken to; and sometimes comments are assimilated to a view that I did not really have.
Not unsurprisingly, people are variably good at listening. Sometimes a comment will be enlisted in support of a view the interviewer had. Although, I haven’t kept track I don’t think that people inside the library community are necessarily more faithful interpreters than those from outside.
What is surprising – to me anyway – is the number of interviewers in situations like this who like to answer their own questions, or who, in response to the slightest prompt, are keen to talk about experiences on their previous assignments. In my experience, they tend not to produce great reports.
### Comments
URL: https://www.lorcandempsey.net/comments/
Last updated: 2020-10-28T09:11:43.000Z
Apologies to commenters – we had some hiccups. Some were delayed and a couple may have been lost. We will try not to do it again …
### Reconfigurations
URL: https://www.lorcandempsey.net/reconfigurations/
Last updated: 2020-10-28T09:11:45.000Z
Readers will have noted recently that I have been interested in reputation management and impact, and in how libraries may support institutional goals in these areas. In this context I was interested to read the following in a thoughtful reflection on future directions for research libraries by Susan Gibbons:
> Another shift in technical service in academic libraries will be towards the facilitation of discovery and access of locally created materials. The rising importance of open access and the growing acceptance of download counts as part of an academic’s impact metric will cause higher education institutions to focus on achieving the widest possible distribution of their locally created content. Dissertations, articles, books, working papers, technical reports, and other such content will flood into the campus libraries for curation, description, and distribution. Technical service staff will find an increasing percentage of their work shifted away from the procurement of external content to the care and distribution of locally created content.
> Another emerging need for the expertise of technical services staff in academic libraries will develop from the expanding importance of the gathering and maintenance of institutional metrics. The need for a higher education institution to demonstrate its impact on society and return on investment to its state, federal, foundation, and alumni donors will drive the coordination and consolidation of institutional data, such as publications, citations, and grant outputs. The library is a natural locus for such operations, in part as a service related to the institutional repository. \[Time horizon 2020: Library renaissance [PDF](https://www.ala.org/ala/mgrps/divs/alcts/confevents/upcoming/ala/library%5Frenaissance.pdf?ref=lorcandempsey.net)\]
I was also interested in Susan’s emphasis on new forms of collaborative sourcing.
> Ironically, I think the Google Book Settlement will cause a resurgence in the use of the current print collections of libraries as users discover content that was hidden by the difference between searching a full-text index and a MARC record. As these books are rediscovered, there will be a shifting of resources in technical services towards the identification, preservation, and some level of republication of books held uniquely by each library. Regional collaborations around the identification and preservation of last copies, shared off-site storage, and cooperative collection development will open doors towards more formalized sharing of regional skills, infrastructure, and resources. I believe academic libraries will model partnerships which their academic institutions will later need to follow as higher education as a whole retrenches through economic and demographic necessity. \[Time horizon 2020: Library renaissance [PDF](https://www.ala.org/ala/mgrps/divs/alcts/confevents/upcoming/ala/library%5Frenaissance.pdf?ref=lorcandempsey.net)\]
This has also been a topic of interest in these pages. As libraries begin to think about their collective collection and its collaborative management in more focused ways, the balance between local provision , shared provision in offsite storage, and digital availability in GBS or Hathi Trust will become a major focus of service and policy attention.
### Outside-in and inside-out
URL: https://www.lorcandempsey.net/outside-in-and-inside-out/
Last updated: 2026-08-31T15:11:32.000Z
An ‘industry’ pattern appears to have emerged which builds a discovery layer over resources available from the library (or from a group library service, at the level of a state or a consortium for example).
Three characteristics come to mind. First, there is an attempt to provide an integrated discovery experience over multiple resource types/workflows: bought materials (books, CDs, etc), licensed materials (A&I databases, ejournals, etc), and institutional digital materials (digitised special collections, for example, or repositories of learning and research materials). Second, this ‘horizontal’ discovery layer is separated from the ‘vertical’ management systems which may manage those resources: the ‘integrated’ library system, the variety of systems which manage licensed resources, repository infrastructure, and so on. And, third, API access may be provided.
Various issues are being addressed as this model becomes more common. One that is interesting, I think, is that it will show how the three categories of resource I mention above – bought, licensed, and digital – have quite different dynamics in our systems and services.
> One that is interesting, I think, is that it will show how the three categories of resource I mention above – bought, licensed, and digital – have quite different dynamics in our systems and services.
Think, for example, of a distinction between **outside-in** resources, where the library is buying or licensing materials from external providers and making them accessible to a local audience (e.g. books and journals), and **inside-out** resources which may be unique to an institution (e.g. digitized images, research materials) where the audience is both local and external. Thinking about an external non-institutional audience, and how to reach it, poses some new questions for the library.
Or think about the relationship between the ‘locally available’ collection and the ‘universal’ collection in each case.
- For bought materials (books, CDs, …) the library provides access to the locally available collection – the materials acquired for local use – and then may provide access to a broader ‘universal’ collection through Worldcat or another resource.
- For licensed materials, access is first through the broader ‘universal’ level (in various databases) before checking for the subsect of locally available materials.
- For institutional digital materials, access is provided to local repositories but this will not typically be backed up by access to a ‘universal’ source for such materials (although, one can see attempts to do this, as, for example, where an institutional repository expands a search to Scirus).
Of course, if one thinks about other discovery/disclosure channels (Google, for example), these three collection types also behave differently. That is a topic for another blog entry though.
**Note:** Stylistic updates, picture and summary added 16 December 2022\.
**Picture:** I took the picture in Tremont, Cleveland. Some of the [images](http://canjournal.org/2019/05/the-art-of-historic-tremont/?ref=lorcandempsey.net) were sourced from special collections at Cleveland State University.
### Digital content quarterly
URL: https://www.lorcandempsey.net/digital-content-quarterly/
Last updated: 2020-10-28T09:11:48.000Z
*[Digital Content Quarterly](https://sca.jiscinvolve.org/files/2010/01/sca%5Fdcquarterly%5F01%5Fdec09-interactive.pdf?ref=lorcandempsey.net)* is a new publication from the [Strategic Content Alliance](https://www.jisc.ac.uk/contentalliance?ref=lorcandempsey.net).
> In this fast-paced, ever-changing environment the Strategic Content Alliance’s Digital Content Quarterly (DCQ) provides a news round-up of digital content issues from around the world, thought-provoking features highlighting key debates in the field and regular columns from leading digital content experts in areas that have most traction in terms of digital content provision: intellectual property rights and business modelling and sustainability. The quarterly is also interactive, complete with video interviews of features and ‘top tip’ guides as well as a vibrant new design. \[[Digital Content Quarterly](https://sca.jiscinvolve.org/files/2010/01/sca%5Fdcquarterly%5F01%5Fdec09-interactive.pdf?ref=lorcandempsey.net)\]
The video inserts are a nice feature, although as with many publications produced for printing it is difficult to read on the web.
It was interesting reading through fifteen or so pages on digitization and digital content services which only had a couple of small references to Google Book Search 😉
### Reputational survey
URL: https://www.lorcandempsey.net/reputational-survey/
Last updated: 2020-10-28T09:11:50.000Z
As university rankings attract more attention and as national/regional policy discussions continue about whether and how to concentrate research excellence, Thompson Reuters have provided a little more detail about their plans to work with Times Higher Education to develop their own framework to support university profiling and ranking.
> Our aim with the Global Institutional Profiles Project, which includes [our work with Times Higher Education’s World University Rankings](https://www.timeshighereducation.co.uk/story.asp?sectioncode=26&storycode=408908&navcode=105&ref=lorcandempsey.net), is to develop a data source that provides the best informed and most effective resource to build profiles of universities and research-based institutions around the world. The Profiles Project will create data-driven portraits of globally significant research institutions, combining peer review, scholarly outputs, citation patterns, funding levels, and faculty characteristics in one comprehensive database. Thomson Reuters also brings a celebrated legacy of data transparency to the Profiles Project, operating with clear methodology and data gathering practices. \[[Global institutional profiles project](https://science.thomsonreuters.com/globalprofilesproject/?ref=lorcandempsey.net)\]
They announce their ‘[reputational survey](https://science.thomsonreuters.com/globalprofilesproject/gpp-reputational/?ref=lorcandempsey.net)‘, to be sent to a selection of researchers soliciting evaluation of institutions active in their research area. This will provide one stream of data among several. Another will be citation data from Web of Science, styled the “gold standard in research indexing”.
Potentially, this is an important initiative given the influence of adopted metrics on behavior. Appropriate metrics continue to be the subject of debate (see for example the program of this [NSF-sponsored meeting](https://informatics.indiana.edu/scholmet09/announcement.html?ref=lorcandempsey.net) on scholarly metrics) of serious interest to research and science policy and funding bodies, as well as to institutions themselves.
### Europeana
URL: https://www.lorcandempsey.net/europeana/
Last updated: 2020-10-28T09:11:55.000Z
My colleague Ricky Erway bravely accepted the challenge to talk as an outsider on the challenges faced by Europeana to a European conference on digitization last year. Her remarks are recorded in an [article](https://liber.library.uu.nl/publish/issues/2009-2/index.html?000472&ref=lorcandempsey.net) in the *LIBER Quarterly*.
> The organisers of the second LIBER/EBLIDA workshop on digitisation (The Hague, October 19-21) asked Ricky Erway of OCLC to provide a view on Europeana from the US perspective. Erway accepted the invitation with some hesitation, as she was well aware that Europeana is still in its infancy. Her remarks, as reproduced below, were received by her audience as they were intended: as one person’s observations at a particular point in the Europeana timeline. But as she drew on her twenty-year experience in related projects and activities, her observations are well worth the attention of Europeana staff and stakeholders. \[[A view on Europeana from the US perspective](https://liber.library.uu.nl/publish/issues/2009-2/index.html?000472&ref=lorcandempsey.net)\]
### Where are the numbers? The impact of the economic recession on university library and IT services
URL: https://www.lorcandempsey.net/where-are-the-numbers-the-impact-of-the-economic-recession-on-university-library-and-it-services/
Last updated: 2020-10-28T09:11:57.000Z
‘The impact of the economic recession on university library and IT services’ \[[pdf](https://www.jisc.ac.uk/media/documents/publications/libsitimpacts.pdf?ref=lorcandempsey.net)\] is a report by market research company Ipsos Mori for several UK higher education organizations. A [summary](https://www.jisc.ac.uk/publications/documents/libsitimpacts.aspx?ref=lorcandempsey.net) and a [briefing paper](https://www.jisc.ac.uk/publications/documents/libsitimpactsbp.aspx?ref=lorcandempsey.net) are also available.
It documents possible approaches to cost saving based on interviews with librarians and directors of ICT services. I was slightly surprised at the bullish tone in the opening sentences of this headline statement about libraries:
> One thing is clear: most librarians we spoke to are not yet feeling the ‘pinch’ of the recession on their services. There is a clear sense that the library occupies a protected place as the ‘beating heart’ of the institution and most feel the impact of the recession has currently been contained to small, easily managed budget cuts – for now. At the same time, however, there is a sense of vulnerability and a growing concern that libraries may be seen as an easy target for savings and efficiencies whenever required by the institution (given their book funds are typically the largest concentration of uncommitted funds within the University budget) while they struggle to meet ever changing student and academic staff service demands. \[The impact of the economic recession on university library and IT services [PDF](https://www.jisc.ac.uk/media/documents/publications/libsitimpacts.pdf?ref=lorcandempsey.net)\]
Especially as the summary spoke about “an acute sense” of vulnerability.
It notes ‘solutions’ under the following headings: self-service, consortia, renegotiating contracts and planning subscriptions, shared services and outsourced services, library staff, monitoring satisfaction and impact on students. I didn’t notice much discussion of the report when it appeared (September 2009) but I doubt that anybody was very surprised by very much that they read in it.
There are a couple of recommendations in the Foreword by JISC which seem a little ahead of practice. For example, it is suggested that among the opportunities that “are at universities’ disposal to realise efficiencies and cost savings” is the adoption by HE library consortia of shared Library Management Systems (LMS). It is also suggested that open access “should help mitigate increased costs in journal subscriptions”. Neither of these is likely to be an immediate source of cost savings given the current state of play, whatever about the longer term.
However, in reading the report I became increasingly aware of a strange gap, particularly in a report prepared by a market research company. There are hardly any numbers. There is discussion of downturn, of shifting investment, of trends – but hardly anywhere is there an attempt to quantify these. Above all, I wondered if there were a sense of how big the discussed budget cuts were likely to be. This may be institution-specific, but without a sense of scale the whole discussion had a sense of unreality.
### VIAF design pattern
URL: https://www.lorcandempsey.net/viaf-design-pattern/
Last updated: 2020-10-28T09:11:59.000Z
A blog entry by Paul Walk – [An infrastructure service anti-pattern](https://blog.paulwalk.net/2009/12/07/an-infrastructure-service-anti-pattern/?ref=lorcandempsey.net) – drew some attention a while ago. He argues against a model in which a service provider independently develops APIs and a user interface, and in which, accordingly, the APIs are developed in advance of actual use or explicit external requirements. He claims that this model underlies aspects of historic UK higher education thinking, where application to application interoperability was seen as a good in itself and was often built into initiatives from the start in mistaken anticipation of hypothetical future use.
His alternative suggestion is that an API should be developed in tandem with real requirements generated by the user-facing application supporting user interfaces. This motivates the API with real requirements and strengthens the chances of being able to support third party application developers who want to write to the API. He suggests a refinement of this approach as follows:
> An interesting alternative to this is the approach of combining the user-facing web pages and the machine-actionable API into one interface, through embedded RDFa for example:
> 
> It remains to be seen how this approach is going to work out over time, but we have seen hints of simpler approaches to combining user and machine interfaces in the past, such as RSS being styled to give a decent human-readable interface, or earlier attempts to do interesting things with XHTML. \[[An infrastructure service anti-pattern](https://blog.paulwalk.net/2009/12/07/an-infrastructure-service-anti-pattern/?ref=lorcandempsey.net)\]
I left a note suggesting that [VIAF](https://www.viaf.org/?ref=lorcandempsey.net) and [Worldcat Identities](https://worldcat.org/identities?ref=lorcandempsey.net) were architected along the lines of this last picture. For VIAF details, for example, see Thom’s posts [here](https://outgoing.typepad.com/outgoing/2009/08/viaf-and-opensearch.html?ref=lorcandempsey.net) and [here](https://outgoing.typepad.com/outgoing/2009/12/viaf-and-rdf.html?ref=lorcandempsey.net). Several interfaces – OpenSearch, linked data, user-oriented – are supported by an underlying SRU interface. Here is Paul’s response, noted here with his permission:
> I’m fascinated to see that VIAF merges the human/machine interfaces in two ways:
>
> [a machine-centric, but with a human-readably styled version if accessed from a browser](https://viaf.org/viaf/39373043.rdf?ref=lorcandempsey.net)
>
> and
>
> [a human-centric, get the machine view with a little addition to the URL approach here](https://viaf.org/search?query=cql.any+all+%22dempsey%22&maximumRecords=100&stylesheet=xsl/results.xsl%20&sortKeys=holdingscount&http:accept=application/rss%2bxml&ref=lorcandempsey.net)
>
> the second of which is, in turn, also styled for human consumption if accessed from a browser.
### Institutional researcher pages: an example
URL: https://www.lorcandempsey.net/institutional-researcher-pages-an-example/
Last updated: 2021-03-28T20:48:18.000Z
## Reputation management and researchers
I have written a couple of times recently ([here](https://blog.oclc.org/lorcand/archives/002011.html?ref=lorcandempsey.net) and [here](https://blog.oclc.org/lorcand/archives/002023.html?ref=lorcandempsey.net)) about institutional and indvidual reputation management.
> Think, for example, of faculty profiles: the managed disclosure of expertise and research activity. This has often been an informal personal or departmental activity. However, there is now a variety of institutional initiatives which may pull together data about expertise, experience, publications, grants, courses taught, and so on (see OSU Pro at OSU, or Vivo at Cornell, for example). Such initiatives may sit between between several organizational units on campus: Research Support, PR/Communications, IT, Library. They are also at the intersection of different systems: enterprise (Peoplesoft, for example), course lists, research/grants management, bibliographic. At the same time, researchers may have presences in emerging network level research social networks (Mendeley or Nature Network for example), in disciplinary resources (Repec, for example), and, of course, in general use services (Linkedin, for example). There are also commercial services which support such activity in different ways, Community of Science or Symplectic for example. \[[Reputation enhancement](https://blog.oclc.org/lorcand/archives/002011.html?ref=lorcandempsey.net)\]
## The Scholars Hub at the University of Hong Kong
The [Scholars Hub](https://hub.hku.hk/?ref=lorcandempsey.net) is the institutional repository at Hong Kong University. It has recently been enhanced with author pages which pull data from several sources including:
1. Name & Contact Details: HKU Communications Directory
2. Picture & Biography: Departmental web pages
3. Media Spokesmanship: HKU Communications & Public Affairs Office
4. Metrics: Scopus & ISI ResearcherID
5. Open access outputs: HKU Scholars’ Hub.
Each is harvested from its source silo and integrated to form an author profile. In a recent presentation \[[ppt](https://prdla.ucmercedlibrary.info/presentations/2009/2009%5Ftferguson.ppt?ref=lorcandempsey.net)\] about the approach, University Librarian Tony Ferguson and David Palmer describe how researchers can control their own page, and emphasise the incentives for contribution in the context of an overall alignment with the university mission of ‘knowledge exchange’ (KE). KE is defined on the presentation [splash page](https://prdla.ucmercedlibrary.info/?s=critical&ref=lorcandempsey.net): “The HKU definition of KE includes the act of making HKU generated knowledge and skill sets accessible to business, government and the community.” They suggest that the pages give authors a valuable service and point to success in search engine retrieval. For an example, see (click on the image to see the full page):
[](https://hub.hku.hk/rp/rp00026?ref=lorcandempsey.net)
The service also attempts to bring together different versions of author names. They assign a unique local identifier to each researcher, which is in the page URL (rp00026 in the above example).
The bibliometrics section is in preparation for the HKU annual Performance Reviews, and the Hong Kong Research Assessment Exercise.
**Picture:** I took the feature picture in the main library of the University of Hong Kong. Floor feature to assist navigation.
**Provenance:** Cosmetic amendments on 28 March 2021, including adding feature picture and headings. Originally published on 2 January 2010 at Lorcan Dempsey's Weblog.
**Acknowledgement:** Thanks to Tony Ferguson and David Palmer for a note on the work supporting this initiative.
**Related entries:**
- [Research assessment and the library](https://blog.oclc.org/lorcand/archives/002039.html?ref=lorcandempsey.net)
- [Reputation enhancement](https://blog.oclc.org/lorcand/archives/002011.html?ref=lorcandempsey.net)
- [Reputation enhancement redux](https://blog.oclc.org/lorcand/archives/002023.html?ref=lorcandempsey.net)
### How to repost?
URL: https://www.lorcandempsey.net/how-to-repost/
Last updated: 2020-10-28T09:12:04.000Z
I [‘re-posted’](https://blog.oclc.org/lorcand/archives/002035.html?ref=lorcandempsey.net) my entry on the ‘two ways of Web 2.0’ the other day. On the site, I now have a page for the [original entry](https://blog.oclc.org/lorcand/archives/001556.html?ref=lorcandempsey.net) and for the [‘re-post’](https://blog.oclc.org/lorcand/archives/002035.html?ref=lorcandempsey.net).
I have just ‘re-posted’ [another entry](https://blog.oclc.org/lorcand/archives/001392.html?ref=lorcandempsey.net), but this time I chose to do it a different way. I changed the publish date to today’s date, and noted the original date in a note.
I wondered which way was the better, and am not aware of any ‘good practice’ on this issue. It seems to me that newspapers sometimes adopt the latter practice. I notice that [PersonaNonData](https://personanondata.blogspot.com/2009/12/predictions-2009-death-and-resurrection.html?ref=lorcandempsey.net), who occasionally reposts earlier entries, seems to follow the former.
It is interesting to run into this versioning question in a modest way here. I can see pros and cons of each approach and I am sure there is a relevant literature. Something to think about in the new year ….
### Being friends with the librarian in the Bibliothèque National
URL: https://www.lorcandempsey.net/being-friends-with-the-librarian-in-the-bibliotheque-national/
Last updated: 2024-01-15T07:39:31.000Z
\[I bring back this entry prompted by the [selection](https://www.timeshighereducation.co.uk/story.asp?storycode=409554&ref=lorcandempsey.net) of [The Arcades Project](https://worldcat.org/oclc/41176710?ref=lorcandempsey.net) in the series of canonical works in the *Times Higher Education Supplement*. It was originally published on July 13 2007.\]
There is a passage in a letter from [Walter Benjamin](https://www.worldcat.org/wcidentities/lccn-n80-36695?ref=lorcandempsey.net) to [Theodor Adorno](https://worldcat.org/identities/lccn-n80-2956?ref=lorcandempsey.net) where he suggests removing a reference to [Georges Bataille](https://www.worldcat.org/wcidentities/lccn-n50-25778?ref=lorcandempsey.net) from a document. Bataille, in addition to his other accomplishments, was a librarian at the Bibliothèque Nationale de France. Benjamin writes:
> And in this way my own relationship with Georges Bataille will not be adversely affected either, something I would like to maintain, both because of his assistance at the Bibliothèque Nationale, and because of my plans for naturalization. – The fragment would not escape his attention since the Institute journal is openly displayed in the reading room where he often works; and he is hardly the type of person to react serenely to its contents. // [*Theodor W Adorno and Walter Benjamin. The complete correspondence, 1928-1940*](https://worldcat.org/oclc/40820873?ref=lorcandempsey.net). p. 276
I was reminded of this passage as I read Jeremy Harding’s [discussion in the current *London Review of Books*](https://www.lrb.co.uk/v29/n14/hard01%5F.html?ref=lorcandempsey.net) of Walter Benjamin’s ‘last day’ before his death in 1940 while trying to flee to the US.
Benjamin had left various papers, including the manuscript of his [Arcades Project](https://worldcat.org/oclc/41176710?ref=lorcandempsey.net), with Bataille for safe-keeping. Bataille hid them in the library. The Arcades Project is a massive unfinished work, a weaving of quotations and Benjamin’s own text.
So the library comes in at three levels. At one, it is important for the scholar to keep in with the librarian 😉 At a second, the librarian receives a manuscript on the eve of flight and keeps it safely in the library from where it is retrieved and published. At a third, is it possible to imagine a book which rests so much on quotations without the libraries which preserve the scholarly and cultural record the quotations point to and make it available to readers?
Related entries:
- [Aura again: habent sua fata libelli](https://blog.oclc.org/lorcand/archives/000627.html?ref=lorcandempsey.net)
- [Quotes about order and disorder](https://blog.oclc.org/lorcand/archives/000625.html?ref=lorcandempsey.net)
- [Collecting books](https://blog.oclc.org/lorcand/archives/000433.html?ref=lorcandempsey.net)
- [Aura and digitization](https://blog.oclc.org/lorcand/archives/000623.html?ref=lorcandempsey.net)
- [Two buildings](https://blog.oclc.org/lorcand/archives/001219.html?ref=lorcandempsey.net)
**Note:** Originally published July 13 2007\. *WC Identities* URLs updated to current versions.
### Research assessment and the library ...
URL: https://www.lorcandempsey.net/research-assessment-and-the-library/
Last updated: 2020-10-28T09:12:09.000Z
I am pleased to note the appearance of a new report on research assessment and the role of libraries. This has been prepared as part of our [Research Information Management](https://www.oclc.org/research/activities/rim.htm?ref=lorcandempsey.net) stream of work in support of the RLG Partnership.
The study is a comparative review of formal assessment regimes in five countries. Such assessment regimes exist to monitor public research spending in various ways, and are specific to national circumstances. Although such regimes are not universal, evaluation, ranking and assessment of various sorts are becoming more common and some of the library responses discussed (bibliometric assistance, reputation management, names and identifers, institutional management of research outputs) may be of quite general interest.
This is from the introduction by the authors, the UK consultants [Key Perspectives](https://www.keyperspectives.co.uk/?ref=lorcandempsey.net):
> This study was designed to review research assessment regimes and the role of research libraries within those assessment processes in five countries, each of which takes a different approach to assessment. At the beginning of the project it was postulated that libraries occupy an interesting position within the academy, both belonging to an institution yet to an extent separated from it. There is–arguably–a set of ‘research library values’ that remains independent of local, institutional values, enabling libraries to occupy a unique and constructive role in the development and support of research assessment processes. Libraries have an understanding of scholarly communication processes, and they are currently in a state of rapid transformation to keep pace with the way scholars work. They understand the broad range of outputs and the publishing behaviour of scholars across disciplines, and the methodological constraints, limitations and variances that pertain to assessment exercises. This report provides an insight into the extent to which research libraries have so far been able to leverage the particular skills and experience their staff possess to position the library at or near the operational and strategic centre of institutions’ responses to the internal and national requirements of research assessment processes. \[A Comparative Review of Research Assessment Regimes in Five Countries and the Role of Libraries in the Research Assessment Process [PDF](https://www.oclc.org/research/publications/library/2009/2009-09.pdf?ref=lorcandempsey.net)\]
My colleague John MacColl [writes](https://hangingtogether.org/?p=761&ref=lorcandempsey.net) about the report at more length and offers these thoughts …
> The Review provides a fascinating account of different cultural understandings of the purposes of assessment, and a glimpse of the trend of concentrating research excellence in a small number of top universities that is now taking shape in many countries, as the competition for research income, top faculty and students becomes one that occurs within a single international marketplace. We found countries that tied research assessment to large amounts of government funding, and others that did not (yet); countries that operated systems based on bibliometrics and others that mistrusted them; countries that devised league tables of journals and awarded points to researchers on those they published in – and others that assembled national panels of experts to determine the rankings.
> Libraries are involved in these assessment exercises in a range of ways, from the clerical (data entry) to the highly strategic, and from the specialist (bibliometric expertise) to a role as providers of general infrastructure (institutional repositories). Whatever differences there may be in the assessment systems adopted by different countries, they all share a focus upon the research outputs produced by their researchers and faculty. These outputs are managed by libraries – both indirectly (via publications) and, increasingly directly (via arrangements with the authors themselves at pre-publication stages). Does this suggest that libraries play a central role in research assessment within their institutions? Or that they should? At the very least, shouldn’t libraries seek a shared view on this question?\[[National systems of research assessment and implications for libraries](https://hangingtogether.org/?p=761&ref=lorcandempsey.net)\]
### The information, er, protocol society ...
URL: https://www.lorcandempsey.net/the-information-er-protocol-society/
Last updated: 2020-10-28T09:12:11.000Z
The ‘information society’ is a vague term, but seems to convey enough of something useful to stay in currency. Frank Webster reviews the concept as it is used in the social sciences and communications studies [here](https://www.worldcat.org/oclc/172963851/editions?ref=lorcandempsey.net).
Reductively, one might point to two emphases in thinking about an Information Society, which emerged successively. In the first, information management activities are seen as centrally important, manifest in the emergence of the service economy and the importance of ‘knowledge workers’. The defining characteristic is that a large part of economic and professional activity involves information management. A second sees information processing activities as more constitutive and generative of a fuller range of activities, in the way that industrial processes were in an earlier phase. Commerce, manufacturing, trade, and so on, are increasingly structured by flows of information, and reflexively adapt to the application of new knowledge. Think of the processes around supply chain management for example, or of data driven R&D, or of the use of transactional data in consumer websites. In this latter sense, ‘information’ is not just managed, but a wide range of activities are ‘informationalised’ and the application and generation of knowledge is a dynamic force in process evolution and refinement.
In a recent column in the NYT David Brooks uses the term ‘Protocol Society’ for a set of ideas similar to the second emphasis above, or maybe for what Manuel Castells calls an ‘informational society’ (modeled after ‘industrial society’).
> In the 19th and 20th centuries we made stuff: corn and steel and trucks. Now, we make protocols: sets of instructions. A software program is a protocol for organizing information. A new drug is a protocol for organizing chemicals. Wal-Mart produces protocols for moving and marketing consumer goods. Even when you are buying a car, you are mostly paying for the knowledge embedded in its design, not the metal and glass. \[[The protocol society](https://www.nytimes.com/2009/12/22/opinion/22brooks.html?ref=lorcandempsey.net)\]
Brooks goes on to discuss development and innovation in this context referring to recent research.
The term ‘information society’ is probably too vague to be useful except in broad gestural terms. I will be interested to see if ‘protocol society’ gains any traction.
### Being foreign
URL: https://www.lorcandempsey.net/being-foreign/
Last updated: 2024-01-05T19:57:18.000Z
## Pointing to The Economist
We have been traveling over the holiday period – to London briefly, and then on to various Irish destinations.
One of the consequences of Twitter is that there are fewer incentives for the ‘pointer’ blog entry, a collection of links to interesting items. However, this is a pointer entry. It is pointing to an [article](https://www.economist.com/world/international/displaystory.cfm?story%5Fid=15108690&ref=lorcandempsey.net) in *The Economist*.
*The Economist* is an interesting publishing phenomenon, successful when news media in general are suffering. There was an article in *The Atlantic Magazine* a while ago proposing to account for this success. It pokes a little: 'The science-and-technology pages tend toward Gladwell-lite popularizations of academic papers from British universities' .. but suggests why *The Economist* retains its popularity in a news-saturated world:
> The Economist prides itself on cleverly distilling the world into a reasonably compact survey. Another word for this is blogging, or at least what blogging might be after it matures–meaning, after it transcends its current status as a free-fire zone and settles into a more comprehensive system of gathering and presenting information. As a result, although its self-marketing subtly sells a kind of sleek, mid-last-century Concorde-flying sangfroid, The Economist has reached its current level of influence and importance because it is, in every sense of the word, a true global digest for an age when the amount of undigested, undigestible information online continues to metastasize. And that’s a very good place to be in 2009\. // [Why *The Economist* is thriving while *Time* and *Newsweek* fade](https://www.theatlantic.com/doc/200907/news-magazines?ref=lorcandempsey.net) by Michael Hirschorn
The article characterises the stance of *The Economist* as follows: “free-market right-center, if you want to be technical about it; with a dose of left-center social progressivism”.
One of the interesting things about it is an occasional quirkiness alongside the steady fare of financial and political commentary and reporting (see for example its obituaries). I picked up the *Special Christmas Double Issue* in an airport the other day and was struck by the variety, with articles on ‘The perfect violin: older and richer’ (the making of violins), ‘The Harry Potter economy: making money out of the boy wizard’, ‘Difficult languages’ (comparing languages in terms of how difficult they are to learn), ‘Filth: the joy of dirt’ (looking at changing notions of cleanliness), ‘Newspapers and technology: network effects’.
## Being foreign
However, given the travels we are on, what really jumped out at me was the article called ‘Being foreign’. Having been sort of foreign in England, and being foreign in the US, it made interesting reading. Here are its portentous concluding paragraphs; I am not sure whether they lean more to clever distillation or to ‘Gladwell-lite popularization’ of academic articles.
> The funny thing is, with the passage of time, something does happen to long-term foreigners which makes them more like real exiles, and they do not like it at all. The homeland which they left behind changes. The culture, the politics and their old friends all change, die, forget them. They come to feel that they are foreigners even when visiting “home”. Jhumpa Lahiri, a British-born writer of Indian descent living in America, catches something of this in her novel, “The Namesake”. Ashima, who is an Indian émigré, compares the experience of foreignness to that of “a parenthesis in what had once been an ordinary life, only to discover that the previous life has vanished, replaced by something more complicated and demanding”.
> Beware, then: however well you carry it off, however much you enjoy it, there is a dangerous undertow to being a foreigner, even a genteel foreigner. Somewhere at the back of it all lurks homesickness, which metastasises over time into its incurable variant, nostalgia. And nostalgia has much in common with the Freudian idea of melancholia–a continuing, debilitating sense of loss, somewhere within which lies anger at the thing lost. It is not the possibility of returning home which feeds nostalgia, but the impossibility of it. Julia Kristeva, a Bulgarian-born intellectual resettled in France, has caught this sense of deprivation by comparing the experience of foreignness with the loss of a mother.
> But we cannot expect to have it all ways. Life is full of choices, and to choose one thing is to forgo another. The dilemma of foreignness comes down to one of liberty versus fraternity–the pleasures of freedom versus the pleasures of belonging. The homebody chooses the pleasures of belonging. The foreigner chooses the pleasures of freedom, and the pains that go with them. // [Being foreign: the others](https://www.economist.com/world/international/displaystory.cfm?story%5Fid=15108690&ref=lorcandempsey.net)
**Picture:** I took the feature image as we landed in Cork Airport, Ireland.
**Note:** Cosmetically amended on 3 April 2020 to add headings and feature image, and to improve spacing.
### The importance of books ..
URL: https://www.lorcandempsey.net/the-importance-of-books/
Last updated: 2020-10-28T09:12:17.000Z
I read the interesting *Communicating knowledge: how and why UK researchers publish and disseminate their findings* and its supplementary reports (literature review and bibliometric analysis) on a transatlantic flight the other day. (Incidentally, it must have been the most cramped large-plane seat I have ever been on – I could not use my laptop.)
A brief overview and links to report components are available on the [Research Information Network splash page](https://www.rin.ac.uk/our-work/communicating-and-disseminating-research/communicating-knowledge-how-and-why-researchers-pu?ref=lorcandempsey.net).
There is much of interest in the report about publishing and communications practices and about incentives.
Given our general discussion of books and their contexts I was struck by several findings about the relative importance of books in overall practice.
The bibliometric analysis examined the outputs of a sample of UK researchers:
> Although there is no difference over time in the total number of citations per output, there are statistically significant differences in the types of work being cited, shown in Figure 15\. There are more citations to journal articles and websites in 2008 than in 2003, but fewer citations to books and grey literature. [Supporting paper 1: bibliometric analysis](https://www.rin.ac.uk/our-work/communicating-and-disseminating-research/communicating-knowledge-how-and-why-researchers-pu?ref=lorcandempsey.net)\]
Here is a comment from the main report:
> As noted earlier, there has been a drift towards journal papers, meeting abstracts and editorial material, and a corresponding decline in books, book chapters and conference proceedings. But many researchers believe that the increased volumes of publication in recent years are the results of an environment characterised by an increasing emphasis on assessing and evaluating performance, which brings with it pressure to publish too much, too soon and in inappropriate formats. And some believe that quality is being compromised in the pursuit of increased output .. \[[Communicating knowledge .](https://www.rin.ac.uk/our-work/communicating-and-disseminating-research/communicating-knowledge-how-and-why-researchers-pu?ref=lorcandempsey.net).\]
Disciplinary differences are described. As we consider what is going to happen to the monograph literature in the next few years, the impact of increasingly important evaluation regimes is an interesting dimension.
### The two ways of Web 2.0 - retread
URL: https://www.lorcandempsey.net/the-two-ways-of-web-20-retread/
Last updated: 2020-10-28T09:12:19.000Z
\[I first [published](https://blog.oclc.org/lorcand/archives/001556.html?ref=lorcandempsey.net) this in March 2008, and still find it useful to think in terms of **concentration** and **diffusion**. I was reminded of the entry and prompted to ‘recycle’ it – despite its age – when I read the following sentence in a recent [blog entry](https://www.roughtype.com/archives/2009/12/theres%5Fan%5Fappli.php?ref=lorcandempsey.net) by Nicholas Carr “Although a network can be a means of diffusing power, it can also be a means of concentrating it”.\]
I find Web 2.0 increasingly confusing as a label; no surprise there. This is not just because of its essential vagueness, but because I think it tends to be used in a couple of very different ways. Where this happens there is bound to be some confusion. Schematically, I will use the labels ‘diffusion’ and ‘concentration’ for these two ways.
*diffusion* is probably the more dominant of the two. Here it covers a range of tools and techniques which create richer connectivity between people, applications and data; which support writers as well as readers; which provide richer presentation environments. What tends to get discussed here are blogs and wikis; RSS; social networking; crowdsourcing of content; websites made programmable through web services and simple APIs; simple service composition environments; Ajax, flex, silverlight; and so on.
*concentration* is a major characteristic of our network experience, which often involves major gravitational hubs (google, amazon, flickr, facebook, propertyfinder.com). These concentrate data, users (as providers and consumers), and communications and computational capacity. They build value by collaboratively sourcing the creation of powerful data assets with their users. The value grows with the reinforcing property of network effects: the more people who participate, the more valuable they become. And opening up these platforms through web services creates more network effects. These sites also mobilize usage data to reflexively adapt their services, to better target particular users or to identify design directions. Of course, these platforms are very closely controlled, and there is an interesting balance of interests between openness and control at various levels in how they manage resources (see for example [my discussion](https://blog.oclc.org/lorcand/archives/001258.html?ref=lorcandempsey.net) of the Amazon and Google APIs).
Interestingly, if you trace Tim O’Reilly’s writings on Web 2.0 since the publication of his major defining article you see an emphasis on what I have called ‘concentration’ come through. (See[ my note on an interview](https://blog.oclc.org/lorcand/archives/001266.html?ref=lorcandempsey.net) with Tim O’Reilly by David Weinberger, on which I draw above, and also see O’Reilly blog posts [here](https://radar.oreilly.com/archives/2007/08/programming%5Fcol.html?ref=lorcandempsey.net) and [here](https://radar.oreilly.com/archives/2007/03/web%5F20%5Fgoes%5Fmai%5F1.html?ref=lorcandempsey.net).)
Now, of course ‘concentration’ and ‘diffusion’ are often complementary approaches. The major Internet hubs ‘diffuse’ their benefits through service and data syndication, apis, participation, etc, but their value often derives from successfully driving network effects through wide participation and consolidation of data. In fact, many of the ‘diffusion’ techniques work best when associated with concentrating applications. Think of tagging for example. People have incentives to tag their resources in Flickr or Librarything in ways that may not obtain in the library catalog. Scale matters in the context of the social value created in these services (of course, in these examples, folks are also tagging *their own* resources). You cannot simply add social networking to a site and expect it to work well. Think of all those empty forums.
Much of the library discussion of Web 2.0 is about ‘diffusion’, about a set of techniques for richer interaction. It is appropriate that libraries should offer an experience that is continuous with how people experience the web.
However, there is a very important way in which the library experience is not continuous with the web. It remains fragmented: it does not have the characteristics of the concentrating, gravitational hubs which characterize so much web use, and are so much a part of O’Reilly’s Web 2.0\. Fragmented by database boundary, by service boundary (e.g. connecting a discovery experience gracefully to a fulfillment experience through resolution), by library boundary. We are now familiar with the comparison between this fragmented experience and discovery on the web. And we are also familiar with discussion of how the library presence is weakly represented in the major network presences.
However, think also of the library management environment. Think for example of places where data needs to be concentrated to create value: aggregating user data across sites (e.g. counter data), or aggregating user created data (tags, reviews), or aggregating transactions (e.g. circulations, resolver clickthroughs). Motivations here are to drive business intelligence which allows services to be refined (e.g. how does my database usage compare to that of my peer group), to develop targeted services (people who like this, also liked that), to improve local services (e.g. add tags or reviews). These are examples where scale matters, where data may need to be concentrated above the individual library level.
And, we are seeing for fee services emerge which address this need. LibraryThing, for example, syndicates its user-generated tagging to libraries. I am not sure that [ScholarlyStats](https://www2.ebsco.com/en-us/ProductsServices/scholarlystats/Pages/index.aspx?ref=lorcandempsey.net) provides a service which compares usage across libraries; it would be interesting to know if there were demand for such a thing.
This then touches on larger questions about sourcing decisions (in what combination of local, collaborative, and third party do libraries acquire their service capacities) and about concentration of library presence (in what combination of library or library and third party are services offered).
For example, I [discussed](https://blog.oclc.org/lorcand/archives/001564.html?ref=lorcandempsey.net) Georgia Pines and OhioLink the other day as examples of groups of libraries collaboratively sourcing a concentrated library presence which increases their gravitational pull.
And libraries are beginning to think more seriously about sourcing services with central web presences. Think for example of the decisions made by the [National Library of Australia](https://www.nla.gov.au/pub/gateways/issues/80/story01.html?ref=lorcandempsey.net) and the [Library of Congress](https://www.flickr.com/commons?ref=lorcandempsey.net) when they chose to use Flickr for significant image projects. NLA is seeking to expand the coverage of PictureAustralia; LC is seeking to collect tags from viewers. In each case, the library wants to benefit from the concentration of users and data that Flickr has created on the web. And to suggest another example, Andy Powell has been raising some intriguing questions about how repository services should be sourced in ways that, again, map onto peoples’ experience of the web: would a consolidated network level service be more motivating than a serious of institutional presences? (see [here](https://efoundations.typepad.com/efoundations/2008/02/repositories-th.html?ref=lorcandempsey.net) and [here](https://efoundations.typepad.com/efoundations/2008/02/repositories-fo.html?ref=lorcandempsey.net)). Social networking or other services, he suggests, might flourish at this network level in ways that are not feasible at the institutional level.
When we discuss Web 2.0, there is a temptation to think about blogs and wikis, RSS and a Facebook application, and to stop there. There is also some useful thinking about how to expose web services or data in ways that they can be remixed into other applications. However, Web 2.0 is also about concentration, concentration of data, of users and of communications. We need also to think about how libraries reconfigure services in an environment of network level gravitational hubs, driven by network effects. This will involve greater concentration of library resources in various ways, and also – probably? – greater reliance on other web presences to deliver their services.
### QOTD: Spiders and flies and classics
URL: https://www.lorcandempsey.net/qotd-spiders-and-flies-and-classics/
Last updated: 2020-10-28T09:12:22.000Z
Reading *[Concerning E.M. Forster](https://www.worldcat.org/oclc/317928617?ref=lorcandempsey.net)* by Frank Kermode, I was reminded of one of my favorite quotes, Forster’s response to Eliot’s criticism of his remarks about D.H. Lawrence …
> So they corresponded and respected one another, and after Lawrence died Forster wrote that the regarded him as ‘one of the glories of our twentieth-century literature’, and ‘the greatest imaginative novelist of his generation’. On the same occasion T.S. Eliot wrote disputing that judgement: ‘unless we know exactly what Mr Forster means by *greatest*, *imaginative*, and *novelist* I submit that this judgement is meaningless’. Forster replied, ‘ Mr Eliot duly entangles me in his web. He asks what exactly I mean by “greatest”, “imaginative” and “novelist” and I cannot say. Worse still, I cannot even say what “exactly” means – only that there are occasions when I would rather be a fly than a spider, and the death of D.H. Lawrence is one of these.’ Here, if anywhere, is an occasion for Forster’s audience to stand and applaud. \[[Concerning E.M. Forster. New York: Farrar, Straus and Giroux, 2009](https://www.worldcat.org/oclc/317928617?ref=lorcandempsey.net)\]
Here is Forster’s timeline from Worldcat Identities, which shows steady ongoing interest (no doubt partly buoyed up by the movies made from his novels):
[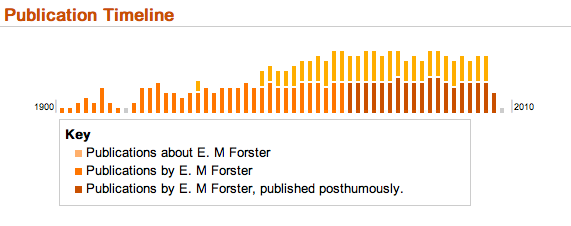](https://www.worldcat.org/wcidentities/lccn-n79-91231?ref=lorcandempsey.net#linktimeline)
Interest is steady in Lawrence also ..
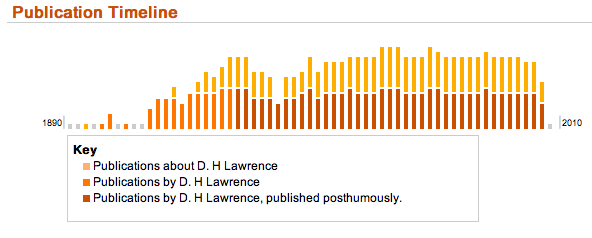
And in Eliot ..
[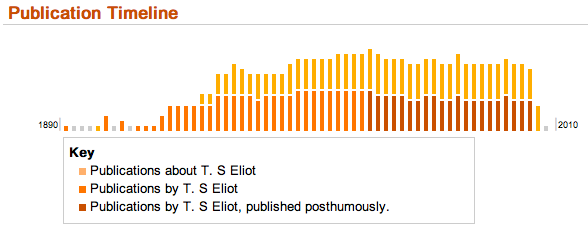](https://www.worldcat.org/wcidentities/lccn-n79-6870?ref=lorcandempsey.net)
The continued publication of editions of these authors’ works, and the appearance of works about them, is bibliographic validation of their ‘classic’ status. It would be interesting to see if you could programmatically identify ‘classics’ using clues like these (this is something we may spend some time looking at next year).
### Stuff as a service ...
URL: https://www.lorcandempsey.net/stuff-as-a-service/
Last updated: 2020-10-28T09:12:23.000Z
First, a note on a couple of recent media experiences …
We went to [The boat that rocked](https://www.imdb.com/title/tt1131729/?ref=lorcandempsey.net) (aka Pirate Radio) recently and were determined to enjoy it. For those that don’t know, it is a movie set in 1966 on a ‘pirate radio’ ship broadcasting music into the UK. However nostalgia was not enough and we were disappointed. One interesting moment was when one of the DJs – Bob – went back into the sinking radio ship to retrieve a box of LPs. He did not want to lose them, and risked his life to retrieve them. And one could understand why: it was probably a lovingly chosen collection whose assembly represented a serious investment of time and effort.
Before going on a trip recently I bought a crime novel, thinking that I might not work **all** the time I was on the plane. Until recently, I would have thought that I was adding this to my collection of books. However, all I could think of as I was buying it was that if I had a Kindle I would be acquiring it for reading not for keeping. By contrast, I am currently reading Frank Kermode’s [recent work](https://www.worldcat.org/oclc/317928617?ref=lorcandempsey.net) on E.M.Forster, a book that, for now anyway, I am happy to own.
It is clear that our attitudes to ownership have changed, perhaps largely, initially, under the influence of music. My children add songs to their iTunes library but do not seem to have a sense of a building a collection. They are aware of the financial cost of replacing what they have built, but know that it can be easily rebuilt. I have a subscription to Zune Pass and am not always sure if I am listening to music I have bought or to songs that are part of a recommended playlist or that I have downloaded to listen to while I have the subscription. Last.fm, Pandora, and Spotify, for example, have accustomed people to models of consumption which don’t depend on amassing and owning a collection of CDs or even of a collection of digital files.
Movies are following. Again, if I think of our choices at home, we can get movies from Netflix, on demand cable, Zune/xBox marketplace, iTunes. The catalog may be shallower, but a range of films is available as a service.
Increasingly, we make choices about ‘owning’, renting, or simply experiencing music and movies. Books may follow.
A while ago, Nick Carr [wrote about](https://www.roughtype.com/archives/2009/11/be%5Feverywhere%5Fn%5F1.php?ref=lorcandempsey.net) this change in our experience of music. He quoted from two BBC reports. One proclaimed “a new golden age of infinite music” in which “there’s no longer any past – just an endless present”. By contrast, he notes, John Taylor, of Duran Duran, takes a more “nuanced view” which he describes as follows: “He wonders whether such easy abundance doesn’t lead to a flattening of experience: When everything’s present, nothing’s new.” He provides a quote from Taylor, who on the basis of the ‘power’ of a TV experience, went on a ten-mile cycle looking for a record, and then listened to it again and again.
> Taylor argues that, when it comes to music or any other form of art, the price of our “endless present” is the loss of a certain “magical power” that the artist was once able to wield over the audience. I suspect he’s right. \[[Be everywhere now](https://www.roughtype.com/archives/2009/11/be%5Feverywhere%5Fn%5F1.php?ref=lorcandempsey.net)\]
So, as a full range of music, movies and maybe books becomes available to us, so too does our engagement with it change. Our sense of ownership changes, as media are delivered as a service. The work involved in assembling a personal collection diminishes. Our sense of historical perspective may change. But, I am not so sure about the loss of a certain “magical power” or the flattening of experience. Sure experiences are different. But think of an earlier transition. This magical power may also have been felt to be lost when “mechanical reproduction” allowed live performances to be shared in the first place: a recording could never take the place of a performance, could it?
Comprehensive digital availability represents another grade of experience, not a necessary withering of it. And it opens up other experiences.
Mind you, Bob probably wouldn’t have gone back for his iPod …
Related entries:
- [The Browne Issue system and the reordering of experience](https://blog.oclc.org/lorcand/archives/001200.html?ref=lorcandempsey.net)
- [Aura again: habent sua fata libelli](https://blog.oclc.org/lorcand/archives/000627.html?ref=lorcandempsey.net)
### Your new home page
URL: https://www.lorcandempsey.net/your-new-home-page/
Last updated: 2020-10-28T09:12:25.000Z
[Tony Hirst](https://ouseful.wordpress.com/?ref=lorcandempsey.net) has made the interesting observation that an organization’s real home page is the first page of its Google results.
One of the several announcements made by Google last week was one about the integration of real-time feeds in its search results.
> First, we’re introducing new features that bring your search results to life with a dynamic stream of real-time content from across the web. Now, immediately after conducting a search, you can see live updates from people on popular sites like Twitter and FriendFeed, as well as headlines from news and blog posts published just seconds before. When they are relevant, we’ll rank these latest results to show the freshest information right on the search results page. \[[Relevance meets the real-time web](https://googleblog.blogspot.com/2009/12/relevance-meets-real-time-web.html?ref=lorcandempsey.net)\]
Google still seems to be experimenting on how to incorporate these results: it is not clear yet what it will look like. Clicking on ‘[latest](https://www.google.com/search?hl=en&rlz=1C1GGLS%5FenUS291US304&tbo=1&tbs=rltm:1&q=be+good+tanyas&btnG=Search&aq=f&oq=&aqi=g10&ref=lorcandempsey.net)‘ results in the ‘Options’ shows you results, but they are also being shown sometimes on the main Google results page in a rolling window.
What happens when Twitter or Facebook feeds begin to show up on the first page of Google results?
You may end up with all sorts of comment on your home page ….
### Choice is hard work: an anecdatum
URL: https://www.lorcandempsey.net/choice-is-hard-work-an-anecdatum/
Last updated: 2020-10-28T09:12:26.000Z
We got an iMac for family use in the Summer. I never liked the keyboard and the mouse keeps sticking as crumbs and so on get lodged in it. Myself and my son headed off to [Micro Center](https://en.wikipedia.org/wiki/Micro%5FCenter?ref=lorcandempsey.net) the other evening to explore replacements. They had sold out of the new ‘magic’ mouse, so we were looking at keyboards.
Now, if I were buying a keyboard for a PC I probably would have been guided by brand and gone for a mid-price Logitech option. However, this was not on offer here. I didn’t really know anything about the brands available. As we looked at the several to chose from, I felt unable to actually select one until we had read some reviews and seen some ratings. We wandered around the store for a few minutes looking for a machine with an Internet connection so that we could do some quick research. We found one, and selected the keyboard based on a combination of price and number of stars.
I thought of this experience as I read two pieces about choice in a network age last week. The first is a nice post by Keri Smith on our aversion to taking small risks now that we can do extensive research on choices. Why buy a book by the cover when we can read the reviews …? Exactly, the type of anxiety I felt when looking at the keyboards 😉
> One of the things I been thinking about lately is how the internet is causing me to take many less risks in my life. I find myself doing entirely too much research on too many things, (god knows I love researching). But is it necessary to do it with everything? Every purchase. Every question. Every topic? My book purchasing has changed dramatically given that I am now prone to sifting through dozens of reviews trying to determine which ones are most similar to my own thought process and intellectual leanings. Instead of making judgments on the publisher’s comments, I find myself endlessly judging reviewers, people I know nothing about and probably have nothing at all in common with. This seems a strange thing when you really start to think about it. If I walked into a classroom with a hundred people in it, I would assume that only about 1% of the people would be of a similar personality to myself (maybe this percentage is low, but then I sometimes fall into the category of “fringe”). Would I take advice from the rest on what to read? Definitely not. So how is it that I judge a book on how many stars it has received? \[[The Wish Jar – risk free life](https://www.kerismith.com/blog/archives/000667.html?ref=lorcandempsey.net)\]
The second was an article in The Economist on the long tail argument. Called *[The world of hits](https://www.economist.com/displaystory.cfm?story%5Fid=14959982&ref=lorcandempsey.net)*, it had the following tag line: “Ever-increasing choice was supposed to mean the end of the blockbuster. It has had the opposite effect”. The article argues that the social nature of consumption and the efficiency of brands favor the blockbuster. It also notes an interesting phenomenon which results in a hit “being carried along by a wave of ill-informed goodwill”: “In “Formal Theories of Mass Behaviour”, William McPhee noted that a disproportionate share of the audience for a hit was made up of people who consumed few products of that type. (Many other studies have since reached the same conclusion.) A lot of the people who read a bestselling novel, for example, do not read much other fiction.”
The article looks at movies, music and books. I thought their analysis of the fate of Borders UK interesting:
> The bestsellers are gaining in part because of a change in the retail marketplace that affects other media too. High-street bookshops, which carry a reasonable selection of what publishers call “mid-list” and “back-list” titles–that is, modestly popular and somewhat out-of-date books–are struggling. Borders UK, owner of a British chain, is reportedly seeking a buyer for its stores. Such shops are being displaced by online retailers, which offer vast selections of obscure titles, and also by supermarkets, which sell a tiny selection of hugely popular books. \[[A world of hits](https://www.economist.com/displaystory.cfm?story%5Fid=14959982&ref=lorcandempsey.net)\]
In this analysis, the long tail and the thick head may end up being serviced differently, with the middle squeezed.
For libraries, I think that this confirms that ranking, relating and recommending are increasingly important. However, more subtly, it suggests that while relevance, availability, authority and other core concerns may still matter, we need to think more about appropriate emphasis where library resources sit alongside other network resources in an environment of scarce attention. I think this means being more bold in suggesting resources. And I think it means working harder to link people back to library resources from external ‘blockbuster’ services (from Google Scholar, for example). And it probably means not doing some things.
### Beyond bibliographic records
URL: https://www.lorcandempsey.net/beyond-bibliographic-records/
Last updated: 2020-10-28T09:12:30.000Z
Our cataloging model revolves around the ‘manifestation’, the particular edition or version of a work that is to be added to the collection. This is also the unit of bibliographic exchange: we ship around MARC records which have data about ‘manifestations’.
These are the ‘inputs’ into our catalogs and bibliographic systems. There is no necessary reason that they should also be the only outputs, although this is in fact what is usually the case. Searches tend to result in lists of entries for manifestations, each of which displays some subset of the data in the bibliographic record.
Recent catalogs have only changed this model slightly. Faceted browse, for example, typically allows manifestations to be brought together by some ‘facet’: subject, place of publication, or date, for example. The facets themselves, potentially interesting ways of organizing data for presentation to a reader, don’t tend to be used in this way.
What is an example of an alternative? Worldcat Identities provides an example of how a person or organization might be used as an organizing principle for displaying data. Here, we pull data from many records, recombine it, and present it in an integrated way. So an Identities page has, for example, a list of books by a person and about a person; it has alternative forms of the name of that person; it has related persons (or organizations); it has a concept-based tag-cloud representing the publications by and about that person; and so on. Here is the page for Don Knuth (click on it to see the full page):
[](https://www.worldcat.org/wcidentities/lccn-n79-135509?ref=lorcandempsey.net)
We have done some work on similar sorts of pages for works. It would be nice to think of this type of organization for places.
In fact, our bibliographic records contain data about lots of entities about which people have an interest, or about which they ask questions. These include works, people, places, subjects, time periods, … However, our manifestation-record-oriented view means that we do not always exploit these data in ways in which they can be mobilized to answer those questions.
Of course, we do also manage other data as ‘records’: name and subject authorities for example. But these are not used extensively as structured data, and are often collapsed to strings in the bibliographic records. Other futures for this type of data are interesting to consider, but not here.
Now, I was prompted to write this by an interesting post by John Mark Ockerbloom who talks about ‘concept-oriented’ catalogs. (Note: by ‘concept’ John means ‘thing’ or ‘entity’ or ‘object’. In some ways, ‘Concept’ is confusing here because it might be thought that he is meaning a ‘subject’ in library terms, something about which we have a lot of coded data. That said, we don’t have agreed words for all that we want to talk about.)
> As more and more knowledge resources become available to users, via the expansion of the Internet, the streamlining of interlibrary loan services, and the mass digitization of print library materials, well-defined, well-documented, and well-connected concepts will become increasingly important for readers that want to find what is most useful to them in a sea of information. While we will never have well-defined concepts for everything readers might be interested in, the concepts that have been defined by someone, somewhere, can serve as valuable guideposts for subsequent information seekers, if we’re smart about managing and using them. \[[Understanding concept-oriented catalogs](https://everybodyslibraries.com/2009/12/04/understanding-concept-oriented-catalogs/?ref=lorcandempsey.net)\]
John notes as examples Worldcat Identities and [FictionFinder](https://fictionfinder.oclc.org/?ref=lorcandempsey.net) (an earlier prototype designed to show how data could be mobilized around works. I always liked the way this allowed you to search for ‘settings’: for example, you can search for detective novels set in Edinburgh, etc). He also notes the [Subject Maps](https://labs.library.upenn.edu/subjectmaps/?ref=lorcandempsey.net) work he is involved in at the University of Pennsylvania.
Libraries have managed bibliographic records, containers of data. The directions above point to a growing interest in seeing how they might more actively manage the data itself, making it work harder to provide information about entities of interest to their readers.
### QOTD: Great cultural collisions
URL: https://www.lorcandempsey.net/qotd-great-cultural-collisions/
Last updated: 2020-10-28T09:12:33.000Z
There is an interview with Paul McGuinness, manager of U2, in the weekend FT. McGuinness has been an active participant in discussions about the impact of network distribution on the music business (see [here](https://www.billboard.biz/bbbiz/content%5Fdisplay/industry/e3i062b16e707aa99916c212e660cbffd3e?ref=lorcandempsey.net) for example).
Given the recent discussions around Google Book Search and around indexing of newspaper content, I thought this was another interesting example of struggles between new and old world orders.
> “All right, it’s been the law of the jungle many times,” McGuinness says as our drinks arrive. “But what dismays me a little about the online universe is that these corporations, like Google and MySpace and Apple, don’t have anything that’s the equivalent of artist relations.”
> One day, tech groups will have their own talent scouts and digital versions of record labels, he predicts. For now, the “great cultural collisions” taking place worry him. “I find I’m often dealing with \[technology\] executives who are really quite careless and frequently arrogant about the cultural impact of what they’re doing. I wish there were an atmosphere of nurturing and respect, which I really don’t see.” \[[Lunch with the FT: Paul McGuinness](https://www.ft.com/cms/s/2/8c1788d2-e059-11de-8494-00144feab49a.html?ref=lorcandempsey.net)\]
### Counting books ...
URL: https://www.lorcandempsey.net/counting-books/
Last updated: 2020-10-28T09:12:38.000Z
I have been careful in recent posts about numbers to note that the term ‘book’ has no precise referent. One person’s book is another person’s pamphlet, or …
Brian Lavoie and I have an article in the current issue of *DLib Magazine* which uses Worldcat to estimate the number of print books published in the US which are potentially in copyright (i.e. with a publication date of 1923 or later). Of course, this question has been given currency in recent years by the mass digitization of library book collections, notably by Google.
> This article characterizes the aggregate collection of US-published print books in WorldCat, with a special emphasis on materials published during or after 1923, and therefore either potentially or definitely in copyright. Findings from the analysis indicate that the collection of US-published print books in WorldCat is quite large, encompassing about 15.5 million print books. Nearly two-thirds of these – those published after 1963 – have a high likelihood of being in copyright; less than 15 percent – those published prior to 1923 – are almost certainly in the public domain, with the rest – those published between 1923 and 1963 – potentially in copyright if copyright was renewed. The post-1923 materials collectively account for more than 80 percent, or about 12.6 million, of the US-published print books in WorldCat. It is difficult to predict how many of these print books might be orphan works, but even a small fraction would, in terms of absolute numbers, be considerable, and require a substantial effort to investigate and clear copyright. \[[Beyond 1923](https://www.dlib.org/dlib/november09/lavoie/11lavoie.html?ref=lorcandempsey.net)\]
In order to generate various counts decisions have to be made about what to count. And those decisions have to be based on what can be supported in the data that we have. I was talking to Brian about some of these decisions a while ao, and he wrote up some of his comments which I include here.
> “As a non-librarian who works with library data on a regular basis, I was surprised to learn that the commonplace object ‘book’ is not well-defined in traditional cataloging practice. This is all the more surprising when one considers that historically, libraries were built around aggregations of books. The difficulty is that there are no explicit bibliographic criteria for identifying something most people would recognize as a ‘book’. So for example, consider a simple question like ‘How many books are in WorldCat?’ In the bibliographic universe, there is nothing explicitly defined as a ‘book’: there are monographs, or more narrowly, language-based monographs, but the items falling into these categories are not necessarily books as we might commonly perceive them. Is a government document a book? A dissertation? A technical report? A pamphlet of only a dozen pages? These kinds of materials, and more, get included when we use a construct like ‘language-based monographs’ as a proxy for ‘books’.
> “Why is this important? The concept of “books” is appearing in a variety of current discussions, most notably in the context of digitization issues like the Google book settlement. So we are often asked questions like, ‘how many print books in WorldCat have been published after 1923?’ We can provide answers to these questions, but only with a degree of approximation built in: i.e., we can calculate a number that reflects something along the lines of ‘all language-based monographs in WorldCat, excluding dissertations and government documents’; we can even throw in a minimum page requirement (at least 49 pages, according to the UNESCO definition of a book). But we can’t say exactly how many books are in WorldCat, because from a cataloging standpoint, we don’t know what a book is. Libraries are grappling with difficult new questions these days, as collections and services transition from print to digital, from local to the network. But an old question still remains: what is a book?” \[Personal communication from Brian Lavoie\]
\[**Note**: Updated to include later version of Brian’s quote. This is repeated from an earlier entry [On books again](https://blog.oclc.org/lorcand/archives/002000.html?ref=lorcandempsey.net).\]
### Network as a service ...
URL: https://www.lorcandempsey.net/network-as-a-service/
Last updated: 2022-11-08T16:55:17.000Z
We have entered the era of *Everything-as-a-service*, where lowering transaction costs mean that a growing range of capacities can be sourced from the cloud.
It has become common to talk about a threefold model:
1. Software or applications as a service. A particular application may be used in the cloud (for example, Salesforce.com or Webex web meetings).
2. Platform as a service. A development environment is provided which supports application development (for example, [Azure](https://www.microsoft.com/windowsazure/windowsazure/?ref=lorcandempsey.net), Microsoft’s cloud operating system, or [force.com](https://www.salesforce.com/platform/?ref=lorcandempsey.net) from Salesforce).
3. Infrastructure as a service. Computing or storage or some other infrastructure component is provided (an example is the computing and storage services available from Amazon).
Recently, I have been wondering about ‘network as a service’. Think of Facebook and eBay. In each case, a major part of their value for third party developers is access to a ‘network’ of other users. And this is an explicit part of the offer of Facebook and eBay. In the former case, a developer can ‘[leverage the social graph](https://developers.facebook.com/cases/?ref=lorcandempsey.net)‘; in the latter, developers have access to the ‘[largest ecommerce opportunity on the web](https://developer.ebay.com/businessbenefits/?ref=lorcandempsey.net)‘. There are cases where access to a network is a useful feature of a service, even when network creation is not its primary purpose. Take for example firms which provide Employee Opinion Survey services. A firm which provides this service to many organizations will have benchmarking and comparison data which will make them an attractive option for some potential clients.
Business models vary in these examples, and in some cases the ‘interconnectedness’ of the network provided is important, in other cases less so. Value may reside in access to the network, or access to intelligence generated by the network (analytics data).
I have been thinking about this in the context of Worldcat. Worldcat is a bibliographic database. A major part of its value however is in the holdings data: it associates bibliographic items with libraries which hold them. In other words it creates a library network. OCLC leverages this network in other services – notably resource sharing. The Worldcat network is also leveraged by services provided by other organizations. For example, it provides a switch between other bibliographic services (Google Book Search, LibraryThing, OpenLibrary, Goodreads, ec) and library collections.
It provides a network as a service …
### Social tools and science
URL: https://www.lorcandempsey.net/social-tools-and-science/
Last updated: 2021-04-11T17:58:43.000Z
In her report on Open science at webscale, I was interested to see Liz Lyon give the following list of tools used to share their work by researchers.
> Currently, researchers are using open science tools such as:
>
> - Connotea for reference management
> - Mendeley (which applies LastFM principles associated with music selections to journal articles)
> - Friendfeed (for threaded discussion and aggregation)
> - Scivee and YouTube (for sharing experimental methodologies and protocols)
> - SciLink and Nature Networks (for social networking)
> - myExperiment (for sharing workflows)
> - eyeLIMS (an open source Laboratory Information Management System)
> - LabLit.com (about science/laboratory culture in the literature and media)
> - ConceptWeb (from WikiProfessional and includes WikiPeople and WikiProteins)
From: *Open science at webscale* \[[PDF](https://www.jisc.ac.uk/media/documents/publications/research/2009/open-science-report-6nov09-final-sentojisc.pdf?ref=lorcandempsey.net)\].
### Libraries and e-science
URL: https://www.lorcandempsey.net/libraries-and-e-science/
Last updated: 2020-10-28T09:12:48.000Z
Emerging data-intensive e-science presents many support challenges for institutions, disciplines and national bodies to work through. The role of the academic library in this multiscale world is also an open question. Two recent reports discuss e-science (or ‘cyberinfrastructure’ or ‘e-research’) in general terms and repay reading.
Liz Lyon, the Director of UKOLN, and also a principal in the Digital Curation Centre, has focused on this area for several years now and has produced an interesting synthesising report for the JISC: *Open science at web-scale: optimising participation and predictive potential: consultative report* \[[Summary](https://www.jisc.ac.uk/publications/documents/opensciencerpt.aspx?ref=lorcandempsey.net); Full report [PDF](https://www.jisc.ac.uk/media/documents/publications/research/2009/open-science-report-6nov09-final-sentojisc.pdf?ref=lorcandempsey.net)\]. An important theme of the report is ‘data informatics’, defined in this way: “library and information science methodologies which have been applied to research data”.
The report is organized around six ‘consultation challenges’. The first is ‘scale, complexity and predictive potential’. Here is the summary:
> Data-intensive science powered by contemporary computational hardware, software and research techniques, enables scientists to perform experiments and calculations at different orders of magnitude of scale and volume: research that was completed in a year can now be repeated in a weekend. Sustained growth in data modelling, complex simulations and visualisations, facilitate interpretation and analysis by humans and machines, leading to the development of predictive science scenarios in a wider range of disciplines. Examples of data intensive science at these extremes of scale, which enable forecasting and predictive assertions, have been described.
> Assessments of the accuracy and robustness of predictions are linked to uncertainty quantification, the accuracy of the underlying model, and the integrity of the data. Key questions address community awareness and understanding of the potential implications and impact of (open) data-intensive science at new extremes of scale and complexity, and the service requirements for associated data curation and preservation. \[Open science at web-scale: Optimising participation and predictive potential – [summary](https://www.jisc.ac.uk/publications/documents/opensciencerpt.aspx?ref=lorcandempsey.net)\]
To give some flavor of concerns, here are the other challenges: Continuum of openness; citizen science; credentials, incentives and rewards; institutional readiness and response; data informatics capacity and capability. A brief chapter is devoted to each.
The author is positive about the role of libraries and librarians, particularly in the data informatics section. That said, given the absence of routine service and organizational responses the library role is still expressed in very general terms. What it might mean in practice is naturally less well developed.
The other publication is a collection of essays assembled in honor of Jim Gray:
> In *The Fourth Paradigm: Data-Intensive Scientific Discovery*, the collection of essays expands on the vision of pioneering computer scientist Jim Gray for a new, fourth paradigm of discovery based on data-intensive science and offers insights into how it can be fully realized. \[[The fourth paradigm](https://research.microsoft.com/en-us/collaboration/fourthparadigm/?ref=lorcandempsey.net)\]
For Gray the first three paradigms are experimental, theoretical, and computational.
> We said, “Look, computational science is a third leg.” Originally, there was just experimental science, and then there was theoretical science, with Kepler’s Laws, Newton’s Laws of Motion, Maxwell’s equations, and so on. Then, for many problems, the theoretical models grew too complicated to solve analytically, and people had to start simulating. These simulations have carried us through much of the last half of the last millennium. At this point, these simulations are generating a whole lot of data, along with a huge increase in data from the experimental sciences. People now do not actually
> look through telescopes. Instead, they are “looking” through large-scale, complex
> instruments which relay data to datacenters, and only then do they look at the information on their computers.
> The world of science has changed, and there is no question about this. The new model is for the data to be captured by instruments or generated by simulations before being processed by software and for the resulting information or knowledge to be stored in computers. Scientists only get to look at their data fairly late in this pipeline. The techniques and technologies for such data-intensive science are so different that it is worth distinguishing data-intensive science from computational science as a new, *fourth paradigm* for scientific exploration \[1\]. \[Jim Gray on escience – [PDF](https://research.microsoft.com/en-us/collaboration/fourthparadigm/4th%5Fparadigm%5Fbook%5Fjim%5Fgray%5Ftranscript.pdf?ref=lorcandempsey.net).\]
The collection of essays is divided into these sections: Earth and environment; Health and wellbeing; Scientific infrastructure; Scholarly communications. And there are opening and concluding sections. The contributions are readable and in the form of short essays rather than research papers. There is a contribution by Cliff Lynch on the changing scholarly record, by Timo Hannay on the impact of the network on the structure of science, and by Herbert Van de Sompel and Carl Lagoze on the enhancement of the scholarly record with actionable structure.
There is no specific contribution on libraries, and it is interesting to note that the directions of much of the occasional mention of libraries is towards network level digital libraries.
It is important for libraries to understand these changes. The reshaping impact of the network on learning and research behaviors is a more important factor for libraries than the direct impact of the network on library processes themselves.
### Reputation enhancement redux
URL: https://www.lorcandempsey.net/reputation-enhancement-redux/
Last updated: 2020-10-28T09:12:50.000Z
I wrote recently about the growing interesting in reputation management on the web.
> Reputation management on the web – individual and institutional – has become a more conscious activity for many, as ranking, assessment and other reputational measures are increasingly influenced by network visibility. In particular, it raises for academic institutions an issue that has become a part of many service decisions: what is it appropriate to do locally? What should be sourced externally? And what should be left to others to do? \[[Reputation enhancement](https://blog.oclc.org/lorcand/archives/002011.html?ref=lorcandempsey.net)\]
This is a wide-ranging issue, pulling together in various ways overlapping issues such as individual and institutional disclosure of research and other outputs; emerging academic social networking practices; formal expertise and research output management; search engine optimization strategies; practices for improving citation, ranking and reputation measures; social reference/bibliography; and so on. I think that we will see some of this activity become more routine in organizational and operational terms over the next few years.
In this context, I was interested to see a presentation on research support by Rachel Cowan and Alex Hardman from the University of Manchester. They focus on reputation and network identity as important parts of overall research management.
[Technology Enabled Research](https://www.slideshare.net/actualal/technology-enabled-research-2472720/22?ref=lorcandempsey.net "Technology Enabled Research")
View more [presentations](https://www.slideshare.net/?ref=lorcandempsey.net) from [Alex Hardman](https://www.slideshare.net/actualal?ref=lorcandempsey.net).
The presentation has three strands: developing reputation through a digital identity, keeping on top of the literature, and extending research connections. Of these, the first and third relate broadly to reputation enhancement or management in a web environment.
They ask the audience if a personal Google search does a good job of showcasing their identity and research. (This reminds me of Tony Hirst’s comment that our ‘home page’ in now the first page of Google results.) Then they talk through some of the ways in which people develop digital identities (blogs, twitter, …). They also review some social networking and other tools of interest in an academic context.
Here is their overview of activities mapped onto services (click to see in situ with ability to enlarge):
[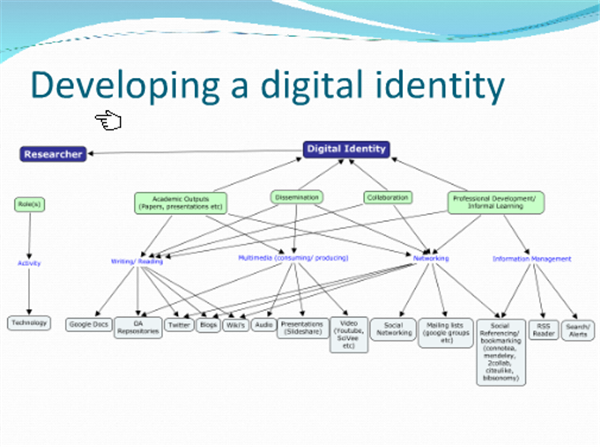](https://www.slideshare.net/actualal/technology-enabled-research-2472720/22?ref=lorcandempsey.net)
### QOTD: protocol-based time travel for the web
URL: https://www.lorcandempsey.net/qotd-protocol-based-time-travel-for-the-web/
Last updated: 2020-10-28T09:12:53.000Z
We are pleased that Herbert Van de Sompel will be talking about Memento, a joint project of Los Alamos National Laboratory and Old Dominion University, at OCLC later this month. We will make a webcast available; see the details [here](https://www.oclc.org/research/news/2009-11-06.htm?ref=lorcandempsey.net). If you are in Central Ohio, come by ….
Here is a recent paper describing the work:
> The Web is ephemeral. Many resources have representa-
> tions that change over time, and many of those represen-
> tations are lost forever. A lucky few manage to reappear
> as archived resources that carry their own URIs. For ex-
> ample, some content management systems maintain version
> pages that reflect a frozen prior state of their changing re-
> sources. Archives recurrently crawl the web to obtain the
> actual representation of resources, and subsequently make
> those available via special-purpose archived resources. In
> both cases, the archival copies have URIs that are protocol-
> wise disconnected from the URI of the resource of which
> they represent a prior state. Indeed, the lack of temporal
> capabilities in the most common Web protocol, HTTP, pre-
> vents getting to an archived resource on the basis of the
> URI of its original. This turns accessing archived resources
> into a signicant discovery challenge for both human and
> software agents, which typically involves following a mul-
> titude of links from the original to the archival resource,
> or of searching archives for the original URI. This paper
> proposes the protocol-based Memento solution to address
> this problem, and describes a proof-of-concept experiment
> that includes major servers of archival content, including
> Wikipedia and the Internet Archive. The Memento solution
> is based on existing HTTP capabilities applied in a novel
> way to add the temporal dimension. The result is a frame-
> work in which archived resources can seamlessly be reached
> via the URI of their original: protocol-based time travel for
> the Web. \[[Memento](https://arxiv.org/PS%5Fcache/arxiv/pdf/0911/0911.1112v2.pdf?ref=lorcandempsey.net)\]
### Libraries and the long tail: intro
URL: https://www.lorcandempsey.net/libraries-and-the-long-tail-intro/
Last updated: 2020-10-28T09:12:55.000Z
Discussing grades of availability in [my last post](https://blog.oclc.org/lorcand/archives/002019.html?ref=lorcandempsey.net), I mention an article I wrote a few years ago on libraries and the long tail. Here is how it starts:
> Discussions of the long tail that I have seen or heard in the library community strike me as somewhat partial. Much of that discussion is about how libraries contain deep and rich collections, and about how their system-wide aggregation represents a very long tail of scholarly and cultural materials (a system may be at the level of a consortium, or a state, or a country). However, I am not sure that we have absorbed the real relevance of the long tail argument, which is about how well supply and demand are matched in a network environment. It is not enough for materials to be present within the system: they have to be readily accessible (‘every reader his or her book’, in Ranganathan’s terms), potentially interested readers have to be aware of them (‘every book its reader’), and the system for matching supply and demand has to be efficient (‘save the time of the user’). \[[Libraries and the long tail: some thoughts about libraries in a network age](https://www.dlib.org/dlib/april06/dempsey/04dempsey.html?ref=lorcandempsey.net)\]
Incidentally, I think Ranganathan’s 5 laws \[[Wikipedia entry](https://en.wikipedia.org/wiki/Five%5Flaws%5Fof%5Flibrary%5Fscience?ref=lorcandempsey.net)\] remain relevent in lots of ways to current discussions, as above.
### On the discriminations of availability ...
URL: https://www.lorcandempsey.net/on-the-discriminations-of-availability/
Last updated: 2021-04-04T23:56:20.000Z
[Seamus Heaney](https://www.worldcat.org/wcidentities/lccn-n79-99140?ref=lorcandempsey.net) famously – and in poetry – complained about being included in an anthology of ‘British’ poetry. In the course of [his poem](https://www.worldcat.org/oclc/10359386?ref=lorcandempsey.net) he invokes [Miroslav Holub](https://www.worldcat.org/wcidentities/lccn-n50-28157?ref=lorcandempsey.net)‘s ‘On the necessity of truth’ where a man creates a disturbance in a cinema when he sees a beaver mistakenly called a muskrat on the screen. The man wants to set the record straight.
I don’t have a copy of Heaney’s work as I write this, but I can point to a [discussion of the passage](https://books.google.com/books?id=b%5Fed7AUp-hUC&lpg=PA148&dq=beaver%20heaney%20holub&lr=&pg=PA148&ref=lorcandempsey.net#v=onepage&q=beaver%20heaney%20holub&f=false) in *[Acting between the lines : the Field Day Theatre Company and Irish cultural politics, 1980-1984](https://www.worldcat.org/oclc/30508889?ref=lorcandempsey.net)* courtesy of Google Books.
(And it would be nice to be able to easily reference the appropriate parts of both Heaney’s and Holub’s works on the web. I find that I am increasingly expecting to be able to find book text online – when looking for a quote, when helping with homework, etc.)
Now, a few weeks ago, Sergey Brin wrote an [op-ed piece](https://www.nytimes.com/2009/10/09/opinion/09brin.html?ref=lorcandempsey.net) about Google Books in the New York Times.
He discusses the fate of books still potentially in copyright:
> But the vast majority of books ever written are not accessible to anyone except the most tenacious researchers at premier academic libraries. Books written after 1923 quickly disappear into a literary black hole. With rare exceptions, one can buy them only for the small number of years they are in print. After that, they are found only in a vanishing number of libraries and used book stores. As the years pass, contracts get lost and forgotten, authors and publishers disappear, the rights holders become impossible to track down.
> Inevitably, the few remaining copies of the books are left to deteriorate slowly or are lost to fires, floods and other disasters. While I was at Stanford in 1998, floods damaged or destroyed tens of thousands of books. Unfortunately, such events are not uncommon — a similar flood happened at Stanford just 20 years prior. You could read about it in The Stanford-Lockheed Meyer Library Flood Report, published in 1980, but this book itself is no longer available. // [A library to last forever](https://www.nytimes.com/2009/10/09/opinion/09brin.html?ref=lorcandempsey.net)
It was soon pointed out in the library community that *The Stanford-Lockheed Meyer Library flood report*, was still ‘available’ in as much as it was held by several libraries. Worldcat.org showed [four libraries](https://www.worldcat.org/oclc/18540285?ref=lorcandempsey.net) holding it, and there are probably more. There was some discussion on the Web4lib mailing list along these lines for example.
At the same time, on a closed mailing list in which I participate, one commenter argued that this level of availability meant that the volume was actually not available in any ‘practical sense’.
As it is available in the ‘library system’, the report is available to library users across the country. However, they have to be affiliated with a library which offers an Inter Library Lending service, they have to know about it, they have to submit a request, and they have to wait for it to arrive.
Certainly, if the report were available through Google Books (or some other network level repository of digital books), its availability would be greatly amplified.
It is clear that there are grades of availability. As some level the transaction costs – or, as importantly, the price – of acquiring something may be considered too high for it to be considered available in a ‘practical sense’. But your mileage may vary.
In this case, the fact that it is in the ‘library system’ means that it is potentially ‘available’ to library users anywhere through the inter library lending arrangements in which most North American libraries participate. The book is available in a very real way for somebody who wants to see it with a little persistence. And through the public availability of Worldcat and other resources, and the greater prominence and ease of use of end-user requesting, the transaction costs have gone down. And there is a link to Worldcat from the [Google Books record](https://books.google.com/books?id=D%5Fv-HAAACAAJ&dq=The+Stanford-Lockheed+Meyer+Library+flood+report&ei=73%5FuSpaiMoWIygTww6m9Aw&ref=lorcandempsey.net) for the report.
However, it would seem that the transaction costs are still too high for many. Libraries do not yet appear as a ‘system’ on the web, in the sense of being able to support well-seamed easy to use discovery, request and delivery across the system. And, of course, instant digital availability sets a different expectation than such a system currently provides.
That said, it seemed to me (as it did to the librarians on the web4lib discussion list) that saying that this volume was no longer available was a stronger statement than the situation warranted. I could go with ‘not easily available’, but ‘no longer available’ was too much …
And as I sat there looking at something being called a muskrat, I wanted to say, no, it is a beaver …. 😉
**Related:**
- [Libraries and the long tail: some thoughts about libraries in a network age](https://www.dlib.org/dlib/april06/dempsey/04dempsey.html?ref=lorcandempsey.net)
### Community bibliography
URL: https://www.lorcandempsey.net/community-bibliography/
Last updated: 2020-10-28T09:12:58.000Z
I prefer ‘crowdsourced’ to ‘user contributed’ but neither works very well for me. In particular ‘user contributed’ does not seem a good term at all for a variety of reasons. Anyway, I was looking at the [new catalogue](https://bibliocommons.biblioottawalibrary.ca/?ref=lorcandempsey.net) at Ottawa Public Library powered by [Bibliocommons](https://www.bibliocommons.com/?ref=lorcandempsey.net) earlier (following a mention by Stephen Abram).
[](https://bibliocommons.biblioottawalibrary.ca/item/show/1429847014%5Fbrooklyn?ref=lorcandempsey.net)
There is much to like about this. It is not organized around the bibliographic record, but places that data in a context more aligned with user interests. Indeed, the bibliographic data ‘block’ is hidden behind a tab. The most prominent features, alongside the picture, are user **actions**: it invites readers to do things. You can add data, add it to your own personal collection, add it to a list. I liked the *Browse the shelf* feature. This is one of several options which allows ‘exploration’ based on attributes shared with the displayed item.
What jumped out at me was how the block at the bottom of the screen was named: *Community activity* seemed like a very good name in this case.
The community features are interesting and feel familiar from other environments. A reader can ‘connect’ with others who have selected the item being viewed. The connections work across libraries in which Bibliocommons is deployed. Here is one of the people listed on this display.
[](https://bibliocommons.biblioottawalibrary.ca/collection/show/69133211%5Fmarybennett/library?ref=lorcandempsey.net)
The left hand column here carries through the ‘narrow by facet’ feature found on results pages.
Some details about Bibliocommons are provided in an article in the [October 2009 issue of The Walrus](https://www.walrusmagazine.com/articles/2009.10-frontier-biblio-tech/?ref=lorcandempsey.net). Here are some excerpts.
> The system launched in Oakville in July 2008; Edmonton and Ottawa go live this fall; locations across Ontario and British Columbia, and as far away as California and Australia, will follow.
> Instead of relying on librarians to act as gatekeepers for collections that are increasingly virtual and global in scope, BiblioCommons harnesses crowds of users to guide one another — a familiar Internet tactic.
> Getting people to participate in BiblioCommons will require seamless in-tegration with existing library catalogues, so that input from other users — and the opportunity to contribute — arise naturally from the experiences of browsing the catalogue and renewing books. The greater technical challenge lies in integrating the patchwork of different systems across the continent. “Librarians care a lot about the details of their catalogues,” Jefferson says diplomatically. But libraries have one key advantage over commercial sites: “People really want to support their libraries,” she says. “There’s a goodwill that Amazon or Chapters simply don’t inspire.”
I enjoyed looking around this and other Bibliocommons sites. It will be interesting to see how Bibliocommons develops, and whether it achieves the scale of participation to succeed more widely. It is not about ‘user contributed’ content, but what my colleague Stu Weibel calls ‘social bibliography’, or maybe ‘community bibliography’ (OK, let’s be generous abut the term ‘bibliography ;-). Community, as I [remarked](https://blog.oclc.org/lorcand/archives/002013.html?ref=lorcandempsey.net) the other day, is the new content.
Related entries:
- [Community is the new content](https://blog.oclc.org/lorcand/archives/002013.html?ref=lorcandempsey.net)
- [Some thoughts about egos, objects and social networks …](https://blog.oclc.org/lorcand/archives/001601.html?ref=lorcandempsey.net)
### Research support services
URL: https://www.lorcandempsey.net/research-support-services/
Last updated: 2020-10-28T09:13:00.000Z
I am pleased to note a collaboration between OCLC Research and the [Research Information Network](https://www.rin.ac.uk/?ref=lorcandempsey.net) in the UK to explore changing research support needs in universities.
We tend to focus on how technology changes library practices, but the impact of technology on libraries will be less important in the long term than the impact of technology on research practices, which in turn the library must be well-placed to support.
> The project will investigate researchers’ needs and desires in a small sample of UK and US universities to identify the significant patterns, intersections, gaps and issues from researchers’ points of view, whatever the source of such services. The nature and scope of research support services will be documented, providing examples of good practice, recommending areas where new practice might emerge and identifying possible areas and scope for collaboration within and between institutions. Comparing transnational academic practices will provide evidence and encourage coordination to meet the needs of academic research internationally. \[[OCLC Research and The RIN announce joint project on research support services](https://www.oclc.org/research/news/2009-10-15.htm?ref=lorcandempsey.net)\]
This work is being carried out in support of the RLG Partnership as part of the [Research Information Management](https://www.oclc.org/research/activities/rim.htm?ref=lorcandempsey.net) theme and we anticipate completing it in May 2010.
### Untangling the library systems environment
URL: https://www.lorcandempsey.net/untangling-the-library-systems-environment/
Last updated: 2020-10-28T09:13:02.000Z
NISO organized a [meeting](https://www.niso.org/news/events/2009/lrms09?ref=lorcandempsey.net) on library resource management a couple of weeks ago: I notice that the [presentations](https://www.niso.org/news/events/2009/lrms09/agenda?ref=lorcandempsey.net) are now available on the web. They make an interesting collection, and I return to them in a moment.
I have written about the library systems environment in these pages from time to time. A [blog entry](https://blog.oclc.org/lorcand/archives/001379.html?ref=lorcandempsey.net) from Summer 2007 formed the basis of a Portal article \[[pdf](https://www.oclc.org/research/publications/library/2008/dempsey-portal.pdf?ref=lorcandempsey.net)\] of the same name (*Reconfiguring the library systems environment*), which had these pictures:

Libraries manage a variety of materials workflows, each supported by a different systems apparatus. In each case there is a vertical arrangement, as materials are disclosed through discovery and delivery services which in turn relate to backend management services in closely coupled ways. Bought (often print) materials go through an ILS workflow and are disclosed through the catalog which is usually a part of the ILS itself. Systems to manage these materials in resource sharing arrangements may also be present. Licensed materials have an emerging apparatus of management systems support (ERM, knowledgebase, A-Z lists, and so on) and are disclosed in a variety of ways including metasearch and resolvers. A routine approach has not emerged for digital materials and they are managed in a variety of repository and other frameworks, and delivered to per-repository user interfaces. Different approaches may be taken with different categories – digitized special materials, web archives, institutional research materials, and so on – and metadata may be exposed for harvesting. Although not pictured here, one might add that there may also be additional workflows associated with archival materials or special collections. (Slide 4 of Mackenzie Smith’s presentation \[[ppt](https://www.niso.org/apps/group%5Fpublic/download.php/2895/smith%5Flrms09niso.ppt?ref=lorcandempsey.net)\] is an interesting depiction of the internal library systems environment showing the range of actual systems supported.)

The complex array of systems – at different stages of maturity and created in quite different technical environments – has encouraged a move towards some rationalization and integration. In particular, we can see a drive to integrate the management workflows across material types. Examples here are OCLC’s Cooperative Webscale Management Systems initiative, Ex Libris’s URM, and the open source OLE project. At the same time, we see two trends on the discovery side. The first is a drive towards deeper integration across types, both through greater use of metasearch and through actual consolidation of files. Althought it will not be comprehensive of all available materials, we will see much more of the latter approach for efficiency reasons. The second is a realization that library resources need to be disclosed more effectively to a variety of other environments, whether they are other institutional systems (e.g. course management) or external.

So, finally I note two major challenges. One is that on the management side libraries have to pull together a variety of systems and services whose legacy business and technical boundaries may no longer map very well onto user requirements. A second is that they have to project their resources into a variety of user environments and workflows over and above whatever integrated local library website environment they create. These include personal (people have a growing variety of ways of finding, saving and collecting information resources), institutional (think of course management systems, student portals, …), and network-level services (search and discovery services; social networking, bookmarking and bibliography sites; …). Related to this is the challenge of integrating community in library services: there is a gap between libraries as inevitably social organizations and the social component of the library experience on the web. A redrawing of this image today would have to include a better sense of user participation.
In this context, here are some incomplete notes on some of the presentations at the NISO meeting:
- **General overviews** were given by Oren Beit-Arie \[[ppt](https://www.niso.org/apps/group%5Fpublic/download.php/2885/beitarie%5Flrms09niso.ppt?ref=lorcandempsey.net)\] and Marshall Breeding \[[pptx](https://www.niso.org/apps/group%5Fpublic/download.php/2887/breeding%5Flrms09niso.pptx?ref=lorcandempsey.net)\] in a wide-ranging opening keynote and conclusion respectively. Oren presents a picture not unlike the one suggested above, discussing the need to move from content-based verticals to service-based horizontals. The context for much of what he says is provided by a summary of responses from interviews with librarians. Here are the headline requirements (adapted slightly): a single interface for discovery and delivery of all library/institutional assets; consolidated workflows, uniting traditional library functions with those of the “digital library”; collaboration to increase productivity, leveraging “network effect”; re-use of metadata; SOA-based interoperability; software-as-a-service deployment option; user-provided data. He characterizes evolving services within a traditional/transitional/transformational framework, where traditional involves doing the same thing differently, transitional involves doing new things in support of the transitional, and transformational involves doing new things. Moving services to the cloud is given as an example of the traditional, as is evolution of the cataloging environment; exploiting network effects (e.g. collaborative collection development, tagging of library images in Flickr, ..) is given as an example of transitional; and the mobilization of usage data to transform services (new metrics of scholarly evaluation, recommender systems, analytics and ranking of results) is given as an example of transformational services.
- **System sourcing** decisions and their implications figure large in the agenda given the recent focus on open source approaches. Marshall Breeding \[[pptx](https://www.niso.org/apps/group%5Fpublic/download.php/2887/breeding%5Flrms09niso.pptx?ref=lorcandempsey.net)\] cryptically notes ‘many unannounced open source projects’ which may change the current low defection rates from established ILS vendors. How will open source initiatives work with emerging software as a service trends?
- **Recommendation** and other ways of mobilising usage (or intentional) data figure in several places, in line with general trends. I [suggested](https://blog.oclc.org/lorcand/archives/002013.html?ref=lorcandempsey.net) recently that we will see services which don’t use direct user input in the form of tagging or review, and indirect in the form of usage data to support ranking, relating and recommending, as bleached, rather like black and white TV in a color world. See Kevin Kidd’s presentation \[[ppt](https://www.niso.org/apps/group%5Fpublic/download.php/2892/kidd%5Flrms09niso.ppt?ref=lorcandempsey.net)\], as well as Oren’s, on this issue.
- **Scalar emphasis** has become an important question for libraries. At what scale should things be done as institution-scale is increasingly the wrong level for many activities? Oren discusses the transitional effect of the network in broader collaborative settings, where the power of the network can be leveraged to improve services. Shared cataloging and resource sharing may be earlier instances of this. Consider now the potential for recommendations where circulation or other usage data is aggregated at a higher level. Consider incentives also in this context. Where are library users most likely to want to invest their effort? Kat Hagedorn \[[ppt](https://www.niso.org/apps/group%5Fpublic/download.php/2891/hagedorn%5Flrms09niso.ppt?ref=lorcandempsey.net)\] discusses a collaborative project of the HathiTrust, New York University, and the partners in the ReCAP shared print facility with the involvement of OCLC Research and CLIR. What policy and service apparatus needs to be in place to provide confidence of supply from HathiTrust and ReCAP sufficient to allow NYU relegate materials from its own collection? Such ‘cloud library’ provision will become more common as libraries seek to transfer resource away from ‘infrastructure’ and towards user engagement. Kyle Bannerjee describes \[[ppt](https://www.niso.org/apps/group%5Fpublic/download.php/2884/banerjee%5Flrms09niso.ppt?ref=lorcandempsey.net)\] Orbis Cascade’s work with OCLC on the integration of local, consortial and global discovery and delivery of resources. He suggests that operations should move to the highest appropriate level in the network, and speculates about what other services should move to the network level. Rachel Bruce \[[ppt](https://www.niso.org/apps/group%5Fpublic/download.php/2888/bruce%5Fsiteversion%5Flrms09niso.ppt?ref=lorcandempsey.net)\] looks at library systems from the point of view of national-scale ‘shared services’. What these and other presentations show is how decisions about level of operation – personal, local, consortial, national, global – are as important as particular discussions of functionality or sourcing. Libraries face interesting choices about sourcing – local, commercial, collaborative, public – as they look at how to achieve goals, and as shared approaches become more crucial as resources are stretched.
- Academic library systems are part of an **enterprise infrastructure**, which is discussed here by Mackenzie Smith \[[ppt](https://www.niso.org/apps/group%5Fpublic/download.php/2895/smith%5Flrms09niso.ppt?ref=lorcandempsey.net)\] of MIT and Diane Mirvis \[[pptx](https://www.niso.org/apps/group%5Fpublic/download.php/2894/mirvis%5Flrms09niso.pptx?ref=lorcandempsey.net)\] of the University of Bridgeport. For me, these were the most interesting presentations here as they point to a set of influences that are not discussed very often. As more activity takes place on the network, as students, faculty and administrators create and use data from many sources, and as there is more pressure for new types of integration on both user and management side, it will be interesting to see how organizational and system boundaries change within institutions.
Note: Updated with minor edits, 26 Oct 09.
### Community is the new content
URL: https://www.lorcandempsey.net/community-is-the-new-content/
Last updated: 2020-10-28T09:13:06.000Z
We are now very used to interacting with resources in a social context. The application of community to content, in terms of discussion, recommendation, reviews, ratings and so on, is evident in many of the services we use, and in some form in most of the major network servies we use (Amazon, iTunes, Netflix, …). Indeed, this is now so much a part of our experience that sites without this experience can seem bleached somehow, like black and white TV in a color world.
In a reductive view, here are three types of social experience, which may be present singly or in combination in these sites.
1. Conversation
2. Connection
3. Context
.
We explicitly talk about resources (conversation). And the traces that we leave intentionally or unintentionally can be mined to create connections between people and to add context to resources (relating, ranking, recommending), based on patterns of association between them. What I am calling ‘context’ here may not be explicitly social, but as it is often mined from aggregate behaviors it does not seem too much of a stretch to include it.
**Conversation.** Conversation about services is a natural part of our experience of them. I bought a Zune HD \[1\] recently; it was not clear to me how to turn it off. A search threw up an answer on one of the several Zune forums. It also showed that others had the same issue, so we can expect that this particular feature will change in future releases. In fact, the detailed instructions we might once have seen with a device like this seem to be a thing of the past; in this case, even the online documentation is not very full. Maybe their decision not be exhaustive is influenced by the knowledge that a rich documentation base will be collaboratively sourced across multiple conversational forums? Forums may have dominant contributors, and employees of the product provider may particpate. Such signed network presences are common: we are used to seeing ‘signed’ reviews, recommendations, comments and ongoing interactions on music, movie, book and general consumer and social sites. And online conversation clearly influences online behavior. I have been interested to receive letters from vendors of items I have acquired through Amazon asking that I give them the highest satisfaction rating, and urging that if I am unhappy in any way to contact them first so that they can rectify issues and preserve their rankings.
**Connection.** I like this quote from Hugh MacLeod:
> 14\. The most important word on the internet is not “Search”. The most important word on the internet is “Share”. Sharing is the driver. Sharing is the DNA. We use Social Objects to share ourselves with other people. We’re primates. we like to groom each other. It’s in our nature. \[[gapingvoid: “cartoons drawn on the back of business cards”: more thoughts on social objects](https://www.gapingvoid.com/Moveable%5FType/archives/004265.html?ref=lorcandempsey.net)\]
We connect with others by sharing information about ourselves. Networks form around ‘social objects’, the focus of these shared interests. Think of social bookmarking, picture sharing and social bibliography sites, for example, where we connect around shared interests, in, respectively, interesting resources, pictures and collecting/reading interests. Facebook and Linkedin connect people – or their online signed identities – based on the networks of connections they have already made. Users of services – the Zune for example – who sign up are offered the opportunity to connect with users of like interests, and can prospect the interests of those who chose to disclose them.
**Context.** We leave traces everywhere. We click, buy, rate, follow pathways, add to playlists. We also create collections, lists, and playlists, which disclose our interests and can be compared to make connections or to generate recommendations, or to seed other lists. Services use this subterranean data not only to make connections with other users but to create context, to configure resources by patterns of relations created by shared user interests and choices, and to use these patterns to broaden the experience of their users. Google mobilized linking behaviors; Amazon made ‘people who bought this, also bought this’ types of association popular. Such context is now a central part of music, movie and other sites. Think of the rich recommendation apparatus of Netflix, or the generation of channels, playlists and recommendations in iTunes, Last.fm or other music sites. This approach has spread to more academic contexts. Mendeley, a research management and social networking site for researchers, is explicitly modeled after Last.fm (and some Last.fm veterans are among its investors). One of its aspirations is to generate impact rankings and relationships based on patterns of collecting and use of research literature.
Here are some random observations that occur in this context … Thoughts about libraries may follow …
- Visitors and residents.
- Managing scale and guided navigation.
- Customer relationship management.
- Real-time tracking of trends and analytics.
- Social experiences around content.
**Visitors and residents**. This is a useful distinction [introduced](https://tallblog.conted.ox.ac.uk/index.php/2008/07/23/not-natives-immigrants-but-visitors-residents/?ref=lorcandempsey.net) by Dave White. The resident lives a part of their lives online; their web selves have become an important projection of identity and they maintain online networks of friends and colleagues. “They are likely to see the web as a worthwhile place to put forward an opinion”. The visitor uses the web to get their work done. “They are sceptical of services that offer them the ability to put their identity online as don’t feel the need to express themselves by participating in online culture in the same manner as a Resident.” In the schematic advanced above, the resident is interested in conversation and connection as an active participant – their traces are visible. Everybody leaves the subterranean traces which conribute to context.
**Managing scale and guided navigation**. The social provides a layer of interpretation, connection, context, direction, filtering which valuably orients us in large information resources. Services mobilize ‘intentional data’, data about usage and choices, and crowdsourced data to manage abundance where ‘professional’ approaches may not scale. Of course this can be managed. Nicholas Carr recently [remarked](https://www.roughtype.com/archives/2009/09/netflixs%5Ftail%5Fm.php?ref=lorcandempsey.net) of Netflix: “.. what I’ve noticed is that the company has deliberately geared its search, filtering, and recommendation tools to lead customers away from newly released hits”.
**Customer relationship management**. Services use the data generated by the activities described above to develop customized engagement with customers, pesonalizing communications, providing recommendations, and so on. Such data-driven communication is often useful, sometimes intrusive, but is clearly a priority, where scale, again, make other approaches difficult.
**Real-time tracking of trends and analytics**. Where there is a critical mass of participation, conversation and context can reveal emerging trends and behaviors. Twitter may be an obvious case, but consider, for example, what the realtime usage data coming from a service like Mendeley might tell us about academic interests. .
**Social experience around content**. I was struck by some remarks by Trip Hawkins, the CEO of Digital Chocolate and the founder of leading games publisher Electronic Arts, in an interview at the Web 2.0 Summit in 2007 \[2\]. He was talking about games in a mobile environment, where Digital Chocolate is active.
“In my opinion traditional content is dead …”, he said, and he went on to characterize traditional content as “about a playback and immersive experience and which involve a business model where you pay a fee for the privilege of escapism and checking out” (Hawkins, 2007). These traditional forms include reading and cinema experiences, and he suggests that participation in those media has leveled out. He contrasts this with a new type of content and associated experience, which is growing:
“… where the consumer is increasingly going to spend their money is on social value which is enabled by content where the content isn’t for sale for its own sake – the content is there to enable improvements in your social life”. (Hawkins, 2007) Depending on your point of view or cultural formation, this characterization might be plausible or startling 😉
\[1\] Coda: A couple of eyebrows were raised at work when I mentioned that I had bought a Zune HD, the recently released third generation Zune. I just wanted a media device and this is very nice. It is growing on me. David Pogue [notes](https://www.nytimes.com/2009/09/17/technology/personaltech/17pogue.html?ref=lorcandempsey.net) that “the software design is fluid, beautiful and incredibly responsive”.
\[2\] “Edge: Gaming moderated” by Morgan Webb with Trip Hawkins and Robert Kotick from Web 2.0 Summit, San Francisco, 18 October 2007, at [https://blip.tv/file/441160](https://blip.tv/file/441160?ref=lorcandempsey.net).
### Government URIs: a write to reply
URL: https://www.lorcandempsey.net/government-uris-a-write-to-reply/
Last updated: 2020-10-28T09:13:09.000Z
[Tony Hirst](https://ouseful.wordpress.com/?ref=lorcandempsey.net) alerted me to an interesting document on the structure of URIs in UK government websites. There were two things of immediate interest.
The first was the emphasis a Government agency was putting on information architecture in a web environment. Other documents will follow. This is from the introduction:
> 8\. URI sets will be an integral component of a UK Public Sector Information Architecture that supports many goals including the release of government data, reduced duplication, and increased information sharing towards transforming government services.
> 9\. URI sets can be published by the UK public sector to provide comprehensive and reliable identifiers for ‘Things’ such as schools, roads, legislation, locations, projects, events and so on. Where the quality of these sets can be described consistently, other data owners will have the confidence to re-use them in their own data, leading to a web of data that can be linked, queried, and aggregated.
> 10\. The existing UK public sector standards for metadata and ‘findability’ work well when applied to documents, but are not sufficient to support a ‘Web of Data’, where each individual statement can be queried and linked.
Read more: [https://writetoreply.org/ukgovurisets/introduction/#ixzz0UIvHjdSq](https://writetoreply.org/ukgovurisets/introduction/?ref=lorcandempsey.net#ixzz0UIvHjdSq)
The second was that they were making it available through the [Write to Reply](https://writetoreply.org/faq/?ref=lorcandempsey.net) service provided by [Tony](https://twitter.com/psychemedia?ref=lorcandempsey.net) and [Joss Winn](https://twitter.com/josswinn?ref=lorcandempsey.net). This provides paragraph level publishing, citing and commenting facilities. The purpose is to provide a venue for public review of documents. The site uses [CommentPress](https://www.futureofthebook.org/commentpress/?ref=lorcandempsey.net).
.
### Discoverability .. a report that's worth a look
URL: https://www.lorcandempsey.net/discoverability-a-report-thats-worth-a-look/
Last updated: 2020-10-28T09:13:14.000Z
We are awash in assisted thinking, as I may have [remarked](https://blog.oclc.org/lorcand/archives/001885.html?ref=lorcandempsey.net). One document that **is** worth a look is *[Discoverability](https://conservancy.umn.edu/handle/48258?ref=lorcandempsey.net)* produced earlier this year by a team at the University of Minnesota.
> In October 2008, the Web Services Steering Committee at the University of Minnesota Libraries created the Discoverability exploratory subgroup, charged to recommend ways to make relevant resources more visible and easier to find, particularly within the user’s workflow. This report shares the findings of Phase 1, in which the primary activity was data‐gathering and analysis. Phase 2 of the group’s work will take the discovery principles identified here and recommend specific strategies for the future. The report consists of four main sections. The first section is a brief description of the process and methodology. The second is a discussion of five key trends related to discovery that were identified in the literature, including a description of how each trend is reflected in current use of local systems. The third section contains a set of suggested principles to guide future decisions related to discovery. Finally, we have collected and analyzed usage data from many of our local systems. These reports are collected in our fourth section and are summarized in “A Month of Library Discovery”. We have also included specific recommendations regarding future data‐gathering and analysis. Our appendices include a copy of the group’s charge, a review of discovery principles at peer institutions, and a set of web statistics reports for the University Libraries’ many websites. \[Summary of [Discoverability: phase 1\. Final report. U of Minnesota.](https://conservancy.umn.edu/handle/48258?ref=lorcandempsey.net)\]
I particularly liked the way in which they identified trends through their environmental analysis and then looked for corroboration (or otherwise) in their own usage logs. This combination is quite effective.
Here are the trends they identified:

They tracked library systems usage during a ‘month of library discovery’ and present this summary of findings:

There are many interesting nuggets. In a discussion of the power of recommendation and ‘collective intelligence’ to drive traffic to resources, for example, they note that almost 15% of people who came to the Archives and Special Collections area of the website came there from Wikipedia. There is interesting discussion of how resolver requests break down between internal (e.g. A-Z lists) and external sources (e.g. Google and PubMed). The majority of library website pages are visited infrequently.
The report is available from the library’s repository. I hope that the authors are considering putting some of their findings about patterns of usage into the literature.
Related entries:
- [Affinity strings, personalization and recommendation](https://blog.oclc.org/lorcand/archives/001853.html?ref=lorcandempsey.net)
- [Personal reference collections as digital libraries](https://blog.oclc.org/lorcand/archives/001545.html?ref=lorcandempsey.net)
- [Research behaviors and the library](https://blog.oclc.org/lorcand/archives/001449.html?ref=lorcandempsey.net)
- [Getting in the flow – beside the Mississippi …](https://blog.oclc.org/lorcand/archives/001299.html?ref=lorcandempsey.net)
### Reputation enhancement
URL: https://www.lorcandempsey.net/reputation-enhancement-2/
Last updated: 2020-10-28T09:13:17.000Z
Reputation management on the web – individual and institutional – has become a more conscious activity for many, as ranking, assessment and other reputational measures are increasingly influenced by network visibility. In particular, it raises for academic institutions an issue that has become a part of many service decisions: what is it appropriate to do locally? What should be sourced externally? And what should be left to others to do?
Think, for example, of faculty profiles: the managed disclosure of expertise and research activity. This has often been an informal personal or departmental activity. However, there is now a variety of institutional initiatives which may pull together data about expertise, experience, publications, grants, courses taught, and so on (see OSU Pro at OSU, or Vivo at Cornell, for example). Such initiatives may sit between between several organizational units on campus: Research Support, PR/Communications, IT, Library. They are also at the intersection of different systems: enterprise (Peoplesoft, for example), course lists, research/grants management, bibliographic. At the same time, researchers may have presences in emerging network level research social networks (Mendeley or Nature Network for example), in disciplinary resources (Repec, for example), and, of course, in general use services (Linkedin, for example). There are also commercial services which support such activity in different ways, Community of Science or Symplectic for example.
In this context, here is a note about several unrelated initiatives which I have come across in the last week or so. I don’t try and create a single narrative around them, but together I think they point to this emerging sense of reputation management (or enhancement) as an important if not yet fully clear service category.
We are exploring such a service category in our [Research Information Management](https://www.oclc.org/programs/ourwork/researchinfo/default.htm?ref=lorcandempsey.net) theme. It looks at the intersection of library services and research administration on campus, and we are thinking about the variety of library services which might emerge (which include, in the context of this entry, bibliographic support, bibliometric advice, effective disclosure of expertise and research to the web, advice about SEO and copyright, and so on).
[**VIVO: research and expertise across Cornell**](https://vivo.cornell.edu/?ref=lorcandempsey.net). Some colleagues from Cornell visited last week (see details and video of Anne Kenney’s presentation [here](https://www.oclc.org/research/announcements/2009-09-30.htm?ref=lorcandempsey.net)) and VIVO came up in discussion.
> VIVO (not an acronym) brings together in one site publicly available information on the people, departments, graduate fields, facilities, and other resources that collectively make up the research and scholarship environment in all disciplines at Cornell. \[[About VIVO](https://vivo.cornell.edu/about?ref=lorcandempsey.net)\]
Managed within the Library, it draws together a lot of data from various sources. Interestingly, it is based on [Vitro](https://vitro.mannlib.cornell.edu/?ref=lorcandempsey.net), an ‘Integrated Ontology Editor and Semantic Web Application’.
[**Bibliometrician**](https://www.jobs.ac.uk/jobs/YD567/Bibliometrician/?ref=lorcandempsey.net). The University of Leicester Library advertised for a ‘bibliometrician’ whose role would be “to provide high-level expertise and advice to the University on the use of bibliometrics and related policies in the external and internal evaluation of the quality of the University’s research”
**[Mendeley](https://www.mendeley.com/?ref=lorcandempsey.net)**. My colleague John MacColl wrote a [blog entry](https://hangingtogether.org/?p=740&ref=lorcandempsey.net) about Mendeley last week. Mendeley describes itself as being like “iTunes for research papers”: “Organize, share, and discover research papers! Mendeley is a research management tool for desktop & web. You can also explore research trends and connect to other academics in your discipline.” John contrasted Mendeley and institutional repository incentives and user experience for researchers. Mendeley is one of several social networking sites aimed at researchers.
[Manchester escholar](https://www.escholar.manchester.ac.uk/jrul/?ref=lorcandempsey.net). The University of Manchester launched its repository service. The first line of its mission reads: “sustain and enhance the research reputations of individuals and organisations affiliated with The University of Manchester”. It is also interesting to read the ‘[project business case and benefits](https://www.irproject.manchester.ac.uk/about/businesscase/index.html?ref=lorcandempsey.net)‘ which have a strong reputation management focus. The first benefit for the research is “increase the visibility of your research findings, your work is easier to disseminate, easier to find and easier to read”. The second emphasizes convenience: “make it easier to manage your list of publications on your personal website and your organisations website”. For institutions, the first-listed benefit is “demonstrate to its employees, in particular the academic community, that individuals and their work are valued, by supporting mechanisms that reduce workload and maximise the benefits to them of their efforts” and the third is to “increase the visibility, reputation and prestige of the institution”.
[**Ranking economists and Repec**](https://ideas.repec.org/top/top.person.anbcites.html?ref=lorcandempsey.net). Greg Mankiw is a Harvard economist, text-book writer, high profile blogger and sometime chair of President Bush’s Council of Economic Advisors. He refers from time to time to a ranking of economists generated by [Repec](https://ideas.repec.org/top/top.person.anbcites.html?ref=lorcandempsey.net). He wrote a [note](https://gregmankiw.blogspot.com/2009/09/nobel-prize-pool.html?ref=lorcandempsey.net) about this year’s Nobel prize last week, and pointed to the Repec ranking, noting that 6 out of the top 10 on the list had already won. The rankings are based on data about authors who have registered with the [Repec Author Service](https://authors.repec.org/?ref=lorcandempsey.net), which aims “to link economists with their research output in the RePEc bibliographic database”. Authors get a profile page and also receive statistics about downloads of their papers and citations to them. Many [rankings](https://ideas.repec.org/top/?ref=lorcandempsey.net) are generated from the system.
Finally, I noticed the following [tweet](https://twitter.com/zephoria/status/4298093062?ref=lorcandempsey.net) from [**Danah Boyd**](https://www.danah.org/?ref=lorcandempsey.net) “It pains me when academics don’t take care of their search engine presence. RateMyTeacher should never be an academic’s top result”.
Search engine presence is increasingly important to people and to institutions … reputation management is emerging as a new service category which should be of interest to libraries.
### Waking the unread
URL: https://www.lorcandempsey.net/waking-the-unread/
Last updated: 2020-10-28T09:13:19.000Z
While looking at Google Book Search the other day I was intrigued to discover that parts of my early oeuvre, such as it is, have been digitized from the University of Michigan collections.
I was particularly struck by the word clouds. Here is a word cloud from a 1991 work on libraries and networks with special reference to the now long forgotten OSI suite of protocols.

Here is the word cloud to a 1988 collection of conference papers on library automation, mostly with a UK focus.

In each case, I think the cloud does a reasonable job of reminding you of topics of interest at the time. Here are a couple of other volumes. Here is the cloud from Charles Hildreth’s influential earlier work (1982) on online catalogs:

And here is the cloud from the first edition (1992) of Ed Krol’s very influential *The whole Internet: user’s guide & catalog* ..

They have a nice quality of ‘glancability’ … not a definitive guide but useful hints and hooks.
### Metadata sources
URL: https://www.lorcandempsey.net/metadata-sources/
Last updated: 2020-10-28T09:13:22.000Z
A while ago, I [suggested](https://blog.oclc.org/lorcand/archives/001351.html?ref=lorcandempsey.net) that it was interesting to think about four sources of metadata in our systems and services:
1. Professional. Produced by staff in support of particular business aims. Think of cataloging, or data produced within the book industry, or A&I data.
2. Crowdsourced. Produced by users of systems.Think of tags, reviews and ratings on consumer sites.
3. Programmatically promoted. Think of automatic extraction of metadata from digital files, automatic classifcation, entity identification, and so on.
4. Intentional. Data about choices and transactions which support analytics or business intelligence services. Think about ranking, relating, recommending in consumer sites (e.g people who like this also like this) based on collected transaction data.
We were discussing these types of data in a meeting at work the other day, and it occurred to me that what I call here crowdsourced, programmatically promoted and intentional data are all ways of managing abundance. Our model to date has been a ‘professional’ one, where metadata is manually created by trained staff. This model may not scale very well with large volumes of digital material. Nor does it necessarily anticipate the variety of ways in which resources might be related. The other sources will become increasingly important ….
### QOTD: Books and bitumen
URL: https://www.lorcandempsey.net/qotd-books-and-bitumen/
Last updated: 2020-10-28T09:13:25.000Z
A very nice reference from the blog of husband and wife writing team [Nicci French](https://www.worldcat.org/wcidentities/lccn-nr97-21153?ref=lorcandempsey.net):
> I’ve just finished On Roads: A Hidden History by Joe Moran. It’s one of those books you keep stopping in order to tell someone the interesting fact you’ve just learned. That the Chiswick flyover was opened by Jayne Mansfield. That the Newbury Bypass was opened at 1.30 in the morning to avoid protesters. Subtle, even-handed, beautifully written. As an author I was particularly chastened by the following passage:
>> ‘Every year, more than 120,000 new books are published in Britain, creating millions of volumes that will never be opened, let alone read. Many of these unread books are shredded into tiny fibre pellets called bitumen modifier, which can be used to make roads, holding the blacktop in place and doubling up as a sound absorber. A mile of motorway consumes about 50,000 books. The M6 Toll Road used up two-and-a-half million old Mills and Boon novels, romantic dreams crushed daily by juggernauts.’
> Better than burning them. Better – in many cases – than reading them. \[[On the road](https://niccifrench.typepad.com/theniccifrenchblog/2009/09/on-the-road.html?ref=lorcandempsey.net). Nicci French Blog\]
### The library website: a unified service?
URL: https://www.lorcandempsey.net/the-library-website-a-unified-service/
Last updated: 2023-07-04T01:32:27.000Z
I mentioned the reworked University of Michigan Libraries [website](https://www.lib.umich.edu/?ref=lorcandempsey.net) a while ago.
> Although it is still a layer over various other resources, I liked the way that the site aimed to project the library on the web as a unified service not as a set of unrelated opportunities. This extended to the way that links to specialist library advice was included alongside the other resources. \[[Lorcan Dempsey’s weblog – A web-siting at the University of Michigan](https://blog.oclc.org/lorcand/archives/001985.html?ref=lorcandempsey.net)\]
For reasons discussed in these pages many times this layering is not straightforward:
> This is largely because they are providing a thin layer over two sets of heterogeneous resources. One is the set of legacy and emerging systems, developed independently rather than as part of an overall library experience, with different fulfillment options, different metadata models, and so on (integrated library system, resolver, knowledge base, repositories, …). Another is the set of legacy database and repository boundaries that map more to historically evolved publisher configurations and business decisions than to user needs or behaviors (for example, metadata, e-Journals, eBooks, and other types of content, which may be difficult to slice and dice in useful ways). \[[Lorcan Dempsey’s Weblog – Stitching costs](https://blog.oclc.org/lorcand/archives/001785.html?ref=lorcandempsey.net)\]
There is a blog entry by Ken Varnum providing a high level overview of design decisions:
> Implemented in Drupal with Solr to power our search results, the site integrates what was a varied and highly decentralized network of library web pages. We pruned and weeded the roughly 100,000 pages on the old site – many of which were leftovers from past redesigns – into about 7,000 pages and 13,000 resource entries. We also introduced powerful new discovery tools for our patrons. \[[\[BLT\] Blog for library technology – The New University of Michigan Library Web Site](https://mblog.lib.umich.edu/blt/archives/2009/08/the%5Fnew%5Funivers.html?ref=lorcandempsey.net)\]
I particularly like the way a [search](https://www.lib.umich.edu/mlibrary/search/mirlyn;website;ejournals;searchtools;deepblue/demographics?ref=lorcandempsey.net) in the home-page search box gives back a range of results, including a match to a subject expert if this is possible. They try to put, literally, a ‘human face’ on the results page.
The catalog search itself is a VuFind deployment, and article search talks to Metalib’s x-server, dropping you into Metalib if you request it (I think – I am not an authorized user so can only go so far).
I think the Michigan site does a very nice job in projecting the library service and trying to abstract the user experience away from the underlying database and service boundaries it is managing. Of course, as a ‘tourist’ I cannot follow trails into resources I am not authorised to use.
Recently, I was directed to the new Libraries [website](https://www.lib.muohio.edu/?ref=lorcandempsey.net) at Miami University. This is on a smaller scale and there is a ‘thinner’ integration layer over the site as a whole. But, again, I liked the fact that the design goal seems to be to project the library as a unified service offering, carrying navigation and appearance as consistently as it could between parts.
In terms of presentation, I was interested to see some things in common between the sites. They each use Libguides to assemble web-based resources in particular subject areas (including links to pictured library staff). This enhances the sense of the pages as a professionally curated resource, and seems to support better overall UI consistency. Another was the use of Drupal and Solr. And another was the deployment of a separate interface to the native ILS catalog, VuFind in Michigan’s case and (I think) MULtifacet in Miami’s.
> MULtifacet is a Drupal 5 module that wraps a UI around an arbitrary Solr index. It shares many features with other Solr-based OPAC projects, including faceted search results, SMS/email output, RefWorks integration, user tagging, saving/exporting of records, RSS feeds, Zotero support, Google Books images/linking, “more like this”, formatted citation output (via the WorldCat API), COinS, unAPI, etc. While developed for, and initially targeted at, library collections, there’s no reason it couldn’t put a UI on other Solr indexes that need similar features. \[[MULtifacet](https://code.google.com/p/multifacet/?ref=lorcandempsey.net)\]
I had begun this entry when I was interested to see a related discussion emerge on the WEB4LIB list. Tim Spalding asked if anybody was aware of a library website where the various solutions looked as if they were part of the same organic whole. David Walker responded by pointing to the [library website](https://lib.calpoly.edu/?ref=lorcandempsey.net) at CalPoly.
And as library websites go, it is indeed very nice. I noticed again that [Libguides](https://www.springshare.com/libguides/?ref=lorcandempsey.net) play a part, and am interested to see that you can browse by both subject area and by librarian (‘[people are entry points](https://blog.oclc.org/lorcand/archives/001873.html?ref=lorcandempsey.net)‘).
Even though the website is increasingly a part only of how the library projects its network services, it is important to improve how it does so.
Related entries:
- [A web-siting at the University of Michigan](https://blog.oclc.org/lorcand/archives/001985.html?ref=lorcandempsey.net)
- [Criss cross catalogs](https://blog.oclc.org/lorcand/archives/001813.html?ref=lorcandempsey.net)
- [A signed network presence: people as entry points](https://blog.oclc.org/lorcand/archives/001873.html?ref=lorcandempsey.net)
- [Stuck in the middle … ](https://blog.oclc.org/lorcand/archives/001700.html?ref=lorcandempsey.net)
### Libraries and publishing: a couple of examples
URL: https://www.lorcandempsey.net/libraries-and-publishing-a-couple-of-examples/
Last updated: 2020-10-28T09:13:28.000Z
As interaction with the book literature, publishing, the role of large print collections, and research and learning behaviors are all changing in a network environment, academic libraries have been looking at their role in the scholarly communication and publishing process. I came across two examples of library activity which prompt this note ….
The Economist has a [short article](https://www.economist.com/businessfinance/displaystory.cfm?story%5Fid=14376406&ref=lorcandempsey.net) on the Google Book Search settlement (who doesn’t?). A colleague and I had a look at the two works it mentions as examples of orphan works. One was *The Appalachian frontier America’s first surge westward* by John Anthony Caruso.
Worldcat tells me about three versions of The Appalachian Frontier.
1. Caruso, John Anthony. 1959\. The Appalachian frontier; America’s first surge westward. Indianapolis: Bobbs-Merrill.
2. Caruso, John Anthony. 2003\. The Appalachian frontier: America’s first surge westward. Knoxville, TN: University of Tennessee Press.
3. Caruso, John Anthony. 2003\. The Appalachian frontier America’s first surge westward. Appalachian echoes. Knoxville: University of Tennessee Press. [https://www.newfoundpress.utk.edu/pubs/caruso/](https://www.newfoundpress.utk.edu/pubs/caruso/?ref=lorcandempsey.net).
The third is a digital version provided by the Library at the University of Tennessee Knoxville through its imprint Newfound Press. The Press is described as follows:
> The University of Tennessee Libraries is developing a framework to make scholarly and specialized works available worldwide. Newfound Press, the University Libraries digital imprint, advances the community of learning by experimenting with effective and open systems of scholarly communication. Drawing on the resources that the university has invested in digital library development, Newfound Press collaborates with authors and researchers to bring new forms of publication to an expanding scholarly universe. We consider manuscripts in all disciplines, encompassing scientific research, humanistic scholarship, and artistic creation. \[[Welcome to Newfound Press](https://www.newfoundpress.utk.edu/index.html?ref=lorcandempsey.net)\]
> In partnership with the library’s Digital Library Initiatives and the UT Digital Repository, Newfound Press applies technology to promote emerging forms of scholarly inquiry and discovery of the results. The University Libraries and the University of Tennessee Press enjoy a longstanding, friendly relationship. Newfound Press draws on these advantages to pursue its mission of expanding access to scholarly and specialized work in the global environment. We aspire to prominence as a publisher of choice. \[[About us](https://www.newfoundpress.utk.edu/aboutus.html?ref=lorcandempsey.net)\]
The second example is a joint initiative between Cambridge University Press and Cambridge University Library called *Books of Enduring Scholarly Value*. From the [press release](https://www.cambridge.org/press/article.asp?artid=154241&ref=lorcandempsey.net):
> Cambridge University Press has launched the Cambridge Library Collection, a new project reissuing books of enduring scholarly value. It uses state-of-the-art scanning and print-on-demand technology to make accessible in new ways works that until now would have been available only in libraries.
> Already a pioneer in the re-publishing of titles from its own backlist, Cambridge University Press is extending its reach to include other books which are still of interest to researchers, students and the general reader. The Press’s unique relationship with Cambridge University Library allows access to a vast range of out-of-print and out-of-copyright titles.
> With subjects ranging from travel to maths and from life sciences to music, the Cambridge Library Collection allows readers access to books they would otherwise struggle to find. Writings by Charles Darwin and his circle, and studies on Shakespeare, Jane Austen, Handel and Wagner all appear, alongside the works of the greatest nineteenth-century mathematicians, and a range of books on Cambridge from the serious to the scandalous.
> The Press takes advice from experts worldwide on what books in their subject areas should be included in the programme. Each book is carefully scanned, and the resulting files undergo a rigorous process of cleaning, in which any blemishes are removed to obtain a crisp and legible text. Each book has a new cover design and a specially written blurb which highlights the relevance of the book to today’s readers.
> The Cambridge Library Collection launched on 20 July with 475 titles, to celebrate the 475 years since the Press was granted permission to print ‘all manner of books’ by Letters Patent of Henry VIII. By the end of 2009, this number will have grown to over 1,000\. \[[Cambridge University Press launches a new venture to reissue rare and out-of print books](https://www.cambridge.org/press/article.asp?artid=154241&ref=lorcandempsey.net)\]
And here is a video, which shows among other things, the actual scanning in action …
The Cambridge example is discussed in an [article](https://www.insidehighered.com/news/2009/08/03/reprinting?ref=lorcandempsey.net) in Inside Higher Ed which also refers to the recent [announcement](https://www.ns.umich.edu/htdocs/releases/story.php?id=7244&ref=lorcandempsey.net) by the University of Michigan about reprint on demand services for thousands of its rare books in collaboration with Booksurge. It also points to Cornell’s arrangement with Amazon for reprint services on 80,000 titles through the Cornell University Library [Bookstore](https://bookstore.library.cornell.edu/?ref=lorcandempsey.net).
These examples show an area of growing interest. They also underline how books will appear through multiple channels with consequences for discovery and fulfillment options.
### Metadata redux
URL: https://www.lorcandempsey.net/metadata-redux/
Last updated: 2020-10-28T09:13:30.000Z
I was asked in a meeting recently to define metadata. This prompts me to adapt some text recycled from [All that is solid melts into flows](https://blog.oclc.org/lorcand/archives/000663.html?ref=lorcandempsey.net)\* …
Like most people ;-), I tend to think about metadata as ‘schematized assertions about resources’: *schematized* because patterned and machine understandable; *assertions* because they involve a claim about the resource by a particular agent; *resource* because any identifiable object may have metadata associated with it. Metadata is useful because it relieves a potential user (a person or a program) of having to have full advance knowledge of the characteristics or existence of the resource. In other words, metadata provides ‘intelligence’ which supports more efficient operations on resources. Examples of operations are discovery, preservation, purchase, reformatting, embedding, analysis, extraction of components, and so on.
\* And sorry, I couldn’t resist keeping in the smiley ….
### Muldoon and Colbert
URL: https://www.lorcandempsey.net/muldoon-and-colbert/
Last updated: 2020-10-28T09:13:34.000Z
I have mentioned Paul Muldoon [in these pages](https://www.google.com/search?rlz=1C1GGLS%5FenUS291US304&sourceid=chrome&ie=UTF-8&q=site:https://orweblog.oclc.org+&ref=lorcandempsey.net) several times. I could not resist linking to this appearance of the Northern Irish poet, Princeton [faculty](https://www.princeton.edu/arts/arts%5Fat%5Fprinceton/creative%5Fwriting/professor%5Fbios/muldoon/index.xml?ref=lorcandempsey.net) member, and poetry editor of the New Yorker, on The Colbert Report. The best bit is at the end.
| [The Colbert Report](https://www.colbertnation.com) | Mon – Thurs 11:30pm / 10:30c |
| ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ | ---------------------------- |
| [Paul Muldoon](https://www.colbertnation.com/the-colbert-report-videos/231220/june-18-2009/paul-muldoon) | |
| [www.colbertnation.com](https://www.colbertnation.com/) | |
| [Colbert Report Full Episodes](https://www.comedycentral.com/colbertreport/full-episodes) [Political Humor](https://www.indecisionforever.com) [Health Care Protests](https://www.colbertnation.com/video?keywords=health+care+protesters) | |
Here is Muldoon’s [Worldcat Identity](https://www.worldcat.org/wcidentities/lccn-n81-98944?ref=lorcandempsey.net).
### QOTD: public libraries and social engineering
URL: https://www.lorcandempsey.net/qotd-public-libraries-and-social-engineering/
Last updated: 2020-10-28T09:13:36.000Z
From the Preface to *Books, buildings and social engineering*:
> We seek to rescue the historic public library building from a perspective that in the past has all too easily denigrated it. The mass construction – for that is what it eventually became – of early public library buildings is to be celebrated as a successful exercise in social engineering, an unprecedented effort by a public-sphere movement to persuade citizens, in a consensual way, of the importance of knowledge in an increasingly open and modernising society (we have deliberately used the term ‘social engineering’ as opposed to the narrower and misleading term ‘social control’). More precisely, the provision of what amounted to over one thousand library buildings in the period 1850-1939 was an exercise in what Karl Popper called ‘piecemeal social engineering’ – social engineering that was incremental and continually amended in the light of experience and new knoweldge, a scientific approach to planning social change, in this instance via the free provision of books, information, education and knowledge, that reflected the essence of the public library as an institution of progress and scientific inquiry. \[Black, A., Pepper, S., & Bagshaw, K. (2009). [Books, buildings and social engineering: Early public libraries in Britain from past to present](https://www.worldcat.org/oclc/276514861?ref=lorcandempsey.net). Farnham, England: Ashgate Pub.\]
### Strategic reading and bouncing
URL: https://www.lorcandempsey.net/strategic-reading-and-bouncing/
Last updated: 2020-10-28T09:13:38.000Z
I was very taken by [Timothy Burke](https://weblogs.swarthmore.edu/burke/?ref=lorcandempsey.net)‘s presentation at the [first open meeting](https://www.loc.gov/bibliographic-future/meetings/2007%5Fmar08.html?ref=lorcandempsey.net) of the Library of Congress Working Group on Bibliographic Control. What was especially interesting was how he outlined a variety of ways in which he needed to interact with the literature. In his own specialties, he expected to have comprehensive knowledge of what was published. Occasionally he might prospect a new area, wanting to get a sense of its ‘shape’. He might need to understand something of the research area of a student. And so on. This variety of approaches led him to outline a set of capacities that would be useful to him, summarized in the [meeting report](https://www.loc.gov/bibliographic-future/meetings/2007%5Fmar08.html?ref=lorcandempsey.net) as follows:
> - the ability to recognize clusters of knowledge production (persons and subjects),
> - the lineage of publications (i.e., how they exist in chronological relationship to each other),
> - the ability to make previously unknown connections among resources,
> - the ability to make serendipitous or unforeseen connections among topics,
> - identification of the authoritativeness of sources,
> - the popularity/amount of use of a resource, and
> - the sociology of knowledge, for example the “pedigree” of authors and publishers.
>
> \[[Users and Uses of Bibliographic Data Meeting – Meetings – (Library of Congress)](https://www.loc.gov/bibliographic-future/meetings/2007%5Fmar08.html?ref=lorcandempsey.net)\]
Now, he does not talk about ‘discovery’ or ‘search’; he talks about patterns, relationships, judgements. That said, I was also interested that for his specialist areas he was able to name appropriate Library of Congress Subject Headings.
It seems to me that that phrase “strategic reading” might cover what he is doing quite nicely: his pattern of reading is determined by a particular goal, and will be different depending on the goal. His goals are probably variably well supported by our bibliographic apparatus (and remember he is also the author of the modestly notorious [Burn the catalog](https://www.ask.com/bar?q=burn+the+catalog+burke&page=1&qsrc=2243&ab=0&u=https://www.swarthmore.edu/SocSci/tburke1/perma12004.html&ref=lorcandempsey.net).)
“Strategic reading” is a phrase used by Alan Renear and Carole Palmer in a recent contribution to *Science Magazine*: [Strategic Reading, Ontologies, and the Future of Scientific Publishing](https://www.sciencemag.org/cgi/content/full/325/5942/828?ref=lorcandempsey.net) (*Science* 14 August 2009: 828-832) (behind a paywall), and in the associated [news story](https://www.sciencedaily.com/releases/2009/08/090818182058.htm?ref=lorcandempsey.net). Their focus is more on the techniques adopted to do some of what is discussed above, than the patterns themselves.
> Scientists have always strived to avoid unnecessary reading. Like all researchers, they use indexing and citations as indicators of relevance, abstracts and literature reviews as surrogates for full papers, and social networks of colleagues and graduate students as personal alerting services. The aim is to move rapidly through the literature to assess and exploit content with as little actual reading as possible. As indexing, recommending, and navigation has become more sophisticated in the online environment, these strategic reading practices have intensified. …
> … They sweep through resources, changing search strings, chaining references backward and citations forward, dodging integrator and publisher sites to find open-access copies, continually working to reduce the number of clicks required for access. By note-taking or cutting and pasting, scientists often extract and accumulate bits of specific information, such as findings, equations, protocols, and data.
> In this process, rapid judgments are made–such as assessments of relevance, impact, and quality–while search queries are being formulated and refined. (Fig. 3). The goal often seems to be undifferentiated assimilation of information about a domain or a problem at hand, and the online experience may be highly valuable, even though no clear aim is met and no articles to read are located. \[Allen H. Renear and Carole L. Palmer. [Strategic Reading, Ontologies, and the Future of Scientific Publishing](https://www.sciencemag.org/cgi/content/full/325/5942/828?ref=lorcandempsey.net). Science 325, 828 (2009) – behind a paywall\]
They go on to refer to the analogy with the remote control proposed by [David Nicholas](https://www.ucl.ac.uk/infostudies/david-nicholas/?ref=lorcandempsey.net) et al in their work on information behaviors. We have become bouncers and flickers, moving horizontally though the literature.
> Just as the aim of channel surfing is not to find a program to watch, the goal of literature surfing, is not to find an article to read, but rather to find, assess, and exploit a range of information by scanning portions of many articles. This behavior is common among scientists (9). \[Allen H. Renear and Carole L. Palmer. [Strategic Reading, Ontologies, and the Future of Scientific Publishing](https://www.sciencemag.org/cgi/content/full/325/5942/828?ref=lorcandempsey.net). Science 325, 828 (2009) – behind a paywall\]
What types of services are strategic readers most likely to use?
(9) D. Nicholas, P. Huntington, H. R. Jamali, T. Dobrowolski, Inf. Process. Manage. 43, 1085 (2007).
### Serendipity
URL: https://www.lorcandempsey.net/serendipity/
Last updated: 2020-10-28T09:13:40.000Z
Digital environments provide many more opportunities for serendipity than print ones. Sure, there may be happy discoveries on the shelf or in a random group of items bound together. But the chances of happy discovery are multiplied in the web environment. Now, when I hear an argument based on serendipity, I usually assume that it really an assertion of a preference for one set of behaviors over another.
In this context, I was interested to read Steven Johnson’s discussion of serendipity from a few years back …
> I find these arguments completely infuriating. Do these people actually *use* the web? I find vastly more weird, unplanned stuff online than I ever did browsing the stacks as a grad student. Browsing the stacks is one of the most overrated and abused examples in the canon of things-we-used-to-do-that-were-so-much-better. (I *love* the whole idea of pulling down a book because you like the “binding.”) Thanks to the connective nature of hypertext, and the blogosphere’s exploratory hunger for finding new stuff, the web is the greatest serendipity engine in the history of culture. It is far, far easier to sit down in front of your browser and stumble across something completely brilliant but surprising than it is walking through a library looking at the spines of books. With music blogs and iTunes, I’ve discovered more interesting new bands and albums in the past year than I did in all of my college years. I know radio has gotten a lot worse, but really — does anyone actually believe that radio was ever more diverse and surprising in its recommendations than surfing through the iTunes catalog or the music sites? \[[stevenberlinjohnson.com: Can We Please Kill This Meme Now](https://www.stevenberlinjohnson.com/2006/05/can%5Fwe%5Fplease%5Fk.html?ref=lorcandempsey.net)\]
Now, if you narrow the discussion to the library ‘before’ and ‘after’ the digital turn, we come back to the issue that library systems do not make their data work hard enough in service of discovery, routine or happy ….
### On books again
URL: https://www.lorcandempsey.net/on-books-again/
Last updated: 2022-11-08T18:23:31.000Z
‘Book’ is a big word. It has a lot of power as it is intimately bound up with our intellectual and imaginative histories. More parochially, the book is also strongly bound up with the professional practice and identity of the library and librarians.
At a more prosaic (sic) level, the book is also interesting as we manage data about multiple formats. We use book to mean a format (a set of bound pages, etc, say), a type of creative work (continuous textual/pictorial narrative, say), a work (Don Quixote, say), and maybe other things. Because of its centrality when our professional practices were being formed, perhaps more was taken for granted about the book than has been about other formats (the phrase ‘non-book formats’ is telling here).
This is a bigger topic than a late-night blog entry will tackle. I am prompted to write the post by a conversation I had recently with my colleague Brian Lavoie about what a book is. This was in the context of data mining activity looking at counts of books in particular contexts ([here](https://blog.oclc.org/lorcand/archives/001997.html?ref=lorcandempsey.net) and [here](https://www.dlib.org/dlib/september05/lavoie/09lavoie.html?ref=lorcandempsey.net) for example). There are two questions here: ‘what is a book?’, and ‘how do you operationalise that definition in relation to a particular data set?’. It may be that it is not possible to operationalise aspects of your definition, in which case you will not be able to count as you wish. For example, one sometimes sees this Unesco definition of a ‘book’:
> A book is a non-periodic publication of at least 49 pages exclusive of the cover pages, published in the country and made available to the public. \[[Revised Recommendation concerning the International Standardization of Statistics on the Production and Distribution of Books, Newspapers and Periodicals, 1 November 1985](https://portal.unesco.org/en/ev.php-URL%5FID=13146&URL%5FDO=DO%5FTOPIC&URL%5FSECTION=201.html?ref=lorcandempsey.net)\]
The document provides some other qualifications as to what is and what is not a book. So, is this this unambiguous enough to be operationalizable in a database like, say, Worldcat? Well, the short answer is ‘probably not completely’ 😉 I would have to consult more knowledgable colleagues who would have to do some work to find out how much could be done. However, it is unlikely that one would be able to consistently identify all the included categories of materials **and** apply a limit of 49 pages.
Anyway, this is a prelude to the these comments that Brian sent me about the issue:
> “As a non-librarian who works with library data on a regular basis, I was surprised to learn that the commonplace object ‘book’ is not well-defined in traditional cataloging practice. This is all the more surprising when one considers that historically, libraries were built around aggregations of books. The difficulty is that there are no explicit bibliographic criteria for identifying something most people would recognize as a ‘book’. So for example, consider a simple question like ‘How many books are in WorldCat?’ In the bibliographic universe, there is nothing explicitly defined as a ‘book’: there are monographs, or more narrowly, language-based monographs, but the items falling into these categories are not necessarily books as we might commonly perceive them. Is a government document a book? A dissertation? A technical report? A pamphlet of only a dozen pages? These kinds of materials, and more, get included when we use a construct like ‘language-based monographs’ as a proxy for ‘books’.
> “Why is this important? The concept of “books” is appearing in a variety of current discussions, most notably in the context of digitization issues like the Google book settlement. So we are often asked questions like, ‘how many print books in WorldCat have been published after 1923?’ We can provide answers to these questions, but only with a degree of approximation built in: i.e., we can calculate a number that reflects something along the lines of ‘all language-based monographs in WorldCat, excluding dissertations and government documents’; we can even throw in a minimum page requirement (at least 49 pages, according to the UNESCO definition of a book). But we can’t say exactly how many books are in WorldCat, because from a cataloging standpoint, we don’t know what a book is. Libraries are grappling with difficult new questions these days, as collections and services transition from print to digital, from local to the network. But an old question still remains: what is a book?” \[Personal communication from Brian Lavoie\]
### Ebooks and/or digital books
URL: https://www.lorcandempsey.net/ebooks-and-or-digital-books/
Last updated: 2020-10-28T09:13:45.000Z
I was in a meeting with a group of folks from research libraries the other week. I was interested in a particular terminological issue: ‘ebooks’ and ‘digital books’ were each being used in conversation. I asked was there a pattern of consistent use here. ‘Not complete consistency’ was the answer, but there was certainly a tendency to use ‘ebooks’ for materials available for license from external providers, and a tendency to use ‘digital books’ for materials digitized from library collections.
So, in this context, it is easy to see how each expression has a different – if overlapping – set of associations. Ebooks may evoke an environment currently fragmented by provider platforms, with restrictions on use, and managed in a licensed e-resource workflow. They are for reference, information, reading. Digital books may evoke a digital library environment, an aspiration to provide higher level research services based on text mining, entity identification, and so on, and various funding and cooperative initiatives which aim to increase the corpus. The [Monk Project](https://www.monkproject.org/?ref=lorcandempsey.net) or the international [Digging into Data Challenge](https://www.diggingintodata.org/?ref=lorcandempsey.net) are examples of a direction here.
Over the next few years, it will be interesting to see how these environments evolve as ebooks/digital books grow in number and usage. Ebooks and digital books – to continue to use these ambiguous terms – will become more important in the practice of research and learning. There are at least three big drivers in the environment the group above was discussing. The first is around moving physical collections to the cloud as libraries balance service between local collections, shared offsite collections and digital collections. There are early discussions about policy and service frameworks within which libraries can reduce their print inventory and the opportunity costs associated with it (see [here](https://www.oclc.org/us/en/nextspace/012/research.htm?ref=lorcandempsey.net) for example). The second is around the demand environment, as books in digital form offer a better fit with research and learning workflows which are increasingly network based. The increasing availability of books in digital form supports patterns of discovery, analysis and use now common with other resources. Think for example of the practice of ‘strategic reading’ (or ‘reading avoidance’) where researchers are found to prospect the literature broadly in a digital environment, searching, consulting abstracts, scanning for terminology, diagrams and so on (interestingly described by Renear and Palmer [here](https://www.sciencedaily.com/releases/2009/08/090818182058.htm?ref=lorcandempsey.net)). For many purposes, people will prefer the digital versions and will shift use. This is not to say that people will not continue to read physical books, but it is interesting to consider the pattern of adoption (and continued development) of the journal literature. The third is around the environment of supply, where there is major current activity. The post settlement Google Books institutional product offering, Amazon’s attempt to ‘iPodify’ books, the rise of the iPhone, and a range of other developments point to rapidly changing opportunities.
So the relationship with the book literature is going to change in significant ways, which may make the ebook/digital book distinction advanced above less relevant. In fact, Google Book Search already moves beyond it in important ways. And libraries are exploring various syndication models (with Amazon, for example, or Kirtas) or in collaboration with publishers such as the the [Cambridge Library Collection](https://www.cambridge.org/features/cambridgeLibraryCollection/default.html?ref=lorcandempsey.net), for example. Fragmentation, of technical platform, of format, of business model, and so on, will complicate service provision..
This poses major questions for libraries at all levels. From a (current) workflow point of view, we will see a shift of more activity out of the ‘bought’ materials workflow into the ‘licensed’ materials workflow. From a collections point of view we will see a rebalancing between local, shared and third party print and digital provision in ways now being worked through. There are bigger issues, already with us with the journal literature, about the curation of the scholarly record, about sharing of materials, and about assuring the type of access that is compatible with use and re-use in research and learning.
I was very interested to read the following remarks by David Nicholas in [Update](https://www.cilip.org.uk/publications/updatemagazine?ref=lorcandempsey.net) (behind a member wall) recently …
I think that libraries may be underestimating the impact and pace of change in the book world …
### Counting titles and authors
URL: https://www.lorcandempsey.net/counting-titles-and-authors/
Last updated: 2020-10-28T09:13:51.000Z
The proposed Google Books settlement has created a strong interest in quantifying publications and authors, to get a better sense of the scale of impact. We have been looking at Worldcat and hope to publish an analysis later this year.
Here is an issue that came up this week: how many print books were published in the US since 1923, and how many authors were associated with those books? Here are some numbers, acknowledging that they provide good indications based on the data we have and what we can do with it, not definitive answers.
- Print books published in the US in 1923 or later: 12,582,962
- Unique personal authors: 3,685,778
- Unique corporate authors: 977,679
Now, ‘book’ is a pretty vague term. This analysis uses the definition we used in the [Anatomy of Aggregate Collections](https://www.dlib.org/dlib/september05/lavoie/09lavoie.html?ref=lorcandempsey.net) paper we published a few years ago, which analyses the collections of the orginal Google 5 libraries, which was as follows:
> Although there is no unambiguous bibliographic definition of a book, libraries have often used monographic language materials as a proxy for books, and this practice is adopted for this study. More specifically, in the context of a MARC21 record, a book is defined as a language-based monograph, identified by the codes “a” and “m” in bytes 6 and 7 of the leader, respectively. For the purposes of this study, theses/dissertations and government documents are excluded from the analysis, since these materials are usually acquired and managed as separate segments of the library collection. Records describing books in print format were identified by eliminating all non-print formats, such as digital, microform, Braille, and so on.)
What we are counting are ‘manifestations’ (in FRBR terms), which might relate to ‘title’ in common usage. There would be more individual copies. We pull together authors as best we can.
Here is the ranked list of the personal authors by number of manifestations published in the US after 1923.
1. Shakespeare, William 1564 1616
2. Marsh, Carole
3. Twain, Mark 1835 1910
4. Rudman, Jack
5. Dickens, Charles 1812 1870
6. Jackson, Ronald vern
7. Bloom, Harold
8. Christie, Agatha 1890 1976
9. Stevenson, Robert Louis 1850 1894
10. Cowley, Joy
An interesting list; I have [remarked](https://blog.oclc.org/lorcand/archives/001271.html?ref=lorcandempsey.net) on the Bloom phenomenon before.
Here is the ranked list of corporate authors:
1. society of automotive engineers
2. american national standards institute
3. national business institute
4. national learning corporation
5. foreign technology div wright patterson afb ohio
6. national bureau of economic research
7. sothebys firm
8. sotheby parke bernet inc
9. electric power research institute
10. naval postgraduate school monterey ca
It will be seen from the list of corporate authors that our working definition pulls in standards and art catalogs. Remember that we are not counting theses and government documents. This is a reminder that although we may have a common-sense notion of a ‘book’ based on an academic or trade publication, it actually requires some discretionary interpretation to bound the population of books in an operational way for this type of analysis.
And a final reminder: these lists are based on print books published in the US since 1923, not on an analyis of the whole of Worldcat.
The actual analysis was done by my colleagues Jenny Toves and Brian Lavoie.
### Twitterage again ...
URL: https://www.lorcandempsey.net/twitterage-again/
Last updated: 2020-10-28T09:13:57.000Z
Here a few random thoughts on Twitter, nothing more …
([me on twitter](https://www.twitter.com/lorcand?ref=lorcandempsey.net)) …
- **Scheduling**. Because of the fugitive nature of the medium – tweets can roll out of your field of attention quite quickly – and because of the geographic spread of followers, I am much more conscious of the time at which I twitter then when I do other things. And I am conscious that it is not optimum given the distribution of my followers. I often twitter in the evening, which is late for folks in EST time zone, and by which time folks in Europe are in bed. As twitter is more of a ‘real-time’ medium, it makes you more aware of the reality of time. (As does the phone 😉
- **Corporate identity**. I follow a variety of organizations, commercial and non-commercial, from big to small. It is clear that general norms about consistency of tone, type of message (product-related stuff, ‘fun’ stuff, general awareness and interest stuff), formality, and so on, don’t yet widely exist. This is reasonable enough, but it is interesting to watch different practices. Of course, because it may not be a strongly ‘managed’ activity in many cases, it is often premature to try to say too much about the organization from the way in which they twitter. Which sort of defeats the purpose? I was interested a while ago to see [reports](https://www.guardian.co.uk/uk/2009/jul/27/twitter-socialnetworking?ref=lorcandempsey.net) of the guidelines developed for use of twitter by the UK government. They suggested the development of a ‘hypothetical identity’ to which all contributors could try to align themselves to achieve some consistency of tone.
- **Small businesses**. We live in Clintonville, Columbus. A few minutes to the south of us is [PattyCake Bakery](https://twitter.com/pattycakebakery?ref=lorcandempsey.net), a ‘vegan dessert bakery’. A few minutes to the north is [Crimson Cup Coffee](https://twitter.com/crimsonCup?ref=lorcandempsey.net), each active twitterers. I follow several Columbus small businesses. I think it makes me more inclined to use their services.
- **Reputation**. I began twittering earlier this year after coming back from the JISC conference. There was a big emphasis on twitter at the event, as I [discussed](https://blog.oclc.org/lorcand/archives/001909.html?ref=lorcandempsey.net) at the time. The organisers and several of the speakers made much of the advantages of twitter to professional and personal life, from social, informational and reputational perspectives. However, as with any public disclosure of self, the reputation thing can work in different ways 😉
### Worldcat Local usability results and FRBR
URL: https://www.lorcandempsey.net/worldcat-local-usability-results-and-frbr/
Last updated: 2020-10-28T09:13:59.000Z
I [posted a while ago](https://blog.oclc.org/lorcand/archives/001971.html?ref=lorcandempsey.net) about the potential benefits of sharing usability results between libraries, and there was some interest in Worldcat usability testing at the time.
In that context, some readers may be interested in the following report which OCLC prepared for distribution at ALA:
> Some Findings from WorldCat Local Usability Tests Prepared for ALA Annual, July 2009 \[[pdf](https://www.oclc.org/worldcatlocal/about/213941usf%5Fsome%5Ffindings%5Fabout%5Fworldcat%5Flocal.pdf?ref=lorcandempsey.net)\]
There is a lot of interesting material in the report (which is a readable 8 pages). I was especially interested to read the section on FRBR given [my post](https://blog.oclc.org/lorcand/archives/001992.html?ref=lorcandempsey.net) the other day on how different services handle the presentation of works.
Here are some snippets:
> We found that in general work-level granularity for search results based on FRBR rather than edition-level granularity fit the expectations of both academic and public library test participants.
> Undergraduate test participants, primarily in the humanities and social sciences, reported that they seldom (seven participants of ten participants) or never (three participants) looked for a specific edition of a book.
> We repeatedly heard editions sometimes matter to scholars–the last, the first, the last during the author’s lifetime. Historians expressed a preference for the first edition of primary sources and the most recent edition of secondary sources.
### QOTD: small books
URL: https://www.lorcandempsey.net/qotd-small-books/
Last updated: 2020-10-28T09:14:00.000Z
From [Larry McMurtry’](https://www.worldcat.org/wcidentities/lccn-n79-27185?ref=lorcandempsey.net)s reminiscences as a bookseller: *[Books: a memoir](https://www.worldcat.org/oclc/213408552?ref=lorcandempsey.net)*.
> At Booked Up one of our favorite eccentrics was a gentleman we called the “little book” man.
> Once or twice a year this customer would show up at the shop with a ruler and work his way around the main room, measuring the books.
> He was not cheap in the least, and seemed to have no exact height limit. Every time he showed up he spent $2,000 at least, and often more. He never said much – indeed, I can’t recall him sayinganything. But he always went away carrying a box of short books. \[[Books: a memoir](https://www.worldcat.org/oclc/213408552?ref=lorcandempsey.net), p 138\]
I mentioned this to Thom Hickey yesterday in the context of an ongoing conversation about bibliographic data and the size of books.
The dimensions of a book are an important piece of metadata for some; if you are shipping books it is useful to know in advance what size they are. It also provides an example of how requirements can change over time. I was talking to somebody involved in an offsite storage facility a while ago where they had to measure incoming books who said that it would be so nice if they consistently knew the heights of the books from the metadata.
I wonder what they guy wanted the short books for 😉
### Working around works
URL: https://www.lorcandempsey.net/working-around-works/
Last updated: 2020-10-28T09:14:03.000Z
There is a significant – if little read – literature of cataloging theory. A recurrent theme is the balance between **gathering** like items, and **discriminating** between them. Managing similarity and difference in this way, and making sensible user interface choices, is not straightforward.
The FRBR model represents a recent approach to a part of this question: how to gather things that are in some way instances of the same intellectual work (a discretionary decision at the edges\*), and how to distinguish sensibly between these things (critical editions, for e.g, or translations, etc).
We now have a variety of online systems which present data about ‘book-like objects’. They have to make user experience decisions about how best to represent works and their instances.
Interestingly, Goodreads\*\* and LibraryThing seem to default to a work-based view: the entry is at the work level. See for example [Dr Zhivago](https://www.goodreads.com/book/show/130440.Doctor%5FZhivago?ref=lorcandempsey.net) and [Dr Zhivago](https://www.librarything.com/work/5263?ref=lorcandempsey.net).
Amazon seems to default to a particular ‘manifestation’ or ‘expression’ (to use FRBR terms) as in [Dr Zhivago](https://www.amazon.com/Doctor-Zhivago-Boris-Pasternak/dp/0679774386/ref=ntt%5Fat%5Fep%5Fdpi%5F1?ref=lorcandempsey.net). Google Books seems to do something similar – [Dr Zhivago](https://books.google.com/books?id=a517KSzY0EwC&dq=dr+zhivago&source=gbs%5Fnavlinks%5Fs). In each case, though, there is an attempt to link to other editions etc from a particular page.
Worldcat.org is more like Amazon and Google. At the moment, it aims to show the most highly held member of a work set in a result, and then link to other editions from that, as in [Dr Zhivago](https://www.worldcat.org/oclc/71399452?ref=lorcandempsey.net).
There are reasons for taking these various approaches and each service make decisions based on what it is trying to do, and the view it takes of its user interests.
Now, although the idea of a work has been a library concept for some time, the ‘manifestation’ level has tended to dominate practice, and this has carried forward into online catalogues. The catalog card, and the MARC record, are typically at the manifestation level and systems have been very ‘record-based’. They have not done a lot to re-combine the manifestation-level data to present other types of user experience than a record-by-record results display. The main exception to this may be an author-based approach. But typically, local systems have not sought to cluster data into works, or into displays about place or subject, the various things about which they have data.
Worldcat Identities is one response to this. It aims to pull data from multiple records to create a page which records what we know about a particular identity, [Boris Pasternak](https://worldcat.org/identities/lccn-n79-18438?ref=lorcandempsey.net), for example. Goodreads or LibraryThing will also give you a Boris Pasternak page based on what they know about him. (The National Library of Australia’s People Australia is also interesting in this regard. See for example, [Patrick White](https://nla.gov.au/nla.party-543123?ref=lorcandempsey.net).)
More recently, OCLC Research has been experimenting to see what data is available for display in a consolidated way at the work level. See a sample set of [pages](https://frbr.oclc.org/research/pages/?ref=lorcandempsey.net) here, and some background detail here \[[pdf](https://www.oclc.org/programs/events/2009-06-01h.pdf?ref=lorcandempsey.net)\].
\* A note on ‘discretionary’. We cluster stuff based on aggregate cataloger choices. I like Tim Spalding’s characterization of the ‘cocktail party test’ in a [blog entry](https://www.librarything.com/blog/2008/05/works-editions-isbns-and-cocktails.php?ref=lorcandempsey.net) about works and LibraryThing.
\*\* See the [comment](https://blog.oclc.org/lorcand/archives/001992.html?ref=lorcandempsey.net#comments) by Alex Thurman on Goodreads, suggesting it is more like Amazon.
### Rachel
URL: https://www.lorcandempsey.net/rachel/
Last updated: 2023-12-19T01:14:13.000Z
Andy Powell rang me a few days ago to tell me that our friend and former UKOLN colleague, Rachel Heery, had died. Although Rachel had been fighting cancer for a long time, I was shocked, as I had been speaking to her a few weeks before and she was in good form. Since being in the US I have not interacted with Rachel as much as I used to, but each time we spoke she was always so engaged and so full of news that I never really expected her to go.
I first met Rachel when she still worked for what was SLS in Bristol, later acquired by Innovative Interfaces. She rang up about a visit. I asked her to suggest a time. “Why don’t I come across this afternoon?” she responded, which was typical of her urge to move things along quickly. Not long after that Rachel came to work at UKOLN and helped establish the project work that was important to funding activity. She was an active participant in projects, and she was driven by the desire to do good work, to leave a mark (see the [UKOLN tribute](https://www.ukoln.ac.uk/ukoln/rmh-tribute-v1.1.html?ref=lorcandempsey.net) for a record of her contributions).
But what I will remember most from this time is all the dreary paperwork, the endless proposals, the torture by technical annex, the negotiations about partnerships, the working and reworking of spreadsheets to see if everybody could get what they wanted within allowable amounts, the scraping together of matching effort, the accounting for time, and the writing of project reports. Rachel did a lot of this work and she did it with determination and a sardonic humour: Rachel always did what it took to get the job done, even when the job was the pits.
Rachel was always ready to ask the difficult questions: she was more concerned about being on the right course than about being comfortable. Rachel stretched you. She told you what she thought. But she was often humorous and always focused on a good outcome. People recognized that she was ambitious, not for herself, but for the success of whatever effort she was contributing to.
She was also very conscious of being a woman in a male-dominated, often techie, environment. I think she would have been very pleased by [Sarah Currier’s remark](https://blogs.cetis.ac.uk/lmc/2009/07/28/rachel-heery/?ref=lorcandempsey.net#comments) on Lorna Campbell’s blog entry. “You always knew you had an ally- not an ally in the back-room handshake sense, but in the cut-the-crap, ‘let’s work out what’s best’ sense. She was fun and funny and an excellent role model for younger women coming through.”
Rachel developed a strong network of collaborators – through JISC, EU and DCMI activities – who will sorely miss her energy and friendship. As will her UKOLN colleagues. She leaves a big gap. Rachel was an important part of my working life and a good colleague and friend. We worked closely together for many years in an exciting time. I owe her a lot, and I will miss her. My sympathies are with Mike Heery, her husband, and her family, and I hope they take some small comfort from knowing the high esteem and affection which she inspired among her colleagues.
Here are some of the tributes to Rachel I have seen: [Lorna Campbell](https://blogs.cetis.ac.uk/lmc/2009/07/28/rachel-heery/?ref=lorcandempsey.net), [Stu Weibel](https://weibel-lines.typepad.com/weibelines/2009/07/rachel-heery-a-remembrance.html?ref=lorcandempsey.net), [Rachel Bruce](https://infteam.jiscinvolve.org/2009/07/31/rachel-heery/?ref=lorcandempsey.net), [Andy Powell](https://www.blipfoto.com/view.php?id=337042&month=7&year=2009&ref=lorcandempsey.net), [UKOLN](https://www.ukoln.ac.uk/ukoln/rmh-tribute-v1.1.html?ref=lorcandempsey.net).
There is a [note](https://www.bath.ac.uk/news/2009/07/27/death-rachel-heery/?ref=lorcandempsey.net) on the University of Bath site with funeral details.
### Related searches
URL: https://www.lorcandempsey.net/related-searches/
Last updated: 2020-10-28T09:14:07.000Z
Google has had some optional features for a while, although I have not seen much discussion of them. I don’t know if this is because they are not being much used, or there is some other reason.
Anyway, I was interested to try the related search earlier on my own name. Here is what I saw …

I suppose most of this is understandable, although I wondered what ‘lorcan dempsey encyclopedia’ was about.
### Blogging
URL: https://www.lorcandempsey.net/blogging-3/
Last updated: 2020-10-28T09:14:09.000Z
\[I am on vacation the latter couple of weeks in July, so not much blogging happening.\]
I was not registered for ALA at Chicago and only dipped in briefly to present on one panel. Afterwards, I continued congenial conversation in the bar in the Hilton, Kitty O’Shea’s (see the [entry](https://en.wikipedia.org/wiki/Katharine%5FO'Shea?ref=lorcandempsey.net) in Wikipedia for some background on the various names of Kitty O’Shea).
This meant that I turned up late for the OCLC Blog Saloon, er, I mean Salon, which was winding down as I arrived. I was interested to see [Meredith’s note](https://meredith.wolfwater.com/wordpress/2009/07/22/whither-blogging-and-the-library-blogosphere/?ref=lorcandempsey.net) about the Salon, and about the state of blogging in general. I agree about the volume of interesting blog material, and have made [similar comments](https://blog.oclc.org/lorcand/archives/001948.html?ref=lorcandempsey.net) in these pages recently, although I am less sure about what an ideal state would be like.
A while ago, I noted that I would be slowing down on the blogging front. This was largely because of the time commitment, the opportunity cost was a bit too high. However, as I did this, I also sensed that some of the heat had gone out of the blogosphere in general, and the library blogosphere in particular. The lists in my aggregator have visibly contracted.
Why? [Walt](https://scienceblogs.com/waltatrandom/?ref=lorcandempsey.net), whom I was pleased to bump into at the salon, is probably right to suggest in the comments that some energy around notifications etc has moved to Twitter: “Twitter et al … have, in a way, strengthened essay-length blogging while weakening short-form blogging (maybe)-and essays have always been harder to do than quick notes”. I think that there has also been some professionalization, generally and to a limited extent in the library world, where some blogging activity is aligned with publishing or professional venues, or with a particular job (see the HBR set of ‘blogs’ for e.g. or blogs like TechCrunch or Ars Technica which are effectively magazines). Some of the more active Twitterers – and bloggers – have positions that make it easier to contribute.
Incidentally, as we wound up in Kitty O’Shea’s and my cheque arrived, I signed with my room number. The waiter returned. There was a problem: he was courteously concerned that a different name than mine was showing up when he entered the details, and again when he rechecked. I went out to the front desk to sort things out. The same thing happened, and furthermore they had no record of my even being at the hotel. Was I sure I was actually staying at the hotel, the patient staff member asked? I huffed and puffed about having already signed for a meal and having been there since the day before. Suddenly, I realized that no, I was not at this hotel, I was staying in the Hyatt down at the conference center. My companions in Kitty O’Shea’s kindly said that they would not spread my embarrassment, but I would not want to spoil a good story for them 😉
Hey – when you are only there for a day or two, moving between hotels, … anybody could make a mistake 😉
Related entry:
- [Blogging ](https://blog.oclc.org/lorcand/archives/001948.html?ref=lorcandempsey.net)
### Library and beehive ...
URL: https://www.lorcandempsey.net/library-and-beehive/
Last updated: 2020-10-28T09:14:11.000Z
JISC has produced a short video about the library of the future …
This is part of its [Libraries of the Future](https://www.jisc.ac.uk/whatwedo/campaigns/librariesofthefuture.aspx?ref=lorcandempsey.net) initiative, and is about nine and a half minutes long.
Two quick things. First, I wish that the card catalogue was not used so much as an image of the library. Second, I liked Sarah Thomas’s suggestion that the library of the future would be like a beehive, where people could see and be seen, and congregate for conversation, food and learning.
I was reminded of Louis MacNeice’s characterization of the British Museum Reading Room as a hive-like dome to which I have referred in these pages a couple of times:
- [That reading room again](https://blog.oclc.org/lorcand/archives/000719.html?ref=lorcandempsey.net)
- [The flattening manifesto](https://blog.oclc.org/lorcand/archives/000718.html?ref=lorcandempsey.net)
### Shifting the sourcing model
URL: https://www.lorcandempsey.net/shifting-the-sourcing-model/
Last updated: 2020-10-28T09:14:13.000Z
A recurrent theme of this blog has been that networking changes the way we think about organizational boundaries.
So, we have seen a major shift to webscale which has reconfigured whole industries as well as individual organizations. Some obvious examples are the influence of Expedia/Orbitz/Travelocity on travel, Amazon on retail, Netflix on movie distribution, and the Web generally on newspapers and TV. Discovery is now largely a webscale activity.
At the same time the web has accelerated the vertical disintegration of firms and the sourcing of capacity with specialist providers. Think historically of payroll, or more recently of customer relationship management and SalesForce.com. A wide range of capacities may be sourced externally: think of anything from data centers, to the provision and care of plants, to education and counselling services. Companies make decisions about what their distinctive capacities are, and often externalise other capacities to networks of providers and partners. And, in fact, effective supply chain management has become an important competitive factor.
These types of questions are becoming more important for libraries, even if they don’t pose them in quite these terms. And they are not especially new. Historically, for example, think of two major shifts: shared cataloging/resource sharing and the move to licensed access to A&I databases and e-journals. In the former case, activity was externalised to consortial activity or to national-scale organizations, and today many organizations provide such services around the world, including OCLC. In the latter case, libraries gave up the institution-scale management of the A&I and journal resources they had collected in print form. They externalized this activity to, often commercial, third parties. At the same time, JSTOR was developed aiming to give libraries confidence in externalising the management of journal backruns, although it developed a broader role.
This trend has accelerated and will continue to do so as the network makes it easier to collaboratively source activities or to conveniently acquire service from third parties. Think of the variety of hosting options libraries now have across a range of systems and operations.
I was thinking about this last week as David Kay was visiting OCLC. David is a consultant working with the association of UK universities and national libraries, SCONUL, on a feasibility study into further ‘shared services’ in the library management systems. ‘Shared services’ is a UK government policy area which emphasises the advantages of consolidation through collaborative sourcing, potentially with commercial third party involvement. This policy area is [inherited](https://www.hefce.ac.uk/finance/shared/?ref=lorcandempsey.net) in higher education and for an example of the types of consolidation being discussed see the[ list](https://www.hefce.ac.uk/finance/shared/feasibility/?ref=lorcandempsey.net) of funded feasibility studies, including [some](https://www.hefce.ac.uk/finance/shared/feasibility/showcats.asp?cat=8&ref=lorcandempsey.net) in the library area.
David and colleagues are exploring with SCONUL the feasibility of various shared services to support library management systems. They have a project blog where you can find an interesting interim deliverable: the results of a survey of SCONUL membership about their readiness to embrace shared services across library operations. A brief report is available \[[.doc](https://www.sero.co.uk/assets/090629%20SCONUL%20Shared%20Services%20Survey%20Headlines.doc?ref=lorcandempsey.net)\], as well as a summary of the responses \[[.doc](https://www.sero.co.uk/assets/090606%20SCONUL%20SS%20Survey%20Responses%20Summary.pdf?ref=lorcandempsey.net)\]. Here are some of the highlights from the project blog:
> - The strongest focus is on adopting digital solutions and electronic content to reduce physical holdings and therefore space (85%)
> - A good number are ready to consider consolidating physical assets (51%)
> - Whilst 90% see reducing overall cost as an immediate high/medium priority, there is more interest in repositioning human resources (82%) than in reducing the establishment (50%)
> - High cost benefits are principally linked to content licensing (69%) and physical space savings (43%); possible staff cost savings are predominantly linked to management time (29%) and cataloguing (29%)
> - There is greater interest in library management systems functions being delivered through external shared services (80%) than by other local institutional systems (52%), though developing the role of the library service within the institution is a high priority intangible gain (84%)
> - Leveraging larger (web) scale services is seen by 73% as a high/medium 3-5 year priority but only an immediate priority for 46%; this fits with the high priority interest (84%) in enhancing flexibility and agility for developing electronic services
> - There exists a high level of readiness to consider Open Source software (30% with a further 45% neutral)
>
> \[[SCONUL Shared Services](https://sconulss.blogspot.com/?ref=lorcandempsey.net)\]
There is further detail in the blog and in the report. A video of David’s presentation at OCLC is also available ([.wmv](https://www5.oclc.org/downloads/research/webinars/20090701-Kay.wmv?ref=lorcandempsey.net)).
It is interesting seeing the high acceptance of the shared services model and the focus on particular areas. It will be interesting to see the final report. Of course, it will be more interesting to see whether there is the organizational will to put in place frameworks for such services to emerge.
### QOTD: Seamus Heaney on lecturing
URL: https://www.lorcandempsey.net/qotd-seamus-heaney-on-lecturing/
Last updated: 2022-11-08T18:21:07.000Z
From [Stepping Stones](https://www.worldcat.org/oclc/216941702?ref=lorcandempsey.net), a book-length collection of interviews with [Seamus Heaney](https://www.worldcat.org/identities/lccn-no2008-73657?ref=lorcandempsey.net) by [Dennis O’Driscoll](https://www.worldcat.org/identities/lccn-n85-87972?ref=lorcandempsey.net).
> The thing I should say, however, is that I am always nervous before a lecture. Even in my fifties, in Harvard, if I had a lecture, I’d be up early to try to get it squared out in my head – not that I could ever quite manage to do so. Lecturing week after week, as part of the padagogic routine, is more of a test than people realize. In the end, the most important thing is to be in good physical and mental shape. You can prepare as much as you like and amass material galore, but unless you come in fresh. like an athlete on to the track. you aren’t going to do the job required. At the end of a lecture, I tend to be as sweaty as a sprinter at the end of a race. \[Stepping stones: interviews with Seamus Heaney, p.104\]
### A web-siting at the University of Michigan
URL: https://www.lorcandempsey.net/a-web-siting-at-the-university-of-michigan/
Last updated: 2020-10-28T09:14:19.000Z
I came across the University of Michigan [beta library website](https://beta.lib.umich.edu/?ref=lorcandempsey.net) the other day. I thought it was interesting what they had done. Its central part is organized around three areas: **search**, **browse**, and **get help**. News is prominent, alongside a ‘feature’.
[](https://beta.lib.umich.edu/?ref=lorcandempsey.net)
I liked the way the search results were laid out to show a full range of library resources.
[](https://beta.lib.umich.edu/mlibrary/search/mirlyn;website;ejournals;searchtools;deepblue/demographics?ref=lorcandempsey.net)
The browse pages were preconstructed in particular subject areas, and included a link to ‘specialist’ librarian.
[ ](https://beta.lib.umich.edu/browse/Russian%20Studies?ref=lorcandempsey.net)
The **get help** area had links to a variety of guides and library contacts.
Although it is still a layer over various other resources, I liked the way that the site aimed to project the library on the web as a unified service not as a set of unrelated opportunities. This extended to the way that links to specialist library advice was included alongside the other resources.
### Visible people
URL: https://www.lorcandempsey.net/visible-people/
Last updated: 2020-10-28T09:14:22.000Z
I continue to be amazed at how difficult it is to find the name or contact details of the library director on many library websites. And in some cases to find the names of other relevant library contacts. This is especially the case given the emphasis on the human touch the library provides, and the expertise of library staff.
I was interested to see that the central focus of the Kelvin Smith Library website at Case was on collections, services and **people**.
[ ](https://library.case.edu/ksl/?ref=lorcandempsey.net)
Incidentally, I was also interested to see pictures and contact details of library staff placed around the irving K Barber Learning Centre on my recent trip there. Here is a [fuzzy picture](https://twitpic.com/8bdvo?ref=lorcandempsey.net).
Related entries:
- [A signed network presence: people as entry points again](https://blog.oclc.org/lorcand/archives/001873.html?ref=lorcandempsey.net)
- [Who we are](https://blog.oclc.org/lorcand/archives/001803.html?ref=lorcandempsey.net)
### Ranking, rating and recommending
URL: https://www.lorcandempsey.net/ranking-rating-and-recommending/
Last updated: 2020-10-28T09:14:25.000Z
We are now accustomed to being able to rank or recommend on websites. More importantly, we are accustomed to seeing resources ranked, related or recommended. To the extent, I suggested in a recent talk, that when we don’t see these features on a site it is as if as if we are watching black and white TV, or the colour has been bleached out of the experience.
There was a short article in *The Atlantic* recently which discussed this.
> Today’s ratings are only the raw material for what’s to come. Rearden Commerce’s Web-based personal assistant already helps employees in corporations like ConAgra make travel plans, by quizzing them about their age, income, job, family situation, lifestyle, and preferences like favorite types of restaurants. (JPMorgan Chase will roll out a Rearden-based travel adviser to its credit-card customers later this year.) The next step, says Rearden CEO Patrick Grady, is to pull in ratings from all over the Web and mash them up with anonymous information from Rearden users. Then, if a beef-loving cat-litter salesman is traveling to Dallas, the system can recommend a top-rated steak house where other cat-litter reps have had luck taking pet-shop owners to close deals. \[[The Rating Game](https://www.theatlantic.com/doc/200907/ratings?ref=lorcandempsey.net)\]
It noted that the Pew Internet & American Life Project “found that about one-third of all American Internet users rated something online” in 2007.
In the last few weeks I have had a couple of reminders about the interest in rating/recommending over and above the usual invitations from Netflix to rate borrowed movies. I bought a bag online from [Timbuk2](https://timbuk2.com/?ref=lorcandempsey.net), and a week or so after it arrived I was invited to go to the website to leave a review – good or bad. Such invitations are now routine. We bought a CD from an independent seller through Amazon. There was also an email followup. This was more interesting. It encouraged us to leave a rating of ‘5’ as anything less would be construed as negative by Amazon. If there were any issue which would prevent us leaving a rating of 5, the seller encouraged us to get in touch to discuss before doing anything to damage their reputation.
Ratings are very important to some. They will become more important to others. The examples above are of sites which invite ratings of services or products they offer, and in an environment of abundant resources and scarce attention we recognise the value of such behavior. However, it is natural to go beyond this to sites whose central function is to rate/recommend. We are familiar with [ratemyprofessor.com](https://ratemyprofessor.com/?ref=lorcandempsey.net) and the article mentions [glassdoor.com](https://glassdoor.com/?ref=lorcandempsey.net), a site which allows employees rate their employers. The article also discusses some of the issues with such sites, as groups protest against being evalutated in this way.
### In English?
URL: https://www.lorcandempsey.net/in-english/
Last updated: 2020-10-28T09:14:30.000Z
I thought I would post some numbers here which were prepared by my colleague Brian Lavoie for another purpose. The question was: how many of the books in US libraries are in English?
First of all, what is a book? Deciding what a book is involves some choices (are theses in or out, for example?). This analysis uses the definition of ‘print books’ given in the Google 5 analysis [published](https://www.dlib.org/dlib/september05/lavoie/09lavoie.html?ref=lorcandempsey.net) in DLib Magazine a while back \[1\].
**a**. All of WorldCat (Apr 09):
135.3 million records
Cataloged as “eng”: 46 percent (so 54 percent non-English)
**b**. Print books only (Apr 09):
91.2 million
Cataloged as: “eng”: 40 percent (so 60 percent non-English)
**c**. Print books in US libraries (Jan 09)
42.5 million
Cataloged as “eng”: 57 percent (so 43 percent non-English)
**d**. Print books representing combined collections of three academic research libraries participating in GBS (April 2009):
7.2 million
Cataloged as: “eng”: 54 percent (so 46 percent non-English)
Note – **c** is calculated on a slightly earlier version of the database as we had already pulled out US library holdings. The data in **d** is being looked at for another purpose: hence the slightly arbitrary selection of 3 libraries.
Note – these numbers are for records in the database, which represent ‘manifestations’ in FRBR terms. If one were to count holdings or actual copies the numbers would be different. The proportion of ‘eng’ would go up as English titles will be more widely held and in greater numbers of copies.
\[1\] Here is how the definition of a ‘print book’ was decided upon and operationalised for the Google 5 analysis. “Although there is no unambiguous bibliographic definition of a book, libraries have often used *monographic language materials* as a proxy for books, and this practice is adopted for this study. More specifically, in the context of a MARC21 record, a book is defined as a language-based monograph, identified by the codes “a” and “m” in bytes 6 and 7 of the leader, respectively. For the purposes of this study, theses/dissertations and government documents are excluded from the analysis, since these materials are usually acquired and managed as separate segments of the library collection. Records describing books in print format were identified by eliminating all non-print formats, such as digital, microform, Braille, and so on.”
### Augmenting
URL: https://www.lorcandempsey.net/augmenting/
Last updated: 2020-10-28T09:14:32.000Z
[Layar](https://layar.eu/?ref=lorcandempsey.net) created a ripple of interest a while ago. It is yet to be released. It is an application for Android based phones which will allow data from various partner resources to be ‘layered’ over the view through a camera phone. Partners discussed include banks (for ATMs), realtors, and a social network site with data about venues. They describe it as an augmented reality application: objects viewed through the camera may be augmented by data about those objects.
> Layar is derived from location based services and works on mobile phones that include a camera, GPS and a compass. Layar is first avaliable for handsets with the Android operating system (the G1 and HTC Magic). It works as follows: Starting up the Layar application automatically activates the camera. The embedded GPS automatically knows the location of the phone and the compass determines in which direction the phone is facing. Each partner provides a set of location coordinates with relevant information which forms a digital layer. By tapping the side of the screen the user easily switches between layers. This makes Layar a new type of browser which combines digital and reality, which offers an augmented view of the world. \[[Sprxmobile – Layar](https://www.sprxmobile.com/we-launched-layar-worlds-first-augmented-reality-browser-for-mobile/?ref=lorcandempsey.net)\]
[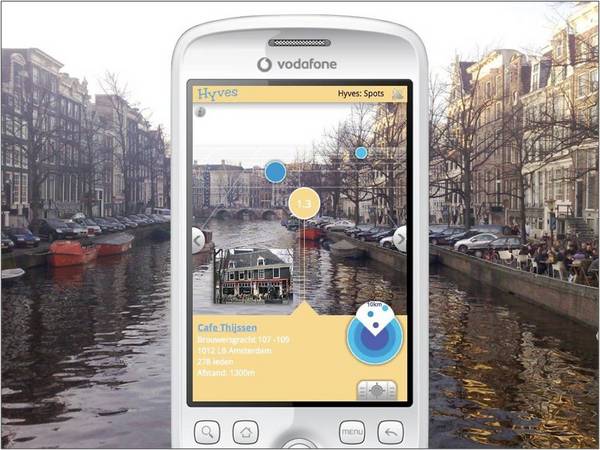](/lorcand/lorcan/layar.jpg)
\[image: layar.eu via Tito Sierra M-Libraries 09 [ppt](https://www.lib.ncsu.edu/dli/projects/wolfwalk/docs/mlibraries-2009.ppt?ref=lorcandempsey.net)\]
Tito Sierra referenced Layar in his presentation about [WolfWalk](https://www.lib.ncsu.edu/dli/projects/wolfwalk/?ref=lorcandempsey.net), project, at the [Second M-Libraries Conference](https://m-libraries2009.ubc.ca/?ref=lorcandempsey.net) in Vancouver last week. WolfWalk is a pilot project at NCSU as I [mentioned](https://blog.oclc.org/lorcand/archives/001979.html?ref=lorcandempsey.net) the other day. It is working on an iPod application which aims to create what Tito called a ‘geomobile collection’. Here is what the project pages say:
> A pilot project to create a mobile application that enables users to explore NC State campus history using a location-aware map-based interface. The application supports a map view (using Google Maps) with geotagged placemarks for approximately 60 major sites of interest on the NCSU campus, and a browse view for quickly locating a known site by name. Each site has several historical images associated with it that are sourced from NCSU Special Collections Research Center digital archives. \[[WolfWalk](https://www.lib.ncsu.edu/dli/projects/wolfwalk/?ref=lorcandempsey.net)\]
[](/lorcand/lorcan/assets%5Fc/2009/06/ww2-thumb-260x382-52.png)[](/lorcand/lorcan/assets%5Fc/2009/06/ww-thumb-383x620-50.png)
Tito discussed how they thought this would be of interest to alumni and was careful to describe it as a modest proof-of-concept. I thought it succeeded very well in demonstrating his contention that the challenge is not just to provide small-screen versions of digital collections but to leverage the capabilities of new mobile technologies to provide new ways of experiencing those collections. In this case, the collections augment the experience of the buildings on campus by providing historic context at the point of interaction; at the same time, the app provides a map-based approach to digital collections.
The [screencast](https://screencast.com/t/anNVO2BBO?ref=lorcandempsey.net) and [powerpoint](https://www.lib.ncsu.edu/dli/projects/wolfwalk/docs/mlibraries-2009.ppt?ref=lorcandempsey.net) presentation are well worth a look. The WolfWalk pictures above are screenshots of the screencast.
[Mlib09](https://www.technorati.com/tag/mlib09?ref=lorcandempsey.net)
### Apple, netbooks and barcodes
URL: https://www.lorcandempsey.net/apple-netbooks-and-barcodes/
Last updated: 2020-10-28T09:14:35.000Z
I traveled home from the [2nd M-Libraries Conference](https://m-libraries2009.ubc.ca/?ref=lorcandempsey.net) in UBC, Vancouver, yesterday. I was interested to come across several relevant news stories in the reading materials I had bought en route: *The Globe and Mail*, *The Economist* (last week’s, as it turns out), and *The Financial Times*. This underlined the topicality of the conference themes.
The iPhone was prominent at the conference, in discussion, but also in practice as they were slipped in and out of pockets and bags throughout. In an interesting presentation about their [WolfWalk](https://www.lib.ncsu.edu/dli/projects/wolfwalk/?ref=lorcandempsey.net) project, Tito Sierra of NCSU opened with some general remarks about geo-location and touch screens as distinctive capacities supporting new applications. He also reminded people of the importance of the Apple Apps store in reducing transaction costs for users: search and acquisition of apps was now straightforward. What Apple has done is to create a network of developers around its successful platform. The App Store is key to this as it allows app developers to find users, and users to find apps, and in the process the value of the iPhone/iTouch is increased. This point was reinforced in a [story](https://www.ft.com/cms/s/0/12c92e6e-60e7-11de-aa12-00144feabdc0.html?nclick%5Fcheck=1&ref=lorcandempsey.net) about Apple’s success in countering the effects of the current downturn in the *Financial Times*. John Gapper quotes [work](https://edgeperspectives.typepad.com/edge%5Fperspectives/2009/06/shift-happens-redux.html?ref=lorcandempsey.net) by Hagel and Seely Brown of Deloitte which shows that lower costs of entry brought about by regulatory and technical trends are creating stronger competitive challenges for companies. Apple’s ability to resist this trend depends on the way in which it has created a platform around which a network of partners has built thousands of apps. So, for the Palm Pre to be successful, for example, it not only has to compete with the iPhone on price and features, but also on its ability to become a platform for app developers. Much of the value of the iPhone now derives from the apps which are available to its users.
I was also struck by the number of Mlib09 delegates who were using netbooks. I suppose you would expect this at such a conference, but this did not make it any less striking. The *Economist* had an [article](https://www.economist.com/businessfinance/displayStory.cfm?story%5Fid=13832588&source=most%5Frecommended) on netbooks, focusing on their challenge to the computer and software industry generally. They report Gartner figures that 21M netbooks will ship this year, twice as many as last year, accounting for more than 15% of the laptop market. By the end of 2008, netbook pioneer Asus had sold nearly 5M Eees. I was interested to read that Microsoft was heavily discounting Windows XP to netbook providers to counter the Linux challenge. Acer and other firms plan to use Android.
One of the hits of the conference was the discussion by Kate Robinson of the use of QR Codes in the [catalog](https://library.bath.ac.uk/uhtbin/bath/UB-LIBS/ckey/129507?ref=lorcandempsey.net) at the University of Bath (blogged [here](https://blog.oclc.org/lorcand/archives/001923.html?ref=lorcandempsey.net) earlier this year). It prompted discussion of the variety of ways in which people and materials could be tied into the network.
The Globe and Mail had several stories about capturing data from codes.
- [Databars](https://www.theglobeandmail.com/report-on-business/new-produce-sticker-is-smarter-smaller/article1196262/?ref=lorcandempsey.net). A discussion of the use of Databars, smaller than barcodes, in retail and supply-chain operations.
- [Samplesaint](https://www.theglobeandmail.com/report-on-business/discounts-offered-by-cellphone-exceed-marketers-expectations/article1196264/?ref=lorcandempsey.net): a story about how this company, which creates digital media for cell phones, now distributes discount coupons for redemption by on-screen scanning at the checkout. Coupons can be received in various ways, including in response to an on-the-spot request by texting a number found on the relevant shelf.
- There is also a [general discussion](https://www.theglobeandmail.com/report-on-business/paying-with-the-wave-of-a-cellphone/article1196263/?ref=lorcandempsey.net) of the use of cell phones as payment devices.
Interestingly, these were opposite an advert for IBM (featuring a barcode image) which promoted its ability to make supply chains smarter and more efficient.
### User symposium presentations
URL: https://www.lorcandempsey.net/user-symposium-presentations/
Last updated: 2020-10-28T09:14:37.000Z
The presentations from the [2009 RLG Partnership Annual Symposium: Hearing voices: connecting with users, enhancing services](https://www.oclc.org/programs/events/2009-06-03.htm?ref=lorcandempsey.net)
, are now available.
Here is how the event was described ..
> User studies have become a critical component in developing and improving services in our institutions. However, investigations into the needs of users and potential users are expensive and time consuming. This event oriented attendees to the importance of user studies, highlighted findings from recent projects of interest and utility to the RLG Partnership, and laid the groundwork for future collaboration. \[[2009 Symposium agenda](https://www.oclc.org/programs/events/2009-06-03.htm?ref=lorcandempsey.net)\]
I was interested to read Arnold Arcolio’s account of user selection on several Worldcat Local implementations. Arnold works for the User Experience Group at OCLC.
See the notes about usability and the symposium from [me](https://blog.oclc.org/lorcand/archives/001971.html?ref=lorcandempsey.net) and from [Jim](https://hangingtogether.org/?p=702&ref=lorcandempsey.net) at HangingTogether.
### Border country: classifying across disciplinary boundaries
URL: https://www.lorcandempsey.net/border-country-classifying-across-disciplinary-boundaries/
Last updated: 2020-10-28T09:14:39.000Z
Terry Eagleton said somewhere that Raymond Williams was a librarian’s nightmare, meaning presumably that his work crossed academic boundaries and resisted easy classification. Let’s have a look using the [Classify](https://deweyresearch.oclc.org/classify2/?ref=lorcandempsey.net) prototype.
> The prototype provides access to more than 36 million WorldCat records that contain Dewey Decimal Classification (DDC) numbers, Library of Congress Classification (LCC) numbers, or National Library of Medicine (NLM) Classification numbers.
> The records are grouped using the OCLC FRBR Work-Set algorithm resulting in a work-level summary of the class numbers assigned a title. You can retrieve a classification summary by ISBN, ISSN, UPC, OCLC number, or author/title. \[[About Classify](https://www.oclc.org/research/researchworks/classify/?ref=lorcandempsey.net)\]
OK, so here is what happens with [The Country and the City](https://www.worldcat.org/oclc/624711/editions?ref=lorcandempsey.net), maybe the one of his works most likely still to be read. It leans to literature, history, sociology …
[](/lorcand/lorcan/countrylcc.png)
Here is Keywords …
[](/lorcand/lorcan/keywordsddc.png)
And here is an early work, The Long Revolution …
[](/lorcand/lorcan/longrevddc.png)
There is quite a bit that could be said here. It would be interesting to explore what the pattern of classification might reveal about intellectual trends or cross-disciplinary work. I will limit myself here to saying that it looks as if Eagleton may be right some of the time 😉
### Reading books on the move ...
URL: https://www.lorcandempsey.net/reading-books-on-the-move/
Last updated: 2020-10-28T09:14:41.000Z
I have just read *M-Libraries: Information use on the move: a report from the Arcadia Programme* \[[pdf](https://arcadiaproject.lib.cam.ac.uk/docs/M-Libraries%5Freport.pdf?ref=lorcandempsey.net)\] by Keren Mills.
It provides an overview of recent trends in ‘mobilized’ library services, library services which use mobile communications. It reports the results of a survey of library users about their preferences and makes some recommendations for library services.
I was interested to read the following:
> These results suggest it is not worth libraries putting development resource into delivering content such as eBooks and e-journals to mobile devices at present. EBooks are already accessible via some mobile phones, such as iPhones and Windows Mobile devices, and audio files such as podcasts and audio books can easily be played on many mobile phones or portable media players. At present, however, most users are put off by the constraints of the technology, such as poor screen quality. iPhone users are already more inclined to read eBooks on their phones, according to comments from the respondents to this survey. \[*M-Libraries: Information use on the move: a report from the Arcadia Programme* [pdf](https://arcadiaproject.lib.cam.ac.uk/docs/M-Libraries%5Freport.pdf?ref=lorcandempsey.net)\]
In the time when this report was being prepared we have seen major developments in the consumer ebook space. There has been discussion of Google Editions, new releases of the Kindle, and a variety of reading applications (e.g. Stanza, Eucalyptus), and several companies are working to provide various reading options.
One reason for this is given in the note above: the iPhone, and now other smartphones which are trying to compete, has made reading more congenial.
In this context, I wonder what sort of response Keren would get if she were to repeat her survey in, say, 3 years time.
Incidentally, Mike Shatzkin has an interesting presentation about the future of books [here](https://www.idealog.com/stay-ahead-of-the-shift-what-publishers-can-do-to-flourish-in-a-community-centric-web-world?ref=lorcandempsey.net), given recently at Book Expo 2009.
### An identity incompletely centered ..
URL: https://www.lorcandempsey.net/an-identity-incompletely-centered/
Last updated: 2020-10-28T09:14:44.000Z
The Facebook username landgrab created a flurry of excitement over the weekend. Individuals ‘claimed’ their piece of network real estate in the form of a Facebook URL, and organizations had an opportunity to protect registered marks. I am now
which chimes with my recently established Twitter presence
[https://www.twitter.com/lorcand](https://www.twitter.com/lorcand?ref=lorcandempsey.net)
I decided to consolidate on **lorcand** a little while ago, when I switched from the more opaque **lisld** on Twitter. Of course, this was late in my online life, meaning that – as most others do – I have a fractured online identity: it is pretty decentralized. I feel that I ought to more actively adopt some centering strategies (see below) but it never gets to the top of the list.
I am prompted by this experience to incorporate here a post of last year – *centering the decentralised identity* – which is still relevant …
Andy Powell, [network resident](https://blog.oclc.org/lorcand/archives/001773.html?ref=lorcandempsey.net), has an interesting post about his ‘fractured’ network identity. How does he define identity?
> “Digital identity is the online representation of an individual within a community, as adopted by that individual and/or projected by others. An individual may have multiple digital identities in multiple communities.” \[[Andy Powell, eFoundations](https://efoundations.typepad.com/?ref=lorcandempsey.net)\]
He describes how his digital identity is ‘fractured’ across many environments (FaceBook, Flickr, various home pages and blogs, Second Life, twitter, etc). Various professional or personal affiliations are explicitly visible in several ‘friendspaces’ (my word), on FaceBook and Twitter for example. Andy even confesses to an ‘identity crisis’ around his second life identity, Art Fossett.
> I also have something of an identity crisis around Art Fossett – specifically concerning how closely the digital identities of Andy Powell and Art Fossett should be related. \[[eFoundations: define:digital identity](https://efoundations.typepad.com/efoundations/2008/11/definedigital-identity.html?ref=lorcandempsey.net)\]
Reading the entry, it seemed to me that Andy is talking about ‘centering’ this ‘decentralized identity’ in various ways: he talks about wanting to ‘consolidate’ his network presence.
(John Breslin schematically represents decentralized identity in a [blog entry](https://www.johnbreslin.com/blog/2007/03/01/linking-personal-posted-content-across-communities/?ref=lorcandempsey.net) of some time ago.)
There are various centering or consolidating strategies …
Andy talks about limiting the number of ‘handles’ his identity has – email addresses and user names, although he is not in a position where his personal identities can override his current work identity (at Eduserv).
He is working to center his network presence at [https://andypowe11.net/](https://andypowe11.net/?ref=lorcandempsey.net) and has some interesting comments about steps taken or to be taken. These include the suggestion that his former place of work put redirects from historically superseded network presences to his current one so that he can capture their ‘Google juice’, which raises interesting questions about our view of the historical record on the web.
He also has some advice about the use of third party services, about control of domain names, and about where you build up ‘google juice’ as moving it may be outside of your control.
Several things struck me reading this post …
- Andy’s concerns here are probably in advance of most people’s, but it seems clear that managing our network presences and the relationships between them is becoming of more interest. And this cuts across previous boundaries – between work, family and friends, for example – in different ways.
- My network identity is less decentralized than Andy’s: overall, I am less residential 😉 Until recently, I would have seen this ‘fracture’ as simply a part of an ongoing transition into new ways of doing things. And I wouldn’t have had the patience or the inclination to adopt various centering strategies. That said, I have been more conscious recently of where I want my network presence to be ‘signed’ and where I don’t. To take an example close to home, I wrote some longish reviews on items in Worldcat; recently, I realised that I would like the system to be able to support in some way my assertion that I was their author, and now it does by linking to a profile page. I have tended to use lisld as a handle in a variety of places. Now, I would probably more consistently use something like LorcanDempsey where I was more concerned about ‘signature’, although I am quite attached to lisld 😉
- Of course, Google is a strong bottom-up centering service (see Tony Hirst’s interesting [suggestion](https://ouseful.wordpress.com/2008/11/20/where-is-the-open-university-homepage/?ref=lorcandempsey.net) that an institution’s de facto home page is the first page of Google results in a search for that institution). My first-page Google results tend to be dominated by this blog, but there are also current and previous work pages, some articles come and go, and more recently Wikipedia and Facebook make a showing. None of these is at a domain name controlled by me. This blog was established as an internal OCLC communications tool for a year before it was externalised so it is ‘located’ at OCLC (in several ways). Now, I am sure that it gets a ranking ‘lift’ from the OCLC domain name, but it also means that I cannot bring it with me as it now stands if I ever leave. In a sense, I lose some of that network capital. Of course this is quite reasonable from another view, but it does raise interestingly the balance between individual and institution.
- My name is not unique. However, it is not very common. Andy notes his ‘Google nemesis’, Andy Powell of Wishbone Ash. It would be interesting to [know more](https://blog.oclc.org/lorcand/archives/001385.html?ref=lorcandempsey.net) about what the impact of findability in Google has been on the naming of children.
- Now, I know that there are various initiatives underway which may make our identities more portable. I assume – hope – that we will end up with the ability to port our identities flexibly, but that we also retain the ability to support decentralised identities which may not know very much, or anything, about each other 😉
\[[Original post](https://blog.oclc.org/lorcand/archives/001809.html?ref=lorcandempsey.net): centering the decentralized identity\]
### Data flows in the book world
URL: https://www.lorcandempsey.net/data-flows-in-the-book-world/
Last updated: 2020-10-28T09:14:45.000Z
One of the recommendations of the [Library of Congress Working Group on the Future of Bibliographic Control](https://www.loc.gov/bibliographic-future/?ref=lorcandempsey.net) was that ways should be found of harnessing publisher data upstream of the cataloging process. The rationale was that this would make data about materials available earlier and reduce overall creation effort.
OCLC recently organized an [invitational symposium](https://www.oclc.org/publisher-symposium/summary/default.htm?ref=lorcandempsey.net) which had this issue as a central topic. The report is an interesting set set of notes from the different perspectives of the multiple players involved. It discusses current practices and incentives to do things differently.
In a follow-on activity to the LC report, R2 Consulting are mapping the flow of MARC records in North American. The symposium notes say: “This list of distributors is much larger than originally anticipated and consists of a very diverse group of entities.”
And, as I discussed the other day, the Research Information Network has published a report about UK practices, *Creating catalogues: bibliographic records in a networked world* \[[Splash page](https://www.rin.ac.uk/creating-catalogues?ref=lorcandempsey.net); [pdf](https://www.rin.ac.uk/files/Creating%5Fcatalogues%5FREPORT%5FJune09.pdf?ref=lorcandempsey.net)\], which also recommends greater re-use of records across the publishing and library worlds.
So, there certainly seems to be a convergence of interest here. Indeed, the potential benefits of such sharing have been a topic of discussion for many years. For example, at the OCLC Symposium, Brian Green, Executive Director of the International ISBN Agency, and I reminisced about UK initiatives to we had been party almost, gulp, twenty years ago to try to create the conditions for an ‘all-through’ system of bibliographic record exchange between the various players in the bookworld.
Now, clearly quite a lot has happened and as R2 reported above data flows through many parties. And publisher data does flow into CIP, and into various organizations which support libraries. Amazon has done much to underline the importance to publishers of having book metadata to support a variety of operations. That said, the renewed emphasis on publisher-library data flow, certainly from the library side, suggests that much more might be done.
Why has more not happened to promote the flow of metadata through the system, from publishers to libraries? Three things occur …
First, there is the mechanical issue of data exchange. Onix has now emerged as a shared approach to disseminating publisher data. However, it is interesting reading the remarks about Onix in the report of the OCLC Symposium. Netlibrary reports that 10% of publishers supply data in ONIX, representing 50% of the supplied content. NLM also reported that 10% of publishers supply Onix, but that these account for 80% of materials catalogued at NLM. There were also lots of comments about the consistency of Onix data. However, one would expect improved technical apparatus to support data flow, not create the need for it.
This prompts the second question: what incentives exist and are they aligned across the system? Historically, metadata may have been created for different purposes. Publishers had an interest in the supply chain, and libraries an interest in inventory control. There may be a shared interest in discovery, but it has been approached differently in each area. In fact, one library interest is a recognition that more descriptive material (table of contents, summary, etc) is in fact very useful for users of their catalogs and other systems even though they have not historically made it a part of their catalog data. There may also be an interest in getting basic descriptive data earlier, to allow more time to be spent on other parts of record creation. What incentives exist for publishers to make data available to libraries? Amazon, and other agents in the supply chain, provide an incentive to make appropriate metadata available to support discovery and sales. Data is supplied for CIP purposes. Are there additional incentives? One may be to have enriched metadata flow back to publishers. Are there incentives here which are strong enough for a framework to emerge within which there is greater flow?
And third, related to this, and probably most important, is that the incentives on either side have not been strong enough to encourage organizations to develop services in this area which would make the flow a reality.
Of course, the reason that OCLC hosted the Symposium mentioned above is that it is now looking at whether it is sensible to begin providing such services. It is doing this in its ‘[next generation cataloging](https://www.oclc.org/partnerships/material/nexgen/nextgencataloging.htm?ref=lorcandempsey.net)‘ program.
> OCLC has launched a pilot project to explore upstream metadata capture and enhancement using publisher and vendor ONIX metadata. Pilot partners from the publishing, vendor and library communities are assisting us in this effort. We hope the pilot will result in ongoing processes for the early addition of new title metadata to WorldCat and enhanced quality and consistency in upstream title metadata used by multiple channels. \[[Next generation cataloging](https://www.oclc.org/partnerships/material/nexgen/nextgencataloging.htm?ref=lorcandempsey.net)\]
Update: In response to query, see [here](https://publishers.oclc.org/en/default.htm?ref=lorcandempsey.net) for more information about how OCLC can work with publishers and [here](https://www.oclc.org/partnerships/material/cataloging/default.htm?ref=lorcandempsey.net) for how OCLC works with book vendors to deliver cataloging data.
**Postscript**: The conversation with Brian Green prompted me to look up various pieces I wrote at the time which reflected some of the discussion we remembered. (I note that while I have difficulty opening Word files from that time, the RTF file is still readable.)
- Publishers and libraries: an all-through system for bibliographic data?
*International Cataloguing and Bibliographic Control*. 20 (3), July/September, 1991, 37-41.
RTF: [https://www.ukoln.ac.uk/services/papers/ukoln/dempsey-1991-01/ubcim.rtf](https://www.ukoln.ac.uk/services/papers/ukoln/dempsey-1991-01/ubcim.rtf?ref=lorcandempsey.net)
- Users’ requirements of bibliographic records: publishers, booksellers, librarians.
*ASLIB Proceedings*, 42 (2), February 1990, 61-69\. \[[Worldcat.org](https://www.worldcat.org/oclc/56916306?ref=lorcandempsey.net)\]
- *Bibliographic records: use of data elements in the book world*. Bath: Bath University Library, 1989\. ISBN 0861970853 \[[Worldcat.org](https://www.worldcat.org/oclc/19267913?ref=lorcandempsey.net)\]
### Sharing usability results
URL: https://www.lorcandempsey.net/sharing-usability-results/
Last updated: 2020-10-28T09:14:47.000Z
I was interested to see that MIT Libraries have a [public page](https://libstaff.mit.edu/usability/?ref=lorcandempsey.net) with links to various usability results. I thought it was quite interesting, and that, while acknowledging some local flavor, it might be useful if more libraries shared results in this way.
More generally, we know that there are a lot of local user study activities the results of which would be of interest to others.
There was some discussion of the benefits of such sharing at the *[2009 RLG Partnership Annual Symposium: Hearing voices: connecting with users, enhancing services](https://www.oclc.org/programs/events/2009-06-03.htm?ref=lorcandempsey.net)*. (Presentations available soon.)
Jim builds on that discussion in a post over on HangingTogether …
> My screenagers aren’t fundamentally different from your screenagers. My graduate students aren’t fundamentally different from your graduate students. My students and faculty don’t do their work in a fundamentally different way then yours. My clients expectations and use of a local library catalog are not fundamentally different than yours. Why would we imagine that the willingness to go beyond the first page of results in a catalog search is going to differ by institution? If we can accept that there is a system-wide relevance to these studies then we are well on the way to a shareable profile of our different client segments (academic/public, undergrad/graduate, casual user, etc.). We’re well along on having a broad foundation on which to do further work that is more closely aligned with the distinctive services and impact that the library can have. \[[HangingTogether](https://hangingtogether.org/?p=702&ref=lorcandempsey.net)\]
He goes on to make some interesting remarks about understanding users and their desire to connect with each other.
Related entries:
- [A signed network presence: people as entry points again](https://blog.oclc.org/lorcand/archives/001873.html?ref=lorcandempsey.net)
- [Some thoughts about egos, objects, and social networks](https://blog.oclc.org/lorcand/archives/001601.html?ref=lorcandempsey.net)
### Libraries and catalogues: systemic attention
URL: https://www.lorcandempsey.net/libraries-and-catalogues-systemic-attention/
Last updated: 2020-10-28T09:14:49.000Z
The Research Information Network in the UK has released a timely report: *Creating catalogues: bibliographic records in a networked world* \[[Splash page](https://www.rin.ac.uk/creating-catalogues?ref=lorcandempsey.net); [pdf](https://www.rin.ac.uk/files/Creating%5Fcatalogues%5FREPORT%5FJune09.pdf?ref=lorcandempsey.net)\]. It is concise and has a useful Summary and Key Findings section.
I found it an interesting read, in no small part because it rehearses various key themes of these pages. Critically, it discusses systemwide reconfiguration of library services, a far-reaching and critical issue for libraries in a network environment.
There are two overarching issues. One is that library processes are inefficient because resources are consumed in redundant activity that do not create distinctive local value. The second is that a fragmented presence on the web reduces impact and visibility. Of course each of these is related to the institutional-scale nature of much current work, which is poorly aligned with emerging network organization, where we have become accustomed to institutions externalizing activities. The network allows routine work to be consolidated (think payroll) and it favors concentrated user hubs (think Amazon and Google).
So, from a processing point of view it is not surprising to see recommendations which point to better sharing of the burden of data creation across the book/journal world and between libraries (and in this context, there is a discussion of record re-use and innovation). And from an impact point of view, there are recommendations about consolidating the web presence of libraries in order to better focus user attention.
Perhaps the recommendation which will receive the most attention is the following:
> Libraries are therefore spending significant resources in editing the records they receive, as well as adding data to meet their own local needs. Sustaining and developing individual catalogues for the more than 160 university libraries in the UK demands considerable resources. A shared catalogue for the whole UK higher education (HE) sector, with dynamic links to local holdings, could bring enormous benefits, in terms of reduced costs, of a more comprehensive coverage of both national and local holdings with better-quality records. It would also provide the potential for developing new user-focused services allowing them to remain relevant to their users and to compete with Amazon, Google and others.
I guess I would not emphasise competition in this way, as one of the functions of such a concentration (noted elsewhere in the report) would be to act as a switch and syndication point on the network.
The report has sensible recommendations about better provision of e-book data; it argues for better dissemination of article level data; and it supports various consensus making activities. I was surprised not to see more discussion of knowledgebase/ERM activity, although this may have been out of scope. This is especially because this is also an area with some potential for consolidation and network concentration.
I will watch with interest how this report is received and discussed. I think that it is inevitable that libraries will externalize more of what they do to third parties and shared services. This is both to increase efficiency and to increase impact. This does not remove the local role, rather it represents a natural evolution in which time and attention can be devoted to changing local needs and interests.
Update: The report does not provide a blueprint for action. It does put a stake in the ground which may shift the conversation.
### Audience level
URL: https://www.lorcandempsey.net/audience-level-2/
Last updated: 2020-10-28T09:14:50.000Z
I have written about the Audience Level measure in these pages a few times. In this initiative we are using the pattern of holdings across different types of libraries (school, research, etc) to give a ‘hint’ about the level of interest of an item (juvenile, research/specialist, …). You can read more about how we calculate the levels on the project page:
> Recognizing that different types of libraries typically serve different populations, OCLC researchers considered whether library types could be related to audience levels. They decided to explore whether the pattern of holdings of materials in WorldCat might be leveraged to provide an audience-level indicator. \[[Audience Level \[OCLC – Projects\]](https://www.oclc.org/research/projects/audience/default.htm?ref=lorcandempsey.net)\]
The audience level is used in Worldcat Identities pages. It is also used in various internal processing activities where data of a certain type is required, for example where we are asked to share data about ‘academic’ materials. Check it out [here](https://audiencelevel.oclc.org/AudienceLevel/al?ref=lorcandempsey.net).
My colleagues carried out an evaluation a while ago to see how closely this algorithmic approach based on holdings patterns matched human judgments. Their results were published in JASIST last year.
> Edward T. O’Neill, Lynn Silipigni Connaway, Timothy J. Dickey. Estimating the audience level for library resources. *Journal of the American Society for Information Science and Technology*. Volume 59, Issue 13, Pages 2042-2050\. 2008
> \[[https://dx.doi.org/10.1002/asi.20908](https://dx.doi.org/10.1002/asi.20908?ref=lorcandempsey.net) subscription resource\]
> Update: Pre-print available online at: [https://www.oclc.org/research/publications/archive/2008/oneill-jasist.pdf.](https://www.oclc.org/research/publications/archive/2008/oneill-jasist.pdf?ref=lorcandempsey.net).
The team first examined a randomly generated sample of books from a research library, and the results looked promising. They then proceeded to a more formal test.
> The second test compared the rankings of the audience level against ranking decisions made by human subjects. A sample of 30 books was ranked by each of 21 test participants, and a set of test rankings was created for each of the books. The test collection consisted of a stratified sample of 30 books from WorldCat. The books were all in the field of zoology, published in the year 2004, and representative of the entire spectrum of audience-level rankings.
And the result …
> The conclusion is that there exists a significant correlation between the human subjects’ ranking and the audience-level rankings. The most important result of this test is the indication that the audience level and human subjects’ perceptions are strongly correlated.
Leading them to conclude ..
> The audience level is a valuable aid in identifying the appropriate resources for a particular audience. The algorithm produced audience-level values that were consistent with those of human evaluators as demonstrated both by the analysis of the actual books and by the comparison of the algorithmic results to those of a test group of human subjects. Based on the findings of this research, the audience level can be seen as a new tool with the potential to improve information relevance for discovery and selection for collection analysis, readers’ advisory, and reference services.
### Find on a plane ...
URL: https://www.lorcandempsey.net/find-on-a-plane/
Last updated: 2020-10-28T09:14:52.000Z
After many years of traveling without much incident I left a couple of things on planes recently. They never showed up, but It was a bit of a pain inquiring about them. It occurred to me that this was an application that lent itself to something of a crowdsourced approach, or at least to some form of shared network space, where the airline, the affected passenger, and potentially other passengers, could share information about lost items.
Or maybe not …
I thought of this when I saw this tweet earlier from Jeni’s Ice Creams here in Columbus …
> Just found a wallet in front of the Grandview Ave shop… Maybe RT so we can get it back to its rightful owner. Thanks! \[[jenisicecream](https://twitter.com/jenisicecreams?ref=lorcandempsey.net)\]
Nice gesture. Nice use of Twitter. I hope it works.
### Searching
URL: https://www.lorcandempsey.net/searching/
Last updated: 2020-10-28T09:14:55.000Z
I got a note from Debbie Campbell, Director, Collaborative Services, at the National Library of Australia the other week about their new [prototype discovery service](https://sbdsproto.nla.gov.au/?ref=lorcandempsey.net).
> The service is available at [https://sbdsproto.nla.gov.au/](https://sbdsproto.nla.gov.au/?ref=lorcandempsey.net) and provides integrated access to over 42 million metadata and text resources from a range of the National Library’s collaborative services and from elsewhere. For this initial version there are a range of data sources including: the [Australian National Bibliographic Database](https://librariesaustralia.nla.gov.au/?ref=lorcandempsey.net), [Australian Newspapers](https://ndpbeta.nla.gov.au/?ref=lorcandempsey.net), [Picture Australia](https://www.pictureaustralia.org/?ref=lorcandempsey.net), the
> [ARROW Discovery Service](https://search.arrow.edu.au/?ref=lorcandempsey.net), [Pandora](https://pandora.nla.gov.au/?ref=lorcandempsey.net). The new service will also provide the discovery interface for the People Australia initiative. Additionally we have included some external sources of data such as OAIster, Open Library, the Hathi Trust, the Internet Archive and the Library of Congress tables of contents, publishers’ descriptions and sample book chapters.
> In leveraging off the collaborative approach the National Library takes with its discovery services, and in integrating results from across collections and formats, this new service will have distinct benefits for users. For example a researcher searching for images relating to “[George Woodroffe Goyder](https://sbdsproto.nla.gov.au/sbdp-ui/result?q=George+Woodroffe+Goyder&ref=lorcandempsey.net)” will also be presented with results relating to people, book, manuscript, map and newspaper results. This new approach presents major benefits to the researcher who, in the past, would have had to visit each discovery service in turn and conduct separate searches for the material they sought.
There is further information in the [about](https://sbdsproto.nla.gov.au/sbdp-ui/general/about?ref=lorcandempsey.net) pages.
[](https://sbdsproto.nla.gov.au/sbdp-ui/result?q=patrick+white&ref=lorcandempsey.net)
I looked at the service and thought I would do a blog in a day or two. Suddenly then though there was a flurry of admiring comment, not least from my colleage Roy Tennant who reported …
> “We will now be going all out,” Warwick Cathro of the NLA reported in an email to me this week, “to get additional content for this service such as (a) high level collection guides and finding aids from libraries and archives (b) oral history summaries and transcripts (c) metadata describing datasets, especially Australian social science data held by government or research data archives).” \[[One-stop searching with a can-do attitute](https://www.libraryjournal.com/blog/1090000309/post/1900044990.html?ref=lorcandempsey.net)\]
[](https://sbdsproto.nla.gov.au/sbdp-ui/result?q=patrick+white&ref=lorcandempsey.net)
This service brings together many individually innovative services to give a unified experience. I hope that NLA tracks how people use this service and what they think of it and let us know what they find out.
### A single business system environment redux
URL: https://www.lorcandempsey.net/a-single-business-system-environment-redux/
Last updated: 2020-10-28T09:14:57.000Z
The new [prototype discovery service](https://sbdsproto.nla.gov.au/?ref=lorcandempsey.net) from the National Library of Australia caused a ripple of interest the other week when it was released. One reason for the interest is that it brings together access to a range of NLA resources (Picture Australia, Libraries Australia, and Pandora, among others) as well as to external resources (Oaister, for example). The rationale for this approach was outlined in an NLA report from two years ago. I will do an entry about the new service, but in the interim here is what I wrote about the report which argued for bringing the systems together in this way …..
The National Library of Australia has made an interesting report available, *National Library of Australia IT Architecture Project Report, March 2007*. \[[pdf](https://www.nla.gov.au/dsp/documents/itag.pdf?ref=lorcandempsey.net)\] Here is the declared purpose:
> The aim of this report is to define the IT architecture that will be needed to support the management, discovery and delivery of the National Library of Australia’s collections over the next three years. The current architecture has allowed the library to develop a significant digital library capability over the last decade. Now the burden of maintaining and supporting existing systems and services is increasingly hindering us from bringing new services online, improving the user experience, exploring new ideas or responding to technological change. In the meantime, enormous changes are occurring in the broader environment.
The report identifies three major responses within the context of a new framework for digital library services (I talk about them in a different order than the one in which they are presented). **One**, it recommends a move to a service-oriented architecture. The grounds for this are clear, and clearly made in the report. They include the ability to share common services across applications, to be able to respond to change effectively, and to reduce over time the redundancy, cost and complexity of development.
**Two**, it argues for using open source solutions where they are ‘functional and robust’. It notes an amendment to prior policy which favored a *buy* over a *build* policy. The Library will now consider open source solutions based on function and cost comparisons. The assessment of cost will not only include consideration of the direct costs of additional development but also the benefits of contributing code to the community and, interestingly, the opportunity costs of using commercial software whose development path is not aligned with library direction and need. The report notes the possibility of collaboratively sourcing some functionality with partners.
And **three**, the report talks about a ‘single business’ approach. This was the most interesting aspect of the document to me, because it underscores a major issue for libraries and the systems they deploy. This is that applications have developed in a piecemeal fashion over recent years, so that library operations are now supported by many applications, in different stages of maturity, and with different levels of process standardization. However, this ensemble of applications does not support efficient working across the range of library requirements, and inhibits flexible service development. Indeed, boundaries between these applications seem increasingly arbitrary, and to owe more to historic circumstance, and to the structure of the industry that has developed over time, than to current needs. Simply managing this diversity is a major task in itself. The ERAMS (electronic resource access and management services) discussion I [mentioned](https://blog.oclc.org/lorcand/archives/001250.html?ref=lorcandempsey.net) a while ago is one symptom of a growing sense that the library systems landscape needs to be redefined.
The ‘single business’ approach is a recommendation that the library think in terms of a single ‘business’ and a single data corpus as part of its planning process, rather than in terms of separate planning for each service line or resource type (e.g. images, books, music). And that technical solutions be designed in ways that minimize the number of separate business applications that need to be developed. Of course, the service-oriented approach would facilitate the latter goal. In practice this would mean trying to streamline workflow across management environments for different resource types; using common delivery, rights management and other solutions; and developing a single integrated discovery environment across collections and resource types, which can be accessed through different views.
The report is well structured, and is worth reading as much as for its discussion of some general issues as it is for the particular National Library of Australia situation. .
\[[Original post](https://blog.oclc.org/lorcand/archives/001307.html?ref=lorcandempsey.net)\]
### Weekend reading
URL: https://www.lorcandempsey.net/weekend-reading/
Last updated: 2020-10-28T09:14:59.000Z
I am pleased to note two recently released RLG Partnership reports.
- Schaffner, Jennifer. *The Metadata is the Interface: Better Description for Better Discovery of Archives and Special Collections* ([.pdf: 190K/17 pp](https://www.oclc.org/programs/publications/reports/2009-06.pdf?ref=lorcandempsey.net).)
- Smith-Yoshimura, Karen. *Networking Names* ([.pdf: 135K/25 pp.](https://www.oclc.org/programs/publications/reports/2009-05.pdf?ref=lorcandempsey.net))
### Scientific data sets
URL: https://www.lorcandempsey.net/scientific-data-sets/
Last updated: 2020-10-28T09:15:01.000Z
As attention to research data management and re-use grows I was interested to see the [Gateway to Scientific Data](https://cisti-icist.nrc-cnrc.gc.ca/eng/services/cisti/gateway-scientific-data.html?ref=lorcandempsey.net) provided by CISTI at the National Research Council Canada.
> Access to data from scientific research is increasingly important to collaborative research. This section aims to improve access to scientific research data for Canadians and support the use and re-use of data sets by providing a central gateway, as well as resources to guide data management activities. \[[NRC-CISTI Gateway to Scientific Data](https://cisti-icist.nrc-cnrc.gc.ca/eng/services/cisti/gateway-scientific-data.html?ref=lorcandempsey.net)\]
### Three sentences
URL: https://www.lorcandempsey.net/three-sentences/
Last updated: 2020-10-28T09:15:04.000Z
I just spent a very congenial couple of days in Champaign, Illinois, at the [Summer Institute for Humanities Data Curation](https://cirss.lis.uiuc.edu/CollMeta/dcep/SummerInstituteHumanities.htm?ref=lorcandempsey.net). Here are some memorable sentences …
Karen Wickett shared a very nice Rule in discussion: “I like to do favors for my future self”.
I used this sentence of [Geoff Bilder](https://network.nature.com/people/mfenner/blog/2009/02/17/interview-with-geoffrey-bilder?ref=lorcandempsey.net)‘s in my presentation: “For every distributed service created, we’ve then had to create a centralized service to make it useable again”.
And spotted on a coffee shop T-shirt: “we don’t do tall”.
### QOTD: libraries and museums
URL: https://www.lorcandempsey.net/qotd-libraries-and-museums/
Last updated: 2020-10-28T09:15:07.000Z
[CILIP](https://www.cilip.org.uk/?ref=lorcandempsey.net) is the UK professional organization for library (and other information) workers. I was interested to read the passage below in a recent submission it made to a parliamentary group looking at public libraries in England. It is referring to [MLA](https://mla.gov.org.uk/?ref=lorcandempsey.net), the Museums, Libraries and Archives Council, a government sponsored body which exists to promote good practice in those domains.
> It could be argued that the establishment \[…\] yoked public libraries into an arbitrary relationship with museums and galleries which is proving counterproductive in terms of the other relationships which public libraries in England need to establish at national level – with learning, with health, with communities, with public libraries in other parts of the UK, with the other parts of the library and information sector. \[All-Party Parliamentary Group on Libraries, Literacy and Information Management: Inquiry into the Governance and Leadership of the Public Library Service in England The Submission of Evidence by the Chartered Institute of Library & Information Professionals [PDF](https://www.cilip.org.uk/NR/rdonlyres/A21CBC59-5518-4982-B14F-B1E13CE6A461/0/APPGInquiryevidence0409.pdf?ref=lorcandempsey.net)\]
The weak opening qualification – “it could be argued” – aside, this is an interesting, and unusually emphatic, position for a library organization to take.
Incidentally, I wonder does the lack of reference to archives here signify anything.
### Reputation enhancement
URL: https://www.lorcandempsey.net/reputation-enhancement/
Last updated: 2020-10-28T09:15:09.000Z
I was interested to see the combination of services presented on the [Research and Enterprise](https://www2.lse.ac.uk/researchAndExpertise/home.aspx?ref=lorcandempsey.net) pages of the London School of Economics.
These include:
- [The LSE experts directory](https://www2.lse.ac.uk/researchAndExpertise/Experts/Home.aspx?ref=lorcandempsey.net)
- [LSE Research Online](https://www2.lse.ac.uk/researchAndExpertise/Experts/Home.aspx?ref=lorcandempsey.net) (the institutional repository)
Links to corporate relations, commercialization activites, and to podcasts, videos and other public outputs.
I was especially interested in the Motivating headline on the Experts database [page](https://www2.lse.ac.uk/researchAndExpertise/Experts/Home.aspx?ref=lorcandempsey.net): Be seen. Be heard. Be cited.
I expect we will see more of this type of convergence as universities look at more organized and integrated disclosure of their research and expertise capacities on the web. This is especially topical in an environment of growing ranking and assessment.
Library roles here are one of the issues which have come up in our [Research Information Management](https://www.oclc.org/programs/ourwork/researchinfo/default.htm?ref=lorcandempsey.net) strand of work.
### Web 2.0 and air freshener
URL: https://www.lorcandempsey.net/web-20-and-air-freshener/
Last updated: 2020-10-28T09:15:11.000Z
Web 2.0 is often talked about in terms reminiscent of an advert for air freshener: spray it on and there will be a major improvement in the quality of life, or at least of your service.
Add tags or an RSS feed and you will be future-ready. You will smell of roses.
Now, of course, this is partly because Web 2.0 is used in different ways. And, yes, there are indeed many places where such features will be helpful.
Influenced by Tim O’Reilly’s various commentaries, I have [spoken](https://blog.oclc.org/lorcand/archives/001556.html?ref=lorcandempsey.net) about Web 2.0 in terms of concentration and diffusion. It has not just been about features, it has been about reconfiguration of organizations and services in a network environment (think of the impact of Amazon or Wikipedia, for example).
In this context, I was interested in Andy Powell’s comments on two recent UK discussions about Web 2.0, one about appropriate responses by CILIP, the professional organization, and one about a recent [report](https://ukwebfocus.wordpress.com/2009/05/12/higher-education-in-a-web-2-0-world-report-published/?ref=lorcandempsey.net) on Web 2.0 and university education. The post is in part a response to Brian Kelly. Brian has a [useful overview](https://ukwebfocus.wordpress.com/2009/04/30/cilip-more-popular-than-swine-flu/?ref=lorcandempsey.net) of the CILIP discussion.
In each case, the conversations seem to underemphasise the systemwide reconfiguring aspect of the network, and emphasize change in terms of adding communication or social networking features to existing structures. How will those structures themselves change in a network world?
> Or, to put it a different way, if Web 2.0 changes everything, I see no reason why that doesn’t apply as much to professional bodies and universities as it does to high street bookshops. \[[The role of universities in a Web 2.0 world](https://efoundations.typepad.com/efoundations/2009/05/the-role-of-universities-in-a-web-20-world.html?ref=lorcandempsey.net)\]
### The library of the future ...
URL: https://www.lorcandempsey.net/the-library-of-the-future/
Last updated: 2020-10-28T09:15:15.000Z
A recurrent theme of this blog has been that networking changes the way we think about organizational boundaries. That said, there is generally not very much discussion of this issue in libraries, where the focus tends to be on individual services or applications, or on changing user behaviors. For this reason, I was interested to read [Mark Dahl’s presentation](https://synthesize-specialize-mobilize.blogspot.com/2009/04/gathering-storm.html?ref=lorcandempsey.net) on cloud computing and libraries (full disclosure: I and OCLC get hat-tips).
Think of the more general case. We have seen a major shift to webscale which has reconfigured whole industries as well as individual organizations. Some obvious examples are the influence of Expedia/Orbitz/Travelocity on travel, Amazon on retail, Netflix on movie distribution, and the Web generally on newspapers and TV. Discovery is now largely a webscale activity.
At the same time the web has accelerated the vertical disintegration of firms and the sourcing of capacity with specialist providers. Think historically of payroll, or more recently of customer relationship management and SalesForce.com. A wide range of capacities may be sourced externally: think of anything from data centers, to the provision and care of plants, to education and counselling services. Companies make decisions about what their distinctive capacities are, and externalise other capacities to networks of providers and partners. And, in fact, effective supply chain management has become an important competitive factor.
These types of questions are becoming more important for libraries, even if they don’t pose them in quite these terms. And they are not especially new. Historically, for example, think of two major shifts: shared cataloging/resource sharing and the move to licensed access to A&I databases and e-journals. In the former case, activity was externalised to consortial activity or to national-scale organizations, and today many organizations provide such services around the world, including OCLC. In the latter case, libraries gave up the institution-scale management of the A&I and journal resources they had collected in print form. They externalized this activity to, often commercial, third parties.
What Dahl does in this presentation is to look at the future of the library in the context of the reconfiguring potential of network services. He talks in general terms and then offers specific examples. He suggests that the library may become smaller, may shift to new service areas, and may become more creative in the work it does. What I especially like about it is that he acknowledges that organizational change is an appropriate response and then works through what this might mean in practice.
### Dura-sell
URL: https://www.lorcandempsey.net/dura-sell/
Last updated: 2020-10-28T09:15:18.000Z
The organizational coalescence of Dspace and Fedora, [announced yesterday](https://www.duraspace.org/pressrelease.html?ref=lorcandempsey.net), is welcome and not too surprising. This arrangement concentrates the resources of two organizations with similar missions and should strengthen their joint ability to secure future resources and to improve their products and services. The new organization is to be called [Duraspace](https://www.duraspace.org/index.html?ref=lorcandempsey.net). The press release suggests that Fedora and Dspace software products will continue to exist independently, although presumably one might expect to see greater sharing of approaches between them.
The press release highlighted DuraCloud …
> Currently, the organization is developing DuraCloud, a new web-based service that will enable content replication to a network of cloud-based storage services, and provide an environment for running access and preservation services within the cloud. \[[DuraSpace Faq](https://duraspace.org/faq.html?ref=lorcandempsey.net)\]
The idea here appears to be to provide convenient and mediated replication services for Dspace and Fedora users (and maybe others?). Other services might also be part of the mix and one can imagine a variety of those (format validation/migration, automatic classification, etc). (See the [comment](https://timesync.gmu.edu/wordpress/?p=904&ref=lorcandempsey.net) by Michele Kimpton from earlier this year \[1\]).
The continued trajectory of this organization will be interesting to watch. The transition from research-led, sponsor- and grant-funded activity to demand-led, revenue-generating activity is not straightforward, especially if one wants to preserve something of the ethos and impulses of the originating organisations.
It will also be interesting to see what actual revenue-generation potential DuraCloud has. The offer potentially simplifies the use of various cloud based services by hiding the multiple negotiation and other transaction costs behind a single service. How valuable is such a service to institutions? Given the early stages of academic cloud services, DuraCloud may have to create awareness about the model and its potential advantages as part of building the business.
A major question, presumably, will be to what extent there is sufficient volume of particular classes of data to make offering the service, and value-added services, ‘routinizable’. Where data requires custom attention, or where the costs of providing particular services on it cannot be shared across a large number of customers, then the rationale for the service diminishes.
Anyway, congratulations to the leadership of the two organizations for taking this step and good luck with this new venture.
\[1\] Note: Confusingly, DuraSpace seems to have started out as the name for what became DuraCloud.
### QOTD: studio work
URL: https://www.lorcandempsey.net/qotd-studio-work/
Last updated: 2020-10-28T09:15:20.000Z
The NYT describes James Patterson’s work practice …
> … an author who so towers over the best-seller lists that a couple of years ago he estimated that he earned royalties on one out of every 15 hardcover books published in this country. In fact, Mr. Patterson now publishes so many best sellers, in so many different genres, that he can’t possibly write them all. So he farms many of his books out to a factory, or an atelier, if you like: a team of co-authors who work from Patterson-supplied outlines and stick closely to the no-frills Patterson formula: short chapters, short paragraphs, short sentences, short words. \[[NYT – Peter de Jonge](https://www.nytimes.com/2009/05/05/books/05dejo.html?ref=lorcandempsey.net)\]
Here is James Patterson’s [Worldcat Identity](https://www.worldcat.org/identities/lccn-n78-86409?ref=lorcandempsey.net) which shows climbing interest, and here is a mention in Thom’s [nice post](https://outgoing.typepad.com/outgoing/2009/02/popular-authors.html?ref=lorcandempsey.net) about the UK Public Lending Right which showed Patterson as the most borrowed author in UK public libraries (read the last para ;-).
### Earth works
URL: https://www.lorcandempsey.net/earth-works/
Last updated: 2020-10-28T09:15:22.000Z
One of the most interesting things we have seen while in the US is the Serpent Mound in southern Ohio, reputedly the largest effigy earthworks in the world.
> Atop a plateau overlooking the Brush Creek Valley, Serpent Mound is the largest and finest serpent effigy in the United States. Nearly a quarter of a mile long, Serpent Mound apparently represents an uncoiling serpent. \[[OHS – Places – Serpent mound](https://ohsweb.ohiohistory.org/places/sw16/index.shtml?ref=lorcandempsey.net)\]
We have also enjoyed visiting the Newark Earthworks, East of Columbus.
> The Great Circle is one part of the Newark Earthworks State Memorial, the largest system of connected geometric earthworks built anywhere in the world. Octagon Earthworks and Wright Earthworks are both additional local sites that preserve other features of this majestic remnant of prehistoric Ohio. \[OHS – Places – Newark Earthworks\]
It is hard to convey the impression these earthworks make, massive fabricated parts of the landscape.
The Serpent Mound was mentioned in yesterday’s New York Times. The context was an article about the Storm King Wavefield, a permananent landscape sculpture by artist and architect Maya Lin, perhaps still best known for the Vietnam Veterans Memorial in Washington, D.C.
> Born in 1959, Ms. Lin was raised in rural Ohio, and as a child visited the great Serpent Mound and other American Indian earthworks in the Midwest. \[[NYT – Art review – Storm King Wavefield](https://www.nytimes.com/2009/05/08/arts/design/08lin.html?%5Fr=1&pagewanted=2&ref=lorcandempsey.net)\]
Here is what the NYT says about the work …
> But the piece is already a classic. It has the gravity of Ms. Lin’s commemorative sculptures and the sociability of the earlier “wave” pieces, which lent themselves to picnics, play and privacy. And, more immediately than almost any of her other outdoor projects, it is inextricable from nature, which is where, as I say, all her art starts. \[[NYT – Art review – Storm King Wavefield](https://www.nytimes.com/2009/05/08/arts/design/08lin.html?%5Fr=1&pagewanted=2&ref=lorcandempsey.net)\]
Check out the [slideshow](https://www.nytimes.com/slideshow/2009/05/08/arts/20090508%5FMAYALIN%5FSLIDESHOW%5F5.html?ref=lorcandempsey.net) and [video](https://www.google.com/url?sa=t&source=web&oi=video%5Fresult&ct=res&cd=1&url=http%3A%2F%2Fvideo.nytimes.com%2Fvideo%2F2008%2F11%2F07%2Farts%2Fdesign%2F1194832296918%2Fmaya-lin-s-wave-field.html&ei=I6YFSoXLNZeuNdjj0KID&usg=AFQjCNGlX3T5U4TEAp-U02yhF0sovRuE3Q&sig2=r3wUTppK2Y4uf2Srku6VbQ) showing the Storm King Wavefield and other work by Maya Lin.
We will have to make a trip …
### QOTD: measuring web audiences
URL: https://www.lorcandempsey.net/qotd-measuring-web-audiences/
Last updated: 2020-10-28T09:15:24.000Z
From an article in the MIT Technology Review …
> …. confusion about the size of web audiences is universal.
> No one really knows how many people visit websites. No established third-party supplier of audience measurement data is trusted. Internal Web logs exaggerate audiences. This matters to more people than investors, like McNamee, who worry that they have no way to evaluate new-media businesses. The issues involved are technical, and occluded by ugly jargon, but they concern anyone anxious about the future of media as print and broadcast television and radio shrink in importance. \[[But who’s counting](https://www.technologyreview.com/business/22122/?ref=lorcandempsey.net)\]
The article contends that the absence of a reliable and agreed measure of web audience means that there are no authoritative third party measuring services which in turn is impeding the development of online advertising.
It also profiles Quantcast, a company which is trying to fill that gap. I look at Quantcast occasionally. I find its listing of other sites interesting, other sites liked and other sites linked: the list for the BBC is given here. (Caveat: I have not looked into how Quantcast assembles this data and note it here just for interest.)
[](https://www.quantcast.com/bbc.co.uk?ref=lorcandempsey.net)[](https://www.quantcast.com/bbc.co.uk?ref=lorcandempsey.net)
### Blogging
URL: https://www.lorcandempsey.net/blogging-2/
Last updated: 2020-10-28T09:15:26.000Z
I seem to spend less time looking at blogs, library or otherwise. I don’t know if this is just me or if it is a general experience. The demands of work, life and Twitter perhaps. No doubt Walt will [inform](https://www.lulu.com/content/paperback-book/the-liblog-landscape-2007-2008/4898086?ref=lorcandempsey.net) us in due course whether the volume of library blogging, at least, is up or down, whatever about the quality or interest.
However, as soon as I say that I realise that it is probably not true. I do look at quite a lot of things that are sort of quasi-blogs/quasi-news (e.g on Cnet) which I do not tend to think of as blogs because they do not have a strong personal voice. I occasionally look at some other things which are clearly ‘blogs’, if in some managed space. The [blogs at HarvardBusiness.org](https://blogs.harvardbusiness.org/?ref=lorcandempsey.net) are an example, and they seem a bit flat, as if produced to order.
In this context, I was quite interested to read the [job advert](https://jobs.bbc.co.uk/fe/tpl%5Fbbc01.asp?newms=jj&id=27386&aid=15716&ref=lorcandempsey.net) for the editor of the BBC Internet Blog.
> The BBC internet blog is the key audience facing accountability blog for senior staff in the BBC’s online and technology teams (e.g. BBC Online, BBC iPlayer, Future Media & Technology, Online Media Group, A&Mi, Vision Multi-platform). It aims to showcase the work of these teams and to respond to live issues in the blogosphere and elsewhere on what the BBC does in technology and online.
> The blog is a fast moving editorial proposition which aims to publish a blog post every day. \[[BBC – Jobs – Job Details](https://jobs.bbc.co.uk/fe/tpl%5Fbbc01.asp?newms=jj&id=27386&aid=15716&ref=lorcandempsey.net)\]
This prompts me to think that perhaps the word blog has become overburdened and as a result somewhat fuzzy in use. Sometimes we use it for the mechanics, for a mode of delivery which has become a useful and general web publishing medium: a stream of messages which are individually commentable, addressible, and signed, which can be subscribed to as a stream and which can be aggregated and mixed in various ways. Other times we may mean this, but we are principally thinking of the personal voice that comes through …
So, I probably spend as much or more time looking at blogs in that mechanical sense. But I probably spend less time listening to individual, idiosyncratic voices …
### Entrepreneurial skills are not given out with grant letters
URL: https://www.lorcandempsey.net/entrepreneurial-skills-are-not-given-out-with-grant-letters/
Last updated: 2020-10-28T09:15:27.000Z
Ithaka produced a report last year – *Sustainability and revenue models for online academic resources* [PDF](https://sca.jiscinvolve.org/files/2008/06/sca%5Fithaka%5Fsustainability%5Freport-final.pdf?ref=lorcandempsey.net) – for the Strategic Content Alliance (SCA), a UK collaboration of cultural and educational organizations. They followed up with a series of [case studies](https://sca.jiscinvolve.org/publications/?ref=lorcandempsey.net) (scroll down the list of SCA publications to the sustainability section) which were discussed at a recent SCA workshop, for which the materials are also [available](https://sca.jiscinvolve.org/2009/04/07/workshop-notes-case-studies-in-sustainability/?ref=lorcandempsey.net). More complete materials will appear in June.
The context for this work is the large cumulative investment by various funding agencies in making academically relevant content available on the web through grants to projects in the education, cultural and related areas. How does one create the circumstances in which effective ongoing management and use of such materials is secured?
I have not digested the case study material and will look at the final materials with interest when they appear. This is likely to be useful work, given the experience and contacts of the authors.
In the interim, here is a brief note on last year’s report. I was drawn to this telling paragraph in the summary:
> Acting as the principal investigator of a research grant project is a very different responsibility from operating as the organisational leader of a sustainable enterprise. The issue of ‘impact’ is just one example. In our opinion, delivering impact is the key factor in the potential for achieving long-term sustainability; only high impact and highly useful materials will draw the financial support from beneficiaries needed for long-term success. Yet the importance of impact is often underestimated by leaders of not-for-profit digital resource projects. Much attention is given to making material available and very little attention is given to doing the work to make sure that people will become aware of it, that they can find it, and if they do find it that they will actually use it. We find that few digital resource projects have devoted substantial financial or intellectual resources to understanding user needs, preferences and behaviours. Nor, often, have they invested in understanding the environment of other resources that compete for those users’ attention and support. The absence of focused effort on use, impact, and competition among these types of projects has deep implications for their potential long-term success. \[Sustainability and revenue models for online academic resources: an Ithaka report [PDF](https://sca.jiscinvolve.org/files/2008/06/sca%5Fithaka%5Fsustainability%5Freport-final.pdf?ref=lorcandempsey.net)\]
I was struck by three further issues. First was the discussion of scale. Funded projects cannot generate the economies of scale that larger enterprises exhibit. “Scale” the authors suggest “is required to support the technology platform and the staff to manage that infrastrucutre, as well as staff for tasks such as user support, marketing, and fundraising.” They argue that it is a “kind of paradox” that publishing a single item on the web may “cost next to nothing”, but that “publishing aggregated content in an effective and sustainable way favours massive scale”.
Second was the contention that much project work is supply-driven rather than demand-driven. Project leaders, they suggest, tend to focus on the inherent values of their work rather than on what might be of most importance to their intended users. Examples of such values are: “the quality or uniqueness of the content, the novelty of their approach, the elegance of their technology, or the degree to which it satisfies their own research needs”.
Third was the acknowledgement that projects may not naturally think of ‘value’ in business or commercial terms, and indeed there may sometimes be an antipathy to commercial enterprise. (This is not the only measure of ‘value’.)
The larger part of the report is a description of various revenue models.
As noted above, this is the first part in an ongoing programme of work. In some ways, the detail of the case studies and lessons drawn from those will be of more interest. However, I think that the arguments in this report are interesting and important. In some ways, they are more important for the funding agencies than for they individual projects. The current project based approach, in which each project stands on its own, may have been appropriate for an earlier phase where local experiment was apt. As a general development approach it is limited – as I have argued elsewhere:
> But project-based funding is not the way to go to introduce much of the systemic change that is now again required. Projects tend to be institutional or consortial: it is difficult for these to operate at the level of the system. Of course, their results may be transferable, but this does not always happen. And it does not happen for good reason: a project will develop its own requirements and deliverables, which may not transfer easily into a production environment somewhere else. There is often a large gap between a project output and a ‘product’ in the sense that something is ready to meet broader objectives. Projects may not produce portable solutions. Widescale project working also has another interesting dynamic. It disperses rather than concentrates expertise, and given that expertise is a finite resource it means that many individual projects may achieve less than fewer larger ones would. There is also an opportunity cost, as expertise is devoted to projects, and it may be difficult to align project goals and institutional needs. Of course, this is to state the extreme case: there may be some institutional benefit.
> The absence of systemic attention, the dispersal of expertise, and the lack of a ‘product’ focus can be seen as issues in several recent programmes. Think of the range of digitisation projects in recent years in the UK \[34\]. This is not to say that there should not be support for R&D. Or that we should not find ways to reward and sustain creativity and innovation. Clearly we should. But we should realise what a programme of projects can produce. This should not be confused with designing, building and sustaining the library services that will effectively support research and learning into the future. \[[The (Digital) Library Environment: Ten Years After](https://www.ariadne.ac.uk/issue46/dempsey/?ref=lorcandempsey.net)\]
It would be good if this work led to some serious thinking about how to structure such programmatic investment so that its impact is maximized. Asking individual projects to measure outcomes or think about sustainability is only part of the issue.
May 4: slight edits for style and emphasis.
### Tweet, tweet, tweet, tweet .....
URL: https://www.lorcandempsey.net/tweet-tweet-tweet-tweet/
Last updated: 2020-10-28T09:15:29.000Z
I have just got the latest issue of one of my favorite publications, the [*London Review of Books*](https://www.lrb.co.uk/?ref=lorcandempsey.net), which has an article by one of my favorite critics, [Frank Kermode](https://worldcat.org/identities/lccn-n80-126228?ref=lorcandempsey.net), on one of my favorite writers, [Jane Austen](https://worldcat.org/identities/lccn-n79-32879?ref=lorcandempsey.net).
I paused over the following sentence and admired how he kept it going right to the end 😉
> There is a question that is bound to exercise in different ways readers who rejoice that the critical fortunes of Jane Austen show no signs of failing, and those who wonder how it can be that these tales of idle ladies and gentlemen, their interests fixed on money, their language elegantly out of date, should not only be the adored subject of an enthusiastic cult, but can elicit the acclaim of scholars who count her among the greatest novelists in the language. \[[Too good and too silly](https://www.lrb.co.uk/v31/n08/kerm01%5F.html?ref=lorcandempsey.net) – behind pay wall\]
With spaces, this is approximately 465 characters. This single sentence would require four tweets to communicate 😉
### Metasearch redux
URL: https://www.lorcandempsey.net/metasearch-redux/
Last updated: 2020-10-28T09:15:31.000Z
Here is something I said about metasearch in these pages some time ago ….
> The issue is that libraries have to manage a range of database resources whose legacy technical and business boundaries do not very well map user preferences or behaviors. The approach has been to try to move away from presenting a fragmentary straggle of databases to bundling them in various ways in a metasearch application, sometimes in one big search, sometimes in smaller course or subject bundles. The issues here are well-known, not least of which is that libraries typically have limited control over the performance of the target databases. \[[Lorcan Dempsey’s weblog](https://blog.oclc.org/lorcand/archives/001528.html?ref=lorcandempsey.net)\]
And elsewhere ….
> It is for this reason that I [wondered a while ago](https://blog.oclc.org/lorcand/archives/000615.html?ref=lorcandempsey.net) if it might make more sense to attack the boundary issue differently, by working on business and technical approaches which would result in fewer, larger resources to search. This would reduce the complexity of boundary spanning by pushing data integration and other issues upstream. At the cost of putting more burden on the search system to make discriminations that have been lost. It does also raise the question of how much difference is useful. \[[Lorcan Dempsey’s weblog](https://blog.oclc.org/lorcand/archives/000768.html?ref=lorcandempsey.net)\]
It has been interesting to see the trend towards the type of consolidation I discuss above continue, consolidation of metadata and of metadata and full-text.
My sense is that Google Scholar accelerated this development, even if the level of Google’s ongoing investment and interest is not clear.
Emerging service examples are [Summon](https://www.serialssolutions.com/summon/?ref=lorcandempsey.net) from Serials Solutions and the [Ebsco Discovery Service](https://www.google.com/url?sa=t&source=web&ct=res&cd=2&url=http%3A%2F%2Fwww.ebscohost.com%2FthisTopic.php%3FmarketID%3D1%26topicID%3D1245&ei=hbP3Sc-8FpuqMvDewbgP&usg=AFQjCNEZsa4dQopX0W0AW46cssPloiU0pA). And I should mention that OCLC continues to add data sources to Worldcat.org as part of its [goal](https://www.oclc.org/us/en/news/releases/200916.htm?ref=lorcandempsey.net) of being able to fully represent library collections.
### Books in the humanities
URL: https://www.lorcandempsey.net/books-in-the-humanities/
Last updated: 2020-10-28T09:15:33.000Z
In the context of recent discussion of monograph publishing in the humanities I was interested to read this recommendation in Marc Taylor’s NYT op-ed this morning. It is a critique of graduate education …..
> 4\. Transform the traditional dissertation. In the arts and humanities, where looming cutbacks will be most devastating, there is no longer a market for books modeled on the medieval dissertation, with more footnotes than text. As financial pressures on university presses continue to mount, publication of dissertations, and with it scholarly certification, is almost impossible. (The average university press print run of a dissertation that has been converted into a book is less than 500, and sales are usually considerably lower.) For many years, I have taught undergraduate courses in which students do not write traditional papers but develop analytic treatments in formats from hypertext and Web sites to films and video games. Graduate students should likewise be encouraged to produce “theses” in alternative formats. \[NYT – Opinion – [End the university as we know it](https://www.nytimes.com/2009/04/27/opinion/27taylor.html?pagewanted=2&%5Fr=1&ref=lorcandempsey.net)\]
One of his concerns is over-specialization:
> And as departments fragment, research and publication become more and more about less and less. Each academic becomes the trustee not of a branch of the sciences, but of limited knowledge that all too often is irrelevant for genuinely important problems. A colleague recently boasted to me that his best student was doing his dissertation on how the medieval theologian Duns Scotus used citations. \[NYT – Opinion – [End the university as we know it](https://www.nytimes.com/2009/04/27/opinion/27taylor.html?%5Fr=1&ref=lorcandempsey.net)\]
That said, unburdened by any relevent knowledge 😉 I can imagine somebody feeling that that is a useful contribution …..?
Duns Scotus: [Worldcat identity](https://worldcat.org/identities/lccn-n50-66853?ref=lorcandempsey.net)
Marc C Taylor: [Worldcat identity](https://worldcat.org/identities/lccn-n80-82389?ref=lorcandempsey.net)
### QOTD: books: the last frontier for ads
URL: https://www.lorcandempsey.net/qotd-books-the-last-frontier-for-ads/
Last updated: 2020-10-28T09:15:39.000Z
Fintan O’Toole writes about the Google books settlement in the Irish Times. He wonders which ads will be shown to accompany which texts. My favorite is the third, the opening of Ulysses ….
> PICTURE THIS. You read “It is a truth universally acknowledged, that a single man in possession of a good fortune, must be in want of a wife”, and up pops an ad for a dating agency.
> You read “As Gregor Samsa awoke one morning from uneasy dreams he found himself transformed in his bed into a gigantic insect”, ads for Odearest mattresses and bug repellent swim before your eyes. You read “It was a bright cold day in April, and the clocks were striking thirteen” and a message from Omega urges you to buy a new watch.
> You read “Stately, plump Buck Mulligan came from the stairhead, bearing a bowl of lather on which a mirror and razor lay crossed” and you get Weight Watchers at the top of your screen and Gillette at the bottom. \[[D-Day approahes for Google’s assault on writers’ copyright](https://www.irishtimes.com/newspaper/weekend/2009/0425/1224245347234.html?ref=lorcandempsey.net)\]
Prompted by this note, I searched for “stately, plump Buck Mulligan” …..
[](https://books.google.com/books?q=stately+plump+buck+mulligan&btnG=Search+Books&ref=lorcandempsey.net)
The piece is a general one about the agreement, from an author’s perspective (O’Toole is a journalist and prolific [author](https://www.worldcat.org/identities/lccn-n87-138492?ref=lorcandempsey.net)). He argues that the web’s “assault on copyright” is less a blow for freedom than an attack on the ability of artists to “make decisions about the user of their work”.
I was taken by his note about ads and books, and his use of the last frontier phrase ….
> One of the last frontiers is, oddly, that quaintly old-fashioned thing, the book. Books usually advertise themselves and often discreetly plug other works from the same author and/or publisher. Readers see them, however, as private spaces and resist any attempt to invade that privacy. As books and reading move online, however, this last frontier is being comprehensively crossed. \[[D-Day approahes for Google’s assault on writers’ copyright](https://www.irishtimes.com/newspaper/weekend/2009/0425/1224245347234.html?ref=lorcandempsey.net)\]
Incidentally, the picture in the banner of this blog is of Dublin Bay, looking from south to north, close to the Martello Tower which was the setting for the Buck Mulligan scene above.
### Web scale library management services
URL: https://www.lorcandempsey.net/web-scale-library-management-services/
Last updated: 2020-10-28T09:15:41.000Z
OCLC has just released a press-release about its Web scale library management services. For some context see Andrew’s note:
> OCLC is extending the [WorldCat Local](https://www.oclc.org/us/en/worldcatlocal/default.htm?ref=lorcandempsey.net) platform to include circulation and delivery, print and electronic acquisitions, and license management components. A quick start version of WorldCat Local–available at no additional charge to FirstSearch WorldCat subscribers–is a first step to WorldCat Local and to a truly next-generation cooperative library management service. \[[And now for something completely different – Hectic Pace](https://community.oclc.org/hecticpace/archive/2009/04/and-now-for-something-complete.html?ref=lorcandempsey.net)\]
Further details and directions are available [here](https://www.oclc.org/productworks/webscale.htm?ref=lorcandempsey.net).
Through its cataloging and resource sharing services OCLC and its members have shown the value of shared network level activity. These new services extend that model to generate efficiencies across a wider range of library operations.
### Larkin, work and libraries
URL: https://www.lorcandempsey.net/larkin-work-and-libraries/
Last updated: 2020-10-28T09:15:43.000Z
Philip Larkin on being a librarian ….
> “I hate work. Libraries are a quite pleasant way of earning a living. Dismal prospects though! Jobs connected with books like publishing are not good for creative writing. That’s why libraries, all technical and administration, are so good.” \[[Larkin’s first interview John Shakespeare TLS](https://entertainment.timesonline.co.uk/tol/arts%5Fand%5Fentertainment/the%5Ftls/article6013896.ece?ref=lorcandempsey.net)\]
I have [written](https://blog.oclc.org/lorcand/archives/001546.html?ref=lorcandempsey.net) about Larkin and libraries before.
### Library and archives - visible
URL: https://www.lorcandempsey.net/library-and-archives-visible/
Last updated: 2020-10-28T09:15:45.000Z
[](https://www.ryman.com/HatchGallery.html?ref=lorcandempsey.net)We were in Nashville for a couple of days over the Easter period. Doing the tourist thing, we spent a couple of hours in the [Country music hall of fame and museum](https://www.countrymusichalloffame.com/site/?ref=lorcandempsey.net). I was very interested to see at the center of the building, though glass panels, the [Frist Library and Archive](https://www.countrymusichalloffame.com/site/explore-exhibits-detail.aspx?cid=&ref=lorcandempsey.net).
> The Frist Library and Archive represents more than 30 years’ worth of collecting country music books, periodicals, photographs, fan club newsletters, scrapbooks, sheet music, songbooks, video and film, oral histories and sound recordings. \[[Frist Library and Archive | Country Music Hall of Fame® and Museum | Nashville, Tennessee](https://www.countrymusichalloffame.com/site/explore-exhibits-detail.aspx?cid=235&ref=lorcandempsey.net)\]
Here is how the experience was described in a Serials Review article of 2005 \[1\]:
> Notice, though, that as you make your way around the exhibits, you find yourself separated only by a wide stretch of glass panels from the heart and guts of the museum–staff areas where sound recordings are transferred for preservation, artifacts are restored, and exhibits are prepared. As Chris Herrington, across the state at the *Memphis Flyer*, noted, this “\[gives\] the space the feel of a living museum.” \[2\] You’ll also see rows of compact shelving, occupied by holdings of the Frist Library and Archive. This is really where the heart is–the exhibition space is great, but behind the glass is country music’s Library of Congress. \[Behind a pay wall: [ScienceDirect – Serials Review : SR Visits the Country Music Hall of Fame and Museum in Nashville, Tennessee](https://www.sciencedirect.com/science?%5Fob=ArticleURL&%5Fudi=B6W63-4G6J896-1&%5Fuser=5335617&%5FcoverDate=06%2F30%2F2005&%5Frdoc=14&%5Ffmt=high&%5Forig=browse&%5Fsrch=doc-info%28%23toc%236587%232005%23999689997%23599677%23FLA%23display%23Volume%29&%5Fcdi=6587&%5Fsort=d&%5Fdocanchor=&%5Fct=22&%5Facct=C000066376&%5Fversion=1&%5FurlVersion=0&%5Fuserid=5335617&md5=ca3178e1dbe6727064d3c5debd739bd5&ref=lorcandempsey.net)\]
What I liked was that visitors to the museum could clearly see the shelves, boxes and equipment,the actual apparatus of managing materials. These were put at the center of the building, unobtrusive but clearly visible.
Incidentally, a highlight of the visit was the discovery of the [Hatch Show Print](https://www.countrymusichalloffame.com/site/experience-hatch.aspx?ref=lorcandempsey.net) letterpress posters. See this [selection of work](https://www.ryman.com/HatchGallery.html?ref=lorcandempsey.net) done for The Ryman.
Note: I know very little about country music and have only a tourist’s view of the library, supplemented by the account in the article.
\[1\] Peter Wilson and Katy Ginanni. “SR Visits the Country Music Hall of Fame and Museum in Nashville,Tennessee”. *Serials Review*. Volume 31, Issue 2, June 2005, Pages 159-163
\[2\] Chris Herrington, “Will the Circle Be Unbroken? Nashville Has a New Home for the Country Music Hall of Fame and Museum,” MemphisFlyer.com, June 22, 2001, https://memphisflyer.com/MFSearch/full\_results.asp?xt\_from=1&aID=1354
### E-journal impact ....
URL: https://www.lorcandempsey.net/e-journal-impact/
Last updated: 2020-10-28T09:15:47.000Z
The Research Information Network in the UK has released a report about the impact of e-journals …
> ‘E-journals: their use, value and impact’ takes an in-depth look at how researchers in the UK use electronic journals, the value they bring to universities and research institutions and the contribution they make to research productivity, quality and outcomes. \[[E-journals: their use, value and impact | RIN](https://www.rin.ac.uk/use-ejournals?ref=lorcandempsey.net)\]
The report is based on work by [CIBER](https://www.ucl.ac.uk/infostudies/research/ciber/?ref=lorcandempsey.net) at the University of London. They examine the use of ScienceDirect and Oxford Journals at ten research institutions across several selected subjects.
The report is rich, and I won’t try to summarize it here. It is worth reading in full. Some highlights for me were …
They characterize the scale of the UK e-journal market as follows …
- UK universities and colleges spent nearly £80 million licensing electronic journals
in 2006/07
- we estimate that university researchers and students downloaded almost 102 million articles during that period, and
- downloads cost, on average, 80 pence (excluding overheads, time and other indirect costs).
(I read this to mean that the average price of an article is of the same order as a song on itunes?)
Use of e-journals is growing. The authors claim that the sheer scale and intensity of use of e-journals is ‘mind-boggling’, and provide some numbers.
There is a familiar story about access through Google …
> Once journal content is opened up to Google for indexing, Google is then used by large numbers of even the most proficient and informed information seekers. Just four months after ScienceDirect content in physics was opened up to Google, more than a third of all traffic arrived via this route. This is particularly notable in a field richly endowed with online information resources.
> Google’s popularity is also shown in the case of Oxford Journals where Google has had access for some years: over half of their traffic comes via Google, especially in the case of ‘super-users’. \[[E-journals: their use, value and impact](https://www.rin.ac.uk/files/E-journals%5Fuse%5Fvalue%5Fimpact%5FApril2009.pdf?ref=lorcandempsey.net)\]
They note that few users use search and navigational features that are available on publisher sites.
One of the more interesting findings is the reported difference between researcher behavior at different types of university. They note heavier use at research intensive universities, in part because they have more researchers. The heaviest users also have the shortest sessions, which they suggest appears to be related to the use of intermediate ‘gateway’ sites (Google, PubMed, ..). And thirdly, they report that researchers in less research-intensive universities use more site features (such as advanced search), something which may need more work to explain.
They note some correlations which are intriguing but which also require more work to find out what is going on. They note a positive correlation between the number of e-journal pages viewed at an institution and the number of articles published at that institution. They also note a strong negative correlation between the research rating of life scientists in each institution and the length of their sessions in ScienceDirect.
Importantly, they move to what they call an ‘intriguing’ conclusion: “patterns of e-journal use at UK universities appear to line up very closely both with spending and with selected research outcomes.”
They promise further work. And a question that might be on the mind of many librarian readers might be “does better library provision improve research outcomes?”
There is much more in the report, and various supporting materials are included.
### QOTD: library catalogs and users
URL: https://www.lorcandempsey.net/qotd-library-catalogs-and-users/
Last updated: 2020-10-28T09:15:48.000Z
Karen Calhoun and other colleagues have produced a report on catalog data from user and library points of view.
> The findings suggest two traditions of information organization at work–one from librarianship and the other from the Web. Librarians’ perspectives about data quality remain highly influenced by their profession’s classical principles of information organization, while end users’ expectations of data quality arise largely from their experiences of how information is organized on popular Web sites. What is needed now is to integrate the best of both worlds in new, expanded definitions of what “quality” means in library online catalogs. \[[Online catalogs: what users and librarians want](https://www.oclc.org/us/en/reports/onlinecatalogs/fullreport.pdf?ref=lorcandempsey.net)\]
### Articles on structured data: matching, mining and mixing
URL: https://www.lorcandempsey.net/articles-on-structured-data-matching-mining-and-mixing/
Last updated: 2020-10-28T09:15:51.000Z
The current issue of Library Resources and Technical Services (not on the web) has a couple of interesting articles which touch on the complications of processing inconsistent data.
Creating organization name authority within an ERM system
Kristen Blake and Jackquie Samples
LRTS 53(2) April 2009 p 94-107
This article looks at issues of Organization name consistency within ERM systems. There is some general discussion of structured data within ERM systems followed by a specific focus on organization names. Some OCLC initiatives are discussed as part of the environmental analysis, and several people managing ERM functions in libraries are interviewed. Work on this issue at NCSU is then described. The authors conclude by suggesting that such work provides local benefits and pointing to the advantages of greater community discussion and agreement.
Automated metadata harvesting: low-barrier MARC record generation from OAI-PMH repository stores using MarcEdit.
Terry Reese
LRTS 53(2) April 2009 p 121-134
This article outlines an environment in which a library is interested in metadata for digital resources from multiple sources, often available via OAI-PMH as organizations expose data about their digital collections. A particular requirement is explored: to convert such multiple streams into MARC for internal library use. This involves crosswalking between metadata from different creation regimes and MARC. A particular issue here is the absence of widely deployed content standards which means that inconsistent approaches to data creation have to be managed. OCLC services are also considered as part of the environmental analysis. The article then considers how MarcEdit, a tool created by the author, can be used to address the requirements described.
Each of these articles discusses a topic that is the subject of active OCLC interest and development attention. But it was less this that prompted me to connect them than the discussion of where and why consistency of data is important, and what complications for processing arise in the absence of such consistency.
Library standards-making has often seemed to emerge from social consensus-making and a type of anticipative refinement to meet a wide range of cases. As libraries exercise data in a variety of applications, as data flows between systems more, as matching, mining and mixing become important to support services, then there is more evidence available about where structure and consistency are important and what trade-offs are involved (between upstream flexibility in data creation practices and downstream processing and use, for example). This should improve the ways in which we think about standardisation and best practices.
### National libraries on YouTube
URL: https://www.lorcandempsey.net/national-libraries-on-youtube/
Last updated: 2020-10-28T09:15:52.000Z
While looking at the Library of Congress [presence](https://www.youtube.com/user/LibraryOfCongress?ref=lorcandempsey.net) on YouTube the other day, I was curious about other national library presences. A very quick search for national library ‘channels’ revealed the following …
- [The European Library](https://www.youtube.com/user/theeuropeanlibrary?ref=lorcandempsey.net)
- [The National Library Board of Singapore](https://www.youtube.com/user/NationalLibraryBoard?ref=lorcandempsey.net)
- [The National Library of Wales](https://www.youtube.com/user/llyfrgen?ref=lorcandempsey.net)
- [The National library of NZ](https://www.youtube.com/user/NationalLibraryNZ?ref=lorcandempsey.net)
- [The National Library of Scotland](https://www.youtube.com/user/NLofScotland?ref=lorcandempsey.net)
- [The Library of Congress](https://www.youtube.com/user/LibraryOfCongress?ref=lorcandempsey.net)
Mostly, they are exploratory steps. I have [mentioned](https://blog.oclc.org/lorcand/archives/001695.html?ref=lorcandempsey.net) the National Library of Scotland presence before and quoted an interesting discussion by Eilidh MacGlone about the initiative:
> In conclusion, there really is no place like home to us at the moment – our catalogue is in much better shape than YouTube’s. But we think YouTube is a great place to take our filmshows, to visit and meet our users, to build relationships and to interact with them, and perhaps in this aspect, YouTube is better than any online service we yet offer. \[[WIDWISAWN: volume 6, issue 1, page 4](https://widwisawn.cdlr.strath.ac.uk/issues/vol6/issue6%5F1%5F4.html?ref=lorcandempsey.net)\]
The Library of Congress has an interesting selection of videos and I wonder what their target volume is. I was also interested in how the library characterised itself: “As **the world’s preeminent reservoir of knowledge**, we are the steward of millions of recordings dating from the earliest Edison films to the present” (emphasis mine). And indeed the most popular video is titled *[“Edison Kinetoscopic Record of a Sneeze, Jan. 7, 1894”](https://www.youtube.com/watch?v=2wnOpDWSbyw&feature=channel%5Fpage&ref=lorcandempsey.net)*.
### Partial reception
URL: https://www.lorcandempsey.net/partial-reception/
Last updated: 2020-10-28T09:15:54.000Z
As participation in social networking services grows, information about peoples’ interests or activities is variably diffused through organizations based on selective affiliations between colleagues.
Now, this was always the case and information flow in organizations has been studied in various ways. However, participation in social networks accelerates and potentially reconfigures these flows.
We are already seeing academic studies of social network behaviors. It will be interesting to watch the response of the management literature as well to these issues.
Related entry:
- [Network management](https://blog.oclc.org/lorcand/archives/001919.html?ref=lorcandempsey.net)
### QOTD: therapeutic value of objects
URL: https://www.lorcandempsey.net/qotd-therapeutic-value-of-objects/
Last updated: 2020-10-28T09:15:56.000Z
A project looking at the use of ‘heritage’ materials in hospital contexts caught my eye …
> Working with Guy Noble, UCL Hospitals (UCLH)’s Art Curator, as well as the British Museum, Oxford University Museums Service, Reading Museums Service, Islington Education Library Service and the Museum, Libraries and Archives Council, their project is designed to lead to an understanding of the potential and value of taking handling collections from museums, libraries and archives into hospitals and other healthcare organisations such as care homes….
> Preliminary research conducted by Drs Chatterjee, Lanceley and Menon at UCLH showed that object handling sessions resulted in an increase in patient wellbeing and patients’ perception of their health status. Further, they found that patients felt positive about the role of object handling sessions as a distraction from everyday ward life, and that sessions had a positive impact on relationships amongst staff and patients….
> … Related to this, under the auspices of the interdisciplinary UCL Centre for Museums, Heritage and Material Culture (a collaboration between UCL Museums & Collections, the UCL Institute of Archaeology and UCL Anthropology), Drs Chatterjee, Beverley Butler and Professor Michael Rowlands held a workshop exploring ‘Heritage and Wellbeing’ on 10 December, which was the second in a series looking at the social care role of museums. Mark Watson, Heritage Officer of the Valence House Museum in Dagenham, was the seminar speaker, addressing the group on his work using loan boxes with Alzheimer’s patients and in schools. This was followed by a discussion forum that explored the workshop participants’ work and interests in the field of ‘heritage and wellbeing’. \[[Object Handling Therapy – AHRC grant and book launch](https://www.ucl.ac.uk/news/news-articles/0812/08121703?ref=lorcandempsey.net)\]
### Snap and go catalogue
URL: https://www.lorcandempsey.net/snap-and-go-catalogue/
Last updated: 2020-10-28T09:15:58.000Z
Several things about catalogs, mobile apps, and pictures ….
Just after doing the [entry](https://blog.oclc.org/lorcand/archives/001921.html?ref=lorcandempsey.net) on the photo feature in the Amazon Blackberry app, I was looking at the [catalogue](https://library.bath.ac.uk/uhtbin/cgisirsi/se0P4GupCy/UNIV-BATH/54800006/60/1055/X?ref=lorcandempsey.net) at the University of Bath (where I worked for many years) and saw that they were using QR codes.

From a library blog description of the initiative …
> I think this is wonderful, it is a really obvious efficiency saving for individuals. So instead of searching the catalogue and writing the info on scraps of paper. I simply find the resource I want, scan the code and save it on my phone. I can then use this to find the item on the shelf. Infact, I can save this on my phone (I’d probably take a little more time and cut and paste into a mobile word document) and start to build up my own reference collection. \[[QR codes at Bath » Blog Archive » Uni of Bath Library including QR Codes in Catalogue](https://blogs.bath.ac.uk/qrcode/2009/03/23/uni-of-bath-library-including-qr-codes-in-catalogue/?ref=lorcandempsey.net)\]
Jim Michalko left a comment on the earlier entry about Compare Everywhere, an Android application, for comparison shopping.Says Jim: “In fact the WorldCat API drives an Android App called [Compare Everywhere](https://www.android.com/market/free.html?ref=lorcandempsey.net#app=compareeverywhere) that links a barcode scan to a book in a local library”.
Finally, Kelly Smith noted that she tried out the Amazon Remembers app on the iPhone with book covers and that it worked well. This prompted me to try using the following rather poor image of Paul Muldoon’s *[The end of the poem](https://www.worldcat.org/oclc/61748380&referer=brief%5Fresults?ref=lorcandempsey.net)*.

Amazon matched it correctly to the [details](https://www.amazon.com/End-Poem-Oxford-Lectures/dp/0374148104?ref=lorcandempsey.net) for the volume … pretty fancy.
Update: apparently, Amazon Remembers uses human effort to match images to fulfilment opportunities on Amazon. See [here](https://blog.wired.com/business/2008/12/amazon-proves-i.html?ref=lorcandempsey.net) for details of how the Mechanical Turk application supports this application.
### Amazon remembers
URL: https://www.lorcandempsey.net/amazon-remembers/
Last updated: 2020-10-28T09:16:01.000Z
I noticed this feature on the page for the [Amazon Blackberry App](https://www.amazon.com/gp/anywhere/sms/bbapp?ref=lorcandempsey.net).

I haven’t yet tried the app or seen the feature working so I do not know how well it works.
Perhaps we need an application which allows you to take a picture of a book cover and find it in your library … Or which allows …..
Update: apparently, Amazon Remembers uses human effort to match images to fulfilment opportunities on Amazon. See [here](https://blog.wired.com/business/2008/12/amazon-proves-i.html?ref=lorcandempsey.net) for details of how the Mechanical Turk application supports this application. .
### "Harvesting intentionality"
URL: https://www.lorcandempsey.net/harvesting-intentionality/
Last updated: 2022-11-08T18:25:32.000Z
Jonathan Schwartz, CEO of Sun used the phrase “harvesting intentionality” in a blog post recently.
> **Discovering Intent**
> Now, why is the search business so valuable? Because it’s an exceptionally efficient means of harvesting intentionality – if a consumer is searching for “flights to Cairo,” the odds are good she’s in the market for a trip to Egypt. That intent represents a ton of value for the airlines, hotel chains and car rental companies that serve travelers to Egypt. Whoever first recognizes that intent can broker a relationship between the traveler and those businesses, and charge a healthy toll for the privilege (that’s the heart of on-line advertising). A discount airfare to Cairo, presented alongside the results of a “flights to Cairo” search, has a far higher likelihood of generating a ticket purchase than an unqualified billboard or ad in a newspaper. It’s easier to find needles in haystacks when the haystacks are sorted by needle count. \[[Jonathan Schwartz’s Blog: Sun’s Cloud (4 of 4)](https://blogs.sun.com/jonathan/entry/unified%5Fcomputing?ref=lorcandempsey.net)\]
He goes on to discuss how downloads of Sun’s open source software provide valuable ‘intentional’ data, data which reveals intent.
There has also been some discussion of the value of bit.ly, the URL shortening service, in light of recent investment. For example:
> … The most important aspect of Bit.ly is not that it can shorten URLs. Instead its real prowess lies in its ability to track the click-performance of those URLs, and conversations around those links. It doesn’t matter where those URLs are embedded — Facebook, Twitter, blogs, email, instant messages or SMS messages — a click is a click and Bit.ly counts it, in real time. Last week alone, nearly 25 million of these Bit.ly URLs were clicked.
> By clicking on these URLs, people are essentially voting on the stories behind these links. Now if Bit.ly collated all these links and ranked them by popularity, you would have a visualization of the top stories across the web. In other words, it would be a highly distributed form of Digg.com, the social news service that depends on people submitting and voting for stories from across the web. Don’t be surprised if Bit.ly formally launches such as an offering real soon. This will help them monetize their service via advertising. \[[Why Bit.ly Will Upstage Digg](https://gigaom.com/2009/03/31/why-bitly-could-upstage-digg/?ref=lorcandempsey.net)\]
So, again, a discussion of the value of intentional data, of trying to discern people’s intent and using that to support other services.
In a library context, this was a topic of discussion at the recent heavily amplified [Libraries of the Future](https://www.jisc.ac.uk/whatwedo/campaigns/librariesofthefuture/debate.aspx?ref=lorcandempsey.net) event in Oxford, where library consultant, Ken Chad, argued that libraries suffered by not aggregating circulation or other data which revealed user choices. Libraries in general don’t have good mechanisms in place for discerning people’s intent and and for using this data to develop services for ranking, relating and recommending. This was also a central theme of the recent [Tile](https://www.jisc.ac.uk/whatwedo/programmes/resourcediscovery/tile.aspx?ref=lorcandempsey.net) report of which Ken was one of the authors.
See some discussion of these comments by Joy Palmer of COPAC [here](https://copac.ac.uk/development-blog/2009/04/catalogues-as-communities-some-thoughts-on-libraries-of-the-future/?ref=lorcandempsey.net).
Related entries:
- [Four sources of metadata about things](https://blog.oclc.org/lorcand/archives/001351.html?ref=lorcandempsey.net)
- [Tile and organizational evolution](https://blog.oclc.org/lorcand/archives/001892.html?ref=lorcandempsey.net)
- [Web 2.0 again](https://blog.oclc.org/lorcand/archives/001783.html?ref=lorcandempsey.net)
- [Making data work harder – intentionally](https://blog.oclc.org/lorcand/archives/000822.html?ref=lorcandempsey.net)
- [Recommendation and Ranganathan](https://blog.oclc.org/lorcand/archives/001566.html?ref=lorcandempsey.net)
[LOTF09](https://www.technorati.com/tag/LOTF09?ref=lorcandempsey.net)
### Network management
URL: https://www.lorcandempsey.net/network-management/
Last updated: 2020-10-28T09:16:05.000Z
Gary Hamel, management guru, has a couple of posts about about management in the network age. On the web, he says, authority trickles up, not down.
The first, on a WSJ blog is called ‘The Facebook generation vs the Fortune 500’, and in it he discusses the expectations of Generation F: “At a minimum, they’ll expect the social environment of work to reflect the social context of the Web, rather than as is currently the case, a mid-20th-century Weberian bureaucracy”.
> With that in mind, I compiled a list of 12 work-relevant characteristics of online life. These are the post-bureaucratic realities that tomorrow’s employees will use as yardsticks in determining whether your company is “with it” or “past it.” In assembling this short list, I haven’t tried to catalog every salient feature of the Web’s social milieu, only those that are most at odds with the legacy practices found in large companies. \[[Growing up online will profoundly shape the workplace expectations of the Facebook Generation](https://blogs.wsj.com/management/2009/03/24/the-facebook-generation-vs-the-fortune-500/?ref=lorcandempsey.net)\]
I thought there was much of interest here, although I wondered if there was a touch of playing to the gallery involved also. Individually, there are no strong surprises on the list, although it would be interesting to read of organizations which model a variety of these behaviors:
1\. All ideas compete on an equal footing.
2\. Contribution counts for more than credentials.
3\. Hierarchies are natural, not prescribed.
4\. Leaders serve rather than preside.
5\. Tasks are chosen, not assigned.
6\. Groups are self-defining and -organizing.
7\. Resources get attracted, not allocated.
8\. Power comes from sharing information, not hoarding it.
9\. Opinions compound and decisions are peer-reviewed.
10\. Users can veto most policy decisions.
11\. Intrinsic rewards matter most.
12\. Hackers are heroes.
In the second, on a HBR blog, he reports the outcomes of a meeting of management leaders to discuss major management challenges in this environment.
> Before arriving, each of the 35 attendees participated in an hour-long interview. The double-barreled question: What is it about the way large organizations are currently managed that will most imperil their ability to thrive in the decades ahead; and given this, what fundamental changes will be needed in management principles, processes and practices? \[[25 Stretch Goals for Management – Gary Hamel – HarvardBusiness.org](https://blogs.harvardbusiness.org/hamel/2009/02/25%5Fstretch%5Fgoals%5Ffor%5Fmanagemen.html?ref=lorcandempsey.net)\]
The outcome here is a set of 25 “moonshots for management”. As an example, here is Number 7: “Redefine the work of leadership. The notion of the leader as a heroic decision maker is untenable. Leaders must be recast as social-systems architects who enable innovation and collaboration.”
And here is number 16 “Empower the renegades and disarm the reactionaries. Management systems must give more power to employees whose emotional equity is invested in the future rather than in the past.”
### Virtual International Authority File
URL: https://www.lorcandempsey.net/virtual-international-authority-file/
Last updated: 2020-10-28T09:16:07.000Z
Thom discusses the updated [viaf.org](https://viaf.org/?ref=lorcandempsey.net) site …
> The [VIAF site](https://viaf.org/?ref=lorcandempsey.net) has recently had a major overhaul. What you now search are records created from a merge of matching source authority records. Within this record you can see what source records were used to create it, along with cross references and other information gleaned both from the authority records and from associated bibliographic records. \[[Outgoing: Changes to VIAF](https://outgoing.typepad.com/outgoing/2009/04/changes-to-viaf.html?ref=lorcandempsey.net)\]
There are 7.8 million VIAF records built from 9.2 million source records across four authority files. More files will follow and Thom also describes proposed directions in how the data is presented.
My authority control poster child is Flann O’Brien \[[WC Identities](https://www.worldcat.org/identities/lccn-n50-1905?ref=lorcandempsey.net), [VIAF](https://viaf.org/viaf/22146540?ref=lorcandempsey.net)\]. Here is the variety of alternate names listed for him …

Here is the [Marc 21 data](https://viaf.org/viaf/22146540.m21?ref=lorcandempsey.net).
For those that are interested in the implementation detail …
> The whole site is just a thin layer of XSLT stylesheets and URL rewrite rules over an SRU database. Other than some JavaScript, virtually everything else is XSL transforms on XML data returned from SRU queries. The graph is put up using a JavaScript vector graphics package jsGraphics. Mouse overs, etc. are currently working better in Firefox than IE. \[[Outgoing: Changes to VIAF](https://outgoing.typepad.com/outgoing/2009/04/changes-to-viaf.html?ref=lorcandempsey.net)\]
### Slowing down for a while ..
URL: https://www.lorcandempsey.net/slowing-down-for-a-while/
Last updated: 2020-10-28T09:16:08.000Z
Blogging has been a little thin of late as I have been traveling and I have a couple of writing commitments which require my spare attention. The latter means that I will be posting less frequently here for a while …
### Four sources of metadata about things - version 2
URL: https://www.lorcandempsey.net/four-sources-of-metadata-about-things-version-2/
Last updated: 2022-11-08T18:28:31.000Z
I think it is useful to think of four sources of descriptive metadata in libraries. These are not mutually exclusive, and one of the interesting questions we have to address is how they will be mobilized effectively together.
I don’t have good names for these. How about: *professional*, *contributed*, *programmatically promoted*, and *intentional*?
**Professional**
The curatorial professions have made major investments in knowledge organization, through the development and application of cataloging rules, controlled vocabularies, authorities, gazetteers, and so on. One of our major challenges is releasing the value that has been created through those approaches in web environments. There is much to think about here, and many folks are thinking about it. Currently, these approaches do not tend to work well across silos, they are not made available as web resources themselves so that they can be part of the connected fabric of the web, they only work with the other approaches I mention in particular projects or services, their ‘relating’ power is underused, and higher level services based on data mining or statistical analysis are limited. Now, these types of issues are being addressed, but are some way from routine systemwide application. I believe that these approaches will continue, within a reconfigured system, and we need to make that data work harder. My personal view is that the curatorial professions need to invest more in the shared production of resources which identify and describe authors, subjects, places, time periods, and works.
**Contributed**
A major phenomenon of recent years has been the emergence of many sites which invite, aggregate and mine data contributed by users, and mobilize that data to rank, recommend and relate resources. These include, for example, Flickr, LibraryThing, and Connotea. These services have a different focus, and create real value in the way that they organize resources. They also have value in that they reveal relations between people. Libraries have begun to experiment with these approaches, but individual libraries may not have the scale to iron out local or personal idiosyncrasy or emphasis. This is another area which lends itself to shared attention. There are real advantages to be gained. So, for example, as we digitize photographic and other community collections, we will want to mobilize knowledge about those collections that does not exist within the library. Or, if you think about a service like Worldcat Identities, at some stage we will want to allow those ‘identities’ themselves to comment, augment, amend. What this means is that we will have to get rather more sophisticated about managing assertions about resources from different sources.
**Programmatically promoted**
We are handling more digital materials, where it is possible to programmatically identify and promote metadata from resources themselves or groups of resources. We will also do more to mine collections, including collections of metadata, to discern pattern and relations. We are increasingly familiar with clustering, entity identification, automatic classification and other approaches. Look at the home page for books that Google is creating to see a resource created from mining Scholar, Google Book Search, and big Google to deliver a range of related materials.
**Intentional**
I have used this term to refer to the data that we are collecting about use and usage. Pagerank is based on aggregate linking choices. Amazon recommendations are based on aggregate purchase choices. We use holdings data in ranking algorithms, which aggregates selection choices of libraries. This type of data has emerged as a central factor in the major web presences as they seek to provide useful paths through massive amounts of data.
To repeat, these approaches are not mutually exclusive and will increasingly be deployed alongside each other. For example, authority lists may support programmatic identification of personal or place names in large text resources. The shared interests revealed in social networking applications may be abstracted into a form of intentional data to drive recommendations or ‘related work’ services. Patterns of association and interaction will develop between tags and subject headings. And so on.
Much of our discussion pits these approaches against each other. This seems like the wrong approach. Clearly there will always be choices about where one invests effort, especially as the network continues to reconfigure what we do, but the starting point should be how we create better services and what approaches support that, and not a ‘techeological’ position around one or other approach which confuses ideology and technology.
Related entries:
- [All that is solid melts into flows](https://blog.oclc.org/lorcand/archives/000663.html?ref=lorcandempsey.net)
- [Circulating intentional data](https://blog.oclc.org/lorcand/archives/000875.html?ref=lorcandempsey.net)
### What's on your mind ...
URL: https://www.lorcandempsey.net/whats-on-your-mind/
Last updated: 2020-10-28T09:16:13.000Z
Ohio State, our neighbors to the South, have a nice tag cloud feature on their home page. I am not sure how they are generating it, but they have clouds based on the behavior of different classes of audience.
Here are students …
[](https://www.osu.edu/mostpopular/index.php?a=10&n=40&ref=lorcandempsey.net)
Here are faculty/staff …
[](https://www.osu.edu/mostpopular/index.php?a=12&n=40&ref=lorcandempsey.net)
Update: I see that the ‘clouds’ show most popular links on relevant sections of the website ([students](https://www.osu.edu/currentstudents/?ref=lorcandempsey.net), [faculty/staff](https://www.osu.edu/facultystaff/?ref=lorcandempsey.net)).
### Book covers and the scholarly record
URL: https://www.lorcandempsey.net/book-covers-and-the-scholarly-record/
Last updated: 2020-10-28T09:16:16.000Z
There have been various discussions among research libraries recently about the management of the collective print collection as pressures on library space coincide with shifting research and learning behaviors in a network environment.
This will create interesting questions about preserving the print scholarly record over the next few years: what combination of agencies should be responsible for assuring – and paying for – as complete a print record as seems desirable? Previously, continuity of access was a benign side-effect of the redundant local storage involved in the print distribution model. As libraries look at retiring or consolidating parts of their collection, this redundancy cannot be counted on and calls for some collective management attention. This is likely to happen at a national level in some countries.
I was reminded of this issue in a small but symptomatic way by a very nice story on the Penguin blog. Penguin decided to adorn a reissue of Raymond Chandler’s novels with facsimiles of the original cover art. However, it proved very difficult to track down the pictures in question.
> The Bodleian got back to my email and told me that they’d unearthed copies of The Little Sister, Farewell, My Lovely and The Big Sleep but that none of them had jackets with them; they’d presumably been lost over the years or thrown away when they became too damaged. However, there was a dust jacket collection somewhere in the library called the John Johnson collection; perhaps the jackets would be in there. Sure enough, I contacted a lady there to find out that the collection held the jacket for the 1949 first edition of The Little Sister and as long as we sorted out all the boring bits, we should be able to procure a scan. Bingo. One down, three to go. \[[The Penguin Blog: In search of Chandler](https://thepenguinblog.typepad.com/the%5Fpenguin%5Fblog/2009/03/in-search-of-chandler.html?ref=lorcandempsey.net)\]
> Since we’d got lucky with the Bodleian, the next logical step was to phone and email lots of other libraries all over the country, concentrating particularly on copyright libraries, which should hold copies of every book ever published. So we phoned around, and emailed, and phoned, and emailed and phoned. Mostly we got the expected response, that although copies of the books existed, the jackets were far more elusive. But Cambridge University Library happened to still have an intact 1953 first edition of The Long Good-bye – complete with its dust jacket. I thanked my stars. Two down. \[[The Penguin Blog: In search of Chandler](https://thepenguinblog.typepad.com/the%5Fpenguin%5Fblog/2009/03/in-search-of-chandler.html?ref=lorcandempsey.net)\]
There is also some discussion of tracking down copies via used book sources.
Now, libraries have as much difficulty as most folks in divining future needs, and discarding covers or not holding onto thrillers is defensible in local contexts.
But one would expect to be able to locate such things in the ‘system’ as a whole, within, say, the library apparatus in the UK? And if such things are available, will you be able to find them?
Related entries:
- [Pick up a penguin, nostalgically](https://blog.oclc.org/lorcand/archives/001190.html?ref=lorcandempsey.net)
### The intrusion of ads
URL: https://www.lorcandempsey.net/the-intrusion-of-ads/
Last updated: 2020-10-28T09:16:18.000Z
We are now used to seeing ads on web pages, and it seems quite normal. In fact, occasionally, they are even interesting or useful. And Google is certainly working hard to make them even more so.
Tom Wilson has published *Information Research* for many years …
> *Information Research*, is an open access, international, peer-reviewed, scholarly journal, dedicated to making accessible the results of research across a wide range of information-related disciplines. It is privately published and edited by [Professor T.D. Wilson](https://informationr.net/tdw/?ref=lorcandempsey.net). It is hosted, and given technical support, by [Lund University Libraries](https://www.lub.lu.se/new%5Ftop/omlub/bd%5Feng.shtml?ref=lorcandempsey.net), Sweden. Editorial support is provided by the [Swedish School of Library and Information Science](https://www.hb.se/bhs/?ref=lorcandempsey.net), Gothenburg University and Högskolan i Borås. \[[Information Research: an international electronic journal. Information science, Information management, Information systems, Information retrieval, Digital libraries, Information seeking behaviour, Information seeking behavior, World Wide Web, WWW](https://informationr.net/ir/?ref=lorcandempsey.net)\]
I occasionally look at it. It has carried ads on issue contents pages for a little while. In the [current issue](https://informationr.net/ir/14-1/infres141.html?ref=lorcandempsey.net) the location of the ads has changed: they are level with the contents on the right hand side of the page.
For some reason, I find these very intrusive and inappropriate. I am not quite sure why. It may partly be to do with the contrast between the blues, but this only contributes to the uneasiness, it does not create it. And it is probably difficult to offer ads which are in line with the article contents. However, call me old-fashioned, but I guess my main concern is that the table of contents of a research journal doesn’t seem like the place to view ads.
\[Of course, I am not saying that Tom should not do this. He does a lot of work and has real costs.\]
### The archived website as historical document
URL: https://www.lorcandempsey.net/the-archived-website-as-historical-document/
Last updated: 2020-10-28T09:16:20.000Z
Presentations from the JISC conference last week are now [available on the website](https://www.jisc.ac.uk/events/2009/03/jiscconference09/programme.aspx?ref=lorcandempsey.net).
I attended the session on web archiving and was struck by the presentation by Niels Brügger (PDF of session [here](https://www.jisc.ac.uk/media/documents/events/2009/03/preservetheweb-harris1pm.pdf?ref=lorcandempsey.net); he begins at page 64). Kevin Ashley’s overview of institutional issues and Paul Cunnea’s discussion of national web-archiving issues were also interesting.
Brügger’s perspective was that of a web historian, who uses the contents of web archives as historical documents. This raises interesting evidential issues as technical and policy choices mean that archived and original website are not identical. Here is the abstract from an earlier article which gives a flavor of the topics addressed.
> Website history can be considered an emerging discipline at the intersection between media history and Internet history. In this discipline, the individual website is regarded as the unifying entity of the historical analysis rather than the Internet or the Web. Writing the history of a website involves using many sources and methods similar to those used in writing the history of any other media type. But one document type requires special attention: the archived website. This is so because the problems involved in finding, collecting and preserving the website are different from those characterizing the archiving of other types of traces of human activity, including other media types. The primary problem is that the actual act of finding, collecting and preserving changes the website that was on the live web in a number of ways, thus creating a unique version of it and not simply a copy. The present article sets out, first, to discuss to what extent the archived website can be considered a new type of historical document and how its characteristics affect the task of the website historian who must later use it; second, the article discusses and attempts to formulate some methodological principles, rules and recommendations for a future critical textual philology of the website. \[[Niels Brügger](https://person.au.dk/da/pub/14857729?id=14437&ref=lorcandempsey.net)\]
And here is a practical example he discussed …
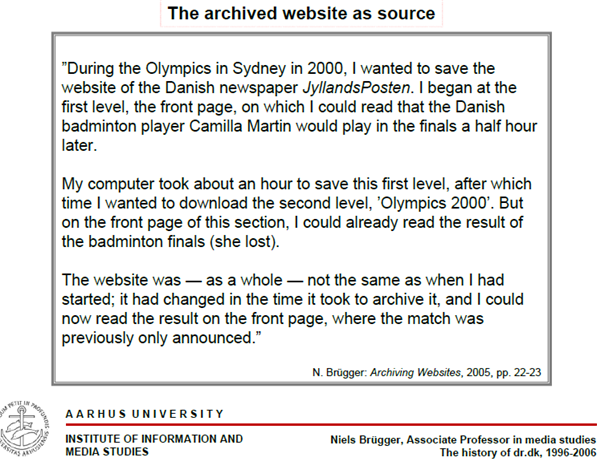
### Twitterage
URL: https://www.lorcandempsey.net/twitterage/
Last updated: 2020-10-28T09:16:22.000Z
I spent much of last week in Edinburgh for the [JISC Conference](https://www.jisc.ac.uk/jiscconference09?ref=lorcandempsey.net), of which maybe more later. JISC has a heavy communications component and strongly encourages ‘[amplification](https://en.wikipedia.org/wiki/Amplified%5Fconference?ref=lorcandempsey.net)‘ of conference activity through blogging, Twitter, video streaming, and so on. This might be one reason that discussions about Twitter are what I most remember of the event, partly because of the occasional questions about level of use from speakers or exhortations to participate.
It polarized somewhat: a familiar complacent cliquishness at one end and a defensive affected incomprehension at the other. I didn’t sense that this was generational, but there did seem to be a managerial gap, with ‘senior’ people often towards the latter pole.
Incidentally, proposals to overhaul the primary (aka elementary) school curriculum were leaked while I was there. Twitter was central to the coverage …..
> Children will no longer have to study the Victorians or the second world war under proposals to overhaul the primary school curriculum, the Guardian has learned.
> However, the draft plans will require children to master Twitter and Wikipedia and give teachers far more freedom to decide what youngsters should be concentrating on in classes. \[[Pupils to study Twitter and blogs in primary shake-up | Education | The Guardian](https://www.guardian.co.uk/education/2009/mar/25/primary-schools-twitter-curriculum?ref=lorcandempsey.net)\]
[JISC09](https://www.technorati.com/tag/JISC09?ref=lorcandempsey.net)
### QOTD: Content economy and attention economy
URL: https://www.lorcandempsey.net/qotd-content-economy-and-attention-economy/
Last updated: 2020-10-28T09:16:24.000Z
We are catching up on the *The Wire* on NetFlix so I was interested to see these remarks on the newspaper industry by its creator, David Simon …
> In an exclusive interview with the Guardian, the award-winning writer and producer launches a tirade against newspaper owners who, he says, showed “contempt for their product” and are now reaping the whirlwind. But he rejects the idea that [newspapers](https://www.guardian.co.uk/media/newspapers?ref=lorcandempsey.net) should seek ways to embrace the new world of free information, arguing that they must urgently start charging money for content distributed online. …
> … The only hope, Simon insists, is for major news outlets to find a way to collaboratively impose charges for reading online, and to demand fees from aggregators such as Google News, which profit from their journalism. “If you don’t have a product that you’re charging for, you don’t have a product,” he says. “If you think that free is going to produce something that’s as much of a cost centre as good journalism – because it costs money to do good journalism – you’re out of your mind.”
> The number of readers willing to pay a small fee each month might never rival the heyday of newspaper circulation, but it would attract enough “people who care what’s going on in the world” to fund crucial reporting, he maintains. “And once they do that, and go to Google and Yahoo and every other search engine and say: ‘No, ain’t no free.'” He scoffs at the notion that amateur “citizen journalism”, or new online-only outlets, might take the place of newspaper reporters: “The internet does froth and commentary very well, but you don’t meet many internet reporters down at the courthouse.” \[[Newspapers last bastion against political corruption says David Simon, award-winning creator of The Wire | Media | guardian.co.uk](https://www.guardian.co.uk/media/2009/mar/27/david-simon-wire-newspapers?ref=lorcandempsey.net)\]
### Reading, Starbucks and imbrication
URL: https://www.lorcandempsey.net/reading-starbucks-and-imbrication/
Last updated: 2025-05-31T20:42:49.000Z
Jim has a very interesting account of a discussion at an AAAS panel about the future of the book, publishing and libraries over at [HangingTogether](https://hangingtogether.org/?p=629&ref=lorcandempsey.net). (It was part of a [symposium](https://www.amacad.org/events/recent.aspx?ref=lorcandempsey.net) on Information technology and the public good.)
One note jumped out at me. He quotes Dan Clancy, of Google,
> “Starbucks succeeded because it provided a place for digital reading.” – Dan Clancy
I have returned to Starbucks several times [in these pages](https://www.lorcandempsey.net/lorcand/lorcan/orweblog%5Fconfig/mt-search.cgi?IncludeBlogs=1&search=Starbucks), beginning here some time ago ..
> It seems to me that the role of the coffee house, and it must be said, Starbucks in particular given its reach, in the contemporary urban setting is becoming clearer. Starbucks provides time-place alignment in busy, moving lives: in other words it provides ‘on-demand place’. It provides a place which is convenient at the time that it is required. This may be for downtime (a place to spend time relaxing), connect-time (a place to spend time connecting to the network), rendezvous time (a place to spend time with others), work-time (a place to spend time working). A colleague recently described Starbucks to me as his mobile office when he was on the road. It is not unusual to see job interviews take place there. \[[Lorcan Dempsey’s weblog](https://blog.oclc.org/lorcand/archives/000799.html?ref=lorcandempsey.net)\]
I take Dan’s comment as a very small example of what Saskia Sassen is talking about when she talks about the embeddedness of the digital in physical, social and institutional contexts.
> I use the term imbrication to capture this simultaneous interdependence and specificity of each the digital and the nondigital. They work on each other but they do not produce hybridity. Each maintains its distinct irreducible character. \[Saskia Sassen. [Territory, authority, rights](https://www.worldcat.org/oclc/60491951?ref=lorcandempsey.net). p.345\]
Update: Sassen’s canvas is a large one, looking at changing contexts of the nation state and globalization. So my connection here is a little contrived. But I was struck by the quote above in the overall flow of her argument here: that digital activity depends on material supports. We do not have purely digital corporations or experiences. So, large financial centres in major cities are the hubs for the digital flows of financial markets. Google and other Internet hubs are creating a massive physical footprint to support their digital presence. Coffee-shops are connection points. And libraries are thinking about reconfiguring their space to adapt to the digital lives of their users. Thinking about more social space to support the ad hoc rendezvous or group work of mobile communicators. Thinking about access to specialist advice or equipment. Thinking about materials ‘to go’ on portable devices and storage. Thinking about connectivity.
Our physical and digital libraries are increasingly imbricated.
### The Google research offer
URL: https://www.lorcandempsey.net/the-google-research-offer/
Last updated: 2020-10-28T09:16:28.000Z
I was interested to see this note on the home page of Google Book Search:

It links through to a page of ‘research tips’ based on the use of Google Book Search.
> Can’t remember where you found that quote? Did someone grab the last copy of the book you needed from the library? Google Book Search can help! \[[Research Tips from Google Book Search](https://books.google.com/googlebooks/midterms.html?ref=lorcandempsey.net#utm%5Fsource=gbs%2Bhome%20page%20promo&utm%5Fmedium=link&utm%5Fcampaign=midterms)\]
It is nice to see it mention the Worldcat link …
[](https://books.google.com/url?id=zutxr7rGc%5FQC&pg=PP1&q=https://worldcatlibraries.org/wcpa/oclc/52301582&clientid=librarylink&usg=AFQjCNEnJsvjdfkCWvetwwOJREFfork4lQ&source=gbs%5Fbuy%5Fs&cad=1)
I note that it does not mention Google Scholar.
Aside: a [search](https://www.google.com/search?as%5Fq=book&ref=lorcandempsey.net) on ‘book’ in Google returns Google Book Search as the first result.
### QOTD - those library users!
URL: https://www.lorcandempsey.net/qotd-those-library-users/
Last updated: 2020-10-28T09:16:30.000Z
From [Derek Law](https://www.worldcat.org/identities/lccn-nr89-9313?ref=lorcandempsey.net):
> It is also something of a paradox that academic staff, who almost by definition work at the leading edge of their discipline and thrive on change are library and in many cases IT conservatives, seeking investment in back runs of journals and support for long since superseded or home-made software. As the mythical Professor Quincy Wagstaff (from the 1932 Marx Brothers film Horse Feathers) would have it ‘Whatever it is, I’m against it’. \[In: Hanson, Terry. 2005\. [Managing academic support services in universities: the convergence experience](https://www.worldcat.org/oclc/58455223?ref=lorcandempsey.net). London: Facet.p.101\]
### Convergence ...
URL: https://www.lorcandempsey.net/convergence/
Last updated: 2020-10-28T09:16:32.000Z
I have been glancing through the contributions to
> HANSON, T. (2005). *[Managing academic support services in universities: the convergence experience](https://www.worldcat.org/oclc/58455223?ref=lorcandempsey.net)*. London, Facet.
They examine convergence between libraries, IT and other support services in universities. This is a phenomenon more common in the UK than elsewhere: more than half of UK universities have adopted some form of converged model according to the editor. The contributions are mostly written by central actors in planning or managing converged services in the UK, alongside a historical perspective, and brief summary articles on the rest of Europe (based on a survey by Mel Collier), the US and Australia. Included also are some discussions of why a converged model was not adopted.
There is a variety of patterns of convergence, and it is very clear that local personalities and politics are decisive. Common is some coming together of the library and the campus computing or IT services, but other units may also be drawn in: management information systems, e-learning developments, language labs, audio-visual support and so on. I have wondered in these pages whether the founding type of library/IT convergence that is central here is an artifact of an earlier time and queried whether …
> … it now makes more sense to associate the library with emerging support for e-learning and e-research, creating a set of capacities aligned around academic systems and services, and the management of research and learning data. \[[Lorcan Dempsey’s weblog](https://blog.oclc.org/lorcand/archives/001656.html?ref=lorcandempsey.net)\]
(Indeed, in their review of Australian developments, Helen Hayes and Vic Elliot note a more recent trend to convergence between library and online learning services. p.176)
That said, what comes across in many of the discussions here is the importance of scale and of the ability to more flexibly re-allocate resources and make connections in a bigger unit. Conversely, some contributors point to the dangers of a converged service appearing too big – attracting 5-10% of the overall university budget according to Nigel Macartney – and presenting an attractive target for cuts. Apparent also, at least some of the time, are potential benefits in consolidation of both infrastructure and ‘customer’ relationship management. An interesting occasional theme is the additional institutional political influence the Director of a converged service may have. However, a couple of contributors also express concern that the breadth of expertise and attention required to effectively manage a wide range of services is such that some areas may inevitably be less well addressed. And specific to the UK is the common mention of several national policy documents and initiatives which encouraged this direction in the nineties.
I imagine that Derek Law’s comment in his contribution might be applied to several of the others here: “This author has noted elsewhere the tendency for institutions to (re)write their history in terms of principled and timely decision-making, rather then the somewhat grimmer pragmatic institutional politics which in reality usually drives change”. (p.97)
Anyway, skimming the articles here, my eye was caught by several passages …
Paradoxically, although convergence began in the USA, it has been proportionately more pervasive in the UK. (Clive D. Field, p 10)
Staff development and communication policies, considered to be important to bring about cultural change, were developed but with too much emphasis on ‘process’ and not enough on actual delivery of success in getting staff to take ownership of what had emerged. There was no ‘mourning’ of the passing of some of the old cultural icons that were swept away with convergence or celebration of new things that emerged. (Michele Shoebridge. p. 32)
… Information Services is still perceived in the University, and largely also in the division itself, as the Library Service and the Computing Service with new and confusing names. (Cathryn Gallacher. p.52)
We believe that true convergence requires an acceptance of common professional values, including evidence-based and reflective practice. (Margaret Haines et al. p.74)
At the time Information Services was created its budget and staff numbers was broadly equivalent to each of the then faculties and was not perceived as a problem. However, once the organization moved to eight schools, each of which had much smaller budgets, and the Registrar’s area was broken up on the administration side, the Information Services budget became the exception rather than the rule. It had the largest budget and staff, and began to be questioned on those grounds, rather being judged merely on cost effective service provision. (Sue Clegg. p.85)
The characteristics required in the head of the converged service depend to a large extent on what is expected of the convergence – if there are major structural problems to be overcome then tenacity, political savoir-faire and HR skills will be more important than than the technical understanding which might be needed if the structure and people are right but the IT strategy is defective. ….. The will to work together and not to be precious about tradition or territory is more important than any formal structure. (Tom Crawshaw. p.113)
Probably the most effective local influence on convergence at Swansea has been the simple expedient of combining library and computing services and staff in a single building. (Christopher West. p.120)
Ultimately it is people – not structures – who deliver services and working together depends more on creating the right climate than finding the best design. (Sheila Corrall. p.151)
World-class institutions do not have converged service delivery; there could be considerable debate over the names in the top 100 worldwide and their ranking, but it is the case that these institutions have no evident converged approaches to service delivery. (Mark Clark. p.157)
Some of the newer and smaller universities seem to be able to adapt to changing needs as they occur whereas such flexibility often proves more difficult in larger and older institutions. It is also true that structural change, at least in the Australian higher education sector, has often been driven by strong personalities and power plays during a time of constant change in which responsibilities have been reviewed and redefined to meet new challenges. (Hayes and Elliott. p.177)
Our hypothesis is that conditions in Europe \[outside the UK\] are generally not conducive to convergence. Such conditions could include: powerful decentralized administrations, conservative policies, and the level of maturity or professionalization of university services. (Mel Collier. p.199)
As one library director I interviewed succinctly put it, ‘The only thing I discovered is that structure does not mean a tinker’s damn. If people have a good attitude and can communicate, structure does not matter.’ (Larry Hardesty. p.210)
### Programmatically promoting data
URL: https://www.lorcandempsey.net/programmatically-promoting-data/
Last updated: 2020-10-28T09:16:36.000Z
Several items have come over my desk (?) in the last few days which together point to the growing importance of techniques for programmatically promoting data from unstructured documents, including web pages.
The *Economist* had a piece about Autonomy, the search sofware company a while ago.
> Yet the most important reason for Autonomy’s success is that it is riding a long-term trend in computing. Corporate computing was once all about “structured data” such as payroll records or sales figures. Now, however, computers are also able to crunch “unstructured” data, such as documents, e-mails and photographs. And the quantity of such data has exploded: more than 80% of a typical company’s information is now unstructured, according to some estimates. Firms that can extract meaning from this digital pile will have a big advantage. \[[Software in the recession | Out on its own | The Economist](https://www.economist.com/business/displaystory.cfm?story%5Fid=13185883&ref=lorcandempsey.net)\]
Here is how the article describes what Autonomy does: “Using complex algorithms, they are able to extract ideas from all kinds of data, be it text, audio or video–even if these ideas are expressed in different terms.”.
Several of my colleagues have looked at the OpenCalais web service from Thomson Reuters. Here is the blurb from their website:
> The Calais Web Service automatically creates rich semantic metadata for the content you submit – in well under a second. Using natural language processing, machine learning and other methods, Calais analyzes your document and finds the entities within it. But, Calais goes well beyond classic entity identification and returns the facts and events hidden within your text as well. \[[How Does Calais Work? | OpenCalais](https://www.opencalais.com/about?ref=lorcandempsey.net)\]
I got a note from Krista Thomas of Thomson Reuters about Media Cloud, an initiative of the Berkman Center at Harvard which uses Calais. This is an adventurous initiative which aims to provide tools to track trends in the media …
> For each story from a given news source, the system automatically assigns relevant terms to that article. These terms, and the stories they describe, are then explored in relation to the rest of the interconnected network of media sources. Sources may cluster together around specific topics, or diverge.
> In its most ambitious incarnation, Media Cloud might ultimately identify new memes as they emerge in the media ecosystem. By combining massive data collection with novel clustering techniques, we may be able to identify thousands of instances of new ideas emerging from one corner the media ecosystem and spreading to other parts – or failing to spread. \[[Media Cloud » About](https://www.mediacloud.org/about-2/?ref=lorcandempsey.net)\]
Finally, a colleague circulated a note about Microsoft Research’s EntityCube initiative …
> The need for collecting and understanding Web information about a real-world entity (such as a person or a product) currently is fulfilled manually through search engines. But the information about a single entity might appear in thousands of Web pages. Even if a search engine could find all the relevant Web pages about an entity, the user would need to sift through all the pages to get a complete view of the entity. EntityCube is an entity search and summarization system that efficiently generates summaries of Web entities from billions of crawled Web pages. The summarized information is used to build an object-level search engine about people, locations, and organizations and explore their relationships. \[[EntityCube – Microsoft Research](https://research.microsoft.com/en-us/projects/entitycube/?ref=lorcandempsey.net)\]
These are all very different: but they are symptomatic of a major interest in extracting meaningful content from masses of unstructured data through various programmatic techniques.
This is something of interest to all organizations — including universities. In this context, I was struck by this comment in the Taiga 2009 provocative statements:
> 4\. … knowledge management will be identified as a critical need on campus and will be defined much more broadly than libraries have defined it. The front door for all information inquiries will be at the university level. Libraries will have a small information service role. \[Taiga. Provocative Statements (after the meeting)
> February 20, 2009 – [PDF](https://www.taigaforum.org/documents/Taiga%204%20Statements%20After.pdf?ref=lorcandempsey.net)\]
Now, this is intended to be provocative ;-), but it is worth thinking about what sorts of techniques will be useful to manage campus information and where the library should be thinking about developing capacities. And indeed, libraries themselves are also managing more digital materials – eprints, web pages, digitized materials, … – where the current metadata creation model does not scale and programmatic promotion of metadata, entity identification, and so on, becomes more important.
Related entries:
- [Four sources of metadata about things](https://blog.oclc.org/lorcand/archives/001351.html?ref=lorcandempsey.net)
- [Calais – identification in the cloud](https://blog.oclc.org/lorcand/archives/001667.html?ref=lorcandempsey.net)
### Web-sightings
URL: https://www.lorcandempsey.net/web-sightings/
Last updated: 2020-10-28T09:16:38.000Z
A few features I noticed recently on library web-sites …
Oregon State University explicitly notes resources that are **unique** to the institution …
[](https://osulibrary.oregonstate.edu/digitalcollections/?ref=lorcandempsey.net)
These include the University Press, the institutional repository, and a range of digitized materials from different collections. With the exception of the University Press, these are materials that come ‘below the line’ in the collections grid we developed a while ago.

In recent years, the institution’s unique intellectual assets have received more attention, whether these are archives and special collections, or newly generated research and learning materials (eprints, data, courseware, digital scholarly resources). In some ways, it is interesting seeing the ‘new’ and the ‘old’ come together in this way. Each is a distinctive contribution of the institution; each is the institution’s responsibility to preserve to the extent it wishes; each involves discussion and construction of a metadata and repository apparatus; each involves engagement with learning and research practice in new ways; each brings to the fore historically the archival concerns of provenance, authenticity, context, … In some ways, it is getting easier to see new scholarly and learning outputs as forming significant ‘special collections’ in the future.
Anyway, I thought it was interesting how OSU clustered and highlighted the ‘unique’ in this way. The second example is similar in that it highlights a particular area of collections, but it is a rather different one …
I was interested to see the University of Indiana at Bloomington highlight **top recommended resources** on its home page …
[](https://www.libraries.iub.edu/?ref=lorcandempsey.net)
We know from various studies that some resources are very popular, but also that there may not be student recognition that they are provided by the library. They are just there, on the network. At the same time, many library websites may still have long lists of resources, favoring completeness and neutrality over convenience and recommendation. This may be changing as metasearch or contextualization through course pages, [LibGuides](https://www.springshare.com/libguides/?ref=lorcandempsey.net), or other similar approaches becomes more common.
In this context, I thought it was nice that the library here clearly foregrounded a central set of resources and associated itself with them through a **recommendation**.
And finally, I notice that the Indiana [website](https://www.libraries.iub.edu/?ref=lorcandempsey.net) has an ‘ask a librarian’ box beside the upper central search box. There is a picture of a librarian beside the search box, which changes on each visit. I was looking at the [University of Washington library site](https://www.lib.washington.edu/?ref=lorcandempsey.net) a while ago, and also noticed a box inviting reader to ‘talk’ with a librarian; it too had a picture of a librarian beside it. It is nice to see the people 😉
Update: I notice a [list](https://trilogy.brynmawr.edu/guides/index.php?ref=lorcandempsey.net) of the ‘most popular’ databases at the [Tri-colleges Subject Portal](https://trilogy.brynmawr.edu/guides/index.php?ref=lorcandempsey.net).
### Concentration and diffusion again
URL: https://www.lorcandempsey.net/concentration-and-diffusion-again/
Last updated: 2020-10-28T09:16:44.000Z
From the Financial Times:
> According to Microsoft research chief Rick Rashid, around 20 per cent of all the servers sold around the world each year are now being bought by a small handful of internet companies – he named Microsoft, Google, Yahoo and Amazon. That is an amazing statistic, and certainly not one I’d heard before. And this is before cloud computing has really caught on in a big way. \[[FT.com | Tech Blog | How many computers does the world need?](https://blogs.ft.com/techblog/2009/03/how-many-computers-does-the-world-need/?ref=lorcandempsey.net)\]
I found this via [Nick Carr](https://www.roughtype.com/archives/2009/03/the%5Fcoming%5Fof%5Ft.php?ref=lorcandempsey.net) who goes on to say:
> What we’re seeing is the first stage of a rapid centralization of data-processing power – on a scale unimaginable before. At the same time, of course, the computing power at the edges, ie, in the devices that we all use, is also growing rapidly. An iPhone would have qualified as a supercomputer a few decades ago. But because the user devices draw much of their functionality (and data) from the Net, it’s the centralization trend that’s the key one in reshaping computing today. \[[Rough Type: Nicholas Carr’s Blog: The coming of the megacomputer](https://www.roughtype.com/archives/2009/03/the%5Fcoming%5Fof%5Ft.php?ref=lorcandempsey.net)\]
I [wrote a while ago](https://blog.oclc.org/lorcand/archives/001556.html?ref=lorcandempsey.net) about Web 2.0 in the context of *concentration* and *diffusion*.
Here is the pattern again. We are seeing a progressive diffusion of computational and communications capacity as we acquire more devices (netbooks, gaming consoles, phones,…). At the same time we see a concentration of computational capacity to support the major network services which are so large a part of .our network experience.
### Needs, wants and expertise
URL: https://www.lorcandempsey.net/needs-wants-and-expertise/
Last updated: 2020-10-28T09:16:46.000Z
I came across Frank Kermode’s 1995 obituary of JB Trapp, scholar and librarian of the Warburg Institute before becoming its director, recently, while looking for something else. I have bolded some phrases which seem to me to be a quite nice statement of purpose.
> The library of the institute, as arranged by founder Aby Warburg, was intended to obey what he called “the law of the good neighbour”. He believed that it must provide its users **not with the books they were looking for, but with the books that they needed, without necessarily having prior knowledge of them**. As librarian, Trapp made this quixotic pursuit quite rational; he knew where everything was and led one to it with the speed and penetration of the rugby player he had once been. \[[JB Trapp | Obituaries | guardian.co.uk](https://www.guardian.co.uk/obituaries/story/0,3604,1536581,00.html?ref=lorcandempsey.net)\]
I was reminded of a note I did a while ago about personal knowledge of collections and readers, and of some parallels with modern recommender systems. It seems to me that one of the major challenges libraries have over the next while relates to how they manifest expertise in their online services and presence, how the system emulates the “good neighbour” or knowledgeable library colleague.
> I worked many years ago in public libraries in Dublin, at a time, I reluctantly acknowledge, when [circulation systems](https://blog.oclc.org/lorcand/archives/001200.html?ref=lorcandempsey.net) were manual. I remember admiring the knowledge of those who had worked for a long time in branches, knowledge of their stock and knowledge of their readers. It seemed to me that they best understood the secret lives of books, as represented by the people who read them. The very best understood as well the secret lives of their readers, as represented by the books they read. They could make the types of connections that we are now seeing automated as ‘intentional data’ is collected and mined, in social networking sites, and in recommender systems. \[[Lorcan Dempsey’s weblog: What the reader intends …](https://blog.oclc.org/lorcand/archives/001523.html?ref=lorcandempsey.net)\]
Worldcat Identities:
[Frank Kermode](https://worldcat.org/identities/lccn-n80-126228?ref=lorcandempsey.net)
[JB Trapp](https://worldcat.org/identities/lccn-n77-17481?ref=lorcandempsey.net)
[Warburg Institute](https://www.worldcat.org/identities/lccn-n50-46134?ref=lorcandempsey.net)
[Warburg Institute Library](https://www.worldcat.org/identities/lccn-n50-46135?ref=lorcandempsey.net)
[Dublin City Public Libraries](https://worldcat.org/identities/lccn-nr2006-2457?ref=lorcandempsey.net)
### A multiscale catalog
URL: https://www.lorcandempsey.net/a-multiscale-catalog/
Last updated: 2020-10-28T09:16:47.000Z
From the Worldcat Local implementation at the University of Washington:

The user can telescope between institution, consortium and Worldcat.
I am not sure that ‘telescope’ is the right word here 😉
**Aside**: As we know we have different access models for stuff in journals and stuff normally found in the catalog. There is one distinction that I would expect to see more made of in the discussions around ‘next generation catalogs’. Think of the ‘available collection’ (what is published) and the local collection (what is held/licensed locally). With A&I databases we offer some subset of the ‘available collection’ and then offer some fulfillment options including access to a copy in the local collection if available. With the catalog, we typically offer the ‘local collection’ only, maybe with some links to ‘other catalogs’. Except in the very largest libraries, the catalog is not a general discovery tool. So users will naturally do their books/music/dvd/etc discovery activity elsewhere?
### Levels of amplification
URL: https://www.lorcandempsey.net/levels-of-amplification/
Last updated: 2020-10-28T09:16:49.000Z
I was very aware of the UKRDS conference this week as it left many traces in my network environment. It discussed aspects of data curation and reuse in a national context. I was interested to see these three blog reports, covering the same event with very different levels of immediacy. Here they are, getting progressively more immediate as you move down the list …
1. [Recollected in tranquility](https://hangingtogether.org/?p=633&ref=lorcandempsey.net) – John MacColl
2. [Narrative contemporary blog reporting](https://digitalcuration.blogspot.com/2009/02/ukrds-session-4.html?ref=lorcandempsey.net) – Chris Rusbridge
3. [Coveritlive-based blow by blow liveblogging](https://efoundations.typepad.com/livewire/2009/02/a-national-research-data-service-for-the-uk.html?ref=lorcandempsey.net) – Andy Powell
Both John and Andy refer to differences between librarians and researchers in terms of expectation.
> This meeting in some ways acted as a venue for a dialogue between these two camps – librarians and those who supported library support-like national services, on the one hand, and specialist researchers and their support services on the other. \[[Hangingtogether.org](https://hangingtogether.org/?p=633&ref=lorcandempsey.net)\]
### Tile and organizational evolution
URL: https://www.lorcandempsey.net/tile-and-organizational-evolution/
Last updated: 2020-10-28T09:16:51.000Z
A [set of documents](https://www.sero.co.uk/jisc-tile-deliverables.html?ref=lorcandempsey.net) from the [TILE project](https://www.sero.co.uk/jisc-tile.html?ref=lorcandempsey.net) has appeared.
TILE continues the [work](https://www.sero.co.uk/jisc-lms.html?ref=lorcandempsey.net) that was done by this group on the ILS last year. It extends this work by looking at library systems and services in broader contexts. In particular it looks at the library in the context of Web 2.0 and of service frameworks.
And – full disclosure – I was pleased to see their use of the [Concentration/Diffusion idea](https://blog.oclc.org/lorcand/archives/001556.html?ref=lorcandempsey.net) as a way of talking about Web 2.0, and their use of the [modeling work](https://www.dlib.org/dlib/july06/lavoie/07lavoie.html?ref=lorcandempsey.net) of the DLF group on service frameworks.
I have not yet digested the full range of material they provide. On first impression, what I like about the approach is that it lifts the discussion very explicitly out of the single institution. It is clear that an institution-scale approach is not appropriate for various of the issues of working in a network environment. They then suggest a way of thinking about systemwide activities in a simple framework which makes quite a bit of sense (whatever about the choice of labels). They also take a ‘business’ approach, rather than a purely technical one. By this I mean that they are concerned about how resources are organized to achieve goals, which touches on issues of boundaries, roles, incentives, different models of resource allocation, …. The report does not simply talk about existing organizations making changes at the edges; it looks at systemic change across a range of players to adapt to modes of service more appropriate to a web environment.
This is only a first look, and I haven’t looked at those parts where I may be initially less interested. And I find the higher level discussion and framework more interesting than the e-framework style decomposition of processes/services which I think is probably somewhat premature.
Two more general points also struck me as I was glancing through the materials …
The first is that it will be interesting to observe what sort of organizational evolution there is as a result of TET (tough economic times). One can imagine more focused attention on collaborative structures to increase shared capacity, reduce costs and improve local effectiveness. There may also be greater willingness to outsource some activity to commercial partners. These trends will likely be reinforced by a focus on distinctive local impact. However, this in turn suggests the need for some broad agreements on what types of activity might move into shared environments (infrastructure, which tends to be common makes sense here, as does the management of shared print collections), and also organizational frameworks to channel shared activity efficiently. On the former, it will be interesting to see how many more libraries move to hosted ILS or repository environments for example, or move to shared systems environments within broader groupings. On the latter, we are likely to see some rationalization of existing organizations and the emergence of new ones (see the context for the Hathi Trust for example).
This prompts a second point about international differences. Reading the TILES material, as well as working for an international organization like OCLC, is to be reminded of the often very different scalar emphasis in different geographies. This report is written in a UK educational environment where national-scale activity is strong, through publicly funded education infrastructure and services. JISC, for example, has provided a national research network, national authentication services, national data centres, national advisory services, national content licensing services, and a range of other national infrastructure and support services. There is a natural propensity for institutions here to look to a national apparatus to move things along. And of course there are national union catalogue or library infrastructure services in many countries. The US is a much more decentralized environment, and national-scale activity is less strong. However, there may be a strong state presence (think of OhioLink here in Ohio) or there may be quite a lot of activity through consortia of various types, but this is variable and libraries are variably bound into larger groupings for these types of shared services.
### One big index: Google Scholar in Google
URL: https://www.lorcandempsey.net/one-big-index-google-scholar-in-google/
Last updated: 2020-10-28T09:16:52.000Z
Google Books results in searches on big Google are common (in my experience, anyway). I hadn’t noticed before, however, what appear to be Google Scholar results mixed in. I am sure they have been there, I just haven’t seen them.
[](https://www.dlib.org/dlib/april06/dempsey/04dempsey.html?ref=lorcandempsey.net)
I still continue to be surprised when people talk about what Google can and can’t do, as they continue to be able to do more as the volume and variety of data they have grows.
### A Columbus triangle
URL: https://www.lorcandempsey.net/a-columbus-triangle/
Last updated: 2020-10-28T09:16:54.000Z
I appear to live near the middle of a triangle whose corners are the offices of LibLime, OCLC and OhioLINK 😉

### How many friends have you got?
URL: https://www.lorcandempsey.net/how-many-friends-have-you-got/
Last updated: 2020-10-28T09:16:57.000Z
The Economist has an [article about social networks](https://www.economist.com/science/displaystory.cfm?story%5Fid=13176775&ref=lorcandempsey.net) in the current issue. It introduces the Dunbar Number, the number of people we can comfortably network with. This turns out to be 150\. Dr Marlow, Facebook’s ‘inhouse sociologist’ found that the average Facebook user has 120 friends, although the range is large and women typically have more than men.
> Thus an average man–one with 120 friends–generally responds to the postings of only seven of those friends by leaving comments on the posting individual’s photos, status messages or “wall”. An average woman is slightly more sociable, responding to ten. When it comes to two-way communication such as e-mails or chats, the average man interacts with only four people and the average woman with six. Among those Facebook users with 500 friends, these numbers are somewhat higher, but not hugely so. Men leave comments for 17 friends, women for 26\. Men communicate with ten, women with 16.
> What mainly goes up, therefore, is not the core network but the number of casual contacts that people track more passively. This corroborates Dr Marsden’s ideas about core networks, since even those Facebook users with the most friends communicate only with a relatively small number of them.
> Put differently, people who are members of online social networks are not so much “networking” as they are “broadcasting their lives to an outer tier of acquaintances who aren’t necessarily inside the Dunbar circle,” says Lee Rainie, the director of the Pew Internet & American Life Project, a polling organisation. Humans may be advertising themselves more efficiently. But they still have the same small circles of intimacy as ever. \[[The size of social networks | Primates on Facebook | The Economist](https://www.economist.com/science/displaystory.cfm?story%5Fid=13176775&ref=lorcandempsey.net)\]
I was reminded of a study of patterns of interaction on Twitter reported in First Monday a while ago ..
> In conclusion, even when using a very weak definition of “friend” (i.e., anyone who a user has directed a post to at least twice) we find that Twitter users have a very small number of friends compared to the number of followers and followees they declare. This implies the existence of two different networks: a very dense one made up of followers and followees, and a sparser and simpler network of actual friends. The latter proves to be a more influential network in driving Twitter usage since users with many actual friends tend to post more updates than users with few actual friends. On the other hand, users with many followers or followees post updates more infrequently than those with few followers or followees. \[[Social networks that matter. Huberman et al. First Monday](https://firstmonday.org/htbin/cgiwrap/bin/ojs/index.php/fm/article/view/2317/2063?ref=lorcandempsey.net)\]
These studies are interesting. In one way they are a little misleading though: Facebook – or Twitter – is not the sum of our network lives. That said, it would be interesting to see something which compares to what extent patterns of interconnection are similar across different communication platforms: RSS, mail, FB, Twitter, face to face, ….
### Indiana tags, books, cloud
URL: https://www.lorcandempsey.net/indiana-tags-books-cloud/
Last updated: 2020-10-28T09:16:58.000Z
Indiana University Bloomington Libraries has a nicely produced [Annual Report](https://www.indiana.edu/~libadmin/annual/2008/index.html?ref=lorcandempsey.net) on the web. We are growing used to seeing tag clouds used in various contexts. I was interested to see this page in the report …..

The report focuses emphasizes change, asking in its title “when does change become transformational?”.
I was interested in their note about their participation in the Google digitization program:
> Indiana’s renowned Folklore and Ethnomusi-cology Collection, assembled over decades and valuable for its completeness, is also the first “collection of distinction” recognized by Google as a collection that will retain its coherence in the digital transition. \[[Indiana University Bloomington Libraries 2007-08 Annual Report](https://www.indiana.edu/~libadmin/annual/2008/a%5Fspike.html?ref=lorcandempsey.net)\]
I had not come across the suggestion that Google would be looking at maintaining whole collection integrity in this way before. It would be interesting to see a list of the collections that will be treated in this way.
### Copyright evidence registry
URL: https://www.lorcandempsey.net/copyright-evidence-registry/
Last updated: 2020-10-28T09:17:02.000Z
I was talking to my colleague Bill Carney earlier, who manages the Copyright Evidence Registry initiative, as well as our work to synchronize Worldcat with Google and other digitization initiatives.
> OCLC has launched a pilot to explore the feasibility of building a cooperatively created and maintained repository of copyright evidence. Based on WorldCat, which contains more than 100 million bibliographic records describing items held in thousands of libraries worldwide, the Copyright Evidence Registry uses data contributed by libraries and other organizations participating in the pilot. Those participating in the pilot are using the Copyright Evidence Registry to find information about a book, learn what others have said about its copyright status, and share what they know. Pilot participants include libraries, individuals, OCLC and other organizations collaborating to contribute data and build the repository. \[[WorldCat® Copyright Evidence Registry \[OCLC\]](https://www.oclc.org/productworks/cer.htm?ref=lorcandempsey.net)\]
The project has just released a rules engine to pilot participants:
> … pilot participants will be able to create and run automated copyright rules that conform to their institution’s standards for determining copyright status. The rules will help you analyze the information available in the Copyright Evidence Registry and form your own conclusions about copyright status. \[[WorldCat® Copyright Evidence Registry \[OCLC\]](https://www.oclc.org/productworks/cer.htm?ref=lorcandempsey.net)\]
Here is an [example of an entry](https://www.worldcat.org/copyrightevidence/registry/1175455?ref=lorcandempsey.net) (look under the ‘copyright details’ tab for contributed data).
### Assisted thinking ..... and assisted reading
URL: https://www.lorcandempsey.net/assisted-thinking-and-assisted-reading/
Last updated: 2022-11-08T18:30:12.000Z
As we are in a period which encourages sustained reflection on direction, structure, and value it is not surprising to see an upsurge in the volume of ‘assisted thinking’ that is now available …
In a US context, CLIR, Ithaka, ARL and other organizations regularly release weighty reports. And, yes, I have pointed to several recent reports from OCLC Research and the RLG Partnership in these pages. More generally, Pew reports appear regularly. And for those willing to pay, Gartner, Outsell, or others, will provide assisted thinking in conveniently short documents.
The UK academic community is particularly well-served in this regard, as JISC, the Research Information Network, and others, regularly commission reports to assist thinking about information management, changing research and learning behaviors, and other topics. Indeed, Neil Beagrie also wondered about impact a while ago, as he noted just how many JISC reports were being published and pointed to a list of the most downloaded:
> JISC is quite a large specialist publisher: there have been 28 [JISC Reports ](https://www.jisc.ac.uk/publications/browsetypes/reports.aspx?ref=lorcandempsey.net)and 24 [JISC Briefing Papers ](https://www.jisc.ac.uk/publications/browsetypes/briefing.aspx?ref=lorcandempsey.net)published in 2008 alone so far, so there is stiff competition to get into the listings and I was chuffed to see Keeping Research Data Safe at No. 3\. \[[Neil Beagrie’s Blog » Blog Archive » and the Top Five are…](https://blog.beagrie.com/2008/12/04/and-the-top-five-are/?ref=lorcandempsey.net)\]
Luckily, reading opportunities may not yet have exceeded available reading time; however, I wonder if writing opportunities exceeded available expertise a while ago.
Now, these materials are variously targeted at assisted understanding, assisted decision-making, assisted planning, and so on. Some are illuminating, and occasionally something seminal comes along; in some cases, the consultants clearly got lucky.
I tend to track these publications as much as the next person. Lately though, I have been feeling that there is a market for a version of Pierre Bayard’s *[How to talk about books you haven’t read](https://www.worldcat.org/oclc/154677642?ref=lorcandempsey.net)* for those of us who do not want to let on about how far behind we are in our reading ….
Note: link to Neil’s blog post via my colleague Brian Lavoie, who is a co-author of the [Keeping research data safe](https://www.jisc.ac.uk/publications/publications/keepingresearchdatasafe.aspx?ref=lorcandempsey.net) report Neil mentions. One of the better ones 😉
### A note on Google Book Search
URL: https://www.lorcandempsey.net/a-note-on-google-book-search/
Last updated: 2022-11-08T18:31:52.000Z
Robert Darnton’s plangent [discussion](https://www.nybooks.com/articles/22281?ref=lorcandempsey.net) of the proposed Google Book Search agreement in the New York Review of Books was widely noticed. In particular, I was interested to read comments from the different perspectives of [Paul Courant](https://paulcourant.net/2009/02/04/google-robert-darnton-and-the-digital-republic-of-letters/?ref=lorcandempsey.net) (University Librarian and Dean of Libraries at the University of Michigan, a major partner in the Google enterprise and a pioneer in creating and managing digital collections) and [Tim O’Reilly](https://radar.oreilly.com/2009/01/competition-in-the-ebook-marke.html?ref=lorcandempsey.net) (who has helped shape our view of the current network environment, and proponent of the interesting view that [book search should be like web search](https://radar.oreilly.com/archives/2006/12/book-search-sho.html?ref=lorcandempsey.net)).
The issues raised across these contributions are major and
Note: check out Robert Darnton’s [Worldcat Identities page](https://worldcat.org/identities/lccn-n82-20431?ref=lorcandempsey.net).
### Decentering and recentering: the TV/PC and the network
URL: https://www.lorcandempsey.net/decentering-and-recentering-the-tv-pc-and-the-network/
Last updated: 2020-10-28T09:17:12.000Z
A couple of interesting articles on how the network is changing patterns of media consumption appear back-to-back in the current issue of *The Atlantic*. They prompt an observation about networking and the home.
Here is James Parker on the phenomenon that is *Guitar Hero* and *Rock Band*:
> Both franchises, however, rely on pretty much the same business model: after buying the game, its “peripherals” (guitar, drums, etc.), and a bundle of songs, the consumer then purchases extra songs at about two bucks a pop in the game’s online store. … Weezer’s “My Name Is Jonas,” first released in 1994, reportedly increased its sales tenfold after being featured in Guitar Hero III. Rock Band currently has a library of about 500 songs; since its launch, there have been more than 28 million downloads. \[[School of Rock – The Atlantic (March 2009)](https://www.theatlantic.com/doc/200903/guitar-hero?ref=lorcandempsey.net)\]
And here is Michael Hirschorn writing about the changing profile of network television …
> Speaking at a screenwriter expo in Los Angeles, Tim Kring struggled to defend his sci-fi-tinged show, which has endured two seasons of faltering ratings. *Heroes* is presented in a serialized format, meaning that stories “arc” over the course of an entire season rather than conclude at the end of each episode, as in a sitcom, or a police procedural such as *[CSI](https://www.cbs.com/primetime/csi/?ref=lorcandempsey.net)* or *[Law & Order](https://www.nbc.com/Law%5Fand%5FOrder/?ref=lorcandempsey.net)*. The serialized format is “a very flawed way of telling stories on network television right now,” [a blogger quoted Kring](https://www.tvweek.com/news/2008/11/adalian%5Fcolumn%5Fblack%5Fthursday.php?ref=lorcandempsey.net) as saying, “because of the advent of the DVR and online streaming. The engine that drove \[serialized TV\] was, you had to be in front of the TV \[when it aired\]. Now you can watch it when you want, where you want, how you want to watch it, and almost all of those ways are superior to watching it on-air.” \[[The Future Is Cheese – The Atlantic (March 2009)](https://www.theatlantic.com/doc/200903/television?ref=lorcandempsey.net)\]
In each case, the network is a central part of the described behaviours. In our own household we reckon we reached a tipping point some time last year, which was then intensified by Christmas gifts 😉
The significant shift was that the fixed congregation points (TV and Computer) have been decentred. The network is now central, and this connects various services, experiences and devices internally and to services in the cloud.
So, like others, we have various devices which routinely depend on the network: PC/netbook, playstation, iTouch, xBox, DVR, … And a growing number of applications which depend on the network: Skype, xBox Live, streaming video from Netflix, as well as the range of web-based communication and services.
This means that any disruption to the network causes havoc: our lives become pale reflections of their full networked reality. It also creates irritating challenges as we want to be able to mobilize ‘content’ and ‘experiences’ across different home environments. There is nothing special about our situation; in fact, we are variably maladroit at getting stuff to work at all, let alone well, … 😉
We increasingly expect everything to be connected ….
Note: we tried playing FIFA09 some time ago using Rock Band instruments as controllers. It was interesting for a few moments only, but was a nice lesson in ‘affordances’.
Note: I fear that I cannot shake my anachronistic habit of talking about ‘taping’ TV programs on the DVR …
### Books about universities
URL: https://www.lorcandempsey.net/books-about-universities/
Last updated: 2020-10-28T09:17:13.000Z
Many of the pages in Worldcat Identities are for corporate authors, [Ohio State University](https://www.worldcat.org/identities/lccn-n79-46205?ref=lorcandempsey.net), for example.
It is interesting in these cases to see what the most widely held items about the institution in question are. Here are some examples from universities …..
So, the [list of most widely held items about](https://www.worldcat.org/identities/lccn-n79-46205?ref=lorcandempsey.net#linkworksabout) Ohio State University, maybe not unsurprisingly, has a strong football flavor. Quite a few universities have strong sporting coverage.
Thinking along these lines, I tried Notre Dame, only to discover that the [list](https://www.worldcat.org/identities/lccn-n79-22791?ref=lorcandempsey.net#linkworksabout) is dominated by mystery novels by [Ralph McInerny](https://www.worldcat.org/identities/lccn-n79-18057?ref=lorcandempsey.net).
Where an institution figures centrally in a popular work of fiction, it may not be surprising to see it in the list, although it might not be what immediately comes to mind. So, [E.M. Forster](https://www.worldcat.org/identities/lccn-n79-91231?ref=lorcandempsey.net)‘s posthumously published Maurice is recorded as the most widely held work about the University of Cambridge. There are also two writers of mysteries set in Cambridge on [the list](https://www.worldcat.org/identities/lccn-n79-18862?ref=lorcandempsey.net#linkworksabout): [Jill Paton Walsh](https://www.worldcat.org/identities/lccn-n50-80396?ref=lorcandempsey.net) and [Susanna Gregory](https://www.worldcat.org/identities/lccn-n96-57522?ref=lorcandempsey.net).
This prompted me to go looking for Inspector Morse in the [University of Oxford](https://www.worldcat.org/identities/lccn-n79-95521?ref=lorcandempsey.net#linkworksabout) page, but did not find him. The two books by [John Bayley](https://www.worldcat.org/identities/lccn-n50-5533?ref=lorcandempsey.net) about his wife [Iris Murdoch](https://www.worldcat.org/identities/lccn-n80-13587?ref=lorcandempsey.net) feature in the top four, as does a novel by [Alan Hollinghurst](https://www.worldcat.org/identities/lccn-n86-822799?ref=lorcandempsey.net), *The line of beauty*.
Maybe predictably, [Humphrey Carpenter](https://www.worldcat.org/identities/lccn-n80-1545?ref=lorcandempsey.net)‘s book about the Inklings ([Tolkein](https://www.worldcat.org/identities/lccn-n79-5673?ref=lorcandempsey.net), [Lewis](https://www.worldcat.org/identities/lccn-n79-3974?ref=lorcandempsey.net) and colleagues) is also in the Oxford top four. [Cardinal Newman](https://www.worldcat.org/identities/lccn-n78-95501?ref=lorcandempsey.net) figures strongly in the [University College Dublin](https://www.worldcat.org/identities/lccn-n50-27617?ref=lorcandempsey.net) list, which is headed by a book about [Gerard Manley Hopkins](https://www.worldcat.org/identities/lccn-n80-32727?ref=lorcandempsey.net), but interestingly [Joyce](https://www.worldcat.org/identities/lccn-n79-56824?ref=lorcandempsey.net) does not figure. There are a couple of books about [Condoleeza Rice](https://www.worldcat.org/identities/lccn-n82-242801?ref=lorcandempsey.net) in the top five at [Stanford](https://www.worldcat.org/identities/lccn-n79-54636?ref=lorcandempsey.net#linkworksabout).
In some cases, particular events figure strongly near the top of the [list](https://www.worldcat.org/identities/lccn-n79-96729?ref=lorcandempsey.net#linkworksabout) as with the tragic shootings at Kent State University in 1970\. Events and cultural change in the 60s are well represented in books about several universities, including [Berkeley](https://www.worldcat.org/identities/lccn-n79-46084?ref=lorcandempsey.net#linkworksabout).
Sometimes, the most widely held item might not be something that the institution would have chosen. [E.P. Thompson](https://www.worldcat.org/identities/lccn-n78-89033?ref=lorcandempsey.net)‘s book on the [University of Warwick](https://www.worldcat.org/identities/lccn-n50-59535?ref=lorcandempsey.net#linkworksabout) is an example I came across. Two of the top five on MIT’s [list](https://www.worldcat.org/identities/lccn-n79-6591?ref=lorcandempsey.net#linkworksabout) are about the MIT students who famously went to Vegas.
I am not sure how much to take away from this superficial exploration, but here are a few random observations …
- Much depends on the vagaries of cataloguer/classifier activity.
- I was surprised not to find more scientists, although I did not look for very long (a book about [Rutherford](https://www.worldcat.org/identities/lccn-n50-24959?ref=lorcandempsey.net) is on top of the list at [Manchester](https://www.worldcat.org/identities/lccn-n80-126193?ref=lorcandempsey.net#linkworksabout)). The absence of women was also notable; I did come across some cases where a discussion about the status of women featured, [Oberlin](https://www.worldcat.org/identities/lccn-n79-99236?ref=lorcandempsey.net#linkworksabout) and [Cornell](https://www.worldcat.org/identities/lccn-n79-21621?ref=lorcandempsey.net#linkworksabout), for example.
- The web environment has made us very aware of how what is said by others about an institution is as readily available as what it says about itself. Maybe it was always thus, but less generally visibly? For many institutions, however, histories, lives of presidents, celebrations of various types, and other such materials were heavily represented. Just as, on the web, institutional materials will also feature strongly.
- I did not explore long enough or closely enough to develop a list of recurrent issues, but this would have been interesting (the influence of sports, the status of women in education, unrest in the sixties were examples that did surface).
- This is something of a time sink!
### M-libraries in Vancouver
URL: https://www.lorcandempsey.net/m-libraries-in-vancouver/
Last updated: 2020-10-28T09:17:16.000Z
I am looking forward to attending the second M-Libraries Conference in Vancouver in June. The [programme](https://m-libraries2009.ubc.ca/programme2.html?ref=lorcandempsey.net) has now appeared and the conference is open for registration.
Although mobile communications raise specific questions, more generally it represents the further diffusion of computational and networking capacity through our lives. I have quoted from the [piece](https://firstmonday.org/htbin/cgiwrap/bin/ojs/index.php/fm/article/view/2291/2070?ref=lorcandempsey.net) I wrote for the proceedings of the first conference in these pages several times already. Here is the abstract ….
> Mobile communication has been more widely adopted more quickly than any other technology ever (Castells, et al., 2007). It represents a diffusion of communications and computational capacity into a growing part of our research, learning and social activities. It has resonated with emerging youth behavior, providing support for distinctive patterns of social interaction and group formation, information use and personal expression.
> Diffuse networking changes how we coordinate our resources to achieve goals. For example, our use of time and space changes. Timeshifting is routine as students may listen to or watch lectures in the gym or on the train. The use of space to support ad hoc rendezvous and social learning is becoming more important.
> As networking spreads, we have multiple connection points which offer different grades of experience (the desktop, cell phone, xBox or Wii, GPS system, smartphone, ultra-portable notebook, and so on). While these converge in various ways, they are also optimized for different purposes. A natural accompaniment of this mesh of connection points is a move of many services to the cloud, available on the network across these multiple devices and environments. This means that an exclusive focus on the institutional Web site as the primary delivery mechanism and the browser as the primary consumption environment is increasingly partial.
> Students are results-oriented and value convenience. This emphasis coupled with the design constraints on some devices promotes a need to get to relevance quickly. Socialization, personalization and location awareness become very important.
> Libraries have been working to develop network-ready services. Mobile communication intensifies this activity and adds new challenges as they look at what it means to be mobile-ready. This has organizational implications as a shift of emphasis towards workflow integration around the learner or researcher creates new relationships with other service organizations on campus. It also has implications for how space is used, for library skills, and for how collections are developed. We can see the impact of mobile communication on services in two ways. First, services may be made mobile-ready, as with special mobile interfaces for library services, alerting services, and so on. Second, mobilization continues the restructuring of services, organizations and attention that networking has brought about. Think here of how to socialize and personalize services; how to adapt to collection and service use which spans personal, institutional, and cloud environments; how to position and promote the library ‘brand’ as services become atomized and less ‘visible’ on the network; and more complex questions about what best to do locally and what to source with collaborative arrangements or third parties. \[[Always on: libraries in a world of permanent connectivity](https://firstmonday.org/htbin/cgiwrap/bin/ojs/index.php/fm/article/view/2291/2070?ref=lorcandempsey.net)\]
### Libraries and cultural resources at the University of Calgary
URL: https://www.lorcandempsey.net/libraries-and-cultural-resources-at-the-university-of-calgary/
Last updated: 2020-10-28T09:17:17.000Z
Tom Hickerson, Vice Provost, Libraries and Cultural Resources, and University Librarian, University of Calgary, visitied us last week together with several colleagues. He spoke about their ambitious plans for the new [Taylor Family Digital Library](https://tfdl.ucalgary.ca/?ref=lorcandempsey.net).
It was especially interesting to hear about the organizational structure within [Libraries and Cultural Resources](https://lcr.ucalgary.ca/?ref=lorcandempsey.net), which brings together several ‘memory organizations’ and the University Press, and their various professional expertises, around a shared mission.
> Libraries and Cultural Resources (LCR) brings together the University Library, Archives and Special Collections, The Nickle Arts Museum, and the UofC Press. LCR develops, preserves, and provides access to large collections of print, digital and three-dimensional objects, and archival materials. This unique organizational structure provides a key strategic advantage to researchers and makes information – regardless of format – readily available.
> LCR has a number of subject specialists including Subject Librarians, Special Collections Librarians, Archivists, and Curators. If you have any questions about collections or services, need assistance in accessing information from our collection or from the collections of other institutions, professionals in each of these areas are able to assist you. \[[Libraries and Cultural Resources](https://lcr.ucalgary.ca/?ref=lorcandempsey.net)\]
### Recording and disclosing print archiving commitments
URL: https://www.lorcandempsey.net/recording-and-disclosing-print-archiving-commitments/
Last updated: 2020-10-28T09:17:21.000Z
My colleague Constrance Malpas is inviting comments on the use of MARC Field 583 “to record and effectively disclose local print archiving commitments so that libraries might better judge the relative risk of local de-duplication efforts or, conversely, where maximum preservation benefit might be gained through a distributed archiving effort”.
The document is available [here](https://docs.google.com/Doc?id=dc2djpm6%5F46cbq4kfgd&ref=lorcandempsey.net) and is open for editing. Various inline comments appear.
### The centrality of the catalog?
URL: https://www.lorcandempsey.net/the-centrality-of-the-catalog/
Last updated: 2020-10-28T09:17:22.000Z
In listening to discussions about the library catalog, I am surprised not to hear more about how the type of library affects our assessment of how central the catalog is to library services or user behaviors.
For simplicity sake, think reductively of three categories of library material: bought, licensed and digital.
Bought materials (books, DVDs, CDs, …) are typically managed within the integrated library system workflow, are cataloged and appear in the library catalog.
Licensed materials (e-journals, databases, …) are typically managed within an emerging knowledge base/ERM/custom workflow, and appear to the user in a variety of databases, maybe consolidated through metasearch and resolver systems.
Digitized/digital materials (digitized collections, research and learning materials in repositories, …) are typically managed within a repository environment, and appear to the user through a user interface to that environment.
Newer discovery layers may try to provide access across these three strands (as well as others), and sometimes data or services will be syndicated to other environments (e.g. Google Scholar, toolbar/widget, etc).
The systems to provide access to these three collection types probably account for the vast majority of access traffic to library collections.
However, volume of access breaks down differently across types of libraries. Digital is probably a minority in most. The catalog may get more traffic than access mechanisms for licensed materials in many public libraries, quite a bit more in many cases. And access mechanisms for licensed materials may get more traffic than the catalog in many academic environments, quite a bit more in many cases.
It would be interesting to synthesise recent research findings to quantify this ….
Related link:
- [The catalogue in the new discovery environment](https://www.ariadne.ac.uk/issue48/dempsey/?ref=lorcandempsey.net)
### More on repositories and search engines
URL: https://www.lorcandempsey.net/more-on-repositories-and-search-engines/
Last updated: 2020-10-28T09:17:24.000Z
I [referenced](https://blog.oclc.org/lorcand/archives/001876.html?ref=lorcandempsey.net) a [note](https://efoundations.typepad.com/efoundations/2009/02/repository-usability.html?ref=lorcandempsey.net) by Andy Powell on institutional repositories and Google in an earlier post. Herbert Van de Sompel left a [comment](https://blog.oclc.org/lorcand/archives/001876.html?ref=lorcandempsey.net#comments) pointing to a [short document](https://public.lanl.gov/herbertv/papers/Repository%5FUsability.htm?ref=lorcandempsey.net) he has prepared addressing some of Andy’s concerns based on recent work with OAI-ORE. Here are a couple of the opening paragraphs ….
> This write-up is an impromptu response to Andy Powell\`s [Repository Usability](https://efoundations.typepad.com/efoundations/2009/02/repository-usability.html?ref=lorcandempsey.net) blog entry. It also touches on some issues that Andy raised in another entry, [Freedom, Google-juice and institutional mandates](https://efoundations.typepad.com/efoundations/2009/02/freedom-googlejuice-and-institutional-mandates.html?ref=lorcandempsey.net). The purpose of the write-up is to try and alleviate some of Andy\`s pain regarding the status quo of scholarly repositories: while the current situation may indeed not be perfect, a possible solution may not be too hard to establish. The solution I describe uses the [OAI-ORE](https://www.openarchives.org/ore/toc?ref=lorcandempsey.net) specifications, and quite some other techniques that have been introduced by several communities over the past years. Hey, a technological mash-up, one could say. Use and reuse what is there before inventing new stuff is the motto. I am afraid that the solution may cause Andy some phantom pain, since it also leverages [OAI-PMH](https://www.openarchives.org/OAI/openarchivesprotocol.html?ref=lorcandempsey.net). While [I agree that there are a few things we didn\`t get quite right with OAI-PMH](https://hangingtogether.org/?p=616&ref=lorcandempsey.net), I don\`t think it\`s the cause of all evil in the (repository) world, and I actually even think we can leverage the existing deployed PMH repositories for **a good cause**
> Anyhow, I think the [DSpace example](https://hdl.handle.net/1842/1476?ref=lorcandempsey.net) of Andy\`s blog entry is a nice one to have a close look at, indeed. The four URIs that are a source of frustration for Andy, are an indication to me that OAI-ORE Aggregations can come to the rescue. As a matter of fact, the [ORE Primer](https://www.openarchives.org/ore/1.0/primer?ref=lorcandempsey.net) uses an [arXiv example](https://arxiv.org/abs/astro-ph/0601007?ref=lorcandempsey.net) that is quite similar to the DSpace one: lots of URIs flying around that somehow belong together. \[[Repository Usability – Herbert’s Take](https://public.lanl.gov/herbertv/papers/Repository%5FUsability.htm?ref=lorcandempsey.net)\]
### QOTD: "the occasional young adult Christmas paranormal love story mystery"
URL: https://www.lorcandempsey.net/qotd-the-occasional-young-adult-christmas-paranormal-love-story-mystery/
Last updated: 2020-10-28T09:17:26.000Z
The [Public Lending Right](https://www.plr.uk.com/?ref=lorcandempsey.net) is a mechanism for distributing funds to authors based on circulation of their books in UK public libraries. It provides an interesting measure of popularity. The PLR has just released the [list](https://www.plr.uk.com/mediaCentre/mediaReleases/feb2009%281%29.pdf?ref=lorcandempsey.net) \[pdf\] of the highest circulating authors in 2007/2008\. [James Patterson](https://worldcat.org/identities/lccn-n78-86409?ref=lorcandempsey.net) is now the most circulated author. Before him it was [Jacqueline Wilson](https://worldcat.org/identities/lccn-n50-15537?ref=lorcandempsey.net) (now in second place), and before her it was [Catherine Cookson](https://worldcat.org/identities/lccn-n79-45994?ref=lorcandempsey.net), who was enormously popular for many years.
[Thom](https://outgoing.typepad.com/outgoing/?ref=lorcandempsey.net) links to the [Identities](https://worldcat.org/identities?ref=lorcandempsey.net) pages of the top authors in the list, and looking at the genres to which they contribute concludes like so:
> Looking at what these authors write, it’s easy to see what people read: mysteries, love stories, children’s books, mystery love stories, young adult mysteries, young adult love stories, and the occasional young adult Christmas paranormal love story mystery. \[[Outgoing](https://outgoing.typepad.com/outgoing/2009/02/popular-authors.html?ref=lorcandempsey.net)\]
### SEI - search engine interoperability
URL: https://www.lorcandempsey.net/sei-search-engine-interoperability/
Last updated: 2020-10-28T09:17:30.000Z
I have used the phrase *search engine interoperability* in these pages a [couple](https://blog.oclc.org/lorcand/archives/001810.html?ref=lorcandempsey.net) of [times](https://blog.oclc.org/lorcand/archives/001838.html?ref=lorcandempsey.net). This is a play on *search engine optimization*, which some do not like (although I think we should not avoid using a standard industry term). We value *interoperability* in libraries, and I think that a large part of SEO is, effectively, interoperability with search engines, where, to [repeat](https://blog.oclc.org/lorcand/archives/001838.html?ref=lorcandempsey.net) myself, interoperability means managing resources in ways which promote effective crawling, indexing and ranking by search engines.
In this context, I was very interested to read Andy Powell’s [critique](https://efoundations.typepad.com/efoundations/2009/02/repository-usability.html?ref=lorcandempsey.net) of ‘web usability’ in an institutional repository. He looks at how a particular document is presented and how that ‘plays’ with search engines in a web environment. Andy suggests that his experience here is probably broadly representative of this class of service, something I am not in a position to judge. He examines a range of features and concludes in this way …
> OK, I apologise… I’ve lapsed into sarcasm for effect. But the fact remains that repository jump-off pages are potentially some of the most important Web pages exposed by universities (this is core research business after all) yet they are nearly always some of the worst examples of HTML to be found on the academic Web. I can draw no other conclusion than that the Web is seen as tangential in this space. \[[eFoundations: Repository usability](https://efoundations.typepad.com/efoundations/2009/02/repository-usability.html?ref=lorcandempsey.net)\]
Update: Andy has a [followup entry](https://efoundations.typepad.com/efoundations/2009/02/repository-usability-take-2.html?ref=lorcandempsey.net) looking at a document in another institutional repository, using a different technical platform.
Update 2: There is an interesting [stream of comments](https://efoundations.typepad.com/efoundations/2009/02/repository-usability.html?ref=lorcandempsey.net#comments) on Andy’s first post.
### Configuration of data curation infrastructure
URL: https://www.lorcandempsey.net/configuration-of-data-curation-infrastructure/
Last updated: 2020-10-28T09:17:40.000Z
Further to my [remarks](https://blog.oclc.org/lorcand/archives/001874.html?ref=lorcandempsey.net) about Canadian research data curation of the other day, I was interested to read the following from Chris Rusbridge of the Data Curation Centre.
> It is clear that a national research data infrastructure is needed, but there are problems with all of the approaches taken so far to address this. Subject data centres provide subject domain curation expertise, but there are scalability issues across the domain spectrum: it appears unlikely that research funders will extend their funding to a much larger set of these data centres (indeed the AHDS experience might suggest a concern to cut back). Institutional data repositories are being explored, but while disclosing institutional data outputs might provide sustainability incentives, and such data repositories might be managed at a storage level by developments from existing institutional library/archive and IT support services, it is difficult to see how domain expertise can be brought to bear from so many domains across so many disciplines. Meanwhile, various of the studies done by UKOLN/DCC with Southampton University suggest the value of laboratory or project repositories in assisting with curation in a more localised context. \[[A national research data infrastructure?](https://digitalcuration.blogspot.com/2009/02/national-research-data-infrastructure.html?ref=lorcandempsey.net)\]
Chris wonders whether one approach would be to unbundle the process, localising data storage with the institution, department, laboratory or other organizational unit, and specialising data curation activities in a national apparatus which assembles relevant domain or subject expertise. Such expertise, he suggests, involves “aspects of appraisal, selection, retention, transformation, combination, description, annotation, quality etc”.
I assume, although Chris does not explicitly state it, that in this model the data storage responsibility assures continuity of access, but that it might be physically sourced in various ways (from a supercomputer center, for example).
This is an interesting arrangement, because it reverses what one might think to be a natural division of labor, where expertise is localised and more generic infrastructure externalised to specialist providers.
Chris suggests that national provision may not extend across the full range of subjects, but also notes that local curation expertise does not scale well given the range of institutional disciplinary interests.
I don’t pretend to know how this type of infrastructure will eventually be provided, and at this stage it is reasonable to be working through various options. The discussion in the recent interim report of the [Blue Ribbon Task Force on Sustainable Digital Preservation and Access](https://brtf.sdsc.edu/?ref=lorcandempsey.net), of which Chris is a member, has some useful background material in this context.
What I found especially interesting about Chris’s post, though, was the assumption that approaches would have to be multi-scalar in organizational and resourcing terms. (I realise that Chris is talking about how well expertise can scale above, rather than the organizational scale I have in mind here.)
We are increasingly aware that the individual institution is not the best level for many activities. Discovery, for example, is increasingly web-scale in practice, as search engines and other large aggregations support search and discovery of materials. In some cases, national scale activity is plausible, where there is a public funding context for this. Chris’s own organization for example is part of a national apparatus of support for research and learning, provided by JISC and other organizations. This can give discussions in the UK, say, a more strongly **national** flavor than they might have, say, in the US. In a related context, [The Hathi Trust](https://www.hathitrust.org/?ref=lorcandempsey.net) is an example of infrastructure collaboratively sourced within a consortial arrangement.
Of course, multi-scalar planning can get complicated ….
### Name authorities, crowdsourcing, and Máire Mhac an tSaoi
URL: https://www.lorcandempsey.net/name-authorities-crowdsourcing-and-maire-mhac-an-tsaoi/
Last updated: 2020-10-28T09:17:42.000Z
I was sad to read of the death of Conor Cruise O’Brien \[[Wikipedia](https://en.wikipedia.org/wiki/Conor%5FCruise%5FO'Brien?ref=lorcandempsey.net), [Worldcat Identity](https://worldcat.org/identities/lccn-n50-43483?ref=lorcandempsey.net)\] before Christmas. See the [obituary](https://www.timesonline.co.uk/tol/comment/obituaries/article5372017.ece?ref=lorcandempsey.net) in *The Times* and John Naughton’s [note](https://memex.naughtons.org/archives/2008/12/23/5902?ref=lorcandempsey.net) for context.
O’Brien was the husband of Máire Mhac an tSaoi, noted scholar, writer and poet in the Irish language. Mhac an tSaoi is known under various permutations of English/Irish and married/original versions of her name(s). Here is how she describes herself in a chronology attached to her autobiography, [*The same age as the state*](https://www.worldcat.org/oclc/57039076/editions?editions&ref=lorcandempsey.net) (where she writes as Máire Cruise O’Brien).
> Máire Cruise O’Brien (nee Máire MacEntee, in Irish (Gaelic) Máire Mhac an tSaoi, under which name she publishes in that language)
Here is the LC data as given in the [VIAF entry](https://orlabs.oclc.org/viaf/LC|n86102319?ref=lorcandempsey.net). Interestingly, the preferred form is Máire O’Brien, and a search in the [Library of Congress catalog](https://catalog.loc.gov/webvoy.htm?ref=lorcandempsey.net) will lead you to “O’Brien, Máire, 1922-“.
[](https://orlabs.oclc.org/viaf/LC|n86102319?ref=lorcandempsey.net)
Now, in reading the obituaries of Conor Cruise O’Brien, I was interested to see the form “Máire Mac an tSaoi” used, which is not a version given in the LC authority file. (It differs in that it has ‘Mac’ rather than ‘Mhac’.) Checking elsewhere, I notice that this is also the form used in the review of recent Irish history by Roy Foster, *[Luck & the Irish: a brief history of change 1970-2000](https://www.worldcat.org/oclc/173749429?ref=lorcandempsey.net)*. (Incidentally, John Naughton speculates above that Foster may be the author of the Times obituary mentioned above.)
I also notice that WorldCat shows this form of the name for [one item](https://www.worldcat.org/oclc/16550767?ref=lorcandempsey.net), *An galar dubhach*, but this may be a mistake as it is shown as Máire Mhac an tSaoi in the National Library of Ireland (in which catalog, incidentally, Máire Mhac an tSaoi is the preferred form) and in the [British Library](https://catalogue.bl.uk/F/GSLH1JYYU2PDFFFV3674GFQ6DIIHHDLS4U32EHK5K9PASNMEL9-16346?func=full-set-set&set%5Fnumber=151051&set%5Fentry=000001&format=001&ref=lorcandempsey.net) (where Máire O’Brien is the preferred form).
Now, I have forgotten, or more likely may never have known, what one might expect here (‘Mhac’ or ‘Mac’) or why the masculine ‘Mac’ is being used (see the [Wikipedia article](https://en.wikipedia.org/wiki/Irish%5Fname?ref=lorcandempsey.net) on Irish names for an explanation of this point), and I don’t know what choices Máire Mhac an tSaoi may have made about her name. I have made some limited inquiries but have not researched the issue in any depth.
Anyway, all of this is prelude to the point I want to make. LC and national libraries around the world create authorities data. There may be collaborative structures like [NACO](https://www.loc.gov/catdir/pcc/naco/nacopara.html?ref=lorcandempsey.net) to support this.
These types of service seem remarkably well-suited to social approaches. Once I came across several examples of ‘Mac an tSaoi’ and discovered that it was not recorded in any authority file, I thought that it would be nice to make that known to LC or the National Library of Ireland or the BL or … However, I have no way of easily doing that which seems a shame. Authorities work – and think NACO here – is a professional activity, hedged around by rules and procedures; it is after all ‘authorities’ work. However, it would seem sensible to open it up to suggestion and information.
[](https://www.worldcat.org/oclc/57039076?ref=lorcandempsey.net)
Incidentally, [Worldcat Identities](https://www.worldcat.org/identities?ref=lorcandempsey.net), which is programmatically built on top of authorities and bibliographic data does not handle Máire Mhac an tSaoi very well with entries split across several versions of her name and combining her work with some others. This is a good example of why we are working on approaches to allow readers to suggest splitting or merging of Identities.
### A signed network presence: people as entry points again
URL: https://www.lorcandempsey.net/a-signed-network-presence-people-as-entry-points-again/
Last updated: 2020-10-28T09:17:44.000Z
The phrase ‘people are entry points’ has stayed in my mind since I heard Dan Chudnov use it at a meeting a while ago. It tends to occur to me also when I read, as I just have, documents which talk about ‘providers’ and ‘users’ of information, as in many of our more interesting services these roles mingle. Here is something I wrote a while ago on this ..
> People connect and share themselves through ‘social objects’ (music, photos, video, links, or other shared interests) and it has been argued that successful social networks are those which form around such social objects. We are becoming used to selective disclosure and selective socialization through affinity groups within different social networks. Together, these experiences have created an interesting expectation: many network resources are ‘signed’ in the sense that they are attached to online personas that we may or may not know, whose judgment and network presence we may come to know. Think of social bookmarking sites or Amazon reviews, for example. People are resources on the network, and have become entry points and connectors for others. \[First Monday. [Always on](https://firstmonday.org/htbin/cgiwrap/bin/ojs/index.php/fm/article/view/2291/2070?ref=lorcandempsey.net).\]
Now, clearly services are increasingly capturing usage and other data invisibly to refine what they do. Some services solicit explicit participation, in the form of tags, reviews, and so on. And some services are structurally built around people’s interests, where social value enhances the practical value they provide, as with social bookmarking services for example.
We have become used to this, as part of the ‘weather’ of our web lives, and it is interesting to think about how much of what we learn and discover is shared with us by other people in network environments.
However, I have been struck recently by how I will intentionally seek out more directly personal entry points where before I might have done a more general topical search. Of course we are now used to following particular blogs in particular contexts. So, for example, I have come to value [PersonaNonData](https://personanondata.blogspot.com/?ref=lorcandempsey.net) for publishing and book trade context. I am not currently on Twitter, but I subscribe to several folk’s Twitter pages via RSS, because it is often the best way of understanding what is important in particular areas. Delicious provides another example. I don’t tend to follow what is happening with Second Life. But if I want a quick update, my starting point is [Andy Powell](https://claimid.com/andypowell?ref=lorcandempsey.net)‘s SecondLife [Delicious bookmarks](https://delicious.com/andypowell/secondlife?ref=lorcandempsey.net). In each case, I recognize the value and economy of a personal entry point.
In the First Monday piece I quote from above, I went on to talk about how this may change expectations …
> *A ‘signed’ network presence*: As I noted above, we are used to seeing ‘signed’ resources: reviews, ratings, social networking profiles, bookmarks. People have become entry points on the network, and signature is important. Think of library Web sites. They tend to be anonymous. Often, it is not straightforward finding appropriate contact points: there may not be photographs, or communication options are limited (office hours, IM, texting, e-mail, phone). Library services are not always associated with people. How often do subject pages, for example, carry a name and contact information who can be consulted?
> Connaway and Radford (2007) \[[PDF](https://www.oclc.org/research/publications/archive/2007/connaway-acrl.pdf?ref=lorcandempsey.net)\] note how students are sometimes reluctant to use virtual reference because they do not want to interact with somebody who remains anonymous or who they do not know, even if it is a library service. \[First Monday. [Always on](https://firstmonday.org/htbin/cgiwrap/bin/ojs/index.php/fm/article/view/2291/2070?ref=lorcandempsey.net).\]
In this context I was very taken with a [presentation](https://codyhanson.com/CodyHansonCIC032007.ppt?ref=lorcandempsey.net) \[PPT\] I saw a while ago by [Cody Hanson](https://codyhanson.com/blog/?ref=lorcandempsey.net) which I tend to associate with Dan’s comment about people being entry points. I have referred to this before in these pages. Cody discusses the importance of signature in social networking sites and goes on to recommend that librarians be more personally visible on the network and …
- Make personal and public recommendations of sources and articles
- Expose our selection processes
- Expose our expertise
Related entries:
- [Who we are](https://blog.oclc.org/lorcand/archives/001803.html?ref=lorcandempsey.net)
- [Some thoughts about egos, objects and social networking](https://blog.oclc.org/lorcand/archives/001601.html?ref=lorcandempsey.net)
### Looking at Darwin
URL: https://www.lorcandempsey.net/looking-at-darwin/
Last updated: 2020-10-28T09:17:45.000Z
I was interested to look at [Charles Darwin’s Worldcat Identity](https://www.worldcat.org/identities/lccn-n78-95637?ref=lorcandempsey.net) given his bicentenary next week. The event is being widely marked and there is a long list of celebratory activities at [Darwin Online](https://darwin-online.org.uk/?ref=lorcandempsey.net), the site of his digitized papers.
> The year 2009 is the 150th anniversary of the publication of *On the Origin of Species* (24 November 1859) and the 200th anniversary of Darwin’s birth (12 February 1809). This page aims to list the associated worldwide events and publications. \[[Darwin Online: Darwin 2009 commemorations around the world](https://darwin-online.org.uk/2009.html?ref=lorcandempsey.net)\]
The [Identities timeline](https://www.worldcat.org/identities/lccn-n78-95637?ref=lorcandempsey.net#linktimeline) shows the strong ongoing interest in Darwin and his work.

Here are the most widely held books **about** Darwin:
- *The origin : a biographical novel of Charles Darwin* by Irving Stone (Book)
- *Darwin and the Beagle* by Alan Moorehead (Book)
- *Darwin* by Adrian J Desmond (Book)
- *The tree of life : a book depicting the life of Charles Darwin, naturalist, geologist & thinker* by Peter Sís (Book)
- *The survival of Charles Darwin : a biography of a man and an idea* by Ronald William Clark (Book)
Here are the most widely held books in Worldcat **by** Darwin, together with the numbers Worldcat shows to give some sense of relative spread:
- *The origin of species by Charles Darwin* (Book). 615 editions published between 1800 and 2007 in 26 languages and held by 5,639 libraries worldwide
- *The voyage of the Beagle* by Charles Darwin (Book). 435 editions published between 1800 and 2006 in 16 languages and held by 4,438 libraries worldwide
- *The Darwin reader* by Charles Darwin (Book). 56 editions published between 1886 and 2007 in 6 languages and held by 2,680 libraries worldwide
- *The origin of species* by Charles Darwin (Book). 121 editions published between 1859 and 2007 in 12 languages and held by 2,654 libraries worldwide
- *The descent of man, and selection in relation to sex* by Charles Darwin (Book). 278 editions published between 1870 and 2007 in 15 languages and held by 2,314 libraries worldwide
- *Computer version of Darwin’s Descent of man and Origin of species*, plus DOS applications.
- *The expression of the emotions in man and animals* by Charles Darwin (Book). 94 editions published between 1872 and 2007 in 7 languages and held by 2,174 libraries worldwide
- *Autobiography and selected letters* by Charles Darwin (Book). 68 editions published between 1929 and 2005 in 6 languages and held by 2,045 libraries worldwide
- *The life and letters of Charles Darwin, including an autobiographical chapter by Charles Darwin* (Book). 150 editions published between 1887 and 2005 in 8 languages and held by 1,916 libraries worldwide
- *The voyage of Charles Darwin* by Charles Darwin (Book). 67 editions published between 1877 and 2003 in 5 languages and held by 1,464 libraries worldwide
(Yep – The Origin of Species gets in there twice …)
### Research data set management
URL: https://www.lorcandempsey.net/research-data-set-management/
Last updated: 2020-10-28T09:17:47.000Z
Via Pam Bjornson, Chair, [Research Data Strategy Working Group](https://data-donnees.gc.ca/eng/members.html?ref=lorcandempsey.net), I learn of a report from Research Data Canada: [*Stewardship of research data in Canada: a gap analysis*](https://data-donnees.gc.ca/docs/GapAnalysis.pdf?ref=lorcandempsey.net) \[pdf\].
The method is interesting:
> This report provides a statement of the ideal state of research data stewardship in Canada and a description of the current state, as determined by examining a number of indicators. The purpose is to provide evidence of gaps between current and ideal state in order to begin filling in the gaps. The indicators of the state of the stewardship of research data in Canada are as follows: policies; funding; roles and responsibilities; \[trusted digital\] data repositories; standards; skills and training; reward and recognition systems; research and development; accessibility; and preservation. \[[Key Achievements – Research Data Canada](https://data-donnees.gc.ca/eng/about/achievements.html?ref=lorcandempsey.net)\]
It is no surprise that they find evidence of significant gaps: looking towards an ‘ideal state’ raises a high bar 😉 Here is a schematic:
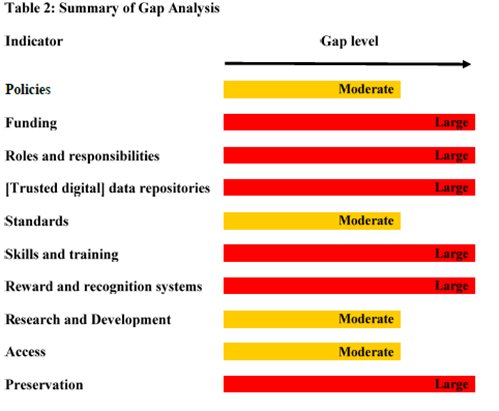
Although they point to activities in other countries as evidence that Canada is behind, I imagine that national policy, funding and service infrastructure in few countries is really very advanced.
There has been some discussion about the role of research libraries in relation to data curation. This touches on general questions about institutional roles, in the context of disciplinary and regional or national provision. However, it also raises interesting questions about the future position of libraries in relation to institutional materials. As digital information management begins to pervade research and learning activity, so do information processing and data management activities, which puts the library into a potentially new relationship with faculty and other service departments. So far, much of this interaction has focused on the institutional repository. The role of the library in the broader context of managing institutional intellectual assets (research data, learning materials, business records/archives, video and sound recordings of university events, …) is one that universities – and libraries – will have to grapple with in coming years.
### Become a librarian - shortcut
URL: https://www.lorcandempsey.net/become-a-librarian-shortcut/
Last updated: 2020-10-28T09:17:49.000Z
I signed up to GoodReads earlier today to see what it was like. I entered a few books and was interested to try combining some editions. I got this message …

I thought this was an interesting choice of words. What can a librarian do?
> Goodreads members with Librarian Status can edit book and author data, add book covers, and combine different editions of books. Each book and author has one unique entry in the Goodreads database. Librarians help correct book issues, like if the data isn’t correct, or is missing things like the book description or URL. \[[Goodreads | librarian manual](https://www.goodreads.com/help/librarian?ref=lorcandempsey.net)\]
What do you have to do to become a ‘librarian’?
> We have a little ‘safeguard’ rule where we like users to have at least 50 books shelved before granting them librarian status. This just helps us make sure that those tidying up the data are committed to the site. \[[Goodreads | apply to be a librarian](https://www.goodreads.com/about/apply%5Flibrarian?ref=lorcandempsey.net)\]
It is interesting – and quite nice, I thought – that ‘librarian’ is the term used for those who pass a certain threshold in terms of collection management. That said, the threshold is not set too hign ….
### Stock ideas
URL: https://www.lorcandempsey.net/stock-ideas/
Last updated: 2020-10-28T09:17:52.000Z
I was looking at [iStockphoto](https://www.istockphoto.com/?ref=lorcandempsey.net) earlier for something and on a whim searched for ‘library’. If stock photographs capture stock ideas about things, then it is clear what people still think about libraries ….

Incidentally, I liked the ‘flame’ coming out of the top of the images: it indicates how ‘hot’ an item is based on number of downloads.
### Metadata creation practices
URL: https://www.lorcandempsey.net/metadata-creation-practices/
Last updated: 2020-10-28T09:17:55.000Z
We have released a report on metadata creation practices based on a survey of RLG partner institutions. 134 responses from 67 institutions were received.
> Ayers, Leighann, Beth Picknally Camden, Lisa German, Peggy Johnson, Caroline Miller and Karen Smith-Yoshimura. 2009\. *What We’ve Learned from the RLG Partners Metadata Creation Workflows Survey*. Published online at: [https://www.oclc.org/programs/publications/reports/2009-04.pdf](https://www.oclc.org/programs/publications/reports/2009-04.pdf?ref=lorcandempsey.net) \[pdf\].
It shows the variety of tools and techniques in use. Here are a couple of passages …
> The working group had hoped that the survey would point to tools and resources for streamlining metadata workflows that might be shared within the RLG Partnership and that could be adapted locally. However, survey responses suggest that the tools being used are very localized, and no one tool kit is being used. Most tools mentioned were generic, i.e., standard software and programming (Java, Perl, XSL-based custom code) or a combination of these that has been locally customized for metadata creation and non-MARC enrichment….
> … When asked about the types of materials to which metadata creation tools are applied, 78 respondents identified various material types. By far the most common material type identified was archival materials/finding aids–selected by 73% of the 78 respondents to this question. Electronic texts were next (50%), followed by visual (2-D) materials (45%).\[[What we’ve learned from the RLG Partners metadata creation workflows survey](https://www.oclc.org/programs/reports/2009-04.pdf?ref=lorcandempsey.net)\]
### Top Tech Trends gets amplified
URL: https://www.lorcandempsey.net/top-tech-trends-gets-amplified/
Last updated: 2020-10-28T09:17:58.000Z
Roy [writes](https://www.libraryjournal.com/blog/1090000309/post/1140039714.html?ref=lorcandempsey.net) about how Top Tech Trends has become an [amplified conference](https://en.wikipedia.org/wiki/Amplified%5Fconference?ref=lorcandempsey.net).
### Breakthrough ideas
URL: https://www.lorcandempsey.net/breakthrough-ideas/
Last updated: 2020-10-28T09:18:00.000Z
The [Harvard Business Review list of breakthrough ideas for 2009](https://hbr.harvardbusiness.org/web/tools/2009/01/list-toc?ref=lorcandempsey.net) had a few interesting entries. My favorite was the ‘IKEA Factor’ …. we do often see examples where folks are reluctant to let go of things they have invested time and resource in.
*Institutional memory goes digital*
> Suppose every utterance and facial expression at a meeting were routinely captured and archived in high-definition digital video recordings – searchable and available in perpetuity. Would this be a godsend or a nightmare? The answer is probably both, but we’re about to find out for sure. Within a few years, a synthesis of technologies from an array of companies will make possible a “total recall system,” or TRS, that can produce such recordings. \[[The HBR List; institutional memory goes digital](https://hbr.harvardbusiness.org/web/2009/hbr-list/institutional-memory-goes-digital?ref=lorcandempsey.net)\]
*The IKEA Factor*
> Research conducted with my colleagues Daniel Mochon, of Yale University, and Dan Ariely, of Duke University, shows that labor enhances affection for its results. When people construct products themselves, from bookshelves to Build-a-Bears, they come to overvalue their (often poorly made) creations. We call this phenomenon the IKEA effect, in honor of the wildly successful Swedish manufacturer whose products typically arrive with some assembly required….
> … Finally, the IKEA effect has broader implications for organizational dynamics: It contributes to the sunk cost effect, whereby managers continue to devote resources to (sometimes failing) projects in which they have invested their labor, and to the not-invented-here syndrome, whereby they discount good ideas developed elsewhere in favor of their (sometimes inferior) internally developed ideas. Managers should keep in mind that ideas they have come to love because they invested their own labor in them may not be as highly valued by their coworkers – or their customers. \[[The HBR list 2009: the IKEA factor](https://hbr.harvardbusiness.org/web/2009/hbr-list/ikea-effect-when-labor-leads-to-love?ref=lorcandempsey.net)\]
*Just because I’m nice, don’t assume I’m dumb*
> Inaccurate warmth/competence judgments can lead managers to trust untrustworthy associates or undervalue potentially important connections with people. They can also undermine companies’ efforts to build effective teams, identify lucrative opportunities, and retain good employees. For example, mothers, like the elderly, are chronically stereotyped as less competent (although warmer) than other workers and as a result are often underpromoted and underpaid. \[[The HBR List: Just because I’m nice, don’t assume I’m dumb](https://hbr.harvardbusiness.org/web/2009/hbr-list/because-i-am-nice-dont-assume-i-am-dumb?ref=lorcandempsey.net)\]
*Should you outsource your brain?*
> With a shortage of analytic skills in the United States and Western Europe and a ready supply in India, Eastern Europe, and China, it’s perhaps not surprising that organizations are now outsourcing these more cerebral functions.\[[The HBR List: Should you outsource your brain?](https://hbr.harvardbusiness.org/web/2009/hbr-list/should-you-outsource-your-brain?ref=lorcandempsey.net)\]
### MLA welcomes Obama
URL: https://www.lorcandempsey.net/mla-welcomes-obama/
Last updated: 2020-10-28T09:18:02.000Z
The Museums, Libraries and Archives Council in the UK welcomes the inauguration of Barack Obama, quoting from his speech at the ALA Annual Conference in Chicago, June 2005.
[](https://www.mla.gov.uk/?ref=lorcandempsey.net)
Here is how the piece opens ….
> During an especially historic week, the MLA, and its Chief Executive Roy Clare, would like to welcome Barack Obama into office, taking the opportunity to point to his lesser known record as someone who shares a drive and enthusiasm for public libraries.
> With the MLA embarking on a library campaign to highlight the vital role of libraries and their changing face – modern libraries for modern users – it’s good to know this view is shared by a man who has been elected to the most powerful office in the world. \[[A powerful library champion](https://www.mla.gov.uk/news/comment/obama%5Flibraries?ref=lorcandempsey.net)\]
### Phone home
URL: https://www.lorcandempsey.net/phone-home/
Last updated: 2020-10-28T09:18:05.000Z
Mike Leigh’s film Happy-go-Lucky has been doing well, and Sally Hawkins who plays the lead won a Golden Globe for her performance.
We liked it much less than the critics appeared to, including the excellent Philip French. (French [reviews it](https://www.guardian.co.uk/film/2008/apr/20/culture.mikeleigh?ref=lorcandempsey.net) in the Observer; while looking for this I came across a [different view](https://entertainment.timesonline.co.uk/tol/arts%5Fand%5Fentertainment/film/article3713952.ece?ref=lorcandempsey.net) from Kevin Maher in the Times).
The action is built around close observation of Poppy, a thirty year old primary school teacher living in London.
As I watched, something felt not quite right. About half way through I realized what it was: Poppy was not using a mobile phone. She did use it but only very occasionally and more towards the end. I found myself thinking all the time: where is your phone ….? why don’t you text them ….? why is nobody calling you …?
### Collective collection policies
URL: https://www.lorcandempsey.net/collective-collection-policies/
Last updated: 2022-11-05T20:39:47.000Z
One of the more interesting library developments in recent years has been the growing interest in cooperative approaches to the storage and management of collections. This has been made more real by pressures on space, and the opportunity cost of using that space to house print collections. Such collaborative sourcing throws up the need for policy frameworks. A recent study, the *[Shared Print Policy Review Report](https://www.oclc.org/programs/publications/reports/2009-03.pdf?ref=lorcandempsey.net)* \[pdf\], was carried out under the auspices of the RLG Partnership Shared Print Collections Working Group and examined emerging frameworks across a range of initiatives.
> In summary, our study suggests that libraries interested in adopting cooperative print management regimes on a limited scale, typically determined by geographic proximity, can do so with relative ease, provided certain core elements are included in a formal collection-sharing agreement. Based on a review of existing policies, three critical components were identified as necessary to securing an inter-institutional accord on print collection management:
> 1. An explicit retention commitment (regardless of duration) for titles committed to the shared archive;
> 2. Identification of conditions under which materials may be recalled or temporarily withdrawn from the archive;
> 3. Definition of terms: duplication, withdrawal, what constitutes reasonable effort to replace lost or missing items, etc.
>
> \[[*Shared Print Policy Review Report*](https://www.oclc.org/programs/publications/reports/2009-03.pdf?ref=lorcandempsey.net) pdf\]
Related entries:
- [Collective Collection](https://www.google.com/search?q=lorcan+dempsey+collective+collection&ref=lorcandempsey.net)
### Libraries and research information practice
URL: https://www.lorcandempsey.net/libraries-and-research-information-practice/
Last updated: 2020-10-28T09:18:09.000Z
I am pleased to note the appearance of a new report which synthesizes research findings about scholarly information practices and draws out lessons for libraries ..
> Palmer, Carole L., Lauren C. Teffeau and Carrie M. Pirmann. 2009\. *Scholarly Information Practices in the Online Environment: Themes from the Literature and Implications for Library Service Development*. Report commissioned by OCLC Research. Published online at: [https://www.oclc.org/programs/publications/reports/2009-02.pdf](https://www.oclc.org/programs/publications/reports/2009-02.pdf?ref=lorcandempsey.net) \[pdf\]
From the introduction:
> Research libraries exist to support scholarly work. In recent years, the literature on scholarly practices and information use has been growing, and research libraries should be prospering from this increased base of knowledge. Unfortunately, the profession has no effective means for systematically monitoring or synthesizing the published results. This review begins to address the problem by reporting on the state of knowledge on scholarly information behavior, focusing on the information activities involved in the research process and how they differ among disciplines. It provides an empirical basis for identifying promising directions and setting priorities for development of digital information services to support and advance scholarship. \[[Scholarly information practices in the online environment](https://www.oclc.org/programs/publications/reports/2009-02.pdf?ref=lorcandempsey.net) pdf\]
The body of the report is structured around ‘scholarly primitives’: “The sections that follow present the literature on scholarly information work framed around five core scholarly activities: searching, collecting, reading, writing and collaborating, with two or more primitives distinguished for each activity. Four cross-cutting primitives that are associated with more than one activity are also covered and serve as an important indicator of how the processes involved in the conduct of research and scholarship overlap and interact.”

For some additional background see the note by my colleague Constance Malpas who commisioned the work in support of the RLG Partnership: [*Moving library services into research flows*](https://hangingtogether.org/?p=605&ref=lorcandempsey.net).
### Library website analytics
URL: https://www.lorcandempsey.net/library-website-analytics-2/
Last updated: 2020-10-28T09:18:11.000Z
I have just been looking at the [presentation](https://conferences.infotoday.com/documents/52/C102%5FSheikh.ppt?ref=lorcandempsey.net) \[ppt\] given by Tony Hirst and Hassan Sheikh to [Internet Librarian International](https://www.internet-librarian.com/2008/day.php?day=Thursday&ref=lorcandempsey.net#session%5FC102) last October.
They report the results of their analysis of traffic to the home page of the Open University Library using Google Analytics.
Here are some of the things that I noticed:
- The most clicked links on the home page were: Databases (20%), eJournals (19%), Library Catalogue (11%).
- Slightly over half the traffic came directly to the website, about 40% from referring sites, and just over 5% from search engines.
- The most popular pages (aside from the home page) are Journals, Databases, and eResources (Online collections by subject).
- There is data on referrals to particular resources, by source website (e.g. from a learning management system) and by network location.
- The presentation concludes with some questions for further investigation, including thinking about slicing data by referring course (from within the learning management system) and by database.
A couple of things jumped out at me. First, I wondered whether the low number of clicks from the home page through to the catalogue as compared to licensed materials would be repeated in other institutions. And second, I was interested in the large number of referrals from other internal OU systems (e.g. the learning management system aka VLE). Again, I wondered whether this pattern was repeated in other university environments.
For related work, see Tony Hirst’s blog entries beginning with [this one](https://ouseful.wordpress.com/2008/08/20/library-analytics-part-1/?ref=lorcandempsey.net).
Update: Check out the [comments](https://blog.oclc.org/lorcand/archives/001858.html?ref=lorcandempsey.net#comments) for a note by Tony Hirst about ways in which the OU may not be typical. He also talks a little about measuring traffic from the VLE to the library.
### A referenceable list
URL: https://www.lorcandempsey.net/a-referenceable-list/
Last updated: 2020-10-28T09:18:12.000Z
My colleague Constance Malpas has created an interesting Worldcat List in support of ongoing work:
> Selected print-only, refereed scholarly journals in the humanities with fewer than 50 aggregate library holdings. Holdings count limited to recs containing ISSN and English-language cataloging. \[[RLG Prospective Journals Preservation Project – sample titles](https://www.worldcat.org/profiles/cmalpas/lists/346407?ref=lorcandempsey.net)\]
This is an interesting list in itself. What struck me was how nice it was to be able to publish a list so that it was publicly referenceable, the data could be shared, and the items link back to library holdings.
### Reading, skimming, avoiding ...
URL: https://www.lorcandempsey.net/reading-skimming-avoiding/
Last updated: 2020-10-28T09:18:14.000Z
I have been meaning to mention [Carole Palmer’s](https://people.lis.uiuc.edu/~clpalmer/?ref=lorcandempsey.net) observation that we are seeing ‘reading avoidance’ as an emerging behavior among researchers, as they increasingly depend on abstracts, citations, and other reading cues and clues to ‘avoid’ full engagement with the materials themselves. Here is what I wrote in my [recent piece on mobile communications](https://firstmonday.org/htbin/cgiwrap/bin/ojs/index.php/fm/article/view/2291/2070?ref=lorcandempsey.net) in First Monday about changing patterns of attention ….
—
The network style of consumption — particularly mobile consumption — calls forward services which atomize content, providing snippets, thumbnails, ringtones, abstracts, tags, ratings and feeds. All of these create a variety of hooks and hints for people for whom attention is scarce. It has even been recently suggested that this pattern of consumption is rewiring our cognitive capacities (Carr, 2008). Regardless of the longer term implications, it is clear that people need better clues about where to spend their attention in this environment, and that this is one incentive for the popularity of social approaches. This attention scarcity is apparent also in the academic environment where a bouncing and skimming style of consumption has been observed (Nicholas, et al., 2006). Palmer, et al. (2007) talk about actual ‘reading avoidance’. Researchers may survey more material, but spend less time with each item, relying on abstracts and other content clues to avoid reading in full.
**Nicholas Carr**, 2008\. “Is Google making us stupid?” Atlantic Monthly (July/August), at [https://www.theatlantic.com/doc/200807/google](https://www.theatlantic.com/doc/200807/google?ref=lorcandempsey.net), accessed 10 October 2008.
**David Nicholas**, Paul Huntington, Hamid R. Jamali, and Tom Dobrowolski, 2006\. “Characterising and evaluating information seeking behaviour in a digital environment: Spotlight on the ‘bouncer’,” Information Processing and Management, volume 43, number 4, pp. 1085-1102.
**Carole L. Palmer**, Melissa H. Cragin, and Timothy P. Hogan, 2007\. “Weak information work in scientific discovery,” Information Processing and Mangement, volume 43, number 3, pp. 808-820\.
—
Here is what she said in a [presentation](https://www.oclc.org/programsandresearch/dss/ppt/dss%5Fpalmer.ppt?ref=lorcandempsey.net) \[ppt\] at OCLC last year:
> Researchers are rapidly navigating through more material, spending less and less time with each item, and attempting to assess and exploit content with as little actual reading as possible.
### Google Book Search and Libraries
URL: https://www.lorcandempsey.net/google-book-search-and-libraries/
Last updated: 2020-10-28T09:18:16.000Z
My colleague Ricky Erway has distilled material relevant to libraries from the proposed Google agreement with the APA and Authors’ Guild.
> Now I’m not a lawyer (and I’ve had that confirmed by our folks in legal) and not even a little lawyer-like, but I read the settlement agreement, most of the appendices (I mean, really, at some point do even the lawyers say, I am not going to read that one!?), and the three library-registry agreements and I tried to note the bits that matter to libraries. (That’s boiling down about 320 pages into a 4 1/2 page summary, so I’ve left out a bit of detail.) \[HangingTogether – The Google Book Settlement – what does it mean for the rest of us?\]
The above blog entry provides some context. The distillation is [here](https://www.oclc.org/programs/publications/reports/2009-01.pdf?ref=lorcandempsey.net) \[pdf\], and readers may also be interested in our [Public/Private Mass Digitization Agreements resource list](https://www.oclc.org/programs/ourwork/collectivecoll/massdigresourcelist.htm?ref=lorcandempsey.net).
### Hiccups
URL: https://www.lorcandempsey.net/hiccups/
Last updated: 2020-10-28T09:18:20.000Z
Apologies for any hiccups while we updated the blog software over the last few days. This blog runs on a local instance of Movable Type. As I [suggested](https://blog.oclc.org/lorcand/archives/001809.html?ref=lorcandempsey.net) when talking about online identity the other day, I might have set it up on an externally hosted system if done today. However, there are now over 700 people registered to receive the email digest and we would have to move or lose those. I am sure we could figure out what to do, but life is short ….
### Affinity strings, personalization and recommendation
URL: https://www.lorcandempsey.net/affinity-strings-personalization-and-recommendation/
Last updated: 2020-10-28T09:18:23.000Z
I heard about ‘affinity strings’ on a visit to Minnesota some time ago. I was pleased to see that they have written up what they are doing in the recent issue of *The Code4Lib Journal*:
> The University of Minnesota Libraries have created a MyLibrary portal, with databases and e-journals targeted to users, based on their affiliations. The University’s enterprise authentication system provides an “affinity string”, now used to personalize the MyLibrary portal. This affinity string automates discovery of a user’s relationship to the University-describing a user’s academic department and degree program or position at the University. Affinity strings also provide the Libraries with an anonymized view of resource usage, allowing data collection that respects users’ privacy and lays the groundwork for automated recommendation of relevant resources based on the practices and habits of their peers. \[[The Code4Lib Journal – Affinity Strings: Enterprise Data for Resource Recommendations](https://journal.code4lib.org/articles/501?ref=lorcandempsey.net)\]
I thought there were several interesting things about this. First, it is using enterprise-wide data. Everybody at the University of Minnesota has one or more strings based on their area of study or work. These are generated from the University’s PeopleSoft system. Here is the example given in the article.

(This is a student based in the **T**win **C**ities campus, who is a **grad**uate student enrolled in the **g**raduate **s**chool, and doing a **PhD** in **psy**chology.)
Next they can use this in several ways. It gives them a concise representation of user interests, which can then be processed and matched in various ways. It is used to prioritize content presented to users in the MyLibrary tab of the University portal, MyU. Some resources – the catalog for example – would be shown to all; some are shown selectively based on affinity string. The string is further used to match pre-existing ‘Research quick-start’ resource lists to relevant users and there is some interesting discussion of matching issues for different categories of user. Another use is to aggregate electronic resource usage data. The advantage here is that the affinity string provides a more general unit for tracking than the individual person does, protecting privacy. Affinity strings can be associated with particular resources through the centralized authentication system, allowing resource use to be tracked by audience.
Finally, the authors acknowledge the limitations of their approach: they are working with the data they have. But, they are also alert to the variety of ways in which their services can be improved by making the data that they have work harder – better to match resources and users, and better to understand resource usage. And in the process, they are generating additional data which should help them further refine collections and services.
### QOTD: News futures and brands of one
URL: https://www.lorcandempsey.net/qotd-news-futures-and-brands-of-one/
Last updated: 2021-06-10T04:07:57.000Z
Michael Hirschorn speculates about the future of the *New York Times* in *The Atlantic*.
Update: Perhaps the introduction of Bono as an occasional NYT [op ed writer](https://www.nytimes.com/2009/01/11/opinion/11bono.html?ex=1247374800&en=07bd2a60c2a6e5b0&ei=5087&WT.mc%5Fid=OP-D-I-NYT-MOD-MOD-M077-ROS-0109-HDR&WT.mc%5Fev=click&ref=lorcandempsey.net) is a sign of things to come. The Guardian news blog [summarises](https://www.guardian.co.uk/world/blog/2009/jan/13/bono-new-york-times-column?ref=lorcandempsey.net) responses to Bono as a journalist.
I like the phrase “brands of one” to describe high profile columnists operating independently in the market.
> In this scenario, nytimes.com would begin to resemble a bigger, better, and less partisan version of the Huffington Post, which, until someone smarter or more deep-pocketed comes along, is the prototype for the future of journalism: a healthy dose of aggregation, a wide range of contributors, and a growing offering of original reporting. This combination has allowed the HuffPo to digest the news that matters most to its readers at minimal cost, while it focuses resources in the highest-impact areas. What the HuffPo does not have, at least not yet, is a roster of contributors who can set agendas, conduct in-depth investigations, or break high-level news. But the post-print *Times* still would. \[[End Times – The Atlantic (January/February 2009)](https://www.theatlantic.com/doc/200901/new-york-times?ref=lorcandempsey.net)\]
> Clearly, over the short run, there would be a culling of the journalistic herd. If 80 percent of *The* *Times* staff ends up laid off, many of them won’t find their way to new reporting jobs. But over the long run, a world in which journalism is no longer weighed down by the need to fold an omnibus news product into a larger lifestyle-tastic package might turn out to be one in which actual reportage could make the case for why it matters, and why it might even be worth paying for. The best journalists will survive, and eventually thrive. Some will be snapped up by an expanding HuffPo (which is raising millions while its print competitors tank) and by the inevitable competitors that will spring up to imitate its business model, or even by smaller outlets, like [Talking Points Memo](https://www.talkingpointsmemo.com/?ref=lorcandempsey.net), which have found that keeping their overhead low allows them to profit from high-quality journalism. And some will succeed as independent operators. Figures like Thomas Friedman, Paul Krugman, and Andrew Ross Sorkin (the editor of the [DealBook business blog](https://dealbook.blogs.nytimes.com/?ref=lorcandempsey.net), which has been a cash cow for *The Times*) would be worth a great deal on the open market. For them and others, the bracing experience of becoming “brands of one” could prove intoxicating, and perhaps more profitable than fighting as part of a union for an extra percentage-point raise in their next contract. \[[End Times – The Atlantic (January/February 2009)](https://www.theatlantic.com/doc/200901/new-york-times?ref=lorcandempsey.net)\]
### Bibliotherapy at the School of Life
URL: https://www.lorcandempsey.net/bibliotherapy-at-the-school-of-life/
Last updated: 2020-10-28T09:18:27.000Z
If you visit the [School of Life](https://www.theschooloflife.com/homepage.aspx?ref=lorcandempsey.net), you might stay a while; its tagline is “ideas to live by”. Useful services include sermons you can listen to and experts you can talk to on the big questions of life.
What was really interesting were the Bibliotherapy services. Unfortunately, we didn’t know about this before Christmas as it might have helped with some gifts …
> Our bibliotherapists will meet you at The School of Life for an initial half-hour consultation. They also do consultations by phone or e-mail. This will consist of an unusually in-depth conversation about your attitude and experiences of books (you might read one a day or not have picked one up since school), during which you are invited to share your particular area of concern or curiosity (anything from Japanese archery to how to rediscover your creativity). Following the discussion, you will be given a beautifully presented reading prescription. A longer list will be sent to you by email within the next few days. \[[The School of Life](https://www.theschooloflife.com/bibliotherapy/how-does-it-work.aspx?ref=lorcandempsey.net)\]
However, it doesn’t stop there. They offer a variety of other services including ‘long term bibliotherapy’, and even the construction of whole libraries. They are also some specialist offerings:
A wedding list ….
> Our Wedding Library service is the ideal way to ensure that you, or a couple you know, enter this exciting new phase of life with a bookshelf well stocked – not just with the fundamentals, but with books hand-picked to appeal to and inspire each half of the couple concerned. From the day they are married, their tailored library can be trusted to supply stimulation, inspiration, advice and harmony. \[[The School of Life](https://www.theschooloflife.com/bibliotherapy/bibliotherapy-gifts.aspx?ref=lorcandempsey.net)\]
A retirement library ….
> Treat someone who will finally have a bit more time on their hands to read, to travel and to take up new pursuits, with a handpicked new library. Just tell us your budget and one of our bibliotherapists will meet the person who is retiring and devise a tailored list of books for them to treasure for years to come. We’ll then arrange for these to be delivered, all beautifully wrapped, to the office in time for the leaving do. \[[The School of Life](https://www.theschooloflife.com/bibliotherapy/bibliotherapy-gifts.aspx?ref=lorcandempsey.net)\]
And there are various ‘kid’s bibliotherapy’ services including a ‘survival kit for parents’ and …
> What to give the eight-year-old who fancies himself as the next prime minister, or the twelve-year-old who has already had their heart broken? How to find books that will survive getting wet in the bath or that you won’t mind being asked to read aloud time after time? Just ask and we’ll assemble the perfect book-based gift box for any child. Visit our [Kids Bibliotherapy page](/bibliotherapy/kids'-bibliotherapy.aspx) to find out more. \[[The School of Life](https://www.theschooloflife.com/bibliotherapy/bibliotherapy-gifts.aspx?ref=lorcandempsey.net)\]
\[Note: *Bibliotherapy* is not a new idea for libraries as Karen Schneider noted in a [comment](https://blog.oclc.org/lorcand/archives/001769.html?ref=lorcandempsey.net#comments) on an [entry](https://blog.oclc.org/lorcand/archives/001769.html?ref=lorcandempsey.net) a while ago.\]
### Always on: libraries in a world of permanent connectivity
URL: https://www.lorcandempsey.net/always-on-libraries-in-a-world-of-permanent-connectivity/
Last updated: 2020-10-28T09:18:29.000Z
The January issue of [*First Monday*](https://firstmonday.org/htbin/cgiwrap/bin/ojs/index.php/fm/issue/view/274?ref=lorcandempsey.net) has appeared and I am pleased to have an [article](https://firstmonday.org/htbin/cgiwrap/bin/ojs/index.php/fm/article/view/2291/2070?ref=lorcandempsey.net) in it about libraries and mobile communications. Here is the abstract:
> Mobile communication has been more widely adopted more quickly than any other technology ever (Castells, et al., 2007). It represents a diffusion of communications and computational capacity into a growing part of our research, learning and social activities. It has resonated with emerging youth behavior, providing support for distinctive patterns of social interaction and group formation, information use and personal expression.
> Diffuse networking changes how we coordinate our resources to achieve goals. For example, our use of time and space changes. Timeshifting is routine as students may listen to or watch lectures in the gym or on the train. The use of space to support ad hoc rendezvous and social learning is becoming more important.
> As networking spreads, we have multiple connection points which offer different grades of experience (the desktop, cell phone, xBox or Wii, GPS system, smartphone, ultra-portable notebook, and so on). While these converge in various ways, they are also optimized for different purposes. A natural accompaniment of this mesh of connection points is a move of many services to the cloud, available on the network across these multiple devices and environments. This means that an exclusive focus on the institutional Web site as the primary delivery mechanism and the browser as the primary consumption environment is increasingly partial.
> Students are results-oriented and value convenience. This emphasis coupled with the design constraints on some devices promotes a need to get to relevance quickly. Socialization, personalization and location awareness become very important.
> Libraries have been working to develop network-ready services. Mobile communication intensifies this activity and adds new challenges as they look at what it means to be mobile-ready. This has organizational implications as a shift of emphasis towards workflow integration around the learner or researcher creates new relationships with other service organizations on campus. It also has implications for how space is used, for library skills, and for how collections are developed. We can see the impact of mobile communication on services in two ways. First, services may be made mobile-ready, as with special mobile interfaces for library services, alerting services, and so on. Second, mobilization continues the restructuring of services, organizations and attention that networking has brought about. Think here of how to socialize and personalize services; how to adapt to collection and service use which spans personal, institutional, and cloud environments; how to position and promote the library ‘brand’ as services become atomized and less ‘visible’ on the network; and more complex questions about what best to do locally and what to source with collaborative arrangements or third parties. \[[Always on: libraries in a world of permanent connectivity](https://firstmonday.org/htbin/cgiwrap/bin/ojs/index.php/fm/article/view/2291/2070?ref=lorcandempsey.net). *First Monday*, Volume 14, Number 1 – 5 January 2009\]
This is an adapted version of a contribution to the following, which accounts for the emphasis on academic library examples:
International M-Libraries Conference, Mohamed Ally, and Gill Needham, 2008\. [*M-Libraries: Libraries on the move to provide virtual access*](https://www.worldcat.org/oclc/276989760?ref=lorcandempsey.net). London: Facet.
### Holiday note 3: knitting a web presence
URL: https://www.lorcandempsey.net/holiday-note-3-knitting-a-web-presence/
Last updated: 2020-10-28T09:18:31.000Z
I find website appearance both more and less important, as I suggested in a [post](https://blog.oclc.org/lorcand/archives/000808.html?ref=lorcandempsey.net) a couple of years ago (although it seems only like a couple of months ago ;-).
Less important because I now experience many sites as part of the feed-based universe which makes up much of my information consumption. I ‘look’ at CNN, for example, quite a bit, but rarely visit the actual site. More important because my perception of an organization’s website now plays a more important part in my impression of that organization.
Anyway, over the holiday I have seen quite a few online holiday greetings and sites in festive garb. The one that I liked best was the University of Plymouth’s home page. It is playful and pleasing. It is not often that you see knitting textures as part of a University website! It communicated a good image of the organization, I thought.
[](https://www.plymouth.ac.uk/?ref=lorcandempsey.net)
(I have linked the picture to the University’s home page. I hope that future versions of the home page don’t disappoint 😉
### Holiday note 2: QOTD: video games
URL: https://www.lorcandempsey.net/holiday-note-2-qotd-video-games/
Last updated: 2020-10-28T09:18:33.000Z
John Lanchester has an [article on video games](https://www.lrb.co.uk/v31/n01/lanc01%5F.html?ref=lorcandempsey.net) in the current *London Review of Books*. Because of the cultural segregation between audiences that he describes below, it is unusual to see a serious treatment of video games in a venue like this. I was particularly interested to see this given the increase in gaming capacity our household has seen each Christmas for the past few years 😉
Here is the passage that I will probably remember …
> Northrop Frye once observed that all conventions, as conventions, are more or less insane; Stanley Cavell once pointed out that the conventions of cinema are just as arbitrary as those of opera. Both those observations are brought to mind by video games, which are full, overfull, of exactly that kind of arbitrary convention. Many of these conventions make the game more difficult. Gaming is a much more resistant, frustrating medium than its cultural competitors. Older media have largely abandoned the idea that difficulty is a virtue; if I had to name one high-cultural notion that had died in my adult lifetime, it would be the idea that difficulty is artistically desirable. It’s a bit of an irony that difficulty thrives in the newest medium of all – and it’s not by accident, either. One of the most common complaints regular gamers make in reviewing new offerings is that they are too easy. (It would be nice if a little bit of that leaked over into the book world.) \[[LRB · John Lanchester: Is it Art?](https://www.lrb.co.uk/v31/n01/lanc01%5F.html?ref=lorcandempsey.net)\]
Here is how the article starts …
> From the economic point of view, this was the year video games overtook music and video, combined, in the UK. The industries’ respective share of the take is forecast to be £4.64 billion and £4.46 billion. (For purposes of comparison, UK book publishers’ total turnover in 2007 was £4.1 billion.) As a rule, economic shifts of this kind take a while to register on the cultural seismometer; and indeed, from the broader cultural point of view, video games barely exist. The newspapers cover the movies extensively, and while it isn’t necessary to feel that they do all that great a job of it, there’s no denying that they have a try. Video games by contrast are consigned to the nerdy margins of the papers, and are pretty much invisible in broadcast media. Video-game fans return the favour: they constitute the demographic group least likely to pay attention to newspapers and are increasingly uninterested in the ‘MSM’, or mainstream media. \[[LRB · John Lanchester: Is it Art?](https://www.lrb.co.uk/v31/n01/lanc01%5F.html?ref=lorcandempsey.net)\]
> There is no other medium that produces so pure a cultural segregation as video games, so clean-cut a division between the audience and the non-audience. Books, films, TV, dance, theatre, music, painting, photography, sculpture, all have publics which either are or aren’t interested in them, but at least know that these forms exist, that things happen in them in which people who are interested in them are interested. They are all part of our current cultural discourse. Video games aren’t. Video games have people who play them, and a wider public for whom they simply don’t exist. (The exceptions come in the form of occasional tabloid horror stories, always about a disturbed youth who was ‘inspired’ to do something terrible by a video game.) Their invisibility is interesting in itself, and also allows interesting things to happen in games under the cultural radar. \[[LRB · John Lanchester: Is it Art?](https://www.lrb.co.uk/v31/n01/lanc01%5F.html?ref=lorcandempsey.net)\]
And here is how it finishes …
> The other way in which games might converge on art is through the beauty and detail of their imagined worlds, combined with the freedom they give the player to wander around in them. Already quite a few games offer what’s known as ‘sandbox’ potential, to allow the player to ignore specific missions and tasks and just to roam around. (Many people’s favourite aspect of the *Grand Theft Auto* games involves their sandboxiness. A favourite sandbox activity in the California-set *Grand Theft Auto: San Andreas* was simply driving to the coast and watching the sun go down over the ocean.) I think more and more games will make this central to the user’s experience of the game, and one straw in the wind here is *Fallout 3*, a new game from the producer Bethesda. It’s set in a post-apocalyptic 2277, and your character begins the game living in Vault 101, a bomb shelter set near the ruins of Washington. The game has the usual props and targets, but one of the most striking things about it is the opportunity it offers to explore the bombed-out, desolate, intensely evocative city. This is something which, once you’ve done it, I suspect will be difficult to get out of your head – and it is a glimpse of what games can do at their best. The next decade or so is going to see the world of video games convulsed by battles between the moneymen and the artists; if the good guys win, or win enough of the time, we’re going to have a whole new art form. At a moment when there’s less good cheer than there should be, it’s something to look forward to. \[[LRB · John Lanchester: Is it Art?](https://www.lrb.co.uk/v31/n01/lanc01%5F.html?ref=lorcandempsey.net)\]
### Holiday note 1: Ohio
URL: https://www.lorcandempsey.net/holiday-note-1-ohio/
Last updated: 2020-10-28T09:18:36.000Z
An off-topic holiday note for non-US readers. The first year or two we were in Ohio we spent quite a bit of time driving around the State. This lasted only so long: our children protested about long drives. For them, a long drive is anything that involves traveling further than to the mall 😉
Before we got any more general sense of geography and economy, we were immediately and superficially struck by four things. First was the aerial landscape of gas station and restaurant signage around highway exits, a general phenomenon but new to us. Second was the realization that we had never been so far away from the sea 😉 Third, was the often grand civic and commerical architectural presence in many towns: the courthouse in the central square is a common pattern. This is all the more striking given a general low, plain, spread of buildings, and the relative emptiness of many of those downtowns. And fourth was the density of the college/university presence; in fact, at one stage, thinking only of parents again, we thought we might construct itineraries around towns with liberal arts colleges.
[](https://www.flickr.com/photos/75905404@N00/487287425/in/photostream/?ref=lorcandempsey.net)
One of the Christmas gifts to be exchanged last week was [*Building Ohio: a traveler’s guide to Ohio’s urban architecture*](https://www.worldcat.org/oclc/47182391?ref=lorcandempsey.net) by Jane Ware. In the introduction, the author conveys the views of Doug Graf, a professor of architecture at OSU on why Ohio has “a unique stock of good buildings”. I don’t have enough knowledge to weigh the judgments but was interested to read them ….
> First, the state was located so that it was settled at the right time, when the nation was new, and moving west of the Alleghenies was not yet a commonplace. People came to Ohio with tremendous confidence in the future and in this new place. “Each town had the potential of being the new Athens,” Graf said. Each town had to prepare for greatness with public space and public buildings (the green and the courthouse), with institutions (college, seminary, opera house), with quality structures. That sense of optimism diminished as settlement moved west; the farther west you go, the less interesting the towns are; and private colleges become rarer and rarer. ….
> Second, Ohio had industrialization which made it rich; at one time or an other, every county had money. Agriculture and industry were strong and widely dispersed, an unusual pattern; in other places wealth was more concentrated. As late as 1950, Ohio was the only state with so many as six cities with populations of more than a quarter million. Moreover, these larger cities and many smaller ones stayed prosperous with industrial niches in, say, glass, cash registers, tires. Communities competed with one another.
> Colleges, were, – and are – everywhere. “When you get to a small city in Indiana, you don’t expect to find a college” says Graf. “But in Ohio, every town has a college, many of them fairly good. So you have money in a cultured venue that values the town. Then buildings will matter, will be thoughtful, will be a natural embellishment of the place.”
> Finally, Ohio has many examples of innovative hybridization, which depended on a general interest in what was going on in the rest of the world. The hybridization was reinterpreting styles or, say, combining elements of both New England and Virginia town layouts. The latter had central greens containing an important building, while New England towns had a central green with public buildings facing into it and a commercial street off to the side. ….
The picture is of Ross County Courthouse, Chillicothe, Ohio. It is taken by my OCLC colleague Giles Martin who has a very fine [collection of pictures of Ohio buildings](https://www.flickr.com/photos/75905404@N00/collections/72157600078652323/?ref=lorcandempsey.net) on Flickr.
### A timeline
URL: https://www.lorcandempsey.net/a-timeline/
Last updated: 2020-10-28T09:18:38.000Z
Here is what I saw at the end of the page when I did a Google search on Edmund Burke …
[](https://www.google.com/archivesearch?rlz=1C1GGLS%5Fen-USUS296US304&sourceid=chrome&ie=UTF-8&q=edmund+burke&um=1&scoring=t&sa=X&oi=timeline%5Fresult&resnum=14&ct=title&ref=lorcandempsey.net)
This functionality is available in Google News. I did not see it immediately in Google Book Search, although book content is contributing to the timeline.
I tried a few names, but it only comes up for some. In my few attempts they seemed to be pre-20th Century names.
As Google develops richer book/magazine indexes and retrospective news indexes, it will be interesting to see what services are built over these resources.
There is a qualifying note: “Dates associated with search results are estimated and are determined automatically by a computer program.”
### Museum studies
URL: https://www.lorcandempsey.net/museum-studies/
Last updated: 2020-10-28T09:18:43.000Z
The UK academic world was in a frenzy yesterday as the results of the Research Assessment Exercise were published. In this process, the work of academic departments is graded on a scale from 4\* (‘world leading’) down. It is important for both reputation and revenue, as the results are keenly observed and are used to allocate public research funding.
See the [Times Higher](https://www.timeshighereducation.co.uk/story.asp?sectioncode=26&storycode=404786&c=2&ref=lorcandempsey.net) for details and the [post](https://hangingtogether.org/?p=591&ref=lorcandempsey.net) on HangingTogether by my colleague John MacColl for some context.
The [Department of Museum Studies](https://www.le.ac.uk/ms/?ref=lorcandempsey.net) at the University of Leicester has particular reason to be pleased.
> But the RAE also – by design – exposes pockets of excellence.
> The university rated as having the greatest cluster of world-leading researchers of any discipline in any university in the UK is Leicester.
> It had 65% of its staff rated 4\* and 30% 3\* – in museum studies. \[[BBC NEWS | UK | Education | Many UK researchers ‘world class’](https://news.bbc.co.uk/2/hi/uk%5Fnews/education/7788718.stm?ref=lorcandempsey.net)\]
### Card Catalogue Online
URL: https://www.lorcandempsey.net/card-catalogue-online/
Last updated: 2020-10-28T09:18:45.000Z
I was interested to come across the University of Bristol’s ‘Card catalogue online’, a resource based on scanned images of catalogue cards.
> The digitisation project involved scanning 300,000 cards covering pre-1978 material held in the Arts and Social Sciences Library and all other branch libraries (except the Medical Library).
> As well as providing a browse facility that gives users access to images of the original cards onscreen, Card Catalogue Online is able to perform full-text searches of the item descriptions recorded on the cards.
\[[Bristol University | Information Services | Card Catalogue Online launched](https://www.bris.ac.uk/is/news/2008/cardcat.html?ref=lorcandempsey.net)\]
[](https://bristol.dilib.info/?ref=lorcandempsey.net)
[Edmund Burke](https://worldcat.org/identities/lccn-n79-40055?ref=lorcandempsey.net) was a sometime MP for Bristol.
### QOTD: putting book info in the flow
URL: https://www.lorcandempsey.net/qotd-putting-book-info-in-the-flow/
Last updated: 2020-10-28T09:18:47.000Z
Mike Shatzkin writes about the changing environment for publishers in *Publishers’ Weekly*. There are some familiar themes …
Network concentration (Amazon) and diffusion (recommendation and referral from social sites, widgets, …) …
> Print book review media and subscription book clubs are fewer in number and, most critically, bricks-and-mortar retail shelf space for books is being reduced. At the same time, new channels to promote and sell are opening up. Consumers started telling each other about books with Amazon customer reviews a decade ago; now they’re doing the same at BN.com and through general-interest gathering points like MySpace, Facebook and Twitter, and at a plethora of sites like LibraryThing, Shelfari and GoodReads dedicated to book conversation. Bits and pieces of books are used for Web marketing or sold in installments, placed in e-mails or RSS feeds, or even combined with material from other sources and fed back to the consumer as a unique book printed on demand.
> While sales of books through bricks-and-mortar locations are stagnant, sales through online channels, which today principally means Amazon, are growing. A goodly portion of those sales are driven by “referrals” from specialized Web sites continually sprouting throughout the Internet as well as referrals driven by those publisher widgets commonly found on social networking sites. And this is all just the beginning. \[[What the Hell Is XML? – 12/15/2008 – Publishers Weekly](https://www.publishersweekly.com/article/CA6622219.html?ref=lorcandempsey.net)\]
Network reputation management …
> The reduction of general book review media, print and broadcast, and the reduction in bricks-and-mortar bookstores are already forcing publishers to learn new ways to market and sell their titles. The shift from traditional to digital marketing is already changing publishers’ mindset when books are acquired. (“Does this author have a Web site?”) \[[What the Hell Is XML? – 12/15/2008 – Publishers Weekly](https://www.publishersweekly.com/article/CA6622219.html?ref=lorcandempsey.net)\]
The focus of the article is the use of XML to support new business practices in a network environment …
> In our new universe, the content encased in a well-formed XML file is the sun. The book, an output of a well-formed XML file, is only one of an increasing number of revenue opportunities and marketing opportunities revolving around it. It requires more discipline and attention to the rules to create a well-formed XML file than it did to create a book. But when you’re done, the end result is more useful: content can be rendered many different ways and cleaved and recombined inexpensively, unlocking sales that are almost impossible to capture cost-effectively if you start with a “book.” \[[What the Hell Is XML? – 12/15/2008 – Publishers Weekly](https://www.publishersweekly.com/article/CA6622219.html?ref=lorcandempsey.net)\]
Via [PersonaNonData](https://personanondata.blogspot.com/2008/12/answering-question-what-hell-is-xml.html?ref=lorcandempsey.net).
### Sustaining the digital investment
URL: https://www.lorcandempsey.net/sustaining-the-digital-investment/
Last updated: 2020-10-28T09:18:48.000Z
The *Blue Ribbon Task Force on Sustainable Digital Preservation and Access* was launched last year by the National Science Foundation and the Andrew W. Mellon Foundation in partnership with the Library of Congress, JISC, CLIR, and NARA.
It is jointly chaired by Fran Berman of the San Diego Supercomputer Center and by my colleague Brian Lavoie.
After considerable consultation, the Task Force has produced its interim year one report \[[pdf](https://brtf.sdsc.edu/biblio/BRTF%5FInterim%5FReport.pdf?ref=lorcandempsey.net)\]. From the summary …
> There is no general agreement, however, about who is responsible and who should pay for the access to, and preservation of, valuable present and future digital information. Creating sustainable economic models for digital access and preservation is a major challenge for all sectors, and the focus of investigation of the Blue Ribbon Task Force on Sustainable Digital Preservation and Access. …
> … During 2008, as the Task Force heard testimony from a broad spectrum of institutions and enterprises with deep experience in digital access and preservation, two things became clear: First, the problem is urgent. Access to data tomorrow requires decisions concerning preservation today. Imagine future biological research without a long-term strategy to preserve the Protein Data Bank (PDB), a digital collection that drives new insights into human systems and drug therapies for disease, and represents an investment of 100 billion dollars in research funding over the last 37 years. Decisions about the future of the PDB and other digital reference collections — how they will be migrated to future information technologies without interruption, what kind of infrastructure will protect their digital content against damage and loss of data, and how such efforts will be supported — must be made now to drive future innovation.
> Second, the difficulty in identifying appropriate economic models is not just a matter of finding funding or setting a price. In many institutions and enterprises, systemic challenges create barriers for sustainable digital access and preservation. \[Sustaining the digital investment: issues and challenges of economically sustainable digital preservation [pdf](https://brtf.sdsc.edu/biblio/BRTF%5FInterim%5FReport.pdf?ref=lorcandempsey.net)\]
The report brings together testimony, case studies, and a framing analysis. One of the interesting aspects of the working group is the range of expertise it assembles, across disciplines and institution types.
### QOTD: Innovation
URL: https://www.lorcandempsey.net/qotd-innovation/
Last updated: 2020-10-28T09:18:51.000Z
A couple of sentences in Joseph Stiglitz’s *Vanity Fair* critique of economic and financial policy over recent years jumped out at me:
> But innovation, like “change,” has no inherent value. It can be bad … as well as good. \[[Joseph E Stiglitz on capitalist fools. *Vanity Fair*](https://www.vanityfair.com/magazine/2009/01/stiglitz200901?ref=lorcandempsey.net)\]
### SEO
URL: https://www.lorcandempsey.net/seo/
Last updated: 2020-10-28T09:18:54.000Z
I have mentioned SEO (Search Engine Optimization) a few times as an increasingly important area of interest for librarians. However, as I have [suggested](https://blog.oclc.org/lorcand/archives/001810.html?ref=lorcandempsey.net), I come across resistance on the grounds that this is some sort of base or mendacious activity. We are very interested in interoperability, however, and for this reason it may be that Search Engine Interoperability is a more palatable expression. In this case interoperability means managing resources in ways which promote effective crawling, indexing and ranking by search engines. A reasonable goal, given the importance of search engines in the lives of library users.
Anyway, I repeat these points prompted by a post by Tony Hirst on the topic.
> What does information literacy mean in the age of web search engines? I’ve been arguing for some time (e.g. in [The Library Flip](https://ouseful.open.ac.uk/blogarchive/011081.html?ref=lorcandempsey.net)) that one of the core skills going forward for those information professionals who “help people find stuff” is going to be SEO – search engine optimisation. Why? Because increasingly people are attuned to searching for “stuff” using a web search engine (you know who I’m talking about…;-); and if your “stuff” doesn’t appear near the top of the organic results listing (or in the paid for links) for a particular query, it might as well not exist… \[[Revisiting the Library Flip – Why Librarians Need to Know About SEO « OUseful.Info, the blog…](https://ouseful.wordpress.com/2008/12/13/revisiting-the-library-flip-why-librarians-need-to-know-about-seo/?ref=lorcandempsey.net)\]
It is useful to think about the library website in this context. It is also important for materials which are unique to an institution/library: archival collections, institutional repositories, etc. It is also interesting to think about subject or other liaisons, or specialist library services, or advisory/reference materials. As libraries turn to assisted reputation management for their institutions (thinking about how faculty members, their expertise and their outputs are effectively disclosed on the network for example) it is an important area for investigation. This is a topic which deserves quite a bit more attention ….
Related entries:
- [SEO is part of our business](https://blog.oclc.org/lorcand/archives/001733.html?ref=lorcandempsey.net)
- [Repository interoperability](https://blog.oclc.org/lorcand/archives/001810.html?ref=lorcandempsey.net)
### Network environmental issues
URL: https://www.lorcandempsey.net/network-environmental-issues/
Last updated: 2022-11-08T15:20:47.000Z
I wrote a short piece for *Portal* last year.
> **Reconfiguring the Library Systems Environment**. *portal: Libraries and the Academy*, Vol. 8, No. 2, April 2008\. // [https://www.oclc.org/research/publications/archive/2008/dempsey-portal.pdf](https://www.oclc.org/research/publications/archive/2008/dempsey-portal.pdf?ref=lorcandempsey.net) (.pdf: 195K/18 pp.) \[[Lorcan Dempsey: Selected publications \[OCLC\]](https://www.oclc.org/research/staff/dempsey/publications.htm?ref=lorcandempsey.net)\]
The introductory remarks about the environment repeat many of the topics discussed in these pages in the last few years:
Think of some of the ways in which the environment that library users operate in has changed in recent years. Behaviors and expectations have been reconfigured in a network environment as more of what people do enters a network space.
- *Discovery happens elsewhere*: People discover items of interest in a variety of ways: on search engines, in their RSS aggregators, in the resource networks created on social network sites, in consumer recommendations, on collaborative bookmarking sites, in reading and course lists, and so on. Increasingly, we cannot expect users to seek out individual Web sites or resources.
- *In the flow*: Now that readers and writers increasingly organize their work in network environments, we must build library services around their workflow (or learnflow, or researchflow, or…). This flow is supported by a range of personal tools (RSS aggregators, toolbars, …), network services (Facebook, del.icio.us, …), and by prefabricated workflow support systems (course management systems, for example). Readers and writers expect to work with information resources in those environments, to “gather, create and share.” An important issue here is that the applications that manage the flow (whether it is a social networking site, an RSS aggregator, or a course management system) become the consumers of resources. This creates a demand for machine interfaces: RSS feeds, portlets, Web services, and so on.
- *Information is abundant; attention is scarce*: As resources, tools, and environments proliferate so does the attention available for any single one of them decline. The implication here for libraries is clear: readers and writers have many choices, so convenience of use is really important.
- *Social value and personal value*: Scholarly, cultural, and information products are social creations, and their reception is often social. The library model supports this in various ways, but the social aspect of the creation and reception of knowledge has tended to happen outside the library, in the seminar room, the conversation, the review. However, we are now seeing social value created around scholarly and cultural products in network services (think of Flickr, Connotea, LibraryThing, …). Libraries have begun to think about pushing services into social networking sites and adding social networking features to their own services. How do we create social value within library information services?
- *The rich get richer–aggregation of supply and demand*: Our network experience is characterized by large hubs that exert strong gravitational force on users. Google, Amazon, Realtor.com, eBay, expedia, and so on all aggregate supply. They provide a service that connects a unified discovery experience to multiple fulfillment services; they reduce the effort of getting things done on the network by removing clicks. They also aggregate demand by mobilizing large numbers of users. In this way, hubs provide incentives for both suppliers and consumers to participate; the more users who participate, the more valuable hubs become. I have discussed this dynamic at some length elsewhere in relation to library resources.
- *Data works hard*: On the network, we shed data about what we do; we leave tracks. The mobilization of this data is now a central part of our Web experience. Services adapt what they do based on what they know about you (such as Amazon recommendations); they create new services by comparing what they know about different people; they provide contribution platforms for data (for example, reviews and recommendations).
These and other factors have radically changed the user and service environment in which libraries operate. Libraries are also working through what it means to offer services in this type of environment. However, a major issue has emerged. The library systems environment was, by and large, shaped before the current period, and it was shaped by different requirements. In the remainder of this brief article, I want to consider that systems environment and suggest some possible directions as we look to better align our capacities to changed circumstances.
### Liber shifts gears
URL: https://www.lorcandempsey.net/liber-shifts-gears/
Last updated: 2020-10-28T09:18:57.000Z
And speaking of the *[Liber Quarterly](https://liber.library.uu.nl/index.html?ref=lorcandempsey.net)*, it is good to see that they have made it freely available on the web. It will be interesting to see if we now come across more references to it.
My colleague Ricky Erway has an [article](https://liber.library.uu.nl/publish/issues/2008-3%5F4/?000263&ref=lorcandempsey.net) in the current issue. This provides an overview of the recent [Shifting Gears](https://www.oclc.org/programs/publications/reports/2007-02.pdf?ref=lorcandempsey.net) report \[[pdf](https://www.oclc.org/programs/publications/reports/2007-02.pdf?ref=lorcandempsey.net)\]. Ricky then surveys a range of initiatives which are looking at changing practices so that they can move special materials to the “surface of the web” more quickly and in greater volumes.
Incidentally, for those not familiar with it, [Liber](https://www2.kb.dk/liber/currentinitiatives/index.htm?ref=lorcandempsey.net) is the European association for research libraries.
### Library value
URL: https://www.lorcandempsey.net/library-value/
Last updated: 2020-10-28T09:19:00.000Z
We are seeing more interest in demonstrating value. Here are two rather different items on this topic.
The first is an article on ROI in the current *LIBER Quarterly* by Paula Kaufman, Dean of Libraries at UIUC.
> University administrators are asking library directors to demonstrate their library’s value to the institution in easily articulated quantitative terms that focus on outputs rather than on traditionally reported input measures. This paper reports on a study undertaken at the University of Illinois at Urbana-Champaign that sought to measure the return on the university’s investment in its library. The study sought to develop a quantitative measure that recognizes the library’s value in supporting the university’s strategic goals, using grant income generated by faculty using library materials. It also sought to confirm the benefits of using electronic resources and the resulting impact on productivity over a 10-year period. The results of this study, which is believed to be the first of its kind, represent only one piece of the answer to the challenge of representing the university’s total return from its investment in its library. \[[Liber Quarterly. The Library as Strategic Investment](https://liber.library.uu.nl/publish/issues/2008-3%5F4/?000269&ref=lorcandempsey.net).\]
The discussion of how they settled on the approach they did was of particular interest, as it looks at what is of value to the University – research income generation, in this case – and how the contribution of the library to that might be demonstrated.
The second is a presentation \[[ppt](https://www.library.nuigalway.ie/assets/inuls2007/johnwright-fri0945.ppt?ref=lorcandempsey.net)\] from last year’s INULS conference (Irish National and University Library Staff Conference). It is by John Wright from the University of Bangor in Wales. Bangor hit the headlines a few years ago as the University proposed major cuts in library services. The following extract was widely discussed.
> “the support…from the qualified subject librarians is hard to justify in value-for-money terms at a time when the process of literature searches is substantially de-skilled by online bibliographical resources.”
John Wright repeats this quote in his presentation and talks about how the University and library arrived at this point, and more interestingly the steps they took to improve the situation. His discussion is under four heads: 1\. Demonstrating Value, 2\. Perception and Aesthetics, 3\. Collaboration, 4\. Innovation.
“Value for money”, as one of my colleagues suggested recently, seems a sterner expression than ROI.
### Holiday greeting
URL: https://www.lorcandempsey.net/holiday-greeting/
Last updated: 2020-10-28T09:19:01.000Z
It’s time for the OCLC Research [holiday card](https://www.oclc.org/research/holidaycard/?ref=lorcandempsey.net). Check it out [here](https://www.oclc.org/research/holidaycard/?ref=lorcandempsey.net), and make sure to click on the reindeer for holiday reading/listening/viewing suggestions.
### Discovery to delivery
URL: https://www.lorcandempsey.net/discovery-to-delivery/
Last updated: 2020-10-28T09:19:03.000Z
I guess that Discovery to delivery, and the related discover, locate, request, deliver, might be characterised bemes, maybe somewhat old in the tooth bemes. A beme is a purposeful or business meme, an idea which is memorably
### It's not there ...
URL: https://www.lorcandempsey.net/its-not-there/
Last updated: 2020-10-28T09:19:05.000Z
I was going to do a short entry quoting from Benjamin Schwartz’s review of [David Thompson’s](https://www.worldcat.org/identities/lccn-n50-12250?ref=lorcandempsey.net) [*Have you seen? : a personal introduction to 1,000 films*](https://www.worldcat.org/oclc/190621111?ref=lorcandempsey.net) in the [November issue of the Atlantic](https://www.theatlantic.com/doc/200811?ref=lorcandempsey.net).
I went looking for it a few days ago but there appeared to be a mistake: the photo and title were for the Thomson book, but the [review](https://www.theatlantic.com/doc/200811/editors-choice?ref=lorcandempsey.net) was for another: [*Europe Between the Oceans*](https://www.worldcat.org/oclc/173182722?ref=lorcandempsey.net) by [Barry Cunliffe](https://www.worldcat.org/identities/lccn-n79-59942?ref=lorcandempsey.net), This was the [feature review](https://www.theatlantic.com/doc/200812/editors-choice?ref=lorcandempsey.net) in the December issue.
I just went back now, and the error has not been corrected. I was very surprised. Such an error would stand in the print issue; but don’t we expect the web to be right up to date?
### Centering the decentralized identity ...
URL: https://www.lorcandempsey.net/centering-the-decentralized-identity/
Last updated: 2020-10-28T09:19:07.000Z
Andy Powell, [network resident](https://blog.oclc.org/lorcand/archives/001773.html?ref=lorcandempsey.net), has an interesting post about his ‘fractured’ network identity. How does he define identity?
> “Digital identity is the online representation of an individual within a community, as adopted by that individual and/or projected by others. An individual may have multiple digital identities in multiple communities.” \[[Andy Powell, eFoundations](https://efoundations.typepad.com/?ref=lorcandempsey.net)\]
He describes how his digital identity is ‘fractured’ across many environments (FaceBook, Flickr, various home pages and blogs, Second Life, twitter, etc). Various professional or personal affiliations are explicitly visible in several ‘friendspaces’ (my word), on FaceBook and Twitter for example. Andy even confesses to an ‘identity crisis’ around his second life identity, Art Fossett.
> I also have something of an identity crisis around Art Fossett – specifically concerning how closely the digital identities of Andy Powell and Art Fossett should be related. \[[eFoundations: define:digital identity](https://efoundations.typepad.com/efoundations/2008/11/definedigital-identity.html?ref=lorcandempsey.net)\]
Reading the entry, it seemed to me that Andy is talking about ‘centering’ this ‘decentralized identity’ in various ways: he talks about wanting to ‘consolidate’ his network presence.
(John Breslin schematically represents decentralized identity in a [blog entry](https://www.johnbreslin.com/blog/2007/03/01/linking-personal-posted-content-across-communities/?ref=lorcandempsey.net) of some time ago.)
There are various centering or consolidating strategies …
Andy talks about limiting the number of ‘handles’ his identity has – email addresses and user names, although he is not in a position where his personal identities can override his current work identity (at Eduserv).
He is working to center his network presence at [https://andypowe11.net/](https://andypowe11.net/?ref=lorcandempsey.net) and has some interesting comments about steps taken or to be taken. These include the suggestion that his former place of work put redirects from historically superseded network presences to his current one so that he can capture their ‘Google juice’, which raises interesting questions about our view of the historical record on the web.
He also has some advice about the use of third party services, about control of domain names, and about where you build up ‘google juice’ as moving it may be outside of your control.
Several things struck me reading this post …
- Andy’s concerns here are probably in advance of most people’s, but it seems clear that managing our network presences and the relationships between them is becoming of more interest. And this cuts across previous boundaries – between work, family and friends, for example – in different ways.
- My network identity is less decentralized than Andy’s: overall, I am less residential 😉 Until recently, I would have seen this ‘fracture’ as simply a part of an ongoing transition into new ways of doing things. And I wouldn’t have had the patience or the inclination to adopt various centering strategies. That said, I have been more conscious recently of where I want my network presence to be ‘signed’ and where I don’t. To take an example close to home, I wrote some longish reviews on items in Worldcat; recently, I realised that I would like the system to be able to support in some way my assertion that I was their author, and now it does by linking to a profile page. I have tended to use lisld as a handle in a variety of places. Now, I would probably more consistently use something like LorcanDempsey where I was more concerned about ‘signature’, although I am quite attached to lisld 😉
- Of course, Google is a strong bottom-up centering service (see Tony Hirst’s interesting [suggestion](https://ouseful.wordpress.com/2008/11/20/where-is-the-open-university-homepage/?ref=lorcandempsey.net) that an institution’s de facto home page is the first page of Google results in a search for that institution). My first-page Google results tend to be dominated by this blog, but there are also current and previous work pages, some articles come and go, and more recently Wikipedia and Facebook make a showing. None of these is at a domain name controlled by me. This blog was established as an internal OCLC communications tool for a year before it was externalised so it is ‘located’ at OCLC (in several ways). Now, I am sure that it gets a ranking ‘lift’ from the OCLC domain name, but it also means that I cannot bring it with me as it now stands if I ever leave. In a sense, I lose some of that network capital. Of course this is quite reasonable from another view, but it does raise interestingly the balance between individual and institution.
- My name is not unique. However, it is not very common. Andy notes his ‘Google nemesis’, Andy Powell of Wishbone Ash. It would be interesting to [know more](https://blog.oclc.org/lorcand/archives/001385.html?ref=lorcandempsey.net) about what the impact of findability in Google has been on the naming of children.
- Now, I know that there are various initiatives underway which may make our identities more portable. I assume – hope – that we will end up with the ability to port our identities flexibly, but that we also retain the ability to support decentralised identities which may not know very much, or anything, about each other 😉
### Edublog awards
URL: https://www.lorcandempsey.net/edublog-awards/
Last updated: 2020-10-28T09:19:09.000Z
I was pleased to see that this blog was nominated in the [Best Librarian/Library Blog](https://edublogawards.com/2008/best-librarian-library-edublog-2008/?ref=lorcandempsey.net) category for the 2008 Edublog award.
I notice that my former colleagues, Brian Kelly and Andy Powell/Pete Johnston, are nominated in the [educational tech support category](https://edublogawards.com/2008/best-educational-tech-support-edublog-2008/?ref=lorcandempsey.net) for the [UK Web Focus](https://ukwebfocus.wordpress.com/?ref=lorcandempsey.net) and [eFoundations](https://efoundations.typepad.com/efoundations/?ref=lorcandempsey.net) blogs respectively.
Go on [over](https://edublogawards.com/2008/best-librarian-library-edublog-2008/?ref=lorcandempsey.net) and have a look ….
### Penguin dating
URL: https://www.lorcandempsey.net/penguin-dating/
Last updated: 2020-10-28T09:19:11.000Z
I have just come across [PenguinDating](https://penguin.match.com/matchuk/cp.aspx?cpp=en-uk/landing/penguin/index.html&TrackingID=525527&BannerID=656426&ref=lorcandempsey.net) “where book lovers meet”, a partnership between Penguin and match.com.
> You can go on singles nights in libraries and there’s even a hybrid speed-dating book club in a pub. Here at Penguin Books we’ve teamed up with match.com to create penguindating.co.uk. You can be intrigued, perplexed, turned off or turned-on by our singles’ reading habits. Now we don’t want to get too snobby here, because one woman’s Vampire Encyclopaedia is another’s love at first bite. A young buck reading a history of Goldman Sachs might be exactly what you’re after even though you’re busy stockpiling Marian for a week in the Balearics. Sometimes it’s enough to provoke curiosity when a person’s reading taste jars with your mental image of what they should be reading. That guy who looks like he’s just clocked-off from a building site, surely he can’t be clutching the collected works of Jane Austen? \[[Find Singles Online Dating with Match.com](https://penguin.match.com/matchscene/article.aspx?articleid=9866&menuid=7&lid=429&TrackingID=525527&ref=lorcandempsey.net)\]
Lots of potential for libraries here ….
### Das Bundesarchiv and Wikimedia Commons
URL: https://www.lorcandempsey.net/das-bundesarchiv-and-wikimedia-commons/
Last updated: 2020-10-28T09:19:13.000Z
An announcement from Das Bundesarchiv (German National Archive) and Wikimedia Commons:
> Starting on Thursday Dec 4, 2008, Wikimedia Commons will witness a massive upload of new images. We are anticipating about 100,000 files from a donation from the [German Federal Archive](https://www.bundesarchiv.de/?ref=lorcandempsey.net "https://www.bundesarchiv.de"). These images are mostly related to the history of Germany (including the German Democratic Republic) and are part of a cooperation between [Wikimedia Germany](https://www.wikimedia.de/?ref=lorcandempsey.net "https://www.wikimedia.de") and the Federal Archive. \[[Commons:Bundesarchiv – Wikimedia Commons](https://commons.wikimedia.org/wiki/Commons:Bundesarchiv?ref=lorcandempsey.net)\]
This is another interesting example of a major cultural organization putting materials in an important web destination. Presumably there is some background context which explains why they are going here rather than in the Flickr [Commons](https://flickr.com/commons?ref=lorcandempsey.net) which has been providing a venue for image collections from several cultural institutions (most recently The National Library of New Zealand and the Imperial War Museum).
A notable part of the arrangement is the use of German National Library authority files.
> The other part of the cooperation is a tool for linking people from a list compiled by the Federal Archive to the German Wikipedia Persondata and to the person authority file of the [German National Library](https://www.d-nb.de/?ref=lorcandempsey.net "https://www.d-nb.de/") (something German Wikipedia has already been doing since 2005). \[[Commons:Bundesarchiv – Wikimedia Commons](https://commons.wikimedia.org/wiki/Commons:Bundesarchiv?ref=lorcandempsey.net)\]
Via my colleague Art Smith.
### The changing education experience
URL: https://www.lorcandempsey.net/the-changing-education-experience/
Last updated: 2020-10-28T09:19:14.000Z
The Guardian published a supplement on the ‘digital student’ the other day. There is some general context and there is a range of short pieces on specific approaches or projects. This is all written for a general audience so there is no great detail and it is quite anecdotal.
As context, there is an interview with David Melville chair of the [Committee of Enquiry into the Changing Learning Experience](https://www.clex.org.uk/emergingfindings.php?ref=lorcandempsey.net) …
> But perhaps the largest surprise so far is the continuing value students place on face-to-face contact, despite the time they spend on the web. This does not mean they regard teaching staff in the same way as their predecessors did. “Because web 2.0, Google, Wikipedia are all about being able to change things yourself, the expectations of learners change as a result of that,” says Melville. “Universities are beginning to notice this. There is a greater expectation from students that they are involved in the design of their education.” \[[Students fashion their own education | Digital student | The Guardian](https://www.guardian.co.uk/digitalstudent/1?ref=lorcandempsey.net)\]
… and a general background piece ….
> Technology has dramatically changed the way students experience university life, and not just in terms of the number of gadgets they own. It has affected where and how they study, helped them collaborate with each other and broken down barriers between students and teachers, social life and study. It has also given students a greater voice in the way they learn. \[[Academia tackles the future | Digital student | The Guardian](https://www.guardian.co.uk/digitalstudent/academia?ref=lorcandempsey.net)\]
Here are some snippets from specific treatments of approaches or projects …
The University of Hertfordshire has a scheme where academic staff can consult with their more savvy students about technology issues …
> This is the result of a university scheme which makes use of the fact that students’ IT know-how is often superior to that of their teachers. The scheme, which began in the business school but has since expanded to other departments, provides a 15-strong helpdesk of student mentors, charged with helping lecturers sort out their IT difficulties and make better use of the university’s virtual learning environment (VLE), StudyNet, as well as advising staff on ways to make e-learning more engaging for students. \[[Mentors with a difference | Digital student | The Guardian](https://www.guardian.co.uk/digitalstudent/mentors?ref=lorcandempsey.net)\]
Which leads to an interesting role reversal …
> In return, students get valuable experience to put on their CVs, and an insight into the teaching and learning process. Ramsey says: “It’s tempting to say to a lecturer ‘I’ll do it for you.’ But we are there to guide. You show them better ways of doing things.” \[[Mentors with a difference | Digital student | The Guardian](https://www.guardian.co.uk/digitalstudent/mentors?ref=lorcandempsey.net)\]
Podcasting features strongly in several places. There is some discussion of iTunes. Here are some numbers from the Open University …
> The OU’s move onto iTunes has proved incredibly popular, with an impressive 1m downloads in its first 120 days. Its biggest hit at the moment is a podcast about evolution and Charles Darwin, followed closely by introductory Spanish. Surprisingly 87% of downloads are from outside the UK, and the bulk are downloaded by students who haven’t paid to be at the OU. “Approximately one person every minute downloads a piece of audio or video from the OU who has never even heard of us,” says Scott. \[[Professorial podcasts | Digital student | The Guardian](https://www.guardian.co.uk/digitalstudent/podcasts?ref=lorcandempsey.net)\]
And Oxford …
> Oxford says it is delighted with its early success on iTunes. In the first two weeks of October it notched up 189,861 downloads in total. “It’s getting us such a fantastic audience,” says Carolyne Culver, the university’s head of external communications. “Stiglitz on the credit crunch used to reside on the website of one of our departments and it was getting 3-400 downloads a month. In three weeks in October it got 16,500 downloads and remains on top of the charts.” \[[iWonders | Digital student | The Guardian](https://www.guardian.co.uk/digitalstudent/i-wonders?ref=lorcandempsey.net)\]
The use of services like iTunes or YouTube means that popularity measures can be tracked …
> Seb Schmoller, chief executive of the Association for Learning Technology, says the increasing importance of star performers to universities mirrors what is happening in life generally and warns that iTunes’ success might prove a burden for superstar lecturers, who get quite a lot of email feedback from students. “People at the top of the iTunes list have found themselves completely overwhelmed by the impact that that has had on them,” he says. “Although I don’t think they’ve minded.” \[[Professorial podcasts | Digital student | The Guardian](https://www.guardian.co.uk/digitalstudent/podcasts?ref=lorcandempsey.net)\]
On the use of texting at the University of Wolverhampton ..
> While students, 98% of whom had a mobile phone, welcomed texts containing administrative information, such as reminders about an overdue library book, their reaction to learning-related texts was mixed.
> The main barrier was a cultural one: students use their mobiles for their social life and contacting family and perceive their education to be separate, according to Melas’s report. \[[Push the button | Digital student | The Guardian](https://www.guardian.co.uk/digitalstudent/texting?ref=lorcandempsey.net)\]
On e-portfolios …
> Evidence is growing that e-portfolios may aid student retention, possibly because of the support and feedback elements. Initially, e-portfolios were used with students from non-standard backgrounds, such as returning learners, and those on vocational courses where reflection is important, but that is changing. Some institutions now insist on them for all students; they are useful for modular courses, and as an anti-plagiarism tool because they can help track the development of an essay. \[[Electronic showcase | Digital student | The Guardian](https://www.guardian.co.uk/digitalstudent/showcase?ref=lorcandempsey.net)\]
And there is a short piece in which several students describe their practices …
> I use everything a lot more since I came to university. My laptop is on all day so I can check what’s going on, what I should be doing, and so I can Google anything. \[[Students’ views | Digital student | The Guardian](https://www.guardian.co.uk/digitalstudent/views?ref=lorcandempsey.net)\]
### Cultural heritage resources at UKOLN
URL: https://www.lorcandempsey.net/cultural-heritage-resources-at-ukoln/
Last updated: 2020-10-28T09:19:16.000Z
I notice that my former colleagues at UKOLN have created a set of web pages pulling together support services for the cultural heritage communities …
> ## What will you find here?
>
> Information on a range of topics relating to the use of digital resources and technology. Follow the Topic links in the right hand side bar to see the full list of topics. Currently these include [collection description](https://www.ukoln.ac.uk/cultural-heritage/collection-description/?ref=lorcandempsey.net), [digital preservation](https://www.ukoln.ac.uk/cultural-heritage/preservation/?ref=lorcandempsey.net), [metadata](https://www.ukoln.ac.uk/cultural-heritage/metadata/?ref=lorcandempsey.net), [social networking services](https://www.ukoln.ac.uk/cultural-heritage/social-networks/?ref=lorcandempsey.net), [supporting the user experience](https://www.ukoln.ac.uk/cultural-heritage/user-experience/?ref=lorcandempsey.net) and [Web 2.0](https://www.ukoln.ac.uk/cultural-heritage/web2/?ref=lorcandempsey.net).
>
> ## Key Features
>
> Why not start with [IntroBytes ](https://www.ukoln.ac.uk/cultural-heritage/documents/?ref=lorcandempsey.net)documents for quick introductions to a variety of topics, and then move on to [Best Of](https://www.ukoln.ac.uk/cultural-heritage/best-of/?ref=lorcandempsey.net) to find other useful sources of information and *[Ariadne](https://www.ukoln.ac.uk/cultural-heritage/ariadne/?ref=lorcandempsey.net)* to keep up to date. If you are interested in attending a seminar or workshop, then consult [Meet and Learn](https://www.ukoln.ac.uk/cultural-heritage/events/?ref=lorcandempsey.net) to find out what events are coming up. Just follow the links in the right hand side bar.
>
> \[[UKOLN | Cultural Heritage | Home Page](https://www.ukoln.ac.uk/cultural-heritage/?ref=lorcandempsey.net)\]
The set of short briefing documents, Introbytes, looks like a useful resource.
> UKOLN has published a range of short briefing documents aimed at supporting use of networked technologies and services in the cultural heritage sector. The initial series of documents covers Web 2.0 (with a focus on blogs and social networks), usability, collection description, metadata and preservation. \[[UKOLN | Cultural Heritage | Briefing Documents](https://www.ukoln.ac.uk/cultural-heritage/documents/?ref=lorcandempsey.net)\]
### Zotero and WC lists
URL: https://www.lorcandempsey.net/zotero-and-wc-lists/
Last updated: 2020-10-28T09:19:17.000Z
I have been looking at [Zotero](https://www.zotero.org/?ref=lorcandempsey.net) again while on vacation, as one does. I was impressed earlier to be able to import [WorldCat lists](https://www.worldcat.org/webservices/root/search/lists?ref=lorcandempsey.net) to Zotero courtesy of [Coins](https://ocoins.info/?ref=lorcandempsey.net). Go to the citations view for the list and click on the Zotero folder icon in the address bar (assuming you have Zotero installed). It asks you if you want to import all or some items.
Thanks to Bob Robertson-Boyd for pointing this out to me. It would have been helpful if I had read his [blog entry](https://worldcat.org/blogs/archives/2008/11/coins-in-worldcat.htm?ref=lorcandempsey.net) on the matter before I asked him, but there you go …
### Social networks and citation tools for scientists
URL: https://www.lorcandempsey.net/social-networks-and-citation-tools-for-scientists/
Last updated: 2020-10-28T09:19:20.000Z
And [speaking of](https://blog.oclc.org/lorcand/archives/001822.html?ref=lorcandempsey.net) Nature Network, I was interested to see this list of ‘social networks’ for scientists at the [Science@Cambridge](https://www.lib.cam.ac.uk/scienceportal/?ref=lorcandempsey.net) site.
> ## Science Social Networks
>
> - [Research Gate](https://www.researchgate.net/?ref=lorcandempsey.net)
> - [Nature Networks](https://network.nature.com/?ref=lorcandempsey.net)
> - [2collab](https://www.2collab.com/?ref=lorcandempsey.net)
> - [Within3 (for Medics)](https://www.within3.com/?ref=lorcandempsey.net)
>
> \[[science@cambridge: science portal for Cambridge students | Cambridge University Library](https://www.lib.cam.ac.uk/scienceportal/?ref=lorcandempsey.net)\]
And the following list of citation tools, including Connotea, the Nature service:
> ## Citation Organiser Tools
>
> - [CiteULike](https://www.citeulike.org/?ref=lorcandempsey.net)
> - [Connotea](https://www.connotea.org/?ref=lorcandempsey.net)
> - [Mendeley](https://www.mendeley.com/?ref=lorcandempsey.net)
> - [Lab Meeting](https://www.labmeeting.com/?ref=lorcandempsey.net)
>
> \[[science@cambridge: science portal for Cambridge students | Cambridge University Library](https://www.lib.cam.ac.uk/scienceportal/?ref=lorcandempsey.net)\]
I was aware of some of these, not all. Clearly, Nature has made a significant investment here and is thinking about how to create community in various ways. It will be interesting to see what a list like this looks like in a couple of years.
Update: Ben Toth added four more services in a comment. Here they are …
[doc2doc](https://doc2doc.bmj.com/?ref=lorcandempsey.net)
> doc2doc was set up to improve the working lives of doctors by providing an independent place where doctors can talk freely. doc2doc is maintained by the [BMJ Group](https://group.bmj.com/?ref=lorcandempsey.net). The BMJ Group is a trusted global medical publisher providing a wide range of products and services that improve the decisions doctors make every day. \[[About doc2doc – Doctors Community, Forums and Doctors Networking](https://doc2doc.bmj.com/about.html?ref=lorcandempsey.net)\]
[myExperiment](https://www.myexperiment.org/?ref=lorcandempsey.net)
> The myExperiment Virtual Research Environment enables you and your colleagues to share digital items associated with your research — in particular it enables you to share and execute scientific workflows. \[[myExperiment](https://www.myexperiment.org/?ref=lorcandempsey.net)\]
[BiomedExperts](https://www.biomedexperts.com/?ref=lorcandempsey.net)
> BioMedExperts is a new online community that connects biomedical researchers to each other through the display and analysis of the networks of co-authors with whom each investigator works to publish scientific papers. The comprehensive system of pre-populated expert profiles, coupled with the ability to analyze all associated professional connections within the co-author network, allows scientists and researchers across organizations the ability to share data and collaborate in ways never before considered. \[[BiomedExperts – About](https://www.biomedexperts.com/Portal/AboutBME.aspx?ref=lorcandempsey.net)\]
[PHLab](https://phlab.org/?ref=lorcandempsey.net)
> PH Lab has been developed to allow professionals working in public health to find out about the social networking platforms and other digital tools that support the Department of Health’s Informing Healthier Choices initiative. \[[PHLab](https://phlab.org/?ref=lorcandempsey.net)\]
Ben asks: “I’m wondering about the implications for librarians if these things take off.”
The emergence of these services is symptomatic of the move from website to workflow as our unit of attention on the web, and of the social nature of intellectual work in this context. We want to get things done, by tying things together ourselves or by having them tied together in prefabricated services. It is interesting to see how many of them strongly feature literature resources. Books and articles are social objects around which networks can be built, and the workflows which manage those networks become important consumers of information services.
### LabLit
URL: https://www.lorcandempsey.net/lablit/
Last updated: 2020-10-28T09:19:22.000Z
A little off topic … I was interested just now to come across [LabLit.com magazine](https://www.lablit.com/?ref=lorcandempsey.net), an online presence devoted to the representation of science in literature.
> LabLit.com is dedicated to real laboratory culture and to the portrayal and perceptions of that culture – science, scientists and labs – in fiction, the media and across popular culture. The site is intended for non-scientists as well as scientists, and the goal is to inform, entertain and surprise (see the launch [Editorial](https://www.lablit.com/article/1?ref=lorcandempsey.net "Editorial") for more information). \[[About LabLit.com](https://www.lablit.com/about?ref=lorcandempsey.net)\]
Via [Mind the Gap](https://network.nature.com/people/UE19877E8/blog?ref=lorcandempsey.net), the blog – on [Nature Network](https://network.nature.com/blogs?ref=lorcandempsey.net) – of the editor, [Jennifer Rohn](https://network.nature.com/people/UE19877E8/profile?ref=lorcandempsey.net).
### Holiday and RSS
URL: https://www.lorcandempsey.net/holiday-and-rss/
Last updated: 2020-10-28T09:19:24.000Z
No posts for the next few days over the (US) holiday period as we are travelling.
A parting note on reading feeds. I have shifted to Chrome for much of my web use. Although there are a few things I miss, overall I like the snappiness of its response. This means that I have also shifted to Google Reader for much of my feed reading. I never took to BlogLines, and Chrome is without the two environments in which I did most of my feed reading: the integrated reader of Flock and the Sage extension that I use in FireFox. A few random notes about this:
1. Before shifting to a network level reader I had an intermittently synchronized sets of feeds. Different browsers at work and at home were not always in synch (I would typically have four overlapping sets of feeds, as I would use FireFox and Flock on work and home machines). This was a feature. It was nice to open up a different set of feeds, even if the differences were minor. And if I hadn’t used a particular browser for a while, FireFox at home for example, when I returned to it I would rediscover feeds I hadn’t seen for a while. There might be a small core, but the variety was good. It is a bit boring turning to the same set of feeds each time now 😉
2. Of course, this represents a move further into [Googleville](https://www.surfchrome.com/images/stories/gallery/chrometoon-googleville-satire/initial-mock-cartoons/chrometoon-googleville-satire-01.jpg?ref=lorcandempsey.net). I have also been using Google Blogsearch as my main blog search tool. I still look at Ask/Bloglines but less often. That said, I notice that recently Google appears to be indexing whole ‘blog pages’, including sidebar text and so on, which is a bit confusing. A search on ‘lorcan dempsey’ for example will bring back newly published pages in which ‘lorcan dempsey’ appears in the blogroll. I wonder why the change.
3. As I say, one result of moving between sets of feeds was that I would sometimes go for a while without reading one feed or another. When I didn’t read a feed for a while, I found myself imagining that it had faded away and that other people were also not reading it 😉 Of course, I knew this wasn’t the case, but it was an interesting reminder of how much the rock we stand on influences our perspective …
Writing this, I was reminded of Nicholas Carr’s post on the [centripetal web](https://www.roughtype.com/archives/2008/10/the%5Fcentripetal.php?ref=lorcandempsey.net).
### Criss cross catalogs
URL: https://www.lorcandempsey.net/criss-cross-catalogs/
Last updated: 2020-10-28T09:19:25.000Z
It is interesting to look at the variety of ways in which newer catalog/discovery layer deployments are linking to third party services.
The list of [VuFind](https://www.vufind.org/index.php?ref=lorcandempsey.net) implementations on their ‘[about](https://www.vufind.org/about.php?ref=lorcandempsey.net)‘ page provides a good sample. There is some variety within the overall VuFind pattern.
Here is an example from a result for an edition of Voss by Patrick White at the [National Library of Australia](https://catalogue.nla.gov.au/?ref=lorcandempsey.net), providing the ability to bookmark the item in Delicious or to go through to an entry in LibraryThing.

Here is an author results page for Patrick White in the [Yale beta implementation](https://yufind.library.yale.edu/yufind/?ref=lorcandempsey.net) pulling in data from the Wikipedia entry for White.

I couldn’t find any Patrick White at the [London School of Economics](https://beta.catalogue.lse.ac.uk/?ref=lorcandempsey.net) 😉 but this set of links appeared alongside a title by John Harsanyi.

Here is what the prototoype ‘[Searchworks](https://searchworks.stanford.edu/?ref=lorcandempsey.net)‘ at Stanford shows for one of their editions of Voss.

George Mason University has an Alpha version up which has [some reviews nicely integrated](https://zoombox.gmu.edu/vufind/Record/419417/Reviews?ref=lorcandempsey.net), but I did not see where they were coming from.
Here is [Minnesota Pals](https://plus.mnpals.net/?ref=lorcandempsey.net).

Clearly other systems are doing similar things. A few random thoughts, focusing on the catalog …
- Switch and destination. How much is the catalog a research tool in itself (a destination) and how much is it a finding tool for people who already pretty much have an idea of what they want and want to see if the library has it (a switch)? Of course, there is quite a bit of research on the use of the catalog; I haven’t seen a **synthesis** of work around this question. And yes, it can be both.
- Linking. The growth of interest in linking raises questions about identity. Am I linking to the correct entry in Wikipedia? Or to the right item in another bibliographic system? It is good when we have identifiers, but we often don’t.
- FRBR: granularity and aggregation. I was struck by the potential utility of FRBR. Where entries in one system are being linked to entries in another the level becomes important (e.g. the 2008 Virago 30th anniversary edition of Excellent Women, or any edition). This is why I was particular to say ‘**an edition**‘ above. For example, one might link to the same ‘edition’, to any other ‘edition’, or to all related editions. It will become more useful to be able to manage this.
- Persistent URLs. Many of the features involve linking back to the catalog (from a social bookmarking site, or potentially from a citation manager). Which requires catalog entries to have persistent URLs.
- Tags. We are in early days here. We will probably see frameworks emerge for sharing tags, greater linking of tags and controlled vocabularies, and maybe the introduction of ‘seed vocabularies’ from which readers can pick or be prompted. Libraries often think of tags in descriptive/retrieval terms. The ‘social’ aspect is important, and I was particularly interested to see the [note](https://www.rss4lib.com/2008/02/new%5Ftagging%5Ftool%5Fat%5Funiversity.html?ref=lorcandempsey.net) from Michigan a while ago about providing a network infrastructure for serendipitous encounter through their tagging environment. Scale and incentives are key here so we may see various models emerge which go beyond the single catalog.
### In Borders earlier
URL: https://www.lorcandempsey.net/in-borders-earlier/
Last updated: 2020-10-28T09:19:28.000Z
I was in our local Border’s just now, forlornly looking for a weekend *Financial Times*. Not finding one, I was looking around aimlessly. A couple of things caught my eye, where one mode influences another.
One of the nice things about Border’s is that you can look for items on their ‘catalog’ in the store. I was amused to see a paper note hanging on the catalog screen: *this is not a touch screen*. I wonder did they have this issue before the iPhone and the devices it has influenced?
They also have occasional sections on the shelves where they display a book alongside several similar ones. They suggest that if you enjoyed reading the displayed title that you may also enjoy the several others that they place alongside it. I wonder are the recommendations generated by their sales data, or are they hand-picked by staff?
### BL web
URL: https://www.lorcandempsey.net/bl-web/
Last updated: 2020-10-28T09:19:30.000Z
I notice that the British Library has revamped its [website](https://www.bl.uk/index4.shtml?ref=lorcandempsey.net).
[](https://www.bl.uk/?ref=lorcandempsey.net)
They have also launched a [new catalog](https://searchbeta.bl.uk/?ref=lorcandempsey.net) in beta, using Primo. Currently it searches over 13M records for books and other materials, a major scholarly resource.
They also point to the just launched [Europeana](https://www.europeana.eu/?ref=lorcandempsey.net) portal which has been remarked in various places in the last day or two. This brings together digitized collections from libraries, archives and museums from across the European Union.
> Over 1,000 cultural organisations from across Europe have provided material for Europeana. Europe’s museums, including the Louvre in Paris and the Rijksmuseum in Amsterdam, have supplied digitised paintings and objects from their collections. State archives have made important national documents available, and France’s Institut National de l’Audiovisuel supplied 80,000 broadcasts recording the 20th century, right back to early footage shot on the battlefields of France in 1914\. National libraries all over Europe have contributed printed and manuscript material, including digitised copies of the great books that brought new ideas into the world. \[[Now Online: “Europeana”, Europe’s Digital Library](https://www.bl.uk/news/2008/pressrelease20081120.html?ref=lorcandempsey.net)\]
Finally, I like their Annual Report format, although it must present some preservation challenges 😉
[](https://www.bl.uk/about/annual/2007to2008/index.html?ref=lorcandempsey.net)
### A bright future ....
URL: https://www.lorcandempsey.net/a-bright-future/
Last updated: 2020-10-28T09:19:32.000Z
The [Research Information Network](https://www.rin.ac.uk/?ref=lorcandempsey.net), a national research and policy unit in the UK which looks at the information needs and practices of researchers, has produced what it calls a Guidance Booklet. The title is [*Ensuring a bright future for research libraries: a guide for vice-chancellors and senior institutional managers*](https://www.rin.ac.uk/bright-futures-libraries?ref=lorcandempsey.net). The audience is senior university administrators.
> Digital technologies and online information resources have brought fundamental changes in how research is done, and also in what researchers expect from library and information services. The services that librarians and information professionals provide have also changed fundamentally over the past decade. They can now do much more to provide leadership that brings improvements in research performance and effectiveness. New resources, services and technologies continue to create new opportunities, new challenges and new expectations. Librarians and information services need the resources and the continuing top-level support within their institutions to ensure that they can fulfil their potential and meet these challenges. …
> … Most higher education institutions (HEIs) have clear research strategies. The challenge now is to set out a clear direction for the relationship between these strategies and the development of your institution’s library and information services, ensuring that the two fit well together. There is also a need for much better communication and engagement between library and information professionals, researchers, and managers at all levels in HEIs.\[*Ensuring a bright future for research libraries* [PDF](https://www.rin.ac.uk/files/Ensuring%5Fbright%5Ffuture%5Fguide%5FNov08@.pdf?ref=lorcandempsey.net)\]
It introduces a framework within which to consider library services, and sketches some detail under these headings:
1. Linking library content and collections to research strategies
2. Cataloguing, navigation, discovery, delivery and access: Researchers’ needs
3. Sharing skills and expertise
4. Communicating and evaluating research outputs
5. Curation, preservation and disposal
6. Sustainable resources
Given the audience, I wondered about the level of detail under some of these. I was interested to see the *Communicating and evaluating research* outputs strand:
> Effective communication of research results is an integral part of the research process. Library and information professionals are key sources of advice and expertise about the rapid changes taking place in disseminating, publishing and sharing research results, and also in assessing their impact. Institutions should ensure that they develop and implement, through consultation both with researchers and with library and information staff, strategies that optimise the dissemination and impact of the research their staff undertake. \[*Ensuring a bright future for research libraries* [PDF](https://www.rin.ac.uk/files/Ensuring%5Fbright%5Ffuture%5Fguide%5FNov08@.pdf?ref=lorcandempsey.net)\]
This is an area where we have introduced a new program of work: [research information management](https://www.oclc.org/programs/ourwork/researchinfo/default.htm?ref=lorcandempsey.net). Indeed it was good to see that there was a variety of contact points with the RLG [work agenda](https://www.oclc.org/programs/ourwork/default.htm?ref=lorcandempsey.net).
### A network generation ...
URL: https://www.lorcandempsey.net/a-network-generation/
Last updated: 2020-10-28T09:19:34.000Z
Further to notes about [NetGen](https://blog.oclc.org/lorcand/archives/001814.html?ref=lorcandempsey.net), Fintan O’Toole’s [wonderful remarks](https://blog.oclc.org/lorcand/archives/000624.html?ref=lorcandempsey.net) on public libraries, and [networking and the Obama campaign](https://blog.oclc.org/lorcand/archives/001639.html?ref=lorcandempsey.net), here is Fintan O’Toole on generations, networks, and the election.
> Thirdly, and closely related to this change, is the cultural impact of the internet. The fears expressed about the internet even a decade ago were that it would create a culturally atomised society, in which everyone could choose to connect only to people like themselves with the same narrow range of obsessions. Obama’s campaign showed, more profoundly than ever before, the capacity of the technology for creating a sense of common purpose.
> This is not just about the obvious ways in which the campaign used the internet for brilliant propaganda (winning the You Tube wars hands down) and to create a crucial advantage in fundraising.
> It is much more profoundly that the very habit of using the technology seems to have created a new kind of engagement with public space. It is striking, for example, that the internet generation in the US, which was supposedly going to be atomised and individualistic, is far more inclined to want larger government doing more things than those who are older.
> Even among white evangelicals, this split is obvious – those under 35 are twice as likely to want “big government” as those over 35\. It would be wrong to see all of this as a mere result of the internet, but there is clearly a complex change under way in which the very idea of the net – personal connection to a larger whole – has been a key part. \[[Election result reflects a cultural shift from brawn to brain – The Irish Times – Sat, Nov 08, 2008](https://www.irishtimes.com/newspaper/weekend/2008/1108/1225925561826.html?ref=lorcandempsey.net)\]
### QOTD: Murdoch
URL: https://www.lorcandempsey.net/qotd-murdoch/
Last updated: 2020-10-28T09:19:36.000Z
Some interesting quotes from a Rupert Murdoch lecture on the current media landscape on [CNET](https://news.cnet.com/8301-10787%5F3-10098194-60.html?part=rss&subj=news&tag=2547-1%5F3-0-20&ref=lorcandempsey.net).
He talks about “compacency and condescension” in newsrooms.
> “The complacency stems from having enjoyed a monopoly–and now finding they have to compete for an audience they once took for granted. The condescension that many show their readers is an even bigger problem. It takes no special genius to point out that if you are contemptuous of your customers, you are going to have a hard time getting them to buy your product. Newspapers are no exception.” \[[Murdoch to media: You dug yourself a huge hole | Coop’s Corner – CNET News](https://news.cnet.com/8301-10787%5F3-10098194-60.html?part=rss&subj=news&tag=2547-1%5F3-0-20&ref=lorcandempsey.net)\]
He talks about the changing balance of power in determining what is and what is not news. He cites the role of bloggers in the resignation of Dan Rather.
> “Far from celebrating this citizen journalism, the establishment media reacted defensively. During an appearance on Fox News, a CBS executive attacked the bloggers in a statement that will go down in the annals of arrogance. ’60 Minutes,’ he said, was a professional organization with ‘multiple layers of checks and balances.’ By contrast, he dismissed the blogger as ‘a guy sitting in his living room in his pajamas writing.’ But eventually it was the guys sitting in their pajamas who forced Mr. Rather and his producer to resign. \[[Murdoch to media: You dug yourself a huge hole | Coop’s Corner – CNET News](https://news.cnet.com/8301-10787%5F3-10098194-60.html?part=rss&subj=news&tag=2547-1%5F3-0-20&ref=lorcandempsey.net)\]
And he has some suggestions ….
> Despite the blemishes, however, Murdoch said newspapers can still count on circulation gains “if papers provide readers with news they can trust.” He added they will also need to embrace technology advances like RSS feeds and targeted e-mails. The challenge, according to Murdoch, will be to “use a newspaper’s brand while allowing readers to personalize the news for themselves-and then deliver it in the ways that they want.” \[[Murdoch to media: You dug yourself a huge hole | Coop’s Corner – CNET News](https://news.cnet.com/8301-10787%5F3-10098194-60.html?part=rss&subj=news&tag=2547-1%5F3-0-20&ref=lorcandempsey.net)\]
An exercise for the reader: compare and contrast with libraries.
### The book and the cover up
URL: https://www.lorcandempsey.net/the-book-and-the-cover-up/
Last updated: 2020-10-28T09:19:37.000Z
I spent a couple of hours in Heffer’s in Cambridge a while ago. Turning a corner I was pleasantly surprised by a set of handsome books in fine covers especially set out for inspection. It turned out they were a special issue to mark the 30 year anniversary of the Virago Modern Classics.
[](https://www.littlebrown.co.uk/NewsEvents/News-Archive/Virago-Modern-Classics?ref=lorcandempsey.net)
> 2008 is the 30th anniversary of the Virago Modern Classics. To celebrate this occasion, we’ve produced a stunning set of eight hardbacks, featuring cover artwork by twentieth-century women textile designers, including Lucienne Day, Cath Kidston, Orla Kiely, Celia Birtwell, and founder of Biba, Barbara Hulanicki. This stylish collection, celebrating literature and art by women in the twentieth century even featured in the Sunday Times style barometer (going up, of course). \[[Virago Modern Classics – Little, Brown Book group](https://www.littlebrown.co.uk/NewsEvents/News-Archive/Virago-Modern-Classics?ref=lorcandempsey.net)\]
I do not know the background here, or the history of Virago in recent years. And certainly, that last sentence seems out of synch with its founding ethos. The iconic green covers loom large in my book memory.
> I consulted my colleagues, my fixation reaching such a degree that poor Harriet tells of me pinning our designer to the wall, demanding five colour covers, exquisite paper, washed tops, strings, and every production frill for my beloved new idea. Penguin used a serious male thinker – Isaac Newton? – to advertise their classics. The Virago Modern Classics list was meant to be more ebullient, a library of women’s fiction with Boadicea rather than Newton waving the flag. I chose green because it was neither blue for a boy nor pink for a girl. I saw in my mind rows of green paperbacks with luscious covers on all the bookshelves of the world. \[[Carmen Callil on Virago Modern Classics | Books | The Guardian](https://www.guardian.co.uk/books/2008/apr/26/featuresreviews.guardianreview2?ref=lorcandempsey.net)\]
[](https://www.littlebrown.co.uk/Title/9781844085262?ref=lorcandempsey.net)I immediately bought the [Barbara Pym](https://www.orlakiely.com/?ref=lorcandempsey.net) from the anniversary set. Barbara Pym is being read in our house at the moment and [Orla Kiely](https://www.orlakiely.com/?ref=lorcandempsey.net), a focus of our daughter’s unfulfilled consumer interest for a while, designed the cover. It is a nice object to own.
Near these books was a selection from the publisher [Persephone Books](https://www.persephonebooks.co.uk/index.htm?ref=lorcandempsey.net), and seeing them close by like that I wondered if the Persephone approach had influenced the Virago anniversary editions.
> We have given much thought not only to the choice of titles we will publish but also to ‘what women want’. Our books look beautiful because we believe that, whether they are on an office desk, by the Aga, or hanging in a bag over the handles of a buggy, it is important to get pleasure from how they look and feel….
> …Fabrics are as much a part of our daily lives as furnishing and dress materials, yet we rarely see them used in any other context. However, fabric design should be celebrated for its own sake; and because it is a field in which women designers have been particularly prominent we would like to use their work whenever possible. \[[Persephone Books, rediscovered twentieth century novels, neglected women writers, twentieth century female authors, out of print books, inter-war novels](https://www.persephonebooks.co.uk/pages/about/design%5Fand%5Fendpapers.htm?ref=lorcandempsey.net)\]
Also on display in Heffer’s was a table full of David Pearson’s *Books as History* which I mentioned [in these pages](https://blog.oclc.org/lorcand/archives/001789.html?ref=lorcandempsey.net) a while ago. His theme, I suggested, was that artifactual properties of books have historic, aesthetic or other interest independent of the texts they convey. Appropriately enough, then, you could buy a signed copy of the book.
[](https://www.worldcat.org/oclc/123536594?ref=lorcandempsey.net)In recent months, since reading David’s book, I have been more conscious of the physical properties of the books I come across. And wandering around Heffer’s, I did wonder if there was an increased focus on interesting covers or formats for some publishers, of which the Virago and Persephone books were striking examples.
In fact, I nearly bought Simon Armitage’s translation of *Sir Gawain and the Green Knight* because it looked very nice, and had to hurry out of the shop before I got carried away.
Related entries:
- [Book covers and Piclens](https://blog.oclc.org/lorcand/archives/001696.html?ref=lorcandempsey.net)
- [Pick up a penguin, nostalgically](https://blog.oclc.org/lorcand/archives/001190.html?ref=lorcandempsey.net)
- [End of year randomness](https://blog.oclc.org/lorcand/archives/001516.html?ref=lorcandempsey.net)
### Net gen again
URL: https://www.lorcandempsey.net/net-gen-again/
Last updated: 2020-10-28T09:19:40.000Z
From the [Economist review](https://www.economist.com/books/displaystory.cfm?story%5Fid=12591038&ref=lorcandempsey.net) of Don Tapscott’s latest book, [*Grown up digital*](https://www.worldcat.org/oclc/225873622?ref=lorcandempsey.net). Young people are fine, he argues, it is baby boomers who are befuddled.
> Contrary to the claims that video games, Facebook and constant text-messaging have robbed today’s young of the ability to think, Mr Tapscott believes that “Net Geners” are the “smartest generation ever”. The experience of parents who grew up watching television is misleading when it comes to judging the 20,000 hours on the internet and 10,000 hours playing video games already spent by a typical 20-year-old American today. “The Net Generation is in many ways the antithesis of the TV generation,” he argues. One-way broadcasting via television created passive couch potatoes, whereas the net is interactive, and, he says, stimulates and improves the brain …
> … Mr Tapscott identifies eight norms that define Net Geners, which he believes everyone should take on board to avoid being swept away by the sort of generational tsunami that helped Barack Obama beat John McCain. Net Geners value freedom and choice in everything they do. They love to customise and personalise. They scrutinise everything. They demand integrity and openness, including when deciding what to buy and where to work. They want entertainment and play in their work and education, as well as their social life. They love to collaborate. They expect everything to happen fast. And they expect constant innovation. \[[The generation raised on the internet | The kids are alright | The Economist](https://www.economist.com/books/displaystory.cfm?story%5Fid=12591038&ref=lorcandempsey.net)\]
Via [Memex 1.1](https://memex.naughtons.org/archives/2008/11/15/5688?ref=lorcandempsey.net). My copy of the Economist never seems to arrive on time 😉
### LeVan on Yee on mashups
URL: https://www.lorcandempsey.net/levan-on-yee-on-mashups/
Last updated: 2020-10-28T09:19:42.000Z
I [mentioned](https://blog.oclc.org/lorcand/archives/001577.html?ref=lorcandempsey.net) Raymond Yee’s book on mashups a while ago and signaled that a fuller review would follow from my colleague Ralph LeVan. This has now appeared: Ralph reviews the book positively in the current issue of Ariadne.
> I can’t imagine a more comprehensive book on mashups. This book would make a great textbook for a class on the topic. If you are a developer of mashups, this book must be in your reference library. However, if you’re looking for a gentle introduction to the topic, it may be more than you want. \[[News and Reviews: ‘Pro Web 2.0 Mashups: Remixing Data and Web Services’, Ariadne Issue 57](https://www.ariadne.ac.uk/issue57/levan-rvw/?ref=lorcandempsey.net)\]
Raymond is the originator of the useful and widely used phrase “[gather, create, share](https://raymondyee.net/wiki/GatherCreateShare?ref=lorcandempsey.net)” to characterise personal information use.
### M-libraries
URL: https://www.lorcandempsey.net/m-libraries/
Last updated: 2020-10-28T09:19:43.000Z
[](https://www.worldcat.org/oclc/216659547?ref=lorcandempsey.net)I have a contribution in
> Mohamed Ally and Gill Needham. *M-Libraries: Libraries on the Move to Provide Virtual Access*. London: Facet, 2008\. \[[Worldcat](https://www.worldcat.org/oclc/216659547?ref=lorcandempsey.net)\]\[Table of contents [PDF](https://www.facetpublishing.co.uk/mlibrariestoc.pdf?ref=lorcandempsey.net) on Facet\]
That said, I notice that I am not listed among the contributors on the publisher’s page 😉
This collects the proceedings of the first M-Libraries conference. I have agreed to speak at the successor conference, [The 2nd International M-Libraries Conference](https://library.open.ac.uk/mLibraries/?ref=lorcandempsey.net), in Vancouver in June 2009\. A call for papers is posted on the conference [page](https://library.open.ac.uk/mLibraries/?ref=lorcandempsey.net).
> This conference aims to explore and share work carried out in libraries around the world to deliver services and resources to users ‘on the move,’ via a growing plethora of mobile and hand-held devices. The conference will bring together researchers, technical developers, managers and library practitioners to exchange experience and expertise and generate ideas for future developments. \[[mLibraries 2009 conference – Homepage](https://library.open.ac.uk/mLibraries/?ref=lorcandempsey.net)\]
### Repository interoperability
URL: https://www.lorcandempsey.net/repository-interoperability-2/
Last updated: 2020-10-28T09:19:45.000Z
JISC has just made available a report by Nicky Ferguson and colleagues about consistency of metadata and policies between repositories.
> In the UK, a large number of Institutional Repositories have been set up very recently. Often, it seems, they lack sufficient clarity of policy and purpose. In interviews with depositors and after conducting a case study of an Institutional Repository, we find different perceptions of the role of the repository, some seeing it mainly as an administrative tool for collecting and collating research at the institution and others believing it is a tool for sharing research and creating open access to the results of that research. If such perceptions are combined with weakly defined policies and/or unclear implementation procedures, then it would be unsurprising to find inconsistencies both within and between repositories. In fact, our respondents tell us that such inconsistency is widespread and are pessimistic that this will change, except where sufficient resources, shared objectives and strong relationships are in place. \[[Feasibility study into approaches to improve the consistency with which repositories share material](https://ie-repository.jisc.ac.uk/256/1/jisc-clax-final-report-repocon.pdf?ref=lorcandempsey.net)\]
The report makes detailed recommendations to JISC and to repository managers. (Note: I was among those interviewed by the authors.) I don’t propose to summarise their findings here, but to note several things that occurred to me while reading through it:
**Interoperability and SEO**. We applaud interoperability. Even, or so it sometimes seems, as an end in itself, independent of any motivating services or applications which will benefit. However, we have a somewhat limited interpretation of interoperability. We tend to think about it as something that happens within our domain, between like things. Think of moving metadata or content between repository applications, or searching across multiple databases. However, it is increasingly important to think about interoperability between our services and other people’s services, notably with the general web environment of search engines, RSS aggregators, and so on. This is something that the report touches on. Sitemaps and RSS feeds are increasingly important in terms of disclosing repository content into user environments. SEO (search engine optimization) is increasingly important: given the importance of search engines as entry points, repository and data managers need to think about how their services and data work in a world where being crawled and ranked well are so important. I sometimes come across a view that SEO is to be frowned on, that it involves deception or nasty commercial practices. Maybe if we were to invent a new phrase, SEI or Search Engine Interoperability, people would be happier with it 😉
**Names**. As search and citation in electronic environments become more important it is interesting to see the focus on consistent names, or author identifiers, emerge more strongly. Authors, institutions, publishers and others have an interest here, as inconsistent naming reduces impact. The authors note various initiatives, including some of our work. National libraries have so far not broadened the scope of their authority work beyond the ‘cataloged’ collection, something that I discuss [here](https://blog.oclc.org/lorcand/archives/001699.html?ref=lorcandempsey.net). We are now in a phase where multiple organizations are looking at academic author identification and profiling.
**Variable metadata.** Metadata created in different regimes, with different rules or guidelines, with different editors, with variable access to controlled vocabularies and authority data, will be inconsistent. There should be no surprise here. And working effectively with this metadata will have a cost (what I have called a ‘[stitching cost](https://blog.oclc.org/lorcand/archives/001785.html?ref=lorcandempsey.net)‘). The authors discuss this and point to other confirming work including a JCDL paper by Lagoze et al. There, the authors note their initial expectation that Worldcat and shared cataloging was a potential model for a service based on metadata aggregation. Not surprisingly, they were disappointed:
> In fact, reality fell far short of our expectations. We discovered that the WorldCat paradigm, which works so well in the shared professional culture of the library, is less effective in a context of widely varied commitment and expertise. Few collections were willing or able to allocate sufficient human resources to provide quality metadata. \[Metadata aggregation and “automated digital libraries”: A retrospective on the NSDL experience [PDF](https://arxiv.org/ftp/cs/papers/0601/0601125.pdf?ref=lorcandempsey.net)\]
However, what is ‘quality’ in this context. What is distinctive about the shared cataloging environment? There are mature editors developed over many years, which encapsulate many discussions/agreements about cataloging policy and practice. There is a community of practice institutionalized in various professional venues. There are detailed rules and rule interpretations. There are shared authority and terminology files. There is extensive sharing of metadata between systems. which encourages uniformity And there are criteria for addition to Worldcat or other union catalogues. There is a whole apparatus here devoted to ensuring consistency of metadata, and this is enforced through a shared infrastructure and shared professional practice, as well as through codes and rules. This is a very different model to one in which data is simply aggregated from multiple repositories, even if they are nominally using the same standards.
This is one reason why I think that shared network level metadata creation tools are an interesting area for exploration, particularly for organizations with the national remit of JISC. They may not benefit from the same sharing of creation effort as happens in the shared cataloging environment – because the resources they are describing may be unique – but there are other aspects of the shared environment which would be beneficial.
If people use the same editing environment, with access to a set of vocabularies, and participate in a shared community of interpretation, then the chances for consistency may go up. See [Calames](https://blog.oclc.org/lorcand/archives/001641.html?ref=lorcandempsey.net) for what I understand to be an example of this.
Of course, this note touches on cases where metadata is being created manually. Where and when such creation is justified or affordable is another question, and this is something that the report also dwells on.
Related entries:
- [Stitching costs](https://blog.oclc.org/lorcand/archives/001785.html?ref=lorcandempsey.net)
- [Four sources of metadata about things](https://blog.oclc.org/lorcand/archives/001351.html?ref=lorcandempsey.net)
### Hackathon
URL: https://www.lorcandempsey.net/hackathon-2/
Last updated: 2020-10-28T09:19:47.000Z
Eric Lease Morgan has a nice [note](https://infomotions.com/blog/2008/11/worldcat-hackathon/?ref=lorcandempsey.net) reporting on the Worldcat Hackathon held at the end of last week. A group came together to explore building applications against OCLC [Grid Services](https://worldcat.org/devnet/wiki/Services?ref=lorcandempsey.net).
> Taking place in the Science, Industry and Business Library (New York Public Library), the event began with an overview of each of the Web Services and the briefest outline of how they might be used. We then quickly broke into smaller groups to “hack” away. The groups fell into a number of categories: Drupal, VUFind, Find More Like This One/Miscellaneous, and language-specific hacks. We reconvened after lunch on the second day sharing what we had done as well as what we had learned. \[[Worldcat Hackathon](https://infomotions.com/blog/2008/11/worldcat-hackathon/?ref=lorcandempsey.net)\]
… and he goes on to list some of the things that people did during the two days.
### QOTD: Entering the Midwest via Columbus
URL: https://www.lorcandempsey.net/qotd-entering-the-midwest-via-columbus/
Last updated: 2022-11-08T16:09:55.000Z
I am en route back to Columbus, Ohio. I am now in Atlanta – nearly there! I have been reading [*Roads: driving America’s great highways*](https://www.worldcat.org/oclc/43599121?ref=lorcandempsey.net) by [Larry McMurtry](https://worldcat.org/identities/lccn-n79-27185?ref=lorcandempsey.net) on the plane.
I was interested to read the following on page 80:
> Accordingly I pulled across the Ohio River at Wheeling just as the rising sun glinted in my rearview mirror – thirteen hours later I watched it sink into the plains, beyond the Kansas River at Lawrence. I spent the day in Ohio, Indiana, Illinois, Missouri, answering, at least to my own satisfaction, the question about where the Midwest begins. Its eastern edge would appear to be Columbus, Ohio, after which the great cornfields appear, and continue all the way to St Louis. Eastern Ohio still has the look of Appalachia, with narrow framehouses on steep hillsides, but after Columbus there are no hillsides, just the flat Midwestern plain. Columbus itself has grown a good crop of cornstalklike postmodern skyscrapers since I was last through it; it even produced a respectable traffic jam, though later in the day, at Kansas City, I was to see a really mature traffic jam, one that stretched for eleven miles; …
### Flying and light posting
URL: https://www.lorcandempsey.net/flying-and-light-posting/
Last updated: 2024-12-23T03:31:05.000Z
Posting will be light this week as I am attending the 2008 [RLG European Partners](https://www.oclc.org/programs/events/2008-11-05.htm?ref=lorcandempsey.net) meeting later in the week. I go to Paris via a meeting in Ottawa tomorrow ….. Too much flying 🙁
I was traveling through National in Washington DC a while ago. I was tired. It was early in the morning and I was coming off a bumpy and cramped commuter flight from Columbus, Ohio (purportedly within an hour and a half’s flying time of 56% of the US population, I seem to remember reading somewhere).
I passed by a display of retro Pan Am flight bags, proud with that iconic logo. They were on sale. Since then, it seems that I have been seeing retro flight bags everywhere.
As a young child, the logo was very familiar to me, and not a little magical. I had an uncle who worked with Pan Am, and for a while there were always bags or other items around. It was a time when flying was exciting and even exotic. And Pan Am seemed more exciting than the rest. I notice that Wikipedia [describes](https://en.wikipedia.org/wiki/Pan%5FAmerican%5FWorld%5FAirways?ref=lorcandempsey.net) Pan Am as a “cultural icon of the 20th Century”.
Indeed, the flight bag, and that logo in particular, seem to belong to a different era. And it is perhaps now, when the excitement has been squeezed from most flying, that the logo can come to life again as an emblem of the glamor of an experience that has mostly faded away.
**Note:** logo copied from the [Wikipedia page](https://en.wikipedia.org/wiki/Image:Pan%5FAm%5FLogo.svg?ref=lorcandempsey.net) about the image. Note the fair use rationale.
**Update:** Pan Am logo fixed. See [here](https://commons.wikimedia.org/wiki/File:Pan%5FAm%5FLogo.svg?ref=lorcandempsey.net) for original. Some reformatting. Abstract added. 12/22/2024.
### Amplification around a tag
URL: https://www.lorcandempsey.net/amplification-around-a-tag/
Last updated: 2020-10-28T09:19:52.000Z
My former colleague and [network resident](https://blog.oclc.org/lorcand/archives/001773.html?ref=lorcandempsey.net), [Andy Powell](https://www.eduserv.org.uk/foundation/people/andypowell/?ref=lorcandempsey.net), advocates strongly that public events should publish a conference tag, a virtual venue to which event [amplifying](https://en.wikipedia.org/wiki/Amplified%5Fconference?ref=lorcandempsey.net) network activity like blog posts, tweets, images and so on can cluster.
> It’s easy to forget, but I’d go as far as saying that the tag is almost as important as the venue. In fact, in a sense, the tag becomes the virtual venue for the event’s digital legacy. \[[eFoundations: Tags as virtual venues](https://efoundations.typepad.com/efoundations/2007/09/tags-as-virtual.html?ref=lorcandempsey.net)\]
For a network resident this may make complete sense; to others, it may seem overstated.
I raise this in the context of the [Libraries Australia 2008 Forum](https://www.nla.gov.au/librariesaustralia/aum/laf08/?ref=lorcandempsey.net). They have gone the extra step of pulling that network amplification into a [single page](https://www.nla.gov.au/librariesaustralia/aum/laf08/web.html?ref=lorcandempsey.net).
> This is what people have posted about the 2008 Libraries Australia Forum. If you are posting about the forum, please tag your blog posts, presentations or flickr photos **laf2008.** If you are using twitter, use the tag **#laf2008** in your tweets. \[[2008 Libraries Australia Forum – from the web](https://www.nla.gov.au/librariesaustralia/aum/laf08/web.html?ref=lorcandempsey.net)\]
Now, at the time of writing, the network amplification seems largely to be the work of one person. I don’t think this is a particular issue: whatever the level of participation, the organizers are to be commended for taking this extra step I think.
However, it does raise for me an interesting question about the relative balance in conference audiences between ‘network residents’ and ‘network visitors’, or, more broadly, the relative balance between these categories in the general use of our network services. (For those that are not familiar with this helpful distinction, see Dave White’s [discussion](https://tallblog.conted.ox.ac.uk/index.php/2008/07/23/not-natives-immigrants-but-visitors-residents/?ref=lorcandempsey.net) and my [comments](https://blog.oclc.org/lorcand/archives/001773.html?ref=lorcandempsey.net) made after I read about it in Andy’s [post](https://efoundations.typepad.com/efoundations/2008/09/residents-and-v.html?ref=lorcandempsey.net).)
I know from my own experience that the balance is very different in different audiences. In some audiences there are likely to be bloggers; in others it is very unlikely. In some audiences, there may be people who will take pictures and post them; in others it is very unlikely. And from a service point of view, I think that it would be very interesting to get a sense of how the users of a library catalog, for example, break down along a resident/visitor spectrum.
Incidentally, see Paul Hagon’s [report](https://www.paulhagon.com/libraries/2008/10/23/next-generation-library-catalogues/?ref=lorcandempsey.net) of Eric Lease Morgan’s remarks about the catalog, and his [account](https://www.paulhagon.com/libraries/2008/10/23/new-futures-for-authority-data/?ref=lorcandempsey.net) of my current colleague, Thom Hickey, talking about authorities and identities. I was also interested in the [note](https://www.paulhagon.com/libraries/2008/10/23/communicating-university-research-identity/?ref=lorcandempsey.net) about about university and researcher identity in the context of Simon Porter’s presentation about the University of Melbourne; ~~I hope they make the presentations available~~. The presentations are now [available](https://www.nla.gov.au/librariesaustralia/aum/laf08/agenda.html?ref=lorcandempsey.net).
Note: Eric’s own discussion and a copy of his presentation are [here](https://infomotions.com/musings/ngc-in-sydney/?ref=lorcandempsey.net).
[laf2008](https://www.technorati.com/tag/laf2008?ref=lorcandempsey.net)
### Who we are ....
URL: https://www.lorcandempsey.net/who-we-are/
Last updated: 2020-10-28T09:19:55.000Z
I was pretty interested to see this panel on the home page of the [Kelvin Smith Library](https://library.case.edu/ksl/?ref=lorcandempsey.net) at Case.
[](https://library.case.edu/ksl/?ref=lorcandempsey.net)
In recent presentations I have been noting that while we are increasingly used to seeing ‘signed’ network resources, library websites are often very anonymous.
Think of reviews, ratings, social networking profiles, shared bookmarks. People have become entry points on the network, and signature is important. \[1\]
However, think of library websites. They tend to be anonymous. Often, it is not straightforward finding appropriate contact points: there may not be photographs, or communication options are limited (office hours, IM, texting, email, phone). Library services are not always associated with people. How often do subject pages, for example, carry a name and contact information who can be consulted? Libraries promote their expertise, but do not always make experts visible.
My colleague Lynn Connaway has noted how students are sometimes reluctant to use virtual reference because they do not want to interact with somebody who remains anonymous or who they do not know, even if it is a library service. \[2\]
Putting faces to names, as Case is doing, is important, I think ….
\[1\] I heard the phrase ‘people are entry points’ used by [Dan Chudnov](https://onebiglibrary.net/?ref=lorcandempsey.net) at a meeting and thought it very relevant. See also this interesting presentation at the CIC Library Conference, Minnesota, March 2007, which reinforced for me the importance of ‘signature’. Cody Hanson. ‘ Next Generation Librarians: Visions of Our Future.’ [https://codyhanson.com/CodyHansonCIC032007.ppt](https://codyhanson.com/CodyHansonCIC032007.ppt?ref=lorcandempsey.net).
\[2\] Lynn Silipigni Connaway and Marie L Radford, 2007\. “Service Sea Change: Clicking with Screenagers Through Virtual Reference.” Presented by Lynn Silipigni Connaway and Marie L. Radford at the Association of College and Research Libraries 13th National Conference, “Sailing into the Future – Charting Our Destiny,” 29 March – 1 April 2007, Baltimore, Maryland (USA), and forthcoming in the conference proceedings. Pre-print available online at: [https://www.oclc.org/research/publications/archive/2007/connaway-acrl.pdf](https://www.oclc.org/research/publications/archive/2007/connaway-acrl.pdf?ref=lorcandempsey.net),
Note: yes, I know, footnotes are a bit much 😉
### Google Book Search channelling
URL: https://www.lorcandempsey.net/google-book-search-channelling/
Last updated: 2020-10-28T09:19:57.000Z
Regular readers will know that I follow the Hitwise blog. I was interested to see their note on Google Book Search the other day, prompted by the settlement which discussed which sites benefited from downstream traffic from that site. In other words, where do people go when they leave Google Book Search by following links.
> Among other things, the settlement allows universities and libraries to buy a subscription to the entire collection of scanned books in Google’s archives. Last week, 22% of visits from Google Book Search went to an Education website, with Worldcat (a website that allows users to search library catalogs) the #3 downstream website overall and the #1 Education website. \[[Hitwise Intelligence – Heather Hopkins – US: Google Books Drives Visits to Book Retailers](https://weblogs.hitwise.com/us-heather-hopkins/2008/10/google%5Fbooks%5Fdrives%5Fvisits%5Fto%5F1.html?ref=lorcandempsey.net)\]
If I am reading the entry correctly, the order of downstream destinations is \[1\] Google.com, \[2\] Amazon.com, and \[3\] Worldcat.org.
### On the record: two views from the Guardian
URL: https://www.lorcandempsey.net/on-the-record-two-views-from-the-guardian/
Last updated: 2020-10-28T09:19:58.000Z
There is an interesting and reflective commentary about the historical record and ‘unpublishing’ in the Guardian. I particularly like the comment about tattoos.
> The consequences of putting information about yourself into the public domain are more far-reaching in a world where things you say are linked to, easily passed around and can pop up if your name is put into a search engine by, for example, a prospective employer. The web makes a lie of the old cliche that today’s newspaper pages are tomorrow’s fish and chip wrapping. Nowadays, as I’ve said before, the things you say about yourself in a newspaper are more like tattoos – they can be extremely difficult to get rid of. …
> … The established view is that a newspaper’s online archive is a historical record and that there is therefore a strong public interest in maintaining its wholeness, unless deletions or amendments are strictly necessary. In line with these principles, changes to the Guardian’s online archives are usually made only for the purpose of correcting errors or for legal reasons. However, in exceptional cases, amendments are made on compassionate grounds, particularly when children are involved. \[[Open door: The readers’ editor on unpublishing | Comment is free | The Guardian](https://www.guardian.co.uk/commentisfree/2008/oct/20/blogs-publishing-record-privacy?ref=lorcandempsey.net)\]
Now that the ‘record’ is within the editing control of newspapers, rather than being printed and distributed to the world, it will be interesting to see how they resist requests for changes. The recent introduction of editing histories on web pages by newspapers is welcome. An aspect of future scholarship may be to check versions of newspapers, the publisher version against snapshots in national library or other archives.
The second article examines journal publishing and the scholarly record, [Web journals ‘narrowing study](https://www.guardian.co.uk/education/2008/oct/28/research-internet?ref=lorcandempsey.net)‘. This is a lazy piece which runs together various trends in scholarly dissemination. It touches on reputation management in online environments, the use of citation analysis in research evaluation, researcher behavior in an environment of scarce attention and abundant resources, and the proliferation of publishing outlets. The hook is that changes in these various areas add up to a decline in the quality of scholarship, but the article does not do enough work to convince. I hope that any future readers of this particular historical record are appropriately informed ….
See Marieke Guy’s [discussion](https://jiscpowr.jiscinvolve.org/2008/10/24/unpublishing-the-web/?ref=lorcandempsey.net) of ‘unpublishing’ on the JISC-PoWR blog.
### Jazzing up information/scholarly literacy
URL: https://www.lorcandempsey.net/jazzing-up-information-scholarly-literacy/
Last updated: 2020-10-28T09:20:00.000Z
Writing about scholarly method, Paul Courant discusses ‘information literacy’ and ‘scholarly literacy’.
> Partly in response to these concerns, there has been much talk about the importance of developing “information literacy”. I will argue here that our most important audience is already information literate and then some. \[3\] Our interest should be in ensuring the production of something that we might call “scholarly literacy”, by which I mean the understanding of sources, methods, and their use that is at the heart of knowing what one knows and does not know. The problem is that the remarkable growth of information literacy has both enhanced our technical ability to produce scholarly literacy, by greatly increasing access to resources, while at the same time reducing the imperative to engage in sound scholarly practice by doing work that is “good enough.” The challenge that we face will not and should not be that of turning back the clock; our task is to take ubiquitous information literacy and exploit it as an asset for the development of scholarly literacy. (There would be a high payoff, by the way, to generating a phrase that is jazzier and more marketable than “scholarly literacy.”)
> \[3\] As Stanley Wilder has noted, “Any educational philosophy is doomed to failure if it views students as information seekers in need of information-seeking training.” From Stanley Wilder, “Information literacy makes all the wrong assumptions,” *The Chronicle of Higher Education* (January 7, 2005): B13\.
> \[Paul Courant. Scholarship, the wave of the future in the digital age. [PDF](https://net.educause.edu/ir/library/pdf/PUB7202t.pdf?ref=lorcandempsey.net) In: [*The tower and the cloud*](https://www.educause.edu/thetowerandthecloud/133998?ref=lorcandempsey.net). Richard N Katz, ed.\]
When I read Wilder’s article a couple of years ago, [I wrote about](https://blog.oclc.org/lorcand/archives/000540.html?ref=lorcandempsey.net) the ‘eat your spinach, it’s good for you’ attitude to information literacy that you occasionally come across, often coupled with a defensive attitude to Google.
I liked the discussion of scholarly literacy here … But the question remains … what is a “jazzier” name for ‘Scholarly literacy’ ….. ?
### Are you Asking ...
URL: https://www.lorcandempsey.net/are-you-asking/
Last updated: 2020-10-28T09:20:02.000Z
After a recent makeover, search engine Ask has a nice clean interface and some nice features. One that is foregrounded is the ‘related searches’ feature. I could not immediately see how they were generating this list, but it was often helpful.
I was interested in what a [search for Lorcan Dempsey](https://www.ask.com/web?q=lorcan+dempsey&ref=lorcandempsey.net) returned …

### Spinning
URL: https://www.lorcandempsey.net/spinning/
Last updated: 2020-10-28T09:20:05.000Z
I have [observed](https://blog.oclc.org/lorcand/archives/001556.html?ref=lorcandempsey.net) that ‘concentration’ – of data, of connections, of computing capacity – is major feature of Web 2.0\. Nick Carr [talked about](https://www.roughtype.com/archives/2008/10/the%5Fcentripetal.php?ref=lorcandempsey.net) *the centripetal web* the other day, and this was picked up in an interesting way by Mark Dahl:
> With the web as the medium, it becomes that much easier to take the IT department (or the library for that matter) out of the loop when provisioning software or academic content. The HR department, the development office, or an academic department can select content or services over the Internet that meets their needs. User communities for cloud software and services can easily transcend institutional boundaries and make what used to be isolated choices seem less so. Nick Carr recently [discusses](https://www.roughtype.com/archives/2008/10/the%5Fcentripetal.php?ref=lorcandempsey.net) how cloud computing is exerting a centripetal force throughout the web as a whole, with a trend toward centralization. In the context of an organization, it’s exerting a centrifugal force: it is now much easier for a department or professor to deploy a multi-user application (eg [VoiceThread](https://voicethread.com/?ref=lorcandempsey.net), a NITLE favorite) without the participation of the IT department.
> \[[synthesize-specialize-mobilize: thoughts ahead of NITLE Cloud Computing Event](https://synthesize-specialize-mobilize.blogspot.com/2008/10/thoughts-ahead-of-nitle-cloud-computing.html?ref=lorcandempsey.net)\]
This is an example of a major trend. Universities have internalized particular IT or information management activities because there were advantages in doing this, and have developed organizational structures to manage them. It was more efficient for some things to be done centrally within the institution, so that individual departments, or individual faculty, students or administrators, did not have to individually procure them. E-mail and current awareness services might be examples. However, the network changes this dynamic. It may be more efficient for some things to be done at the network level, and the incentives to use or to provide some institutional services change. Departments or individuals increasingly have alternative options for many institutional services, and institutional service providers may have a variety of sourcing models (do I try and build local social networking capacity for students, or do I use an external service; do I create resource pages, or do I use delicious; and so on).
### QOTD: IBM and standards
URL: https://www.lorcandempsey.net/qotd-ibm-and-standards/
Last updated: 2020-10-28T09:20:09.000Z
On the politics and business of standards making …..
> Bob Sutor, vice president of open source and standards, tells me that Big Blue has decided to cast a cold eye over the performance of the standards bodies it belongs to – which number “several hundred” – and may drop its links to some. The process of creating standards is “much more broken than people realised”, he said: in particular, there is a lack of transparency in some bodies about how decisions are arrived at or even how membership of the standards groups is set, which opens the system to abuse. \[[FT.com | Tech Blog | IBM takes a blunt axe to its dealings with standards-setters](https://blogs.ft.com/techblog/2008/09/ibm-takes-a-blunt-axe-to-its-dealings-with-standards-setters/?ref=lorcandempsey.net)\]
I was interested that IBM was a member of ‘several hundred’ standards bodies.
### User behaviors
URL: https://www.lorcandempsey.net/user-behaviors/
Last updated: 2020-10-28T09:20:17.000Z
My colleague Lynn Connaway has been working on several collaborative projects looking at user behaviors over the last few years. Together, she and colleagues have produced a nice body of work looking at user attitudes and behaviors to library services, and to information work more generally.
I thought it would be useful to pull together some publications which report on this work and list them here …..
Connaway, Lynn Silipigni, Marie L. Radford, and Timothy J. Dickey. 2008\. “On the Trail of the Elusive Non-user: What Research in Virtual Reference Environments Reveals.” Bulletin of the American Society for Information Science and Technology, 34,2 (December/January): 25-28\. Available online in HTML or PDF (222K/4 pp.) from: [https://www.asis.org/Bulletin/Dec-07/](https://www.asis.org/Bulletin/Dec-07/?ref=lorcandempsey.net)
Connaway, Lynn Silipigni, Marie L. Radford, Timothy J. Dickey, Jocelyn De Angelis Williams, and Patrick Confer. 2008\. “Sense-making and Synchronicity: Information-seeking Behaviors of Millennials and Baby Boomers.” Libri 58, 123-135.
Connaway, Lynn Silipigni. 2007\. “Mountains, Valleys, and Pathways: Serials Users’ Needs and Steps to Meet Them. Part I: Identifying serials users’ needs: Preliminary analysis of focus group and semi-structured interviews at colleges and universities.” Serials Librarian, 52,1/2: 223-236\. E-print available online at: [https://www.oclc.org/research/publications/archive/2007/connaway-serialslibrarian.pdf](https://www.oclc.org/research/publications/archive/2007/connaway-serialslibrarian.pdf?ref=lorcandempsey.net) (.pdf: 49K/14 pp.).
Connaway, Lynn Silipigni, with Marie L. Radford \[first author\]. 2007\. “‘Screenagers’ and Live Chat Reference: Living Up to the Promise.” Scan, 26,1 (February): 31-39.
Connaway, Lynn Silipigni, and Marie L. Radford. 2007\. “Service Sea Change: Clicking with Screenagers Through Virtual Reference.” Presented by Lynn Silipigni Connaway and Marie L. Radford at the Association of College and Research Libraries 13th National Conference, “Sailing into the Future – Charting Our Destiny,” 29 March – 1 April 2007, Baltimore, Maryland (USA), and forthcoming in the conference proceedings. Pre-print available online at: [https://www.oclc.org/research/publications/archive/2007/connaway-acrl.pdf](https://www.oclc.org/research/publications/archive/2007/connaway-acrl.pdf?ref=lorcandempsey.net) (.pdf: 68K/19 pp.).
Connaway, Lynn Silipigni, and Marie L. Radford. 2007\. “The Thrill of the Chase in Cyberspace: A Report of Focus Groups with Live Chat Librarians.” Guest Forum, Informed Librarian Online (January). Available online at: [https://www.informedlibrarian.com/guestForum.cfm?FILE=gf0701.html](https://www.informedlibrarian.com/guestForum.cfm?FILE=gf0701.html&ref=lorcandempsey.net).
Prabha, Chandra, Lynn Silipigni Connaway, Lawrence Olszewski, & Lillie Jenkins. 2007\. “What is enough? Satisficing information needs,” Journal of Documentation, 63,1(January):74-89\. E-print available online at: [https://www.oclc.org/research/publications/archive/2007/prabha-satisficing.pdf](https://www.oclc.org/research/publications/archive/2007/prabha-satisficing.pdf?ref=lorcandempsey.net) (.pdf: 176K/18 pp.).
### LAM Consolidation and public funding
URL: https://www.lorcandempsey.net/lam-consolidation-and-public-funding/
Last updated: 2020-10-28T09:20:19.000Z
It looks as if Ireland is to follow Canada in amalgamating its national archives and national library. However, the driver appears to be financial rather than functional, and it is one of several organizational consolidations being pushed through by the Irish Government. The news came in the 2009 budget announcement as part of a package of proposals in the arts. Here is how *The Times* reported the change ….
> “From the point of view of the arts this budget is an unmitigated disaster,” said artist Robert Ballagh.
> “The cutback in Arts Council funding will undoubtedly lead to infrastructural destruction, with irreparable consequences. I cannot see anything to be gained from this hare-brained amalgamation of the National Gallery, the Crawford Gallery and the Irish Museum of Modern Art (IMMA) other than a saving in photocopying expenses.”
> The National Library of Ireland, the National Archives and the Manuscripts Commission will also be amalgamated, with Martin Cullen, the arts minister, saying the fusion “will lead to economies of scale and costs”. The announcement has caused widespread confusion as to what the practical consequences will be. \[[Artists caught up in Lenihan’s tax net – Times Online](https://www.timesonline.co.uk/tol/news/world/ireland/article4968829.ece?ref=lorcandempsey.net)\]
Here is how [Library and Archives Canada](https://www.collectionscanada.gc.ca/index-e.html?ref=lorcandempsey.net) describes itself:
> Library and Archives Canada collects and preserves Canada’s documentary heritage, and makes it accessible to all Canadians. This heritage includes publications, archival records, sound and audio-visual materials, photographs, artworks, and electronic documents such as websites. As part of our mandate, we work closely with other archives and libraries to acquire and share these materials as widely as possible. \[[About Us – Library and Archives Canada](https://www.collectionscanada.gc.ca/about-us/index-e.html?ref=lorcandempsey.net)\]
### Blogging and Montaigne: musing and raving, humours and conceits
URL: https://www.lorcandempsey.net/blogging-and-montaigne-musing-and-raving-humours-and-conceits/
Last updated: 2020-10-28T09:20:21.000Z
I returned from my travels last night to find a new edition of the Atlantic waiting for me. It grabbed attention as it has been redesigned, and I liked the redesign. But also, my eye was caught by the title of Andrew Sullivan’s essay ‘Why I blog’.
Sullivan’s whole essay could be quoted, but as he notes, one of the advantages of the blog commentary is that you can provide a [link](https://www.theatlantic.com/doc/200811/andrew-sullivan-why-i-blog?ref=lorcandempsey.net). The reader can jump to the work being discussed.
He talks about the characteristics of the blogger’s activity ….
> No columnist or reporter or novelist will have his minute shifts or constant small contradictions exposed as mercilessly as a blogger’s are. A columnist can ignore or duck a subject less noticeably than a blogger committing thoughts to pixels several times a day. A reporter can wait—must wait—until every source has confirmed. A novelist can spend months or years before committing words to the world. For bloggers, the deadline is always now. Blogging is therefore to writing what extreme sports are to athletics: more free-form, more accident-prone, less formal, more alive. It is, in many ways, writing out loud. \[[Why I Blog – The Atlantic (November 2008)](https://www.theatlantic.com/doc/200811/andrew-sullivan-why-i-blog?ref=lorcandempsey.net)\]
…. and emphasizes its evolving place in a richer ecology.
> In fact, for all the intense gloom surrounding the news-paper and magazine business, this is actually a golden era for journalism. The blogosphere has added a whole new idiom to the act of writing and has introduced an entirely new generation to nonfiction. It has enabled writers to write out loud in ways never seen or understood before. And yet it has exposed a hunger and need for traditional writing that, in the age of television’s dominance, had seemed on the wane. \[[Why I Blog – The Atlantic (November 2008)](https://www.theatlantic.com/doc/200811/andrew-sullivan-why-i-blog/4?ref=lorcandempsey.net)\]
Sullivan looks to lofty precursors, Plato, Pascal, Karl Kraus, and, above all, Montaigne.
> But perhaps the quintessential blogger *avant la lettre* was Montaigne. His essays were published in three major editions, each one longer and more complex than the previous. A passionate skeptic, Montaigne amended, added to, and amplified the essays for each edition, making them three-dimensional through time. In the best modern translations, each essay is annotated, sentence by sentence, paragraph by paragraph, by small letters (A, B, and C) for each major edition, helping the reader see how each rewrite added to or subverted, emphasized or ironized, the version before. Montaigne was living his skepticism, daring to show how a writer evolves, changes his mind, learns new things, shifts perspectives, grows older—and that this, far from being something that needs to be hidden behind a veneer of unchanging authority, can become a virtue, a new way of looking at the pretensions of authorship and text and truth. \[[Why I Blog – The Atlantic (November 2008)](https://www.theatlantic.com/doc/200811/andrew-sullivan-why-i-blog/3?ref=lorcandempsey.net)\]
Coincidentally, I was returning from a trip to Cambridge University Library where we were privileged to be taken on a tour of their current Montaigne exhibition by [Professor Philip Ford](https://www.mml.cam.ac.uk/french/staff/pjf2/?ref=lorcandempsey.net).
> In 2008 Cambridge University Library received the Montaigne Library of Gilbert de Botton (1935–2000), a remarkable collection of books connected with Montaigne, his life and times, and his library, including ten of Montaigne’s personal copies. This exhibition draws on the collection to celebrate a writer whose book has for more than four hundred years fascinated its readers with glimpses of the complex, subtle, shifting self it seeks to portray. \[[‘MY BOOKE AND MY SELFE’: MICHEL DE MONTAIGNE 1533–1592](https://www.lib.cam.ac.uk/exhibitions/Montaigne/index.html?ref=lorcandempsey.net)\]
I particularly liked this quote …
> In 1570 Montaigne resigned from the Parlement and went to Paris to publish La Boétie’s works. The following year, on his thirty-eighth birthday, he retired from public life. He spent most of his days in his library, a circular room on the third floor of a tower at the château, where he had inscribed on the rafters quotations from his favourite works. Around him were some thousand diverse volumes, of both ancient and modern writers. ‘There without order, without methode, and by piece-meales I turne-over and ransacke, now one booke and now another. Sometimes I muse and rave; and walking up and downe I endite and enregister these my humours, these my conceits’. It was here that the that the *Essais* took shape. \[[‘MY BOOKE AND MY SELFE’: MICHEL DE MONTAIGNE 1533–1592](https://www.lib.cam.ac.uk/exhibitions/Montaigne/c67.html?ref=lorcandempsey.net)\]
Musing and raving, humours and conceits: not a bad account of blogging.
Note: see commentary by [John Naughton](https://www.guardian.co.uk/media/2008/oct/19/blogging?ref=lorcandempsey.net) and [Nick Carr](https://www.roughtype.com/archives/2008/10/the%5Fsuperficial.php?ref=lorcandempsey.net).
Note: see the [Worldcat Identities](https://worldcat.org/identities/?ref=lorcandempsey.net) pages for [Montaigne](https://worldcat.org/identities/lccn-n79-68499?ref=lorcandempsey.net), [Philip Ford](https://worldcat.org/identities/lccn-n85-817779?ref=lorcandempsey.net), [Kraus](https://worldcat.org/identities/lccn-n79-108035?ref=lorcandempsey.net), [Pascal](https://worldcat.org/identities/lccn-n79-84279?ref=lorcandempsey.net) and [Plato](https://worldcat.org/identities/lccn-n79-139459?ref=lorcandempsey.net).
### A local view
URL: https://www.lorcandempsey.net/a-local-view/
Last updated: 2020-10-28T09:20:24.000Z
[](https://www.lib.cam.ac.uk/scienceportal/subject.php?subjectId=53&ref=lorcandempsey.net)I have had a chance to [see more](https://blog.oclc.org/lorcand/archives/001784.html?ref=lorcandempsey.net) of the [Science@Cambridge](https://www.lib.cam.ac.uk/scienceportal/?ref=lorcandempsey.net) ‘portal’ and to hear from Cambridge colleagues how they plan to evolve it.
As I noted, I particularly like the way in which access to the literature is surrounded by feed-based contextual services. I wondered about a view of materials produced within Cambridge and this is indeed on their agenda. On the medical pages (perhaps a medical portal is a ‘mortal’?) you can see how they are identifying and pulling out publications by Cambridge authors. Again, it is nice that you can subscribe to this; you can place it where you want to consume it.
### Starbucks and Arcadia
URL: https://www.lorcandempsey.net/starbucks-and-arcadia/
Last updated: 2022-12-16T04:47:46.000Z
Posting has been light as I am in Cambridge (UK) this week. Some of the time I was talking with folks involved in the Arcadia Programme. This initiative is potentially important in that it provides some space for otherwise busy practitioners to do some thinking ….
> The Arcadia Programme is a three-year programme funded by a generous grant from the Arcadia Trust to Cambridge University Library. The grant will enable us to explore the role of academic libraries in a digital age, create new programmes and services, particularly for undergraduates — and also to improve the external environment of the library. \[[Arcadia Programme | arcadia@cambridge | Cambridge University Library](https://arcadiaproject.lib.cam.ac.uk/?ref=lorcandempsey.net)\]
> A major part of the Programme is the Arcadia Fellowship Programme which will bring talented people to Cambridge to work on aspects of this very broad subject. Arcadia Fellows will work on projects aimed at increasing the library’s capability to provide users with services appropriate to a networked world. Each Fellowship will have ‘deliverables’ (broadly defined) associated with it and our findings and outputs will be shared with colleagues in the academic library community worldwide.. \[[Arcadia Programme | arcadia@cambridge | Cambridge University Library](https://arcadiaproject.lib.cam.ac.uk/?ref=lorcandempsey.net)\]
The academic adviser to the programme is [John Naughton](https://memex.naughtons.org/?ref=lorcandempsey.net). We spent a congenial hour or so the other day wandering around Saffron Walden, an interesting market town south of Cambridge. We ended up in, er, Starbucks. A Starbucks, mind you, which exposed some modest wooden beams. We were very impressed that they were able to process my US Starbucks card. A global organization indeed …
Related entries:
- [Starbucks](https://www.google.com/search?q=site%3Ahttps%3A%2F%2Fwww.lorcandempsey.net%2F+starbucks&ref=lorcandempsey.net)
### Books as History
URL: https://www.lorcandempsey.net/books-as-history/
Last updated: 2020-10-28T09:20:27.000Z
I have just read with enjoyment David Pearson’s finely produced *Books as history* \[[Oak Knoll Press](https://www.oakknoll.com/detail.php?d%5Fbooknr=96664&ref=lorcandempsey.net)\]\[[Worldcat](https://www.worldcat.org/oclc/231724429?ref=lorcandempsey.net)\].
His theme is that the artifactual properties of books have historic, aesthetic or other interest independent of the texts they convey.
He opens with some consideration of the place of the book in the current digital environment, and then proceeds to the core of the book: a chapter each on five ways in which individual books are interesting.
1. Books beyond texts. This chapter considers books as icons and the iconography of books. It looks at how books have been used in works of art and how works of art have been made from books. It considers the contribution of design, of illustration, and of typography to the impact of a book.
2. Individuality within mass production. For much of its life the book has been an object of mass production, something explicitly acknowledged in FRBR, the model of the bibliographic world used in the library community, in the ‘manifestation’. This chapter considers variation within the ‘manifestation’, whether deliberate (a luxury version printed on better paper, for example) or mistaken (a printing error, for example).
3. Variety through ownership. This chapter discusses the traces left on individual copies of books by their owners: annotations, signatures, bookplates.
4. Variety through binding. This chapter considers binding practices, a specialist area of this author.
5. The collective value of libraries. This chapter considers the aggregate effect of books in libraries. A particular collection may have interest because of the taste and sensibilities which guided its construction.
There is a concluding chapter and a case study looking in more detail at five copies of the same book “with their individual histories and differentiating features”.
I read it on a short flight. I mention this as given its 200 or so pages I had expected it would take rather longer. However, there are many fine illustrations (see the [slideshow](https://www.oakknoll.com/ssp/index.php?booknr=96664&ref=lorcandempsey.net) on the Oak Knoll Press pages for a sample) and it is written in an accessible style.
The treatment is pragmatic and more quickly reaches for examples and illustrations than for theory or historical context. The illustrations are drawn from major research libraries where the author has worked (The British Library, The National Art Library, V&A, and the University of London Research Library Services), and they are a major part of the pleasure of this volume. When done, I found myself wishing for more. What for example does the author have to say about the balance between artifactual integrity and onward transmission of the ‘content’ in conservation activities?
Here is the blurb from the publisher’s site:
> Books have been hugely important in human civilization as instruments for communicating information and ideas. The digital age is challenging their ongoing existence – although the e-book has not yet taken over from print on paper, the landscape is constantly changing, with more and more of the traditional functions of books being performed electronically. People usually think of books in terms of their contents, their texts, with less thought for books as artifacts. In fact, books may possess all kinds of potentially interesting qualities beyond their texts, as designed or artistic objects, or because they have unique properties deriving from the ways they have been printed, bound, annotated, beautified or defaced. David Pearson explores these themes and uses many examples of books from the Middle Ages to the present day to show why books may be interesting beyond their texts. As the format of the book becomes history – as texts are increasingly communicated electronically – we can recognize that books are also history in another significant way. Books can develop their own individual histories, which provide important evidence about the way they were used and regarded in the past, which make them an indispensable part of the fabric of our cultural heritage. \[[David Pearson. Books as History. Oak Knoll Press book detail](https://www.oakknoll.com/detail.php?d%5Fbooknr=96664&ref=lorcandempsey.net)\]
### djatoka, OpenURL and OOMRef-J
URL: https://www.lorcandempsey.net/djatoka-openurl-and-oomref-j/
Last updated: 2020-10-28T09:20:28.000Z
djatoka, “A Reuse Friendly, Open Source JPEG 2000 Image Server” developed at Los Alamos National Laboratory, Research Library, was released recently. An [article in D-Lib Magazine](https://www.dlib.org/dlib/september08/chute/09chute.html?ref=lorcandempsey.net) by Ryan Chute and Herbert Van de Sompel introduces it.
A particular feature of the approach is its use of the OpenURL as enabling infrastructure:
> When it comes to the reuse suggested by Andy Powell, off-the-shelf tools typically don’t go beyond offering the ability to embed an entire image in a remote page, either as a stand-alone image or as an embedded object (e.g., an applet). However, a trend is emerging to support URI-addressability of a specified Region. For example, both [Luna Imaging’s Media Manager](https://www.lunaimaging.com/insight/technicalinfo.html?ref=lorcandempsey.net) and the [Harvard University Library Image Delivery Service](https://hul.harvard.edu/ois/systems/drs/ids.html?ref=lorcandempsey.net) support identification and Region Extraction by means of home grown HTTP URI syntaxes (see \[[15](https://www.dlib.org/dlib/september08/chute/09chute.html?ref=lorcandempsey.net#15)\] for Harvard’s syntax). As we show below, djatoka continues this trend and offers URIs for a wide variety of image disseminations. Considering the widespread use of high-resolution images, the availability of a standardized syntax to request Regions or other services pertaining to JPEG 2000 images from an image server would be rather helpful. Since the URIs used for Region Extraction or to get metadata clearly serve the purpose of (dynamically) requesting services pertaining to an identified resource (the entire JPEG 2000 image), we felt that NISO Z39-88.2004 “The OpenURL Framework for Context-Sensitive Services” \[[7](https://www.dlib.org/dlib/september08/chute/09chute.html?ref=lorcandempsey.net#7)\] provides a standardized foundation that could be leveraged in this realm. Below, we give details about the basic JPEG 2000 OpenURL Application that we defined for this purpose. \[[Introducing djatoka: A Reuse Friendly, Open Source JPEG 2000 Image Server](https://www.dlib.org/dlib/september08/chute/09chute.html?ref=lorcandempsey.net)\]
In this context we were pleased that the LANL team found the work of our colleague Jeff Young useful, both his [OOMRef-J](https://www.oclc.org/research/software/openurl/default.htm?ref=lorcandempsey.net) software and his wider thinking about the evolution and wider applicability of OpenURL.
> For quite some time, OCLC’s [Jeff Young](https://www.oclc.org/research/staff/young.htm?ref=lorcandempsey.net) has been speaking about the OpenURL Framework in terms of [Q6](https://q6.oclc.org/2006/08/welcome%5F1.html?ref=lorcandempsey.net) \[[21](https://www.dlib.org/dlib/september08/chute/09chute.html?ref=lorcandempsey.net#21)\], the six core questions: What, Why, Who, Where, How, and When. The first five questions map directly to core concepts of the OpenURL Standard (Referent, ServiceType, Requester, ReferringEntity, Transport), and the last one is surprisingly missing from it. We believe Q6 is a very promising approach that, if executed properly, could give OpenURL a real chance of adoption beyond the initial target community. We would very much welcome community collaboration around these ideas. \[[Introducing djatoka: A Reuse Friendly, Open Source JPEG 2000 Image Server](https://www.dlib.org/dlib/september08/chute/09chute.html?ref=lorcandempsey.net)\]
OOMRef-J (OpenURL Object Model–Java Reference Implementation) is available [here](https://www.oclc.org/research/software/openurl/default.htm?ref=lorcandempsey.net).
Update: See Jeff’s [note](https://q6.oclc.org/2008/10/cobwebs%5Fand%5Fthe.html?ref=lorcandempsey.net) on OOMRef-J.
### Stitching costs
URL: https://www.lorcandempsey.net/stitching-costs/
Last updated: 2026-08-29T16:05:40.000Z
We are familiar with *switching costs*, the costs of changing a supplier. I may decide not to change my phone or email arrangements, for example, because I do not want to incur the effort of notifying all my contacts. Libraries are very familiar with switching costs given the range of data migration issues involved in changing library systems. Indeed, high switching costs are one reason that libraries often stay with the same vendor for long periods.
Libraries are also familiar with high ‘integration’ costs: perhaps these might be called *stitching costs*. This means that it may be costly developing higher level services based on integration of various lower level services.
Think for example of the website integration issues libraries have where they want to provide unified access to the catalog, to licensed resources, to repositories and so on. The intermittent levels of integration we see are because the ‘stitching costs’ are high.
This is largely because they are providing a thin layer over two sets of heterogeneous resources. One is the set of legacy and emerging systems, developed independently rather than as part of an overall library experience, with different fulfillment options, different metadata models, and so on (integrated library system, resolver, knowledge base, repositories, …). Another is the set of legacy database and repository boundaries that map more to historically evolved publisher configurations and business decisions than to user needs or behaviors (for example, metadata, e-Journals, eBooks, and other types of content, which may be difficult to slice and dice in useful ways).
Or think of higher level federation across library services. We have few compelling federated services, whether these are based on metadata harvesting, metasearch, or other approaches. Again, this is partly because of high stitching costs. I [cited](https://blog.oclc.org/lorcand/archives/001779.html?ref=lorcandempsey.net) Jerry McDonough’s [article](https://balisage.net/Proceedings/html/2008/McDonough01/Balisage2008-McDonough01.html?ref=lorcandempsey.net) the other day about how abstraction and optionality in library standards design creates unhelpful variation in implementation which in turn is a barrier to efficient interoperability.
Things are changing, as it becomes more important to effectively stitch library resources into other environments and as lighter-weight approaches get adopted. However, it is useful to bear stitching costs in mind when there is discussion of approaches based on federation and interoperability. These costs may be to do with technical issues (interfaces, metadata, …), or policy issues (ILL policies in a resource sharing system, for example), or higher level organizational and resource allocation issues (who will run the federation service, etc). And they are very real.
I first wrote about [stitching costs](https://www.lorcandempsey.net/stitching-services-into-user-environments-intrastructure/) (and the not very popular neologism ****intrastructure)** some years ago.
Note: Added feature image and summary comments 4 November 2022\. Added reference to previous entry on stitching costs 29 August 2026.
### Library resources on the web
URL: https://www.lorcandempsey.net/library-resources-on-the-web/
Last updated: 2020-10-28T09:20:33.000Z
Cambridge University Library has launched an interesting new website [science@Cambridge](https://www.lib.cam.ac.uk/scienceportal/?ref=lorcandempsey.net). It provides the increasingly common combination of metasearch, catalog and e-resource search. However, around this it provides a range of contextual services, many of them feed-based and dynamic. What I thought was especially interesting was the focus on providing access to collections and to library staff within a fuller user experience.
[](https://www.lib.cam.ac.uk/scienceportal?ref=lorcandempsey.net)
Here is the rationale:
> [Science@cambridge](https://www.lib.cam.ac.uk/scienceportal/?ref=lorcandempsey.net) aims to draw users into a virtual library space giving them immediate access to electronic information from their desktop, tools to help them navigate through the vast number of sources available, as well as on-line real-time help from library subject-experts.
> This development acknowledges that for many of those working in contemporary science the library is now largely a ‘virtual resource’. [Science@cambridge](https://www.lib.cam.ac.uk/scienceportal/?ref=lorcandempsey.net) will increase access to and knowledge of scientific electronic resources. It will help users discover, search across and improve the use of science e-resources, generally and within discipline specific areas. \[[Latest News](https://www.lib.cam.ac.uk/news/view.php?ref=lorcandempsey.net#news39)\]
At the top level there is a cloud-based navigation option, Yahoo Pipes-based feed aggregation of relevant feeds (podcasts, blogs), links to relevant other sites, a LibraryThing-based new books feature, and the now familiar *addthis* to your favorite bookmarking service.
The structure carries through the subject pages, where there is also specific information about library services and a Meebo widget for online connection to library staff.
I will be in Cambridge in a week or two and look forward to talking with the developers about where they plan to take this. I wondered about more local material, for example, showing articles, blogs, etc by Cambridge academic staff in the relevant subject areas.
Looking at the site I was reminded of a quote from the BBC that I have used here a couple of times already – about a ‘feed-based universe’. One of the issues that a site like this highlights is the boundary between the library resources (in the catalogue, metasearch application, and list of e-resources) and the feed/link based approach of the contextual materials.
> From a conceptual point of view, the widgetization adopted by [Facebook](https://www.facebook.com/), [iGoogle](https://www.google.com/ig?ref=lorcandempsey.net) and [netvibes](https://www.netvibes.com/?ref=lorcandempsey.net) weighed strongly on our initial thinking. We wanted to build the foundation and DNA of the new site in line with the ongoing trend and evolution of the Internet towards dynamically generated and syndicable content through technologies like RSS, atom and xml. This trend essentially abstracts the content from its presentation and distribution, atomizing content into a feed-based universe. Browsers, devices, etc therefore become lenses through which this content can be collected, tailored and consumed by the audience. \[[BBC Internet Blog](https://www.bbc.co.uk/blogs/bbcinternet/2007/12/a%5Flick%5Fof%5Fpaint%5Ffor%5Fthe%5Fbbc%5Fho.html?ref=lorcandempsey.net)\]
### Web 2.0 again
URL: https://www.lorcandempsey.net/web-20-again-2/
Last updated: 2020-10-28T09:20:36.000Z
I have just got around to looking at *Programming Collective Intelligence* \[[O’Reilly](https://oreilly.com/catalog/9780596529321/?ref=lorcandempsey.net)\]\[[Worldcat](https://www.worldcat.org/oclc/166886837?ref=lorcandempsey.net)\] by Toby Segaran.
> This fascinating book demonstrates how you can build web applications to mine the enormous amount of data created by people on the Internet. With the sophisticated algorithms in this book, you can write smart programs to access interesting datasets from other web sites, collect data from users of your own applications, and analyze and understand the data once you’ve found it. \[[Programming Collective Intelligence | O’Reilly Media](https://oreilly.com/catalog/9780596529321/?ref=lorcandempsey.net)\]
I was struck by the foreword by Tim O’Reilly, where he discusses what he sees as distinctive about Web 2.0 as a concept (there is some overlap between the foreward and the blog entry from which I quote here).
> When [Time Magazine picked “You” as their Person of the Year](https://www.time.com/time/magazine/article/0,9171,1569514,00.html?ref=lorcandempsey.net) for 2006, they cemented the idea that Web 2.0 is about “user generated content” — and that Wikipedia, YouTube, and MySpace are the heart of the Web 2.0 revolution. The true story is so much more complex than that. The content that users contribute explicitly to Web 2.0 sites is the small fraction that is visible above the surface. 80% of what matters is below, in the dark matter of implicitly-contributed data.
>
> \[[Programming Collective Intelligence – O’Reilly Radar](https://radar.oreilly.com/archives/2007/08/programming-collective-intelli.html?ref=lorcandempsey.net)\]
He talks about how Google’s invention of PageRank was in many ways the defining moment for Web 2.0, as it was one of the first applications to mobilize ‘implicitly-contributed’ data, in this case the ‘choices’ or ‘intentions’ implied by links to webpages.
> No one would characterize Google as a “user generated content” company, yet they are clearly at the very heart of Web 2.0\. That’s why I prefer the phrase “harnessing collective intelligence” as the touchstone of the revolution. A link is user-generated content, but PageRank is a technique for extracting intelligence from that content. So is Flickr’s “interestingness” algorithm, or Amazon’s “people who bought this product also bought…”, Last.Fm’s algorithms for “similar artist radio”, ebay’s reputation system, and Google’s AdSense. \[[Programming Collective Intelligence – O’Reilly Radar](https://radar.oreilly.com/archives/2007/08/programming-collective-intelli.html?ref=lorcandempsey.net)\]
> I defined Web 2.0 as “the design of systems that harness network effects to get better the more people use them.” Getting users to participate is the first step. Learning from those users and shaping your site based on what they do and pay attention to is the second step. \[[Programming Collective Intelligence – O’Reilly Radar](https://radar.oreilly.com/archives/2007/08/programming-collective-intelli.html?ref=lorcandempsey.net)\]
I have spoken about this ‘implicitly-contributed’ data as ‘intentional’ data, drawing on John Battelle’s notion of Google’s database of intentions’, the progressively richer map of user choices it is amassing.
In general, I think that we are too much occupied in libraries by the 20%, the ‘user generated content’, and not enough by network effects and the ‘dark matter of implicitly contributed data’ which drives ranking, relating and recommending on many sites.
Incidentally, I remember thinking that the Time cover story was a clumsy attention grab.
Related entries:
- [The two ways of Web 2.0](https://blog.oclc.org/lorcand/archives/001556.html?ref=lorcandempsey.net)
- [Tim O’Reilly](https://www.google.com/search?q=site%3Ahttp%3A%2F%2Forweblog.oclc.org+tim+o%27reilly&ref=lorcandempsey.net)
- [Intentional Data](https://www.google.com/search?q=intentional+data+lorcan&ref=lorcandempsey.net)
### Optimal disclosure of published materials
URL: https://www.lorcandempsey.net/optimal-disclosure-of-published-materials/
Last updated: 2020-10-28T09:20:38.000Z
Simon Inger and Tracy Gardner released an interesting report a little while ago on *How scholars navigate to scholarly content*. This is a followup to a similar study carried out in 2005 \[[pdf](https://www.sic.ox14.com/presentations/Changing%5Frequirements%5FPublisher%5FWebsites.pdf?ref=lorcandempsey.net)\], and one of the interesting strands of this report is an account of changes in that period.
The focus is on how publishers should think about their network presence in light of changing network behaviors of scholars. They report that readers are increasingly more likely to land in a publisher’s website from some other starting point (RSS, Google, A&I database, library portal, etc). This switches focus from navigation of the publisher website to effective disclosure (my word) to those other starting points. They suggest that the “most highly sought-after features of journal web sites are content alerting services, but not personalization and not search functions”. They emphasizes the importance of link and data syndication strategies to increase the exposure of their content to their potential readers.
There is much of interest in the specific results, and they have been collected into a readable and brief report. The conclusion provides a good summary.
> A key measure of publisher success is the usage of its e-journals, which can
> be maximised by influencing and enabling all the routes to its content. Library
> technology plays a key role in user navigation, as well as the more apparent
> starting points such as Google or major subject A&I databases.
> Publishers need to support all conceivable routes to their content through the
> web. This can best be achieved through the open distribution of XML
> metadata catalogues, through RSS feeds, collaboration with CrossRef, library
> technology vendors and through working with major gateways, A&Is and
> search engines.
> Just as was stated in 2005, as metadata distribution is maximised and users
> are able to choose more freely their preferred routes to content, many of the
> advanced features that users require are likely to migrate to their chosen
> gateways (or portals) leaving the publisher site ever more as a content silo,
> without the need for many of the advanced features that are currently present
> there.
> At the same time it remains true that publishers are under pressure from
> editorial boards, society members and perversely even from librarians, to
> create a high level of functionality and the publisher has to manage a careful
> balancing act to satisfy all of its constituencies. \[How readers navigate to scholarly content [PDF](https://www.sic.ox14.com/howreadersnavigatetoscholarlycontent.pdf?ref=lorcandempsey.net)\]
One question I had as I was reading it. They make a distinction between A&I services and library web pages as starting points. When the former was made available through the latter, it was not clear to me which way it was counted.
Some takeaways for me:
- The report provides good news for libraries, especially in relation to the important ‘channeling’ role of link resolvers. The authors report that nearly 60% of respondents were guided to e-journals by the library over 95% of the time. They note that this is an ‘amazing result’.
- Disclosure to user workflows has been a recurrent theme of this blog, and I was interested in how this was a major theme of the report. Increasingly we have to build services around user workflow, rather than expect them to build their workflow around services.
- I recognized the truth of the last paragraph in the conclusions above, and smiled at the expanded version in the body of the text where it was noted that features sometimes had to be incorporated to support a ‘political position with respect to societies and powerful editorial board members’.
Related entries:
- [In the flow](https://www.google.com/search?hl=en&rlz=1C1GGLS%5FenUS291&q=disclosure+discovery+lorcan+dempsey&btnG=Search&ref=lorcandempsey.net)
- [Disclosure](https://www.google.com/search?hl=en&rlz=1C1GGLS%5FenUS291&q=disclosure+discovery+lorcan+dempsey&btnG=Search&ref=lorcandempsey.net)
- [Networkflow](https://www.google.com/search?q=networkflow+lorcan&ref=lorcandempsey.net)
### The silos of the LAMs
URL: https://www.lorcandempsey.net/the-silos-of-the-lams/
Last updated: 2020-10-28T09:20:39.000Z
Libraries, archives and museums have different curatorial traditions and professional outlooks. In the digital environment, correspondences grow, around both the management of surrogates and of born-digital materials.
Based on workshops in five RLG partner institutions, my colleagues have released a report \[[PDF](https://www.oclc.org/programs/publications/reports/2008-05.pdf?ref=lorcandempsey.net)\] on institutional collaboration between libraries, archives and museums.
> The project that forms the basis of this report began in 2007, when RLG Programs initiated work on the program, Library, Archive and Museum Collaboration. The goal of the program was threefold: to explore the nature of library, archive and museum (LAM) collaborations, to help LAMs collaborate on common services and thus yield greater productivity within their institutions, and to assist them in creating research environments better aligned with user expectations—or, to reference this report’s title, to move beyond the often-mentioned silos of LAM resources which divide content into piecemeal offerings. \[Beyond the Silos of the LAMs Collaboration Among Libraries, Archives and Museums [PDF](https://www.oclc.org/programs/publications/reports/2008-05.pdf?ref=lorcandempsey.net)\]
Update: See Günter’s [update](https://hangingtogether.org/?p=513&ref=lorcandempsey.net) on the report.
### Supporting research data management needs
URL: https://www.lorcandempsey.net/supporting-research-data-management-needs/
Last updated: 2020-10-28T09:20:41.000Z
Several recent reports discuss the evolving environment of institutional research data management with particular reference to library issues. Here is a list, with a quote from each and a comment or two.
***Skills, Role & Career Structure of Data Scientists & Curators: Assessment of Current Practice & Future Needs.*** Alma Swan & Sheridan Brown (Key Perspectives Ltd) \[[summary page](https://www.jisc.ac.uk/publications/publications/dataskillscareersfinalreport.aspx?ref=lorcandempsey.net)\]\[full report [PDF](https://www.jisc.ac.uk/media/documents/programmes/digitalrepositories/dataskillscareersfinalreport.pdf?ref=lorcandempsey.net)\]
In some ways, I found this the most interesting of the crop as it provided some new perspectives for me. The aim was to consider education and career paths for those involved in data curation activities. One of the interesting outputs is a definition of some terms which correspond to different roles.
> - **Data Creator** Researchers with domain expertise who produce data. These people may have a high level of expertise in handling, manipulating and using data
> - **Data Scientist** People who work where the research is carried out – or, in the case of data centre personnel, in close collaboration with the creators of the data – and may be involved in creative enquiry and analysis, enabling others to work with digital data, and developments in data base technology
> - **Data Manager** Computer scientists, information technologists or information scientists and who take responsibility for computing facilities, storage, continuing access and preservation of data
> - **Data Librarian** People originating from the library community, trained and specialising in the curation, preservation and archiving of data
>
> \[[Skills, Role & Career Structure of Data Scientists & Curators: Assessment of Current Practice & Future Needs : JISC](https://www.jisc.ac.uk/publications/publications/dataskillscareersfinalreport.aspx?ref=lorcandempsey.net)\]
***Identifying Factors of Success in CIC Institutional Repository Development – Final Report***. Carole Palmer; Lauren C Teffeau; Mark P Newton. \[[summary page](https://www.ideals.uiuc.edu/handle/2142/8981?ref=lorcandempsey.net)\]\[full report [PDF](https://www.ideals.uiuc.edu/bitstream/2142/8981/5/Palmer%20et%20al%20Mellon%20Report.pdf?ref=lorcandempsey.net)\]
Here is how this report is characterised by the authors: “This case study documents the investments and progress being made at three operational IRs at doctoral research institutions to provide a provisional baseline for determining realistic goals and promising approaches for IR development at similar institutions.”
Palmer and her colleagues at the [Center for Informatics Research in Science and Scholarship](https://cirss.lis.uiuc.edu/?ref=lorcandempsey.net) at UIUC have assembled considerable research capacity in this area, and are doing major work to explore the evolving intersections of information management and changing research behaviors.
This is the report of a year long comparative study of institutional repository development at three CIC institutions. Interestingly, in light of the Swan/Brown study, a major part of the analysis is around the various roles that have emerged to support development, management, policy and liaison issues. (Note: see Dorothea Salo’s [favorable review](https://cavlec.yarinareth.net/2008/09/22/a-b-and-c/?ref=lorcandempsey.net) of the report.)
> Within the cases, there were strong indications that IRs can make important contributions to scholarship, particularly in solving specific information visibility, management, or access problems experienced by faculty. At the same time, some of the assumed benefits of IRs are perceived as redundant by scholars who practice other forms of open access dissemination, or are considered risky by the standards of some disciplinary cultures. In general, the basic aims of universities in investing in IRs—to collect, preserve, and provide access to their research output—seem misleadingly simplistic compared to what IRs are actually attempting to accomplish, and what they will need to do to identify and successfully implement functions that are not redundant or risky and of high value to faculty. While the cases show lower levels of participation by humanities faculty and academic units, the traditional role of the research library as the laboratory for humanities scholarship is recognized, but exploration of the potential for IRs to better support humanities research processes has not yet been prioritized. \[*Identifying Factors of Success in CIC Institutional Repository Development – Final Report*. [PDF](https://www.ideals.uiuc.edu/bitstream/2142/8981/5/Palmer%20et%20al%20Mellon%20Report.pdf?ref=lorcandempsey.net)\]
***No brief candle: reconceiving research libraries for the 21st Century***. CLIR. August 2008\. \[[summary page](https://www.clir.org/pubs/abstract/pub142abst.html?ref=lorcandempsey.net)\]\[full report [HTML](https://www.clir.org/pubs/reports/pub142/contents.html?ref=lorcandempsey.net) [PDF](https://www.clir.org/pubs/reports/pub142/pub142.pdf?ref=lorcandempsey.net)\]
This report comprises papers from a CLIR Symposium held in early 2008\. The closer engagement of the library in changing research and learning behaviors was a consistent theme, as was the emergence of a variety of institutional data issues. And this is a central concern of Rick Luce’s contribution: *[A New Value Equation Challenge: The Emergence of eResearch and Roles for Research Libraries](https://www.clir.org/pubs/reports/pub142/luce.html?ref=lorcandempsey.net)*. As might be expected from such an event, the focus is on broad forward-looking service and policy issues.
***Ithaka’s 2006 studies of key stakeholders in the digital transformation of higher education. August 18 2008.*** Ross Housewright and Roger Schonfeld. \[[summary page](https://www.ithaka.org/research/faculty-and-librarian-surveys?ref=lorcandempsey.net)\]\[full report [PDF](https://www.ithaka.org/research/Ithakas%202006%20Studies%20of%20Key%20Stakeholders%20in%20the%20Digital%20Transformation%20in%20Higher%20Education.pdf?ref=lorcandempsey.net)\]
This white paper reports findings from Ithaka studies of researcher attitudes to information management and sources. There is also some polling of librarian attitudes. The studies were carried out in 2000, 2003 and 2006, so this report charts changes in that time. The focus is on published materials although there is one section on what the report calls ‘digital repositories’.
> Still, the vast majority – almost two-thirds – of faculty members are not even sure if their institution has a digital repository and less than a third of those aware of a campus digital repository report having ever contributed content to it. It is clear that these repositories have not become embedded in faculty workflows; in fact, many faculty are not even aware of their existence. Faculty of all different disciplines and across different size institutions were relatively equally unaware if their institution has a repository.Based on these findings, in the absence of mandates or strong campus-wide leadership commitments, we do not foresee institutional repositories yielding a transformative influence on the business side of journal publishing. Other types of digital repositories, especially those for storing images and special collections, are much more likely to continue to grow in importance at all types of institutions. \[Ithaka’s 2006 studies of key stakeholders in the digital transformation of higher education. [PDF](https://www.ithaka.org/research/Ithakas%202006%20Studies%20of%20Key%20Stakeholders%20in%20the%20Digital%20Transformation%20in%20Higher%20Education.pdf?ref=lorcandempsey.net)\]
### Flexibility may not be a good design goal
URL: https://www.lorcandempsey.net/flexibility-may-not-be-a-good-design-goal/
Last updated: 2020-10-28T09:20:42.000Z
Jerry McDonough has written an interesting and important article about XML, interoperability, and the social context of standards making: [Structural Metadata and the Social Limitation of Interoperability: A Sociotechnical View of XML and Digital Library Standards Development](https://balisage.net/Proceedings/html/2008/McDonough01/Balisage2008-McDonough01.html?ref=lorcandempsey.net).
Drawing on a number of examples he presents a strong conclusion:
> The digital library community seems to face a dilemma at this point. Through its pursuit of design goals of flexibility, extensibility, modularity and abstraction, and its promulgation of those goals as common practice through its implementation of XML metadata standards, it has managed to substantially impede progress towards another commonly held goal, interoperability of digital library content across a range of systems. \[[Structural Metadata and the Social Limitation of Interoperability: A Sociotechnical View of XML and Digital Library Standards Development](https://balisage.net/Proceedings/html/2008/McDonough01/Balisage2008-McDonough01.html?ref=lorcandempsey.net)\]
For example, he discusses how greater abstraction in design creates greater optionality in use:
> … the implementation of highly abstract elements for the definition of structure provides a tremendous amount of flexibility to document encoders; there is a vast number of potential encodings of any given object in METS, with variations possible in depth of structure (do I limit my structure to musical movements or do I provide structural information to the measure level?), labeling (you say TYPE=”book”, I say TYPE=”monograph”), and arrangement (should the Lord of Rings film trilogy be encoded as a single METS file? Three METS files? Three METS files for the individual films and a fourth representing the abstract notion of the Trilogy?). This can lead to significant variation in encoding practices, even between two institutions dealing with remarkably similar material and using the same metadata standards, as noted by ([DiLauro et al., 2005](https://balisage.net/Proceedings/html/2008/McDonough01/Balisage2008-McDonough01.html?ref=lorcandempsey.net#mcdo03)).\[[Structural Metadata and the Social Limitation of Interoperability: A Sociotechnical View of XML and Digital Library Standards Development](https://balisage.net/Proceedings/html/2008/McDonough01/Balisage2008-McDonough01.html?ref=lorcandempsey.net)\]
He discusses the conflicting goals of **control** and **connection**. The ability to **control**, to respond to local needs and conditions, promotes flexibility. The ability to **connect**, to efficiently exchange, promotes constraint.
The library community has emphasized flexibility in its standards making and in the past this may have made some sense: the actual exchange of data was quite limited. However, if we expect data to flow efficiently between systems and services then this becomes problematical and greater constraint is beneficial.
Via Evan Owens.
### TagCrowd: yet another tag cloud generator
URL: https://www.lorcandempsey.net/tagcrowd-yet-another-tag-cloud-generator/
Last updated: 2020-10-28T09:20:44.000Z
Several services will now generate tag clouds for you based on a submitted URL or text. I suppose these make ideal ‘cloud’ services (ho, ho, …).
I have just come across TagCrowd. Here is what it makes of this morning’s CNN home page. It is pretty clear what is on folks’ minds!
arrested bailout battle blog business campaign cars cats child cnn cnnmoney colombia com deaths debate egypt ends evangelist forum hemingway house ireport kyle living local makeup mccain meade news palin police politics popular porn presidential probe purring robin stories storm strengthens suspects talks terror tonight tropical tv updated video world
created at [TagCrowd.com](https://tagcrowd.com/?ref=lorcandempsey.net)
Via the University of Cambridge [Science Portal](https://www.lib.cam.ac.uk/scienceportal/?ref=lorcandempsey.net) via the [Arcadia Project](https://arcadiaproject.lib.cam.ac.uk/?ref=lorcandempsey.net).
### Dublin Core in Berlin
URL: https://www.lorcandempsey.net/dublin-core-in-berlin/
Last updated: 2020-10-28T09:20:46.000Z
A wide[ range of presentations](https://dc2008.de/programme?ref=lorcandempsey.net) from the Dublin Core conference held this week in Berlin is available. Much of general interest about the use of metadata in different domains and the semantic web, and lots of specific descriptions of tools, techniques, and initiatives, ….
### QOTD: your friendly public library
URL: https://www.lorcandempsey.net/qotd-your-friendly-public-library/
Last updated: 2020-10-28T09:20:47.000Z
A UK colleague sent me a pointer to [this discussion](https://www.thecnj.co.uk/camden/2008/091108/news091108%5F03.html?ref=lorcandempsey.net) of directions at [Camden public libraries](https://www.camden.gov.uk/ccm/navigation/leisure/libraries-and-online-learning-centres/?ref=lorcandempsey.net) which includes this comment about public libraries by novelist [Beryl Bainbridge](https://worldcat.org/identities/lccn-n79-145714?ref=lorcandempsey.net):
> Camden Town novelist Beryl Bainbridge said yesterday: “Why do they want them to be friendly places? They’re meant to be sacred. I bet you’d really impress young people if you had really old museum exteriors with lots of old books and silence. Make things accessible and people don’t want them. I hate modernity.” \[[Camden New Journal – News: Mike Clarke | Flick Rea | Beryl Bainbridge | Jonathan Miller | Alan Templeton | Doris Lessing](https://www.thecnj.co.uk/camden/2008/091108/news091108%5F03.html?ref=lorcandempsey.net)\]
### Worldcat on iPhone
URL: https://www.lorcandempsey.net/worldcat-on-iphone/
Last updated: 2020-10-28T09:20:49.000Z
Several colleagues have commented on the [view of Worldcat](https://www.apple.com/webapps/searchtools/worldcat.html?ref=lorcandempsey.net) optimized for the iPhone/iTouch created by our colleague Bruce Washburn.
It is a nice use of the [Worldcat Search API](https://www.oclc.org/worldcatapi/default.htm?ref=lorcandempsey.net) and it pulls data from [Worldcat](https://worldcat.org/?ref=lorcandempsey.net) and [Worldcat Identities](https://worldcat.org/identities?ref=lorcandempsey.net).
As I don’t have a Safari browser or an iPhone to hand, I am cheating by showing you how it looks in Chrome …
[](https://www.apple.com/webapps/searchtools/worldcat.html?ref=lorcandempsey.net)
Related entries:
- [Mobile access again](https://blog.oclc.org/lorcand/archives/001644.html?ref=lorcandempsey.net)
- [Worldcat and the iPhone ](https://hangingtogether.org/?p=508&ref=lorcandempsey.net)(Jim on HangingTogether)
### The flatpack wealth of nations
URL: https://www.lorcandempsey.net/the-flatpack-wealth-of-nations/
Last updated: 2020-10-28T09:20:52.000Z
Robert Crawford’s poem [Digital Library, St Andrews](https://www.nationalpoetryday.co.uk/digital-library/?ref=lorcandempsey.net), finishes with these lines ….
> Where laptops open like thick-leaved books
>
> The flatpack wealth of nations.
I know this because I listened to him talk to John MacColl in the latest PARCast …
> Robert Crawford, Professor of Modern scottish Literature at the University of St Andrews, and well-known poet, talks with John MacColl about scholarship, the importance of digitized archives and the inspiration his poetry derives from new technologies.
> The discussion includes details about the scholarship which supported “Scotland’s Books,” a recently published book about the history of Scottish literature, and a forthcoming biography of Robert Burns. Also included is Robert’s description of the importance of digitized archives as well as the pleasure of working with paper in archives such as that at St Andrews, with hundreds of years’ worth of undigitized materila still to be charted. \[[Crawford Podcast \[OCLC\]](https://www.oclc.org/programs/news/2008-09-19.htm?ref=lorcandempsey.net)\]
Check out Robert Crawford’s [Worldcat Identity](https://www.worldcat.org/identities/lccn-n91-4883?ref=lorcandempsey.net) page.
This is the ninth [PARcast](https://www.oclc.org/programsandresearch/parcasts/default.htm?ref=lorcandempsey.net). Earlier interviews were with Richard Ovenden (Bodleian Library, Oxford), Jackie Dooley
(Consulting Archivist, OCLC Programs and Research), Ken Hamma (then Executive Director for Digital Policy and Initiatives J. Paul Getty Trust), MacKenzie Smith (Associate Director for Technology, Massachusetts Institute of Technology Libraries), Jenn Riley (Metadata Librarian, Digital Library Program, Indiana University), Dennis Meissner (Head of Collections Management, Minnesota Historical Society), Jeremy Frumkin (Head of Emerging Technologies,
Oregon State University), Mark Dimunation (Chief of the Rare Book and Special Collections Division, Library of Congress).
### Generations
URL: https://www.lorcandempsey.net/generations/
Last updated: 2020-10-28T09:20:53.000Z
We have been having some internal discussion about the usefulness of the ‘generational turn’ in much recent exploration of reading, media consumption, and learning and research behaviors. It is impossible to move without bumping into a discussion of netgen, natives and immigrants, Y or X, screenagers, the Google generation, and so on.
I incline to Andy Powell’s scepticism, and not just because because I have a significant birthday coming up 😉 He [suggests](https://efoundations.typepad.com/efoundations/2008/09/residents-and-v.html?ref=lorcandempsey.net) that attitude is more important than age, although in response one might wonder about the influence of age on attitude.
Anyway, I also liked Dave White’s presentation of the terms ‘resident’ and ‘visitor’ (as alternatives to ‘native’ and ‘immigrant’) that was the occasion of Andy’s post.
> Anyway, our students appropriation of online services did not seem to follow a simple pattern based on skill level. It seemed to depend on if they saw the web as a ‘place to live’ or as a collection of useful tools. This underlying motivation lead us to outline two main categories of distance learning student. \[[TALL blog » Blog Archive » Not ‘Natives’ & ‘Immigrants’ but ‘Visitors’ & ‘Residents’](https://tallblog.conted.ox.ac.uk/index.php/2008/07/23/not-natives-immigrants-but-visitors-residents/?ref=lorcandempsey.net)\]
These two categories are ‘resident’ and ‘visitor’.
> The resident is an individual who lives a percentage of their life online. The web supports the projection of their identity and facilitates relationships. These are people who have an persona online which they regularly maintain. This persona is normally primarily in a social networking sites but it is also likely to be in evidence in blogs or comments, via image sharing services etc The Resident will of course interact with all the practical services such as banking, information retrieval and shopping etc but they will also use the web to socialise and to express themselves. They are likely to see the web as a worthwhile place to put forward an opinion. They often use the web in all aspects of the of their lives; professionally, for study and for recreation. In fact the resident considers that a certain portion of their social life is lived out online. The web has become a crucial aspect of how they present themselves and how they remain part of networks of friends or colleagues. \[[TALL blog » Blog Archive » Not ‘Natives’ & ‘Immigrants’ but ‘Visitors’ & ‘Residents’](https://tallblog.conted.ox.ac.uk/index.php/2008/07/23/not-natives-immigrants-but-visitors-residents/?ref=lorcandempsey.net)\]
> The Visitor is an individual who uses the web as a tool in an organised manner whenever the need arises. They may book a holiday or research a specific subject. They may choose to use a voice chat tool if they have friends or family abroad. Often the Visitor puts aside a specific time to go online rather than sitting down at a screen to maintain their presence at any point during the day. They always have an appropriate and focused need to use the web but don’t ‘reside’ there. They are sceptical of services that offer them the ability to put their identity online as don’t feel the need to express themselves by participating in online culture in the same manner as a Resident. \[[TALL blog » Blog Archive » Not ‘Natives’ & ‘Immigrants’ but ‘Visitors’ & ‘Residents’](https://tallblog.conted.ox.ac.uk/index.php/2008/07/23/not-natives-immigrants-but-visitors-residents/?ref=lorcandempsey.net)\]
He makes the interesting point that although a resident may have set up various tools to manage their online information flow they are not necessarily more effective at researching any particular topic than a visitor. And here is the pragmatic concluding paragraph …
> This Visitor, Resident distinction is useful when considering which technologies to provide for online learners. For example if your learners are mainly Visitors they are unlikely to take advantage of any feed based system for aggregated information you may put in place. They are also unlikely to blog or comment as part of a course. The Resident will expect to have the opportunity to offer opinions on topics and to socialise around a programme of study. In fact they are likely to find ways of doing this even if they are not ‘officially’ provided. We offered membership of a facebook group to our students as they left their online courses. The majority signed-up without question as they wanted to stay in touch with fellow students and continue discussions. The remainder saw the group as pointless and a possible invasion of privacy. Both sides of this argument are correct… It’s a question of approach and motivation, hence Visitors and Residents. \[[TALL blog » Blog Archive » Not ‘Natives’ & ‘Immigrants’ but ‘Visitors’ & ‘Residents’](https://tallblog.conted.ox.ac.uk/index.php/2008/07/23/not-natives-immigrants-but-visitors-residents/?ref=lorcandempsey.net)\]
I find this distinction quite helpful and it maps well to experiences. Think of something as simple as RSS for example. Some people – *residents* – expect anything that moves to have an RSS feed, and their aggregator is a primary channel of information about the world. Others happily live without it. Or think about the ‘[amplified conference](https://en.wikipedia.org/wiki/Amplified%5Fconference?ref=lorcandempsey.net)‘, the set of social networking, communication and annotation tools that accompany some conference events. For *residents*, having a ‘tag’ for a conference that unifies its online amplification (blog entries, photos on flickr, etc) is obvious and natural; *visitors* may not see the point.
Of course, it is often residents who talk about the importance of the residential behaviors. It would be interesting to have a sense of proportion: how do they reckon the students on their online courses break down across the two categories?
### Naming opportunities
URL: https://www.lorcandempsey.net/naming-opportunities/
Last updated: 2024-12-23T04:22:14.000Z
\[warning: retrospection ahead\]
In a longish and intermittently productive professional writing career, I have had lots of opportunities to come up with titles for publications. With variable results.
Some I like. *[Full disclosure](https://www.ukoln.ac.uk/services/lic/fulldisclosure/?ref=lorcandempsey.net)* captured, I thought, the gist of the report to which it is attached \[[pdf](https://www.ukoln.ac.uk/services/lic/fulldisclosure/report.pdf?ref=lorcandempsey.net)\]. This was a study into the extent of the retrospective catalog conversion challenge in UK libraries and archives. The rationale was similar to the ‘hidden collections’ discussion. If the existence of particular collections is not disclosed, they may not be discovered, and their value to research and learning is diminished.
Some were awful. *A Utopian place of criticism?* was a rather opaque title for [a rather dense article](https://www.ukoln.ac.uk/dlis/models/publications/utopia/?ref=lorcandempsey.net). It is an example of the strained literary allusion that is more of an indulgence for the authors than a helpful hook for the reader.
Some were mis-timed. *[Libraries, networks and OSI](https://www.worldcat.org/oclc/185576057?ref=lorcandempsey.net)* was a [well-received](https://epress.lib.uh.edu/pr/v2/n1/lynch.2n1?ref=lorcandempsey.net) contribution. Despite the advice of colleagues, I was reluctant to drop OSI from the title because a lot of work had gone into the OSI bits. As it turns out I should have heeded the advice. Interest in OSI had peaked and gone into decline by the time the second edition came out. Its impact would have been greater if it had been called *Libraries and networks*, or somesuch: OSI got in the way.
Note 1: An early lesson in the importance of brand.
Note 2: How many current readers know what OSI was 😉
Anyway, this nostalgic note was prompted by the appearance on my desk of *No brief candle: reconceiving research libraries for the 21st Century* \[[pdf](https://www.clir.org/pubs/reports/pub142/pub142.pdf?ref=lorcandempsey.net)\] \[[worldcat](https://www.worldcat.org/oclc/236082910?ref=lorcandempsey.net)\] from CLIR which despite the strained literary allusion in its title has some interesting contributions to which I will no doubt return in these pages.
**Update:** Picture and abstract added 12/22/2024\.
### Public library value
URL: https://www.lorcandempsey.net/public-library-value/
Last updated: 2020-10-28T09:20:57.000Z
I wrote a [blog entry](https://blog.oclc.org/lorcand/archives/001428.html?ref=lorcandempsey.net) from the fine public library in Cheyenne last year. I was interested to come across an article mentioning this same library in this week’s *Economist*.
> Laramie County’s libraries are the best of an excellent lot. Their flagship is a three-storey, zinc-clad edifice in Cheyenne, a town best-known for its annual rodeo. In addition to a third of a million volumes, the building contains well-equipped meeting rooms and computer labs. It has a large area oriented towards teenagers which is often busy, in part because of the librarians’ tolerant attitude to food. In all, about three-quarters of Laramie County’s 86,000 residents hold library cards. \[[Public libraries in Wyoming | Why cowboys read | The Economist](https://www.economist.com/world/unitedstates/displaystory.cfm?story%5Fid=12208693&ref=lorcandempsey.net)\]
And this being the *Economist* there is a punchline ….
> This attention to outreach and meeting local demands is partly the legacy of a long campaign to build Cheyenne’s library. In 2003, after more than ten years’ work, the librarians managed to put an initiative on the county ballot that allocated $27m in additional sales taxes to the new building. Tax increases are always a tough sell in Wyoming, so the librarians were forced to find out exactly what the people of Laramie County wanted for their libraries, and give it to them. In southern Wyoming, at least, an excellent library system was not built in the face of resistance to public spending. The interesting truth is that it is excellent precisely because of it. \[[Public libraries in Wyoming | Why cowboys read | The Economist](https://www.economist.com/world/unitedstates/displaystory.cfm?story%5Fid=12208693&ref=lorcandempsey.net)\]
I am reminded of a piece I[ have quoted before](https://blog.oclc.org/lorcand/archives/001424.html?ref=lorcandempsey.net) from Eleanor Jo Rodger in the September 2007 Library Journal.
> Creating value for our host systems always involves three things: Librarians must understand their host systems; they must understand the source of their claim to being a legitimate part of their system; and they must do their work well so the system is better because they are there. It’s usually far more a matter of asking and listening than it is of telling and pleading.
Also relevant is the recent OCLC membership report *[From Awareness to Funding: A study of library support in America.](https://www.oclc.org/us/en/reports/funding/default.htm?ref=lorcandempsey.net)*
Related entry:
- [Knowing about libraries and services in the network](https://blog.oclc.org/lorcand/archives/001429.html?ref=lorcandempsey.net)
### Power grab
URL: https://www.lorcandempsey.net/power-grab/
Last updated: 2020-10-28T09:20:59.000Z
Posting is light this week. We have been without power at home since the weekend as the remnants of Hurricane Ike passed through Ohio. I write blog posts in the morning between the children heading off to school and coming in to work, or in the evening. Not at the moment 😉
As I have mentioned before, we live beside a branch of Columbus Metropolitan Library. It is on a different circuit and has power. It is hopping, as people come to ‘fill up’ on power … here is what the Columbus Dispatch had to say this morning ….
> Like moths to a flame, Clintonville residents converged yesterday on a corner of Whetstone Park for a collective power trip.
> The Whetstone branch of the Columbus Metropolitan Library and adjacent lighted tennis courts were literal beacons of light last night in a neighborhood otherwise bathed in dark. \[[The Columbus Dispatch : Whetstone library keeps residents charged](https://www.dispatch.com/live/content/local%5Fnews/stories/2008/09/17/library.ART%5FART%5F09-17-08%5FA6%5FG3BBO4K.html?type=rss&cat=&sid=101&ref=lorcandempsey.net)\]
### QOTD: reading is community work
URL: https://www.lorcandempsey.net/qotd-reading-is-community-work/
Last updated: 2020-10-28T09:21:01.000Z
The University of Bristol has an interesting offer: A BA in English Literature and Community Engagement. I wonder if any of the students work with or through libraries.
> The Department of English offers a part-time BA (Hons) in English Literature and Community Engagement. This is an undergraduate degree, taught entirely in evenings (normally one night per week) over six years. It is aimed primarily at mature students from the local area who, for whatever reason, need or wish to study part-time. …
> … The degree is the first in this country to combine literary study and community work throughout the programme. Each student will have the opportunity to study a full range of literature in English and also to run a reading group in the community (or at their workplace) as part of their studies. \[[Bristol University – Department of English – BA (Hons) English Literature and Community Engagement](https://www.bris.ac.uk/english/cont-ed/elce?ref=lorcandempsey.net)\]
**Peripherally related update:** while looking to see if there was any reference to the above initiative on the Bristol public libraries’ website I came across the *Books on prescription* scheme. This is an interesting form of community engagement by the library.
> In much the same way that your GP can prescribe medication for you to pick up at the chemist, health workers can now prescribe a range of self-help books which can be collected from libraries across Bristol. …
> … The books which are part of the scheme have been chosen by a range of specialist health professionals, counsellors and academics. Some of the books contain exercises, self-assessments and treatment programmes for you to work through as you read them. These are designed to raise your self-awareness and then suggest courses of action to help, often simple behavioural or thought strategies. \[[Bristol City Council: Books and reading: Books on prescription](https://www.bristol.gov.uk/ccm/content/Leisure-Culture/Libraries/books-on-prescription.en?ref=lorcandempsey.net)\]
### Up front repository work
URL: https://www.lorcandempsey.net/up-front-repository-work/
Last updated: 2020-10-28T09:21:03.000Z
Mark Leggott has an interesting post on how they plan to construct and populate their institutional repository.
> With a minimum of training our hope is that the presentation of a 90% complete IR record will encourage faculty to complete the process. Some future enhancements will include parsing the Sherpa-Romeo record to automatically grab the publisher version where appropriate and implement disseminators to convert word-processing formats. We will be providing the RIB as an example in our packaged open source Drupal/Fedora module, which will be available at the end of September from SourceForge. \[[LoomWare: RIB – Repository in a Box](https://loomware.typepad.com/loomware/2008/09/rib---repositor.html?ref=lorcandempsey.net)\]
They plan to create an up front record of publications by harvesting from existing databases and faculty CVs. They plan to link to the institutional OpenURL resolver and to the [Sherpa-Romeo repository](https://www.sherpa.ac.uk/romeo/?ref=lorcandempsey.net) of publisher policies.
The intention is to present the faculty member with a set of data that he or she can augment or amend, rather than will an empty slate.
> The individual can click the “Get-It @ UPEI” button to retrieve the final version, if desired, read the publisher open access policy (including a link to the full policy) and add the appropriate version of the pre-post-final print. \[[LoomWare: RIB – Repository in a Box](https://loomware.typepad.com/loomware/2008/09/rib---repositor.html?ref=lorcandempsey.net)\]
### University mission: curation
URL: https://www.lorcandempsey.net/university-mission-curation/
Last updated: 2020-10-28T09:21:05.000Z
The University of Edinburgh strategic [plan](https://www.planning.ed.ac.uk/strategic%5Fplanning/SP2008-12/SP0812.htm?ref=lorcandempsey.net) for 2008-12 states a new mission:
> The mission of our University is the creation, dissemination and curation of knowledge. \[[Governance and Strategic Planning: Strategic Planning – Strategic Plan 08-12](https://www.planning.ed.ac.uk/strategic%5Fplanning/SP2008-12/SP0812.htm?ref=lorcandempsey.net)\]
Note the word **curation**.
Via Chris Rusbridge, Director of the Digital Curation Centre at the University who is justifiably [pleased](https://digitalcuration.blogspot.com/2008/09/curation-in-university-mission.html?ref=lorcandempsey.net) …
### Hackathon
URL: https://www.lorcandempsey.net/hackathon/
Last updated: 2020-10-28T09:21:06.000Z
Check out the Hackathon being sponsored by the [OCLC Developers’ Network](https://worldcat.org/devnet/index.php/Main%5FPage?ref=lorcandempsey.net) and [NYPL Labs](https://labs.nypl.org/?ref=lorcandempsey.net) …. It is on Nov 7-8 in New York.
> Join fellow coders, hackers and tech-enthusiasts for a two-day *WorldCat Hackathon* at the New York Public Library. Sponsored by the **OCLC Developer’s Network** and [NYPL Labs](https://labs.nypl.org/?ref=lorcandempsey.net "https://labs.nypl.org/") of [The New York Public Library](https://nypl.org/?ref=lorcandempsey.net "https://nypl.org/"), the WorldCat Hackathon gives participants the opportunity for two full days of brainstorming and coding mash-ups with local systems and [other Web services](https://techessence.info/apis/?ref=lorcandempsey.net "https://techessence.info/apis/") to take advantage of all that [WorldCat](https://www.worldcat.org/?ref=lorcandempsey.net "https://www.worldcat.org/"), the world’s largest bibliographic database, has to offer. \[[2008NYCHackathon – WorldCat Developers’ Network](https://worldcat.org/devnet/index.php/2008NYCHackathon?ref=lorcandempsey.net)\]
It prompts a reminder about the [list of library APIs](https://techessence.info/apis?ref=lorcandempsey.net) that Roy is maintaining.
### Chrome links
URL: https://www.lorcandempsey.net/chrome-links/
Last updated: 2020-10-28T09:21:08.000Z
The new Google Chrome browser has captured major attention since it was launched a few days ago. Here, without extensive comment, are links to some interesting posts about Chrome.
Nicholas Carr considers strategic motivations ….
> To Google, the browser has become a weak link in the cloud system – the needle’s eye through which the outputs of the company’s massive data centers usually have to pass to reach the user – and as a result the browser has to be rethought, revamped, retooled, modernized. Google can’t wait for Microsoft or Apple or the Mozilla Foundation to make the changes (the first has mixed feelings about promoting cloud apps, the second is more interested in hardware than in clouds, and the third, despite regular infusions of Google bucks, lacks resources), so Google is jump-starting the process with Chrome. \[[Rough Type: Nicholas Carr’s Blog: The cloud’s Chrome lining](https://www.roughtype.com/archives/2008/09/the%5Fclouds%5Fchro.php?ref=lorcandempsey.net)\]
In a detailed post, Niall Kennedy looks at motivations, the contribution of particular acquisitions and technologies, and the people involved and their experiences.
> Android, Chrome, and Gears will continue to grow in unison and extend individual pieces into established operating systems. Google is building a new suite of application extraction layers that should have strong leverage across Windows, Mac, and Linux to directly control the company’s destiny on these platforms. \[[The story behind Google Chrome](https://www.niallkennedy.com/blog/2008/09/google-chrome.html?ref=lorcandempsey.net)\]
I [commented](https://blog.oclc.org/lorcand/archives/001761.html?ref=lorcandempsey.net) the other day on the single box. Chris Messina has some interesting remarks ….
> So if you were going to [design a new browser](https://www.google.com/chrome/intl/en/why.html?hl=en&ref=lorcandempsey.net), how would you handle the enormity of that responsibility? How would you seize the monument of that opportunity and create something great?
> Well, for starters, you’d probably want to think about that first run experience — what it’s like to get behind the wheel for the very time with a newly minted driver’s permit — with the daunting realization that you can now go anywhere you please…! Which is of course awesome, until you realize that you have no idea where to go first!
> Historically, the solution has been to flip-flop between [portals and search boxes](https://www.flickr.com/photos/factoryjoe/sets/72157607075652506/?ref=lorcandempsey.net), and if we’ve learned anything from [Google’s shockingly austere homepage](https://google.com/?ref=lorcandempsey.net), it comes down to recognizing that the first step of getting somewhere is expressing some notion of where you want to go ….. \[[Musings on Chrome, the rebirth of the location bar and privacy in the cloud | FactoryCity](https://factoryjoe.com/blog/2008/09/02/musings-on-chrome-the-rebirth-of-the-location-bar-and-privacy-in-the-cloud/?ref=lorcandempsey.net)\]
He notes that the location field has been “fairly inert and useless”, and notes some examples which lead him to say that “browsers can and should provide more direction and assistance to get people going”.
> So you can imagine, having recognized this trend, Google went ahead and [combined the search box and the location field](https://dev.chromium.org/user-experience/omnibox?ref=lorcandempsey.net) in Chrome and is now pushing the location bar as the starting place, as well as where to do your searching … \[[Musings on Chrome, the rebirth of the location bar and privacy in the cloud | FactoryCity](https://factoryjoe.com/blog/2008/09/02/musings-on-chrome-the-rebirth-of-the-location-bar-and-privacy-in-the-cloud/?ref=lorcandempsey.net)\]
He then goes on to discuss a tradeoff: if we are to benefit from these predictive and responsive services then we need to share data about our behaviors.
Fred Stuzman continues this discussion ….
> That is, in embracing the mediated web, we trade (to some extent) our agency, any sense of privacy, and most importantly, our extant strategies of *finding and reminding* for new, less conceptually transparent ones. To embrace the web in Chrome’s model, we must embrace the algorithm, and essentially invite it into our minds. This new lens is all-or-nothing, and it casts away our strategies of past, those operationalized in pre-web design patterns. \[[Unit Structures – Fred Stutzman’s thoughts about information, social networks and technology.](https://fstutzman.com/?ref=lorcandempsey.net)\]
And to return to the general strategic direction, Umair Haque discusses it in the context of his ongoing grand narrative about what success means in a network environment …
> **Chrome is a shared resource that ensures the sustainable growth of a larger ecosystem.** There are two key words in that sentence. The first is *shared*. Google is investing in a shared resource because it has the potential to expand the pie dramatically for all, and so Google stands to benefit more than by hoarding it. The second is *sustainable growth*: through Chrome, Google ensures the ecosystem stays a level playing field, amplifying incentives for innovation, quality, and productivity. \[[How to Chrome Your Industry – Umair Haque](https://discussionleader.hbsp.com/haque/2008/09/where%5Fis%5Fthe%5Fchrome%5Fin%5Fyour%5Fst.html?ref=lorcandempsey.net)\]
### Life and passwords
URL: https://www.lorcandempsey.net/life-and-passwords/
Last updated: 2020-10-28T09:21:09.000Z
It sometimes seems like this: life is a series of forgotten passwords and one forgotten OpenID.
### QOTD: Books on the web
URL: https://www.lorcandempsey.net/qotd-books-on-the-web/
Last updated: 2020-10-28T09:21:11.000Z
An interesting story about an academic imprint from Bloomsbury with a different business model ….
> The imprint will use Creative Commons licences to allow non-commercial use of all its titles on publication. Pinter described it as “a major commitment to spreading knowledge more easily throughout the world, with a sustainable business model”.
> She said it was the first time a major publishing company had devoted a whole imprint to this model. “We think it will work for certain kinds of books: it will promote our titles, which will be known because the students will have easy access to them in a digital form, and we will be relying on the institutional market and library sales.” Titles will be sold as books using short-run technologies and print-on-demand. \[[theBookseller.com](https://www.thebookseller.com/news/66448-bloomsbury-unveils-academic-imprint.html?ref=lorcandempsey.net)\]
It will be interesting to see how this develops and in particular how ‘commercial’ use is defined. Will it be OK to add the titles to various emerging aggregations of ebooks? And what will the attitude towards the library promoting use of the free versions by putting records for them in catalogs and so on?
The story claims that 50 titles will be in circulation by the end of 2009.
Via [PersonaNonData](https://personanondata.blogspot.com/?ref=lorcandempsey.net).
### Really one box
URL: https://www.lorcandempsey.net/really-one-box/
Last updated: 2020-10-28T09:21:12.000Z
Some time ago I was going to look at something on the web with my son. He looked on incredulously as I began to type in a (medium-sized) URL. “What are you doing?” he asked “why don’t you use the other box?”.
I hadn’t realized until then that his preferred entry point for everything was the search box. Most ‘known’ thing he is looking for have a name or some other obvious handle with which to search, and will land near the top of a search. And, the search box remembers what you search for, so most times a single letter will do. Typing in a URL was just too much unnecessary work.
I have been intermittently playing with the new Chrome browser from Google, and it looks as if they have taken on board the experiences of people like my son. They have got down right down to one box: you enter a URL or a search into the single same box and it figures out what to do.

URL and search suggestions are integrated.
### Helicopter parents
URL: https://www.lorcandempsey.net/helicopter-parents/
Last updated: 2020-10-28T09:21:15.000Z
A recent [story](https://www.guardian.co.uk/education/mortarboard/2008/aug/20/parents.schools?ref=lorcandempsey.net) in *The Guardian* about helicopter parents points to a earlier [fuller discussion](https://www.guardian.co.uk/education/2008/jan/02/students.uk?ref=lorcandempsey.net) of the topic.
> The five types of helicopter parent, [ identified by Paul Redmond](https://www.guardian.co.uk/education/2008/jan/02/students.uk?ref=lorcandempsey.net) in the Guardian involve themselves not only in the application to university, but in every aspect onwards – open days, choice of course, halls of residence (buying a house for the helicoptered student and friends to rent is the top of the range, Cherie Blair option). \[[Helicopter parents take over every aspect of children’s future | Education | guardian.co.uk](https://www.guardian.co.uk/education/mortarboard/2008/aug/20/parents.schools?ref=lorcandempsey.net)\]
Redmond describes them thus:
> The term first appeared in the 1990s to describe a new category of 40-something baby boomers who have a close – in some cases intense – involvement in their child’s development. What defines them is a tendency to ‘hover’ over their offspring, booking their appointments, chaperoning them to events, and swooping down like a personal Swat team whenever the need arises. \[[Pushy parents involved in graduate careers | Education | Education Guardian](https://www.guardian.co.uk/education/2008/jan/02/students.uk?ref=lorcandempsey.net)\]
And notes ….
> In response, several universities have recently appointed ‘family liaison officers’ to help new parents ‘settle in’. Others have produced ‘parents’ packs’ to be distributed prior to the start of term. It seems that the day of the ‘helicopter parent’ has finally arrived. \[[Pushy parents involved in graduate careers | Education | Education Guardian](https://www.guardian.co.uk/education/2008/jan/02/students.uk?ref=lorcandempsey.net)\]
He talks about the influence of parents as consumers on this trend, and also talks about the cellphone as “surely the longest umbilical chord in history”.
I was reminded of some interesting comments by [Susan Gibbons](https://www.worldcat.org/identities/lccn-no2003-82300?ref=lorcandempsey.net) in her [book](https://www.worldcat.org/oclc/123119498?ref=lorcandempsey.net) on net gen students where she talks about the benefits of working with parents to create more awareness of library resources, as students will often turn to them for help. She also has quite a bit to say about the influence of the cellphone.
Redmond finishes by outlining five types of helicopter parent: the agent, the banker, the white knight, the bodyguard, the black hawk.
Related entries:
- [A family affair](https://blog.oclc.org/lorcand/archives/001000.html?ref=lorcandempsey.net)
- [The academic library and its users](https://blog.oclc.org/lorcand/archives/001418.html?ref=lorcandempsey.net)
### Above the Fold
URL: https://www.lorcandempsey.net/above-the-fold/
Last updated: 2020-10-28T09:21:17.000Z
I am pleased to point to *Above the fold*, a new awareness resource ….
> Above the Fold consists of a compendium of articles that relate to the work of the RLG Partnership and the information context in which we’re all operating — but readers might not see in the course of their regular awareness routines. Each citation will include a short annotation explaining why we think the article is of interest. And each note will be attributed to the staff member whose thoughts on the issue and its relevance can be tapped. \[[Above the Fold Launch \[OCLC\]](https://www.oclc.org/research/announcements/2008-09-03.htm?ref=lorcandempsey.net)\]
Check out the [first issue](https://visit.oclc.org/bin/archive%5Fviewer?id=6FB64ED51A04512E5A5D4AABB0D3BFC1&ref=lorcandempsey.net) and [sign up to receive it](https://www.oclc.org/email/subscribe%5Fabovethefold.htm?ref=lorcandempsey.net) regularly.
### Meet the candidates
URL: https://www.lorcandempsey.net/meet-the-candidates/
Last updated: 2020-10-28T09:21:18.000Z
Here is the Worldcat Identity for each of the Democrat and Republican candidates ….
[Joe Biden](https://worldcat.org/identities/lccn-n80-16125?ref=lorcandempsey.net)
[John McCain](https://worldcat.org/identities/lccn-nr91-3214?ref=lorcandempsey.net)
[Barack Obama](https://worldcat.org/identities/lccn-n94-112934?ref=lorcandempsey.net)
[Sarah Palin](https://worldcat.org/identities/lccn-no2007-7261?ref=lorcandempsey.net)
I will leave it to others to offer any commentary 😉
And here are some others to review ….
[George Bush](https://worldcat.org/identities/lccn-n80-15879?ref=lorcandempsey.net)
[George W Bush](https://worldcat.org/identities/lccn-no95-49848?ref=lorcandempsey.net)
[Bill Clinton](https://worldcat.org/identities/lccn-n82-29644?ref=lorcandempsey.net)
[Hillary Rodham Clinton](https://worldcat.org/identities/lccn-n93-10903?ref=lorcandempsey.net)
[Christopher J Dodd](https://worldcat.org/identities/lccn-n93-20496?ref=lorcandempsey.net)
[Al Gore](https://worldcat.org/identities/lccn-n86-130265?ref=lorcandempsey.net)
[Mike Huckabee](https://worldcat.org/identities/lccn-n97-73659?ref=lorcandempsey.net)
[Dennis J Kucinich](https://worldcat.org/identities/lccn-n79-4542?ref=lorcandempsey.net)
[Ralph Nader](https://worldcat.org/identities/lccn-n80-67178?ref=lorcandempsey.net)
[Mitt Romney](https://worldcat.org/identities/lccn-nr95-17857?ref=lorcandempsey.net)
Here is the subject cloud for John McCain:
[](https://worldcat.org/identities/lccn-nr91-3214?ref=lorcandempsey.net#linkfastheadings)
Here is the subject cloud for Barack Obama:
[](https://worldcat.org/identities/lccn-n94-112934?ref=lorcandempsey.net#linkfastheadings)
### Metadata and Heraclitus
URL: https://www.lorcandempsey.net/metadata-and-heraclitus/
Last updated: 2020-10-28T09:21:21.000Z
I was very struck a couple of years ago by a comment made by my colleague Eric Hellman. He talked about metadata in terms of rivers and lakes. In the library cataloging model we have had lakes – accumulating stores of data that do not change frequently over time and are fed by a few principal sources. In the ERM/Knowledge Base model we have rivers – stores of data that change frequently as products and services change and which are fed by many streams.
And as [Heraclitus](https://worldcat.org/identities/lccn-n78-95675?ref=lorcandempsey.net) is reported to have said: you cannot step into the same river twice. The data river for licensed materials is always in flux.
Now, I think that we will need to get used to cataloging data becoming more river-like also, more in flux, as that environment too becomes more dynamic. Here are some examples ….
- Work based approaches. We are getting used to thinking about clustering records as works. Works are dynamic: new manifestations or expressions may continue to appear and be linked in various ways to the work or expression to which they belong. If we move to represent the other FRBR entities in appropriate ways, we may link bibliographic data to data about subjects, names and so on.
- We have a similar relationship issue as materials are digitized and may live in different places. How do we represent the relationships between items and digitised versions of them.
- Rights data has become more important as we want to do more with books than buy them and make them available physically to a local audience. In particular, digitization has caused us to ask questions about what can be done with the book content. This has caused us to look at data in new ways and to think about what data is needed. (See the newly released Worldcat [Copyright Evidence Registry](https://www.worldcat.org/copyrightevidence?ref=lorcandempsey.net), for example.)
- We are becoming used to collecting data from users – tags, ratings, reviews, additional details, … – about materials in an ongoing way.
Update: I changed the order of the Heraclitus sentence this morning and then noticed that Roy had quoted the earlier version in a [nice amplification ](https://www.libraryjournal.com/blog/1090000309/post/1110032511.html?nid=3565&ref=lorcandempsey.net)of the river theme. I do sometimes wonder about the etiquette of changing stuff, but usually only note big changes.
### Article history and Enid Blyton
URL: https://www.lorcandempsey.net/article-history-and-enid-blyton/
Last updated: 2020-10-28T09:21:23.000Z
It is nice seeing the Guardian record article history on the web version of articles – when was it originally published, what are the details of print publication, revisions. This shows that they are serious about what they publish as part of an ongoing part of the historical record.
[](https://www.guardian.co.uk/books/2008/aug/20/costabookaward?ref=lorcandempsey.net)
Incidentally, the article I link to here is about a poll of best loved authors in the UK commissioned by Costa. [Enid Blyton](https://worldcat.org/identities/lccn-n2007-76814?ref=lorcandempsey.net) came top, a name not as well known in the US as in the UK.
> But this latest nomination is not for best children’s writer, it is for best-loved writer, full stop. Blyton’s gold medal position in this table, along with the high preponderance of children’s writers elsewhere on Costa’s list (Roald Dahl took second place and JK Rowling third, while JRR Tolkien and Beatrix Potter made the top 10), is evidence that it is the books we read, wholeheartedly, passionately, uncritically, in childhood to which we remain most firmly and irrevocably attached. The flaws we see in them as adults, the criticisms – and some pretty hefty ones, in the shape of accusations of sexism, racism and class snobbery have been flung Blyton’s way over the years – do not weaken those bonds. For hundreds of thousands of us, Blyton was the wedge that cracked open the pleasure-filled world of reading and allowed us in. Our rational adult sides reject and mock Kirrin Island and all the adventures played out there; our inner children remember it rightly, and gratefully, as the promontory from which we caught our first glimpse of the promised land. \[[Lucy Mangan celebrates the literary talents of Enid Blyton | Books | The Guardian](https://www.guardian.co.uk/books/2008/aug/20/costabookaward?ref=lorcandempsey.net)\]
Here is her identities page ….
[ ](https://worldcat.org/identities/lccn-n2007-76814?ref=lorcandempsey.net)
Finally, and in keeping with the ‘record’ theme, a sense of her continuing popularity can be gained from the note about a corrected mistake that concludes the article.
> This article was amended on Friday August 22 2008\. About 8m copies of Enid Blyton books are sold worldwide every year, rather than 800m. This has been corrected. \[[Lucy Mangan celebrates the literary talents of Enid Blyton | Books | The Guardian](https://www.guardian.co.uk/books/2008/aug/20/costabookaward?ref=lorcandempsey.net)\]
### Amplifying the meaning of the amplified conference
URL: https://www.lorcandempsey.net/amplifying-the-meaning-of-the-amplified-conference/
Last updated: 2020-10-28T09:21:25.000Z
I have found the phrase [‘amplified conference’](https://www.google.com/search?q=%22amplified+conference%22+lorcan&ie=utf-8&oe=utf-8&aq=t&rls=FlockInc.:en-US:official&client=firefox&ref=lorcandempsey.net) useful as a way of talking about the surrounding communications techniques which accompany many recent conferences. These allow conference content to be communicated more widely, conversations about the conference to take place, and even the conference to reflexively adapt based on network input.
Brian Kelly has a nice post where he discusses what this means in practice. He offers a definition …
> The term amplified conference describes a conference or similar event in which the talks and discussions at the conference are ‘amplified’ through use of networked technologies in order to extend the reach of the conference deliberations.
> The term is not a prescriptive one, but rather describes a pattern of behaviors which initially took place at IT and Web-oriented conferences once WiFi networks started to become available at conference venues and delegates started to bring with them networked devices such as laptops and, more recently, PDAs and mobile phones. \[[Defining An “Amplified Conference” « UK Web Focus](https://ukwebfocus.wordpress.com/2008/08/28/defining-an-amplified-conference/?ref=lorcandempsey.net)\]
…. and he then goes on to describe various ways in which this is achieved.
Related entries:
- [Amplified conference](https://www.google.com/search?q=%22amplified+conference%22+lorcan&ie=utf-8&oe=utf-8&aq=t&rls=FlockInc.:en-US:official&client=firefox&ref=lorcandempsey.net)
### QOTD: responsibly open and openly responsible
URL: https://www.lorcandempsey.net/qotd-responsibly-open-and-openly-responsible/
Last updated: 2020-10-28T09:21:26.000Z
Marin Weller of the Open University has an interesting paragraph in a blog post about his new role as director of the [SocialLearn](https://www.open.ac.uk/blogs/socialearn/?ref=lorcandempsey.net) project. He talks about a desire to be open in communicating the progress of the initiative and soliciting input …. which prompts this thought:
> … it’s easy to be a blogger when you don’t have much responsibility, but it strikes me that the as your official responsibility increases so the the amount of stuff you can happily blog about decreases proportionally. So, for the sake of the project I may find that I can say less and less about it. But I hope not, and my default position is to be open as we go along. \[[The Ed Techie: SocialLearn Director](https://nogoodreason.typepad.co.uk/no%5Fgood%5Freason/2008/08/sociallearn-director.html?ref=lorcandempsey.net)\]
### Who's on Twitter
URL: https://www.lorcandempsey.net/whos-on-twitter/
Last updated: 2020-10-28T09:21:28.000Z
Interesting story on TIme.com from the Hitwise folks about Twitter demographics.
> I figured that the service would appeal exclusively to youngsters with nothing better to do. The user data, however, tell me I’m wrong, and reveal a very specific user profile: for example, males make up 63% of Twitterers, specifically males from California, whose residents account for more than 57% of Twitter’s visitors. More interestingly, the age demographics of Twitterers show a dramatic shift. When the site became popular in early 2007, the majority of its visitors were 18-to-24-year-olds. Today the site’s largest age demographic is 35-to-44-year-olds, who make up 25.9% of its users. \[[Even Gen X is aTwitter – TIME](https://www.time.com/time/business/article/0,8599,1834131,00.html?ref=lorcandempsey.net)\]
### Metrics and visibility
URL: https://www.lorcandempsey.net/metrics-and-visibility/
Last updated: 2020-10-28T09:21:29.000Z
I was interested to come across the Service Level Definitions page at the Library at the London School of Economics.
> Additionally, we have a number of Service Targets which we monitor on a monthly or termly basis. You can see our general service standards and the full results for our service targets for the academic year to date [here](https://www.lse.ac.uk/library/SLDs/OurServiceStandards.htm?ref=lorcandempsey.net). We have put a few interesting facts for last month opposite. \[[ Service Level Definitions](https://www.lse.ac.uk/library/SLDs/SLDsHome.htm?ref=lorcandempsey.net)\]
What is interesting is that they publish their performance against the targets. I do not have a sense of how common this is. Here are their targets for availability of the catalogue and library IT equipment.
[](https://www.lse.ac.uk/library/SLDs/OurServiceStandards.htm?ref=lorcandempsey.net#Availability%20of%20the%20Library%20catalogue%20and%20IT%20equipment)
When I do presentations, I sometimes get asked about the library brand on the web. It is well-known that users do not always associate the range of licensed materials they have access to with the library directly. And the more integrated library resources appear with other environments, paradoxically, the less visible the library itself may appear.
I usually respond that we are seeing the library itself become more visible through active engagement with research, teaching and learning activities, marketing, assessment, and programs. This type of measurement also becomes more important.
### Library analytics
URL: https://www.lorcandempsey.net/library-analytics/
Last updated: 2020-10-28T09:21:31.000Z
The indefatigable Tony Hirst has an interesting post about using Google Analytics to analyse library website traffic. He looks at the [Open University Library](https://library.open.ac.uk/?ref=lorcandempsey.net) website. This is in preparation for a fuller paper he is preparing with Hassan Sheikh of the Library for [Internet Librarian International 2008](https://www.internet-librarian.com/index.php?ref=lorcandempsey.net). Something to look forward to …. Here is a taste of the entry:
> A quick glimpse suggests the search links need dumping, and more real estate should be given over to the “Journals” and “Databases” links that are currently in the left hand sidebar, and which get 20% and 19% of the click-thrus respectively. Despite the large areas of the screen given over to the image-based navigation, they aren’t pulling much traffic. (That said, if we segment the users it might well be the case that the images in the middle of the page disproportionately attract clicks from certain sorts of user? I don’t think it’s possible to segment this out in the general report, however? For that, I guess we need to define some separate reports that are pre-segmented according to referrer?)
> Just chasing the traffic a little more, I wonder if there are a few, popular databases or whether traffic is distributed over all of them equally? The Library databases page is pretty horrible – a long alphabetical list of databases – so can the analytics suggests ways of helping people find the pages they want? \[[Library Analytics (Part 1) « OUseful.Info, the blog…](https://ouseful.wordpress.com/2008/08/20/library-analytics-part-1/?ref=lorcandempsey.net)\]
### Data at the network level
URL: https://www.lorcandempsey.net/data-at-the-network-level/
Last updated: 2020-10-28T09:21:34.000Z
The impact of networking on organizational evolution is interesting: how does networking impact how libraries coordinate their resources to get their work done effectively? In the ‘network age’ there have been several major shifts in how libraries coordinate resources (and by *resources*, I am thinking about their budgets, staff, and systems as well as collections). Shared cataloging and resource sharing mark one important shift, where libraries externalized some activities to a shared policy and service infrastructure. The externalization of A&I services, and then journals, to aggregators and others marks another major shift. These types of resource coordination or sourcing decisions – go local, collaboratively source through some cooperative arrangement, source with an external supplier – are becoming more frequent across a greater range of services. Think of general systems infrastructure, repository infrastructure, population of knowledge bases, virtual reference, and off-site storage for example.
My colleague Janifer Gatenby has a reflective article in the new issue of [Ariadne](https://www.ariadne.ac.uk/?ref=lorcandempsey.net) which looks at the data that is needed to manage library operations. She discusses how this might be coordinated differently over the medium term future. She discusses the workflow across three core collection categories: print/bought, licensed/electronic, and digital/digitized collections. Currently, these are largely managed separately and locally. As we move to more collective approaches, and as we seek to manage collections in more integrated ways, it is appropriate to consider whether data and workflows might be coordinated differently across groups of libraries.
> As library collections are increasingly shared, there may be significant advantages (in terms of both cost and efficiency) in moving more acquisitions and licensing data and processes to the network level where they can be shared among the ILS, ERM and repositories and with other libraries. Moreover, libraries are finding their ILS acquisitions modules inadequate for managing the acquisition of the newer parts of whole collections. There is already a clear need for the acquisitions of the three parts of the collection to be managed as a whole; moving data to the network, thereby enabling shared network services, is one solution. \[[Main Articles: ‘The Networked Library Service Layer: Sharing Data for More Effective Management and Co-operation’, Ariadne Issue 56](https://www.ariadne.ac.uk/issue56/gatenby/?ref=lorcandempsey.net)\]
Janifer steps through some of the issues in suggestive ways focusing on one major area: “An example is explored, namely the benefits of moving data from different local systems to the network level to manage acquisition of the total collection as a whole and in combination with consortia members.”
An important point to emerge is that different categories of data may live at different levels:
> There is a clear need to define data at multiple levels:
>
> - globally sharable data (e.g. bibliographic metadata, holdings, issue level holdings, suppliers, statistics, reference query-and-answer pairs)
> - Data that can be shared within one or more co-operatives to which the library belongs (e.g. selection / rejection decisions, weeding reasons)
> - Local data that are not shared (e.g. budgets, invoice details, some user information)
>
> \[[Main Articles: ‘The Networked Library Service Layer: Sharing Data for More Effective Management and Co-operation’, Ariadne Issue 56](https://www.ariadne.ac.uk/issue56/gatenby/?ref=lorcandempsey.net)\]
Update: check out Jim’s [post](https://hangingtogether.org/?p=499&ref=lorcandempsey.net) on HangingTogether for some context about Janifer’s article.
### Repository of Repository-related blogs
URL: https://www.lorcandempsey.net/repository-of-repository-related-blogs/
Last updated: 2020-10-28T09:21:37.000Z
I notice that this blog is included in a useful [list of repository-related blogs](https://rsp.ac.uk/blogs?ref=lorcandempsey.net) from the Repositories Support Group.
> The JISC funded Repositories Support Project has today launched a new service – The RSP Blog Directory ([https://rsp.ac.uk/blogs/](https://rsp.ac.uk/blogs/?ref=lorcandempsey.net)). It provides a list of recommended and informative blogs regarding the repository scene from around the globe. Listed blogs include personal creations from those with firsthand experience of repository management, and / or technical development of repository software; blogs for specific repositories projects and software developers; as well as blogs for groups and societies with an interest in the open access movement and digital curation. \[[RSP News – RSP Directory of repository related blogs](https://rsp.ac.uk/news/news2008-08-19-blog.php?ref=lorcandempsey.net)\]
Via [Andy Powell.](https://efoundations.typepad.com/efoundations/2008/08/directory-of-re.html?ref=lorcandempsey.net)
### The collective collection and Ranganathan
URL: https://www.lorcandempsey.net/the-collective-collection-and-ranganathan/
Last updated: 2022-11-05T20:34:39.000Z
Readers of this blog – or of the RLG Partnership [work agenda](https://www.oclc.org/programs/ourwork/collectivecoll/default.htm?ref=lorcandempsey.net) – will be familiar with the phrase *collective collection*. We use it to refer to the intensification of systemwide interest in the management of collections, whether the system is at consortial, state, national or some other level. Consortial discovery to delivery systems, mass digitization initiatives, preservation of print and digital, off-site storage: many current discussions involve this systemwide perspective.
In simple terms, I think we can see a natural progression from shared discovery, to better resource sharing logistics, to collective collection development and management. The last has always been an interest, variably realized, but current pressures and capacities bring it back into focus in different ways. This progression is characterized by deeper resource sharing, greater mutual dependency and more extensive shared infrastructure.
Now, over the years, there have been some suggestions about updating Ranganathan’s laws \[[*Ranganathan’s 5 laws of library science*, Wikipedia](https://en.wikipedia.org/wiki/Five%5Flaws%5Fof%5Flibrary%5Fscience?ref=lorcandempsey.net)\]. These have not been very convincing. Once some adjustment is made for gender and format, I think that the laws actually continue to capture very well some fundamental challenges about what we do. And one of the interesting things to me is that the laws resonate even more strongly as we do more things at a collective level. In fact, conformance to the laws in many cases suggests moving in this direction. And this is in line with his fifth law: *the library is a growing organism*. In this case, we need to think about what effective service means in a network environment where service models and user behaviors and expectations continue to co-evolve.
Here is one example, among several I could advance: when writing about the long tail and libraries a while ago, Ranganathan naturally came to mind:
> Discussions of the long tail that I have seen or heard in the library community strike me as somewhat partial. Much of that discussion is about how libraries contain deep and rich collections, and about how their system-wide aggregation represents a very long tail of scholarly and cultural materials (a system may be at the level of a consortium, or a state, or a country). However, I am not sure that we have absorbed the real relevance of the long tail argument, which is about how well supply and demand are matched in a network environment. It is not enough for materials to be present within the system: they have to be readily accessible (‘every reader his or her book’, in Ranganathan’s terms), potentially interested readers have to be aware of them (‘every book its reader’), and the system for matching supply and demand has to be efficient (‘save the time of the user’) \[[Libraries and the Long Tail: Some Thoughts about Libraries in a Network Age](https://www.dlib.org/dlib/april06/dempsey/04dempsey.html?ref=lorcandempsey.net)\]
Incidentally, I left the above paragraph as a comment on Bob Molyneux’s [nice post](https://open-ils.org/blog/?p=118&ref=lorcandempsey.net) of a while ago about the user benefits of the collective Pines approach, as he too returned to Ranganathan in his discussion of how Pines makes the participants’ ‘collective collection’ available in one ‘big resource rich library’.
Related entries:
- [Systemwide activities and the Long Tail](https://blog.oclc.org/lorcand/archives/000955.html?ref=lorcandempsey.net)
- [Logistics and synchronization: making data work harder](https://blog.oclc.org/lorcand/archives/001494.html?ref=lorcandempsey.net)
- [Library logistics](https://www.google.com/search?hl=en&client=firefox&rls=FlockInc.%3Aen-US%3Aofficial&hs=Wlm&q=%22library+logistics%22+lorcan&btnG=Search&ref=lorcandempsey.net)
- [Collective collection](https://www.google.com/search?hl=en&client=firefox&rls=FlockInc.%3Aen-US%3Aofficial&hs=Z6R&q=%22collective+collection%22+lorcan&btnG=Search&ref=lorcandempsey.net)
### RLG Partnership
URL: https://www.lorcandempsey.net/rlg-partnership/
Last updated: 2020-10-28T09:21:41.000Z
We have just released a [highlights report](https://www.oclc.org/research/announcements/2008-08-12.htm?ref=lorcandempsey.net) \[[pdf](https://www.oclc.org/programs/about/updates/2007-08annual.pdf?ref=lorcandempsey.net)\] about our work over the last year in support of the RLG Partnership. It is a very nice record of achievement and has a range of useful pointers to documents and intiatives.
### The future of media?
URL: https://www.lorcandempsey.net/the-future-of-media/
Last updated: 2020-10-28T09:21:42.000Z
As we have been traveling I haven’t been watching a lot of TV, I thought I would go and have a look at a few videos of discussed Olympic events.
The BBC is usually my first port of call for things like this, but of course, as [noted](https://blog.oclc.org/lorcand/archives/001670.html?ref=lorcandempsey.net) previously, they will not allow their video clips to be viewed outside the UK.
> We use technology to prevent people from outside the UK from accessing content that we need to limit to the UK for rights reasons. \[[BBC NEWS | Help | Your guide to the BBC Embedded Media Player](https://news.bbc.co.uk/2/hi/help/7277283.stm?ref=lorcandempsey.net#in%5Fuk)\]
So, over to NBC. Lots of materials here, and a wide range of videos. However, to watch a video you need first to watch an advert. After a while of seeing the same ad for AT&T, Nissan or Budweiser it gets a bit tedious.
Free is rarely quite free.
Incidentally, I was interested that I had to download Silverlight to view the NBC material.
### Walter Benjamin, Dairy Queen and the card catalog
URL: https://www.lorcandempsey.net/post_9/
Last updated: 2026-08-29T15:56:49.000Z
## Larry McMurtry and the card catalog
I bought *[Walter Benjamin at the Dairy Queen](https://www.worldcat.org/oclc/40723811?ref=lorcandempsey.net)* by Larry McMurtry while on vacation in Dublin last week. I had read a review of his recent *[Books: a memoir](https://www.worldcat.org/oclc/213408552?ref=lorcandempsey.net)* on the plane over and this prompted me to pick it up when I saw it, appropriately enough maybe, given its discussion of book selling and finding, on a bargain table in Hodges Figgis. Here is a descriptive paragraph from the New York Times review:
> Walter Benjamin at the Dairy Queen,” McMurtry’s tentative, poignant new book, subtitled ”Reflections at Sixty and Beyond,” begins in the summer of 1980 with the author reading Benjamin’s 1936 essay ”The Storyteller” in the Dairy Queen in Archer City, Tex. — the town long since made famous as Thalia to readers of McMurtry’s novels. The Dairy Queens of West Texas, he declares, ”by providing a comfortable setting that made possible hundreds of small, informal local forums, revived, for a time, the potential for storytelling of the sort Walter Benjamin favored.” McMurtry then reflects, glancingly, on ”the resilience of a story” in an age when ”we are all so oversupplied with information” that human memory seems almost unnecessary. // [Even Cowboys Get the Blues](https://www.nytimes.com/books/99/11/21/reviews/991121.21mallont.html?ref=lorcandempsey.net)
I was amused by how he tested Benjamin’s thoughts against his own experience in early pages, and the suggestive description of the different fictional strategies available in ‘old Europe’ and the American West that flowed from this.
The retrospective nature of the work means that there is much focus on things lost. And in a book much about books and reading, it is not surprising to see the card catalog figure as one of these lost things. Indeed, we are now used to seeing the disappearance of the card catalog stand service for a wider set of regretted change. Here, the context is a discussion of how computers ‘take the work out of work’, quoting an observation of Valery about the modern abbreviation of work. The case is a comparison of writing by hand, using the typewriter, and using a computer. He talks about the tactile nature of typing, the connection between touch and writing, the ‘imperfections in the ribbon or the inking, just enough so that the process of writing demands a little attention and some manual application’.
> This may seem – and be – an overtly romantic view of typing and typewriters; by the same token Nicholson Baker’s paean to the library card catalogues (now gone) was considered romantic by most librarians. // p.35
## Adorno and the card catalog
Reading this I was reminded of some observations about the ‘withering of experience’, which is what McMurtry seems to be getting at here, by Benjamin’s friend Adorno which I have linked to the disappearance of the card catalog in the past.
> This experience has become a private touchstone when I see discussions of how technology has changed things, or when people bemoan the loss of valuable practices as our digital environment spreads. Take this quote, for example, from the melancholy Adorno:
>
>> Technology … expels from movements all hesitation, deliberation, civility … Not least to blame for the withering of experience is the fact that things, under the law of pure functionality, assume a form that limits contact with them to mere operation, and tolerates no surplus either in freedom of conduct, or in autonomy of things, which would survive as the core of experience, because it is not consumed by the moment of action. // Theodore Wiesengrund Adorno. Minima Moralia. Verso: London, 1978.
>
> Now, the replacement of the Browne Issue System represented the decline of a minor craft, the replacement of a modestly skilled but tedious activity. It changed a pattern of experience, saved time, restructured buildings (not necessarily for the better). But this is a case where access to ‘pure functionality’ is a benefit which outweighs the ‘withering of experience’ it brought about. // [Lorcan Dempsey’s weblog: The Browne Issue System and the reordering of experience](https://www.lorcandempsey.net/orweblog/the-browne-issue-system-and-the-reordering-of-experience/)
Elsewhere, I take up the same theme:
> The catalogue has a special place. Much of the collection is hidden: it exists as potential. Discovery in the catalogue makes it actual. The catalogue acts as a surrogate for the collection, and, for the dedicated library user, searching the catalogue is continuous with the wider accumulation of knowledge. It suggests the size of the collection, the mass that still needs to be prospected. The traces of its creators can be seen in the styles, over time, of the individual entries. Griliches includes a photograph of a card catalogue from Boston Public Library and describes it in personal terms “This solid, well-used wooden veteran has a personal attraction and a kind of lasting beauty that a computer can never have. I wanted to make its portrait before it disappears.” A portrait comes from a dialogue with a life: the catalogue has a life that is bound up with the lives of previous users and those that have created it. She includes a caption from Barbara Tuchman: “For me the card catalogue has been a companion all my working life. To leave it is like leaving the house one was brought up in.” And so, it is not difficult to understand how for many people, automation of the catalogue represents, in a real way, a “withering of experience” as described by Adorno. // [Library places and digital information spaces: reflections on emerging network services](https://homes.ukoln.ac.uk/~lisld/publications/alex.html?ref=lorcandempsey.net)
As I go on to say, this is especially so as it is recognized as a prelude to further change, which not only signals a changing relationship to particular physical places, but the disappearance of the craft, the tacit knowledge, which is a part of their use. Seen this way, developments are part of a larger reordering of experience, and assume symptomatic importance.
**Picture:** I took the feature image of a Dairy Queen in Worthington, Ohio.
**Note:** Cosmetic amendments on 2 April 2021, including fixing spacing, and adding feature image and headings.
### Worldcat API
URL: https://www.lorcandempsey.net/worldcat-api/
Last updated: 2020-10-28T09:21:46.000Z
The Worldcat API was released beyond the original trial group while I was away.
> The WorldCat Search API provides access to WorldCat bibliographic records and holdings using the FRBR concepts to pull together various editions of the same work. The API provides access to the WorldCat databases from clients that can send RESTful URI queries with either the OpenSearch or SRU protocols and can accept RSS, Atom, MARC XML or Dublin Core \[[WorldCat Search API \[OCLC – Web and Data Services\]](https://www.oclc.org/worldcatapi/default.htm?ref=lorcandempsey.net)\]
Technical details are [here](https://worldcat.org/devnet/index.php/SearchAPIDetails?ref=lorcandempsey.net); eligible users described [here](https://worldcat.org/devnet/index.php/SearchAPIWhoCanUse?ref=lorcandempsey.net).
### Holiday
URL: https://www.lorcandempsey.net/holiday/
Last updated: 2020-10-28T09:21:48.000Z
I am on holiday in Ireland so no posting in the last few days, or for the next ….
### Texting shelf information
URL: https://www.lorcandempsey.net/texting-shelf-information/
Last updated: 2020-10-28T09:21:51.000Z
I have heard of people photographing catalog results with their cell phones and heading off to the shelves. And now I have just come across the [Tripod library catalog](https://tripod.brynmawr.edu/search~/?ref=lorcandempsey.net).

You can text yourself the bibliographic details – see the icon on the entry above. Here is what happens when you click on it ….

They advertize it as more convenient than writing down the details with pencil and paper.
### Stuck in the middle ....
URL: https://www.lorcandempsey.net/stuck-in-the-middle/
Last updated: 2020-10-28T09:21:55.000Z
Much of our current model of network information and communication behavior is in the middle ground, it is based on the personal computer (desk- or lap-top) as a consumption target and the organizational website as the delivery target. In other words, the library website is the front door to network library services consumed on the user’s computer.
However, this model is increasingly at odds with their user’s diffuse network experience in an environment of mobile communications, multiple devices, and various integration environments (social networking, RSS aggregator, iGoogle, etc) on the one hand, and cloud based services which concentrate data, user experience and communications and computational capacity on the other. And we do indeed see libraries moving in directions which better play in this context.
Think of two challenges around the library website as the focus in this environment.
One, as I have discussed here before, it is often difficult for libraries to provide a well-seamed, smooth experience at that website. This is for well-known reasons. They are providing a thin layer over two sets of heterogeneous resources. One is the set of legacy and emerging systems, developed independently rather than as part of an overall library experience, with different fulfillment options, different metadata models, and so on. Typically, a library will manage an ILS, a set of services around licensed materials (knowledge base, resolver, metasearch, …), a repository or two, and so on. Another is that the library cannot chose not to provide certain resources because they pose some integration challenges. They need to provide what is required to support the community they serve. So here they have to manage a set of legacy database boundaries that map more to historically evolved publisher configurations and business decisions than to user needs or behaviors. Additionally resources may have different technical or business terms attached to their use. This fragmentation – of systems and of content – is certainly an ongoing challenge.
The second is more subtle and maybe more profound. Remember what I claimed: our model of provision is based on the desktop as a consumption target and the organizational website as a delivery target.
However, it appears that the desktop and the website may be progressively less the sole focus of attention, and a model which focuses almost exclusively on them looks increasingly partial in a world of diffuse network presence and cloud-based resources. This is what I mean by being ‘stuck in the middle’, while more – not by any means all- of the action moves elsewhere.
So, what do I mean by a diffuse network presence? We increasingly have a ‘mesh’ of entry points: PC and phone, yes, but also DVRs, cameras, navigation systems, consoles and so on. This is not a simple distinction between mobile and fixed: think of the iPhone or Asus Eee which close that gap somewhat. And we increasingly have a range of ways in which services are diffused through the network into different user environments: widgets of various sorts, RSS, toolbars, and so on. In other words, in an age of increasingly pervasive connectivity we have a variety of grades of experience available to us in how we connect up. Users are constructing their own digital workflows and identities out of a variety of network services.
A natural complement of this diffusion is a growing reliance on cloud-based services, which can be available to all the ways in which I engage with the network. If my network engagement is increasingly spread across different devices or applications, then I need to have access to my stuff from different places. We increasingly use a range of shared network level network services, for search, for social networking, for managing content and information, for communication, for processing, for bookmarking, and so on. Think of Google Docs, or Flickr, or Facebook. Some of these concentrate data, communications and computational capacity. Others may provide ‘portalization’ services as these are separated from the device or desktop (think Bloglines and Google Reader vs locally installed aggregator).
What this means is that resources are increasingly shared, synchronized and syndicated through a diffuse network of devices and services, and often between those and several concentrated cloud-based services. This is not to suggest that people don’t use a desktop, or, in some cases use it as a principal place to interact with their stuff and with stuff on the network. But this is alongside a growing range of activity which has been untethered from that local desktop. The local desktop, and all that it implies (web browser, local storage, reasonable screen real estate, sufficient attention to be able to manage complex chained transactions or multiple choices) cannot be taken for granted as the primary consumption target.
Now, these two issues are related of course. The library is managing monolithic fragments: the catalog, metasearch, repositories, a-z lists, etc. It is difficult to integrate these in the library websites, and it is difficult to push resources from them into diffuse environments of use and into cloud services. As I have suggested before, we spend too much time **getting** our systems to work, and not enough **putting** them to work. Additionally, the interface between the local presence and the consortial and other arrangements that are increasingly important to meet local needs may be more or less well-seamed.
Of course, a major focus of current efforts is to try to transcend the limitations of this environment. Libraries are working on this as are the organizations which supply them (think, for example, of Ex Libris’s [discussion](https://www.meanboyfriend.com/overdue%5Fideas/2008/05/bx-and-sfx-for.html?ref=lorcandempsey.net) about integrated discovery and uniform resource management, Evergreen’s discussion about the ‘[big resource rich library](https://open-ils.org/blog/?p=118&ref=lorcandempsey.net)‘, shared arrangement like [Deff](https://www.deff.dk/default.aspx?lang=english&ref=lorcandempsey.net) in Denmark or the [Scholars Portal](https://www.scholarsportal.info/?ref=lorcandempsey.net) in Ontario, or OCLC’s worldcat local and worldcat.org).
We can see two important directions, one towards concentration and one towards diffusion.
First concentration, which we see at at least three levels. At the institutional level, there is a strong push to overcoming fragmentation by moving towards new institutional discovery layers (Primo, Encore, Worldcat Local). At the group level we see the emergence of more state or national systems which pull together resources in user-facing services. These are attractive because they present more resources to the user. And at the global level, we see library resources being represented – through linking or syndication strategies – in search engines, Flickr, Google Scholar, Worldcat and other network level resources.
The second is atomization of content and services so that they can be better integrated into diffuse networking device and applications environments. Here think of RSS/AtomPub, mobile interfaces, APIs, alerting services, portlets and widgetization, persistent links to library services and content, etc. Issues here are technical and licensing. Users increasingly value convenience and relevance, and packaging materials in ways that make most sense for them is not always straightforward.
Of course, the second of these can happen at any of the local, group or global levels, and one of the more interesting organizational questions for libraries in the near future is how much resource to invest at each of these levels.
So, synchronization and syndication become much more important. The institutional website is still important, but a service strategy which focuses on that alone will be increasingly partial.
Related entries to follow …
### Selecting snippets
URL: https://www.lorcandempsey.net/selecting-snippets/
Last updated: 2020-10-28T09:21:59.000Z
Her [Worldcat Identities](https://www.worldcat.org/identities/lccn-n80-109150?ref=lorcandempsey.net) page currently appears on the first page of results in a [search for Eavan Boland](https://www.google.com/search?q=eavan+boland&ref=lorcandempsey.net)

[Thom Hickey](https://worldcat.org/identities/lccn-n82-54463?ref=lorcandempsey.net) mentioned steps that his group is taking to make Identities more crawler-friendly [in a recent post](https://outgoing.typepad.com/outgoing/2008/08/html-rendering.html?ref=lorcandempsey.net). Looking through various results with him the other day, the Boland snippet caught our eye. If you look at the Boland Identities page you will see that the snippet comes from the last listed book by her ([here are the books](https://www.worldcat.org/identities/lccn-n80-109150?ref=lorcandempsey.net#linkworksby), scroll down).
[ ](https://www.worldcat.org/identities/lccn-n80-109150?ref=lorcandempsey.net#linkworksby)
I wonder what Google did here? This is a good snippet to post, maybe even the best available on that page? How did Google select it? I assume that they have algorithms which look for the best candidate sentence or two? it is not just the first match. Were they just luck here, or are they usually this good? I will have to look out for this more in the future …..
### Google was here
URL: https://www.lorcandempsey.net/google-was-here/
Last updated: 2020-10-28T09:22:00.000Z
We live a hundred yards or so off High Street, the historic North-South thoroughfare in Columbus. In fact, the picture below is taken from High Street and the exit is the entrance to our street. I just noticed this on Google Maps; I don’t know how long they have had it up. They are getting closer and closer!
They must have had [one of these](https://memex.naughtons.org/archives/2008/07/16/5342?ref=lorcandempsey.net) drive past – I am sorry I missed it!

### From GLAM to Columbus
URL: https://www.lorcandempsey.net/from-glam-to-columbus/
Last updated: 2020-10-28T09:22:03.000Z
I use GLAM as a category on this blog, standing duty for Galleries, Libraries, Archives and Museums. We do not have a great collective name for these institutions. Sometimes we may use memory institutions or organizations, but it can sound a little contrived.
I was interested to see Tara Brabazon writing about ‘GLAMS’ in the Times Higher. She is writing about the role of these organizations, and a particular museum in particular, in the rebranding of Wellington, New Zealand, as a cultural centre.
> From this basis, a tourist and business initiative titled Absolutely Positively Wellington was able to build a tourist portfolio not only to rejuvenate but to brand the city. This was a GLAM strategy, working with the social, intellectual and economic capacity of galleries, libraries, archives and museums. \[[Times Higher Education – Education news, resources and university jobs for the academic world – Kiwi culture goes GLAM](https://www.timeshighereducation.co.uk/story.asp?sectioncode=26&storycode=403045&c=2&ref=lorcandempsey.net)\]
And she goes on to talk about broader relations between these several types of institution, drawing on collaborative developments in Australia and New Zealand.
> There are many historical relationships between museums and archives, galleries and museums, and libraries and archives. To integrate all four institutions of memory is a rarer objective. In 2003, the Australian Society of Archives used GLAM as the hook for its annual conference, seeking strategies across the cultural sector to “glamorise culture” and assist diverse curatorial traditions while building relationships between school and university collections, along with business, labour and corporate archives. Once GLAM as a term was publicised online through this conference the usage increased, moving east to New Zealand. The internet and the challenges of digitisation were (and are) the catalyst for unifying agendas about storage, preservation, accessibility and platform migration. \[[Times Higher Education – Education news, resources and university jobs for the academic world – Kiwi culture goes GLAM](https://www.timeshighereducation.co.uk/story.asp?sectioncode=26&storycode=403045&c=2&ref=lorcandempsey.net)\]
She refers to the well-known work of [Richard Florida](https://www.worldcat.org/identities/lccn-n90-648392?ref=lorcandempsey.net) on the role of the creative industries in a city or region’s prosperity and notes: “The role of GLAMs in such a narrative is underplayed, lacking policy integration with the more stylish creative industries of music, fashion and film.”
Lynne Brindley, the CEO of the British Library has recently been writing and talking about the contribution of the BL and other public ‘memory institutions’ to the UK’s creative industries, presumably trying to close that policy gap.
> The Work Foundation’s 2007 report Staying Ahead notes that most members of the UK’s creative and cultural industries have in some way been helped to develop their franchise through public support and investment. This so-called ‘propitious public infrastructure’ has been accumulated over a long period and includes a rich institutional heritage of libraries, museums and galleries, the BBC, our art and design schools, our conservatoires, and theatre, opera and dance companies across the country.
> The relationship between public culture and commercialised creativity is often indirect and unacknowledged. Best-selling author Stef Penney conducted research for her historical thriller The Tenderness of Wolves entirely in the British Library in London – and yet, had she not won the Costa Prize last year, we may never have learnt of the extent to which she drew on its collections. \[[It’s our public institutions that drive Britain’s creative surge | UK news | The Observer](https://www.guardian.co.uk/media/2008/feb/10/9?gusrc=rss&feed=media&ref=lorcandempsey.net)\]
Incidentally, I have just finished Richard Florida’s latest book: *[Who’s your city?: how the creative economy is making where to live the most important decision of your life](https://www.worldcat.org/oclc/191258391?ref=lorcandempsey.net)*. I was interested in his remarks about Columbus, Ohio (where he lived briefly). He includes the Short North among what he calls ‘hipster havens’, areas with a mix of ‘city grit and posh’, and German Village is included in his list of ‘designer digs’, upscale urban neighbourhoods. And among larger regions, Columbus is in number four, between San Jose and Austin, in his list of ‘best buy’ places to live for mid-career professionals, and third, between Hartford and Austin, in his list of best places overall for gay and lesbian mid-career professionals.
### Metadata crosswalk web service
URL: https://www.lorcandempsey.net/metadata-crosswalk-web-service/
Last updated: 2020-10-28T09:22:05.000Z
Metadata crosswalks are becoming more important as more data flows from application to application. We have been working on this issue and the approach was described a while ago in the Code4Lib Journal.
> This paper discusses an approach and set of tools for translating bibliographic metadata from one format to another. A computational model is proposed to formalize the notion of a ‘crosswalk’. The translation process separates semantics from syntax, and specifies a crosswalk as machine executable translation files which are focused on assertions of element equivalence and are closely associated with the underlying intellectual analysis of metadata translation. A data model developed by the authors called Morfrom serves as an internal generic metadata format. Translation logic is written in an XML scripting language designed by the authors called the Semantic Equivalence Expression Language (Seel). These techniques have been built into an OCLC software toolkit to manage large and diverse collections of metadata records, called the Crosswalk Web Service. \[[The Code4Lib Journal – Toward element-level interoperability in bibliographic metadata](https://journal.code4lib.org/articles/54?ref=lorcandempsey.net)\]
This work is used internally by OCLC as we manage more streams of metadata. A [demonstration web service](https://www.oclc.org/research/researchworks/xwalk/?ref=lorcandempsey.net) has also now been made publicly available. There is not much to look at unless you are a machine 😉
### Buying books ... sometimes
URL: https://www.lorcandempsey.net/buying-books-sometimes/
Last updated: 2020-10-28T09:22:07.000Z
When I was in Edinburgh recently I spent some time trying to find [Dai Smith](https://worldcat.org/identities/lccn-n84-236441?ref=lorcandempsey.net)‘s recently published biography of [Raymond Williams](https://worldcat.org/identities/lccn-n80-36657?ref=lorcandempsey.net) (which was published in the UK, but not yet in the US). It was not to be had in Blackwell’s or Waterstones and I was surprised not to find it in [Word Power Books](https://www.word-power.co.uk/?ref=lorcandempsey.net). The person at one of the information desks in the chains noted that they had one copy on order for someone, and made a remark about it being published by a ‘small Welsh publisher’ as if in mitigation.
Although I order books from time to time from Amazon I still find that I prefer to buy books I have been waiting for in a shop. Even though it often means waiting longer for them, I have a fond – but mistaken – feeling that I will get them quicker this way. If it is not available locally, I think I can pick it up on my next trip. Having it come through the mail is just not the same as the pleasure of discovering it on the shelf 😉
I was interested to see the recently published [collected poems](https://www.word-power.co.uk/books/the-annotated-collected-poems-I9781852247461/?ref=lorcandempsey.net) of [Edward Thomas](https://worldcat.org/identities/lccn-n79-29744?ref=lorcandempsey.net) edited by [Edna Longley](https://worldcat.org/identities/lccn-n81-147007?ref=lorcandempsey.net) on the home page of Word Power Books. I was looking for this the other day in our local Borders but did not find it. It seems to me it carries less stock than it did when we arrived in Columbus, gulp, seven years ago. I am definitely disappointed more often …..
Anyway, this wouldn’t deserve a blog entry except that I have just been reading [Stefan Collini’s](https://worldcat.org/identities/lccn-n78-71715?ref=lorcandempsey.net) review of Smith’s biography in the London Review of Books (and I like making opportunities to link to lots of Identities pages ;-).
> Claims that everything is going to the dogs all too often rest on the hidden supports of parochialism, snobbery, class insouciance and a wilful refusal of the intellectual effort required to try to draw up a more realistic balance sheet of gain and loss. Williams fought against those things all along the line. It is hard to come away from this biography without admiring the way he made himself strong enough to fight that fight to such good effect. \[[LRB · Stefan Collini: Upwards and Onwards](https://www.lrb.co.uk/v30/n15/coll01%5F.html?ref=lorcandempsey.net)\]
I wonder what Williams would make of the current discussion about reading and the web ……
### SEO is part of our business
URL: https://www.lorcandempsey.net/seo-is-part-of-our-business/
Last updated: 2020-10-28T09:22:10.000Z
John Wilkin has another nice post, talking about making resources available in such a way as to make them more likely to be crawled by Google and hence more generally discoverable and, importantly, useful and used.
> We often go wrong, however, when we try to share our love of complexity with the consumers. We’ve come to understand that success in building our systems involves making complicated *uses* possible without at the same time requiring the user to have a complicated *understanding* of the resource. What we must also learn is that a simplified rendering of the content, so that it can be easily found by the search engines, is not an unfortunate compromise, but rather a necessary part of our work. \[[John Wilkin’s blog » Our hidden digital libraries](https://scholarlypublishing.org/jpwilkin/archives/14?ref=lorcandempsey.net)\]
Roy has been [talking](https://hangingtogether.org/?p=475&ref=lorcandempsey.net) about this issue also.
This is clearly less straightforward than many imagine. Google can make choices about what to crawl, what to index, and what to present in results. At play for larger sites also is the danger of falling foul of the search engines’ spam protection measures.
I participate in a JISC advisory committee on repository issues in the UK. I spent some time arguing earlier this year that search engine optimization should be a higher priority for repository managers, for institutions, and for both the capacity building systemwide infrastructure and advisory structures that JISC is capable of providing. We now recognize that simply having stuff on the web is often not enough. It is increasingly necessary to think about how well it is being crawled, indexed and discovered. .
This is why I have [emphasized](https://www.google.com/search?q=%22lorcan+dempsey%22+disclosure&ref=lorcandempsey.net) ‘disclosure’ as a new word in our service lexicon. We may not control the discovery process in many cases, so we should be increasingly concerned about effective disclosure to those discovery services. Effective disclosure has be be managed, whether it is about APIs, RSS feeds, support for inbound linking, exposure to search engines, ……
Related entries:
- [Discovery happens elsewhere](https://blog.oclc.org/lorcand/archives/001430.html?ref=lorcandempsey.net)
- [Discovery and disclosure again](https://blog.oclc.org/lorcand/archives/001111.html?ref=lorcandempsey.net)
- [Discovery and disclosure](https://blog.oclc.org/lorcand/archives/001084.html?ref=lorcandempsey.net)
### Mobile apps and Google traffic
URL: https://www.lorcandempsey.net/mobile-apps-and-google-traffic/
Last updated: 2020-10-28T09:22:14.000Z
I have mentioned the often interesting Hitwise blog a few times. They have presented a couple of interesting analyses recently.
One looks at the searches for mobile applications after the recent new iPhone release. They look at specific applications and also at general application areas. It is interesting seeing the emphasis on social networking, communication and music radio.
> I ran a search term suggestions report for the phrase ‘iPhone app’ to get a sense of which applications consumers were searching for outside of the iTunes interface. Last week, social networking, instant messaging, and radio applications were very popular along with the game [Super Monkey Ball](https://www.monkeyballworld.com/?ref=lorcandempsey.net), which has been prominently featured in the application store and receives many favorable reviews. Other applications that work with [Twitter](https://www.twitter.com/?ref=lorcandempsey.net) were also being searched along with the [NYTimes](https://www.nytimes.com/?ref=lorcandempsey.net) application. A few brands are also coming up frequently in search that do not as of yet have official applications (although the services can be accessed through other applications) are for the two popular photo-sharing websites [Flickr](https://www.flickr.com/?ref=lorcandempsey.net) and [Picasa](https://picasa.google.com/?ref=lorcandempsey.net), as well as Internet phone service provider [Skype](https://www.skype.com/?ref=lorcandempsey.net). \[[Hitwise Intelligence – Heather Dougherty – US: Pimp My iPhone](https://weblogs.hitwise.com/heather-dougherty/2008/07/pimp%5Fmy%5Fiphine.html?ref=lorcandempsey.net)\]
eBooks and eBook readers figures on the list of general applications.
And another looks at the relative traffic to Google sites. The context was the rumored acquisition of Digg by Google and they show Digg’s relative position in the table. Here I was interested to see where Google Book Search figures – right between Orkut and Picasa Web Albums. I was also interested to note that Google Scholar did not make the list of the top 20 at all.
[](https://weblogs.hitwise.com/us-heather-hopkins/2008/07/digg%5Facquisition%5Frumors%5Ftake%5F3%5F1.html?ref=lorcandempsey.net)
### Van the Man
URL: https://www.lorcandempsey.net/van-the-man/
Last updated: 2020-10-28T09:22:18.000Z
Something for the weekend …..
I have been interested to observe the disappearance of many Van Morrison songs from YouTube over the last while. I used to look at some from time to time. For example, there were a couple of videos of Cassandra Wilson’s wonderful interpretation of Tupelo Honey which are now gone. The video showing his duet with Sinead O’Connor on The Late Show\* is also gone. His version of that Dublin song based on the Patrick Kavanagh poem, Raglan Road, with Derek Bell is gone.
What has been added recently is a set of ‘obscured’ videos from [OfficialExileFilms](https://www.youtube.com/user/OfficialExileFilms?ref=lorcandempsey.net).
I also notice that there is some stuff made available by permission of Exile Productions, his production company. Here is Jen Chapin singing Into the Mystic.
There has been quite a bit of Morrison activity lately with compilations and further releases of his remastered back catalog. And his view of record companies controlling his earlier work is well known. He has had his own label, Exile Productions, for many years. The ‘obscured’ videos carry a note pointing to [vanmorrison.com](https://vanmorrison.com/?ref=lorcandempsey.net) where a “very important masterwork” is promised, and videos will appear ‘unobscured’. It will be interesting to see what emerges.
I notice that on the ‘obscured’ version of St Dominic’s Preview above there is no information about who is accompanying him or when or where the recording is. It looks as if it might be from Donal Lunny’s TV show, Sult, but I can’t be sure. One hopes that this type of detail will be added in any more ‘controlled’ release of videos.
I looked very quickly to see if I could see any obvious reported background on this activity. But didn’t find anything.
I found this interesting as an example of an artist taking a position on how much he wants to control the reception of his work in an environment like Youtube.
\* For Irish readers, yes, I do mean The Late Show, not The Late Late Show 😉
### The institutional record and web archiving
URL: https://www.lorcandempsey.net/the-institutional-record-and-web-archiving/
Last updated: 2020-10-28T09:22:20.000Z
As an institution’s web presence becomes more central to its identity and business life, it will be interesting to see how long it is before we have more routine approaches to selectively capturing and archiving institutional web resources.
One of the interesting things about this topic, as with many we now face, is that effective approaches probably depend on pulling together different institutional perspectives (archives and/or library, administration, …). This presentation by Lizzie Richmond (University Archivist, Records Manager, and Freedom of Information Co-ordinator) and Alison Wildish (head of web services) at the University of Bath provides an interesting case study: the University of Bath Prospectus. This is an important University document, which gives a strong sense of the changing character of the University over its history. The University would always have kept the print manifestation; what now to do with the web manifestation? One of the interesting changes they note over this time is the ‘rise of the logo’, and tracing changes in **how** the institution presents itself over time is also interesting.
[Preservation of Web Resources: University of Bath Case Study](https://www.slideshare.net/awildish/preservation-of-web-resources-university-of-bath-case-study?src=embed&ref=lorcandempsey.net "Preservation of Web Resources: University of Bath Case Study")
view [presentation](https://www.slideshare.net/awildish/preservation-of-web-resources-university-of-bath-case-study?src=embed&ref=lorcandempsey.net "View Preservation of Web Resources: University of Bath Case Study on SlideShare") (tags: [powr](https://slideshare.net/tag/powr?ref=lorcandempsey.net) [ukoln](https://slideshare.net/tag/ukoln?ref=lorcandempsey.net) [jisc](https://slideshare.net/tag/jisc?ref=lorcandempsey.net) [preservation](https://slideshare.net/tag/preservation?ref=lorcandempsey.net))
Of course, web archiving has been much discussed in recent years and has broader library implications. Public libraries have long had a local history role, collecting local newsletters or reports, for example, as well as other materials. As much of that moves to the web, how does that role continue? And universities are exploring selective capture and management of websites to support various scholarly inquiries.
In this context, I was recently struck by this report of remarks from the ever suggestive James Currall. I thought these were good examples to cite.
> In *The Tangled Web is but a Fleeting Dream … but then again…,* James Currall covered the essentials of web archiving in a clear and engaging way, drawing comparisons between the survival of WWI soldiers’ diaries, and the blogs of present-day servicemen in Iraq. Another example given was the trials and tribulations of the website for the Lockerbie Trial Briefing Unit: outsourced, host ceased trading, domain name lapsed, original website content dependent on outdated Coldfusion and Access environment. Thankfully a remote-harvested, static HTML image of the site does survive. \[[da blog (ulcc digital archives blog) » Blog Archive » JISC-PoWR @ IWMW2008](https://dablog.ulcc.ac.uk/2008/07/25/jisc-powr-iwmw2008/?ref=lorcandempsey.net)\]
Both of the presentations referenced above were given at [JISC-PoWR](https://jiscpowr.jiscinvolve.org/?ref=lorcandempsey.net) events. PoWR stands for Preservation of Web Resources, and it has been focusing some attention on this question again recently.
University of Bath presentation via [Brian Kelly](https://ukwebfocus.wordpress.com/?ref=lorcandempsey.net), who is one of the PoWR principals. The James Currall quote was from [da blog](https://dablog.ulcc.ac.uk/?ref=lorcandempsey.net), a home for University of London Computer Centre Digital Archives staff which also carried interesting discussion in this area. ULCC is also a PoWR partner.
### Quotes of the day: scholars on Google Book Search
URL: https://www.lorcandempsey.net/quotes-of-the-day-scholars-on-google-book-search/
Last updated: 2020-10-28T09:22:22.000Z
Here is John Sutherland on Google Book Search ….
> What we are witnessing this year is the beginning of the greatest act of recovered memory in the history of our species. The next decade will be the age of the unimaginably vast archive. More particularly, the dynamic and usable archive. The archive, that is, which hurls its contents at you, rather than requiring laborious spadework. \[[John Sutherland on how Google’s library project could transform research | Education | guardian.co.uk](https://www.guardian.co.uk/education/2008/jul/23/research.google?ref=lorcandempsey.net)\]
There is some interesting anecdotal stuff here about digital availability assisting scholarship.
Mary Beard [talks about](https://timesonline.typepad.com/dons%5Flife/2008/07/why-research-is.html?ref=lorcandempsey.net#comments) how she serendipitously found two books which were bound together with the one she was looking for in [Cambridge University Library](https://www.lib.cam.ac.uk/?ref=lorcandempsey.net). She later found that they were both available on Google Book Search.
> Now if you’ve clicked on the links, you’ll have seen another joke here. Both these rare books are available on Google books, which is why I’ve been able to share them with you. So I could have got them on my screen all along, without bothering to arm myself with a pencil (no pens in the Rare Books Room) and hoof off to the University Library.
> But the fact is that I wouldn’t have know about this if I hadn’t ordered up the Comic History and flipped through the rest of the volume. That’s where the UL and its funny nineteenth-century habits is always likely to score over Google books. \[[A Don’s Life by Mary Beard – Times Online – WBLG: Why research is fun](https://timesonline.typepad.com/dons%5Flife/2008/07/why-research-is.html?ref=lorcandempsey.net#comments)\]
It is always gratifying to hear stories like this, to hear how a library can be a source of pleasure and reward in scholarly life.
At the same time, I think we are seeing more opportunities for serendipitous discoveries in our online systems. Whether it through relations built on top of collections (e.g. LibraryThing) or lists (e.g. Worldcat lists) or though some of the navigation and linking options that are emerging in Google Book Search and other services. In fact, maybe those services should introduce a bundling feature where given one volume they associate randomly, or according to some other criteria, a set of other things with it (‘I’m feeling lucky’) 😉
RBVs – randomly bound volumes ….?
RBCs – random book collections …?
Mary Beard blog via [Colin Steele](https://www.canberratimes.com.au/blogs/colin-steele/gordon-browns-heathcliff-fixation-and-why-we-are-web-crash-dummies/1172914.aspx?ref=lorcandempsey.net).
### The professional poet
URL: https://www.lorcandempsey.net/the-professional-poet/
Last updated: 2023-12-05T04:46:15.000Z
Going a little off topic for this weekend message. Put aside your prejudices about the poet. [Eavan Boland](https://www.worldcat.org/identities/lccn-n80-109150?ref=lorcandempsey.net) (poet and Stanford [professor](https://english.stanford.edu/bio.php?name%5Fid=27&ref=lorcandempsey.net)) writes about the ‘skills’ modern poets require if they are to thrive. Perhaps an opportunity for business schools to diversify into professional development courses for poets?
> Whether we like it or not, the contemporary poet is increasingly skill-based. Or expected to be. He or she can — or should — lecture, lead a workshop, run an introductory class, teach composition, write a review, give a conference paper. In pursuit of all this, they are also expected to travel neatly, punctually, and soberly. \[[Poetry](https://www.poetrymagazine.org/magazine/0508/comment%5F181502.html?ref=lorcandempsey.net)\]
> Once I thought there was a broad tolerance for this. Now I’m not so sure. In Ireland, or the US or the UK, the tilt is towards the poet who can navigate the worlds of the university, the institution, the community, the reading series, the community workshop, the literary festival. There has been a gradual, perhaps calcifying professionalism which requires of a poet a standard of behavior and communality which poets were once exempted from. I was never uncritical of that exemption. But now, somehow, I wish I saw more of it. \[[Poetry](https://www.poetrymagazine.org/magazine/0508/comment%5F181502.html?ref=lorcandempsey.net)\]
In the picture, our daughter Eavan and her brother in the very nice library and cultural centre in Dun Laoghaire, looking out to the harbour and Dublin Bay beyond.
**Update:** Formatting fixed and picture updated 12/4/2023\.
### Reading and writhing
URL: https://www.lorcandempsey.net/reading-and-writhing/
Last updated: 2020-10-28T09:22:25.000Z
The Nicholas Carr article in the Atlantic – [Does Google make us stupid?](https://www.theatlantic.com/doc/200807/google?ref=lorcandempsey.net) – has generated a lot of commentary. Carr himself has just [pointed](https://www.roughtype.com/archives/2008/07/net%5Fbrain%5Fsyndr.php?ref=lorcandempsey.net) to an [Edge discussion](https://www.edge.org/discourse/carr%5Fgoogle.html?ref=lorcandempsey.net) and an [Encyclopedia Britannica discussion](https://www.britannica.com/blogs/2008/07/this-is-your-brain-this-is-your-brain-on-the-internetthe-nick-carr-thesis/?ref=lorcandempsey.net).
I have commented on the perils of distraction a couple of times recently. Once when [talking about](https://blog.oclc.org/lorcand/archives/001638.html?ref=lorcandempsey.net) the ease with which you can be distracted by the ‘time-saving’ integration ability of the Flock browser (which I still use, I fear) and again when [pointing to](https://blog.oclc.org/lorcand/archives/001615.html?ref=lorcandempsey.net) Fred Stutzman’s attempts to resist the encroachment of the network into the productive time in which he codes, writes, creates.
I have been interested in the discussion around the Carr article. The focus has tended to be on consumption, on the apparent difficulty people have with *immersive reading*.
I confess I find this less of an issue than *immersive writing*. I still read books, maybe not as many as at some other times of my life. However, I am beginning to find it more difficult to write in a sustained way (no great harm there, I hear some of you say ;-). No doubt one reason for this is that I typically write on the laptop, which is also where I intersect with the network. Most of my sustained reading happens away from the network.
Recently, when trying to write something I find that I am turning off the network on the laptop and relying on the Blackberry for email. At home this poses a difficulty though: despite living in a well covered area – inside the city of Columbus – I find that coverage fades if I am not near a window, and even then will sometimes give up. So even though I am not distracted by email, or by my RSS aggregator, or by looking at Facebook statuses go past, I end up walking around with the Blackberry trying to grab some network to synch up!
### Yeats again
URL: https://www.lorcandempsey.net/yeats-again/
Last updated: 2020-10-28T09:22:27.000Z
I mentioned visiting the very nicely done [Yeats exhibition](https://www.nli.ie/en/udlist/current-exhibitions.aspx?article=adb6ce52-1f52-4a33-882c-685dedd0fb9d&ref=lorcandempsey.net) at the National Library of Ireland [in these pages](https://blog.oclc.org/lorcand/archives/001057.html?ref=lorcandempsey.net) a couple of years ago. There is a very positive story about it in the NYT today.
[ ](https://www.nytimes.com/2008/07/20/arts/design/20dwye.html?partner=rssnyt&emc=rss&ref=lorcandempsey.net)
They highlight some of the digital elements of the exhibition …..
> The notebook is one of thousands of elements in a dazzling exhibition, “The Life and Works of William Butler Yeats,” more like a life-size, walk-through Web site than an ordinary museum show. With audiotapes, four short films and software that brings light and breath to aging manuscripts, it amounts to a digital resurrection, allowing Yeats to stride again along the hinge of the 19th and 20th centuries. \[[Art – William Butler Yeats’s Relationship With Maud Gonne Is Explored at the National Library of Ireland – NYTimes.com](https://www.nytimes.com/2008/07/20/arts/design/20dwye.html?partner=rssnyt&emc=rss&ref=lorcandempsey.net)\]
“stride along the hinge”?
I mentioned at the time that it was a pity that the exhibition had a very limited web presence. That has now changed and there is a [flash-based online exhibition](https://www.nli.ie/yeats/main.html?ref=lorcandempsey.net) available. It is structured to replicate the physical exhibition and you can move around it looking at individual pieces. This is nice in one way, but means that you cannot individually link to or reuse resources, and those resources don’t appear to be visible to the web (through search for example). The exhibition itself is searchable, but this didn’t seem to be working when I tried it.
### Library APIs
URL: https://www.lorcandempsey.net/library-apis/
Last updated: 2020-10-28T09:22:29.000Z
Building on some work by [Owen Stephens](https://www.meanboyfriend.com/overdue%5Fideas/?ref=lorcandempsey.net), [Roy](https://www.libraryjournal.com/blog/1090000309.html?ref=lorcandempsey.net) has created [a list of library APIs](https://techessence.info/apis?ref=lorcandempsey.net), or APIs of potential interest to library applications. It is in early stages and he welcomes suggestions for addition.
### "Metadata tends to get more complicated the longer you think about it"
URL: https://www.lorcandempsey.net/metadata-tends-to-get-more-complicated-the-longer-you-think-about-it/
Last updated: 2024-11-21T07:30:16.000Z
Something of a virtuoso performance from Andy Powell: *Does Metadata Matter?*
> This a 30 minute slidecast (using 130 slides), based on a seminar I gave to Eduserv staff yesterday lunchtime. It tries to cover a broad sweep of history from library cataloguing, thru the Dublin Core, Web search engines, IEEE LOM, the Semantic Web, arXiv, institutional repositories and more. \[[eFoundations: Does metadata matter?](https://efoundations.typepad.com/efoundations/2008/07/does-metadata-m.html?ref=lorcandempsey.net)\]
\[[Slideshare](https://www.slideshare.net/slideshow/does-metadata-matter/516694?ref=lorcandempsey.net)\]
This stands up well just as a powerpoint presentation. The rapid-fire slide style (echoes of Dick Hardt) works very well.
If you listen to the presentation (click the arrow in the middle) you get more information but it moves more slowly.
Following the discussion of cataloging in the library community Andy says: “metadata tends to get more complicated the longer you think about it”. I wonder what he can mean ...
**Note:** Reformatted and pic added 11/20/2024
### The future of bibliographic control and the OCLC/ALISE research grants
URL: https://www.lorcandempsey.net/the-future-of-bibliographic-control-and-the-oclc-alise-research-grants/
Last updated: 2020-10-28T09:22:37.000Z
Each year we collaborate with ALISE to award several research grants. Check out the details page:
> Full-time academic faculty (or equivalent) in schools of library and information science are eligible to apply. OCLC and ALISE encourage international proposals and collaborative projects under this program. To aid new researchers, priority will be given when possible to proposals from junior faculty and applicants who have not previously received LISRGP funds. Proposals must be signed by the principal investigator, by the dean/director (or equivalent) of the school, and by an authorized official of the university. \[[Research grant program \[OCLC – Programs and Research\]](https://www.oclc.org/programsandresearch/grants/default.htm?ref=lorcandempsey.net)\]
This year, we have decided to focus the topic of the call:
> Proposals are invited that address the issues identified in “[On the Record: Report of The Library of Congress Working Group on the Future of Bibliographic Control](https://www.loc.gov/bibliographic-future/news/lcwg-ontherecord-jan08-final.pdf?ref=lorcandempsey.net)” (.pdf: 437K/49 pp.), January 9, 2008\. \[[Research grant program \[OCLC – Programs and Research\]](https://www.oclc.org/programsandresearch/grants/default.htm?ref=lorcandempsey.net)\]
The working group pointed to a limited evidence base in many of the areas it discussed. We hope that the research funded here can help address that issue.
### Libraries and the interweb
URL: https://www.lorcandempsey.net/libraries-and-the-interweb/
Last updated: 2020-10-28T09:22:40.000Z
Nick Carr has made a [list](https://www.roughtype.com/archives/2008/07/albums%5Fgoing%5Fst.php?ref=lorcandempsey.net) of his favorite ‘album’ of each year since 1966\. Some more detail:
> Over at The Gaping Silence, Phil Edwards [picks up the challenge](https://gapingsilence.wordpress.com/2008/07/14/when-how-you-want/?ref=lorcandempsey.net) of listing “a favorite album for every year of your life.” I’m definitely game for this game, though, like Phil and for precisely the same reason, I’m going to begin the list a few years after the year I was born. There are two restrictions: only one album per year (painful!) and no repeats of artists. \[[Rough Type: Nicholas Carr’s Blog: Albums going steady](https://www.roughtype.com/archives/2008/07/albums%5Fgoing%5Fst.php?ref=lorcandempsey.net)\]
[Born in 1959](https://www.worldcat.org/identities/lccn-n00-102292?ref=lorcandempsey.net), his list begins in 1966.
His choice for 2008 is [*Evil urges*](https://www.worldcat.org/oclc/228073942?tab=details&ref=lorcandempsey.net) by My Morning Jacket.
As some of you will no doubt know, *Evil Urges* carries a song called ‘Librarian’ (about which I offer no opinion). I do observe that it includes these lines:
> walk across the courtyard, towards the library.
> I can hear the insects buzz and the leaves ‘neath my feet …
>
>
>
> ramble up the stairwell, into the hall of books…
> since we got the interweb these hardly get used.
### Disclosure and diffusion - synchronization and syndication
URL: https://www.lorcandempsey.net/disclosure-and-diffusion-synchronization-and-syndication/
Last updated: 2020-10-28T09:22:43.000Z
David Bigwood on his blog stats:
> Making your content available in more places makes metrics hard. Before Bloglines, Google Reader, Facebook Blog Network, Planet Catalog, and all the rest I could get a feel for the number of readers. Didn’t matter too much to me, this is done for my own benefit as well as the community. However, if I was in a position and needed numbers to justify the work it would make it difficult. \[[Catalogablog: Facebook](https://catalogablog.blogspot.com/2008/07/facebook.html?ref=lorcandempsey.net)\]
David’s comments were in the context of the [Facebook Blog Network](https://apps.facebook.com/blognetworks/blogpage.php?blogid=14920&ref=lorcandempsey.net).
I agree. I also don’t have a good sense of what the relative balance is between reading ‘elsewhere’ (in Bloglines for example) and reading at the blog site itself. Nor do I have a good sense of how many people use ‘personal’ readers (I use the reader built into Flock, for example) as opposed to network level ones (Bloglines). Some stuff I could find out with a bit more effort, other stuff would be much more difficult.
It does strike me that this is an increasingly common pattern. We ‘disclose’ materials in particular ways, and then they enter a diffuse network of syndication and synchronization.
On a related topic, I look forward to seeing some numbers from those libraries who have been experimenting with Facebook apps, toolbars, etc, to see how much use they are channeling to the library.
### QOTD: perpetually engulfed by books ...
URL: https://www.lorcandempsey.net/qotd-perpetually-engulfed-by-books/
Last updated: 2020-10-28T09:22:46.000Z
Writing about the history of Cambridge University Library, David McKitterick \[[Worldcat identity](https://www.worldcat.org/identities/lccn-n78-75204?ref=lorcandempsey.net); [Worldcat search](https://www.worldcat.org/search?q=au%3A+david+mckitterick&ref=lorcandempsey.net)\] says:
> There is one simple lesson to be learned from studying library history. Those administering, and those using, libraries have almost invariably faced a growth of knowledge, reflected in increasing numbers of books, that threatens to engulf each succeeding generation. \[History of the library. In [Cambridge University Library: the great collections](https://www.worldcat.org/oclc/39980080?ref=lorcandempsey.net). Cambridge: Cambridge University Press, 1998\. [Peter Fox](https://worldcat.org/identities/lccn-n82-535?ref=lorcandempsey.net), ed.\]
I was reminded of these lines when reading my colleague Constance Malpas’s account of some interesting work commissioned by Ithaka from Candi Yano. Professor Yano has developed a framework within which to think about the optimal overlap, or redundancy, of collections required to ensure print preservation (the focus was on journals, but it poses interesting questions also for books). We have spent the last few years thinking about digital preservation. I think that the issues surrounding the preservation of the scholarly and cultural record in print are about to loom into view as the opportunity costs of storing progressively less-used print collections become too high to bear. Space is being reclaimed for other purposes, and publications continue to pour forth. The current threat of being engulfed is prompting greater thinking about systemwide responses.
> In sum, the evidence in hand suggests that there is substantially less duplication in aggregate holdings than is required to achieve the preservation guarantees obtained in Yano’s model. Given unrelenting space pressures on library print collections, and decreasing circulation rates, it seems imperative that libraries – research libraries, in particular – take immediate action to establish a common understanding of our respective (and collective) preservation goals and identify the core requirements for managing this highly distributed, thinly duplicated resource as a single, shared collection. This is an area where [RLG partners](https://www.oclc.org/programs/partnership/roster.htm?ref=lorcandempsey.net) are poised to take action. \[[hangingtogether.org » Blog Archive » Safety in Numbers? Calculating Optimal Overlap for Print Preservation](https://hangingtogether.org/?p=448&ref=lorcandempsey.net)\]
### Pogue songs
URL: https://www.lorcandempsey.net/pogue-songs/
Last updated: 2020-10-28T09:22:49.000Z
Jim Michalko describes a talk by David Pogue of the NYT at the American Association of Law Libraries meeting and finishes by pointing to an entertaining video.
> Rather than using the end of his session for questions he walked over to an electronic piano keyboard and performed three parody songs about technology – iTunes (to Piano Man), YouTube (to I got you babe) and RIAA (to YMCA). The law librarians waved arms and sang along heartily with this last one. Obviously he didn’t pull this together for AALL – there’s a high quality loop of him performing this at TED [here](https://www.youtube.com/watch?v=xF7cHmyEJ-c&ref=lorcandempsey.net). \[[hangingtogether.org » Blog Archive » “Nothing stays where you put it” Pogue at AALL](https://hangingtogether.org/?p=462&ref=lorcandempsey.net)\]
### Name authorities
URL: https://www.lorcandempsey.net/name-authorities/
Last updated: 2020-10-28T09:22:52.000Z
Libraries have invested significantly in name authority work over the years, and have created extensive infrastructure to help manage names of people and organizations. The relationship between this work and broader interest in this topic is something that will need to be addressed in coming years if this work is to continue to have utility.
[](https://orlabs.oclc.org/viaf/search/VIAF?query=local.personalName+all+%22lorcan%20dempsey%22+&version=1.1&maximumRecords=100&operation=searchRetrieve&stylesheet=/viaf/xsl/Results.xsl&sortKeys=holdingscount&recordSchema=BriefMarcXML&ref=lorcandempsey.net)
Library authority work is now doubly partial: it is organized on national lines, and it typically only applies to names which come forward in the ‘cataloged’ literature (not in the journal literature, for example). We are working with several national libraries on the [VIAF](https://www.viaf.org/?ref=lorcandempsey.net) project to address the former issue. The latter may end up requiring various partnerships and mappings as other approaches get established, but this is in very early days. More generally, if library authority files are to be of greater use, it seems inevitable that national libraries will need to coordinate more closely in creating and sharing them, and they will have to open up more to a variety of contributions (should I, for example, be able to augment the [authorities data](https://orlabs.oclc.org/viaf/LC|n90602202?ref=lorcandempsey.net) held about me?). It is also probably sensible to consider adding references to author or contributor IDs as they emerge in other contexts.
To simplify, think of three ‘current materials workflows’ which libraries manage in different ways, and which result in access services: (i) materials that are cataloged, typically bought materials like books, where the metadata is managed and sometimes created by the library (ii) materials that are licensed, typically the journal and A&I literature, where the metadata is created, and aggregated, by many external third parties who may not follow common practices with regard to the form of names, and (iii) institutional research and learning outputs, typically e-prints, data or learning materials, where the metadata may be created by academics or by the library, and where the potential value of an agreed regime for the formation of personal and institutional names is only beginning to emerge.
(One place where this lack of consistency is becoming increasingly apparent in libraries is in the new ‘discovery layer’ systems which are bringing the catalog, local digital materials, and maybe knowledge base and metasearch into a single discovery environment.)
Library approaches have historically dealt with (i).
There is now major interest in the other areas, and this interest seems to have grown recently.
In (ii) above see for example [ResearcherID](https://researcherid.com/?ref=lorcandempsey.net) from Thomson or the [Scopus Author ID](https://help.scopus.com/robo/projects/schelp/h%5Fautsrch%5Fintro.htm?ref=lorcandempsey.net).
For an example under (iii) see how the Digital Author Identifier is used by the institutional repository framework in the Netherlands. This is interesting because it does in fact work with library authority files.
> Digital Author Identification (DAI) is a unique national number assigned to every author who has been appointed to a position at a Dutch university or research institute or has some other relevant connection with one of these organisations. SURF and OCLC PICA have set up a link with the PICA thesaurus of personal names that is maintained and updated by the university libraries. One very important factor in this system is the link between the Metis research information system and the repository. …
> …. An application used in NARCIS (the portal into which DAREnet has been integrated since April 2008) allows Open Access publication lists to be generated on the basis of the DAI harvested from the various repositories of Dutch scientific/scholarly institutions. Using the DAI, it is possible to present the information from the various repositories in an integrated manner. \[[Digital Author Identifier (DAI)](https://www.surffoundation.nl/smartsite.dws?ch=eng&id=13480&ref=lorcandempsey.net)\]
At the same time, there is a variety of disciplinary or community approaches. See for example the [RePEc Author Service](https://authors.repec.org/about?ref=lorcandempsey.net).
The interest in names and author IDs is driven by several factors. Services want to disambiguate authors and to cluster works by the same author. Increasingly, personal and institutional reputation management in a web environment is focusing attention on identifiers and consistent naming. This is especially the case as metrics based on citations and web links become more common.
For some useful context on this topic see [this note](https://www.crossref.org/CrossTech/2007/02/crossref%5Fauthor%5Fid%5Fmeeting.html?ref=lorcandempsey.net) by Geoff Bilder and also see the landscape report \[[pdf](https://names.mimas.ac.uk/documents/LandscapeReport26Jun2008.pdf?ref=lorcandempsey.net)\] from the Names project in the UK, an initiative exploring the feasibility of a name authority service for repositories of research outputs.
### Aeon
URL: https://www.lorcandempsey.net/aeon/
Last updated: 2020-10-28T09:22:57.000Z
[Atlas Systems](https://www.atlas-sys.com/?ref=lorcandempsey.net) is one of those smaller companies in the libraries marketplace who provides niche solutions. The are probably best known for the Illiad resource sharing software.
However, they also provide an interesting system in a new application area …
> Aeon offers a circulation management system that enables special collections libraries and archives to provide better customer service in a more secure and controlled environment. By eliminating many of the manual steps in non-automated systems, Aeon allows special collections librarians to improve both the depth and quality of services they provide patrons, without the need for additional staff. \[[Atlas Systems, Inc. – Aeon](https://www.atlas-sys.com/products/aeon/features.html?ref=lorcandempsey.net)\]
I was interested to read this about EAD:
> From within the EAD you can further control the level of requesting. Do you allow patrons to request at the box level, folder level, or item level from within your EAD guide?
> Aeon takes your EAD data and provides convenient check boxes for patrons to request exactly the item(s) they want. \[[Atlas Systems, Inc. – Aeon](https://www.atlas-sys.com/products/aeon/features.html?ref=lorcandempsey.net)\]
One wonders if this is the type of thing that will continue to be sourced separately, or will be absorbed into general ILS functionality, or ….. I have no experience of the product, nor have I spoken to anybody who has.
Via [Frank Hermes](https://www.libraryleadership.net/aboutus.asp?ref=lorcandempsey.net), my former OCLC colleague, who works with Atlas.
### Institutional social networks
URL: https://www.lorcandempsey.net/institutional-social-networks/
Last updated: 2020-10-28T09:22:58.000Z
Tony Hirst has an [interesting post](https://blogs.open.ac.uk/Maths/ajh59/014991.html?ref=lorcandempsey.net) pointing to Ning-based institutional social networks at [The University of Wales, Newport](https://newstudents.newport.ac.uk/?ref=lorcandempsey.net), and at [The University of Bradford](https://developme.ning.com/?ref=lorcandempsey.net). He cites some colleagues reporting “Yeah, it’s happening all over the place”. As Tony points out the Bradford site is part of a more general online student support system, [Develop me](https://www.brad.ac.uk/developme/?ref=lorcandempsey.net).
Michael Webb describes some of the thinking around the Newport site:
> So our options – do something ourselves (our usual default position I guess), piggy back onto an existing service (eg Facebook), or go with one of the new wave of ‘create your own’ social network sites, like Ning. \[[Michael Webb’s Blog : Newspace – a social networking site for new students](https://blog.newport.ac.uk/blogs/michael/archive/2008/07/09/52948.aspx?ref=lorcandempsey.net)\]
> Probably the biggest discussion was whether to make it open or closed – ie visible to everyone on the net or not. We’ve gone with closed – we feel we need to protect our users privacy given we are inviting them into the space, and have a closed space makes it feel a little more special. \[[Michael Webb’s Blog : Newspace – a social networking site for new students](https://blog.newport.ac.uk/blogs/michael/archive/2008/07/09/52948.aspx?ref=lorcandempsey.net)\]
> It’s certainly given me food more thought about how we provide services in the future. If we had created the site ourselves it would have taken months. If we had bought in software it would have still taken weeks. This took days. And no worrying about upgrades, downtime etc. What have we lost? We can’t control the development of the service – our users probably don’t understand this, and have already started suggesting functionality improvements. \[[Michael Webb’s Blog : Newspace – a social networking site for new students](https://blog.newport.ac.uk/blogs/michael/archive/2008/07/09/52948.aspx?ref=lorcandempsey.net)\]
One can see these types of sourcing and policy questions begin to apply to a wider range of institutional services.
### Hot air ... thoughts from a blog bore
URL: https://www.lorcandempsey.net/hot-air-thoughts-from-a-blog-bore/
Last updated: 2020-10-28T09:23:00.000Z
I fear that I am becoming a blog bore!
At work, I find myself often wanting to say, and sometimes actually saying, “as I said in my blog entry the other day …”. Now, I am a bit self-conscious about this. If I don’t say anything, and somebody has read the blog entry, they may think that I am repeating myself as I enter my dotage. If I do say something, and they have not read the blog entry (surprisingly … not all my colleagues read the blog ;-), they may feel I am puffing myself up a little. What to do ….?
Now, seriously, it is not unreasonable to be in this position. A blog is a place to lodge ideas and once they have been externalized it is natural to want to refer to them. A blog entry can be easily referenced; it is a way of giving an idea a URL.
A blog is an ***addressable idea repository***: AIR. Hot air, even …..
For a more worked out view, see this [interesting post](https://q6.oclc.org/2008/07/thought%5Fidentif.html?ref=lorcandempsey.net) from my colleague Jeff Young.
### We enjoy visiting with our users while there is no place like home
URL: https://www.lorcandempsey.net/we-enjoy-visiting-with-our-users-while-there-is-no-place-like-home/
Last updated: 2023-11-28T03:23:47.000Z
How libraries reach into the flow of their users has been one of the recurrent themes of this blog. Recently, I have been interested to see libraries begin to systematise this and to understand the issues around particular approaches. I [mentioned](https://blog.oclc.org/lorcand/archives/001684.html?ref=lorcandempsey.net) the National Library of Scotland’s presence on YouTube the other day, and a comment pointed me to an interesting discussion by Eilidh MacGlone about the initiative:
> In conclusion, there really is no place like home to us at the moment – our catalogue is in much better shape than YouTube’s. But we think YouTube is a great place to take our filmshows, to visit and meet our users, to build relationships and to interact with them, and perhaps in this aspect, YouTube is better than any online service we yet offer. \[[WIDWISAWN: volume 6, issue 1, page 4](https://widwisawn.cdlr.strath.ac.uk/issues/vol6/issue6%5F1%5F4.html?ref=lorcandempsey.net)\]
This is in the nicely named [WIDWISAWN](https://widwisawn.cdlr.strath.ac.uk/index.html?ref=lorcandempsey.net) (who is doing what in Scotland and what is needed). The same issue carries a piece by Andrew Youngson giving a high level overview of NLS interaction with several web-based services:
> In reality the likelihood of major unforeseen issues and problems is slim. To allow such concerns to hold back making information and content available is to the detriment to the vast majority of people who could access it and enjoy it. The imagined lack of “control” is understandable, but ensuring reasonable and professional judgement is used at the point of creation should allay this fear. For every possible concern with utilising these resources, there are many more positives to be gained from sensible usage. \[[WIDWISAWN: volume 6, issue 1, page 3](https://widwisawn.cdlr.strath.ac.uk/issues/vol6/issue6%5F1%5F3.html?ref=lorcandempsey.net)\]
As we get more experience, the particular characteristics of each service will become more apparent. In commenting about this initiative, for example, Seb Chan interestingly contrasts Flickr and YouTube.
> As Burgess points out, though, the best textual responses to YouTube content happen on the blogs, forums and website on which video content ends up being embedded, rather than on YouTube itself. Whilst this also occurs with Flickr embeds, my hunch is that Flickr’s active nurturing of its ‘own’ community around the site means that embedding plays a lesser role than it does for YouTube content. \[[fresh + new(er) » Blog Archive » Video archives in YouTube? – National Library of Scotland](https://www.powerhousemuseum.com/dmsblog/index.php/2008/07/02/video-archives-in-youtube-national-library-of-scotland/?ref=lorcandempsey.net)\]
Andrew Youngson talks about enjoyment in his note above. I was at the National Library of Scotland with some colleagues from the SCONUL conference. In the entrance were panels with pictures from the collection. One caused some discussion. It was a letter from [Elizabeth Taylor](https://worldcat.org/identities/lccn-n50-9560?ref=lorcandempsey.net) to [Muriel Spark](https://worldcat.org/identities/lccn-n80-38438?ref=lorcandempsey.net). Much of the interest was because she signed herself *Elizabeth Taylor Burton* \[\*\]. I can now [share](https://www.flickr.com/photos/nlscotland/2420923958?ref=lorcandempsey.net) our enjoyment with you ……:
\[Note 23 March 2011: I was sad to see the news today that Elizabeth Taylor had died, and it caused me to look back at this entry. I noticed that the image was no longer showing. I am not sure why. It is available [here](https://digital.nls.uk/murielspark/finest/finest2.html) at the National Library of Scotland site.\]
\[\*\] Interestingly, this name is not recorded in [LC](https://orlabs.oclc.org/viaf/LC|n50009560?ref=lorcandempsey.net), [DNB](https://orlabs.oclc.org/viaf/DNB|118621092?ref=lorcandempsey.net) or [BNF](https://orlabs.oclc.org/viaf/BNF|FRBNF120736808?ref=lorcandempsey.net) authority files.
Related entry:
- [A shop window to the National Library of Scotland](https://blog.oclc.org/lorcand/archives/001684.html?ref=lorcandempsey.net)
### Class numbers on works
URL: https://www.lorcandempsey.net/class-numbers-on-works/
Last updated: 2020-10-28T09:23:05.000Z
[Classify](https://deweyresearch.oclc.org/classify2/?ref=lorcandempsey.net) is a protoype service which provides a snapshot of what class numbers (DDC, LCC, NLM) have been assigned to works in Worldcat.
> The records are grouped using the OCLC FRBR Work-Set algorithm resulting in a work-level summary of the class numbers assigned a title. You can retrieve a classification summary by ISBN, ISSN, UPC, OCLC number, or author/title. \[[About Classify \[OCLC\]](https://www.oclc.org/research/researchworks/classify/?ref=lorcandempsey.net)\]
Here are the LCC numbers assigned to [The Consequences of Modernity](https://deweyresearch.oclc.org/classify2/Classify?swid=020491296&ref=lorcandempsey.net) by [Anthony Giddens](https://worldcat.org/identities/lccn-n79-143085?ref=lorcandempsey.net):
[](https://deweyresearch.oclc.org/classify2/Classify?swid=020491296&ref=lorcandempsey.net)
### Changing research behaviors and libraries
URL: https://www.lorcandempsey.net/changing-research-behaviors-and-libraries/
Last updated: 2020-10-28T09:23:06.000Z
Libraries are not ends in themselves, although it is tempting to talk about them as if they are. They support research, learning, civic engagement, personal development, …. This means that it is as important, or more important, to understand how technology is impacting those behaviors as it is to understand how technology is impacting libraries themselves.
In this context, several recent presentations about the practice of research may be of interest.
[Carole Palmer](https://people.lis.uiuc.edu/~clpalmer/?ref=lorcandempsey.net) recently spoke at OCLC.
> At the practical level, informed decisions require deep knowledge of scholarly and scientific research practices and potentials. For instance, studies have shown scientists are reading more and that information users of all kinds are searching in new ways by “bouncing” on the Web.
> Palmer will discuss what findings like these tell us, and don’t tell us, about the value future information services can afford scholars in their research work. Drawing from our studies of scientific and scholarly practices, she will then illustrate the importance of extending information use studies beyond investigations of information discovery, access, and use to how researchers manage and manipulate their own data and create their own digital resources. \[[Carole L. Palmer \[OCLC\]](https://www.oclc.org/programsandresearch/dss/palmer.htm?ref=lorcandempsey.net)\]
The presentation was wide ranging and the powerpoint \[.[ppt](https://www.oclc.org/programsandresearch/dss/ppt/dss%5Fpalmer.ppt?ref=lorcandempsey.net)\] and an MP3 \[[MP3](https://www5.oclc.org/downloads/programsandresearch/dss/mp3/dss%5Fpalmer.mp3?ref=lorcandempsey.net)\] of the presentation are available.
The presentations at the [Digitization and the Humanities: Impact on Libraries and Special Collections Symposium](https://www.oclc.org/programs/events/2008-06-02c.htm?ref=lorcandempsey.net) organized by RLG Programs were also relevant here. In particular it was interesting hearing scholars describe their working practices in relation to digital environments and their current and desired intersection with library resources.
Following an introductory session, the symposium was organized in three parts. In the first, David Harrington Watt, a historian at Temple, and Zachary Lesser, an English scholar at the University of Pennsylvania, spoke about digital resources and their teaching practices. This was particularly interesting in the context of general discussions of ‘information literacy’ and research skills, and interaction between faculty, library and students.
In a second, Anke Timmermann, a historian of alchemy at The Chemical Heritage Foundation (the kind hosts of the meeting) and Douglas S. Reed from the Department of Government at Georgetown spoke about digital resources and their research practices. The first talk focused on the manuscript historical record of alchemy, and the second on the use of educational records.
Finally, Robin Adams, of Trinity College Dublin, and Paul Courant, of the University of Michigan, gave a perspective from the library.
Presentations and audio recordings of sessions are available on the [site](https://www.oclc.org/programs/events/2008-06-02c.htm?ref=lorcandempsey.net).
I particularly enjoyed Anke Timmermann’s style of delivery and some of her remarks stayed in my head. Talking of evidence and the manuscript record, she noted that ‘everything is relevant until it isn’t’, quoting from CSI. And she suggested that we think of poetry as a kind of fridge for language: it preserves it and keeps it fresh.
Related entry:
- [The Long Room Hub](https://blog.oclc.org/lorcand/archives/001648.html?ref=lorcandempsey.net)
### Terminology services
URL: https://www.lorcandempsey.net/terminology-services-3/
Last updated: 2020-10-28T09:23:09.000Z
During the deliberations of the Library of Congress Working Group on the Future of Bibliographic Control (of which I was a member) there was quite a bit of discussion about ‘webifying’ (or ‘webulating’, to use the phrase of my colleague Stu Weibel) library terminology and authority resources.
What this meant in practice was left vague. What was generally meant was that these vocabularies were addressable with ‘element’ level identifiers and were accessible using web-based protocols. In other words, they would become available as web resources in their own right. Before this, the model has usually been one in which elements are added as text strings to other metadata about information resources.
We have now made [a set of controlled vocabularies](https://tspilot.oclc.org/resources/index.html?ref=lorcandempsey.net) available as web services for experiment. In effect, these services make a variety of subject vocabularies available as resources on the web in ways that individual vocabulary elements can be found, referenced and recombined in applications. They are ‘webified’.
Here is how they are described on introductory materials produced for ALA:
> Terminology Services are web-based services for controlled vocabularies. More than 4.5 million terms, 2.4 million concept links, and 2 million contextual data elements are accessible to your applications.
>
> Each vocabulary is fully indexed and searchable. Vocabulary data is retrievable in multiple representations including the MARC authority format, used by libraries, and the SKOS Core Vocabulary used in Semantic Web applications.
Some of the ways in which such services might be used were [reported](https://www.oclc.org/programs/events/2007-09-12.htm?ref=lorcandempsey.net) from a meeting organized by RLG Programs last year. Example uses would be for query expansion (connect search terms to controlled vocabularies, link general to specialist vocabularies, go to broader or narrower terms, etc) or in metadata editors (provide access to various vocabularies without having to locally load them).
A simple example. An application could use MESH through the terminology services to [associate](https://tspilot.oclc.org/mesh/?query=oclcts.terms+all+%22kelp+giant%22&version=1.1&operation=searchRetrieve&recordSchema=info%3Asrw%2Fschema%2F1%2Fmarcxml-v1.1&maximumRecords=10&startRecord=1&resultSetTTL=300&recordPacking=xml&recordXPath=&sortKeys=&ref=lorcandempsey.net) a search term ‘giant kelp’ with the ‘technical’ term ‘Macrocystis’ \[[MESH](https://www.nlm.nih.gov/cgi/mesh/2008/MB%5Fcgi?field=uid&term=D044662&ref=lorcandempsey.net), [Terminology Services](https://tspilot.oclc.org/mesh/D044662.html?ref=lorcandempsey.net)\], and then use that to search, for example, [pubmed](https://www.ncbi.nlm.nih.gov/sites/entrez?cmd=PureSearch&db=pubmed&term=%22Macrocystis%22%5BMeSH%20Terms%5D&ref=lorcandempsey.net) or [worldcat](https://www.worldcat.org/search?q=su%3AMacrocystis&ref=lorcandempsey.net).
This is a rich collection of data, and it is not primarily aimed at human consumers. It is intended for applications. Further information is available on the [project page](https://www.oclc.org/research/projects/termservices/?ref=lorcandempsey.net) and access to resources is available from the [Prototype](https://tspilot.oclc.org/resources/?ref=lorcandempsey.net).
For an example of **one** application which uses the services to access subject terms for graphic materials see the [Indiana University Digital Library Program Collection Search](https://fedora-dev.dlib.indiana.edu:8080/search/index.jsp?ref=lorcandempsey.net). Our Indiana colleagues note that all the usual caveats about proof-of-concept apply here: this is not a polished production system. Try searching for ‘grapes’ or ‘wine’.
### Uniform titles
URL: https://www.lorcandempsey.net/uniform-titles/
Last updated: 2020-10-28T09:23:11.000Z
[Éilís Ní Dhuibhne](https://worldcat.org/identities/lccn-nr88-8209?ref=lorcandempsey.net), librarian and writer, has a review of [*The Library at Night*](https://www.worldcat.org/oclc/183257292?tab=details&ref=lorcandempsey.net) by [Alberto Manguel](https://worldcat.org/identities/lccn-n80-13377?ref=lorcandempsey.net) in today’s *[Irish Times](https://www.irishtimes.com/?ref=lorcandempsey.net)*.
> Mirroring what an eclectic, beautiful library is like, this volume assembles its reflections in a systematic way, under 15 uniform titles, ranked up like handsome spines, all in a row: The Library as Myth, The Library as Imagination, The Library as Identity, etc. Topics range from an account of the great library at Alexandria (The Library as Myth) to a discussion of the Google book project (The Library as Space), from a consideration of catalogues (The Library as Order) to history of book burnings (The Library as Shadow). \[[Booking essential – The Irish Times – Sat, Jul 05, 2008](https://www.irishtimes.com/newspaper/weekend/2008/0705/1215159142847.html?ref=lorcandempsey.net)\]
See that mention of ‘uniform titles’ connecting to librarian readers 😉
### Book covers and Piclens
URL: https://www.lorcandempsey.net/book-covers-and-piclens/
Last updated: 2020-10-28T09:23:14.000Z
The recent discussion of book covers as interface components on the [ngc4lib](https://serials.infomotions.com/ngc4lib/?ref=lorcandempsey.net) list provides an opportunity to mention PicLens, a utility that is has been creating a lot of interest recently.
According to its creators, [CoolIris](https://www.cooliris.com/?ref=lorcandempsey.net), PicLens provides an “immersive full-screen experience for viewing photos and videos”. It is available as a browser plugin, and there are also some other options. There are [guidelines](https://piclens.com/lite/webmasterguide.php?ref=lorcandempsey.net) for webmasters who want their sites to be available for the PicLens experience.
I have used it for a while now and find it very convenient for moving quickly through groups of images. It has some nice other features, including a recently added ‘discover’ feature which allows you to search image sources on the web and display the results within the PicLens environment.
So, two notes about PicLens and book covers. First, I was interested to see this note from Mark Dahl a while ago:
> Jeremy recently made a couple of our sites, [Watzek New Additions](https://library.lclark.edu/newbooks/?ref=lorcandempsey.net) and [accessCeramics](https://accessceramics.org/?ref=lorcandempsey.net), [PicLens](https://www.piclens.com/site/firefox/mac/?ref=lorcandempsey.net) compatible. The new additions browsing is pretty cool. It lets you scan through images of book jackets.
>
> Basically, this requires search results to be in a format called media RSS. \[[synthesize-specialize-mobilize: PicLens](https://synthesize-specialize-mobilize.blogspot.com/2008/06/piclens.html?ref=lorcandempsey.net)\]
[ ](https://library.lclark.edu/newbooks/index.php?catid=34&ref=lorcandempsey.net)
Second, it is possible to search Amazon through the discover feature I mention above and the book covers are displayed as a result and again can be manipulated in the PicLens environment. Some details about each book are also visible.
[](https://www.amazon.com/s/ref=nb%5Fss%5Fgw?url=search-alias%3Dstripbooks&field-keywords=barbara+pym&x=0&y=0&ref=lorcandempsey.net)
Useful? I don’t know 😉 The Barbara Pym covers are pretty nice though …..
Note: although it is possible to search Amazon from within PicLens, Amazon itself does not appear to be enabled for users who have the PicLens addon installed.
### Research Repository Systems
URL: https://www.lorcandempsey.net/research-repository-systems/
Last updated: 2020-10-28T09:23:16.000Z
Chris Rusbridge writes about Research Repository Systems:
> I [promised](https://digitalcuration.blogspot.com/2008/06/reaction-to-negative-click-repositories.html?ref=lorcandempsey.net) to be more specific about what I would like to see in repositories that presented more value for less work overall, by offering facilities that allow it to become part of the researcher’s workflow. I’m going to refer to this as “the Research Repository System (RRS)” for convenience. \[[Digital Curation Blog](https://digitalcuration.blogspot.com/?ref=lorcandempsey.net)\]
He discusses seven facilities …
> - [web orientation](https://digitalcuration.blogspot.com/2008/07/research-repository-system-web.html?ref=lorcandempsey.net)
> - [researcher identity management](https://digitalcuration.blogspot.com/2008/07/research-repository-system-identity.html?ref=lorcandempsey.net)
> - [authoring support](https://digitalcuration.blogspot.com/2008/07/research-repository-system-authoring.html?ref=lorcandempsey.net)
> - [object disclosure control](https://digitalcuration.blogspot.com/2008/07/research-repository-system-object.html?ref=lorcandempsey.net)
> - [data management support](https://digitalcuration.blogspot.com/2008/07/research-repository-system-data.html?ref=lorcandempsey.net)
> - [persistent storage](https://digitalcuration.blogspot.com/2008/07/research-repository-system-persistent.html?ref=lorcandempsey.net)
> - [full preservation archive](https://digitalcuration.blogspot.com/2008/07/research-repository-system-persistent.html?ref=lorcandempsey.net), and
> - [spinoffs](https://digitalcuration.blogspot.com/2008/07/research-repository-system-persistent.html?ref=lorcandempsey.net)
>
> \[[Digital Curation Blog](https://digitalcuration.blogspot.com/2008/07/negative-click-positive-value-research.html?ref=lorcandempsey.net)\]
There is a [summary picture](https://bp1.blogger.com/%5FNKCuJNkebJE/SGuO4qpaBhI/AAAAAAAAAAY/5zDf4rVuRDQ/s1600-h/RRS+map.png?ref=lorcandempsey.net).
I was interested to see Chris mention CRIS (Current Research Information System), something I have seen more mention of in Europe than in the US.
Related entries:
- [Processes and repositories](https://blog.oclc.org/lorcand/archives/001459.html?ref=lorcandempsey.net)
- [Collections grid and digital conservancy](https://blog.oclc.org/lorcand/archives/001450.html?ref=lorcandempsey.net)
- [Our digital identities: bricolage, prefabrication and disclosure](https://blog.oclc.org/lorcand/archives/001309.html?ref=lorcandempsey.net)
- [Repositories and disclosure](https://blog.oclc.org/lorcand/archives/001185.html?ref=lorcandempsey.net)
- [Libraries, research and learning](https://blog.oclc.org/lorcand/archives/001049.html?ref=lorcandempsey.net)
- [Networkflows](https://blog.oclc.org/lorcand/archives/000933.html?ref=lorcandempsey.net)
- [In the flow](https://blog.oclc.org/lorcand/archives/000688.html?ref=lorcandempsey.net)
- [Institutional repositories and research assessment](https://blog.oclc.org/lorcand/archives/000886.html?ref=lorcandempsey.net)
### A 'shop window' to the National Library of Scotland
URL: https://www.lorcandempsey.net/a-shop-window-to-the-national-library-of-scotland/
Last updated: 2020-10-28T09:23:18.000Z
I enjoyed a visit to The National Library of Scotland (NLS) a while ago. The NLS has an [area](https://www.youtube.com/user/NLofScotland?ref=lorcandempsey.net) on YouTube, showing videos from the Scottish Screen Archive. Here is a link to an interesting video (embedding is disabled) which is rather more engaging than its description suggests 😉
> This short clip from the film “From Glasgow Green to Bendigo” (1961) shows an artist from the Templeton Carpet Factory in Glasgow, Scotland demonstrating, in a flamboyant style, how the pattern for a new carpet is designed and created. \[[YouTube – Carpet design at Templeton’s in Glasgow, Scotland](https://www.youtube.com/watch?v=-a8L7%5FuSaAY&ref=lorcandempsey.net)\]
I wonder did he always work in a suit? One of the tags in the description is ‘cheesy’ (I think these are assigned by NLS staff?).
The Scottish Screen Archive has its own website:
> The Scottish Screen Archive is Scotland’s national moving images collection. It preserves over 100 years of Scottish history on film and video. \[[Scottish Screen Archive](https://ssa.nls.uk/index.cfm?ref=lorcandempsey.net)\]
I was actually led to YouTube via this presentation I came across on SlideShare:
[](https://www.slideshare.net/?src=embed&ref=lorcandempsey.net) | [View](https://www.slideshare.net/scottishlibraries/youtube-and-the-national-library-of-scotland?src=embed&ref=lorcandempsey.net "View YouTube and the National Library of Scotland on SlideShare") | [Upload your own](https://www.slideshare.net/upload?src=embed&ref=lorcandempsey.net)
It discusses some of the issues involved in making the videos available on YouTube. There is a nice picture of YouTube metadata on [slide 8](https://www.slideshare.net/scottishlibraries/youtube-and-the-national-library-of-scotland/8?ref=lorcandempsey.net). And on [slide 14](https://www.slideshare.net/scottishlibraries/youtube-and-the-national-library-of-scotland/14?ref=lorcandempsey.net) they suggest that “every website we upload a moving image to is a ‘shop window’ to the National Library of Scotland”.
Finally, with Euro 2008 just finished, [here is a clip](https://ssa.nls.uk/film.cfm?fid=5424&ref=lorcandempsey.net) from an earlier era with a goal by a Scottish footballing legend.
Update: Referring to the NLS presentation above, Seb Chan has an [interesting post](https://www.powerhousemuseum.com/dmsblog/index.php/2008/07/02/video-archives-in-youtube-national-library-of-scotland/?ref=lorcandempsey.net) contrasting YouTube and Flickr. He attributes the presentation to Ann Cameron (who is listed as a contact in the presentation).
Update: There is a nice response to this post on the [Blog of the digital library of Scotland](https://digitalnls.wordpress.com/2008/07/03/web-20-in-action-increased-exposure/?ref=lorcandempsey.net). It gives credit for the presentation to Ann Cameron, Liam Paterson and Eilidh MacGlone. And it points to a [writeup](https://widwisawn.cdlr.strath.ac.uk/issues/vol6/issue6%5F1%5F4.html?ref=lorcandempsey.net) of the initiative by Eilidh MacGlone. An [earlier entry](https://digitalnls.wordpress.com/2008/03/18/new-site-for-the-scottish-screen-archive/?ref=lorcandempsey.net) on the blog provides provides some context for the Scottish Screen Archive.
### QOTD: The cornerstone of the University
URL: https://www.lorcandempsey.net/qotd-the-cornerstone-of-the-university/
Last updated: 2020-10-28T09:23:22.000Z
Consider the following quote …..
> The role of the library in the university is being transformed. Information technology is shaping both the practice of scholarly inquiry and the daily routine of students and faculty, while library services are becoming more client-focused and more integrated into teaching, learning, and research activities. Demands for technology-related services, the digitisation of collections, and technology rich user environments are growing. Library professionals are increasingly directly involved in teaching students and developing their information literacy. These increasing demands occur at the same time as calls for accountability and for quantitative measures of the library contribution to research, teaching, and learning increasingly influence the allocation of institutional resources. The library must deal creatively with the tensions between, on the one hand, demands for free public access to data and outputs from publicly funded research, and, on the other, the protection of privacy and intellectual property rights.
Perhaps it is the opening paragraph of an article in *Educause Review* or *Ariadne* about the academic library today? Maybe it is the blurb attached to an academic library conference? Is it the explanatory text on *ACRLog*?
Nope …. it is from the [job advert](https://www.ucd.ie/hr/html/vacancies/2008/support/003582.html?ref=lorcandempsey.net) for the University Librarian at [University College Dublin](https://www.ucd.ie/?ref=lorcandempsey.net). The successful candidate will be one who “envisions UCD Library as the cornerstone of a leading international research University”.
Often, in a document like this, there are vaguer references to vision and change management, to creating a library for the twenty-first century, and so on. It is interesting seeing here some suggestion of ways in which the [library](https://www.ucd.ie/library/?ref=lorcandempsey.net) **is seen to be** changing, albeit in quite general terms.
### Linking to Identities
URL: https://www.lorcandempsey.net/linking-to-identities/
Last updated: 2020-10-28T09:23:23.000Z
Thom has a note about linking to [Worldcat Identities](https://worldcat.org/identities/?ref=lorcandempsey.net). The current API has various aspects ….. here is a list with examples for the two simpler approaches. See [Thom’s post](https://outgoing.typepad.com/outgoing/2008/06/linking-to-worl.html?ref=lorcandempsey.net) for fuller detail.
1\. Direct linking using an LCCN.
Here is the link for Van Morrison: [https://worldcat.org/identities/lccn-n85-148183](https://worldcat.org/identities/lccn-n85-148183?ref=lorcandempsey.net).
2\. OpenURL
See Thom’s [post](https://outgoing.typepad.com/outgoing/2008/06/linking-to-worl.html?ref=lorcandempsey.net) for the detail.
3\. NameFinder
> The name finder service gives back a list of candidate names with URI’s, ranking information, a sample title and other information about the name. …. NameFinder looks at lots of possible variations in names, so almost always results in a list rather than a unique Identity record. \[[Outgoing: Linking to WorldCat Identities](https://outgoing.typepad.com/outgoing/2008/06/linking-to-worl.html?ref=lorcandempsey.net)\]
Here is Van again: [https://worldcat.org/identities/find?fullName=Van+Morrison](https://worldcat.org/identities/find?fullName=van+morrison&ref=lorcandempsey.net). Or [https://worldcat.org/identities/find?fullName=george+ivan+morrison](https://worldcat.org/identities/find?fullName=george+ivan+morrison&ref=lorcandempsey.net). (There is also a SOAP version.)
4\. SRU searching
There is also full SRU searching and again Thom [provides](https://outgoing.typepad.com/outgoing/2008/06/linking-to-worl.html?ref=lorcandempsey.net) the detail.
And while we are talking about him, here is a [VIAF](https://www.oclc.org/research/projects/viaf/?ref=lorcandempsey.net) [entry](https://orlabs.oclc.org/viaf/LC|n85148183?ref=lorcandempsey.net) for Van Morrison and here is his [FAST](https://www.oclc.org/research/projects/fast/?ref=lorcandempsey.net) subject tag cloud from Identities.
[](https://worldcat.org/identities/lccn-n85-148183?ref=lorcandempsey.net#linkfastheadings)
Finally, here is a [list](https://www.worldcat.org/profiles/harrywagner/lists/61029?ref=lorcandempsey.net) of his CDs in Worldcat.
### Two from Elsevier: Article 2.0 and interdisciplinary
URL: https://www.lorcandempsey.net/two-from-elsevier-article-20-and-interdisciplinary/
Last updated: 2020-10-28T09:23:26.000Z
Two unrelated notes about Elsevier initiatives. The first about a competition in which they are making available an article-based data set for recombination in external environments or applications. The second about a study of Science Direct usage which shows different patterns of interdisciplinary behavior across disciplines. Although, one could push a contrived relation, I suppose, in suggesting that the latter study potentially offers requirements for some types of application that might be attempted in the competition.
> We’ve worked hard to build the Article 2.0 dataset, and now we’re opening it up to developers via a simple, straightforward REST API. We will provide contestants with access to approximately 7,500 full-text XML scientific articles (including images) and challenge each contestant to be the publisher. In other words, each contestant will have complete freedom for how they would like to present the scientific research articles contained in the Article 2.0 dataset. We will encourage the use of XQuery, but this will not be a mandate. By leveraging these APIs, the contestant becomes the publisher and can render scientific articles to meet their needs including integrating the article into existing applications or combining it with other web service APIs. \[[Elsevier Article 2.0 Contest](https://article20.elsevier.com/contest/home.htm?ref=lorcandempsey.net)\]
via [eFoundations](https://efoundations.typepad.com/efoundations/2008/06/article-20-cont.html?ref=lorcandempsey.net).
> The third thought comes from a presentation by Mayur Amin of [Elsevier](https://www.elsevier.com/wps/find/homepage.cws%5Fhome?ref=lorcandempsey.net) about surveys of usage of journals in Science Direct. One of the interesting findings here is that while for researchers in physics and maths, 70% or more of usage is of journals within the discipline, for researchers in other disciplines, such including chemistry and environmental sciences, usage of journals within the discipline is at less than half that level. This may of course be an effect of the way in which Elsevier classify the journals. But it is at least open to the suggestion that researchers in some disciplines are more inclined to read beyond their own discipline. Is this evidence that some disciplines are more interdisciplinary than others? Is this something worth investigating? \[[Three Thoughts on Interdisciplinary Research | RIN](https://www.rin.ac.uk/node/407?ref=lorcandempsey.net)\]
via [Michael Jubb](https://www.rin.ac.uk/node/407?ref=lorcandempsey.net).
### Encore at Glasgow
URL: https://www.lorcandempsey.net/encore-at-glasgow/
Last updated: 2020-10-28T09:23:28.000Z
I was interested to come across the Encore implementation at the University of Glasgow. This is still in development, but here is a description of current features …
> Encore is a new way of searching the Library catalogue offering:
>
> - single search box
> - relevance ranked results
> - location & availability details
> - links to electronic resources
> - easy ways to refine (limit) your search
> - recently added books on your topic
> - a subject tag cloud around your topic
>
> \[[Encore News 2008](https://www.lib.gla.ac.uk/News/2008/encorenews.shtml?ref=lorcandempsey.net)\]
[ ](https://encore.lib.gla.ac.uk/iii/encore/search/C%7CSpaul+muldoon%7COrightresult%7CU1?lang=eng&suite=def&ref=lorcandempsey.net)
My eye was drawn to the images pulled in by Yahoo Web Services (this sometimes worked very well, as in the example above, sometimes less well), and to the subject tag cloud. I wondered what processing was done on subject data to generate the cloud.
I liked being shown which fields accounted for the retrieval (top of the ‘refine by’ column) and seeing new additions.
Interestingly, the tags here are used to refine the search. Of course, they could also be used to expand the search. I wonder do people have expectations either way here when they see ‘tags’?
### IPR
URL: https://www.lorcandempsey.net/ipr/
Last updated: 2020-10-28T09:23:31.000Z
Not surprising really, but I was interested to realize recently how much more real IPR issues are for my children than they were for me. A couple of indicators ….
**Brand.** They are very aware of brands – for clothes, accessories, and so on. More particularly, they have a sense of the ‘aura’ attaching to authentic items, reflected in the price ;-), and while understanding the attraction of copies definitely feel that they are second best. We were waiting in the car the other day and somebody walked past. There was a discussion in the back about whether his jeans were the real thing (I confess to not remembering the brand 😉 or a fake …
**Media.** Several things here. They are of course aware of the limitation on use of music downloaded from iTunes. However, they also realize that there are territorial differences and restrictions on how DVDs can be played, and have also experienced territorial restrictions on the use of media clips as in ….
[ ](https://news.bbc.co.uk/sport2/hi/football/euro%5F2008/7476696.stm?ref=lorcandempsey.net)
### Calais - entity identification in the cloud
URL: https://www.lorcandempsey.net/calais-entity-identification-in-the-cloud/
Last updated: 2020-10-28T09:23:33.000Z
Calais is a web service provided by Thomson Reuters, currently at no charge.
> Calais enhances your content with rich semantic metadata. Using your content as a starting point you can utilize Calais to automatically add metadata such as entities (people, places, organizations, etc.), facts (John Doe works for Acme Corporation as the CEO), and events (a natural disaster of type landslide happened on date x). That metadata is generated in industry-standard formats that ease integration with whatever commercial, open source or proprietary content management system you are using. \[[Content Manager | OpenCalais](https://www.opencalais.com/about/contentManager?ref=lorcandempsey.net)\]
I came across it being used in the Powerhouse Museum, and have no experience of it apart from looking at a few entries in the catalogue there.
> We have been experimenting with Reuters’ [OpenCalais web service](https://opencalais.com/?ref=lorcandempsey.net) since it launched in January. Now we have made a basic implementation of it applied to records in our collection database, initially as a way of generating extra structured metadata for our objects. We can extract proper names, places (by continent, country, region, state and city), company names, technologies and specialist terms, from object records all without requiring cataloguers to catalogue in this way. Having this data extracted makes it much easier for us to connect objects by manufacturers, people, and places within our own collection as well as to external resources.
>
> \[[fresh + new(er) » Blog Archive » OPAC2.0 – OpenCalais meets our museum collection / auto-tagging and semantic parsing of collection data](https://www.powerhousemuseum.com/dmsblog/index.php/2008/03/31/opac20-opencalais-meets-our-museum-collection-auto-tagging-and-semantic-parsing-of-collection-data/?ref=lorcandempsey.net)\]
Here is an example for the object ‘[P3561 Text book, ‘Simple Directions in Needlework and Cutting Out, Intended for the Use of the National Female Schools of Ireland’, Commissioners of National Education, Dublin, Ireland, 1858](https://www.powerhousemuseum.com/collection/database/?irn=329382&search=p3561&images=&c=&s=&ref=lorcandempsey.net)‘.
[](https://www.powerhousemuseum.com/collection/database/?irn=329382&search=p3561&images=&c=&s=&ref=lorcandempsey.net)
I [suggested ](https://blog.oclc.org/lorcand/archives/001351.html?ref=lorcandempsey.net)a while ago that four types of metadata about things were of interest in our systems. Interestingly, an item result page from the Powerhouse Museum now displays examples of all four: professionally created, contributed (tags), intentional (in this case there is a ‘similar searches’ feature), and programmatically promoted (the data generated by the Calais service).
Related entry:
- [Four sources of metadata about things](https://blog.oclc.org/lorcand/archives/001351.html?ref=lorcandempsey.net)
### The institutional web presence again
URL: https://www.lorcandempsey.net/the-institutional-web-presence-again/
Last updated: 2023-11-28T16:55:56.000Z
I [pointed](https://blog.oclc.org/lorcand/archives/001662.html?ref=lorcandempsey.net) to Brian Kelly’s [note](https://jiscpowr.jiscinvolve.org/2008/06/20/the-history-of-the-university-of-bath-home-page/?ref=lorcandempsey.net) about the evolution of the University of Bath’s web presence the other day. Brian works at UKOLN, which is at the University of Bath. He uses the Internet Archive’s Wayback Machine to chart how the University’s web presence changed over the years, and makes some observations about design and format choices in the context of our developing sense of good practice.
In this context, I was interested to come across [this page](https://www.virginia.edu/virginia2008/archive/index.html?ref=lorcandempsey.net) describing the ‘history of U.Va. on the web’. I have not seen other examples like this, but then I have not looked for them. It strikes me as interesting and useful.
> The University’s original gopher server, named “minerva” (for the goddess of wisdom) was installed in 1991\. The University’s first published Web site was the [University Library site](https://etext.lib.virginia.edu/reports/mellonold/mellon.html?ref=lorcandempsey.net), posted by John Price Wilkin in 1993\. \[[History of U.Va. on the Web, U.Va.](https://www.virginia.edu/virginia2008/archive/index.html?ref=lorcandempsey.net)\]
It is interesting to see [John Wilkin's](https://scholarlypublishing.org/jpwilkin/?ref=lorcandempsey.net) name there. And it is interesting to see mention of …….. [Gopher](https://en.wikipedia.org/wiki/Gopher%5F%28protocol%29?ref=lorcandempsey.net)!
To connect this back to Brian’s note, here is an extract from the UKOLN Newsletter of September 1994.
> **The UKOLN server**
> In June 1992 Sun Microsystems Ltd. presented a SPARCserver to UKOLN that is now being used to:
> - host BUBL (Bulletin Board for Libraries), a service that is administered from the University of Strathclyde by Dennis Nicholson with support from teams of subject specialist volunteers
> - maintain the UK National Entry Point gopher, a list of links to all registered UK gopher servers
> \[[UKOLN – Newsletter, issue 2](https://www.ukoln.ac.uk/ukoln/newsletters/issue2.html?ref=lorcandempsey.net)\]
The UK National Entry Point was initially set up by [Andy Powell](https://www.eduserv.org.uk/foundation/people/andypowell/?ref=lorcandempsey.net).
As I have mentioned before, BUBL rejoiced for a while in the URL www.bubl.bath.ac.uk (another link which no longer works). BUBL was an early adopter of the web. In fact, we gave Tim Berners-Lee access to the machine above to install the web server to which BUBL moved. Andy has told the story of what happened then several times:
> Andy then related an amusing story of personal embarrassment from 1993 when he was asked to set up a username on a UKOLN machine for someone called Tim Berners-Lee so he could install something called a ‘WWW server’ – probably an early version of the CERN server \[[25](https://www.ariadne.ac.uk/issue48/iwmw-2006-rpt/?ref=lorcandempsey.net#25)\]. Andy, being a Gopher \[[26](https://www.ariadne.ac.uk/issue48/iwmw-2006-rpt/?ref=lorcandempsey.net#26)\] man at the time hadn’t heard of a WWW server but duly set up the account, exchanging a few emails about how and where the code should be installed. Not long after this the NCSA, whose graphical browser was attracting attention at the time, released their popular server \[[27](https://www.ariadne.ac.uk/issue48/iwmw-2006-rpt/?ref=lorcandempsey.net#27)\]. Andy promptly deleted the Tim Berners-Lee installed server, his account and all email correspondence exchanged, having no idea who Tim Berners-Lee was. As good an example as any of digital history lost forever to the unsentimental and impassive indifference of the Unix command line. \[[‘IWMW 2006: Quality Matters’, Ariadne Issue 48](https://www.ariadne.ac.uk/issue48/iwmw-2006-rpt/?ref=lorcandempsey.net)\]
Who knows what the future will be interested in?
**Note:** The original quote from the UKOLN newsletter above had links to images of bullet points – the links were broken. I replaced with a list. A small persistence issue. Formatting updated on 11/28/2023.
### Not your parent's catalog
URL: https://www.lorcandempsey.net/not-your-parents-catalog/
Last updated: 2020-10-28T09:23:37.000Z
In a meeting the other day, I was struck by the number of systems environments where a library might now put access to catalog data. And I am focusing on what we still call catalog data, while acknowledging that this provides access to a part only of the library collection.
**Institutional**
The **‘classic’ catalog**: provides access to that part of the collection which goes through a cataloging workflow and is usually managed within the ILS.
The so called **Next Generation catalog**: provides access to the catalog data but makes better use of the data to provide a richer browse experience, and may incorporate participation/contribution by users, and so on. May be managed redundantly in parallel with the ‘classic’ catalog. Several approaches exist, based on open source or commercial software.
**Institutional discovery environments**. Recently, we have seen new systems which aim to provide access to the full range of locally managed metadata. These include Primo, Encore and Worldcat Local. Typically independent of the backend library management systems, they incorporate data from the ‘classic’ catalog alongside data from digital repositories, and maybe the knowledge base or other sources. They are a response to the desire to provide access to the library collection in ways that map onto user interests rather than legacy library system environments.
**Metasearch.** Now well-established, if still not straightforward, metasearch systems aim to provide a managed discovery environment over licensed databases and other resources. Metasearch is a response to the desire to provide access to the library collection in ways that map onto user interests rather than to legacy system or database boundaries which reflect business or technical circumstances of less interest to the user. Metasearch may be used to provide one-shot searching of a full range of databases, or to bundle databases by subject or course and so on.
What can one say about this set of systems? Here are some brief observations:
- Of course, these environments are related. Metasearch may include results from the ‘classic’ catalog, or metasearch results may in turn be included alongside results from local resources in an ‘institutional discovery environment’.
- The ‘next generation catalog’ as a reimplementation of the ‘classic’ catalog seems very partial: the techniques and approaches discussed there will find their way into the ‘integrated discovery environments’ that get deployed. The focus on enhancing the catalog is understandable given that the data is under library control. But what about ‘next generation’ abstracting and indexing databases or next generation repository interfaces?
- Controlled value data, in the sense of name or subject authorities, has been a central part of library practice, however variably uninterestingly deployed in actual catalogs. As catalog data is merged with data from other sources – A&I databases, digital repositories, etc – what happens to that controlled value data given that practices are different across resources. Name authority files may be valuable but typically only include authors that have published materials that have been catalogued: what about people who have only published articles? A variety of controlled subject vocabularies are in use across databases. Although mappings may be available, they may not be mobilized within these discovery environments. This becomes more visible as faceted approaches become more common.
- There is no standard way of presenting this array of systems in the library website, or standard way of naming these systems once one moves beyond the catalog.
This diversity may be replicated in the other contexts in which access is provided:
- **Union or group**. A similar set of systems may be offered, and may interact with local provision.
- Syndicated. Access may be syndicated in a variety of ways: widgets, facebook apps, toolbars, RSS feeds, ‘portlets’ in external portal environments, and so on. Again, some combination of the above systems may be offered.
Group
Global
### xISSN and Title History Tool
URL: https://www.lorcandempsey.net/xissn-and-title-history-tool/
Last updated: 2020-10-28T09:23:39.000Z
[xISBN](https://xisbn.worldcat.org/xisbnadmin/index.htm?ref=lorcandempsey.net) is now well established. [xOCLCNUM](https://xisbn.worldcat.org/xisbnadmin/xoclcnum/index.htm?ref=lorcandempsey.net) was introduced a while ago, as an aspect of the xISBN service.
xISBN is now being joined by [xISSN](https://xissn.worldcat.org/xissnadmin/index.htm?ref=lorcandempsey.net), a new Web service. With this service you can supply an ISSN, and find out about any predecessor, successor, and alternate ISSNs and titles, and find the electronic ISSN for a print title or vice versa.
This is a web service which can be integrated into library applications, websites, link resolvers, cataloging tools, and so on. There is also a pretty nifty human-ready demonstration interface known as [Title History](https://worldcat.org/xissn/titlehistory?ref=lorcandempsey.net).
[ ](https://worldcat.org/xissn/titlehistory?issn=0888-5885&ref=lorcandempsey.net)
My grid services colleague, Tim McCormick, provided the above detail, and also explained terms and conditions. The XML Web service is offered at no charge to OCLC members with cataloging subscriptions or to any low-volume users; and for fee to others. The Title History tool is free to everyone.
### CiteMeApp
URL: https://www.lorcandempsey.net/citemeapp/
Last updated: 2020-10-28T09:23:40.000Z
A new Worldcat Facebook application is now available: [CiteMe](https://apps.facebook.com/citemeapp/?ref=lorcandempsey.net).
> Get formatted citations in APA, Chicago, Harvard, MLA, or Turabian style. Start by searching for an item in WorldCat, the world’s largest network of library content and services. Find your title in the results, click the Get citations links, and you’re done. \[[Facebook | CiteMe](https://www.facebook.com/apps/application.php?id=23927330784)\]

### The Bath University record
URL: https://www.lorcandempsey.net/the-bath-university-record/
Last updated: 2023-07-16T21:41:02.000Z
As more of the “institutional record” gets pushed to the institutional website (‘brochureware’, prospectuses, course catalogs, annual reports, newsletters, etc) it raises interesting questions about who manages that institutional memory and about how it is managed.
I worked at the University of Bath for many years. My former colleague Brian Kelly has an interesting set of materials about the evolution of the university website since it was first set up.
This activity was carried out as part of a [project](https://jiscpowr.jiscinvolve.org/?ref=lorcandempsey.net) looking at good preservation practices for institutional web managers.
> In order to illustrate how an institution’s home page may change over a period of over 11 years the [Internet Archive’s WayBack Machine](https://www.archive.org/index.php?ref=lorcandempsey.net) was used to view the first occurence of the [University of Bath home page in every year from 1997 until 2007](https://web.archive.org/web/%2A/https://www.bath.ac.uk). (Note that in browsers which suppoprt Flash you can [interact with the display](https://www.ukoln.ac.uk/web-focus/experiments/experiment-20080612/?ref=lorcandempsey.net) and a more interactive access can be obtained if your install the [PicLens plugin](https://www.piclens.com/?ref=lorcandempsey.net), although there are also links to the static images and an [automated rolling display of the pages in the Internet Archive](https://www.ukoln.ac.uk/web-focus/experiments/experiment-20080612/bath-web-tour.html?ref=lorcandempsey.net)). \[JISC-PoWR » Blog Archive » [The History Of the University of Bath Home Page](https://www.ukoln.ac.uk/web-focus/experiments/experiment-20080612/?ref=lorcandempsey.net)\]
### Harvesting metadata for electronic theses and dissertations
URL: https://www.lorcandempsey.net/harvesting-metadata-for-electronic-theses-and-dissertations/
Last updated: 2020-10-28T09:23:46.000Z
Thom has a nice [note](https://outgoing.typepad.com/outgoing/2008/06/etd-2008-in-abe.html?ref=lorcandempsey.net) on ETD 2008, held at The Robert Gordon University in Aberdeen. (ETD – Electronic Theses and Dissertations.)
He notes our ongoing involvement in NDLTD:
> As part of OCLC’s support to NDLTD we harvest metadata about ETDs, and make a [union catalog](https://alcme.oclc.org/ndltd/servlet/OAIHandler?verb=ListSets&ref=lorcandempsey.net) (which includes metadata from WorldCat) harvestable. This is starting to be a sizeable file, with nearly 750,000 records in it right now. \[[Outgoing](https://outgoing.typepad.com/outgoing/?ref=lorcandempsey.net)\]
This must be one of the largest, longest running, production grade OAI-PMH operations there is? I say this with some uncertainty, as I don’t have a good sense of other initiatives. It would be interesting to hear of other examples which have been in operation for some time ….
### Network level image collections
URL: https://www.lorcandempsey.net/network-level-image-collections/
Last updated: 2020-10-28T09:23:48.000Z
[](https://www.flickr.com/commons?ref=lorcandempsey.net)And speaking of network level access, the [Flickr Commons](https://www.flickr.com/commons?ref=lorcandempsey.net) initiative seems to be getting real traction. The Smithsonian has just joined the Library of Congress, the Brooklyn Museum and The Powerhouse Museum in making a selection of images available on Flickr.
I had not looked closely at the text on the website before, and was interested to see how it describes the goals of the initiative:
> The key goals of The Commons on Flickr are to firstly show you hidden treasures in the world’s public photography archives, and secondly to show how your input and knowledge can help make these collections even richer. \[[Flickr: The Commons](https://www.flickr.com/commons?ref=lorcandempsey.net)\]
This provides a nice example of the ‘[concentrating](https://blog.oclc.org/lorcand/archives/001556.html?ref=lorcandempsey.net)‘ aspect of Web 2.0\. I noted an early [report](https://blog.oclc.org/lorcand/archives/001635.html?ref=lorcandempsey.net) from Seb Chan a while ago where he discussed how the volume and quality of tags on Flickr were both higher than on the home site. It will be interesting following this as it develops and seeing more data of this type.
It seems clear that this type of activity is one important strand in being able to scale description of digitized materials. An approach which relied exclusively on professionally produced metadata would not scale as we look at the volume of materials being created across institutions.
Related entries:
- [Tagging at the network level](https://blog.oclc.org/lorcand/archives/001635.html?ref=lorcandempsey.net)
- [The two ways of Web 2.0](https://blog.oclc.org/lorcand/archives/001556.html?ref=lorcandempsey.net)
- [Libraries and the long tail](https://www.dlib.org/dlib/april06/dempsey/04dempsey.html?ref=lorcandempsey.net) (D-Lib article)
### Metalogue
URL: https://www.lorcandempsey.net/metalogue/
Last updated: 2020-10-28T09:23:50.000Z
I am pleased to be able to report that my colleague Karen Calhoun has launched a [blog](https://community.oclc.org/metalogue?ref=lorcandempsey.net):
> I’m Karen Calhoun, Vice President of WorldCat and Metadata Services at OCLC. Some OCLC colleagues and I have joined together to launch *Metalogue,* a new blog devoted to cataloguing and metadata topics around the world. \[[Hello, and On Small Libraries – Metalogue](https://community.oclc.org/metalogue/archives/2008/06/hello-and-on-small-libraries.html?ref=lorcandempsey.net)\]
In her [first entry](https://community.oclc.org/metalogue/archives/2008/06/hello-and-on-small-libraries.html?ref=lorcandempsey.net), Karen talks about OCLC services to small libraries in the US and elsewhere.
### Flickr switch
URL: https://www.lorcandempsey.net/flickr-switch/
Last updated: 2020-10-28T09:23:52.000Z
I just came across a new document published by TASI, [Using Flickr to Organise a Collection of Images](https://www.tasi.ac.uk/advice/using/flickr-finding.html?ref=lorcandempsey.net). The advice is timely in light of the general discussion about using network-level services to manage or expose resources.
> Whether you have a small number of photographs you would like to share privately with a few colleagues, or a larger collection you need to make more widely available, Flickr offers a possible alternative to setting up an in-house image database. \[[TASI :: News](https://www.tasi.ac.uk/news.html?ref=lorcandempsey.net#news153)\]
My eye was caught by this:
> Once your images are on Flickr, how easy is it to get them back? What about any metadata/tags you have added? What if the site ceases to exist?
>
> Flickr itself does not provide a batch download or ‘export from Flickr’ option. However, if you have a Pro account you can download originals individually. This method will not preserve any of the metadata (titles, descriptions, comments or tags) you have added.
>
> There are a few third party applications that will batch download images, some of which will also export metadata but we haven’t tested them, e.g. [FlickrEdit](https://sunkencity.org/flickredit?ref=lorcandempsey.net) and [FlickrDown](https://greggman.com/pages/flickrdown.htm?ref=lorcandempsey.net). \[[TASI :: Advice | Finding and Using Digital Images | Using Flickr to Organise a Collection of Images](https://www.tasi.ac.uk/advice/using/flickr-organising.html?ref=lorcandempsey.net#externally-hosted)\]
_Includes the latest 500 public posts. Use `/sitemap.xml` for the complete archive of public content._